Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Average-linkage clustering
Past exam of the mathematics course of the University of Cambridge 2001 iii Paper 30 3 c Solution Created 2026-10-03 Updated 2026-10-14
Agglomerative hierarchical clustering starts with each observation as a singleton cluster in cluster analysis, repeatedly joins the closest pair of current clusters, and continues until one remains. The input is a dissimilarity matrix, so choosing variable scales and a scientifically sensible dissimilarity is part of the analysis.
Different linkages define closeness differently:Single-linkage clustering can connect elongated chains through nearest neighbors; complete-linkage clustering emphasizes compact clusters; average-linkage clustering averages all cross-pair distances. For Euclidean observations, Ward minimum-variance clustering instead chooses the smallest increase in within-cluster squared error,This follows by expanding squared deviations around the merged mean and using the zero sums of within-cluster residuals.
A dendrogram plots merge heights. In the lower-left sketch, two close pairs first merge at small heights, then join across a much larger separation; a horizontal cut between these heights yields two groups. The hierarchy gives nested partitions, not a uniquely established number of populations. Examine sensitivity to scaling, linkage and ties; once an agglomerative merge is made, the method does not undo it. The absence of a probability model also means that a visually attractive dendrogram is not itself a significance test.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 4 iii Solution Created 2026-10-03 Updated 2026-10-14
Cluster analysis groups observations without given class labels. It starts by deciding what similarity means, usually through a dissimilarity matrix. Euclidean distance is natural for comparable continuous coordinates; a Mahalanobis distance can account for differing scales and correlations when a meaningful nonsingular covariance estimate is available. Scaling and variable selection can change the groups. Binary, ordinal or categorical data may need a different dissimilarity, rather than arbitrary numerical codes and Euclidean distance.
Agglomerative hierarchical clustering begins with singleton groups, repeatedly merges the pair with smallest intergroup dissimilarity, and records the merges in a dendrogram. The height represents the algorithm's merge criterion. Cutting the dendrogram gives partitions at different resolutions, and merges cannot subsequently be reversed. In single-linkage clustering, the criterion is the nearest cross-pair distance; this detects chains and nonconvex groups, but a thin bridge can connect otherwise separated clouds. Complete-linkage clustering uses the farthest cross-pair distance and tends to produce compact groups, at the cost of sensitivity to extreme points. Average-linkage clustering uses the mean cross-pair distance, lying between these two criteria for a given pair of clusters.
For squared Euclidean geometry, Ward clustering merges the pair that least increases the within-group sum of squares. Expanding deviations about the merged mean givesThis favors low within-group dispersion, but interpreting it as a sum-of-squares increase requires Euclidean data. Different software may plot a rescaled height, so the vertical units of a dendrogram from Ward clustering must be stated.
A nonhierarchical alternative is k-means clustering. For a prescribed , minimizeAt fixed assignments, expanding squared distances or differentiating shows that the minimizing is the group mean. At fixed centroids, each point is assigned to a nearest centroid. Alternating these operations does not increase ; with a consistent tie rule and nonempty groups it reaches a locally stable partition. Initialization matters, so use multiple starts, and give an explicit rule for empty groups. It favors roughly spherical clusters and is sensitive to outliers and scaling. It cannot be expected to reproduce a nonconvex single-linkage partition.
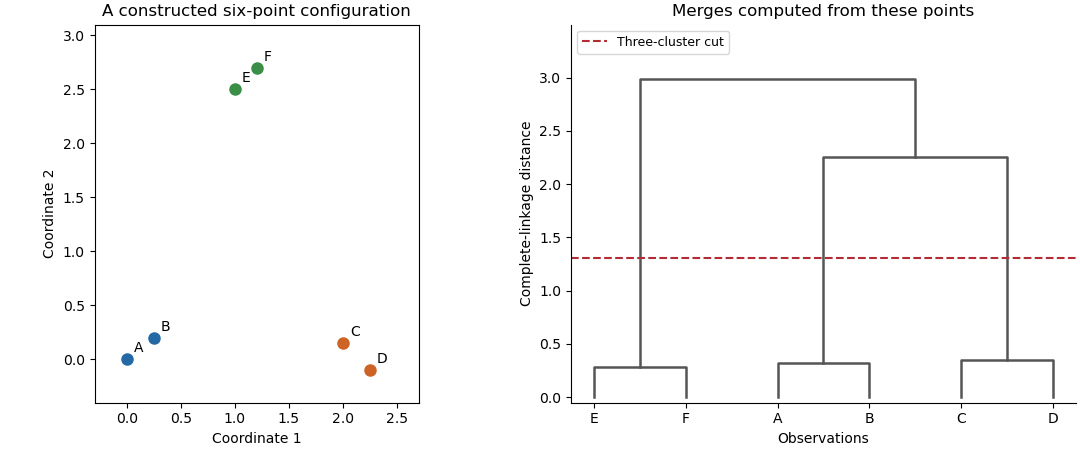
An original point configuration and its computed complete-linkage dendrogram with a three-cluster cut
. Details. 
The sketch displays a constructed point configuration and the complete-linkage merges computed from its actual Euclidean distances. A cut between the within-pair and between-pair merge heights yields three groups. Such visual separation is useful evidence, not proof of a uniquely correct number of populations. Select a resolution using subject knowledge, stability under resampling, separation diagnostics or the change of with . Clustering always gives a partition even for unstructured data, and different distance or linkage choices can yield different sensible summaries. Clustering is an exploratory construction whose conclusions depend on the geometry and the chosen resolution.