
Conditioning on marital status produces five contingency tables. In each, compare the conditional row percentages. The following differences are the sample proportion with some bad experiences minus the sample proportion without them, in percentage points; negative very-safe differences mean fewer respondents feeling very safe in the former group.
| Marital-status stratum | Difference: very safe | Difference: unsafe | Reported Pearson's chi-squared test p-value | Cramér's V | Goodman and Kruskal's gamma |
|---|---|---|---|---|---|
| Single | |||||
| Married | |||||
| Living with a partner | (inconsistent; see below) | ||||
| Divorced | |||||
| Widowed |
The p-values test independence within the respective strata; the magnitudes and directions come from the conditional percentages and association measures. Differences in the table are calculated from the counts before rounding.
Among single respondents, the very-safe sample proportion changes from to , while the unsafe sample proportion changes from to . The direction resembles the weak pooled pattern, but supplies little evidence against independence in this stratum. This is not evidence that the population association is exactly zero.
Among married respondents, the very-safe sample proportion changes from to and the fairly-safe sample proportion rises from to . Unsafe remains almost unchanged, versus . Thus the within-stratum association again chiefly shifts very safe toward fairly safe. Its is below the significance level, while still indicates a small association.
For respondents living with a partner, very safe changes from to , fairly safe from to , and unsafe from to . The very-safe difference is larger than in the married stratum. The printed p-value would be just below the conventional significance level. However, this particular output is internally inconsistent: recalculating Pearson's chi-squared test from its six displayed counts gives , , and . The reported agrees with the counts, whereas the printed would itself imply for two statistical degrees of freedom, rather than the printed . Using the displayed counts, this stratum does not reject independence at . The source PDF itself contains these incompatible figures; this is not resolved by rounding.
Among divorced respondents, very safe changes from to , but unsafe also decreases, from to , as fairly safe increases from to . This is a redistribution toward the middle category, not a simple shift toward greater unsafety. The near-zero gamma, , reflects the lack of a consistent ordinal direction, while can still register distributional differences without a direction. The p-value does not reject independence.
Among widowed respondents, very safe changes from to , and unsafe from to . The ordinal association is positive on the chosen ordering, with gamma . Its lack of conventional statistical significance, , does not imply a smaller estimated association than in the married group: the widowed stratum has only complete observations, versus in the married stratum, and therefore less precision. All five tables have sufficiently large expected counts for the reported approximations; even the smallest expected count is about .
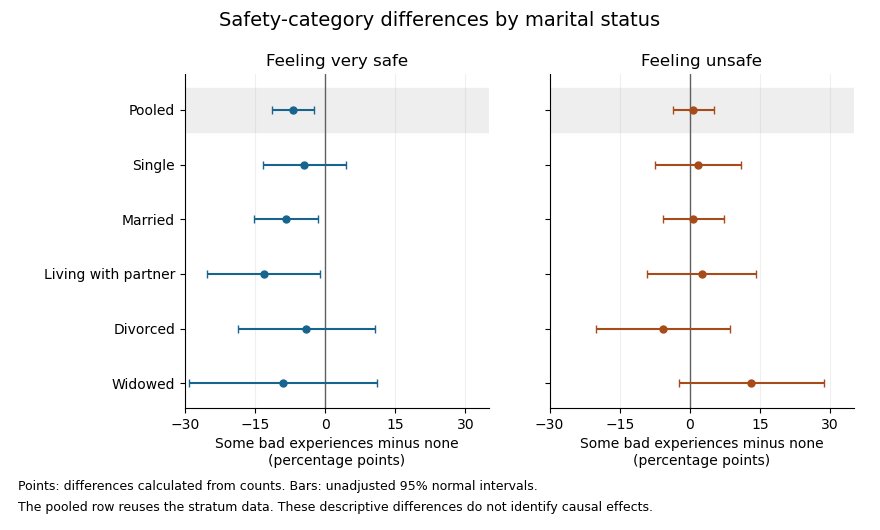

The plot uses large-sample Wald confidence intervals for the difference of independent sample proportions within each stratum. They concern the individual category contrasts, whereas the tabulated Pearson's chi-squared tests compare the full three-category distributions. The intervals are unadjusted for multiple hypothesis testing; the pooled row reuses the stratum observations, so it is not a sixth independent sample.
In the elaboration model, the persistence of a generally weak positive ordinal pattern within four strata is closer to partial replication than to a complete explanation of the pooled association by marital status. The differences in estimated patterns suggest possible specification: the divorced group's shift toward the middle category differs from the widowed group's shift toward unsafe. They do not by themselves establish population effect modification. In particular, significant and nonsignificant results need not differ significantly; compare the effects using an interaction contrast or a fitted model with the appropriate interaction terms, rather than comparing their separate p-values.[ref]
The Difference Between Significant and Not Significant is not Itself Statistically Significant by Andrew Gelman and Hal Stern. Printed p. 328, Introduction: comparing significance labels does not test the difference between estimates
One additional omnibus check can be derived from the supplied tables without assuming a common effect. Recalculating the five statistics from the counts, including the corrected living-with-partner statistic, the joint conditional independence test for stratified contingency tables givesUnder independent-stratum sampling this tests independence within every stratum jointly; it does not test whether the association is homogeneous across strata. It does not reject at , but this alone does not establish that stratification removed the population association: its ten-degree-of-freedom alternative is less focused than the pooled two-degree-of-freedom test, and nonrejection is not proof of equality.
The elaboration model also distinguishes an antecedent confounder from an intervening causal mediator. These cross-sectional tables do not establish the relevant time ordering or identify either role for marital status. Five separate stratum tests further require caution about multiple hypothesis testing: for example a Bonferroni correction at familywise would use per test, below all five individual p-values. That caution changes the interpretation of selected significance labels, not the observed conditional percentages.
The estimated patterns vary across strata, but the tables neither establish a population interaction nor prove that marital status explains away the association.
Significant and nonsignificant results need not differ significantly Created 2026-10-07 Updated 2026-10-25
For independent effect estimates with standard error , and with standard error , one two-sided Wald test is significant at five percent and the other is not. But their difference is with standard error , giving a negligible test statistic. Hence different significance labels do not establish an interaction or between-study heterogeneity; compare the effects directly.[ref]
The Difference Between Significant and Not Significant is not Itself Statistically Significant by Andrew Gelman and Hal Stern. Printed p. 328, Introduction; pp. 328–329, theoretical example