Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 5 1 1 c Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-06
Use the same formula for a measurable representative of . Dilation preserves null sets and gives . To check the weak formulation, change variables and set . ThenThe spacetime integral becomes , as required.
For uniqueness, take any bounded weak solution and write . Choosing in the weak formulation givesFor tensor test functions , this says that is distributionally constant and has value . A countable dense family of spatial test functions identifies almost everywhere. Thus the displayed solution is the unique bounded weak solution.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 5 1 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The characteristic curves solve , hence . By the chain rule, . Pulling back along the characteristic flow map givesFor , this is a classical solution: and cancel in the transport equation, and at the initial condition holds. Conversely, constancy along every characteristic curve forces this formula.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 5 1 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06A weak solution is an equivalence class satisfying, for every test function ,This is integration by parts for the nonconservative transport equation. In particular, the weak formulation contains as well as . The last integral encodes the initial condition; a pointwise boundary value of an arbitrary Lebesgue space representative is not the definition. Compact support of the test function makes the identity meaningful even if is unbounded.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 47 4 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Allowed via a charged-current weak decay. The quark emits a virtual in , followed by . The relevant terms are the quark and lepton weak charged currents, with amplitude proportional to the CKM matrix element . At low energy their product gives a four-fermion interaction of the form plus its conjugate.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 47 3 a i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-20
Codex 0 Created 2026-10-03 Updated 2026-10-20Only a -channel Z boson connects the muon-neutrino line to the electron line. Its endpoints are the weak neutral current vertices and . A W boson couples to a muon, so it cannot produce an additional elastic charged-current diagram with external electrons. There is no photon-neutrino vertex, and a strictly massless Standard Model neutrino has no Higgs Yukawa vertex. There is one diagram.
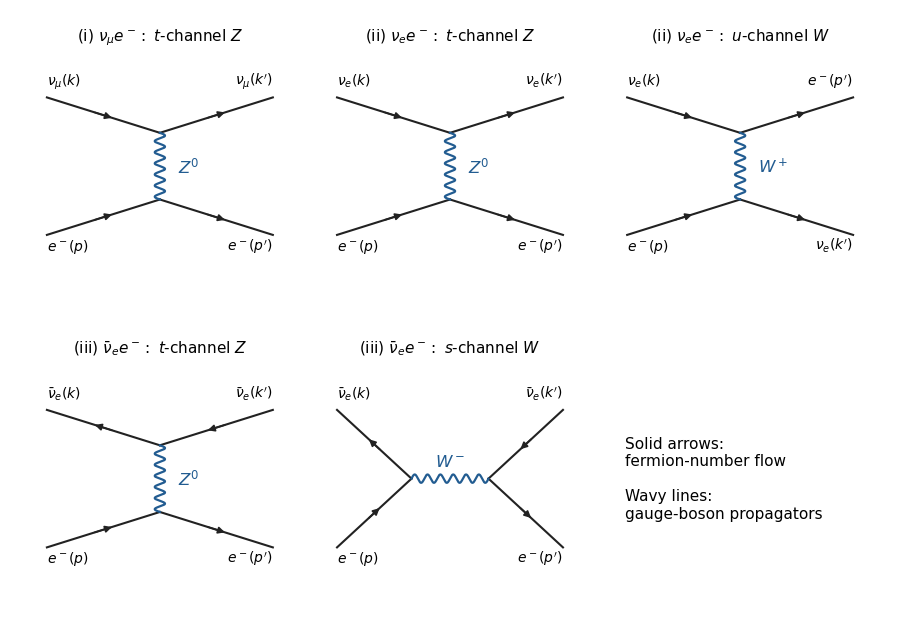
All five tree-level weak diagrams for muon-neutrino, electron-neutrino, and electron-antineutrino scattering on electrons
. Details. Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 40 2 a 2 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06A direct exponential minimization construction of a bounded pricing kernel proves the reverse implication without using a course theorem. ConsiderBoundedness of makes finite, continuous, and differentiable. On every bounded set of , the exponential and its derivatives have deterministic bounds, so differentiation under expectation is justified.
We first prove coercivity: as . Otherwise there would be a sequence with along which stays bounded above. Pass to a subsequence with , . There are two cases.
If , choose with . The bound on gives on this event for all large . ThereforeIf instead almost surely, the portfolio condition forces , since . Hence , and the nonnegative exponential term again forces . Both cases contradict the chosen sequence.
A minimizing sequence is consequently bounded. It has a convergent subsequence, and continuity of gives a global minimizer . At a minimizer each directional derivative vanishes, soThusIf , then : the constructed pricing kernel is bounded and even bounded away from zero. The compactness, coercivity, and differentiation arguments above supply the needed proof rather than appealing to the fundamental theorem of asset pricing.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 40 2 a 1 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Interpret positivity of as strict positivity almost surely. Suppose the stated bounded positive pricing variable exists. For a vector satisfying the two sign restrictions,A nonnegative random variable with zero expectation vanishes almost surely. Since , this gives almost surely and . The supplied nondegeneracy condition now yields . This proves the direction from a one-period martingale deflator to the separating-portfolio condition; no asset-pricing theorem has been invoked.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 6 i e Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Fix any configurations and . List the sites where they differ and update those sites in turn to their target signs. Every specified site has positive probability of being selected. At every intermediate configuration, both values of its full conditional distribution have positive probability, since all weights are finite and strictly positive. The finite prescribed sequence therefore has positive probability and reaches .
Thus every configuration is accessible from every other configuration, so the sampler is an irreducible Markov chain, or equivalently phi-irreducible with counting measure. If , a single update that keeps its selected spin unchanged also has positive probability. This simultaneously proves positive self-transition probability and aperiodicity, including . The sign of finite does not alter the accessibility argument.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 6 i d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Apply the Monte Carlo estimator to the observable :The theoretical justification is the ergodic theorem for a positive Harris recurrent Markov chain, not an independent-sample law of large numbers. The Markov chain has finite state space, is irreducible, and has the strictly positive posterior distribution as invariant law, so it is positive recurrent and Harris recurrent with counting measure. The observable is bounded: . Thus the estimator converges almost surely to the posterior expected value from any initial configuration.
Each state also has positive self-transition probability, so the chain is an aperiodic Markov chain. Finiteness then gives geometric convergence and the relevant central limit theorem; serial dependence determines the Markov chain Monte Carlo asymptotic variance if error bars are required. A fixed finite burn-in can be discarded without changing consistency, but independence of the retained states should not be assumed.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 6 i c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06For , put and . Removing all factors independent of from the posterior distribution gives, for ,A stable implementation uses the difference of the log weights. The conditional log odds areso , a logistic function. For very large , evaluate this logistic expression using the sign of to avoid exponential overflow.
For Gibbs sampling for a finite hidden spin field, initialize any spin configuration. At every step choose uniformly, draw a fresh uniform variable, set spin to with the probability above and to otherwise, and leave all remaining spins fixed. This Random-scan Gibbs sampler has the stated posterior distribution invariant by detailed balance of a random-scan Gibbs sampler. All conditional probabilities are strictly between zero and one. For the one-site case, the conditional probabilities are both .
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 6 i b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The prior factors involving are for . A likelihood factor centered at depends on precisely when , equivalently . Those factors areOnly incident prior edges and likelihoods centered at neighboring sites are affected. In particular, the likelihood centered at does not depend on : its mean involves only the neighbors of . These are the local likelihood factors in a hidden spin field. The resulting conditional dependence can extend two lattice steps, beyond the nearest-neighbor prior interactions. For , both collections are empty.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 6 i a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the Bayes' theorem to multiply the Ising model prior by the conditionally independent normal likelihood factors. For fixed observed , the posterior distribution isThere is no boundary wraparound: the neighbor sets use only actual horizontal and vertical edges inside the square. Each unordered edge is counted once. In particular, the prior retains the printed minus sign in front of , and the likelihood retains the seventh power. The finite state space and finite observed values make every posterior weight positive and finite, with a finite positive normalizing sum.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 5 d 2 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06At each transition, choose a coordinate uniformly and independently of the previous coordinate choices. Draw a fresh value from that coordinate's full conditional distribution given the current remaining coordinates, and keep all other coordinates fixed. This supplies the random-selection and conditional-draw operations lost in the TeX transcription. The update depends only on the current vector and fresh randomness, which proves the Markov property. The printed mathematical requests are the kernel and its detailed balance, answered in the following two subsections.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 5 d 1 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The algorithm is a Random-scan Gibbs sampler. Start at a point where the target is positive, with a proper normalizing integral and well-defined full conditional distributions. Its state is the entire coordinate vector. Choosing the initial point fixes the initial law; it need not already be the invariant law. The transition rule below preserves the target irrespective of this choice.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 4 c iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Recognize the integrand as a Gaussian scale mixture. If has the unit Rayleigh distribution and is an independent standard normal distribution variable, then the conditional density of given is . Multiplying by the radius density givesThus use for the independent radius and for the normal output of the Box-Muller transform:The mixture argument also proves that integrates to one, by the Tonelli theorem. As a check, is exponential of rate , so the characteristic function of is . This is the Rayleigh-normal scale mixture, with Laplace distribution density .
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 4 c ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The Box-Muller transform uses independent uniforms to setThe radius has the unit Rayleigh distribution, with density for , and the angle is independently uniform on . Their joint density is . The Cartesian change of variables has absolute Jacobian determinant , so the joint density of isThe factorization proves that the outputs are independent random variables, each with a standard normal distribution.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 4 c i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Integrating the Weibull distribution density gives for . Inverse transform sampling therefore givesReplacing by produces the same probability distribution. Both uniforms belong to with probability one. Here the conventional Weibull scale is , rather than .
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 2 e ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06This covariance is also zero, but symmetry is essential to the proof. Write , where is an independent fair sign. The normal distribution makes that sign independent of its magnitude and of every other driving variable. Conditional on the magnitudes and all noise except this sign, changing flips and leaves unchanged. Every future conditional scale uses only squared past observations, so is unchanged for .
Thus is independent of the remaining fair sign in . Averaging that sign gives , and henceThe Cauchy-Schwarz inequality again guarantees integrability. For odd , the parity decomposition of a lag-two ARCH process also gives independence directly. For even , the sign symmetry of an ARCH process supplies the argument; the martingale difference sequence property alone would not justify this reversed covariance.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact