
Stack Overflow Vote Fraud Script Updated 2025-07-16
How do you think Ciro got his rep? Just kidding.
Stack Overflow later forbade Ciro from advertising this project as described at: Section "Ciro Santilli's Stack Overflow suspension for vote fraud script 2019". Those newbs know nothing about security through obscurity.
Bad Stack Overflow policies Updated 2025-07-16
Stack Overflow user Updated 2025-07-16
Stack Exchange Updated 2025-07-16
Rectangular wave Updated 2025-07-16
Ciro's Edict #8 Article metadata shown next to every header Updated 2025-07-16
This is a major feature: we have now started to inject the following buttons next to every single pre-rendered header:
This crucial feature makes it clear to every new user that every single header has its own separate metadata, which is a crucial idea of the website.
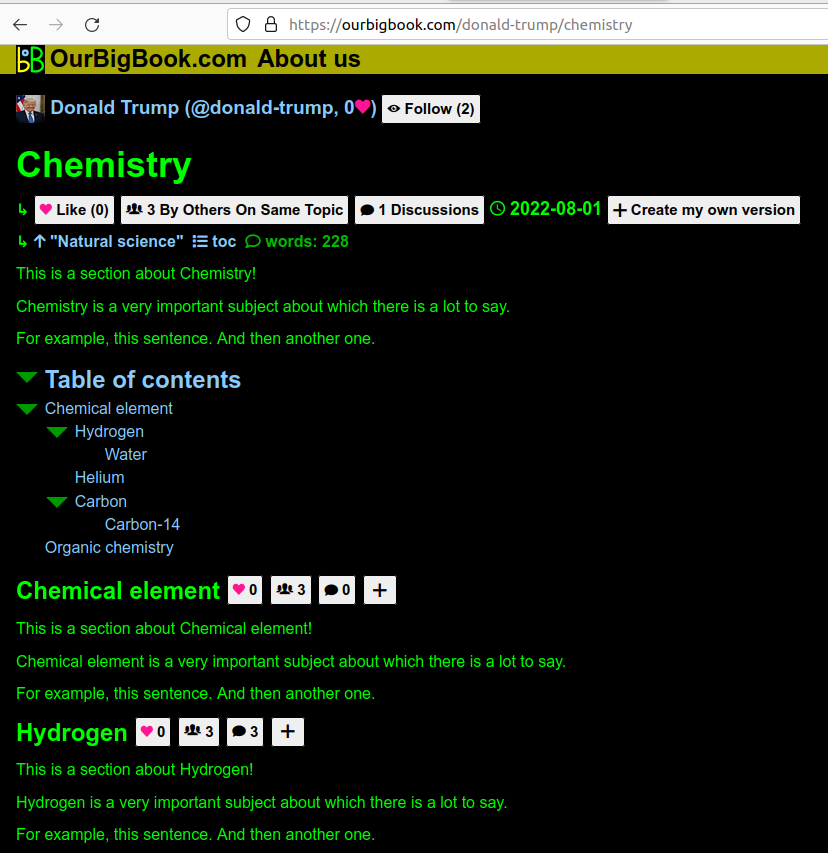
Screenshot showing metadata next to each header
. The page is: ourbigbook.com/donald-trump/chemistry. Note how even the subheaders "Chemical element" and "Hydrogen" show the metadata. Ciro's Edict #8 List topics on home page Updated 2025-07-16
The new default homepage for a logged out user how shows a list of the topics with the most articles.
This is a reasonable choice for default homepage, and it immediately exposes users to this central feature of the website: the topic system.
Doing this required in particular calculating the best title for a topic, since it is possible to have different titles with the same ID, the most common way being with capitalization changes, e.g.:would both have topic ID
JavaScript
Javascriptjavascript.The algorithm chosen is to pick the top 10 most upvoted topics, and select the most common title from amongst them. This should make topic title vandalism quite hard. This was made in a single SQL query, and became the most complext SQL query Ciro Santilli has ever written so far: twitter.com/cirosantilli2/status/1549721815832043522
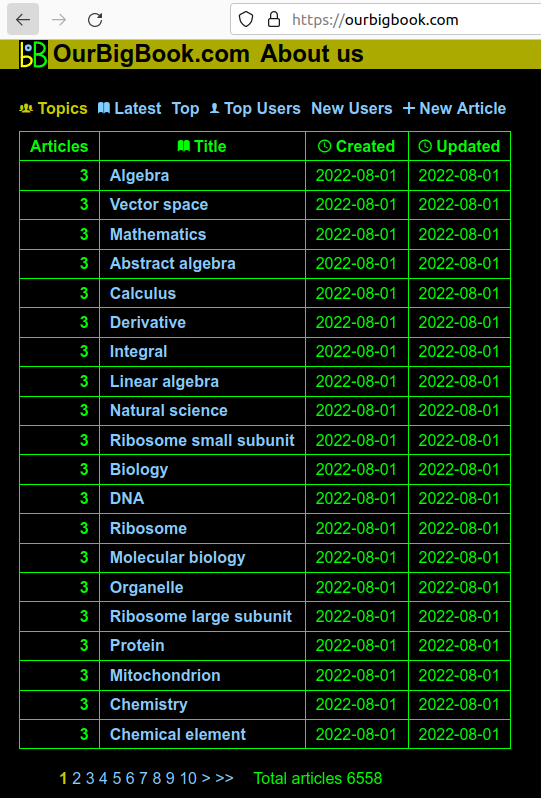
Screenshot showing the list of topics
. The page is: ourbigbook.com for the logged out user, ourbigbook.com/go/topics for the logged in user.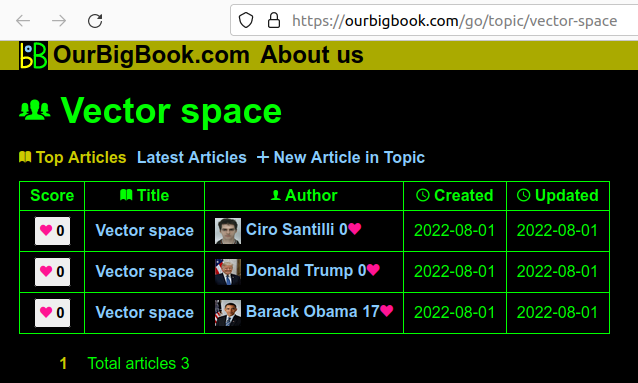
Screenshot showing a topic page
. The page is: ourbigbook.com/go/topic/vector-space. Before this sprint, we didn't have the "Vector Space" at the top, as it wasn't necessarily trivial to determine what the preferred title would be. Ciro's Edict #8 Article size and count limits Updated 2025-07-16
Limited the number of articles, and the size of article bodies. This, together with the reCAPTCHA setup from Email verification and reCAPTCHA signup protection should prevent the most basic types of denial-of-service attacks by filling up our database.
Ciro's Edict #7 Email verification and reCAPTCHA signup protection Updated 2025-07-16
Added this basic but fundamental protection layer to the website.
The email setup will of course be reused when notifications are eventually implemented.
Ciro's Edict #7 Issue tracker Updated 2025-07-16
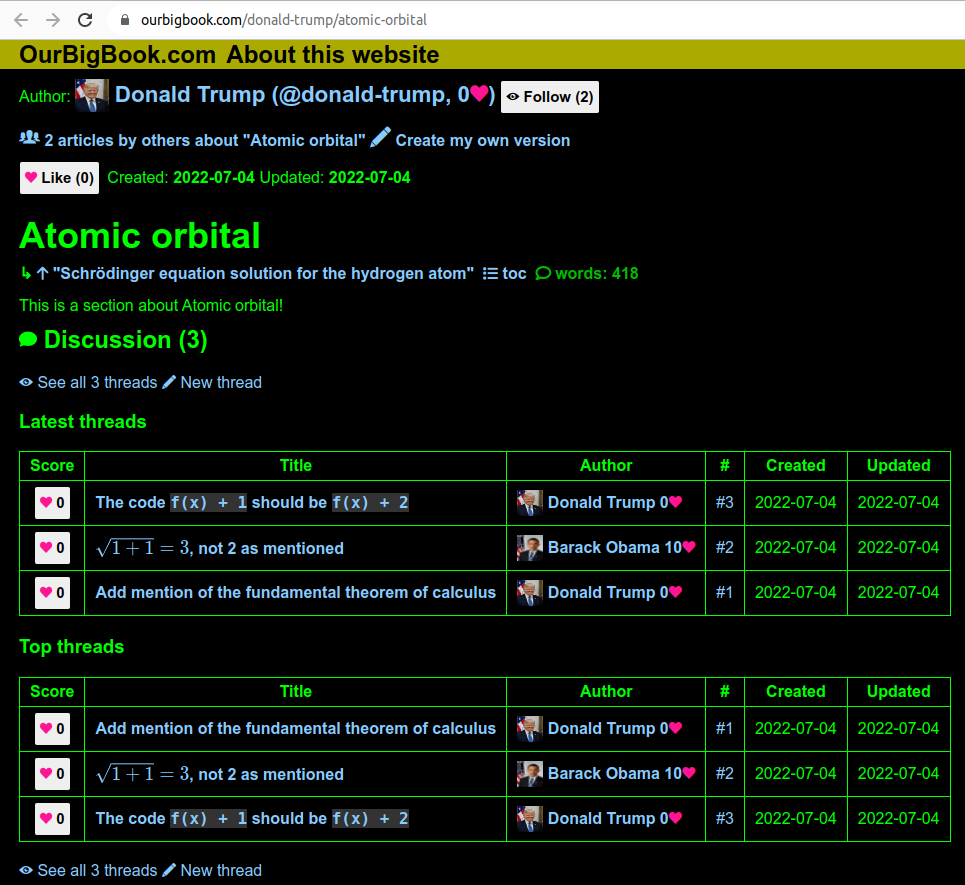
Every article now has a (very basic) GitHub-like issue tracker. Comments now go under issues, and issues go under articles. Issues themselves are very similar to articles, with a title and a body.
This was part of 1.0, but not the first priority, but I did it now anyways because I'm trying to do all the database changes ASAP as I'm not in the mood to write database migrations.
Here's an example:
- ourbigbook.com/go/issue/2/donald-trump/atomic-orbital a specific issue about the article "Atomic Orbital" by Donald Trump. Note the comments possibly by other users at the bottom.
- ourbigbook.com/go/issues/1/donald-trump/atomic-orbital list of issues about the article "Atomic Orbital" by Donald Trump
Ciro's Edict #7 Insane links and parents Updated 2025-07-16
You can now write:in lieu of the old:
<Blue cats> are nice.

= Blue cat

= Big blue cat
{parent=Blue cat}\x[blue-cat]{c}{p} are nice.
= Blue cat
= Big blue cat
{parent=blue-cat} Ciro's Edict #7
--format-source Updated 2025-07-16Added
ourbigbook --format-source automatic code formatting. I implemented it for the following reasons:- I want to do certain automatic modifications to source code on web, e.g.:
- later on, much later, this will allow WYSIWYG export to plaintext
This also ended up having one unexpected benefit: whenever a new feature is added that deprecates an old feature, by converting the large corpus from github.com/cirosantilli/cirosantilli.github.io to the new feature I can test the new preferred feature very well.
For example, converting
\x[blue cat] en masse to the new insane syntax <blue cat> found several bugs with the new insane syntax.This seemed somewhat easy at first, so I started it as a way of procrastinating more urgent Web features (web scares me, you know), but it ended being insanely hard to implement, because there are many edge cases. Also, most bugs are not acceptable, as they would corrupt your precious source code and potentially output.
But well, it is done!
Managed to upload the content from the static website cirosantilli.com (OurBigBook Markup source at github.com/cirosantilli/cirosantilli.github.io) to ourbigbook.com/cirosantilli.
Although most of the key requirements were already in place since the last update, as usual doing things with the complex reference content stresses the system further and leads to the exposition of several new bugs.
The upload of OurBigBook Markup files to ourbigbook.com was done with the newly added OurBigBook CLI
ourbigbook --web option. Although fully exposed to end users, the setup is not super efficient: a trully decent implementation should only upload changed files, and would basically mean reimplementing/using Git, since version diffing is what Git shines at. But I've decided not to put much emphasis on CLI upload for now, since it is expected that initially the majority of users will use the Web UI only. The functionality was added primarily to upload the reference content.This is a major milestone, as the new content can start attracting new users, and makes the purpose of the website much clearer. Just having this more realistic content also immediately highlighted what the next development steps need to be.
Once v1.0 is reached, I will actually make all internal links of cirosantilli.com to point to ourbigbook.com/cirosantilli to try and drive some more traffic.
The new content blows up by far the limit of the free Heroku PostgreSQL database of 10k lines. This meant that I needed to upgrade the Heroku Postgres plugin from the free Hobby Dev to the 9 USD/month Hobby Basic: elements.heroku.com/addons/heroku-postgresql, so now hosting costs will increase from 7 USD/month for the dyno to 7 + 9 = 16 UDS/month. After this upgrade and uploading all of cirosantilli.com to ourbigbook.com, Heroku dashboard reads reads:so clearly if we are ever forced to upgrade plans again, it means that a bunch of people are using the website and that things are going very very well! Happy how this storage cost turned out so far.
One key limitation found was that Heroku RAM memory is quite limited at 512MB, and JavaScript is not exactly the most memory economical language out there. Started investigation at: github.com/ourbigbook/ourbigbook/issues/230 Initially working around that by simply splitting the largest files. We were just on the verge of what could be ran however luckily, so a few dozen splits was enough, it managed to handle 70 kB OurBigBook Markup inputs. So hopefully if we manage to optimize a bit more we will be able to set a maximum size of 100 kB and still have a good safety margin.
Ciro's Edict #6 Misc advances Updated 2025-07-16
Ciro's Edict #5
\Include and \x and working on dynamic website Updated 2025-07-16This was the major final step of fully integrating the OurBigBook CLI into the dynamic website (besides fixing some nasty bugs that escaped passed by me from the previous newsletter).
Ciro's Edict #5 Improve header summary display Updated 2025-07-16
Before
. 
After
. Added font awesome icons. github.com/ourbigbook/ourbigbook/issues/151
Didn't manage to subset, but so be it for now: stackoverflow.com/questions/62395038/how-can-i-export-only-one-character-from-ttf-woff-file-to-avoid-load-unnecessa/71197892#71197892
This means while developing a website locally with the OurBigBook CLI, if you have a bunch of files with an error in one of them, your first run will run slowly until the error:but further runs will blast through the files that worked, skipping all files that have sucessfully converted:so you can fix file by file and move on quickly.
extract_ids README.ciro
extract_ids README.ciro finished in 73.82836899906397 ms
extract_ids art.ciro
extract_ids art.ciro finished in 671.1738419979811 ms
extract_ids ciro-santilli.ciro
extract_ids ciro-santilli.ciro finished in 1009.6256089992821 ms
extract_ids science.ciro
error: science.ciro:13686:1: named argument "parent" given multiple times
extract_ids science.ciro finished in 1649.6193730011582 msextract_ids README.ciro
extract_ids README.ciro skipped by timestamp
extract_ids art.ciro
extract_ids art.ciro skipped by timestamp
extract_ids ciro-santilli.ciro
extract_ids ciro-santilli.ciro skipped by timestamp
extract_ids science.ciroMore details at: cirosantilli.com/ourbigbook#no-render-timestamp
This was not fully trivial to implement because we had to rework how duplicate IDs are checked. Previously, we just nuked the DB every time on a directory conversion, and then repopulated everything. If a duplicated showed up on a file, it was a duplicate.
But now that we are not necessarily extracing IDs from every file, we can't just nuke the database anymore, otherwise we'd lose the information. Therefore, what we have to do is to convert every file, and only at the end check the duplicates.
Managed to do that with a single query as documented at: stackoverflow.com/questions/71235548/how-to-find-all-rows-that-have-certain-columns-duplicated-in-sequelize/71235550#71235550
Ciro's Edict #5 Completely rebrand Cirodown to OurBigBook Updated 2025-07-16
The name cirodown should not appear anywhere now, except with very few exceptions, e.g.:
- github.com/cirosantilli/cirodown to github.com/ourbigbook/ourbigbook
- file extension from
.ciroto.bigb - the Node.js NPM package was renamed from
cirodowntoourbibook. - all in-code instances
I have also squatted
OurBigBook on all major social media handles for near future usage, e.g.: twitter.com/ourbigbook and so on.I was going to do this sooner or later, it was inevitable, but the timing was partly triggered due to noticing that English speakers (and likely many other nationalities) are not able to easily read/hear/pronounce "Ciro".
Ciro's Edict #5 Staging server Updated 2025-07-16
After breaking production and sweating for a bit hotfixing (not that anyone uses the website yet), I decided to be smart and created a staging server: ourbigbook-staging.herokuapp.com. Now I can blow that server up as I wish without afecting users. Documented at: cirosantilli.com/ourbigbook/staging-deployment
Ciro's Edict #5 OurBigBook Library tested on PostgreSQL Updated 2025-07-16
After something broke on the website due to SQLite vs PostgreSQL inconsistencies and took me a day to figure it out, I finally decided to update the test system so that
OURBIGBOOK_POSTGRES=true npm test will run the tests on PostgreSQL.Originally, these were being run only on SQLite, which is the major use case for OurBigBook CLI, which came before the website.
There are unlisted articles, also show them or only show them.