Topics (254k) Articles (260k) Users (325) Discussions (237) Comments (383) Files (1k) New article
The Jump-and-Walk algorithm is a method primarily utilized in the context of graph exploration and network navigation. It is particularly effective in scenarios such as social network analysis, web crawling, and finding information in large data structures. ### Key Features of the Jump-and-Walk Algorithm: 1. **Hybrid Approach**: The algorithm combines two main strategies: "jumping" to a point in the graph (which can be thought of as a long-distance move) and "walking" through adjacent nodes locally.
Iteration is the process of repeating a set of instructions or operations until a specific condition is met or a desired outcome is achieved. It is a fundamental concept in mathematics and computer science, commonly used in algorithms, programming, and software development. In programming, iteration is often implemented using loops, such as: 1. **For loops**: Execute a block of code a specific number of times. 2. **While loops**: Continue to execute as long as a given condition remains true.
The term "Irish logarithm" is not widely recognized in standard mathematical terminology. It is possible that it refers to a concept used in a specific context or a colloquial term rather than a formalized mathematical function.
An in-place algorithm is a type of algorithm that requires a small and constant amount of extra space for its operations, aside from the space needed to store the input. This means that the algorithm transforms the input data without needing to create a copy of it or requiring additional data structures that scale with the input size. ### Characteristics of In-Place Algorithms: 1. **Space Efficiency**: They use only a fixed amount of extra space (e.g.
A hybrid algorithm is a computational approach that combines two or more distinct algorithms or techniques to leverage the strengths of each and improve overall performance or efficiency. Hybrid algorithms can be used in various fields, such as optimization, machine learning, image processing, and data analysis. The goal is to create a more robust solution that can perform better than any of the individual algorithms alone.
"Hub labels" can refer to different concepts depending on the context in which the term is used. However, it is not a widely recognized term in common domains such as technology, marketing, or data science. Here are two potential interpretations: 1. **In Data Visualization or Mapping**: Hub labels can refer to identifiers or names assigned to central points (hubs) in a network or geographical map.
"How to Solve It by Computer" is a book written by the mathematician and computer scientist Donald Knuth, published in 1974. The book is a foundational text in the field of computer science, focusing on algorithm analysis, programming techniques, and problem-solving strategies. In "How to Solve It by Computer," Knuth builds upon the problem-solving principles introduced in his earlier work, "How to Solve It," which addressed mathematical problem-solving.
The term "holographic algorithm" typically refers to a theoretical framework in computer science and mathematics that utilizes concepts from holography to solve certain computational problems more efficiently. Holographic algorithms are often associated with the fields of graph theory, optimization, and quantum computing. ### Key Concepts: 1. **Holography**: In physics, holography is a technique that records and reconstructs three-dimensional images, capturing information in a way that can be reconstructed from different perspectives.
The Hindley–Milner type system is a well-known type system used in functional programming languages, particularly those that support first-class functions and polymorphism. It was developed by Roger Hindley and Robin Milner in the 1970s and is the foundation for type inference in languages such as ML (Meta Language), Haskell, and others.
Higuchi dimension is a method for estimating the fractal dimension of a curve or time series. Developed by Takashi Higuchi in 1988, this approach is particularly useful for analyzing the complex patterns found in various types of data, such as biological signals, financial time series, and other phenomena that exhibit self-similarity. The Higuchi method works by constructing different approximations of the original data, effectively measuring how the length of the curve changes as the scale of the measurement changes.
Hall circles are a concept used in geometry and optics, particularly in the study of optical systems and the analysis of light rays and their behavior in mirrors and lenses. They are often associated with the analysis of reflective surfaces and can help in understanding the relationship between the object, image, and the optical system in use. The term "Hall circle" may also refer to specific circles or loci associated with optical elements that help in visualizing the paths of light rays and their intersections.
HAKMEM, short for "Hacks Memorandum," is a document created in 1972 at the MIT AI Lab. It comprises a collection of clever algorithms, mathematical tricks, and programming techniques that were of interest to computer scientists and programmers at the time. The document was co-authored by members of the lab, including Peter G. Neumark and other prominent figures in the computer science community.
The Gutmann method, also known as the Gutmann disk method, is a technique used in the field of computer science and data security for secure data deletion. It is particularly associated with the process of overwriting data on storage media to minimize the potential for data recovery after deletion. The Gutmann method specifically involves overwriting the data on a hard drive multiple times with a predetermined pattern of binary data.
The Generalized Distributive Law is a mathematical concept that extends the classical distributive law of multiplication over addition in algebra.
The Gale-Shapley algorithm, also known as the deferred acceptance algorithm, is a method for solving the stable marriage problem, which was first proposed by David Gale and Lloyd Shapley in their 1962 paper. The algorithm aims to find a stable matching between two equally sized sets—typically referred to as "men" and "women"—based on their preferences for each other.
The Flajolet-Martin algorithm is a probabilistic algorithm used for estimating the number of distinct elements in a large dataset (or stream of data). It is particularly useful in scenarios where storing all elements is impractical due to memory constraints. The algorithm leverages randomness and hashing to provide a count of unique elements with a probabilistic guarantee. ### Key Concepts: 1. **Hashing**: The algorithm uses a hash function to map elements to a fixed-size integer space.
An external memory algorithm is a type of algorithm designed to efficiently handle large data sets that do not fit into a computer's main memory (RAM). Instead, these algorithms are optimized for accessing and processing data stored in external memory, such as hard drives, SSDs, or other forms of secondary storage.
Enumeration algorithms are algorithmic techniques used to systematically explore a set of possible configurations or solutions to a problem, typically to find specific desired outcomes such as optimal solutions, feasible solutions, or to count possible configurations. These algorithms often generate all possible candidates and then identify those that meet specified criteria. ### Characteristics of Enumeration Algorithms: 1. **Exhaustiveness**: Enumeration algorithms typically aim to examine all possible options within the search space. This makes them exhaustive, ensuring that no potential solution is overlooked.
The term "emergent algorithm" can refer to various concepts across different fields, particularly in computer science, artificial intelligence, and complex systems, though it doesn't reference a single established algorithm or technique. Here are some contexts in which the concept of emergence in algorithms may be relevant: 1. **Swarm Intelligence**: Emergent algorithms often arise from the principles of swarm intelligence, where simple agents follow local rules that lead to complex and coordinated collective behavior.
EdgeRank was the algorithm used by Facebook to determine what content appears in users' News Feeds. Introduced in 2010, it aimed to improve user experience by ensuring that users saw the most relevant and engaging posts. The algorithm evaluates the relevance of content based on three main factors: 1. **Affinity:** This measures the relationship between the user and the content creator.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.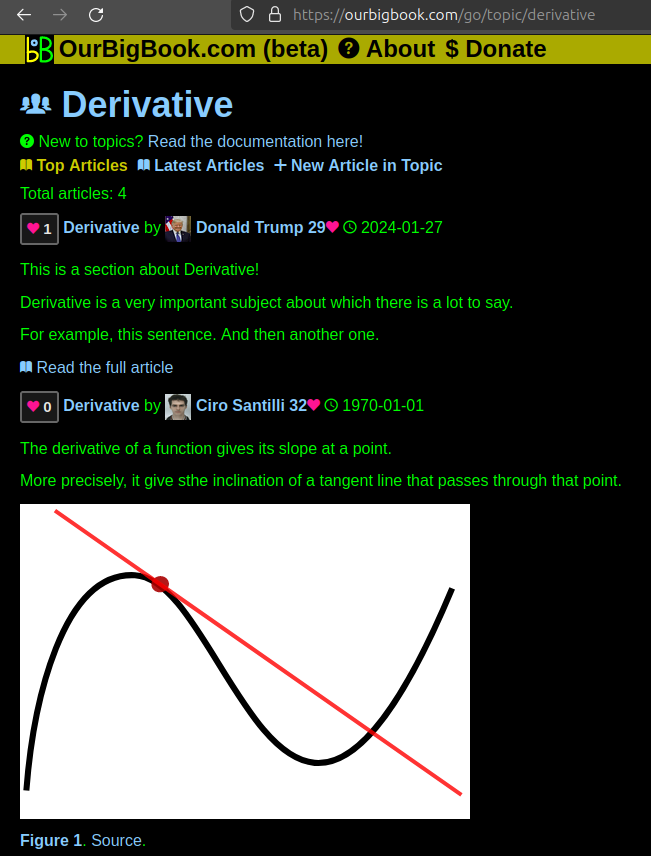
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.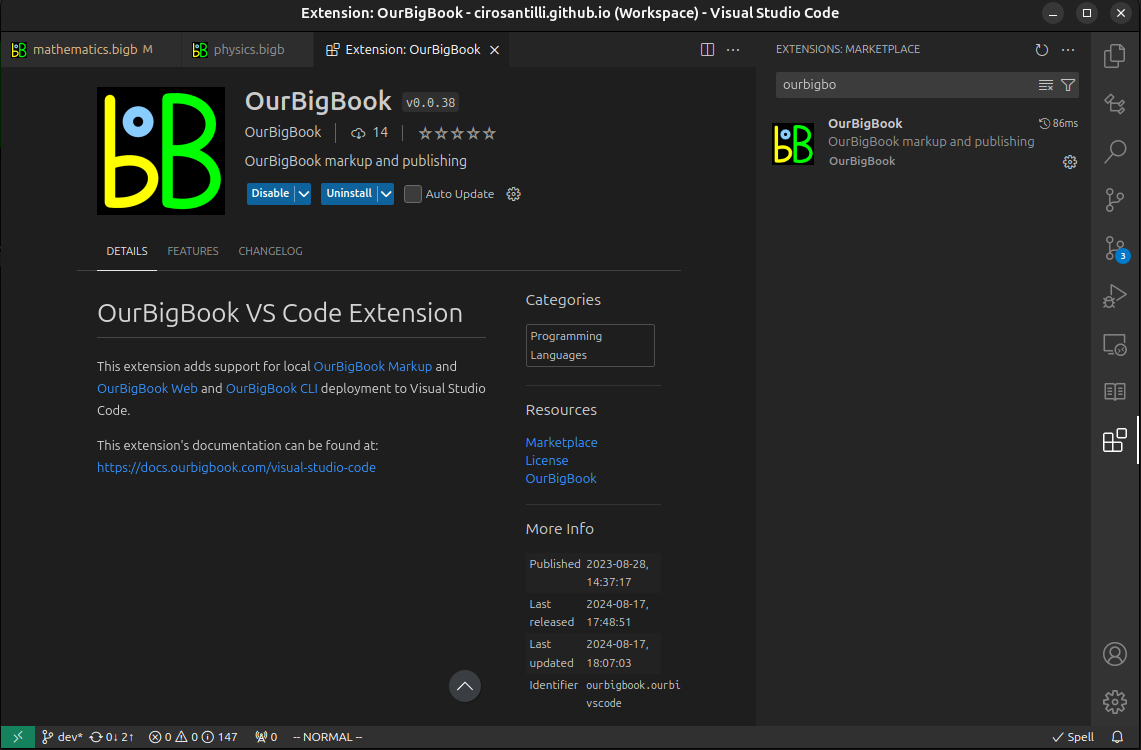
Figure 3. Visual Studio Code extension installation.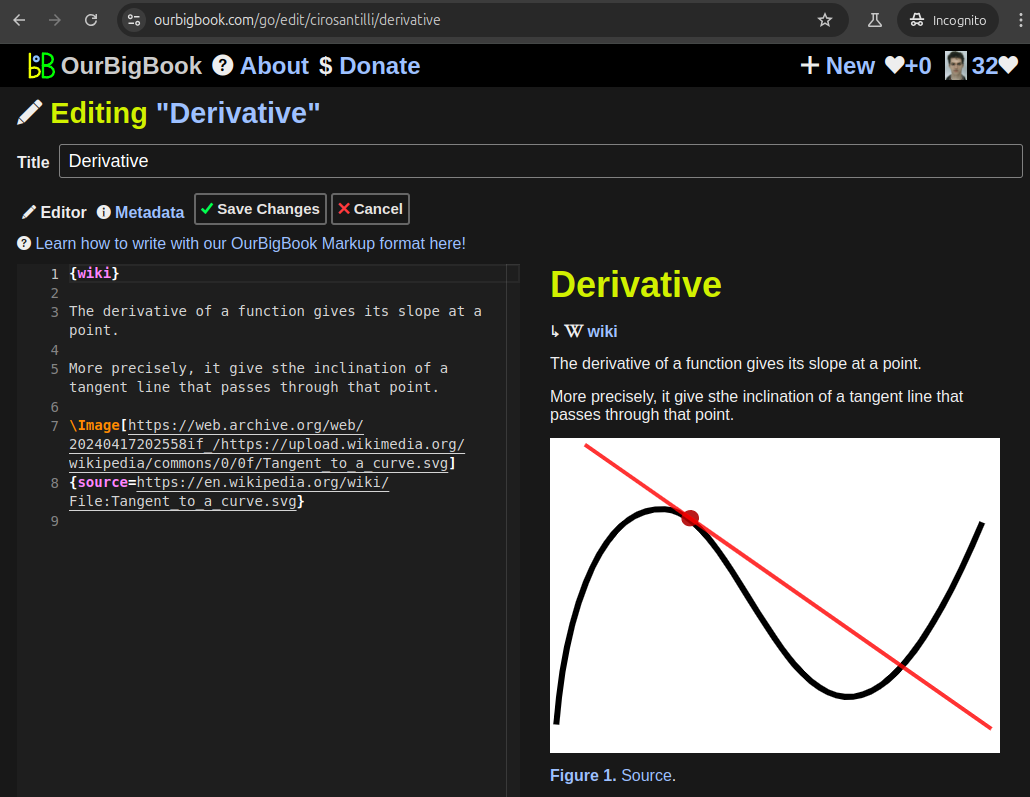
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 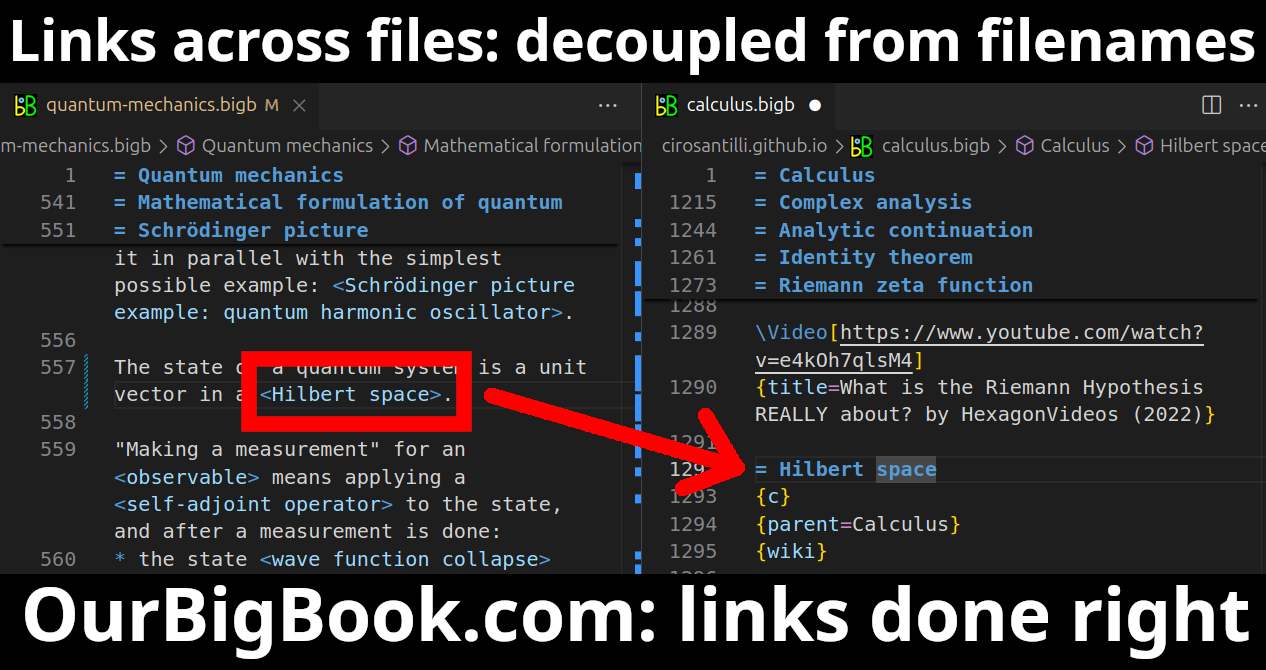
- Infinitely deep tables of contents:
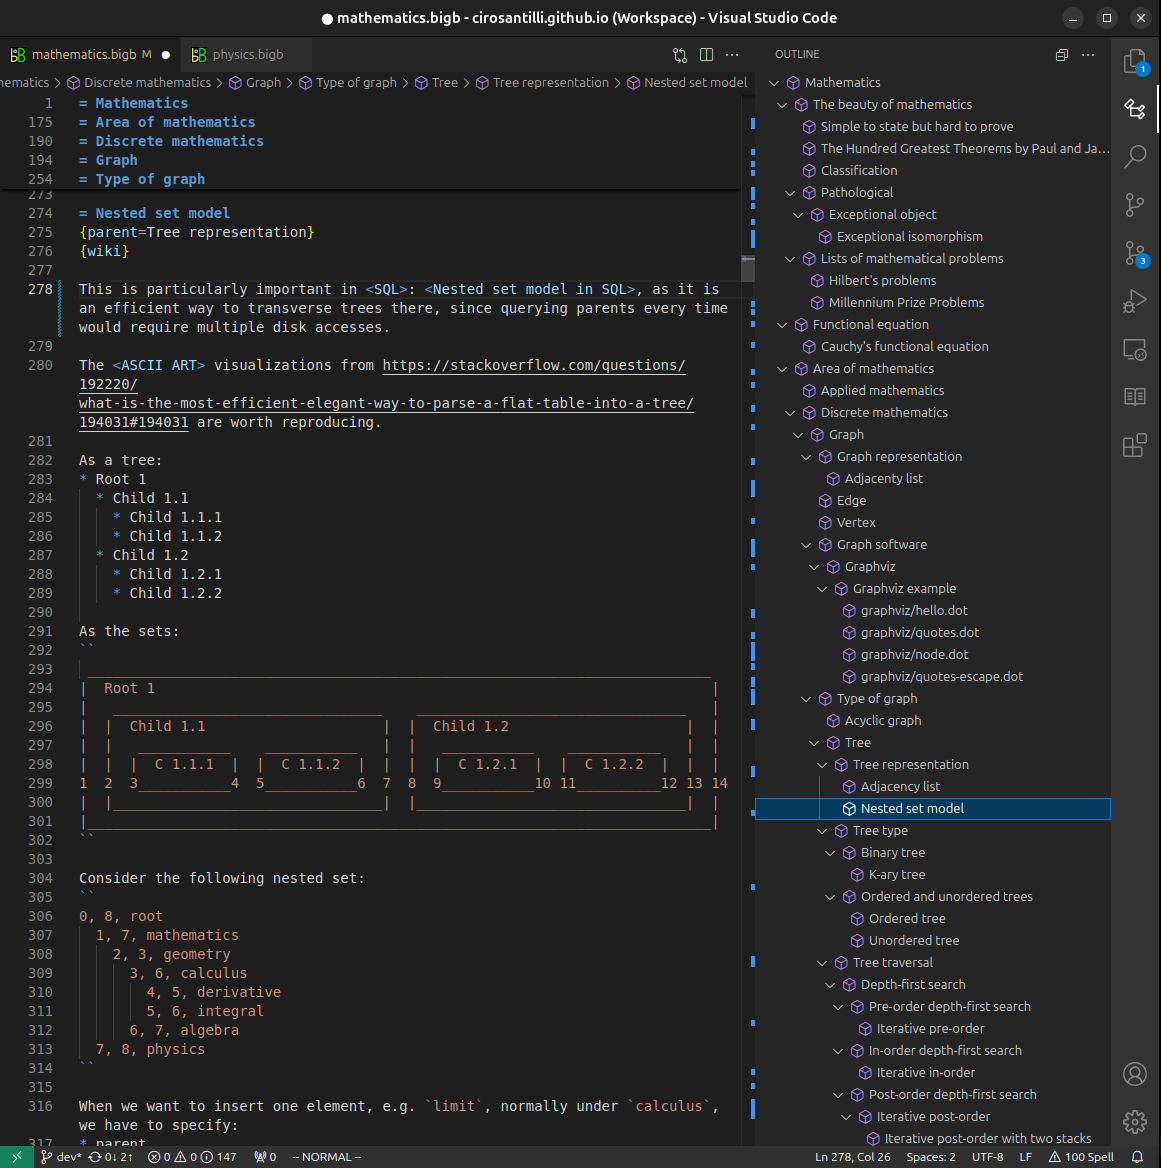
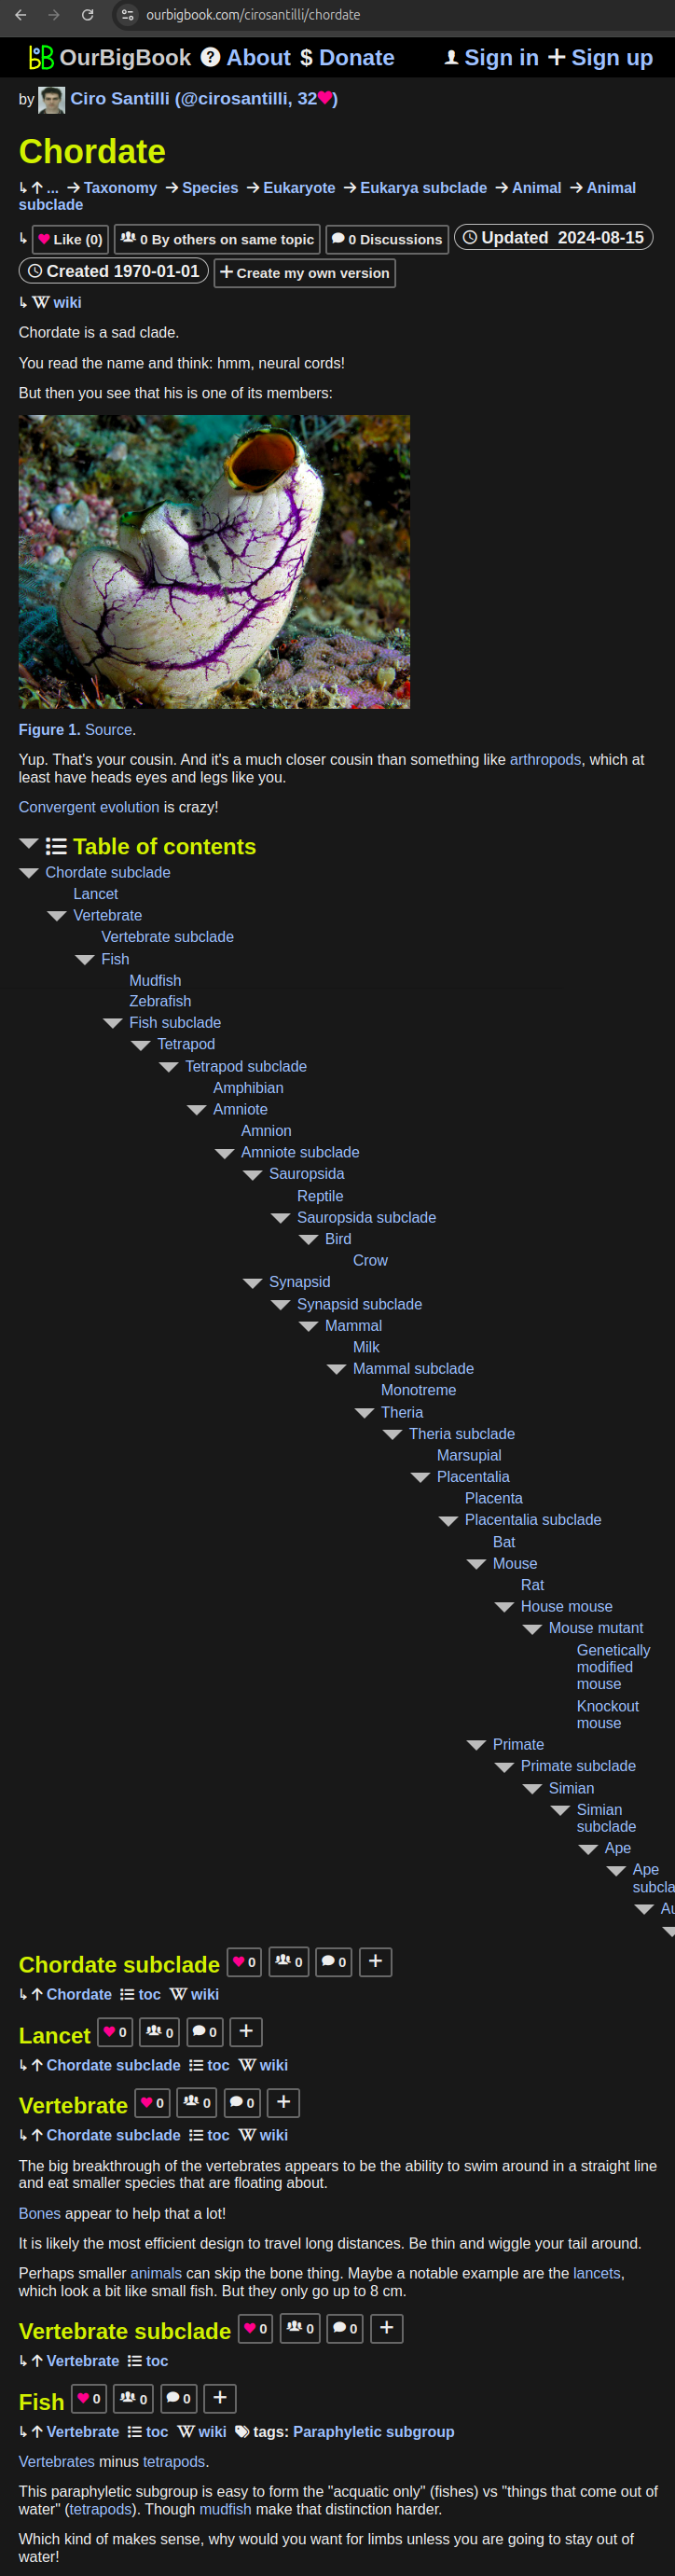
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact