Topics (266k) Articles (272k) Users (340) Discussions (237) Comments (383) Files (2k) New article
Their historic DNS and reverse DNS info was very valuable, and served as Ciro's the initial entry point to finding hits in the IP ranges given by Reuters.
Generic information about the website not specific on this project will be stored at: Section "viewdns.info".
Since this source is so scarce and valuable, we have been quite careful to note down all the domain and IP ranges that have been explored.
At news.ycombinator.com/item?id=38496244, the creator of the viewdns.info, "Hughesey", also stated that he'd able to give some free credits for public research projects such as this one. This would have saved up going to quite a few Cafes to get those sweet extra IPs! But it was more fun in hardmode, no doubt.
We do API access to IP ranges with this simple helper: ../cia-2010-covert-communication-websites/viewdns-info.sh, usage:e.g.:
./viewdns-info.sh <apikey> <start-ipv-address> <end-ipv-address>./viewdns-info.sh 8b890b00b17ed2d66bbed878d51200b58d43d014 66.45.179.187 66.45.179.210For domain to IP queries from the API you should use "iphistory" viewdns.info/api/docs/ip-history.php:
curl 'https://api.viewdns.info/iphistory/?domain=todaysengineering.com&apikey=$APIKEY&output=json'Just beware of the viewdns.info reverse IP bug, that really sucks and led to us missing a ton of domains.
D'oh.
But to be serious. The Wayback Machine contains a very large proportion of all sites. It does happen sometime that a Wayback Machine archive is missing or broken and cqcounter has the screenshot. But the Wayback Machine is still the most complete database we have found so far. Some archives are very broken. But those are rare.
The only problem with the Wayback Machine is that there is no known efficient way to query its archives across domains. You have to have a domain in hand for CDX queries: Wayback Machine CDX scanning.
The Common Crawl project attempts in part to address this lack of querriability, but we haven't managed to extract any hits from it.
CDX + 2013 DNS Census + heuristics however has been fruitful however.
We have dumped all Wayback Machine archives of known websites to: github.com/cirosantilli/cia-2010-websites-dump using ../cia-2010-covert-communication-websites/download-websites.sh. This allows for better grepping and serves as a backup in case they ever go down.
Like Binary search tree, but each node can have multiple objects and more than two children.

Google BigQuery alternative.
- quantumtech.blog/2023/01/17/quantum-computing-with-neutral-atoms/ OK this one hits it:So we understand that it is truly like the classical computer analog vs digital case.
As Alex Keesling, CEO of QuEra told me, "... whereas in gate-based [digital] quantum computing the focus is on the sequence of the gates, in analog quantum processing it's more about the position of the atoms and where you place them so they can mirror real life problems. We arrange the atoms and define the forces that drive them and then measure the result... so it’s a geometric encoding of the problem itself."
- thequantuminsider.com/2022/06/28/why-analog-neutral-atoms-quantum-computing-is-a-promising-direction-for-early-quantum-advantage on The Quantum Insider useless article mostly by Pasqal
TensorFlow quantum by Masoud Mohseni (2020)
Source. At the timestamp, Masoud gives a thought experiment example of the perhaps simplest to understand analog quantum computer: chained double-slit experiments with carefully calculated distances between slits. Calulating the final propability distribution of that grows exponentially.
- github.com/google-deepmind/pushworld 2023 Too combinatorial, gripping makes it so much easier to move stuff around in the real world. But cool nonetheless.

github.com/deepmind/lab/tree/master/game_scripts/levels/contributed/dmlab30 has some good games with video demos on YouTube, though for some weird reason they are unlisted.
TODO get one of the games running. Instructions: github.com/deepmind/lab/blob/master/docs/users/build.md. This may helpgithub.com/deepmind/lab/issues/242: "Complete installation script for Ubuntu 20.04".
It is interesting how much overlap some of those have with Ciro's 2D reinforcement learning games
Generative adversarial network illustrates well AI brittleness. The input looks obvious for a human, but gets completely misclassified by a deep learning agent.
Marek Rosa's play thing.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.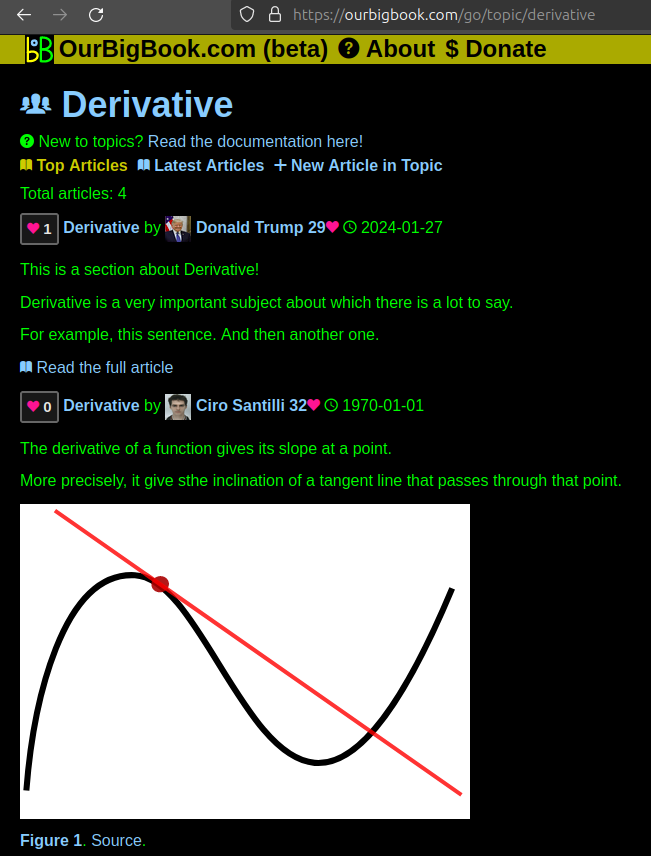
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.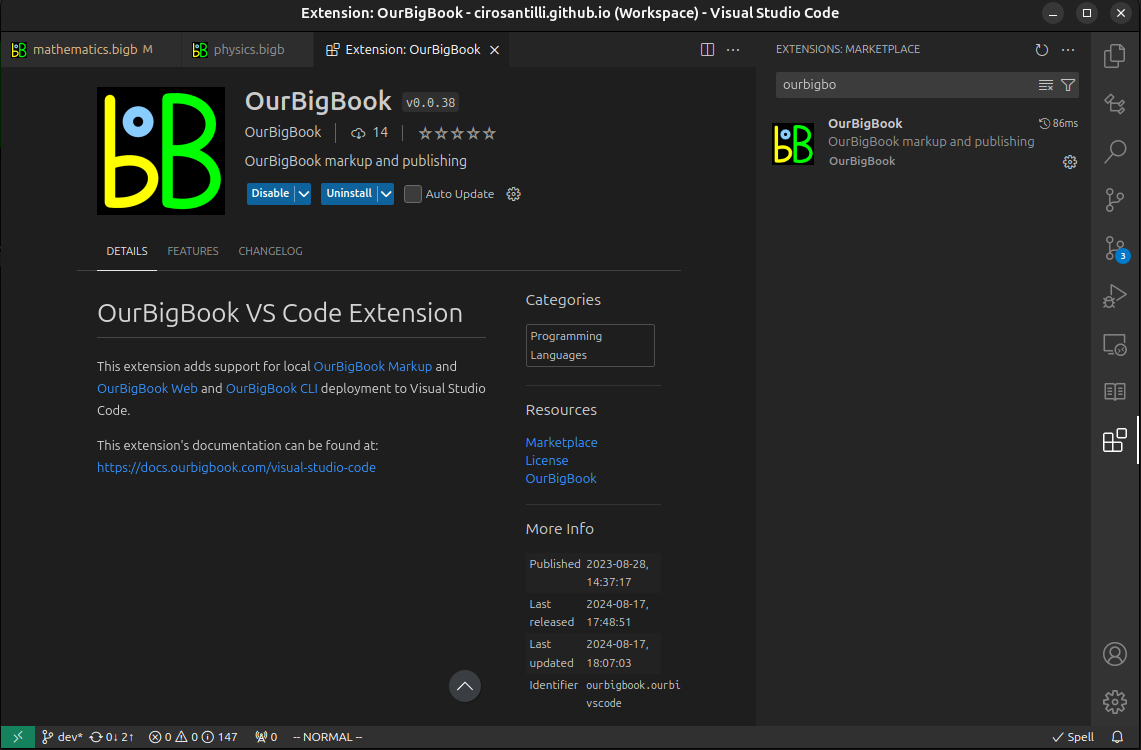
Figure 3. Visual Studio Code extension installation.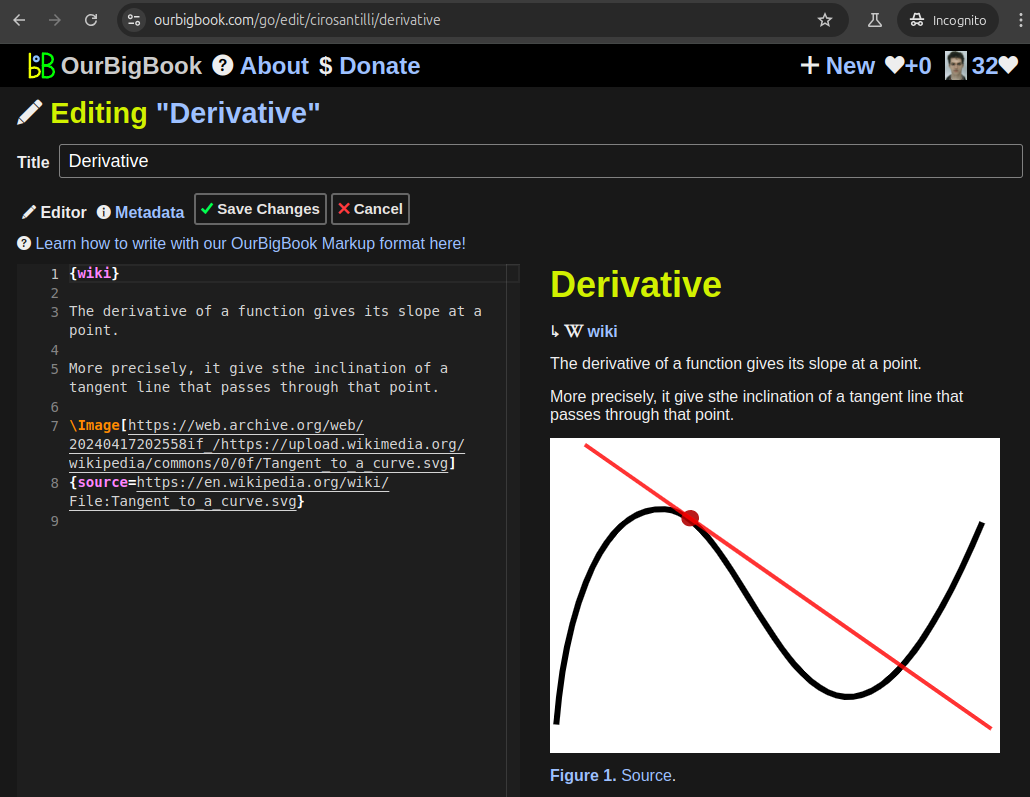
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 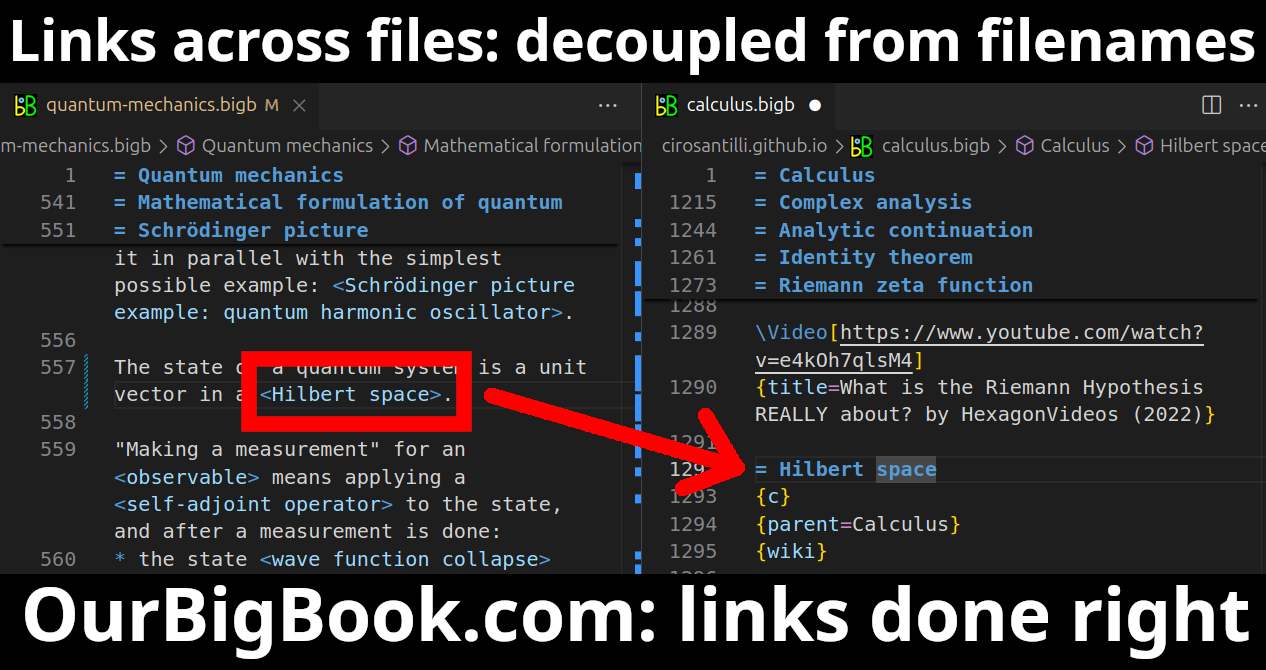
- Infinitely deep tables of contents:
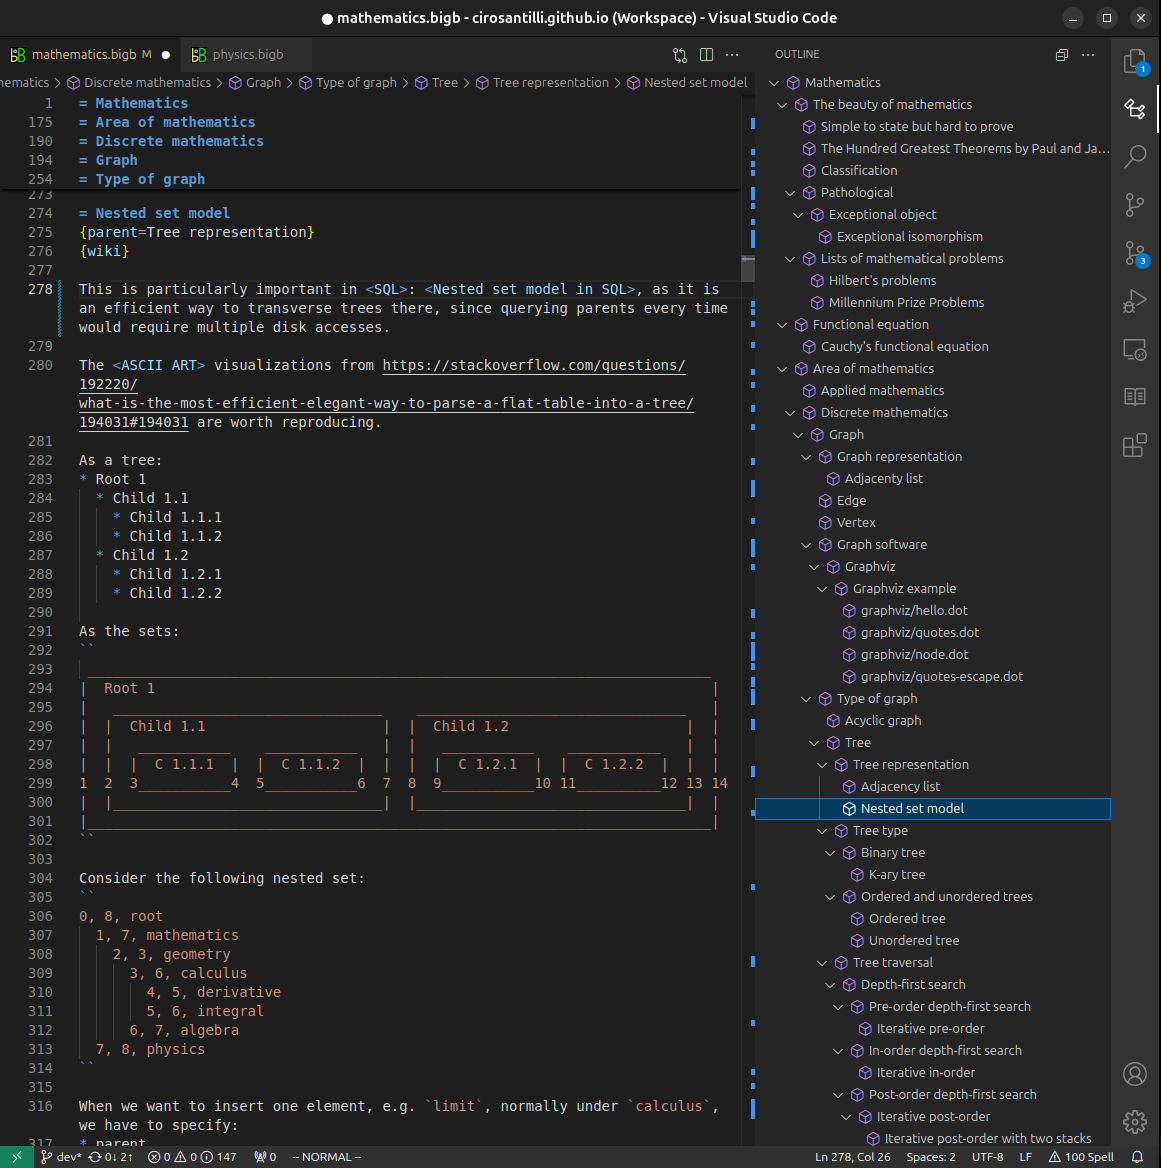
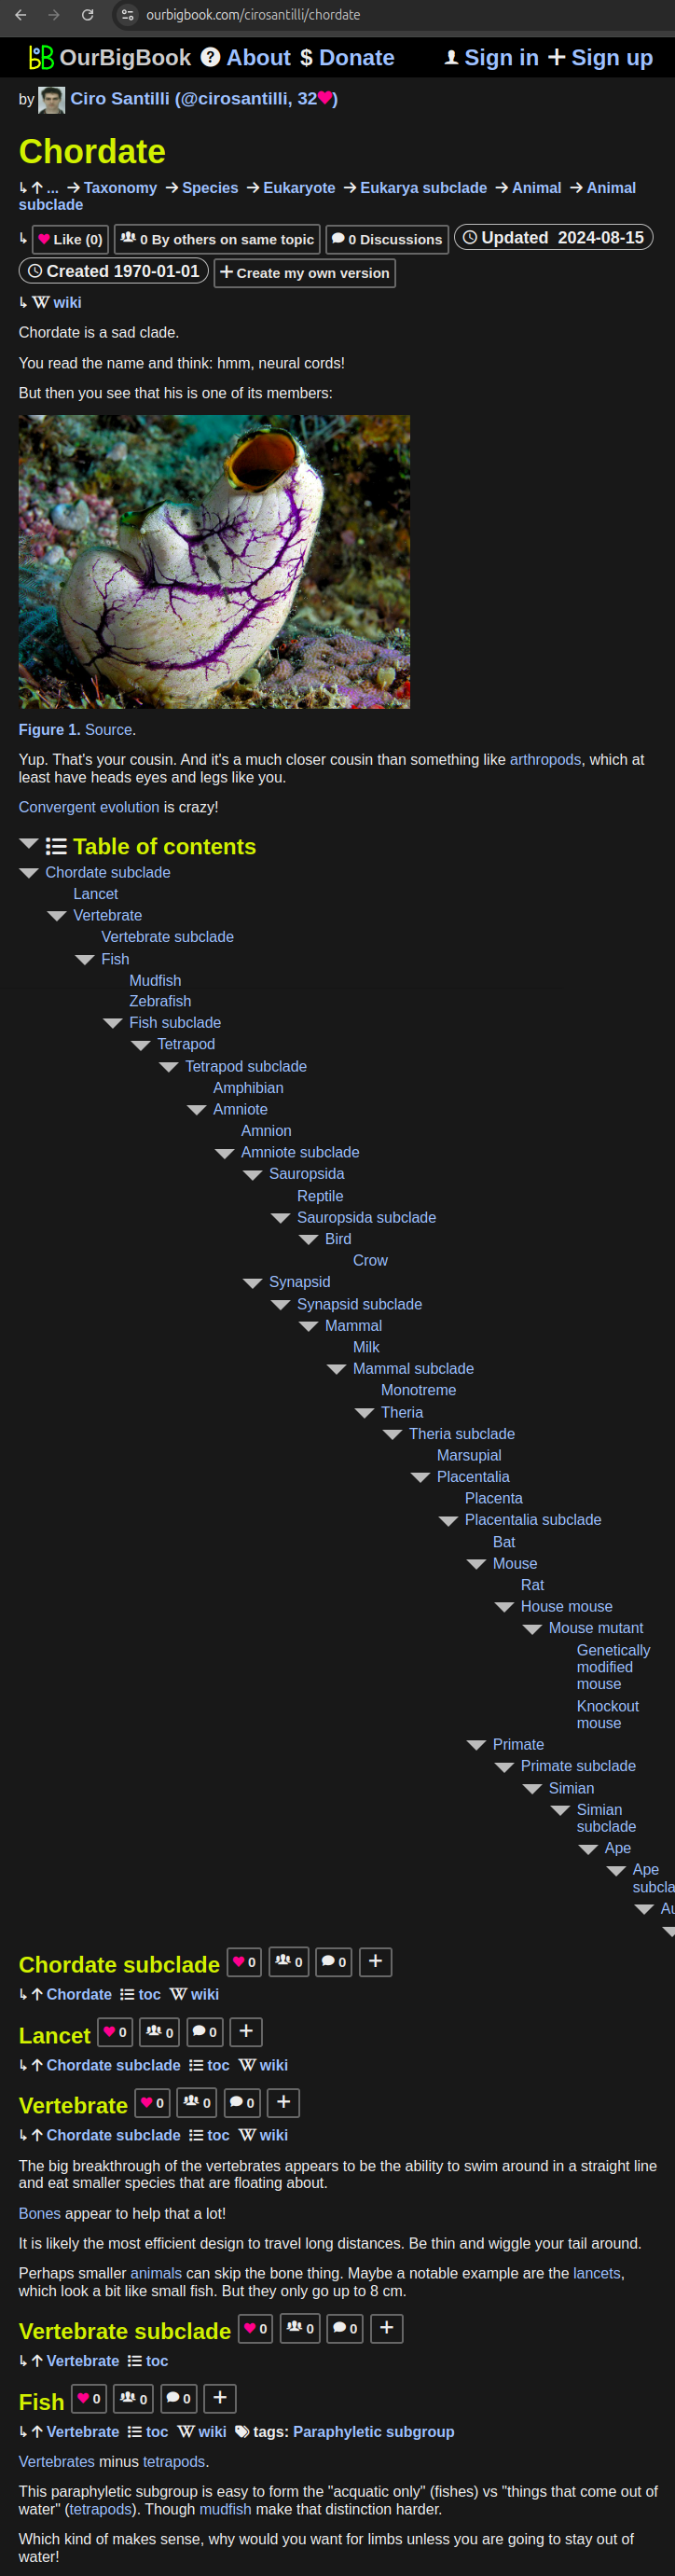

All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact