Topics (349k) Articles (361k) Users (412) Discussions (237) Comments (383) Files (12k) New article

A super-recursive algorithm is a concept that extends beyond classical recursive algorithms, which are typically defined as algorithms that call themselves to solve a problem. The distinction of super-recursive algorithms lies in their ability to perform computations in ways that are not limited to the traditional recursive framework.
Spreading activation is a cognitive science theory used primarily in the context of memory and semantic networks. It describes the process by which the activation of one concept or node in a network can lead to the activation of related concepts or nodes. This idea is often illustrated using a model of a network of interconnected nodes, each representing a different piece of information, idea, or concept.
Sparse Identification of Nonlinear Dynamics (SINDy) is a data-driven approach that aims to discover the governing equations of dynamical systems from time series data. It is particularly useful in fields such as fluid dynamics, robotics, biology, and economics, where the underlying governing equations may not be known or may be complex.
Snap rounding is a numerical rounding method used primarily in data processing and computational contexts. The general idea behind snap rounding is to simplify the representation of numbers by rounding them to a specified set of predefined values or "snap points." This can help in reducing the complexity of data, particularly in applications like computer graphics, data visualization, and statistical analysis. For example, in snap rounding, a number might be rounded to the nearest multiple of a certain value (like the nearest 0.1, 0.
Coupled DEVS (Discrete Event System Specification) is a formal modeling and simulation framework used to describe systems that can be represented as a network of interacting components (models). The DEVS formalism allows for hierarchical modeling, where components can be either atomic or coupled models. Coupled models consist of multiple atomic models that can communicate with each other, thereby simulating complex systems.
Atomic DEVS (Discrete Event System Specification) is a modeling formalism that allows for the representation of discrete event systems. Simulation algorithms for Atomic DEVS are techniques used to simulate models defined using the DEVS formalism. Here’s a brief overview of the key concepts and components: ### DEVS Framework - **Atomic DEVS**: It is the basic building block of the DEVS formalism.
The Sieve of Pritchard is a relatively lesser-known algorithm in number theory used for finding prime numbers. It is named after mathematician J. W. Pritchard, who introduced this technique. The sieve method is a general approach for finding primes, which includes more famous algorithms like the Sieve of Eratosthenes.
The Sieve of Eratosthenes is an ancient algorithm used to find all prime numbers up to a specified integer. It is efficient and straightforward, making it one of the most popular methods for generating a list of primes. Here's how it works: 1. **Initialization**: Start with a list of consecutive integers from 2 to a specified number \( n \) (the upper limit).
The Shapiro-Senapathy algorithm is a method used in the field of data classification and clustering, particularly for analyzing and processing time series data. It is named after its creators, Dr. Walter Shapiro and Dr. P. R. Senapathy. The algorithm is designed to identify patterns and trends within data, making it useful for various applications, including financial analysis, signal processing, and any context where temporal data is examined.
A sequential algorithm is a type of algorithm in which the steps are executed in a linear or sequential order, one after the other. This means that the algorithm progresses step by step, and each step must be completed before the next one can begin. Sequential algorithms are straightforward to understand and implement because they follow a clear and predictable path. ### Characteristics of Sequential Algorithms: 1. **Deterministic**: For a given input, a sequential algorithm will always produce the same output.
The Sardinas–Patterson algorithm is a procedure used in computer science and mathematics for determining the solvability of a word problem in free groups and, more generally, in certain algebraic structures. Specifically, it's a method that helps decide whether a given set of equations over free groups has a solution in that group. ### Overview The algorithm works by analyzing a set of words (or strings) representing elements of a free group.
Run to completion scheduling is a scheduling policy primarily used in computing and real-time systems where a task is allowed to run to its completion without being preempted by other tasks or processes. This means that once a task starts executing, it is not interrupted until it has finished running.
Run-time algorithm specialization refers to the process of optimizing algorithms based on specific properties or inputs known at run-time, rather than at compile-time. This approach allows the system to tailor its behavior dynamically based on the characteristics of the data being processed, leading to improved performance and efficiency.
The "right to explanation" refers to the concept that individuals should have the ability to understand the decisions made about them by automated systems, particularly in the context of artificial intelligence (AI) and machine learning. This right is particularly associated with the General Data Protection Regulation (GDPR) in the European Union, specifically Article 22, which addresses automated individual decision-making.
Reservoir sampling is a family of randomized algorithms used to sample a fixed number of elements from a population of unknown size. It's particularly useful when the total number of items is large or potentially infinite, and it allows you to select a representative sample without needing to know the size of the entire dataset. ### Key Characteristics of Reservoir Sampling: 1. **Stream Processing**: It allows for sampling elements from a stream of data where the total number of elements is not known in advance.
Rendezvous hashing, also known as highest random weight (HRW) hashing, is a technique used in distributed systems for load balancing and resource allocation. The primary goal of Rendezvous hashing is to efficiently distribute keys (or objects) across a set of nodes (or servers) while minimizing the need to redistribute keys when there are changes in the system, such as adding or removing nodes.
Regulation of algorithms refers to the policies, laws, and guidelines that govern the development, deployment, and use of algorithms, particularly in contexts where they significantly impact individuals and society. This can include algorithms used in areas like finance, healthcare, criminal justice, social media, and more. As algorithms increasingly influence decisions and behaviors, concerns arise regarding fairness, accountability, transparency, and privacy.
Randomized rounding is an algorithmic technique often used in the context of approximation algorithms and integer programming. It is particularly useful for dealing with problems where one needs to convert a fractional solution (obtained from solving a linear relaxation of an integer programming problem) into a feasible integer solution, while maintaining a certain level of optimality. ### Overview: 1. **Linear Relaxation**: In integer programming, the objective is to find integer solutions to certain optimization problems.
Proof of Authority (PoA) is a consensus mechanism used in blockchain networks that relies on a limited number of pre-approved validators or nodes to validate transactions and create new blocks. Unlike Proof of Work (PoW) or Proof of Stake (PoS), which require significant resources and can be decentralized, PoA focuses on the reputation and identity of the validators.
The Predictor-Corrector method is a numerical technique used for solving ordinary differential equations (ODEs). It is particularly useful for initial value problems, where the goal is to find a solution that satisfies the equations over a specified range of values. The method consists of two main steps: 1. **Predictor Step**: In this first step, an initial estimate of the solution at the next time step is calculated using an approximation method.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.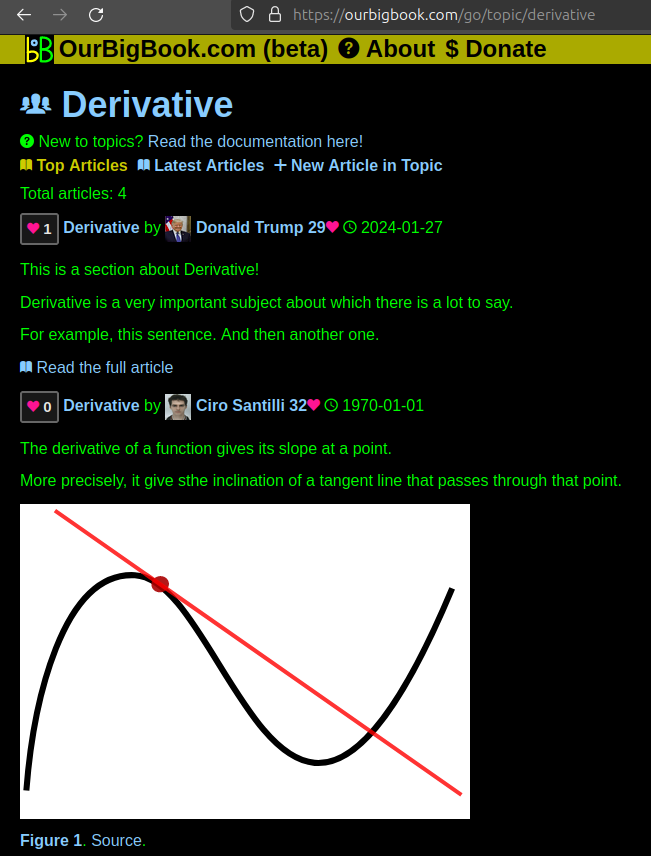
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
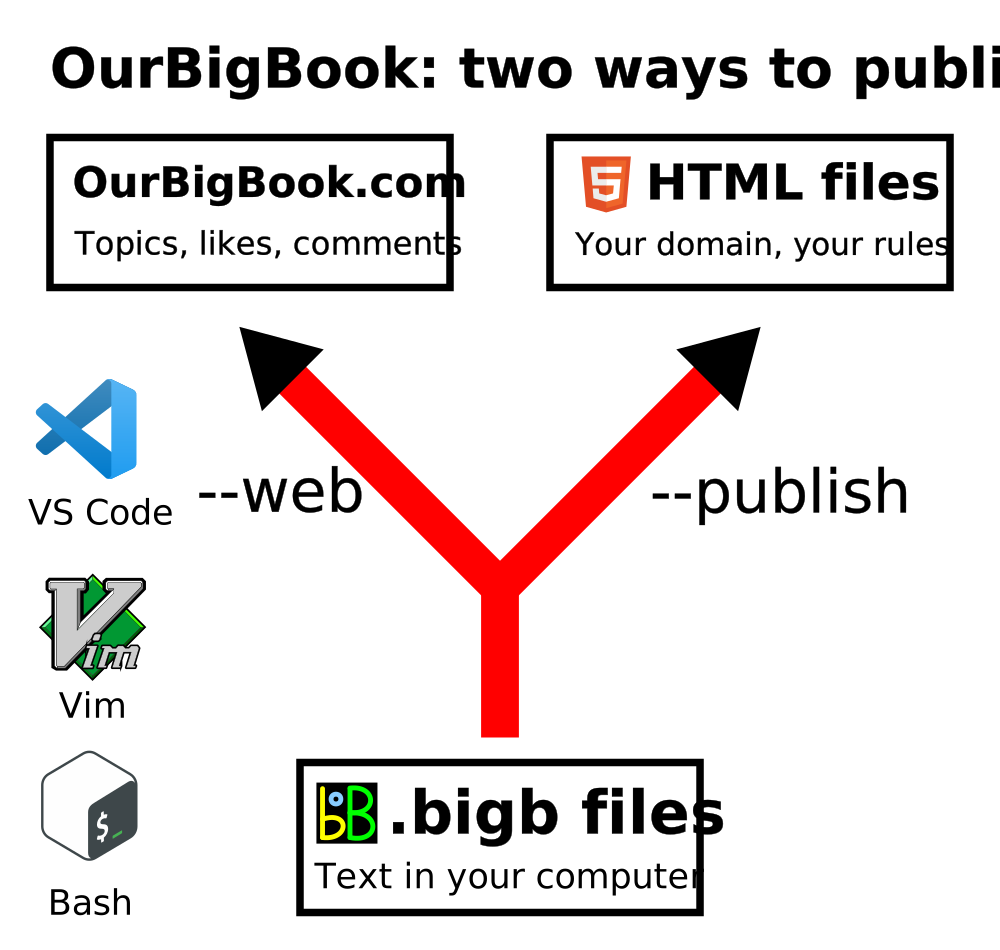
Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.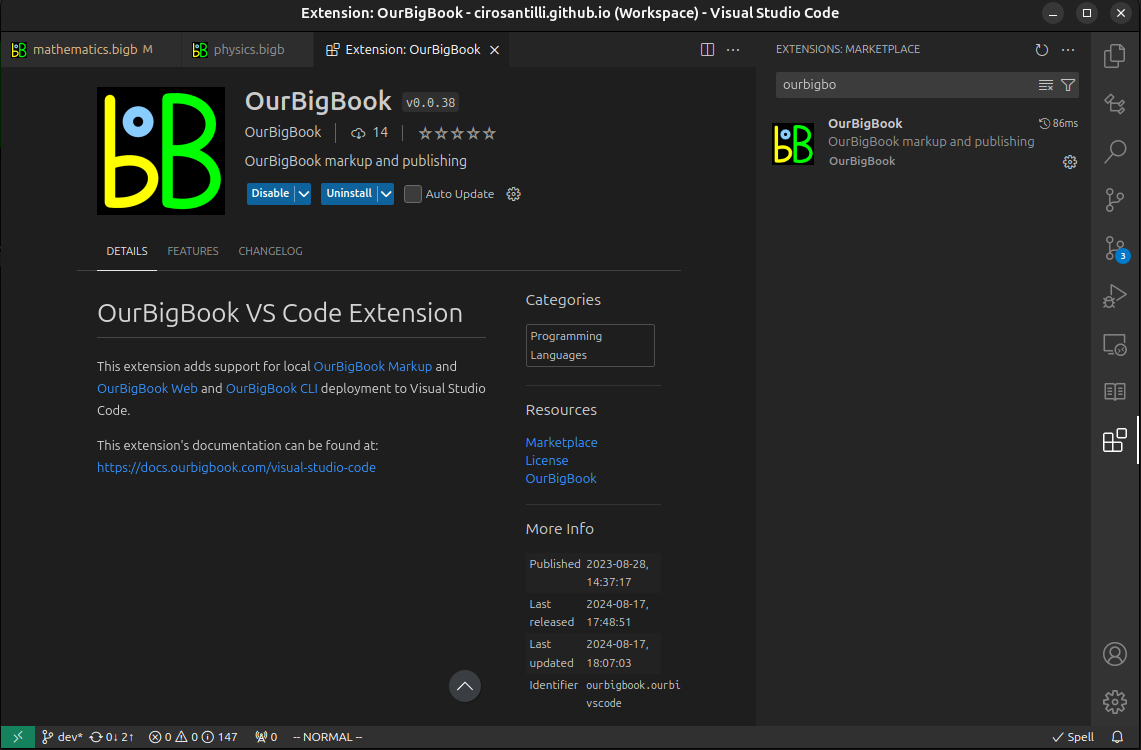
Figure 3. Visual Studio Code extension installation.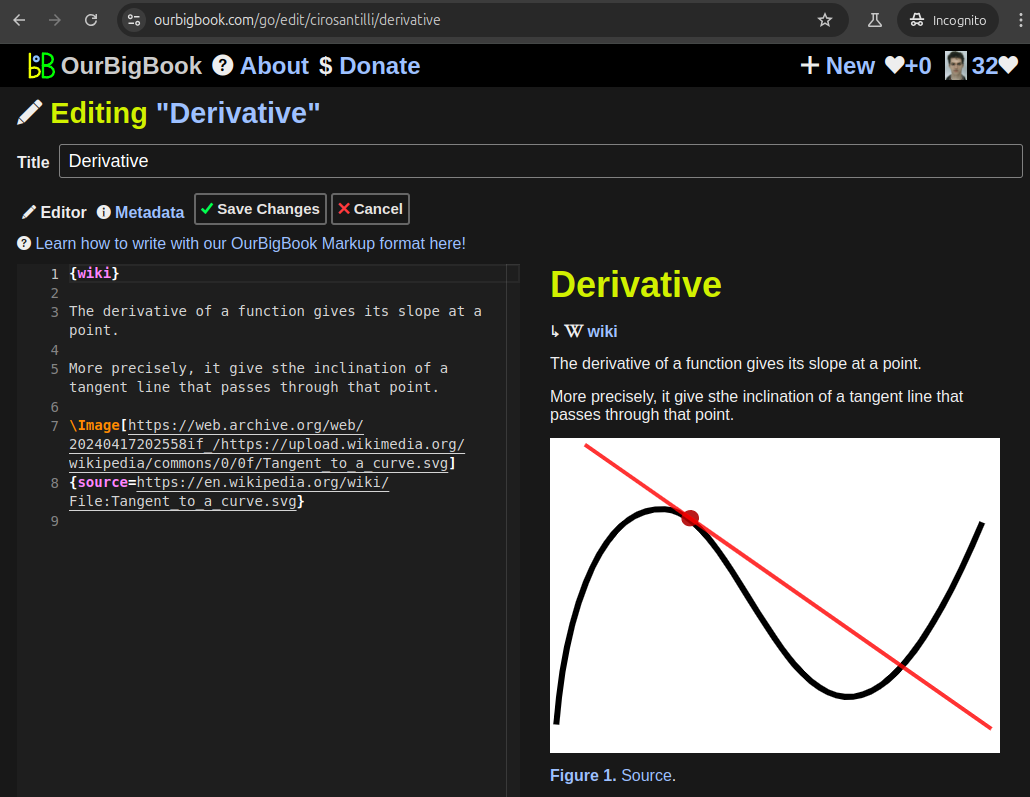
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 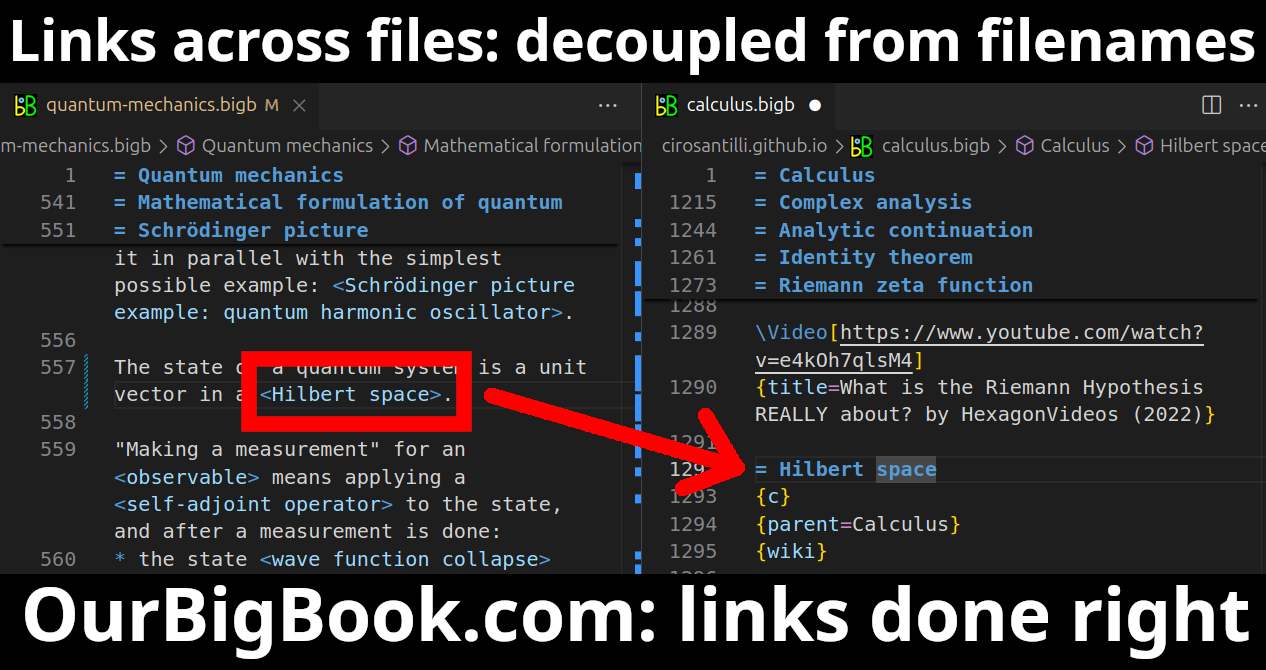
- Infinitely deep tables of contents:
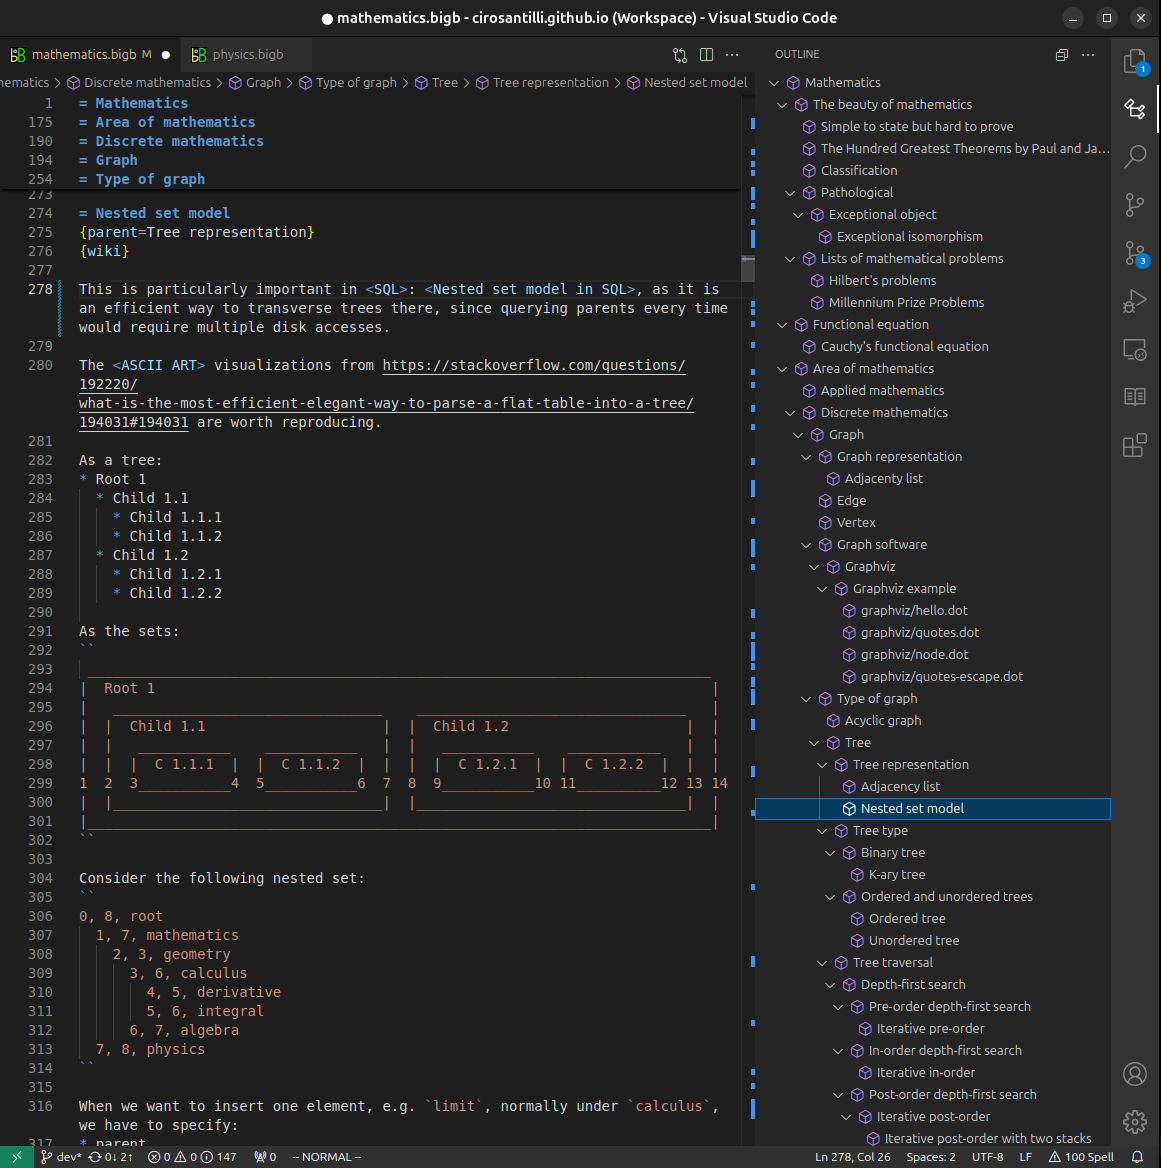
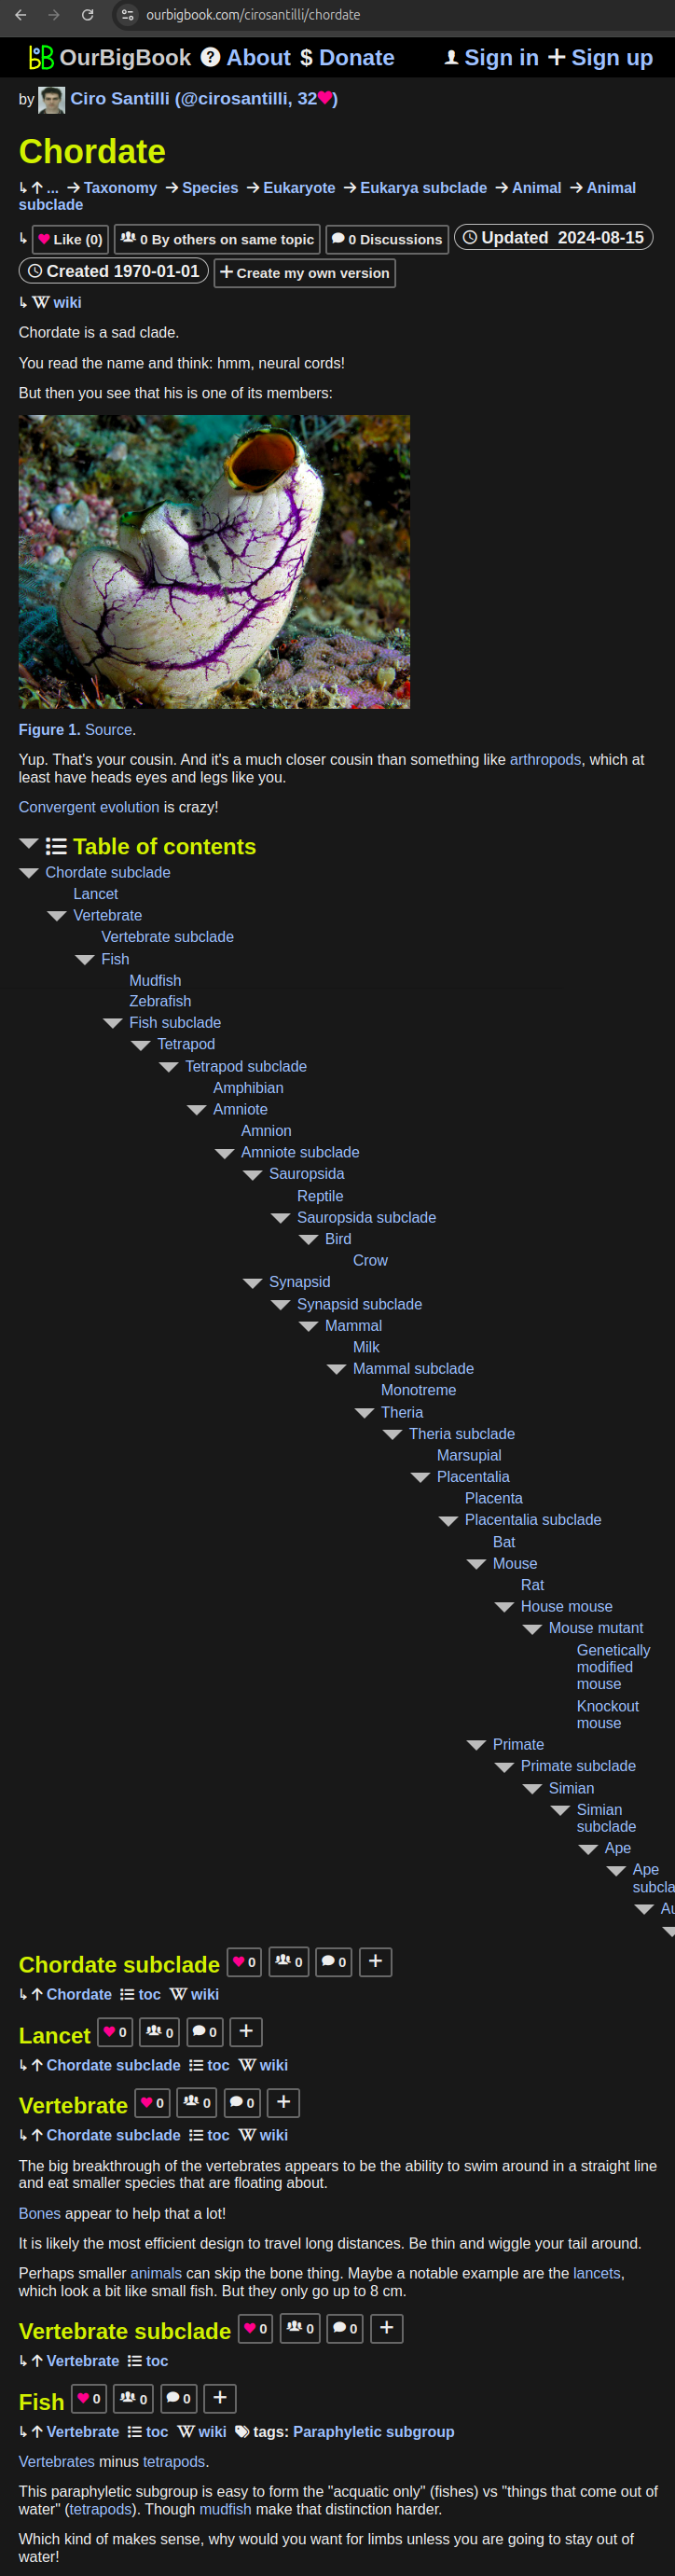
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact