Topics (374k) Articles (387k) Users (410) Discussions (242) Comments (383) Files (12k) New article

Hall circles are a concept used in geometry and optics, particularly in the study of optical systems and the analysis of light rays and their behavior in mirrors and lenses. They are often associated with the analysis of reflective surfaces and can help in understanding the relationship between the object, image, and the optical system in use. The term "Hall circle" may also refer to specific circles or loci associated with optical elements that help in visualizing the paths of light rays and their intersections.
HAKMEM, short for "Hacks Memorandum," is a document created in 1972 at the MIT AI Lab. It comprises a collection of clever algorithms, mathematical tricks, and programming techniques that were of interest to computer scientists and programmers at the time. The document was co-authored by members of the lab, including Peter G. Neumark and other prominent figures in the computer science community.
The Gutmann method, also known as the Gutmann disk method, is a technique used in the field of computer science and data security for secure data deletion. It is particularly associated with the process of overwriting data on storage media to minimize the potential for data recovery after deletion. The Gutmann method specifically involves overwriting the data on a hard drive multiple times with a predetermined pattern of binary data.
The Generalized Distributive Law is a mathematical concept that extends the classical distributive law of multiplication over addition in algebra.
The Gale-Shapley algorithm, also known as the deferred acceptance algorithm, is a method for solving the stable marriage problem, which was first proposed by David Gale and Lloyd Shapley in their 1962 paper. The algorithm aims to find a stable matching between two equally sized sets—typically referred to as "men" and "women"—based on their preferences for each other.
The Flajolet-Martin algorithm is a probabilistic algorithm used for estimating the number of distinct elements in a large dataset (or stream of data). It is particularly useful in scenarios where storing all elements is impractical due to memory constraints. The algorithm leverages randomness and hashing to provide a count of unique elements with a probabilistic guarantee. ### Key Concepts: 1. **Hashing**: The algorithm uses a hash function to map elements to a fixed-size integer space.
An external memory algorithm is a type of algorithm designed to efficiently handle large data sets that do not fit into a computer's main memory (RAM). Instead, these algorithms are optimized for accessing and processing data stored in external memory, such as hard drives, SSDs, or other forms of secondary storage.
Enumeration algorithms are algorithmic techniques used to systematically explore a set of possible configurations or solutions to a problem, typically to find specific desired outcomes such as optimal solutions, feasible solutions, or to count possible configurations. These algorithms often generate all possible candidates and then identify those that meet specified criteria. ### Characteristics of Enumeration Algorithms: 1. **Exhaustiveness**: Enumeration algorithms typically aim to examine all possible options within the search space. This makes them exhaustive, ensuring that no potential solution is overlooked.
The term "emergent algorithm" can refer to various concepts across different fields, particularly in computer science, artificial intelligence, and complex systems, though it doesn't reference a single established algorithm or technique. Here are some contexts in which the concept of emergence in algorithms may be relevant: 1. **Swarm Intelligence**: Emergent algorithms often arise from the principles of swarm intelligence, where simple agents follow local rules that lead to complex and coordinated collective behavior.
EdgeRank was the algorithm used by Facebook to determine what content appears in users' News Feeds. Introduced in 2010, it aimed to improve user experience by ensuring that users saw the most relevant and engaging posts. The algorithm evaluates the relevance of content based on three main factors: 1. **Affinity:** This measures the relationship between the user and the content creator.
The Driver Scheduling Problem (DSP) is an optimization problem commonly encountered in the transportation and logistics industries. It involves creating efficient schedules for drivers or operators to maximize productivity while meeting various constraints and requirements. The problem is critical for industries such as public transportation, freight delivery, ride-sharing services, and any operation that requires managing a fleet of vehicles and personnel. ### Key Elements of the Driver Scheduling Problem: 1. **Drivers**: The available workforce that needs to be assigned to vehicles or routes.
Domain reduction is a concept commonly encountered in fields such as constraint satisfaction problems (CSPs), optimization, and artificial intelligence, particularly in relation to problems where the goal is to find solutions that satisfy specific constraints among variables. ### Overview of Domain Reduction Algorithm A domain reduction algorithm is used to simplify the problem-solving process by reducing the possible values that variables can take.
Divide-and-conquer is a fundamental algorithm design paradigm characterized by three main steps: 1. **Divide**: The problem is divided into smaller subproblems, ideally of roughly equal size. These subproblems are similar in nature to the original problem but smaller in scope. 2. **Conquer**: Each of the subproblems is solved individually. If the subproblems are still too large or complex, they can be further divided and solved recursively.
Distributed tree search refers to a computational method used to solve problems that can be represented as trees, leveraging a distributed system to improve efficiency and scalability. It is commonly employed in fields like artificial intelligence, operations research, and optimization problems, particularly in contexts where the search space is large. In a typical tree search, nodes represent states or decisions, and branches represent the possible actions or transitions between these states.
The Devex algorithm is a method used in operations research and linear programming to solve network flow problems, particularly in relation to the transportation and assignment problems. It is an iterative algorithm that adjusts the flow within a network to find the optimal allocation of resources such that the cost is minimized or profit is maximized.
"DONE" can refer to various concepts depending on the context. Here are a few interpretations: 1. **General Term**: In everyday language, "done" means something has been completed or finished. For example, "I am done with my homework" indicates that the homework task is complete. 2. **Project Management**: In project management, "done" often relates to completed tasks or milestones. It's essential for tracking progress and ensuring that all criteria for completion have been met.
Communication-avoiding algorithms are a class of algorithms designed to minimize the communication overhead that occurs when data is transferred between different processing units, such as between CPUs and GPUs, or between nodes in a distributed or parallel computing environment. These algorithms are particularly important in high-performance computing (HPC) and large-scale data processing scenarios, where communication can become a significant bottleneck, leading to lower overall performance.
The "collision problem" can refer to various scenarios across different fields, but it is most commonly discussed in contexts such as computer science, particularly in hashing algorithms, and in physics, particularly with regard to objects in motion. 1. **Computer Science (Hashing)**: In the context of hashing, a collision problem occurs when two different inputs (e.g., strings, files, or data records) produce the same hash value in a hash function.
Collective operations are functions that facilitate communication and coordination between multiple processes in parallel computing environments, such as those found in high-performance computing (HPC) and distributed systems. These operations allow processes to work together efficiently instead of individually, enabling them to share data and synchronize their actions. Collective operations typically involve a group of processes and can include: 1. **Broadcast**: One process sends data to all other processes in the group.
Collaborative diffusion refers to the process by which ideas, innovations, technologies, or practices are shared and spread through collaborative efforts among various individuals, organizations, or communities. This concept often emphasizes the role of teamwork, partnerships, and collective action in the adoption and adaptation of new concepts or technologies. Key aspects of collaborative diffusion include: 1. **Co-Creation**: Individuals and groups work together to develop and refine ideas, leading to more tailored and effective solutions.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.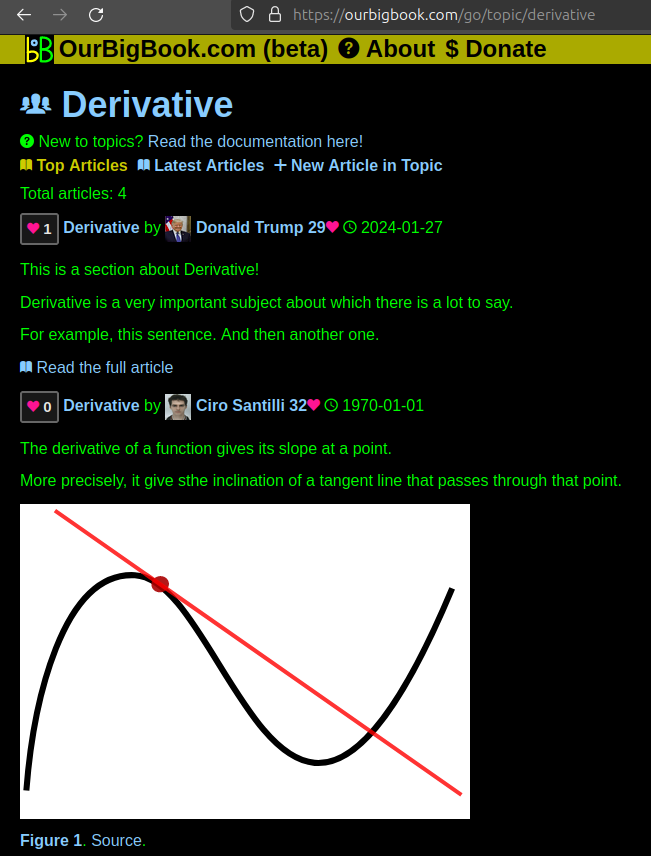
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
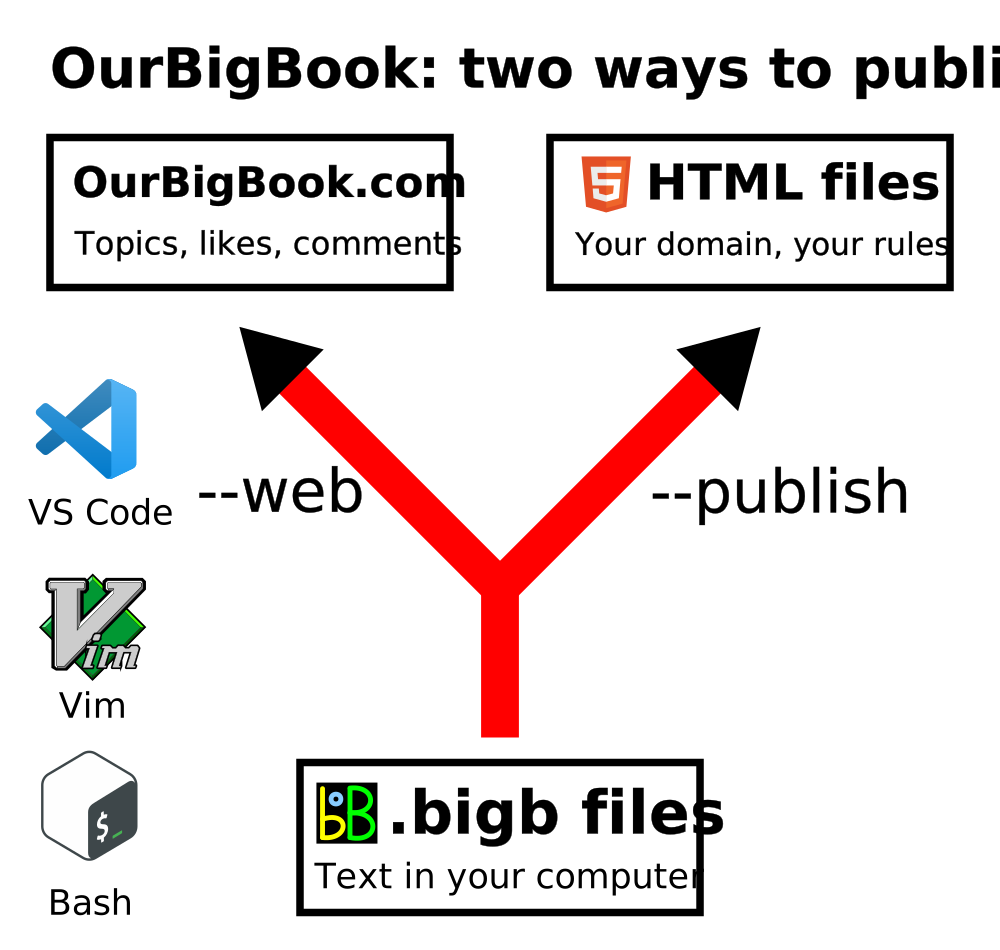
Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.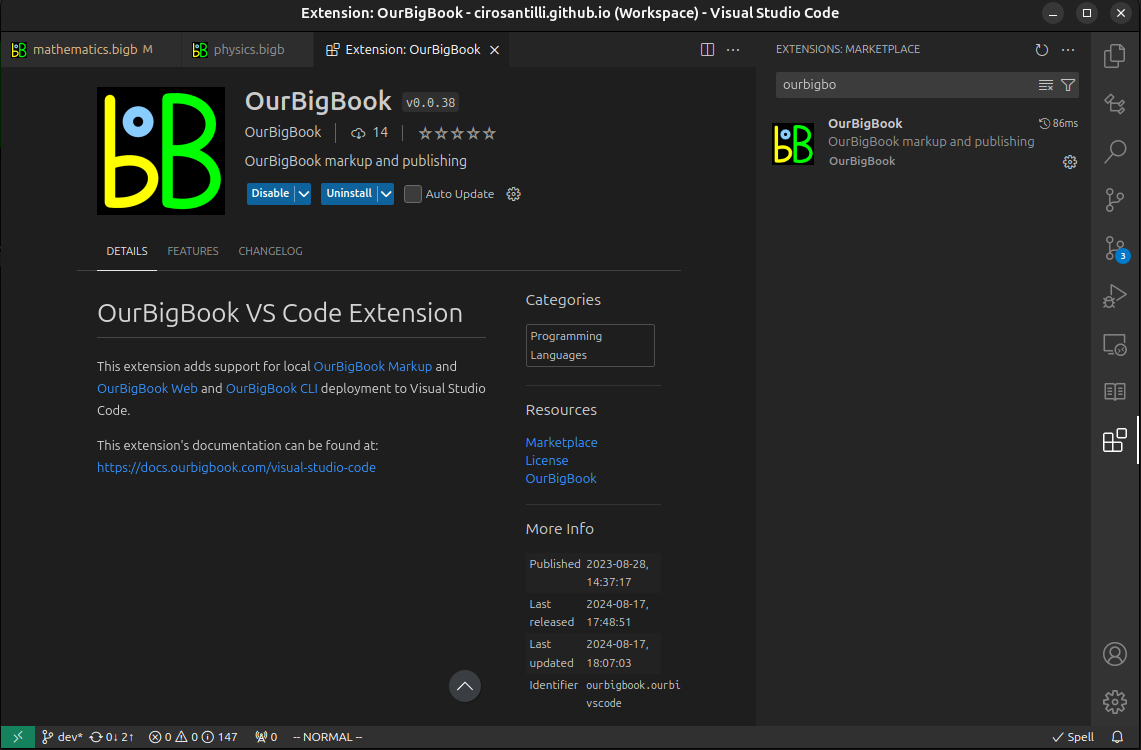
Figure 3. Visual Studio Code extension installation.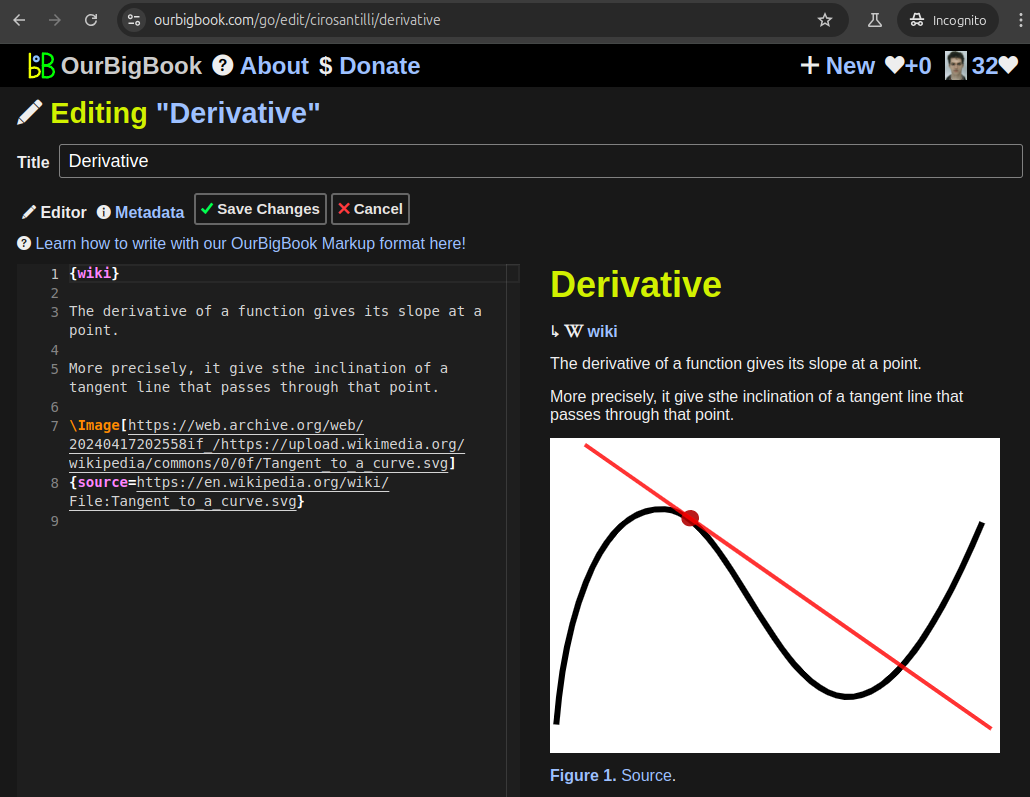
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 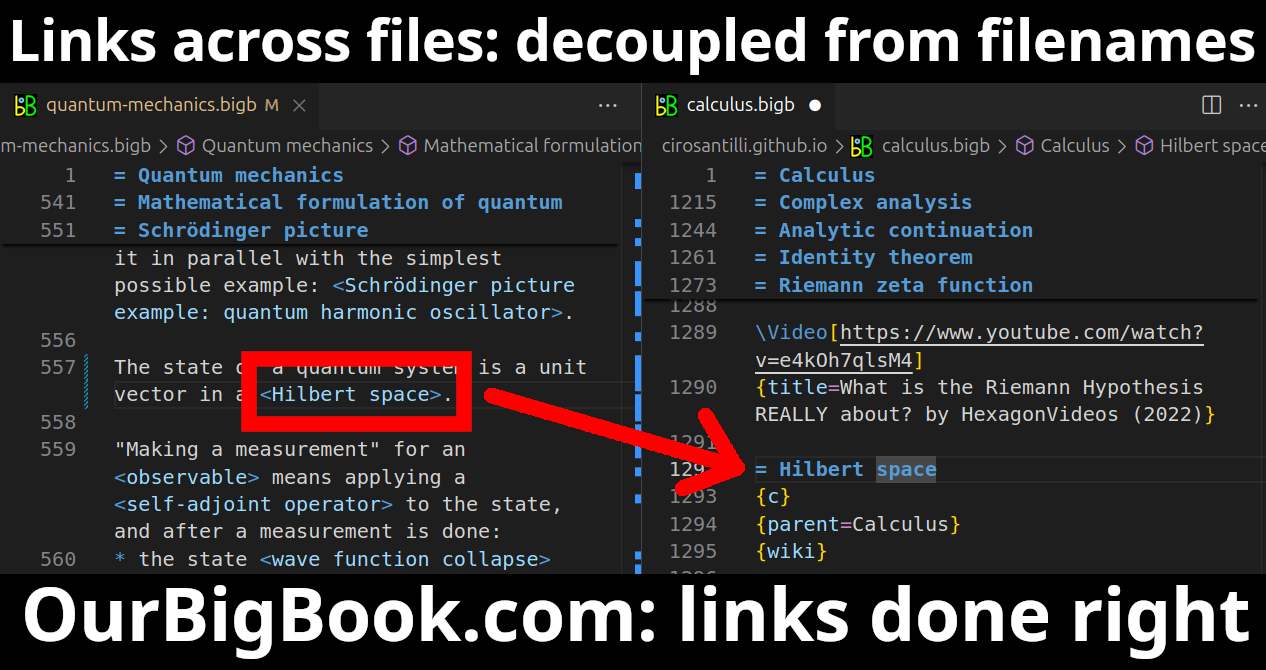
- Infinitely deep tables of contents:
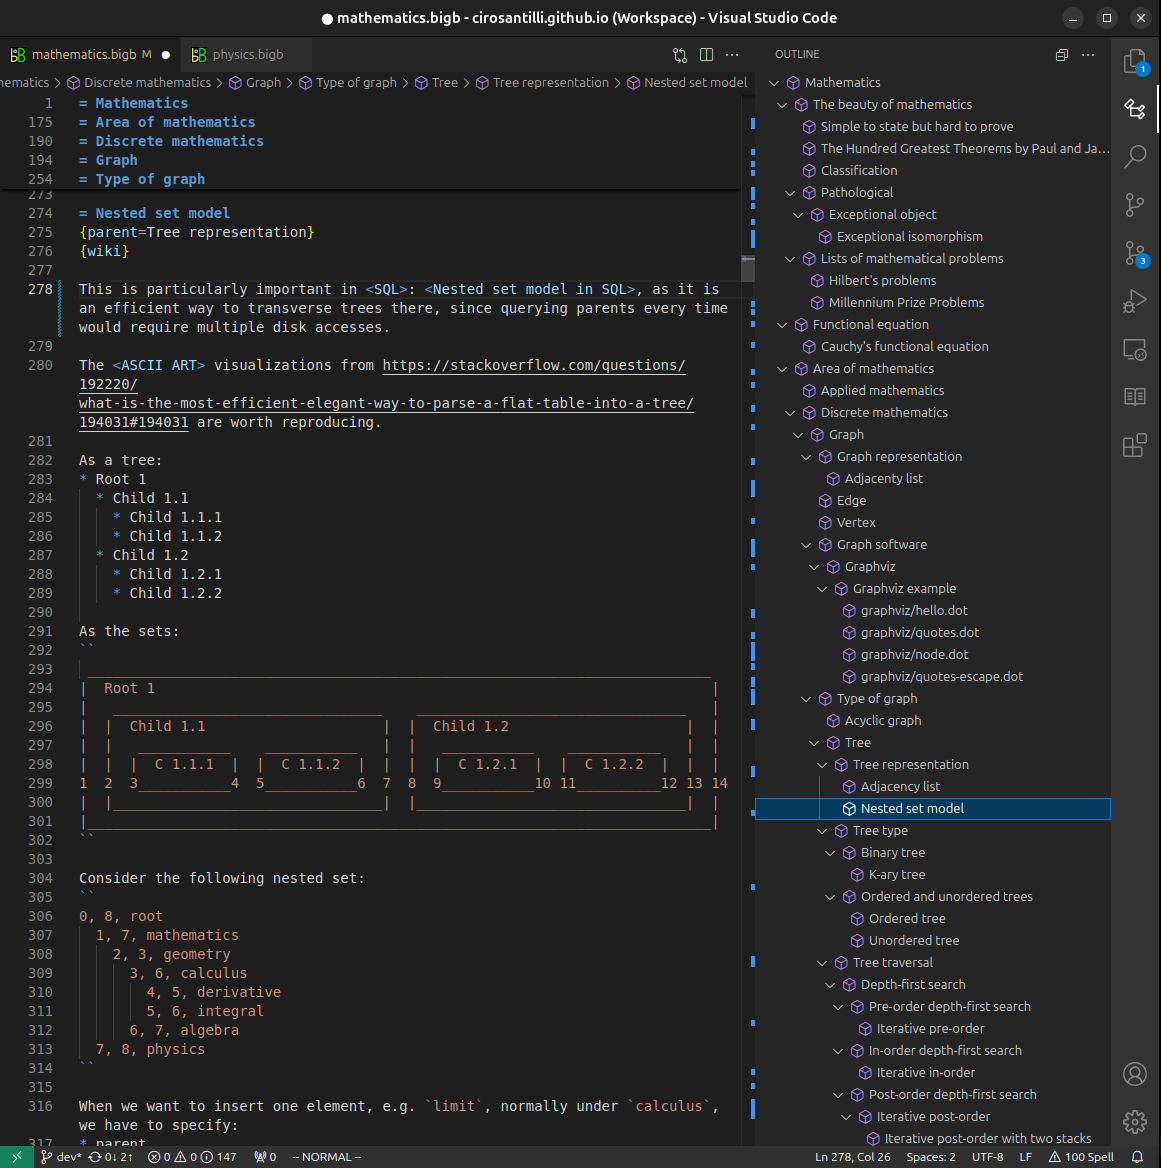
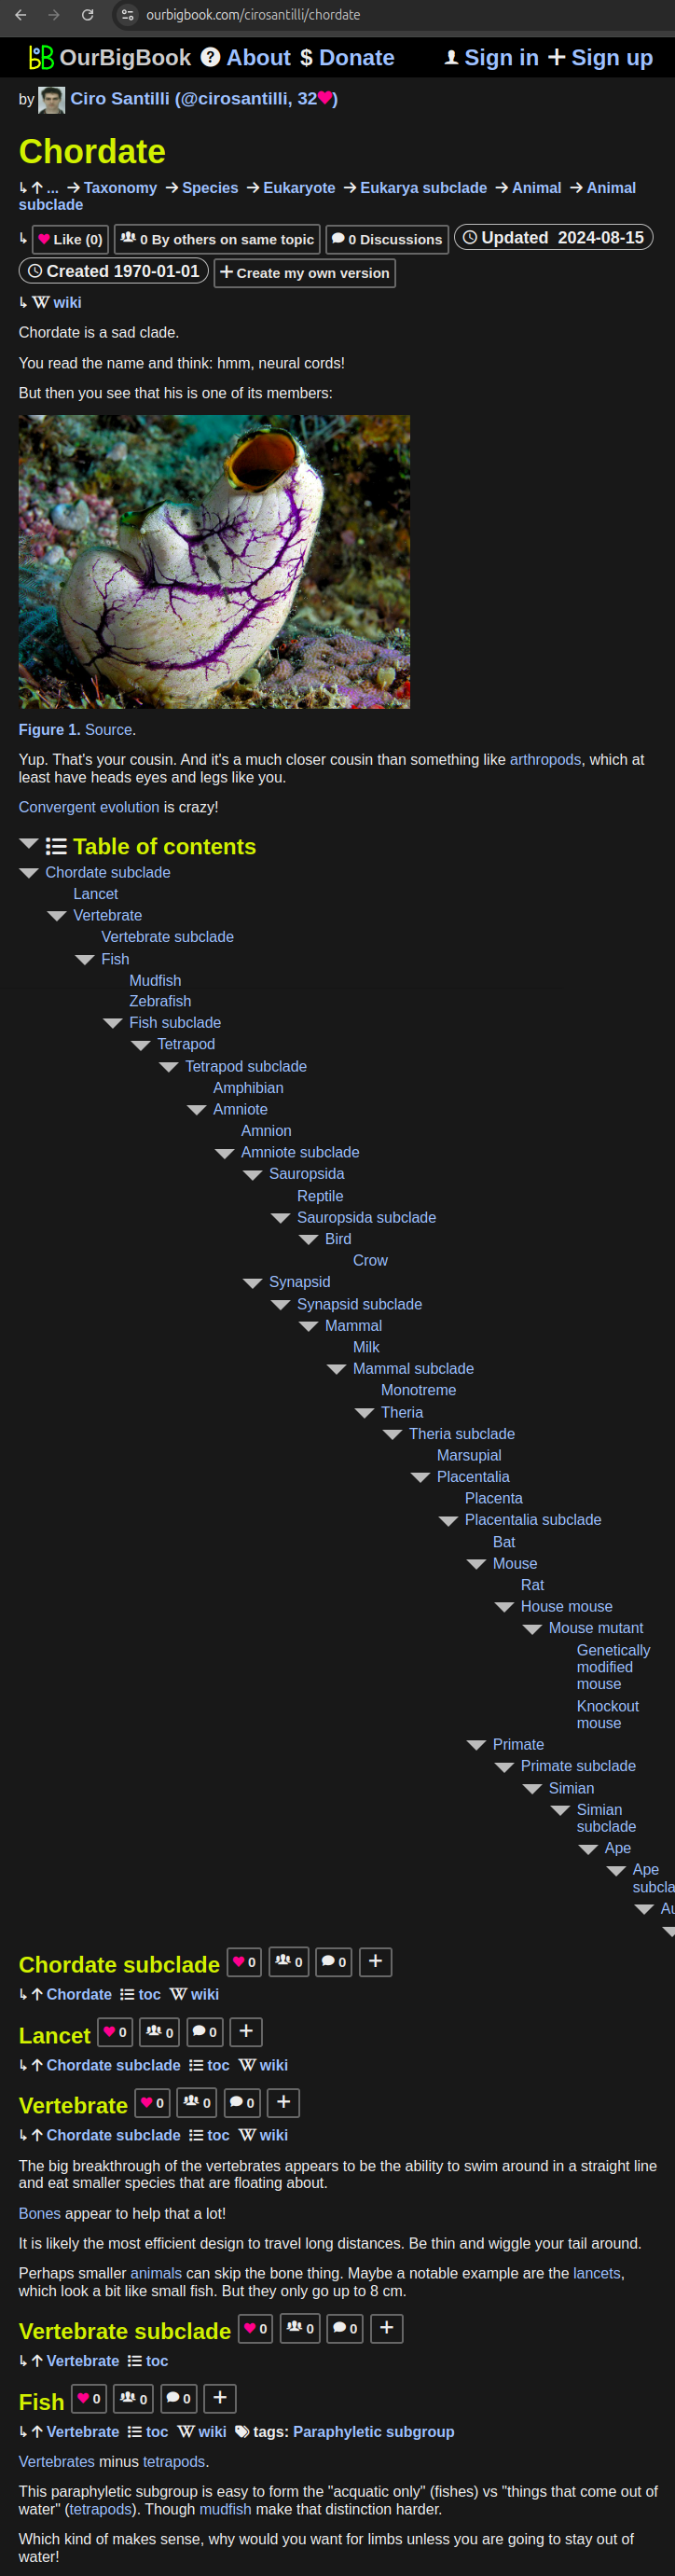
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact