Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 47 2 a Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
For an integrable real function , let . For every measurable region ,The first term is nonnegative because there, and the integral subtracted in the second term is nonpositive. Hence the negative set minimizes the integral. Including or excluding any points where has no effect; changes on null sets do not matter either. This is the minimum-integral decision region principle. Integrability ensures the subtraction is defined, and it holds automatically for the weighted differences of probability density functions used below.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 47 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14At equal spacing , the adjacent increments of an affine mean profile are all . Their differences are therefore zero. Define the matrix whose row associated with the interior time has coefficients in columns . ThenConversely these equations make all adjacent first differences equal, so is affine in , equivalently affine in the equally spaced times. Thus the restriction is exactly , not just a necessary condition. Its null space has basis and , so has rank .
For and , the second-difference test of a linear mean profile is the Hotelling test of linear hypotheses withReject the affine-profile hypothesis when the scaled statistic exceeds its level- upper F-distribution critical value. This removes the nuisance intercept and slope without estimating them separately.
For unequal ordered distinct times, put and replace each second-difference row by the adjacent-slope contrastIts three coefficients are , and . Vanishing means all adjacent slopes agree, again giving null space and rank . Use this new in the same statistic and null distribution. For , every mean profile at distinct times is affine, so there is no lack-of-linearity restriction to test.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 47 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Transform each observation to . If has full row rank , the transformed sample is multivariate normal with mean and positive-definite covariance matrix . Its sample mean is and its unbiased sample covariance matrix is . The Hotelling test of linear hypotheses therefore usesHere is required. Reject for a large scaled statistic using the relevant upper F-distribution quantile. If the rows of are dependent, choose a basis for their row space, use that basis as the contrast matrix, and replace by its rank . The null hypothesis is unchanged, but redundant contrasts must not be treated as independent dimensions. Rank zero gives no restrictions and hence no nontrivial test.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 47 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the unbiased sample covariance matrixand assume is positive-definite and , so is invertible almost surely. For a nonzero fixed direction , the observations have mean and variance . Their squared Student t-test statistic for the projected null mean isPut . The Cauchy-Schwarz inequality giveswith equality when is proportional to , if . For every projected statistic is zero. Maximizing the squared discrepancy over directions therefore gives Hotelling's T-squared statistic:This uses the squared generalized Rayleigh quotient. The preliminary formula on the printed cover has an unsquared numerator and is not valid as written: setting makes that ratio for , so it is unbounded. The displayed Cauchy-Schwarz argument supplies the needed corrected identity independently.
Under the null, let and . Then , , and are independent. To see these sample properties, apply an orthogonal transformation to the observation indices with first row . Its first centered row is ; its other rows are independent residual contrasts, independent of the first. Their outer products sum to , establishing the Wishart distribution and independence.
Since , use the supplied Gaussian-Wishart quadratic-form law with to obtainThus a level- test rejects when this scaled statistic exceeds the quantile of the F-distribution. The Gaussian-Wishart law requires independence; it holds here because of the orthogonal sample decomposition. Its printed use of instead of the introduced is a notational slip. A fixed-direction Student law alone would not calibrate the maximized statistic, because its maximizing direction depends on the sample.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 5 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14At time zero there has been no survival selection, so the population hazard of a survival mixture is the original mean individual hazard:At very large times, surviving individuals overwhelmingly come from the smallest-frailty end of the distribution. Their hazards approach the lower endpoint , soFor a direct check, differentiating the logarithm of the uniform frailty survival mixture givesIts expansion at zero is , and its large-time limit is . The changing population hazard does not imply that an individual's hazard declines. The decreasing population hazard under constant individual hazards identity makes the selection mechanism precise: with ,It follows by differentiating the ratio . Thus the surviving mixture becomes less frail over time even though every conditional hazard is constant.
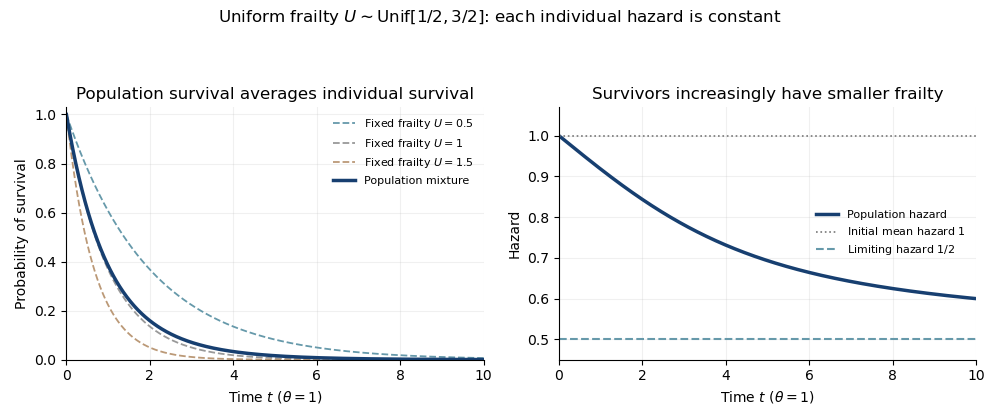
Uniform frailty survival mixture and declining population hazard despite constant individual hazards
. Details. The figure takes . The population survivor curve averages conditional exponential curves, while its hazard falls from the initial mean to the minimum individual hazard.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 5 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The population survivor function is the probability that a randomly selected person, averaging over their unobserved frailty, has not experienced the event by time . Here the conditional hazard is constant, so the conditional survival is . For , the uniform frailty density equals one on its interval, giving the uniform frailty survival mixtureAt its continuous extension is , since the numerator is . This is the Laplace transform of the uniform frailty density at argument . It is not : averaging individual survivor functions does not equal exponentiating the mean hazard. If , every individual hazard is zero and .
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 2 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Measure receipt and transfers directly rather than inferring them only from the outcome difference. Use identifiable pack codes and confidential early follow-up to record whether packs were retained, lost, taken, given away or administered, and to whom. Where feasible, corroborate administration reports with care records and establish whether recipients belonged to the opposite randomized group.
A process-evaluation sample across both arms can estimate the frequency and direction of treatment contamination. Separate receipt tracking from blinded outcome ascertainment where possible. Keep randomized assignments for the primary intention-to-treat analysis: excluding transfers or reclassifying participants by receipt can introduce confounding, since receipt behavior is not randomized. Receipt data can inform a supplementary analysis whose additional assumptions are explicit.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 2 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Define the difference as control minus intervention, positive for fewer deaths under intervention assignment. The observed difference per thousand isFor independent binomial distributions, its unpooled standard error per thousand isThe approximate 95% confidence interval is thereforeThe rare-event Poisson standard error gives almost the same interval. A reduction of 1.5 per thousand is consistent with the data, since it lies inside the interval. Zero also lies inside, so a nonzero benefit is not established at the two-sided 5% significance level. This does not establish equivalence or prove the proposed effect size, and cannot by itself establish treatment contamination.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the assumed 30% risk reduction for recipients and one-to-one transfers to distinct participants in the equal-sized opposite arm. Receipt fractions become 80% under intervention assignment and 20% under control assignment. ThusFor 30,000 participants per arm, the expected counts areThe original benefit per thousand becomes per thousand: symmetric treatment crossover attenuates a risk difference by . Expected counts still sum to 255, since intact transfers preserve the total number of recipients. These predictions assume unchanged receipt-specific risks and distinct control recipients. Loss, sharing or repeated transfers would require a different receipt model.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use equal allocation and a conventional two-sided 5% comparison of independent proportions. The assumed risks are and , giving target difference . Put and let be the number per arm.
The null critical difference is approximately . Under the alternative, the difference has standard deviation . For 80% statistical power, the target difference must exceed the critical difference by alternative standard deviations. Solving gives the sample size for comparing two proportionsThis is about per arm, or altogether. Rounding for planning:The rare-event Poisson approximation gives a similar answer. This assumes the stated baseline risk applies, no endpoint loss, and no attenuation by treatment contamination. The two-sided convention is explicit: a one-sided 5% test would require fewer participants.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 1 e Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14One possibility is increased recognition and care seeking: consultation may make caregivers more alert to minor injuries or more inclined to seek professional care, increasing recorded attendance without increasing injury frequency. This is the distinction in care-seeking effects on a recorded injury outcome.
A second possibility is reduced vigilance or greater exposure after feeling protected: reliance on supplied equipment may lead caregivers to relax other precautions. This is risk compensation in a prevention trial. Both are hypotheses to investigate; an elevated attendance incidence rate ratio does not establish which mechanism occurred.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 1 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14This is a family-level cluster-randomized trial, but there are only about 1.1 contributing children per family. Most families therefore contribute a single eligible child, leaving little opportunity for within-family intraclass correlation to add much uncertainty. The equal-size exchangeable approximation has design effect , with cluster size and correlation ; when is close to one, this is close to one. A multilevel Poisson regression can consequently give nearly the same standard error as the independent-child working analysis.
Agreement is compatible with limited within-family dependence and little change from covariate adjustment; it does not prove all dependence absent. Mean family size alone does not determine the exact design effect for highly unequal cluster sizes.
Larger differences would be expected with larger families and stronger within-family correlation, especially with unequal family sizes. Pronounced between-family heterogeneity, recurrent attendances concentrated in particular children, or important imbalanced covariates can also create overdispersion or change the adjusted comparison.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be attendance totals and the observed person-time at risk. Under independent Poisson distributions for the totals, the estimated incidence rate ratio is . Treating the exposures as known, the supplied large-count approximation, or the delta method, givesIndependence adds the log-count variances, while fixed exposure terms add no variance. Form the normal confidence interval on the log scale and exponentiate:This specifies the calculation without evaluating it. Individual randomization makes a child the assignment unit, but an independent Poisson count model remains an additional assumption about outcomes, not a consequence of randomization alone.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The control attendance rate is approximately per child-year. Assuming that rate is roughly constant over the first five years, expected attendance count is . A crude rare-event approximation gives about a 22% chance of at least one attendance.
A constant-rate Poisson process instead givesThus roughly one child in five is the appropriate order of magnitude. An attendance rate counts recurrent attendances, whereas a first-attendance risk counts children. The aggregate rate alone does not identify that risk without assumptions about recurrence and age-specific incidence; the Poisson conversion makes those assumptions explicit.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 46 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Treating the two-year observation period as approximately complete, divide total person-time at risk by two to estimate the average number of children being observed. Dividing again by the number of families givesThus the estimate is about 1.1 eligible children per family. This is a person-time-based approximation for children contributing to the study, not a count of older children or an exact reconstruction of family composition if follow-up or eligibility changed.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 43 5 e Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14library(mgcv) loads the fitting package; gam fits a Gaussian generalised additive model with the printed identity link. The smooth specification s(x, bs="cr") uses a penalized cubic regression spline. This is a finite-dimensional smooth basis, rather than a full interpolating spline with a free value at all observations. The fitted model isHere in the centred cubic regression-spline basis, with its curvature penalized through . The intercept is estimated separately. In the displayed fit the smooth test space has rank , consistent with nine smooth coefficients after the centring constraint, while penalization lowers its effective dimension.The intercept estimate is , with standard error , and . Because the smooth is centred over the observations, the intercept is the overall fitted average, not necessarily the fitted response at . Its test compares this average with zero. The significance-code legend maps progressively smaller -values to stars; stars are an annotation, not an effect-size measure.
The smooth has effective degrees of freedom, displaying substantial nonlinearity: a centred purely linear term would use one.
Est.rank=9 reports the rank used for its approximate significance calculation. The -value below is very strong evidence that the mean depends on , against a zero smooth term. It does not mean the fitted curve is the exact generating function, or that lack of fit has been tested. The total effective dimension including the intercept is .The adjusted coefficient of determination of and deviance explained of indicate that nearly all variation about the response mean is explained. For this Gaussian model, deviance explained is . The scale estimate estimates residual variance, corresponding to a residual standard deviation about . The GCV score is the prediction-oriented criterion used for smoothing selection, not a probability. It is consistent with the reported scale and effective dimension: .
In the PDF's plot, the solid curve is the estimated centred smooth , and the dashed curves show pointwise uncertainty around that smooth, rather than prediction intervals for new noisy responses. The label
s(x,8.24) gives its rounded effective degrees of freedom. The rug marks the observed covariate locations. Reading the endpoints givesThe smooth is increasing with an almost flat middle and one inflection, resembling a cubic. A simpler model to investigate is ordinary Gaussian polynomial regressionIt uses four mean coefficients rather than about nine effective ones. The apparent near-odd shape also makes a plausible further reduction, but the linear and quadratic terms should be checked rather than discarded solely from the picture. The figure suggests this alternative; it does not supply coefficients or establish the true simulation model. Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 43 5 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be the influence matrix, so . Its trace is the effective degrees of freedom, accounting for shrinkage of the fitted smooth rather than just counting basis coefficients. The generalised cross-validation score isFor a fixed smoothing parameter, the exact leave-one-out residual of this penalized linear fit is , obtained by removing its observation's contribution to the normal equations. Thus Leave-one-out cross-validation uses the average of their squared values. GCV replaces the individual leverages by their average . This avoids separate refits and gives a criterion balancing the small training residuals of a flexible fit against its larger complexity.
Evaluate the score across positive , or optimize it numerically, and choose minimizing GCV. Then refit or retain the spline at this value. In the full natural smoothing-spline family the trace decreases from towards as smoothing increases. The selected parameter is intended to give good prediction, rather than necessarily to pass through every point.
Past exam of the mathematics course of the University of Cambridge 2007 iii Paper 43 5 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14With the convention that the residual term is a sum rather than an average, the penalised least squares criterion isMinimize over functions whose first derivative is absolutely continuous and whose second derivative is square-integrable, that is, the usual Sobolev space . The cubic smoothing spline is its minimizer, with natural boundary conditions and linear continuation outside the data range. It is a natural cubic spline with possible knots at the observed , but usually does not interpolate the noisy .
To see why the minimizer is a natural spline, for any take the natural cubic spline interpolant through its values and write . Then . Integrating by parts on every knot interval twice gives zero: the terms involving vanish at knots, the terms involving cancel because is continuous there, and the outer terms vanish by the natural boundary conditions. Hencewhile their residual sums of squares agree. Replacing by never increases the criterion. This proves the minimum roughness property of the natural cubic spline interpolant needed here.
For fitted values , write , where is positive semidefinite and has the sampled affine functions as its two-dimensional nullspace. The finite-dimensional minimization becomes . Its strictly positive definite Hessian is , so it has the unique solutionThis is the roughness-matrix formula for a natural cubic smoothing spline. Larger penalizes curvature more strongly. As the fit approaches interpolation; as it approaches the ordinary least-squares affine line.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact