Solution
ID: past-exam-of-the-msc-in-advanced-computer-science-course-of-the-university-of-oxford/2021/computational-game-theory/3/a/solution
Past exam of the MSc in advanced computer science course of the University of Oxford 2021 Computational game theory 3 a Solution by  Codex 0 2026-10-25
Exactly , and can be sustained as constant stage game outcomes. Their long-run average payoffs are , and , respectively. We assume the usual repeated game monitoring convention: both players observe each completed joint action before the next round. The source's colour convention puts the blue lower-left row payoff first and the red upper-right column payoff second.
For necessity, row action earns against , so playing it forever guarantees a nonnegative long-run average payoff against every opposing pure strategy. Similarly, column action earns against and guarantees zero or more. Conversely, column action holds the row player's best possible stage payoff to , and row action holds the column player's to . Thus each player's minmax payoff is exactly .
Any Nash equilibrium must give both players at least zero, an individually rational payoff in a repeated game. Every off-diagonal cell has a negative payoff for one player: and hurt row, and hurt column, hurts row and hurts column. Repeating any such cell forever therefore permits a profitable unilateral deviation to the zero-guaranteeing action. The three diagonal cells pass this necessary test.
For sufficiency, fix target or . Each player's finite-state strategy has initial state and an absorbing state . In , output the player's component of ; remain in if the completed joint action equals , and otherwise move to . In , row always outputs and column always outputs , regardless of further observations. These are two-state grim trigger strategies; the separate machines are drawn below. The input is the observed joint action, so after any off-path history the prescribed continuation states agree.
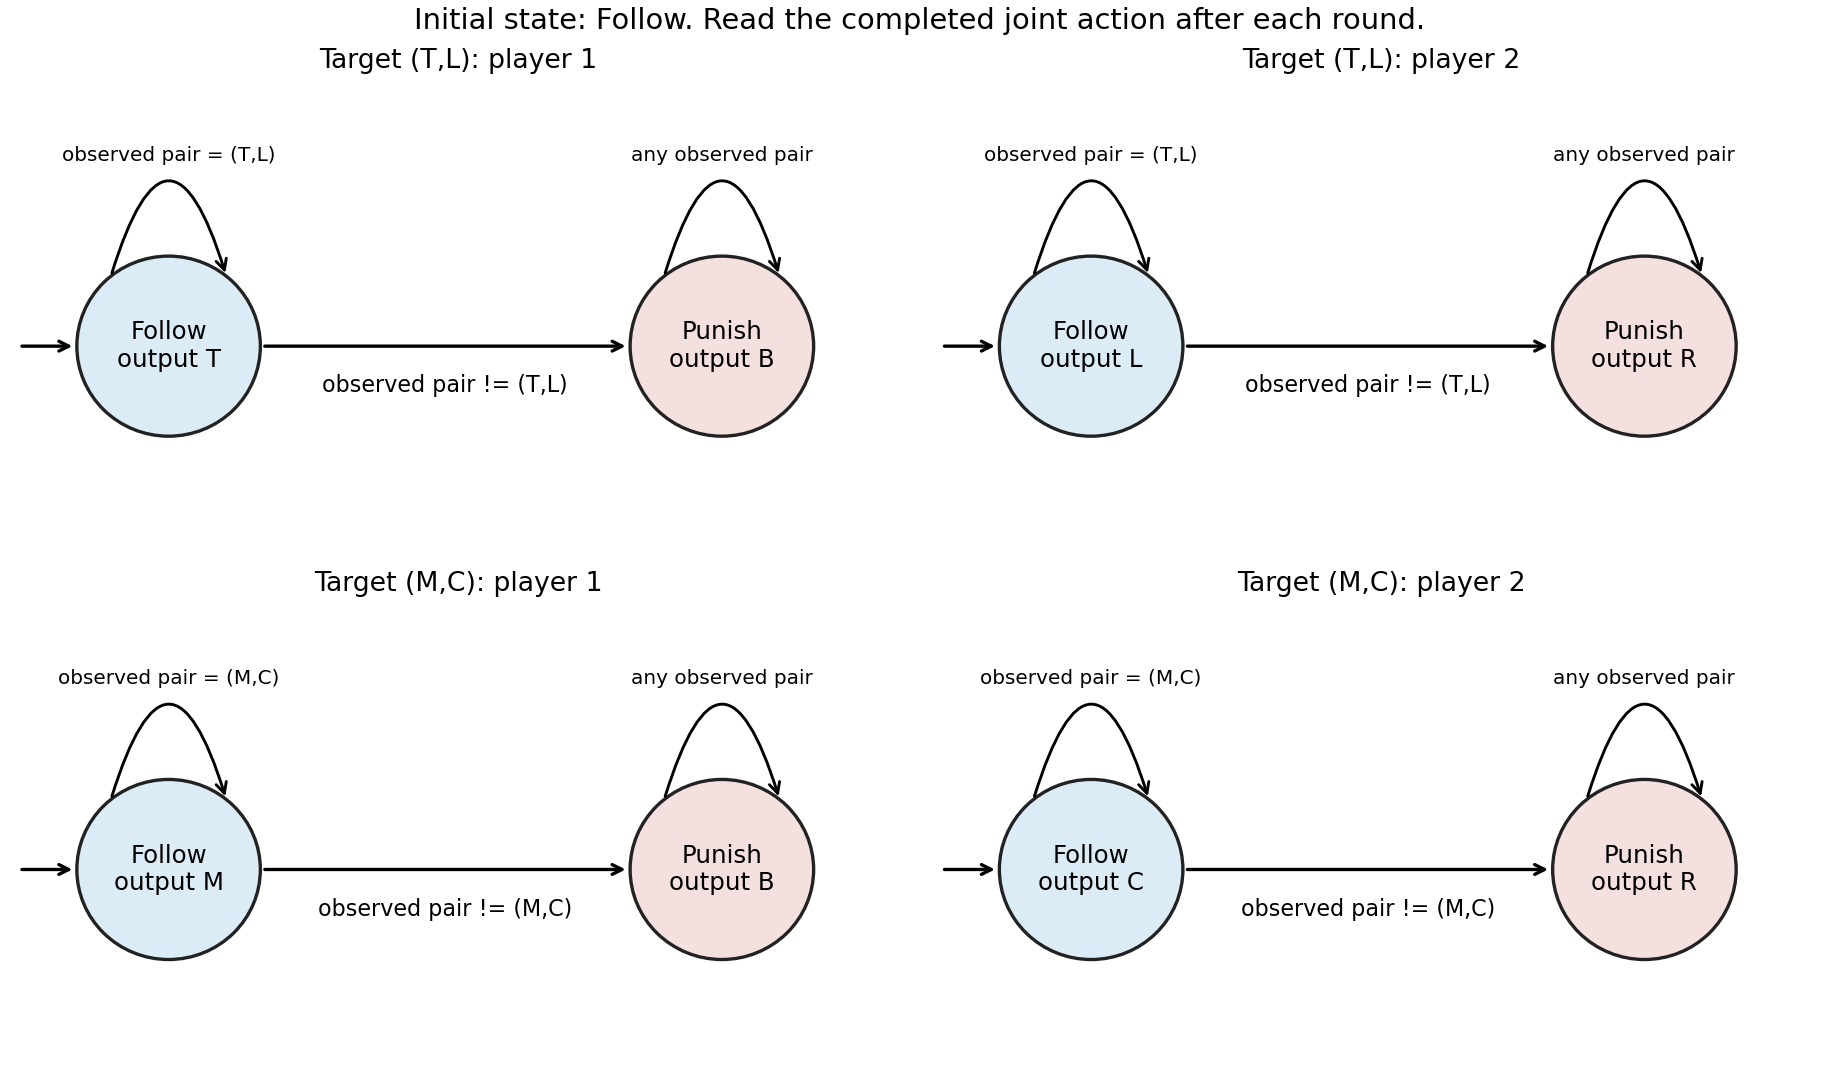

If neither player deviates, the target is repeated forever. If a player first deviates at a finite round , the opponent enters for all later rounds. Against column action , every row action earns at most zero; against row action , every column action earns at most zero. All payoffs are bounded, so the total reward before and at , divided by the horizon, tends to zero. The deviator's upper limiting average is therefore at most , below either target payoff or . This proof tests arbitrary future deviations, not merely a single changed action. It also rules out improvement by deviations whose averages fail to converge, if the criterion is extended by an upper or lower limit.
For target , one-state machines outputting and forever suffice: each is a best response to the other in every round. Their long-run average payoffs are zero and no unilateral deviation can improve them. In fact, the punishment is credible because is a stage Nash equilibrium, so the two positive-target constructions are also subgame perfect equilibria under the stated monitoring assumption. The general punishment mechanism is described in [ref]
Lecture 15: Repeated Games by Asu Ozdaglar. slides 12–15; those slides use discounting, while the finite-prefix argument here uses long-run averages
.“Outcomes of the stage game” here means a fixed action pair repeated forever. Allowing time sharing also sustains some average payoff vectors that are not stage cells: for example, a deterministic alternating cycle gives , with a two-phase finite-state strategy and the same permanent punishment. An off-diagonal cell may occur in a sustainable cycle; the impossibility above concerns its constant repetition, not every appearance on an equilibrium path. With finite-state pure strategies, an undisturbed path is eventually periodic, so its limiting cell frequencies are rational numbers.
New to topics? Read the docs here!