Like breadth-first search, this also has the property of visiting parents before any children.
This is the easiest one to do iteratively:
- pop and visit
- push right to stack
- push left to stack
This is the order in which a binary search tree should be traversed for ordered output, i.e.:
- everything to the left is smaller than parent
- everything to the right is larger than parent
This ordering makes sense for binary trees and not k-ary trees in general because if there are more than two nodes it is not clear what the top node should go in the middle of.
This is unlike pre-order depth-first search and post-order depth-first search which generalize obviously to general trees.
This is a bit harder than iterative pre-order: now we have to check if there is a left or right element or not:
- (START) push current
- if there is left:
- move left
- else:
- (ELSE) pop
- visit
- if there is right
- move right
- GOTO START
- else:
- GOTO ELSE
The control flow can be slightly simplified if we allow NULLs: www.geeksforgeeks.org/inorder-tree-traversal-without-recursion/
Has the property of visiting all descendants before the parent.
This is the hardest one to do iteratively.
Bibliography:
Articles by others on the same topic

Depth-first search is a graph search that follows a branch as far as it can before returning to try the next unexplored branch. Starting at a vertex of an undirected graph on a finite set of vertices, mark as discovered. Scan its graph neighbours in a fixed order: for each undiscovered vertex, record the current vertex as its parent in a rooted tree in the discovery tree, mark the new vertex, and explore it immediately using recursion. Return when its adjacency list is exhausted. Discovery marks persist after return, preventing a graph cycle from causing repeated exploration. This branch-and-return rule is the maze exploration described in MIT's notes. [ref]
Use the same unweighted undirected graph as breadth-first search, with vertex set and edgeswhere denotes the unordered pair . Visit graph neighbours in lexicographic order of their one-letter labels, starting at . The discovery order, computed by the diagram's generator, isThe discovery edges in order are . They form a rooted tree spanning the reached vertices, with root of a tree . The other edges, and , remain in the original graph but never discover a new vertex. In particular, the graph cycle causes no repeated discovery.
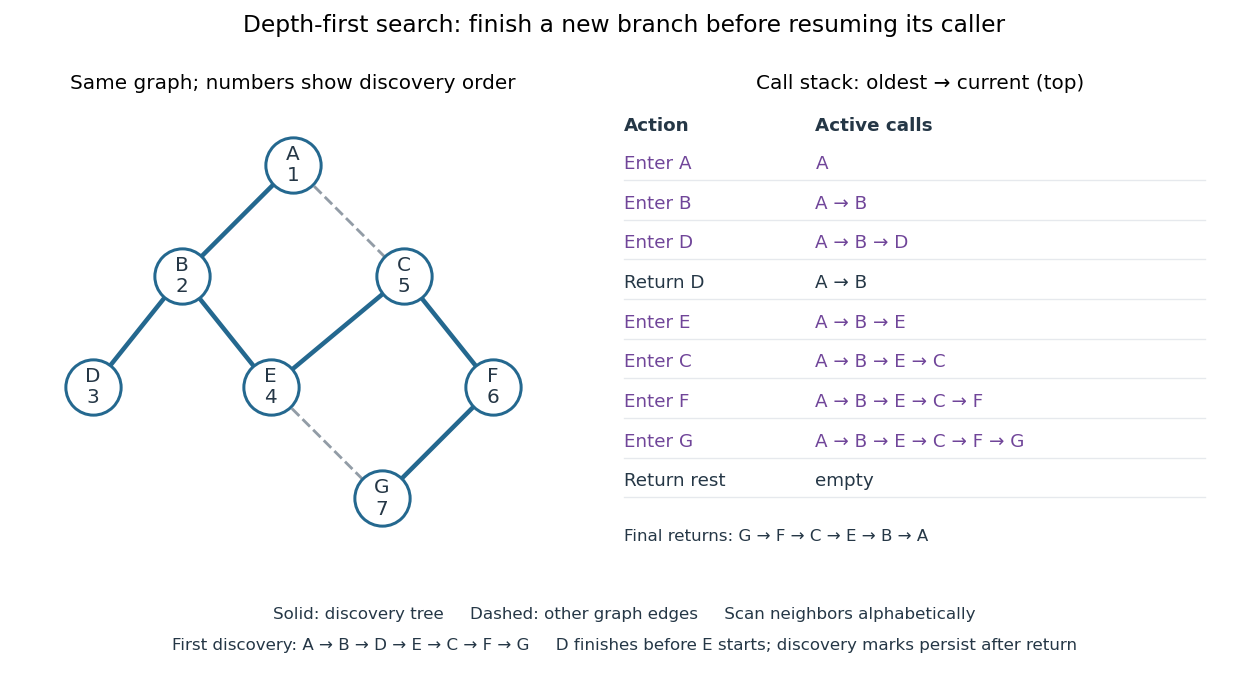
At there is no undiscovered graph neighbour, so its call returns to . The next call enters , then , then , then . Immediately after discovering , the call stack is , with on top; is still discovered but its call has finished. The maximum call stack depth is six, although seven vertices are discovered. Following the recorded parent in a rooted tree backwards at each step reconstructs a graph path; here the route from to is , using five edges. Breadth-first search instead finds , using three edges. Depth-first search establishes reachability but does not guarantee the fewest edges.
An explicit LIFO stack can replace recursion, but its entries and discovery rule must be specified. To reproduce this exact traversal, store one frame per active vertex, retaining the next position in its adjacency list. Advance the top frame by one graph neighbour; if that vertex is undiscovered, mark it and push its frame immediately; pop an exhausted frame. Pushing all undiscovered graph neighbours at once and marking them on push is a different iterative variant. Even pushing them in reverse lexicographic order does not generally reproduce the parent in a rooted tree relationships above: would already be marked while processing , so could not discover .
With an adjacency list representation, constant-cost discovery checks and frame operations, and the graph neighbours already ordered, depth-first search has time complexity in Big O notation. Each reached vertex is entered once and each incident edge is examined at most twice in an undirected graph; initializing all discovery marks costs . The call stack has depth at most , since no active vertex repeats. Discovery marks and the recorded parent in a rooted tree for each nonroot vertex also need auxiliary space complexity, excluding storage for the graph. Sorting adjacency lists to obtain a chosen order is additional work. [ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/DepthFirstPaths.java. Sedgewick and Wayne, Algorithms: DepthFirstPaths discovery marks and resource bounds
One start explores only its connected component of a graph. To cover a disconnected graph, start again at every still-undiscovered vertex while keeping all discovery marks; the discovery trees form a forest. Depth-first search is useful for reachability, constructing a spanning tree of a connected graph, and organizing the return steps needed by a depth-first traversal of a tree. For detecting a graph cycle in a simple graph that is an undirected graph, an edge to an already discovered vertex other than the current parent in a rooted tree closes a graph cycle; the immediate return edge to that parent in a rooted tree is not itself a graph cycle.
// Target: computer-science.bigb


Depth-first search (DFS) is an algorithm used for traversing or searching through tree or graph data structures. The algorithm starts at a selected node (often referred to as the "root" in trees) and explores as far as possible along each branch before backtracking. This method allows DFS to explore deep into a structure before returning to explore other nodes.