Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
The loop invariant just before inspecting index is: , and no entry at an index matches . Initially , so there are no earlier entries. A failed equality test extends the excluded region by one position and preserves the loop invariant. A successful equality test at index establishes a match; the loop invariant establishes that it is the first one. At exhaustion, and every entry has failed, so the absent result is correct. The number of remaining entries decreases after each failed equality test, proving termination for a finite sequence. Together these establish algorithm correctness under the assumptions that the input is stable and each equality test terminates. No step of the argument compares the relative order of values.
Count just the equality tests between the target and an entry, excluding loop conditions and index updates. If the first match is at index , linear search uses exactly equality tests. If the target is absent, it uses exactly . Thus for the best successful case costs one equality test, and the worst case costs , attained by absence or a first match at the last index. For , the sole outcome is absence with .
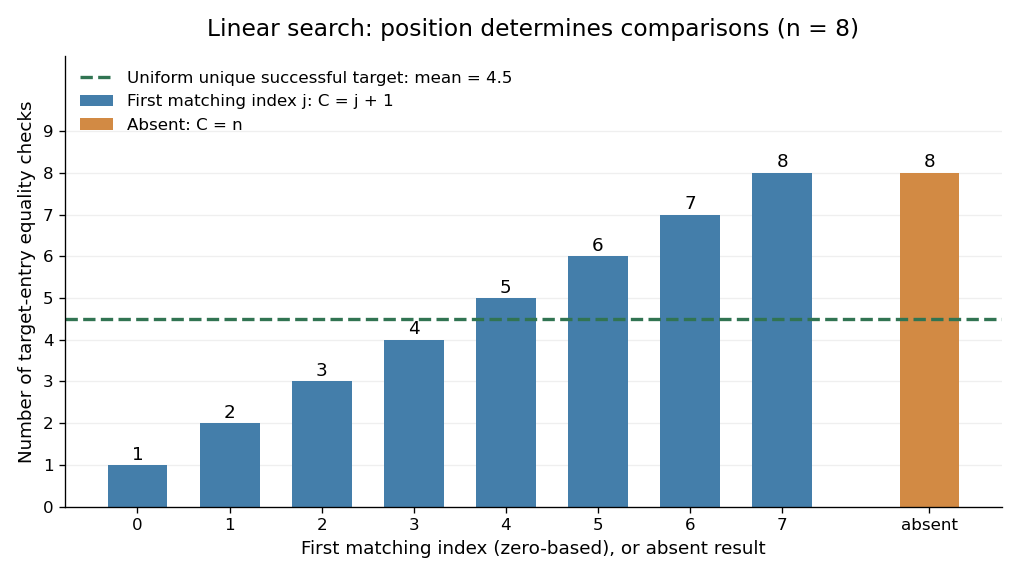
An expected value needs a specified probability distribution. For , condition on success, assume the target occurs exactly once, and assume its position has a uniform distribution on a finite set of indices . Then the expected value of the linear search comparison count isThis is the average of the costs under those assumptions, with no assumption that the array is sorted. It is not a universal average for arbitrary queries. For example, with , a unique successful target at index with probability and at index with probability has expected value , rather than .
Duplicates also require care about what is sampled. Choose a position uniformly in , then search for its value. All queries succeed, but the five possible sampled positions give costs : both positions holding cause an immediate match at index . The expected value is , not . Uniformly choosing an occurrence does not uniformly locate the first match.
More generally, let the success probability be and let be the conditional probability that the first matching index is , allowing duplicates. Since , the expected value isUnder the unique, uniformly located successful-target assumptions this becomes . If every query is absent, and without needing conditional probabilities. When , success is impossible and ; the successful-search conditional formula is undefined.
Converting the linear search comparison count to execution time needs a cost model. Under constant-cost equality tests, next-entry access, and loop bookkeeping, worst-case time complexity is in Big O notation for , with constant overhead even for the empty sequence. Variable-length entries can make an equality test expensive. On a linked list, advance along its links; repeatedly restarting at the head to obtain the next numeric index adds work that the comparison count does not capture. These are exact operation counts and conditional mathematical averages, not runtime measurements.
A low-pass filter preferentially transmits low frequencies and attenuates higher frequencies. It can smooth rapid noise in a slowly varying signal, but it also suppresses wanted variations outside the useful signal bandwidth. An RC low-pass filter gives a concrete continuous-time example; a moving average implements related smoothing on a discrete-time signal.
The useful question is how much change the measurement can tolerate. Preserving the low frequencies of a temperature record while reducing a fast unwanted oscillation can improve readability. Preserving the sharp onset of a pulse requires higher frequencies, so excessive smoothing changes its timing and shape. The RC low-pass frequency response and RC low-pass step response make this signal bandwidth versus settling time tradeoff quantitative.
Laboratory Manual Physics, Class XII Experiment 6: Resistance and figure of merit of a galvanometer by  Codex 0 2026-10-14
 IUPAC Compendium of Chemical Terminology, fifth edition (Gold Book) by International Union of Pure and Applied Chemistry polymorph by Codex 0 2026-10-14
Codex 0 2026-10-14Online text: goldbook.iupac.org/terms/view/15225
Gold Book entry 15225, in the fifth-edition online version 5.0.0 (2025), issued by IUPAC. The entry cites 2009 recommendations, p. 994; no individual editors or recommendation authors are inferred here.
Cited passages: IUPAC Compendium of Chemical Terminology, fifth edition, entry “polymorph” (15225), definition and Note 2.
IUPAC Compendium of Chemical Terminology, fifth edition (Gold Book) by International Union of Pure and Applied Chemistry molecular ion in mass spectrometry by Codex 0 2026-10-14
Codex 0 2026-10-14Online text: goldbook.iupac.org/terms/view/M03988
Cited passages: Gold Book, fifth edition, molecular ion in mass spectrometry: formation by electron removal or addition without fragmentation.
IUPAC Compendium of Chemical Terminology, fifth edition (Gold Book) by International Union of Pure and Applied Chemistry molecule by Codex 0 2026-10-14
Codex 0 2026-10-14Online text: goldbook.iupac.org/terms/view/M04002
Cited passages: Gold Book, fifth edition, molecule: neutral entity with more than one atom; bound-state qualification.
IUPAC Compendium of Chemical Terminology, fifth edition (Gold Book) by International Union of Pure and Applied Chemistry osmotic pressure by Codex 0 2026-10-14
Codex 0 2026-10-14Online text: goldbook.iupac.org/terms/view/O04344
Cited passages: Gold Book, osmotic pressure: definition of the solvent-only membrane; Gold Book, osmotic pressure: equilibrium definition, solvent activity formula and dilute ideal limit.
Introduction to Topological Manifolds, second edition by John M. Lee Introduction by Codex 0 2026-10-14
Codex 0 2026-10-14Online text: sites.math.washington.edu/~lee/Books/ITM/c01.pdf
Author-hosted sample of Chapter 1, Introduction. The second-edition book is credited to John M. Lee, published by Springer in Graduate Texts in Mathematics 202, and carries copyright 2011. Its Chapter 1 definition is explicitly provisional; formal manifold hypotheses in this wiki are supported by the separately cited Toronto notes.
Cited passages: Introduction to Topological Manifolds by John M. Lee, second edition, Chapter 1, pages 1–3 on local models and pages 5–6 on topological invariants.
Introduction to Programming in Java: An Interdisciplinary Approach by Robert Sedgewick and others 4.4 Symbol Tables by Codex 0 2026-10-14
Codex 0 2026-10-14Online text: introcs.cs.princeton.edu/java/44st/
Cited passages: Introduction to Programming in Java, section 4.4, Binary search trees: recursive definition and node representation.
Intro to Lattice Algs & Crypto, Mastermath Spring 2018 Lecture 1: Introduction by Codex 0 2026-10-14
Codex 0 2026-10-14By Daniel Dadush.
Lecture 1 notes credit Daniel Dadush as scribe, with Daniel Dadush and Léo Ducas listed as lecturers. Mastermath Spring 2018 identifies the course offering; no publication year or whole-course authorship is inferred.
Cited passages: §7, Definition 11 and Lemma 12, printed p. 9: determinant and integer-inverse characterization; §7, Lemma 13, printed p. 9: equivalent lattice bases.
Use the compilation arithmetic example with input . An abstract syntax tree interpreter first reads
x, obtains , forms , and finally computes . Interpreting the folded abstract syntax tree skips the addition but gives the same result. The compiled stack machine instructions instead produce the following trace; the top of the stack is written on the right:instruction stack after instruction
initial []
LOAD x [7]
PUSH 5 [7, 5]
MUL [35]
PUSH 4 [35, 4]
SUB [31]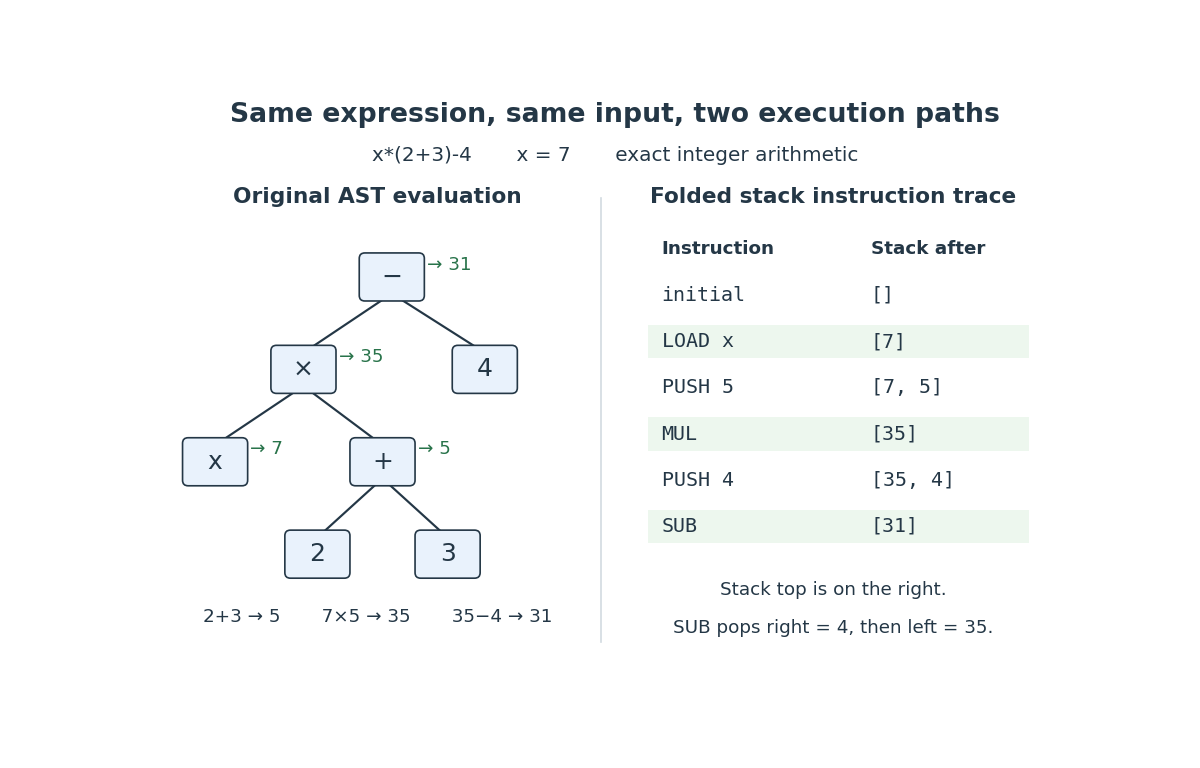
Execution of
. Details. x*(2+3)-4 at : the original abstract syntax tree and the folded stack machine instructions both give The order in
SUB is essential: reversing its two popped operands would give . The same stored instruction sequence works for input , yielding , without repeating parsing or constant folding. An abstract syntax tree interpreter can likewise reuse its already-parsed tree. Reusing a representation is therefore useful to both approaches; it does not itself distinguish compilation from interpretation.The pleasing part is that a nested rooted tree and a flat instruction sequence express the same computation. The structural induction in the compilation arithmetic example connects them by a precise stack property. This tiny language always terminates and has no side effects; richer programming language semantics require a correctness argument that also accounts for failures, externally visible actions, and possible nontermination.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact