Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
A numeral is a written expression representing a number. The number five can be written as the decimal numeral , the binary numeral , or the Roman numeral V. The expressions differ while the represented integer is the same.
This distinction matters when an algorithm examines numerical digits. A palindromic number, for example, is defined through its representation in a specified radix, rather than through the appearance of an abstract number. The integer five is a palindrome as the one-digit decimal numeral and as the binary numeral , whereas ten is written in decimal and in binary, neither of which is a palindrome.
Sulfate is the anion , with sulfur formally in oxidation state and an approximately tetrahedral oxygen arrangement. It forms salts with many cations.
Online text: raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/Digraph.java
Authored accompanying software by Robert Sedgewick and Kevin Wayne, identified by the implementation bylines. The book publication year is 2011; copyright 2002–2025 is not an implementation publication date. Implementation locators refer to the inspected source file, not to the textbook pages.
Cited passages: Digraph.java, addEdge, adj and outdegree: one entry in the tail's collection; indegree is maintained separately; Digraph.java, class documentation and addEdge: parallel edges permitted; a directed self-loop adds one outgoing entry and increments indegree once; Digraph.java, class documentation and adj: obtaining the collection versus iterating in time proportional to outdegree.
Online text: raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/Graph.java
Authored accompanying software by Robert Sedgewick and Kevin Wayne, identified by the implementation bylines. The book publication year is 2011; copyright 2002–2025 is not an implementation publication date. Implementation locators refer to the inspected source file, not to the textbook pages.
Advanced Data Analysis from an Elementary Point of View, 2015 draft by Cosma Rohilla Shalizi Mixture Models by  Codex 0 2026-10-14
Online text: www.stat.cmu.edu/~cshalizi/uADA/15/lectures/20.pdf
The adrenal medulla is the central adrenal region containing chromaffin cells that release catecholamine signals into the circulation. Sympathetic neural input links it to rapid systemic responses. Circulating hormone release is distinct from local neurotransmitter release at a conventional peripheral synapse.
Write and . Suppose each vertex identifier, list descriptor, link and optional edge weight occupies a constant number of machine words, and indexed array access and identifier comparison take constant time. There are list descriptors and directed, or undirected, neighbour entries. Hence adjacency lists use machine words in Big O notation. A full adjacency matrix has entries, regardless of . These are counts under a storage model, not fixed byte sizes.[ref]
Recitation 19: Graph Representations and Traversals (Cornell course page). Recitation 19, The Adjacency List and The Adjacency Matrix: directed and undirected entry totals, linear list storage, and quadratic full-matrix storage
Our undirected example has six list descriptors and fourteen neighbour entries, versus thirty-six full adjacency matrix entries. The numbers and count different kinds of logical items: they do not prove a particular byte saving. A linked list also needs links; an array may have unused capacity. Storing only half of a symmetric matrix changes its exact count while leaving quadratic growth. If identifiers or weights require growing numbers of machine words, their size must be included in the space complexity.
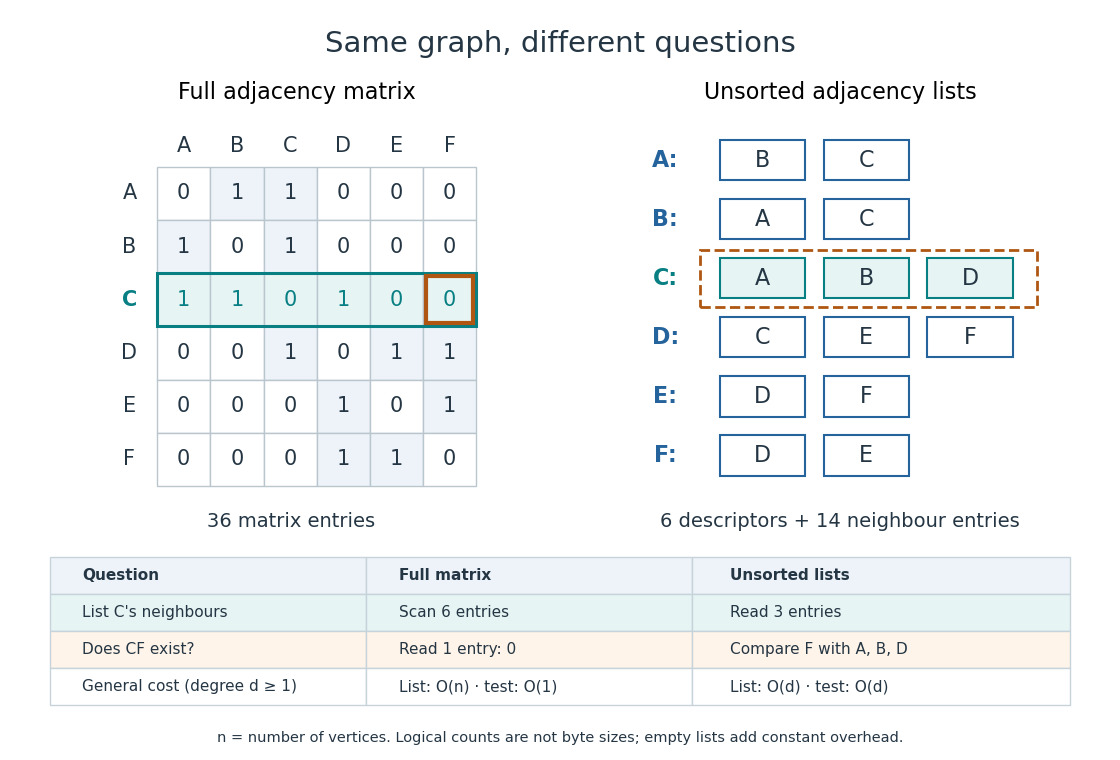
An unsorted adjacency list answers "does the edge exist?" by linear search through . In the worst case it inspects all entries, giving time, or for . Even if is absent, an uninspected entry could still contain it, so arbitrary lists require the whole scan. On our example, looking for in 's list compares with and fails after three comparisons. A full adjacency matrix instead answers from its single entry in time.[ref]
Recitation 19: Graph Representations and Traversals (Cornell course page). Recitation 19, The Adjacency List: edge-membership question; The Adjacency Matrix: constant-time edge-existence query
Different promises change the query. A sorted array of neighbour identifiers permits binary search in time, but maintaining order after insertion may require shifting entries. A per-vertex hash table permits expected constant-time membership under the hashing and load assumptions of that data structure; it does not give that guarantee to an arbitrary adjacency list. A stored list length can likewise make a vertex degree query constant-time even though neighbour enumeration still has to visit its entries.
The advantage grows with scale. For a graph path on vertices, , so there are undirected neighbour entries and descriptors, versus full adjacency matrix entries. Such a family is a sparse graph with . For a complete graph, , so the undirected neighbour entries already number : the adjacency list advantage in growth rate disappears. Choose by the workload: following existing edges favours adjacency lists; many arbitrary pair-membership queries can favour a full adjacency matrix. The representation organizes the same graph for different questions.
Neighbour enumeration reports the neighbours of a specified vertex. For a simple graph, scan its adjacency list and report each entry. With constant-time list access and work per entry, a list of length needs time in Big O notation, conventionally written for nonempty lists. Use vertex degree for an undirected graph and outdegree for a directed graph. Obtaining the list reference can take constant time; consuming it requires visiting every entry.[ref]
Digraph.java. Digraph.java, class documentation and adj: obtaining the collection versus iterating in time proportional to outdegree
In our undirected example, enumerating 's neighbours reads : three entries. Scanning row of the full adjacency matrix reads six entries, , to produce the same answer. In the directed variant, enumerating 's outgoing neighbours reads no neighbour entries, but still needs constant work to locate and recognize its empty list. For a multigraph, scanning lists enumerates incident edges with multiplicity; reporting only distinct neighbours additionally requires removing repetitions.
For a short time complexity argument, each reported entry requires at least one output operation, and one scan suffices. Across all vertices, the undirected entry count is by the handshaking lemma; the directed count is . A graph search that processes each vertex once and scans each of its entries once therefore does structural work, provided its visited-state access and FIFO queue or stack operations also have the required constant-time costs. With a full adjacency matrix, scanning every row instead inspects entries. This is how the representation enters the analysis of breadth-first search and depth-first search.
For a directed graph, store in for the edge . The reverse edge is separate and is stored only if it exists. Consequently, list length is outdegree, not indegree, and each directed edge contributes one entry in total. An incoming-list index is additional storage.[ref]
Digraph.java. Digraph.java, addEdge, adj and outdegree: one entry in the tail's collection; indegree is maintained separately
Orient the seven edges of our example from earlier to later labels. The resulting directed graph hasThere are now seven entries, with outdegrees . In particular, needs an empty list even though it is reached from : incoming edges do not make 's outgoing list nonempty. Replacing each directed edge by an undirected graph connection would lose this distinction.
Our running simple graph excludes self-loops and repeated edges. If those restrictions are relaxed, specify how the adjacency list encodes them. Here an undirected self-loop at contributes two copies of to , matching its contribution of two to the degree of a vertex. A directed self-loop contributes one copy, and one each to outdegree and indegree. Distinct parallel edges retain distinct entries; a multigraph's list length can therefore exceed its number of distinct neighbours.[ref]
Graph.java. Graph.java, class documentation: parallel edges and two-entry undirected self-loop convention; addEdge applies both insertions even when v equals w
[ref]Digraph.java. Digraph.java, class documentation and addEdge: parallel edges permitted; a directed self-loop adds one outgoing entry and increments indegree once
For example, add one undirected self-loop at to the seven-edge example. Its list becomes , the vertex degree of becomes four, and the total entry count becomes sixteen for eight edges. If an application instead stores a self-loop once, it must account for its doubled undirected vertex degree separately. In a weighted graph, an entry can be an ordered pair meaning destination and weight ; the weight belongs to the edge, not to the destination vertex.
Stereochemical sequence rules rank substituents for R and S configuration. Compare the directly attached chemical atoms by atomic number first, then resolve ties by comparing successive shells at the first difference. Isotopes and multiple chemical bonds require additional rules. This ranking convention does not involve optical rotation.[ref]
For a tetrahedral stereocenter, rank its four substituents using stereochemical sequence rules. With lowest-priority group pointing away, a clockwise sequence is and a counterclockwise sequence is . Looking from the other side reverses the apparent sequence, so the viewing condition is essential. The geometric letters A/B/C/D in the tetrahedral mirror-image test carry no assigned priority. Neither nor determines positive or negative optical rotation.[ref]
5.5 Sequence Rules for Specifying Configuration. McMurry, Organic Chemistry, §5.5, Figure 5.8 and discussion after Figure 5.10
Southern Illinois University's ET 304A guide, Lab 4: Voltage Measurements and Meter Loading Effects, documents an instructive test: build equal-arm voltage dividers on a supply, then measure across the lower arm with a digital multimeter, analog multimeter, and oscilloscope. Starting with two resistors, repeat with equal pairs from to . It requires separate recorded readings, unloaded predictions, and predictions including each instrument's input electrical resistance. The guide obtains meter resistances from specification sheets and scope resistance from the input-panel marking. Equal ratios control the unloaded target while changing susceptibility to voltmeter loading. The provided tables are blank: the guide specifies a procedure, not measured outcomes.[ref]
Preparation and accuracy checks are made concrete by Berkeley's Lab 1: Introductory Experiments and Linear Circuits I. Its different divider uses nominal and resistors and a supply on a breadboard. Measure isolated resistors first, record actual supply voltage, recalculate with these measured values, then record the junction voltage with the digital multimeter. It explicitly compares actual values with resistor tolerance and the final voltage with a range-dependent accuracy bound from the instrument manual. This is an uncertainty check, not an independent measurement calibration.[ref]
For a controlled comparison, additionally record the selected instrument range, probe factor, and input coupling; connect each instrument separately to the same electrical reference potential, and monitor the input rather than treating the supply label as an exact voltage. These are proposed controls for interpreting the documented procedures. A voltage indication and a resistance indication from the same digital multimeter do not independently validate its measurement calibration; a traceable reference comparison would be needed for that. Resistor tolerance describes component variation, while measurement uncertainty describes what is known about measured values. Using nominal arms alone can confuse mismatch with loading: equal nominal arms each within one-percent tolerance can give unloaded ratios from to .
The inference to test is specific: once actual arm values, input voltage, and meter input electrical resistance are accounted for, the readout should approach the loaded voltage divider prediction within the remaining measurement uncertainty. A discrepancy can instead reflect contacts, changing temperature, source droop, or an input that is not a fixed passive resistor. A source with positive series electrical resistance can be modeled by replacing with only when denotes its ideal internal voltage; when the actual voltage across the divider is measured, that terminal value is already . During settling, or with appreciable input capacitance and changing signals, the steady direct current calculation is insufficient. Neither institutional procedure supplies measured values for the original example above.
For and , define the fractional shortfall in output magnitude from the unloaded value byThis is a loading bias relative to the unloaded target, not the uncertainty of an instrument's measurement of the connected circuit. The equality with the signed ratio also holds for negative , because the output retains its sign. The Thévenin resistance summarizes the divider's susceptibility: the relevant comparison is , not merely a large absolute .
Set and . ThenThe derivative proves that increasing the load electrical resistance always reduces this error. For equal divider arms, : gives , gives , and gives . Thus a “ten times the lower resistor” rule does not guarantee one-percent agreement with the unloaded target.
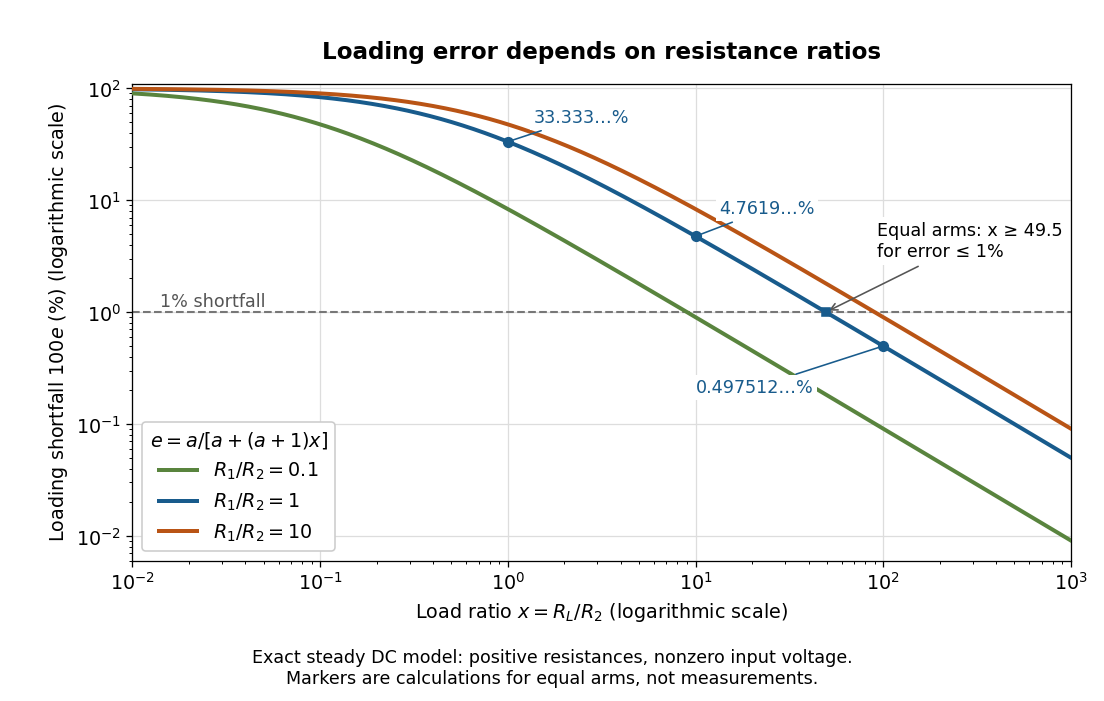
Fractional loading error falls continuously as the load resistance grows relative to the lower divider arm
. Original exact resistance-only predictions for three ratios. The logarithmic axes show the equal-arm examples , including the stipulated load on a lower arm. No points represent measurements. Source. Details.A quantitative design requirement follows without a rule of thumb. For a specified ,For equal arms, , so one-percent loading error requires . Reducing both divider electrical resistances reduces loading but increases unloaded supply electric current and Joule heating: . The stipulated equal-arm example dissipates in total when unloaded. This tradeoff explains why the ratio alone does not determine a useful divider.
Connect a passive electrical load of electrical resistance from the junction to the reference. In the steady direct current model, and share the same electric potential difference and are connected in parallel. Their equivalent electrical resistance isThis is the replacement required when a voltmeter is connected across . The inspected teaching guide explicitly models the meter this way.[ref]
The Kirchhoff's current law proof makes the changed assumption visible:The upper resistor carries the sum of the lower and load electric currents, so the two original resistors no longer have equal electric currents. In the stipulated example, , the upper current is , and each lower branch carries .
For a digital multimeter used as a voltmeter, let its input electrical resistance on the selected voltage range be . With no other load, set ; if an intended load is also present, use in place of . Two instruments connected simultaneously add two branches. Their ideal indicated value equals the voltage of this altered circuit; voltmeter loading can exist even with perfect measurement calibration. Real readout additionally has measurement uncertainty, offsets, and finite resolution. Consult the actual range and input specifications rather than assigning every digital multimeter the same .
For an oscilloscope, the resistance-only model applies to settled direct current with a compatible input coupling setting. The oscilloscope input and cable also have capacitance; changing signals can therefore have loading that depends on frequency. A probe changes the impedance seen at its tip and the relation between tip voltage and displayed voltage; use the probe-and-input combination's specification and attenuation setting. NJIT's guide models the parallel electrical resistance and capacitance and adjusts probe compensation with a square-wave readout.[ref]
Lab 7: Input Impedance of an Oscilloscope and the Scope Probe, NJIT ECE 291. Lab 7: Input Impedance of an Oscilloscope and the Scope Probe, Introduction, Figure 5 and probe adjustment; Laboratory §1(a)–(c)
The negative slope of the Thévenin terminal response with delivered electric current . Thévenin source suppression determines it from the ratio of test voltage to entering test electric current. It need not represent a physical positive resistor inside the original network.
An authored teaching experiment uses an adjustable steady-voltage supply, a digital multimeter, fixed resistors, and a potentiometer or resistance decade box. Its original circuit uses a supply and , , and resistors; the student compares and electrical loads. The readout is load voltage, recorded against prediction and deviation. The student then removes the electrical load to measure the open-circuit voltage, disconnects the supply and substitutes a wire to measure the Thévenin resistance with the multimeter's resistance mode, and restores the supply for an independent method: adjust the variable electrical load until the voltmeter reads half the unloaded voltage. Finally the student builds the equivalent and repeats both load measurements. Its tables are blank recording forms, not reported observations. [ref]
Laboratory Manual for DC Electrical Circuit Analysis by James M. Fiore. Laboratory Manual for DC Electrical Circuit Analysis by James M. Fiore, version 1.4.3, experiment 11, printed pp. 52–55: Equipment, Procedure 1–10, Tables 11.1–11.3
The half-voltage inference assumes negligible voltmeter loading and positive . A finite voltmeter input electrical resistance actually gives an apparent unloaded readingWhen the same voltmeter remains connected across a variable electrical load , the network sees . Setting its reading to , rather than to the true , givesThus the uncorrected half-reading method underestimates positive . In the original example, a stipulated gives and half-reading load , instead of . These are model predictions for a deliberately loading meter, not the specification or observed readout of the source experiment's instrument.
Finite readings can also estimate the terminal line without a physical short. For two distinct load settings with corrected delivered electric currents and terminal voltages ,If the voltmeter remains across each electrical load, the delivered electric current is , including the meter branch. Omitting it biases the inferred slope.
Useful additional controls are to measure each resistor separately before assembly, verify terminal polarity, repeat an earlier load setting to detect supply drift, and compare a third setting with the inferred Thévenin terminal response. These are proposed controls, not reported outcomes of the source experiment. Closely spaced electric currents make the slope estimate sensitive to voltage resolution and measurement error; widely separated settings may trigger source current limiting or Joule heating that changes electrical resistance. Lead and contact electrical resistance, meter input uncertainty and rounding limit the inference. An ohmmeter injects its own test electric current; its reading on a powered network is not the suppressed-network ratio. Measurements with independent sources physically removed do not characterize an active dependent electrical source whose control or supply has also been disconnected.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact