Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 2 e Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-06
In the log-linear transition intensity model, each hazard ratio multiplies a specific off-diagonal transition intensity, comparing its post-transplant period with the pre-transplant period while holding the modeled origin state fixed. Diagonal entries must then be recalculated from row sums.
For mild-to-severe progression, the early hazard ratio suggests a 48% decrease, but its interval includes no effect. The later hazard ratio , with interval wholly below one, suggests a 98% decrease. These findings are compatible with suppression of progression by hematopoietic stem cell transplantation among those remaining in the mild state.
For mild-to-death, the early hazard ratio indicates a very large relative increase, and the later ratio still indicates an increase; both intervals are above one. For severe-to-death, the early ratio indicates increased mortality, whereas the later ratio indicates a 43% decrease; these intervals also exclude one. Early treatment toxicity and infection are plausible explanations for an immediate mortality increase. Later control of the underlying myelodysplastic syndrome is a plausible explanation for reduced advanced-state mortality and progression.
Relative increases must be interpreted alongside baseline rates. The early mild-state death rate is approximately per month, whereas the early severe-state death rate is per month. Thus the far larger mild-state hazard ratio partly reflects its much smaller starting mortality, rather than greater absolute mortality after transplantation. The later corresponding rates are and per month.
Within the question's model, delaying transplantation while the disease is mild can avoid a large immediate mortality cost, whereas the high baseline mortality in the severe state makes the later survival benefit more valuable. This provides a qualitative rationale for the stated policy. The estimates do not establish an optimal timing rule: treatment selection, changing health status, selection of survivors into the later period and the use of the previous visit's covariate value can affect the comparison. They are associations from the fitted cohort model, not automatically causal hazard ratios.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 2 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The mean holding time from a transition intensity matrix is . Apply this to the fitted exit rates and use monotonic inversion for each confidence interval:Thus the expected state durations are 86.96 months and 31.45 months, respectively. A confidence interval for a reciprocal rate reverses the endpoint order; the negative diagonal rates must first be converted to positive exit rates.
For the expected absorption time in an illness-death model, the time spent initially in the mild state is followed by an additional severe-state duration only if progression occurs before death. That probability is . ThereforeThis is an unconditional mean including both possible paths to death, not a mean conditional on progression.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 2 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Let and , where time homogeneity removes dependence on . A recorded state at the next clinic visit contributes a transition probability; an exactly observed death contributes a statistical probability density, not the probability of being dead at that time. If the last recorded living state is , the mixed panel and exact-death likelihood factor after an interval isThis sums over the unobserved living state immediately before death.
Conditioning on the recorded initial states, the contribution of the three displayed patient histories isIn this irreversible illness-death model, , and , simplifying it toThe factor is essential: the death time is known exactly. Replacing the final statistical probability density by would instead model interval observation of death and give a different likelihood.
The assumptions are independent patient histories with common rates; the Markov property; constant rates over calendar/follow-up time in this model; the stated absence of recovery and absorption at death; accurate state labels and death times; and an observation/follow-up mechanism that is noninformative for the latent process given the observed history. Clinic dates are conditioned on. The displayed living endpoints contribute only the shown observations, with noninformative right censoring if they are follow-up endpoints. Initial state probabilities are omitted by conditioning on them. Progression between visits can be unobserved, which is precisely why panel-observed multi-state likelihood uses the matrix exponential rather than assuming a transition occurs at a visit.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06In a time-homogeneous continuous-time Markov chain, a state's holding time is exponential with rate equal to its total outgoing transition intensity. Converting the specified times to months givesThe exit-type probability follows by dividing its transition intensity by the total exit rate. ThereforeThese are starting values for numerical estimation, rather than further observations or constraints on the final fitted rates.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14There are three free transition intensities: progression, death from the initial state, and death from the advanced state. In the three-state illness-death model, state 3 is an absorbing state, and there is no recovery transition.
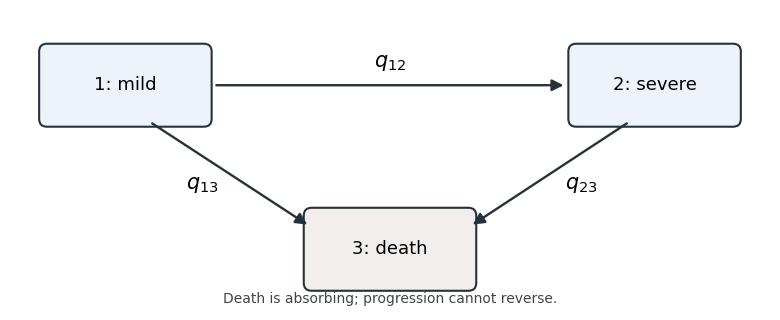
Writing , and , with all three nonnegative, the transition intensity matrix isEach diagonal entry is minus the sum of the row's outgoing transition intensities, rather than an additional unknown parameter. A continuous-time multi-state model with these rates describes the severity labels in the observations; an explicit cured state would require a richer state space.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 1 f Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Use a Rao-Blackwell estimator after interim selection, which is exactly conditionally unbiased. The second-stage sample mean alone is unbiased conditional on continuation, but discards the earlier observations. Apply the Rao-Blackwell theorem by averaging conditional on the combined sample mean and the fact of continuation.
Set and . Before truncation, is , a distribution whose mean no longer involves the unknown . After imposing , its mean is . Since , the resulting estimator isIt uses the outcomes from both stages through their combined sample mean. By iterated expectation, , so its conditional estimator bias is zero, compared with the strictly positive estimator bias above. Its conditional variance is no larger than that of the second-stage-only estimate. This does not assert a smaller mean squared error than every biased estimator.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 1 e Solution by Codex 0 Created 2026-10-03 Updated 2026-11-05
Codex 0 Created 2026-10-03 Updated 2026-11-05Let and denote the first- and second-stage sample means, let , and write . Continuation is the selection event . The second-stage sample mean stays independent of , so . The first-stage sample mean has a truncated normal distribution. With and the upper-tail inverse Mills ratio ,The positive conditional selection bias after futility continuation comes from selecting unusually large first-stage outcomes. The unconditional sample mean of a fixed observations would be unbiased; that is a different sampling distribution from the one restricted to continued trials.
As , , and , so the estimator bias tends to zero. It decreases with : differentiating gives , because for a standard normal random variable. Thus
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 1 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-25
Codex 0 Created 2026-10-03 Updated 2026-10-25Set . Under the null hypothesis rejection requires both and . Since has the standard normal distribution,The bivariate normal distribution in the preceding calculation has a nonsingular covariance matrix and strictly positive statistical probability density everywhere. For every finite futility boundary and , the open rectangle has positive probability. ThereforeFor an explicit expression, conditional on the full-sample statistic is under the null hypothesis, yieldingThe type I error is reduced because some otherwise rejecting paths stop for futility. Equality is approached as , but does not hold at a finite futility boundary.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Write , , and let be independent standard normal random variables obtained by centering and scaling the separate stage means. ThenThe second statistic uses all patients, so the statistics are correlated even though the stages' new observations are independent. Their covariance is and each variance is one. This gives the exact bivariate normal distributionUnder the null hypothesis both means are zero. At replace by ; the mean vector is . In this group sequential design the full-sample statistic may be viewed as a potential statistic from the underlying sequence of outcomes, even on paths where recruitment stops.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 32 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Let denote a quantile of the standard normal distribution. Reject when . The statistical power at the specified positive effect isEquating this to and using gives . Thus, for the usual target ,Rounding up ensures at least the target statistical power. This normal-mean sample size calculation assumes a positive integer sample size; if a requested power is at most , every positive sample size already exceeds that target for , and one should not square a negative quantile sum to impose an unnecessary lower bound.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 31 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Conditional on , summing the individual independent Poisson counts gives . The between-year conditional independence makes the likelihood functionMultiplying by the gamma distribution prior density, proportional to , gives the Poisson-gamma conjugacy with unequal exposures:For an action , the posterior squared-error loss decomposes asHence the Bayes estimator under squared error loss is the posterior mean, givingFuture counts are independent of the observed years conditional on , so the law of total expectation then gives the posterior predictive expected countThe Bayesian and credibility estimates coincide exactly. This exact Bühlmann–Straub credibility for Poisson-gamma counts occurs because the posterior mean is already affine in the exposure-weighted experience, and therefore belongs to the class over which the credibility estimate minimizes mean squared error.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 31 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Use the gamma distribution shape-rate convention: with . The conditional Poisson distribution has mean and variance both equal to , so the Bühlmann–Straub model parameters areFor and , the Bühlmann–Straub credibility factor is . Thusand the required expected-count estimate isThe total exposure determines how much information the observed count carries; the number of years alone is not the appropriate denominator.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 31 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06For the original exponential distribution, cancel the nonzero root into obtainIt lies strictly below the transform pole .
With the extra expenses, the insurer's payment per claim is , where has exponential distribution of expected value and is independent of . The convolution of independent random variables gives a hypoexponential distribution withKeeping the relative safety loading fixed means using the new expected payment: the premium rate becomes . It does not mean keeping the old premium rate fixed. The adjustment coefficient with independent claim expenses therefore solvesSet , cancel , and simplify:The quadratic is positive at and equals at . Its leading coefficient is positive, so the smaller root is in and the larger root exceeds . Only the smaller root lies in the finite moment-generating function domain. HenceFor ,Thus the new adjustment coefficient is about smaller, even though the premium rate has been increased to retain the same relative safety loading. The Lundberg inequality consequently has a slower exponential decay rate as a function of capital.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 31 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Consider the secant slopeThe moment-generating function is continuous on the interior of its finite domain and has right derivative . Thus as . For every fixed positive claim amount , the function is strictly increasing in : its derivative has numerator , since this numerator starts at zero and has derivative as a function of . Taking expected values preserves the strict inequality. Therefore is continuous and strictly increasing. Equivalently, the strictly convex transform has strictly increasing secant slopes from the origin.
If , the assumed blow-up of gives . If , choose with . Such an exists because the claims are positive. Then , so again . This exponential lower bound is needed at an infinite endpoint: mere divergence of would not, by itself, establish divergence of .
The target strictly exceeds the limiting slope . The intermediate value theorem and strict monotonicity therefore giveMultiplying by gives the defining adjustment coefficient equation. The zero root of the undivided equation is excluded. This is the secant-slope existence criterion for an adjustment coefficient.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 31 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06The moment-generating function of a mixture distribution is the mixture of its component transforms, soFor the aggregate, positivity of every claim implies exactly when . ChooseIf , take to have the zero-truncated claim-count distribution, namely the conditional law of given . ThenChoose this count independently of a fresh independent claim-size sequence and put . Its probability distribution is that of conditional on being positive. Thus the hurdle decomposition of a positive random sum givesand an independent Bernoulli random variable of success probability realizes . This establishes the distributional representation, including that is itself a positive random sum of independent claims. If , the aggregate is identically zero; set and choose any positive , for example one claim. Conditioning the count on positivity is then unnecessary and would be undefined.
For the specified geometric distribution on the nonnegative integers,An exponential distribution of expected value has transform . Substitution yieldsHence is exponential with rate and expected value . This is the geometric sum of exponential variables with a rescaling of the claim mean. Identification can also use the uniqueness theorem for Laplace transforms of nonnegative random variables by taking .
The resulting distribution function isIts jump of size at zero is important: the aggregate law is not a purely continuous exponential distribution.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 31 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Condition on the count and use the independence of random variables of the claim sizes. For their joint exponential transform factors, while for the empty sum contributes . Consequently the law of total expectation givesThis random sum of independent claims transform uses both independence assumptions: the count must be independent of the entire claim-size sequence, and the sizes must be mutually independent with the same probability distribution. The probability generating function is interpreted through its defining nonnegative series. The identity holds as a finite moment-generating function wherever that series is finite; outside that domain the expectation and series can agree at . In particular a positive argument may take beyond , so finiteness does not follow merely from the usual unit-disk domain of a probability generating function.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 3 6 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06For the Kronecker quiver representation with arrows and , an endomorphism satisfies and . Solving the second equation givesThus this representation is indecomposable but is not a brick: its endomorphism ring is a local endomorphism ring, while the nonzero endomorphism is nilpotent.
For a general indecomposable non-brick, the proof of Ringel lemma on bricks finds a proper indecomposable submodule with nonzero self-extensions. Repetition in strictly decreasing dimension reaches a brick module with . The linked proof supplies the minimal-rank, retraction and hereditary-extension steps.
Now assume the Tits form of a quiver is positive definite. If an indecomposable were not a brick, this would give the contradictionHence is a brick. For its nonzero dimension vector , positivity and integrality then implyThus every indecomposable in this case is a rigid brick. This deduction uses the Ringel lemma on bricks and the Ringel form, without requiring the full Gabriel theorem.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 3 6 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06A nonzero finite-dimensional representation is a brick module when its endomorphism ring is a division algebra. Over the algebraically closed field , this means : for any endomorphism , an eigenvalue makes noninvertible, hence zero in a division algebra.
For a counterexample to the converse of “brick implies indecomposable”, take the one-loop representation with nilpotent Jordan block . Its endomorphism ring is , a local endomorphism ring of dimension two. It has no nontrivial idempotents, so the module is indecomposable, but it is not a brick.
For the one-arrow quiver, splitting the kernel, image and target complement decomposes any representation into copies of , and . Each has endomorphism ring . Therefore every indecomposable of the one-arrow quiver is a brick.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 3 5 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-06
Codex 0 Created 2026-10-03 Updated 2026-10-06Write the two arrow matrices as . The base change action on quiver representations sends them to . Starting from yields precisely the pairs with both matrices invertible: given such a pair, choose , , . HenceThis is a nonempty Zariski-open subset of the irreducible affine space , so its closure is the entire representation space. Its boundary in that closure is .
The rank classification of a two-step linear map says an orbit is determined by . Indeed, the six interval multiplicities from the elementary decomposition areThey are nonnegative exactly when and . Apart from the open orbit , there are nine boundary orbits. Put and ; representatives areThe two rank-one/rank-one cases differ by whether ; the individual arrow ranks alone do not distinguish them.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact