Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 2 iv Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
Take , , , and . The coefficients are bounded and the operator is uniformly elliptic. If a weak solution existed, testing its weak formulation with would giveBy integration by parts for functions, the first integral on the left is , so the left side is zero. The right side equals , a contradiction. ThusThe forcing is not orthogonal to the homogeneous zero-boundary eigenfunction . This is the obstruction described by the Fredholm alternative for an elliptic Dirichlet problem, proved here directly without assuming that theorem.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 2 iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Symmetry implies that all eigenvalues of lie between and , so . In particular the bilinear form from part (i) is bounded and symmetric under the printed assumptions. The symmetric elliptic Dirichlet energy with a nonpositive potential isAll its terms are finite. For an admissible variation , its first variation is . Thus stationarity is exactly the weak formulation of .
Here is the direct method in the calculus of variations. Put . Expanding the symmetric quadratic form givesThe Poincaré inequality controls by . Therefore is bounded below on the admissible class, and a minimizing sequence is bounded in . By weak compactness in this reflexive Banach space, a subsequence converges weakly to . The affine closed subspace is weakly closed, so remains admissible.
The symmetric square root is measurable and bounded. Since , the two bounded linear mapstake weak convergence to weak convergence. The weak lower semicontinuity of the Hilbert norm shows that is weakly lower semicontinuous. The term is weakly continuous. Hence and attains the minimum. Varying in either sign yields the weak equation.
The sign was used both to make the potential energy nonnegative, hence weakly lower semicontinuous by this argument, and to obtain coercivity. Finally for , since the first variation at vanishes. Therefore
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 2 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14There is a qualification in the printed hypotheses: quadratic ellipticity does not bound a nonsymmetric coefficient matrix. The intended standard existence proof needs , or more generally a bounded principal bilinear form. To see why this does not follow from the displayed inequalities, take andThen for every . However, choose equal to , respectively, on a small rectangle about the origin. There , whose positive part has infinite integral. Thus the standard principal pairing is not a finite Lebesgue integral even for these smooth test functions. This demonstrates the missing form hypothesis, rather than assuming that all unbounded skew coefficients prevent solvability.
Under the intended bounded-coefficient hypothesis the proof is as follows. On use the Hilbert space norm , equivalent to the norm by the Poincaré inequality on a bounded domain. The form from part (i) is bounded, sinceIt is a coercive bilinear form even without symmetry:Here the nonpositive sign of is essential. With , the required equation becomesThe Cauchy-Schwarz inequality, bounded coefficients and the Poincaré inequality show that is a bounded linear functional on . The Lax-Milgram theorem states that a bounded coercive bilinear form on a real Hilbert space represents each bounded linear functional in this way with a unique . It therefore yields with the required boundary condition and weak equation. For completeness, if are solutions, satisfies ; coercivity and the Poincaré inequality imply .
With the missing bounded-form hypothesis, the weak solution exists and is unique. For nonsymmetric matrices the printed quadratic inequalities omit the hypothesis needed for this standard formulation and proof. No maximum principle is used. In part (iii), symmetry makes the quadratic upper bound a bound on the whole matrix, so no such qualification is needed there.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 2 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write and . The Dirichlet boundary condition in the Sobolev space sense means ; this definition remains meaningful even without regularity assumptions on the boundary. For bounded full coefficients, a weak solution is a function satisfyingwhereThe sign follows by integration by parts in . No classical derivatives of the measurable coefficients are taken. Equivalently one may first test against and extend by density, provided this bilinear form is bounded on . All integrals in this definition must exist: as explained below, the printed quadratic bounds alone do not guarantee this when is nonsymmetric.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 1 v Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14No: the conclusion need not survive without an additional restriction at infinity. A counterexample that keeps the functional finite is and . The distinct functions and both lie in and have energy zero. Their boundary data agree because is empty. For any variation with finite gradient energy,so both are genuine critical points, not merely formal solutions with infinite functional value.
With nonempty boundary, the classical Euler-Lagrange equation also illustrates the missing condition: in dimension , on , both and are harmonic functions with zero boundary values. The latter has finite Dirichlet energy, because its gradient-energy integral is proportional to , and is stationary under compactly supported variations. It approaches at infinity while the zero solution approaches .
This is nonuniqueness of Dirichlet data without control at infinity. For a global variational formulation one must specify the admissible variations: the exterior example is not critical against every finite-energy zero-boundary variation, since varying it in its own direction changes its energy to first order. Prescribing an appropriate limit at infinity, or a variational space in which the difference is an admissible zero-boundary test function and constants are excluded, can restore uniqueness.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 1 iv Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be two critical points with the same classical boundary values, and put . Since is independent of , the Euler-Lagrange equation for each is . By the fundamental theorem of calculus along the segment between the gradients,Subtracting the equations gives . The uniformly convex variational integrand makes symmetric and uniformly elliptic with the same positive lower bound. Since is smooth and , is continuously differentiable locally in , sois a classical nondivergence-form elliptic operator with no zeroth-order term.
To avoid assuming that derivatives of stay bounded all the way to the boundary, apply the proved weak maximum principle on inner open sets . Their closures lie compactly in , so all linearized coefficients there are bounded. The maximum principle applies on each component and yieldsEvery point of the inner boundary is at distance from . Since is continuous on the compact closure and equals zero on that boundary, the right-hand side tends uniformly to zero as . Every fixed interior point eventually belongs to , provingThis establishes uniqueness for uniformly convex gradient Dirichlet problems using precisely the boundary continuity and ellipticity needed for the comparison.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 1 iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14On the bounded interval , take and . Its principal coefficient is , so the operator is uniformly elliptic, andThusThe positive zeroth-order coefficient permits a zero-boundary eigenfunction, demonstrating failure of the weak maximum principle with a positive zeroth-order coefficient. The function similarly violates the lower bound.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 1 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The weak maximum principle for elliptic operators gives the clipped boundary boundsIf , constants solve the equation, and applying these bounds after subtracting the boundary maximum or minimum gives the sharper conclusion that both extrema occur on the boundary. For , the clipping by zero is necessary in the general statement.
To prove the upper bound, write and , and choose large enough that . For , uniform ellipticity givesPut . Then . If had a positive maximum at an interior point, its gradient would vanish there and its Hessian matrix would be negative semidefinite. Only the symmetric part of contracts with this Hessian, and its positive definiteness implies . Also . These facts would give , a contradiction.
Since is compact and is continuous on it, its maximum exists. It is therefore either nonpositive or attained on the boundary, proving . The exponential is bounded on the bounded domain; letting proves the upper estimate. Apply the same argument to for the lower estimate. This is the exponential perturbation proof of the weak maximum principle with drift and requires no continuity of the coefficient functions.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 12 1 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Take a compactly supported smooth variation and set . Its support is away from the boundary, so it preserves any prescribed boundary values. Differentiating the functional at gives the first variationBy integration by parts, there is no boundary term. The fundamental lemma of the calculus of variations therefore gives the Euler-Lagrange equationExpanding the total derivative, an equivalent classical form isRepeated indices are summed. In the last term involving , the derivative holds fixed; the other terms account for their dependence on . Compactly supported variations derive the interior equation without imposing a natural boundary condition.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 4 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the population as exposure regardless of whether a population-size category is also a covariate. Define a demographic factor with levels for at most 20%, for %, and above 30%; define if following the suggested population dichotomy. Treat village-size codes as a categorical variable, not equally spaced areas.
A candidate multivariate Poisson generalized linear mixed model retains the random intercept and slope from part (c) and usesThis specifies the suggested village-size-by-population interaction while keeping its main effects. One may add selected time-by-covariate interactions to explain slope heterogeneity, provided information from 32 clusters supports them. Compare continuous demographic and population formulations as a sensitivity analysis: categorization loses information, and the coefficient of a size category measures association beyond the already included exposure effect.
Fit models with the same likelihood convention and conditional distribution when comparing Akaike information criteria; use joint fixed-effect likelihood-ratio tests, boundary-aware parametric bootstrap tests for random effects, residual diagnostics and village-level cross-validation to justify a parsimonious final model. Preserve interactions' main effects and report interval estimates from the final multivariate model, rather than interpreting separate univariate fits. For example, the adjusted inland-versus-coastal rate ratio is , while a medium-versus-small village ratio is ; a Wald interval for that contrast uses the full coefficient covariance matrix. Conditional time effects and standardized marginal predictions should be distinguished.
The displayed rows cannot identify this final model: population exceeds 250 in every displayed village-year, no large village is shown, and inland status is confounded with the identity of the two displayed villages. The complete 160-row file is needed for fitted effects, model selection, all-village plots and uncertainty. No numerical best model or evidence of the specified covariate associations can honestly be reported from this excerpt.
Finally, even a significant adjusted association with young-male percentage would not show that young males were involved in most incidents. This is the ecological fallacy, specifically that aggregate composition does not identify offender composition: the same village counts can be assigned to different individual age and sex groups without changing any observed aggregate predictor. Individual incident-level age, sex and involvement records are required to answer that last question. The aggregate dataset cannot establish the claimed majority involvement.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 4 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Center time at 2008 by setting , and initially ignore the explanatory covariates. A Poisson generalized linear mixed model addressing both heterogeneity questions isHere describes between-village variation of log rates in 2008, while describes heterogeneity of annual log-rate changes. The latent 2008 rate has median , mean and coefficient of variation . A central 95% interval for latent village rates is ; the corresponding interval for village-specific annual rate ratios is . These describe heterogeneity, not confidence intervals for estimated fixed effects.
Fit an intercept-only random-effects model and then add a correlated random slope. Compare them with a parametric bootstrap of the likelihood improvement: the null slope variance is on the boundary, so an ordinary fixed-effect chi-squared reference is not automatically valid. Inspect uncertainty in both variance components, shrinkage of village-specific estimates, residual overdispersion and remaining serial correlation. A negative-binomial conditional model can distinguish additional within-village count variation from persistent village differences when the data support it.
By the marginal mean of a Poisson random-slope model, the marginal log rate is , so marginal curvature can arise even when each village has a straight conditional log trend. Numerical variance estimates and evidence of heterogeneous slopes cannot be obtained for 32 villages from two displayed trajectories.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For a population-averaged rate trend, use the marginal incidence trend with clustered observations modelFit a generalized estimating equation with village as cluster, a log link and an appropriate working correlation; estimate uncertainty with a village-level sandwich covariance matrix. Then is the fitted annual marginal rate ratio, is the annual percentage rate change, and is the four-year endpoint ratio. Test using cluster-robust uncertainty, with a small-sample correction or village-resampling bootstrap given only 32 independent clusters. Also compare year as a factor with a linear trend, since a single slope can conceal nonlinear behaviour.
Report which population is averaged over. The directly pooled rate is exposure weighted; a mean of village rates gives each village equal weight. For standardized comparisons one can use the same village weights at every year, preventing changing population composition from masquerading as a rate trend.
A conditional random-slope coefficient cannot simply be substituted for the marginal slope: the marginal mean of a Poisson random-slope model contains time-dependent variance terms. A direction, magnitude and confidence interval for the trend across all villages require the missing full dataset. The increase in the two displayed villages does not determine the trend in the other thirty.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use incident counts divided by that village-year's population exposure , and graph against calendar year. Show separate small panels or labelled lines for all villages; a population-weighted overall line answers a different question from an equally weighted average village rate. A plot of counts alone can mistake population change for a rate change.
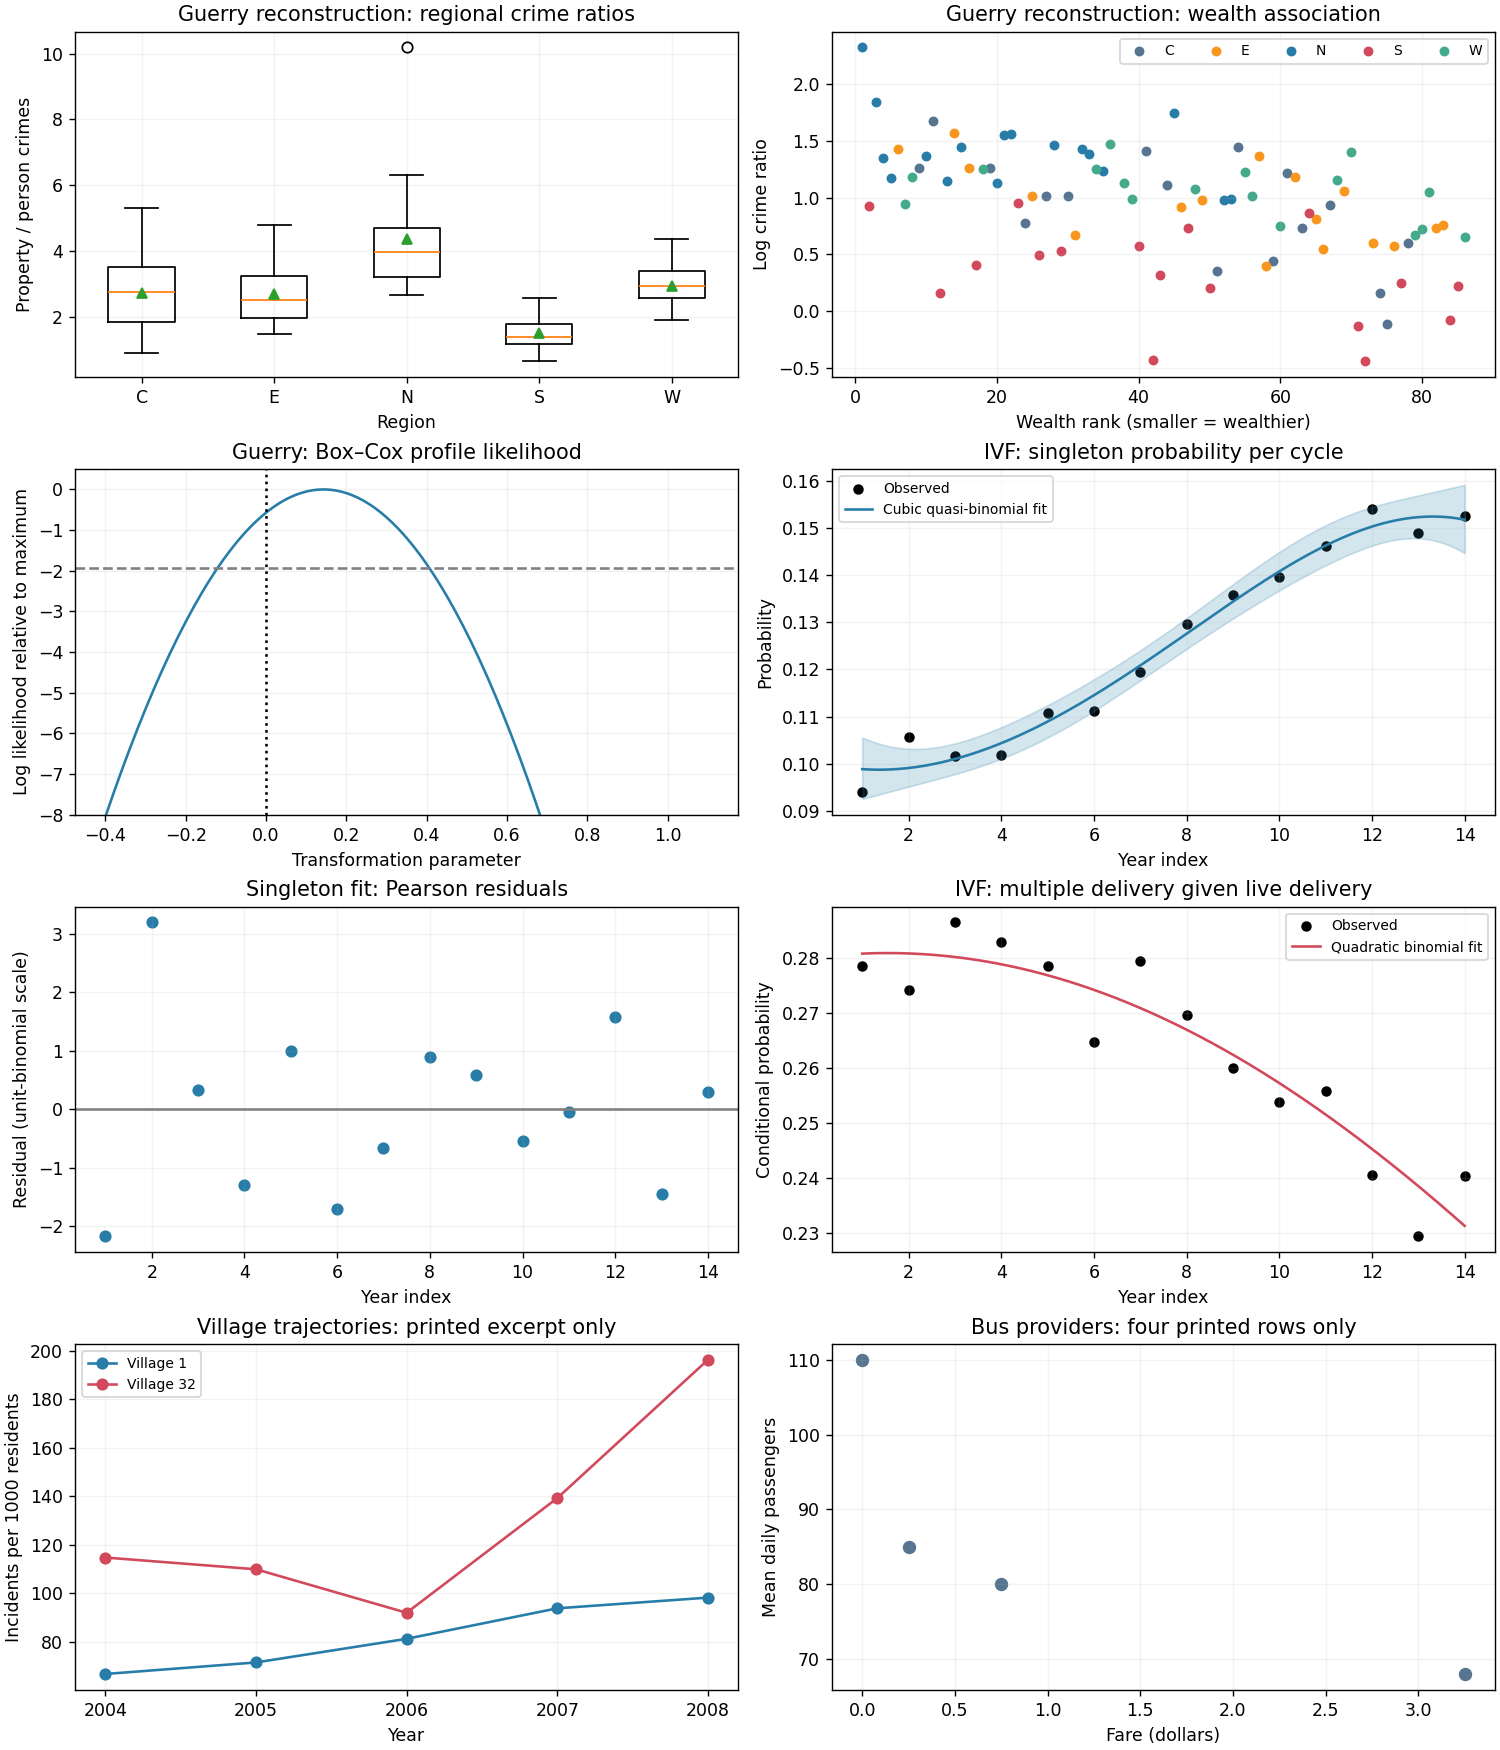
For the two printed villages, the observed rates per thousand residents are approximatelyThe first trajectory increases throughout; the second falls initially and then rises sharply. The last-to-first rate ratios are and , respectively. The figure displays these two observed trajectories only. The other thirty village trajectories cannot be drawn from the PDF, because their observations were supplied in the separate emailed dataset.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 3 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Preserve the original row order and set for the first eight fixed-route providers and for the twelve on-demand providers. A suitable group comparison builds on a selected small predictor set :The model with pools service types; adding changes the baseline; adding selected components of allows different predictor dependence. Center at meaningful values so that compares groups at those values. The predictor-specific rate ratio is in the fixed-route group and in the on-demand group; the group ratio at predictor value is .
Fit common-slope and selected-interaction models, respecting model hierarchy by retaining corresponding main effects. Test the added interaction block jointly with a likelihood-ratio test, or an appropriate quasi-likelihood comparison under estimated dispersion, and check group-specific residual patterns and leave-one-provider sensitivity. Seven interactions plus all main effects would use 16 parameters for just twenty providers and leave only four residual degrees of freedom; an indiscriminate full interaction model is consequently a poor basis for stable inference.
The excerpt contains only , so neither the service-type effect nor any interaction is estimable from it. Full-data estimates could distinguish a baseline difference from genuinely different slopes, but the printed records cannot establish either conclusion.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 3 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be passenger count and use a Poisson regression with log mean, initially treating the response as a working daily count:Center and scale the continuous predictors before fitting, and compare a small set of defensible reduced models rather than saturating twenty observations. Household counts should not be called household proportions without a household denominator; population-scaled counts are alternative intensity covariates. Bus miles can be an estimated elasticity term rather than an offset, since proportionality of passenger numbers to bus miles has not been established.
For actual counts, the log-likelihood score is , with . Fitting by iteratively reweighted least squares uses weights and working response . Compare nested means by a likelihood-ratio test only if the Poisson variance assumption is plausible; check the Poisson deviance, Pearson dispersion , residuals, leverage and sensitivity to influential providers. Consider Quasi-Poisson regression or negative binomial regression if variance exceeds the mean.
The recorded response is actually a daily average, so Poisson working models for averaged counts need special care. If a provider was observed for days and total passengers were , fit with offset . If only the average and no observation duration are available, a Poisson mean model can still be explored, but its likelihood and standard errors are not automatically justified by integer-looking averages.
A one-unit increase in an untransformed predictor has fitted multiplicative mean effect ; a bus-mile elasticity gives a doubling effect . No numerical coefficient estimates or selected twenty-provider model are identifiable from the printed excerpt. The full provider file and, ideally, the averaging periods are needed to execute these model comparisons.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Only four of the twenty provider records are printed, and the full emailed file has not been recovered. The four observed passenger averages have mean , median , sample standard deviation and range --. Their bus-mile mean is , with range --; the highest passenger average belongs to the provider with the lowest bus miles and zero fare. That is a useful diagnostic of differing service patterns, not evidence of a population-wide negative mileage effect.
For the complete dataset, use scatter plots of passenger average against bus miles, fare and population, and inspect population-scaled demographic counts as well as their raw counts. Compare marginal distributions and the sample correlation matrix, especially among population, older residents, low-income households and poverty households: these measure overlapping aspects of area size and composition and can create multicollinearity. Inspect the zero fare directly; a logarithm of fare is undefined there, so do not silently drop it. All four displayed rows belong to the fixed-route group, so they cannot support a between-service comparison.
The figure labels its bus panel as a four-row excerpt. Twenty-provider summaries and exploratory conclusions cannot be determined from these four rows. In particular a full eight-parameter regression has more parameters than observed rows; reporting a fitted full-data model from this excerpt would be unjustified.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 2 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The correct denominator is the number of live deliveries , not treatment cycles and not babies. Define and use ; this is the distinction in denominators in grouped birth-outcome models. The observed conditional multiple-delivery proportion is initially and finally.
A constant logit has residual deviance on 13 degrees of freedom. A linear-year fit gives , deviance on 12 degrees of freedom (), and annual odds ratio . A quadratic term improves the deviance by on one degree of freedom (), whereas a further cubic improvement is only (). A supported parsimonious binomial model isIts residual deviance is on 11 degrees of freedom (), and Pearson statistic is , with no detected excess dispersion. The binomial standard errors are ; approximate 95% Wald confidence intervals are , , and . The annual odds multiplier is , describing near-flat early behaviour and a stronger later reduction, rather than a uniform annual decrease.
As a secondary check, modelling the triplet-or-higher share alone among deliveries needs curvature: its quadratic logit has residual deviance on 11 degrees of freedom, compared with for a straight line. Multiple delivery became less likely conditional on a live delivery, especially later in the series; higher-order multiples declined particularly strongly. This conditional probability is separate from the probability of any successful live delivery per cycle.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use grouped-binomial logistic regression, and . Center the year as . Maximizing gives score and information ; these determine the estimates and working covariance matrix.
A straight-line logit fit is , with naive binomial standard errors and . Its yearly odds multiplier is , with naive 95% Wald confidence interval . However, its residual deviance is on 12 degrees of freedom (), so those small standard errors do not describe an adequate independent-binomial fit.
Comparing polynomial mean structures gives residual deviances for degrees zero through three, with respective residual degrees of freedom . A quadratic term alone adds little; the cubic structure captures the middle-period acceleration and later leveling. Even the cubic independent-binomial fit has for its residual deviance goodness-of-fit test. A useful working model is therefore cubic quasibinomial regression, retaining the logistic mean and estimating overdispersion rather than claiming an exact binomial law:The Pearson estimate is . Using standard errors multiplied by and a reference, the approximate 95% coefficient intervals are , , , and . An approximate quasi-deviance comparison of cubic against linear gives and , supporting the added shape while acknowledging that only fourteen annual groups inform dispersion.
In this preferred mean model the odds change is not constant:The fitted annual change is larger around the middle than at the ends; the straight-line 4.6% increase is a useful overall summary, not an exact yearly effect in the cubic model. The fitted curve, uncertainty band and residual plot appear in the figure. Singleton success increased overall, but a constant log-odds trend with unit binomial dispersion fits poorly. Quasibinomial intervals remain working-model intervals: serial dependence, changing patient mix and treatment practices cannot be separated from annual aggregates alone.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be singleton deliveries among treatment cycles. Under a common-probability binomial distribution model, independently across years. The pooled maximum-likelihood estimator isThe Pearson chi-squared test of homogeneity compares singleton and non-singleton counts across all fourteen years, usingAll expected cells are large. One probability has been estimated, so the reference chi-squared distribution has 13 degrees of freedom. Numerically,The constant singleton-per-cycle probability is decisively rejected under the independent-binomial model. The observed proportion rises from to . Dependence between repeated treatments or patient heterogeneity can invalidate literal binomial precision, but they should be addressed by an explicit variance model rather than ignored.
Past exam of the mathematics course of the University of Cambridge 2009 iii Paper 102 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14If a department has population , crimes against persons and crimes against property, cancellation of the common numerator givesThus is a property-to-person crime count ratio, not its reciprocal. Both counts must be positive for the printed ratio to be defined.
For the reconstructed 85-row data, fit a normal linear model for the Box–Cox transformation , including four region contrasts plus Literacy, Donations and Wealth. With and , the profile likelihood, up to constants, isThe second term is the transformation's Jacobian determinant; omitting it would incorrectly compare different response scales. Maximization gives , with approximate 95% likelihood-ratio confidence interval . The logarithmic transformation is inside this interval, whereas the raw-scale choice is far outside: the twice-log-likelihood drops at zero and one are and , respectively. A log-response model is therefore a simple supported choice.
In the full log model, partial F-tests give for Region (), for Wealth (), and for Literacy and Donations. Dropping Literacy and Donations together gives and . A parsimonious final normal linear model, with C as reference and , isThe standard errors in that order are ; residual standard deviation is on 79 degrees of freedom and . Use residual-versus-fitted and quantile-quantile plots, influence diagnostics and checks for remaining curvature to assess the working Gaussian model; the small p-values alone do not validate its assumptions.
Holding Region fixed, worsening wealth rank by ten positions multiplies the fitted conditional median ratio by . Relative to C at the same wealth rank, the fitted median multipliers are for E, for N, for S and for W. Region and wealth rank explain much of the variation; Literacy and Donations add little once those terms are included. These are associations in the reconstructed dataset. Back-transforming the fitted log mean gives a conditional median under lognormal errors; estimating an original-scale mean requires bias correction after an inverse transformation. Also, the public archive's metadata describe some historical measures differently from the exam wording, so the fitted Donations effect is interpreted only on its recorded scale.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact