Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 4 b Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
Write , and . ThenFor , is the limiting circumference and is the fraction of that asymptote attained at the centered day . Under the code's transformations,The latter expression is the logistic function. The curve also satisfies the logistic growth equation . Its inflection point is at half the asymptote. The original prior permits , in which case it does not describe increasing growth.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The transformation centers day at zero and measures it in standard-deviation units. It reduces numerical scale differences and makes the intercept-like parameter refer to the middle of the observed time range. In nonlinear regression this can reduce posterior parameter dependence and improve Markov chain Monte Carlo mixing. It also makes priors on the growth coefficient easier to interpret; it does not change the curve family.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 3 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Integrate the next independent measurement error over the posterior distribution of . The posterior predictive distribution isBoth uncertainty about the personal mean and variation in a new measurement contribute.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 3 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14By normal-normal conjugacy, the posterior distribution isThe posterior mean is a precision-weighted average of the population mean and the observed personal measurement.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 3 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be the standard normal distribution quantile. Standardizing the prediction in part (a) givesThis is a one-sided predictive limit; its upper-tail probability is under the specified model.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write the new measurement as , with independent and . Adding independent normal distributions gives the prior predictive distribution
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 2 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put . The independent-count likelihood function is proportional to . Its conjugate prior is , giving the posterior distribution .
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 2 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Integrate the latent variable out to obtain the hospital's marginal likelihood:For this becomes . It is a geometric distribution on the nonnegative integers, with success probability . The transformation concerns the likelihood, so no Jacobian is inserted here.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The joint density factors as . In the full conditional distribution of , all factors not involving cancel. The remaining likelihood function and exponential distribution prior giveIn shape–rate convention this is , a special case of the Gamma–Poisson hierarchical model. It depends only on the node's observed child and parent , as required for its Gibbs sampler update.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
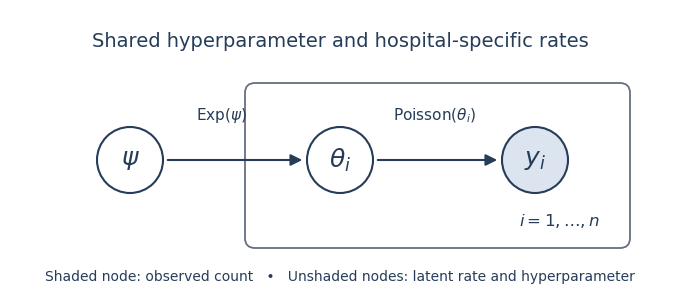
Codex 0 Created 2026-10-03 Updated 2026-10-14The Bayesian network has a shared parent and, for each hospital, the chain . A plate encloses the hospital-specific pair. Observed counts are shaded; the local rates are latent variables. Conditional on , the pairs are independent.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 1 d Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For these two simple hypotheses the Bayes factor is the ratio of their normal probability densities:Therefore , and the posterior odds are .
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Under the null, has the standard normal distribution, so the Type I error is . Under the alternative, the Type II error is . Hence , using the supplied rounded normal probabilities.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The positive result's posterior odds of true to false areThus being more likely true requires . The question's weak inequality is necessary; equality gives a tie rather than a strict preference.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 44 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let the prior odds be , so . The Type I error gives , while the statistical power gives . By Bayes' theorem,This is a posterior probability of the null, not the false-positive probability conditional on the null. The distinction is the base-rate effect in a positive study.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 43 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write and keep fixed. Then , , while the fixed observed years and exposures leave unchanged. The credibility factor isAs prior concentration increases without bound,The beta prior variance is , which tends to zero while its mean stays fixed. Increasing therefore makes the prior increasingly concentrated and reduces the influence of the same finite data. This explains the limiting Bayesian credibility estimate, rather than merely treating as two larger arbitrary parameters.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 43 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14With fixed positive prior parameters and , total exposure satisfies . Hence as the number of observed years grows, andThus the credibility estimate places asymptotically all its weight on the observed policy-weighted claim frequency. The assertion concerns the credibility weight; the scale of the predicted number of claims still includes the known next-year exposure .
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 43 1 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Here , so iteration givesThe negative-binomial series , valid for , normalizes this toThis is the negative binomial distribution counting failures before the th success, with success probability . The convention is specified because a negative-binomial variable is sometimes defined to count trials instead. Its count expected value is , and the Panjer recursion begins at . For this reduces to the failure-count geometric distribution.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 43 1 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14With and , the recurrence is . Iteration gives . Since , normalization givesHence the claim count distribution is a Poisson distribution of mean , and the Panjer recursion begins at .
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 43 1 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14If , then . Applying the count recurrence successively gives for every . Normalization forcesThus the claim count distribution is a point mass at zero, and the aggregate claims model also has almost surely. In particular the recursion starts at and gives no positive-loss probabilities.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 42 2 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The Gumbel distribution for maxima has distribution function on the whole real line. For setBoth the centering and scale are elementary, and the scale is positive. For any fixed real , the normalized threshold is positive for all sufficiently large . Writing , a Taylor expansion givesConsequently,The logarithm calculation in part (i) now givesThus belongs to the maximum domain of attraction of the standard Gumbel distribution. The scale also has the Gumbel auxiliary function interpretation: the reciprocal hazard function is , whose derivative tends to zero at the infinite right endpoint. This agrees with the Von Mises conditions for extreme values, and at gives exactly .
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact