Lossy compression reduces a representation while permitting irreversible changes to the original. The encoder can map distinct inputs to the same output, so its decoder cannot recover both originals exactly. The useful question becomes how much storage is saved for an acceptable amount of distortion: mean squared error is one numerical criterion, but it does not by itself measure how noticeable a visual change is.
For example, storing the arithmetic mean of four grayscale pixels retains their average shade while discarding their arrangement. Blocks and both produce 50. The former has detail and the latter is uniform, yet the decoder receives the same value. Lossy block averaging makes this ambiguity, its bit saving and its mean squared error exact.
This toy image compression method stores one rounded arithmetic mean for each disjoint block of grayscale pixels. The quantization rule is round to the nearest integer, with exact halves rounded upward. Each stored value is an unsigned eight-bit integer. Reconstruction fills the original block with that value, a form of nearest-neighbor interpolation. Averaging already discards information; rounding can discard more.
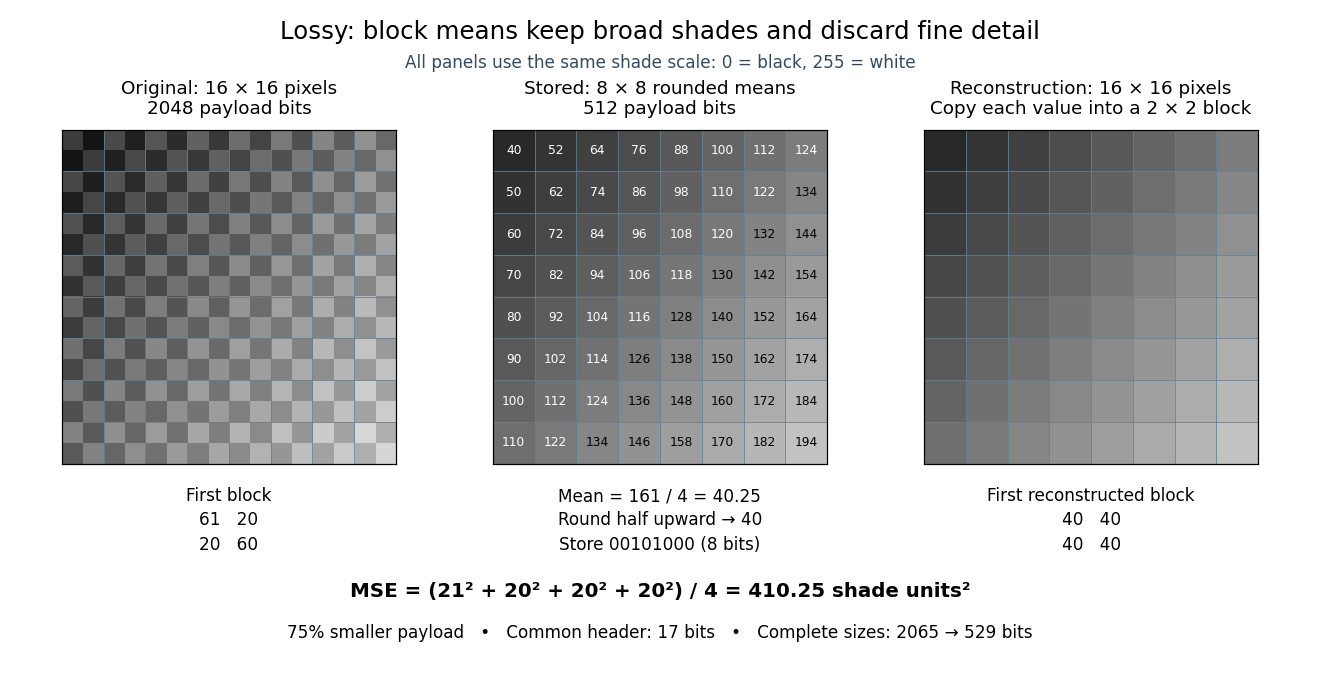
Here is an exact source array. Index rows and columns by and defineThe floor function makes constant within each block; the indicator function adds 1 only to its upper-left pixel. All values are integers from 20 to 215. Each block therefore has the exact formFor example, the upper-left block has arithmetic mean and is stored as 40. The block immediately to its right is stored as 52. The complete stored array is specified by for . Its first row is ; its last is .
This toy file format again has eight-bit width and height fields followed by a one-bit mode: 0 means raw eight-bit grayscale pixels, 1 means the rounded block arithmetic means. This profile accepts only width and height 16. The decoder knows the block size and reconstruction rule from the format, reads the 64 stored values in row order, and repeats each across its corresponding block. The original 256 pixels cost payload bits; the 64 stored values cost payload bits. The reduction is . These payload counts exclude the common 17-bit file header; complete sizes are 2065 and 529 bits, or 2072 and 536 bits after final zero padding to eight-bit units. There is no stored codebook or additional prediction rule.
The empirical mean squared error averages squared differences over the 256 original pixel positions:Every block has the same four errors, so this value is exact in squared stored shade units. If the unrounded arithmetic mean could be reconstructed, the error would instead be ; eight-bit quantization adds . That hypothetical comparison does not count fractional means as free eight-bit values.
The broad shade pattern survives, while the alternating bright and dark pixels vanish. Indeed, a second source with every block constant at produces the identical stored array : exact decoding of both sources is impossible. This makes the storage benefit and the lost detail visible at once. Block averaging is useful for a coarse preview when the individual pixels are dispensable; choosing an acceptable mean squared error or visual result is part of the application, not a guarantee supplied by the encoder.
Articles by others on the same topic

Lossy compression is a data encoding method that reduces file size by permanently eliminating certain information, particularly redundant or less important data. This technique is commonly used in various media formats such as audio, video, and images, where a perfect reproduction of the original is not necessary for most applications. **Key Characteristics of Lossy Compression:** 1. **Data Loss:** Some data is lost during the compression process, which cannot be restored in its original form.

