Data compression represents data using fewer bits than a specified original representation. The saving can reduce storage in a file system and reduce the number of bits sent through a communication channel. At a fixed transmission rate, fewer bits arrive sooner; this makes better use of a fixed transmission budget. Both the encoded data and the instructions needed to interpret them contribute to the size of a stored file.
There are two different promises. Lossless source coding preserves the original exactly: for an encoder and decoder , for every permitted input . Thus must be an injective function. Lossy compression allows to differ from , with the difference judged by an explicit criterion. A program or numerical record may require exact recovery; a preview image may tolerate altered pixels in return for fewer bits.
The appeal of lossless source coding is that repetition can be described rather than copied. Run-length encoding says "repeat this value twelve times"; a prefix code can give more frequent symbols shorter descriptions. These are distinct ways to exploit structure, and neither promises savings for every input. Image compression supplies especially visible examples of both lossless source coding and lossy compression.
Claude E. Shannon's 1948 paper made the role of probability distributions precise. For a memoryless classical information source with Shannon entropy bits per symbol, Shannon's source coding theorem bounds achievable average lengths; sufficiently long blocks allow exact codes to approach bits per symbol. This is a statement about a specified source and average lengths, not a promise to shorten every message.[ref]
Fix . There is no injective function from all length- binary strings to binary strings of length strictly less than . There are possible inputs, but even allowing the empty string gives onlypossible shorter outputs. The finite geometric series and pigeonhole principle leave at least two inputs sharing an output, which prevents exact decoding. For , eight inputs compete for the empty string and the six strings
0, 1, 00, 01, 10, 11.This counting argument includes any file header or other information sent to the decoder. An algorithm chosen separately for each input must also be identified to the receiver; its description is not free. A useful compressor saves space on some inputs while leaving others unchanged or making them longer. Lossy compression avoids the exact-recovery requirement by deliberately allowing several inputs to share an output.
Lossy compression reduces a representation while permitting irreversible changes to the original. The encoder can map distinct inputs to the same output, so its decoder cannot recover both originals exactly. The useful question becomes how much storage is saved for an acceptable amount of distortion: mean squared error is one numerical criterion, but it does not by itself measure how noticeable a visual change is.
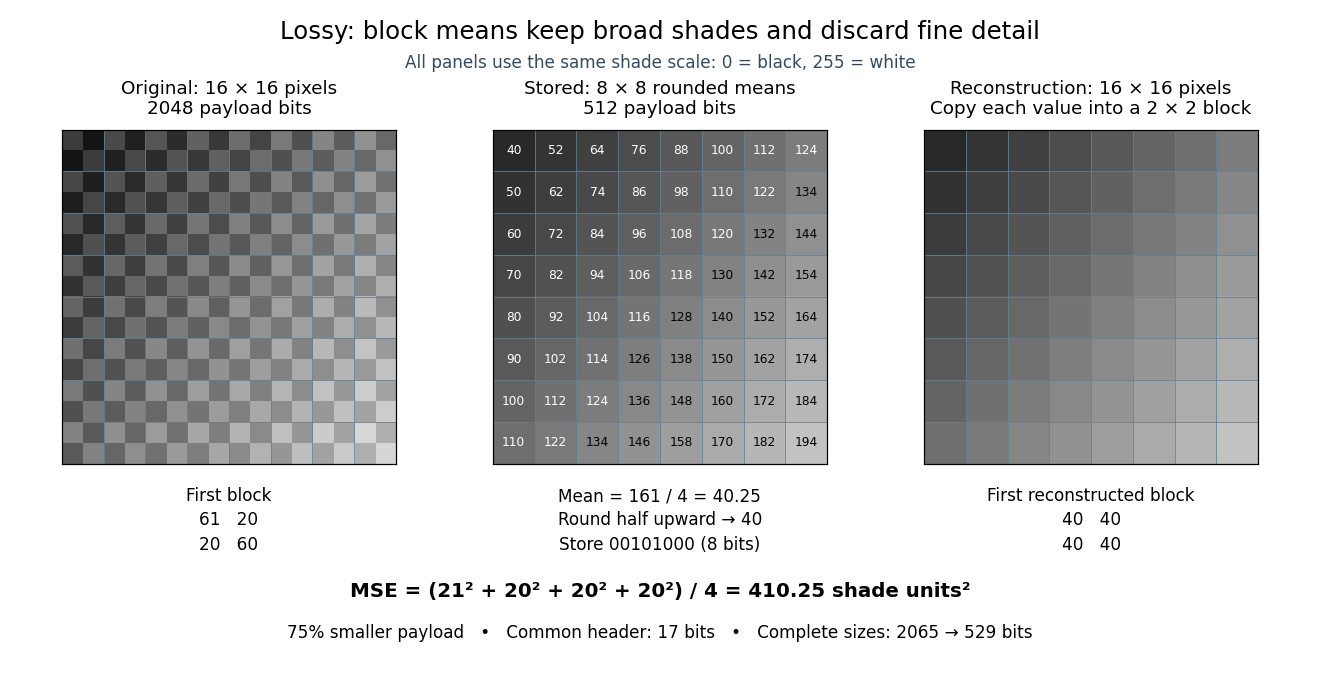
For example, storing the arithmetic mean of four grayscale pixels retains their average shade while discarding their arrangement. Blocks and both produce 50. The former has detail and the latter is uniform, yet the decoder receives the same value. Lossy block averaging makes this ambiguity, its bit saving and its mean squared error exact.
This toy image compression method stores one rounded arithmetic mean for each disjoint block of grayscale pixels. The quantization rule is round to the nearest integer, with exact halves rounded upward. Each stored value is an unsigned eight-bit integer. Reconstruction fills the original block with that value, a form of nearest-neighbor interpolation. Averaging already discards information; rounding can discard more.
Here is an exact source array. Index rows and columns by and defineThe floor function makes constant within each block; the indicator function adds 1 only to its upper-left pixel. All values are integers from 20 to 215. Each block therefore has the exact formFor example, the upper-left block has arithmetic mean and is stored as 40. The block immediately to its right is stored as 52. The complete stored array is specified by for . Its first row is ; its last is .
This toy file format again has eight-bit width and height fields followed by a one-bit mode: 0 means raw eight-bit grayscale pixels, 1 means the rounded block arithmetic means. This profile accepts only width and height 16. The decoder knows the block size and reconstruction rule from the format, reads the 64 stored values in row order, and repeats each across its corresponding block. The original 256 pixels cost payload bits; the 64 stored values cost payload bits. The reduction is . These payload counts exclude the common 17-bit file header; complete sizes are 2065 and 529 bits, or 2072 and 536 bits after final zero padding to eight-bit units. There is no stored codebook or additional prediction rule.
The empirical mean squared error averages squared differences over the 256 original pixel positions:Every block has the same four errors, so this value is exact in squared stored shade units. If the unrounded arithmetic mean could be reconstructed, the error would instead be ; eight-bit quantization adds . That hypothetical comparison does not count fractional means as free eight-bit values.
The broad shade pattern survives, while the alternating bright and dark pixels vanish. Indeed, a second source with every block constant at produces the identical stored array : exact decoding of both sources is impossible. This makes the storage benefit and the lost detail visible at once. Block averaging is useful for a coarse preview when the individual pixels are dispensable; choosing an acceptable mean squared error or visual result is part of the application, not a guarantee supplied by the encoder.
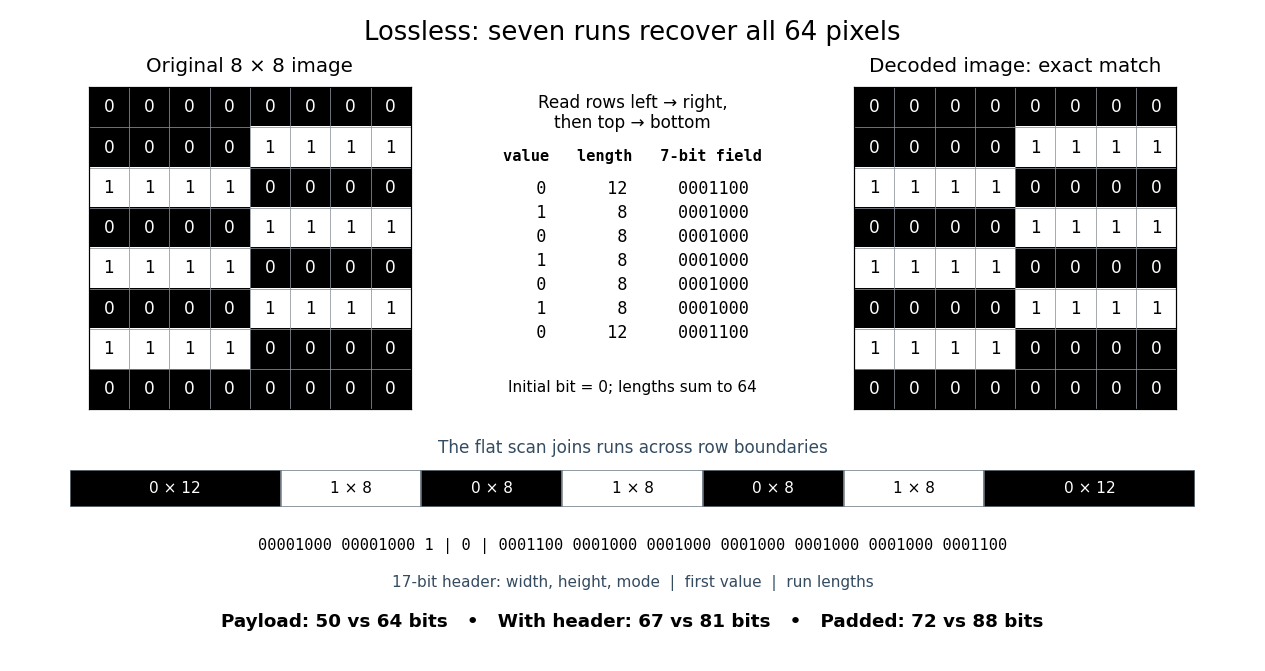
Run-length encoding replaces each maximal consecutive group of equal values, called a run, by its value and length. Decoding repeats each value the specified number of times. It is lossless source coding: no values are discarded. For a binary string, successive maximal runs alternate between 0 and 1, so storing the first bit and all run lengths is enough.
Take this raster image, with 0 black and 1 white, read left to right across each row and then top to bottom:Reading the whole image as one 64-bit binary string gives exactly seven runs:The lengths sum to . Repeating the alternating values for these lengths and splitting after every eighth pixel reconstructs every displayed row exactly.
00000000
00001111
11110000
00001111
11110000
00001111
11110000
00000000Here is a complete toy file format. Its file header is an eight-bit unsigned width, an eight-bit unsigned height, then a one-bit mode: 0 means raw pixels, 1 means run-length encoding. Fields are written most significant bit first; this profile accepts only width and height 8, so both decoders know to stop at 64 pixels. Raw mode contains 64 bits. RLE mode contains the initial bit, followed by seven-bit unsigned run lengths in the range 1 to 64. Zero and lengths above 64 are invalid; a decoder rejects a run that would exceed the remaining pixel count. It stops when the decoded lengths sum to 64, so no run-count field or end marker is needed.
For this image, the complete RLE serialization is:Spaces and vertical bars are explanatory separators, not stored characters. The seven-bit fields directly store the lengths; 64 would be
00001000 00001000 1 | 0 | 0001100 0001000 0001000 0001000 0001000 0001000 00011001000000. The payload costs bits, versus 64 raw bits. The 17-bit file header has the same size in either mode, giving complete sizes of 67 versus 81 bits. If packed into eight-bit units, append zero padding only at the end: the sizes become 72 versus 88 bits. These are sizes of this toy representation, not sizes of PNG files.The field design matters. Restarting RLE on every row costs eight initial bits plus four bits per run when lengths are stored directly: three bits represent only 0 through 7, whereas a row can have length 8. This pattern has row-run counts , totalling 14, so that payload costs bits, with no saving. Storing length minus one would instead fit lengths 1 through 8 into three bits, but is a different declared file format. An alternating flat 64-bit binary string has 64 runs and costs payload bits in our flat format; restarting each row costs payload bits. A one-run image costs only eight payload bits. These extremes explain when RLE is useful: long uninterrupted regions make short instructions, while frequent changes make instructions expensive.
Prefix codes of unequal lengths can replace fixed-width run lengths, provided the decoder knows the code and any necessary code description is counted. Run-length encoding names a technique, not one universal serialization. For a real implementation, Microsoft's bitmap documentation specifies
BI_RLE8 with count and value fields plus special commands, rather than our initial-bit convention.[ref]https://learn.microsoft.com/en-us/windows/win32/gdi/bitmap-compression. Microsoft, Bitmap Compression, BI_RLE8 encoded and absolute modes
Represent a row by sorted disjoint half-open intervals, each carrying a colour. Merge touching intervals precisely when their colours agree. The resulting ordered maximal runs form a canonical representation of occupancy and colour: equality of those runs is equivalent to pointwise equality, while ignoring arbitrary subdivisions inside one colour run. For two rows containing and intervals, constructing and comparing runs takes time complexity, independently of coordinate magnitude or interval lengths.
Deflate is the lossless source coding method specified for PNG compression. It can describe repeated stretches of earlier data, going beyond the single-value repetitions of run-length encoding.[ref]
Portable Network Graphics (PNG) Specification (Third Edition) by Mark Adler and others. W3C, PNG Specification, Third Edition, section 10.1, compression method 0
The format combines Deflate backreferences, which describe repeated stretches, with Deflate Huffman coding, which represents the resulting instructions using prefix codes. Deflate block framing tells the decoder which codes apply and where decoding stops. RFC 1951, DEFLATE Compressed Data Format Specification version 1.3 (May 1996), defines the format; different encoders can choose different instructions for the same input.[ref]
DEFLATE Compressed Data Format Specification version 1.3 by L. Peter Deutsch. RFC 1951, heading and sections 2 and 4: format and encoder choices
This separation is useful: discovering a repeated phrase and choosing short codewords solve different problems. A repeated phrase can contain many distinct bytes, while unequal codeword lengths can help even when no phrase repeats. Neither mechanism removes Deflate compression overhead or guarantees a saving on every input.
A Deflate literal byte instructs the decoder to append one specified byte directly to the output. For example, three Deflate literal bytes with values 65, 66 and 67 produce
ABC. These values are symbols in the Deflate Huffman coding stage, rather than necessarily eight raw stored bits each. A Deflate backreference instead describes a copy from earlier output.A Deflate backreference specifies a length and backward distance , measured in decoded bytes. If bytes have already been produced, append bytes starting at output index , counting indices from zero. The permitted ranges are and . Without a supplied initial history, is also required. The distance refers to decoded history, not a position in the compressed input.[ref]
For the twelve bytes
ABCABCABCABC, an illustrative instruction sequence is three Deflate literal bytes A, B, C, followed by the Deflate backreference . Run-length encoding sees twelve single-byte runs because neighbouring values differ; the Deflate backreference describes a repeated three-byte pattern instead. Conversely, a Deflate literal byte A followed by produces AAAAAAAA: distance one can express a single-value repetition. These are chosen instructional examples, not claims about an encoder's chosen instructions or complete serialized streams.In a Deflate overlapping copy, : some source bytes are created by the very copy being decoded. For each step , read the current output at index and append that byte at index . Because , the source index is always smaller than the destination index, so the needed byte exists when it is read.[ref]
DEFLATE Compressed Data Format Specification version 1.3 by L. Peter Deutsch. RFC 1951, section 3.2.3, printed p. 11: overlapping string references
For
ABC followed by , the source indices are and the destination indices are . Steps 0 through 2 copy the original ABC; steps 3 through 5 copy the ABC just appended; steps 6 through 8 copy the next newly appended ABC. Thus the final output is exactly ABCABCABCABC. Taking a snapshot of the original three-byte source slice would produce only three bytes; that operation does not implement the specified nine-byte copy.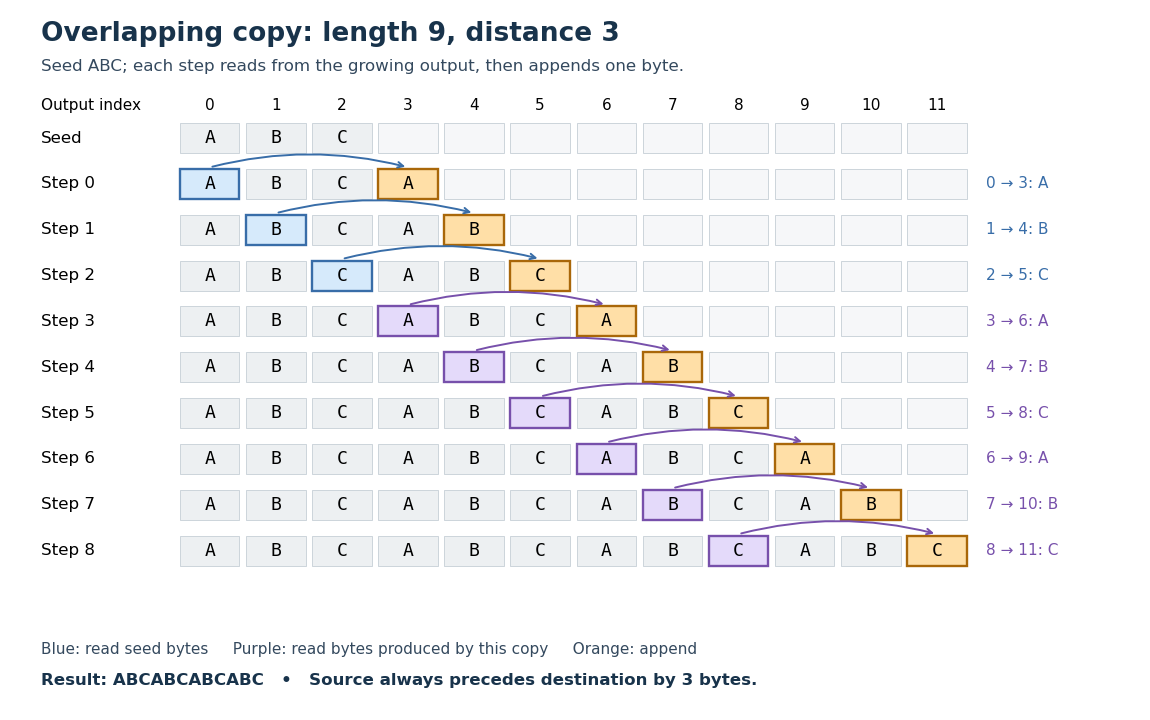
The reusable idea is a short description of periodic continuation: the decoder repeatedly looks a fixed distance behind its growing output. A Deflate backreference can also reach across a Deflate block framing boundary. Changing the block's Huffman codes does not by itself erase the decoded history.[ref]
DEFLATE Compressed Data Format Specification version 1.3 by L. Peter Deutsch. RFC 1951, sections 2 and 3.2.3: independent block codes, references across blocks
For a compressed block, Deflate Huffman coding uses one alphabet for Deflate literal bytes, length symbols and the end-of-block symbol, and another alphabet for distance symbols. Values 0 through 255 denote Deflate literal bytes, 256 ends the block, and 257 through 285 select lengths. A Deflate backreference is encoded as a length symbol, any length extra bits, a distance symbol, then any distance extra bits. Those extra bits select an offset within the symbol's prescribed range; they are not additional codewords.[ref]
In the illustrative Deflate backreference, length 9 uses symbol 263 and distance 3 uses symbol 2; neither needs extra bits. Under the fixed Huffman codes,
A, B and C each cost eight bits, symbol 263 costs seven, and distance symbol 2 costs five. Adding the seven-bit end-of-block symbol and three-bit block header gives bits, packed into six bytes for a single final block. This is a cost calculation for the explicitly chosen instructions, not a displayed compressed stream.[ref]Dynamic blocks transmit codeword lengths from which the decoder reconstructs the prescribed prefix codes. The code descriptions themselves use a smaller Huffman code and repeat instructions for successive codeword lengths, including runs of zero lengths. Here run-length encoding describes repeated code lengths, a separate role from copying repeated data bytes. Fixed blocks use predefined Huffman codes and avoid transmitting those descriptions.[ref]
Each block starts with a one-bit
BFINAL flag and a two-bit BTYPE field. The BTYPE values are 0 for stored data, 1 for fixed Huffman codes, 2 for dynamic Huffman codes, and 3 for an invalid reserved value. For compressed blocks, symbol 256 ends the current block; BFINAL = 1 says this is the last block. An end-of-block symbol does not mean a literal zero byte, and in a nonfinal block it does not end the whole stream.[ref]DEFLATE Compressed Data Format Specification version 1.3 by L. Peter Deutsch. RFC 1951, section 3.2.3: header, block types and decoding loop
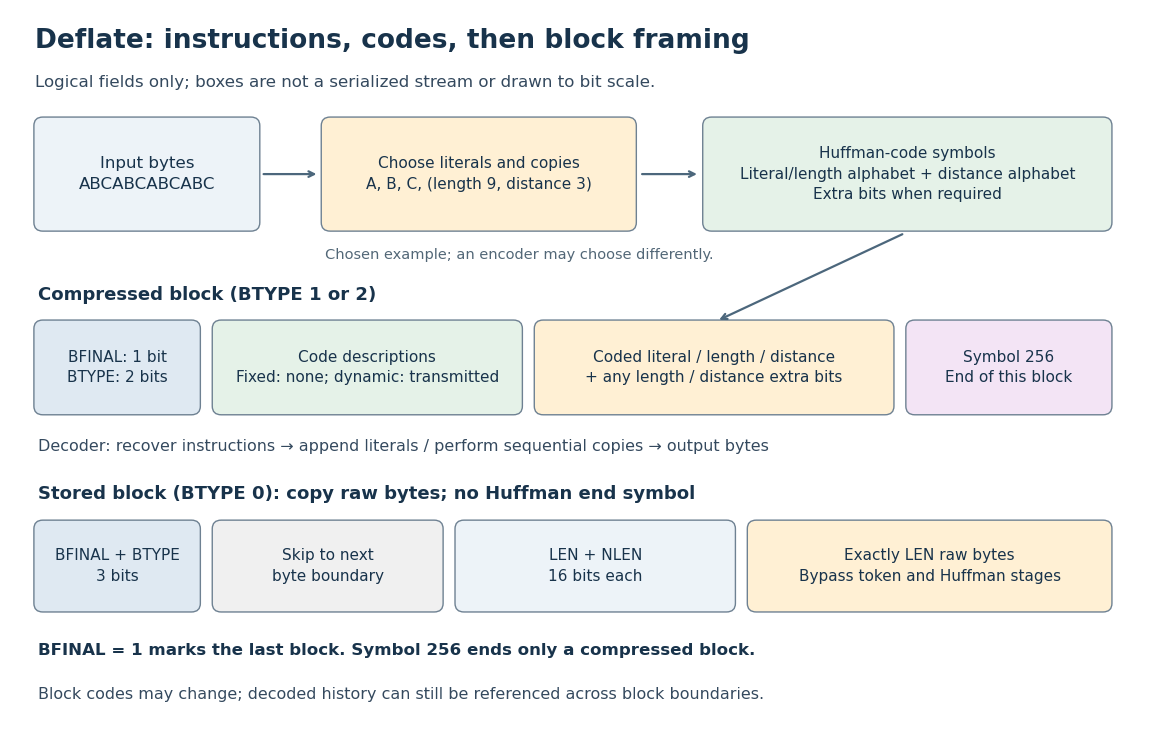
Deflate separates literal and copy instructions from Huffman coding and final-block framing; stored blocks bypass both stages
. Details. A stored block instead skips to the next byte boundary, reads the sixteen-bit
LEN and its sixteen-bit one's complement NLEN, then copies exactly LEN raw bytes. Its length field replaces the compressed block's end-of-block symbol. A compressed block need not end at a byte boundary, so the next block header can start inside the current byte.[ref]The diagram shows logical fields, not a serialization into bits. RFC 1951 specifies bit packing separately, including different conventions for codewords and other fields (section 3.1.1). For PNG, the filtered image data is compressed inside a zlib wrapper with its own header and checksum; raw Deflate and a complete PNG file therefore have different framing.[ref]
Short inputs can spend much of their size on Deflate block framing, the end-of-block symbol and, for dynamic blocks, Deflate Huffman coding descriptions. A repeated phrase is useful only if its Deflate backreference costs less than the Deflate literal bytes it replaces. Huffman coding adapts instruction costs; it does not make either references or code descriptions free.
For an exact expansion example, take the 256 bytes with values , each appearing once. A single fixed block containing only Deflate literal bytes costs bits, or 272 bytes after final packing. One stored block starting at a byte boundary instead costs five overhead bytes plus the 256 data bytes, or 261 bytes. Both exceed the 256-byte input; these counts follow the specified layouts and are not measurements of an encoder's automatic choice. The example illustrates universal lossless shortening is impossible.[ref]
The following independent experiment obtains an actual raw Deflate stream using the standard library's The printed bytes describe this library run. Exact roundtrip recovery is the check; a particular compressed length or instruction choice is not a guarantee for other inputs or library versions.
zlib module, then checks exact recovery. Negative wbits selects raw framing; the three lines of compressed-data handling make no assumptions about which Deflate backreferences the library selects.[ref]zlib — Compression compatible with gzip (Python 3.14 documentation). Python 3.14 zlib documentation, compressobj, decompress and negative wbits
import zlib
data = b"ABCABCABCABC"
encoder = zlib.compressobj(level=6, wbits=-15)
packed = encoder.compress(data) + encoder.flush()
assert zlib.decompress(packed, wbits=-15) == data
print(len(data), len(packed), packed.hex())Image compression applies data compression to pictures, usually represented by raster images. Nearby pixels often have related shades; an encoder can exploit that structure. A flat region invites run-length encoding, while lossy block averaging trades fine detail for fewer stored samples. The choice depends on whether exact pixel values matter and on the patterns in the image.
Lossless source coding recovers the encoded pixel values exactly, including sharp text or numerical image data. Lossy compression preserves an approximation and can remove features that later image processing might need. A visually smooth result is therefore a different promise from exact recovery. Neither method has a universal compression ratio: the chosen file format, its file header and the particular image all matter.
PNG is a real format with lossless source coding of its encoded image data. Its specified compression uses Deflate on reversibly filtered rows, rather than our toy RLE format. The lossy block averaging example is also a teaching format, not a description of PNG. A lossy preprocessing step followed by saving as PNG preserves the already changed pixels, not the earlier original.[ref]
Portable Network Graphics (PNG) Specification (Third Edition) by Mark Adler and others. W3C, PNG Specification, Third Edition (2025), section 10, Compression
PNG is a file format for raster images with lossless source coding of the encoded image data. Its first W3C Recommendation, dated 1 October 1996, described a portable replacement for earlier image formats; this situates the design in exchanging images reliably between systems.[ref]
https://www.w3.org/TR/REC-png-961001. W3C, PNG (Portable Network Graphics) Specification, 1 October 1996, status and abstract
Articles by others on the same topic

Data compression is the process of reducing the size of a data file or dataset by encoding information more efficiently. This can involve various techniques that eliminate redundancy or use specific algorithms to represent the data in a more compact form. The primary goals of data compression are to save storage space, reduce transmission times, and optimize the use of resources when handling large amounts of data.



