Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
For , and , put while . Then . If , decreases to zero at the displayed finite time. The positive branch joins the zero solution with zero first derivative, giving a nonnegative forward solution. The equilibrium at zero is one-sided stable even though the vector field is not locally Lipschitz continuous there; the positive equilibrium is unstable.
Consider the original analytic initial value problemHere and are dimensionless variables in a stipulated mathematical model. The trajectories below are exact solutions of a differential equation, with no measured data or empirical parameter fit. For , the Bernoulli power substitution givesThe integrating factor is . Direct differentiation gives , independently checking the transformation. The linear exists for every real , while the nonlinear solution of a differential equation uses only the interval containing where :For , , so its absolute value decreases toward zero. The lost zero solution of a differential equation is recovered by substitution into the original equation. Since is locally Lipschitz in everywhere, the Picard-Lindelöf theorem ensures uniqueness through every finite point, including . Thus a nonzero trajectory never meets or crosses zero at a finite .
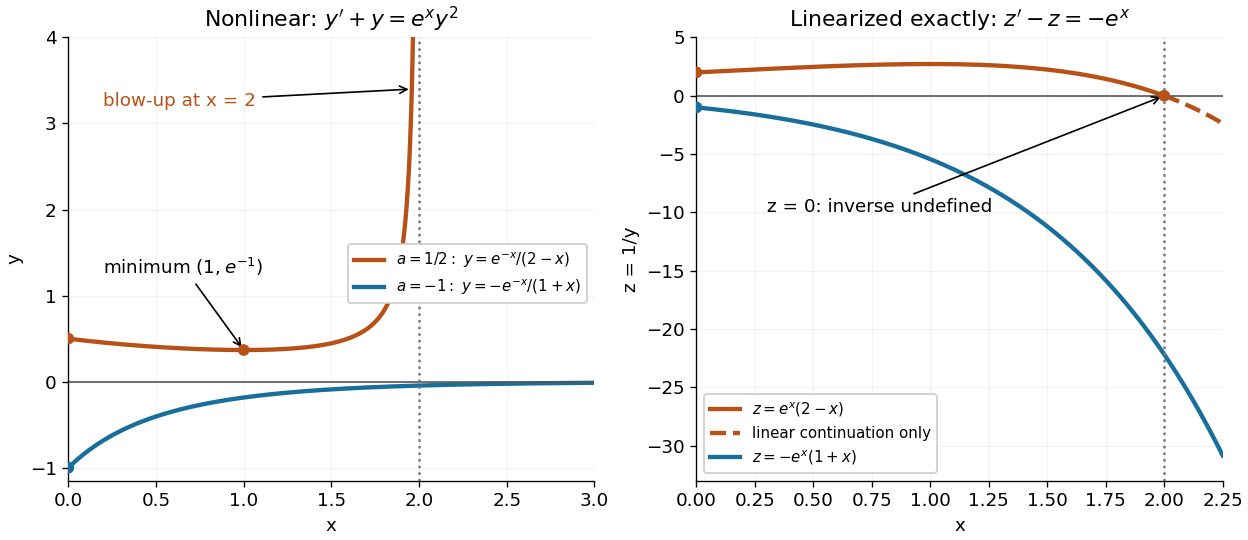
Two Bernoulli trajectories and their exact linearized coordinates
. The initial conditions are in orange and in blue. Left: the positive trajectory reaches finite-time blowup at , while the negative trajectory approaches zero. The vertical axis clips the positive curve at ; this is a display limit. Right: the corresponding trajectories satisfy . The dashed orange continuation past solves the first-order linear differential equation but cannot extend the original positive initial value problem across blowup. Details.For , the exact solution of a differential equation is on . It first decreases, reaches a local minimum , then increases without bound. At the endpoint,The finite-time blowup comes from a simple zero of at , where , rather than from a singular coefficient in the first-order linear differential equation. The same algebraic expression for is negative on , but that is a separate solution of a differential equation on a disjoint interval; infinity supplies no finite joining value. For , on , giving a distinct decaying branch whose finite blowup is instead in the past.
The direction field also explains the positive turning point. Its nullclines are and , becauseAbove the positive nullcline, ; between it and zero, ; below zero, . The moving nullcline is not a solution of a differential equation: its derivative is , whereas the prescribed slope there is zero. The trajectory crosses it at , exactly its local minimum.
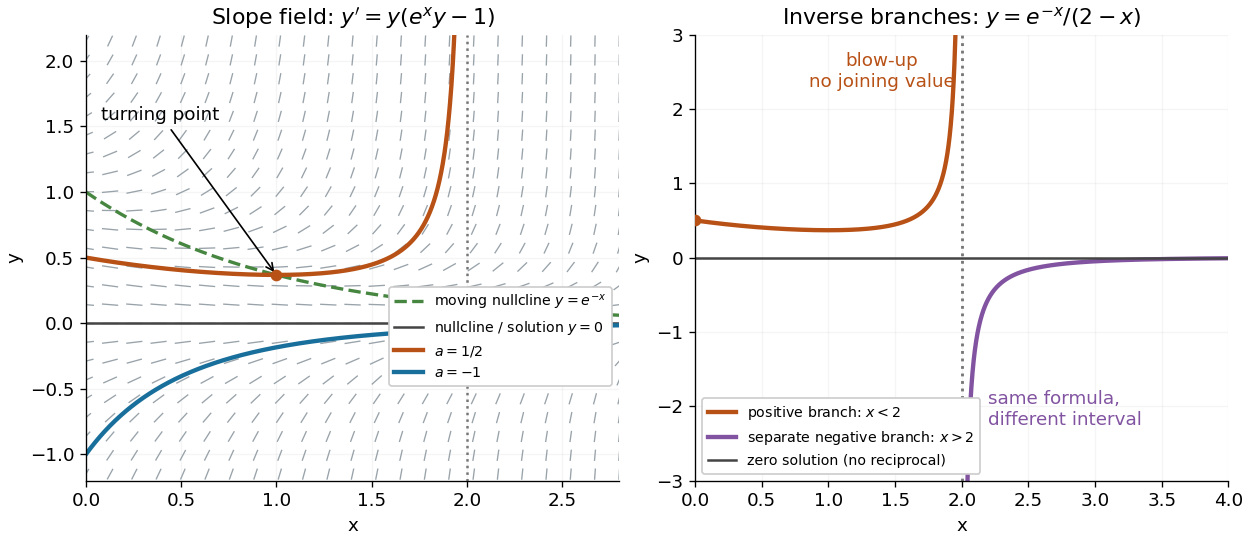
The Bernoulli direction field and the disconnected inverse branches at blowup
. Left: the direction field, its two nullclines, and the exact and trajectories. Right: has a positive branch on and a negative branch on ; the excluded point separates them. The zero solution of a differential equation belongs to the original equation but has no finite reciprocal coordinate. The branches continue beyond the plotted vertical limits. Details.For arbitrary real , work first on an interval where . Define exponentiation by , using the real logarithm. The change of variable is differentiable and invertible there, and the chain rule givesMultiplying the Bernoulli differential equation by yields the first-order linear differential equationThis is an exact transformation of nonzero solutions of a differential equation on the chosen branch; it is valid far from any reference state and does not discard higher powers as a local linearization would.
Given the initial condition , the integrating factor and transformed solution of a differential equation areThe product rule verifies . Recover only on the connected component of containing , inside the original coefficient interval. The first-order linear differential equation can have a longer existence interval than this inverse transformation allows.[ref]
1.4 Linear equations and the integrating factor. Notes on Diffy Qs, §1.4 Linear equations and the integrating factor: product derivative, formula (1.4), and Remark 1.4.1 on existence throughout a coefficient-continuity interval
Negative values need a separately justified real branch. For integer , the required powers are real and differentiable for too, but the inverse must retain the sign selected by the initial condition. For , represents either or ; both square roots are taken of positive . For , retains the sign directly. For a general noninteger exponent, use the positive branch unless a specific differentiable real negative branch has been established. Never evaluate a real fractional power of a negative value merely because the linear formula has become negative.
Division by excludes . When and the original real power is defined at zero, is an additional solution of a differential equation and must be checked in the original equation. When , the equation as written is undefined at zero. On a positive branch the right-hand side is locally Lipschitz in , so the Picard-Lindelöf theorem gives local uniqueness. At zero, the same hypothesis needs a fresh check: it holds for the polynomial example, whereas for a nonzero power coefficient prevents local Lipschitz continuity there. If , the inverse sends for , but sends for . The latter endpoint can lead to finite-time extinction in a sublinear Bernoulli equation, where the original equation determines how to join to zero.
Suppose a connection polynomial of degree at most , with recurrence span gives zero recurrence discrepancies through index but a nonzero discrepancy at . If a polynomial of span successfully explains the prefix through and , evaluate the coefficient at in the convolution . Applying first makes it zero. Applying first leaves its nonzero discrepancy at , because the earlier discrepancies vanish and has constant coefficient one. This contradiction gives the displayed lower bound. It is the minimality step used by the Berlekamp-Massey algorithm; the algorithm cancels the new discrepancy with a shifted earlier failed polynomial.
In the dilute-vortex description of the two-dimensional XY model, is dimensionless stiffness and is phase vortex fugacity. A phase vortex has logarithmic energy , while its placement entropy is . Small phase vortex pairs screen the logarithmic interaction, lowering the stiffness. Near , the rescaled variables , obey , to leading order. The invariant leads to an essential correlation-length singularity , not a finite power-law exponent.
Here increases toward larger observation distances, and the vortex fugacity is a dimensionless weight per unit core, conventionally initialized as with the microscopic measure fixed. Numerical coefficients depend on this normalization. In the displayed convention, differentiating using the original flow givesOnly replacing the prefactor by one near gives the scaled leading model. Its first integral follows directly:Thus this first integral belongs to the stated scaled model, not exactly to the original equations. For , the critical separatrix is . The bound side has and flows to , ; the unbinding side ultimately runs to large vortex fugacity, where the dilute approximation ceases to be quantitative.
To derive the unusual correlation length scaling without fitting an exponent, write the invariant on a nearby unbinding trajectory as . Then and the time to cross fixed small limits to is . If a physical one-parameter path crosses the separatrix transversely, its is proportional to the positive reduced temperature. Since distance grows as , this gives , with a nonuniversal . This is the dimensionless-temperature form of the singularity above.
For odd , multiplication by two permutes the residues modulo . Its orbit through is the binary cyclotomic coset modulo an odd integer. If has order in a finite field whose field characteristic is two, the Frobenius automorphism sends to . Hence the minimal polynomial of an algebraic element over is . Its coefficients are fixed by Frobenius and lie in , and its degree is the orbit size. Thus a binary cyclic code containing one defining zero of a cyclic code must contain the full orbit as zeros.
The designed distance of a BCH code is the value specified by requiring consecutive defining zeros of a cyclic code. The BCH bound guarantees minimum Hamming distance at least , but the actual minimum Hamming distance can be larger. To prove equality, one can exhibit a nonzero codeword of Hamming weight exactly .
For a proper prior distribution independent of coalescent times , let with and . Observing under an infinite sites mutation model gives posterior density , where is the prior predictive probability of . Multiplication by the conditional Poisson mass and normalization is an application of Bayes' theorem.
// Target: statistical-inference.bigb
For continuously distributed uncertain quantities, define rank one to be the largest. A joint posterior distribution induces a discrete distribution on each quantity's rank. Estimate it by ranking the whole vector in each joint draw and averaging rank indicators; the probability of rank one is the probability of being largest. Ranking posterior means does not recover this uncertainty. The joint draws must preserve any posterior dependence, and tie conventions must be specified for models with atoms.
For one uniformly sampled integer , the likelihood function for the unknown endpoint is . A flat improper prior on positive integers gives an improper posterior distribution, since the harmonic series diverges. A reciprocal prior instead gives a proper posterior proportional to for , with approximate survival probability and finite quantiles, but infinite posterior mean. A uniform prior cut off at gives posterior mean , demonstrating sensitivity to that arbitrary cutoff.
For independent observations uniform on and a uniform prior on , the likelihood is constant wherever all data-compatible intervals overlap. The posterior is therefore uniform on the displayed intersection, provided it has positive length. Both squared-error and absolute-error Bayes estimates are its midpoint. An empty or zero-length interval has zero marginal likelihood and cannot be normalized into this ordinary posterior density.
For one observation from a continuous uniform distribution on and prior density , the likelihood cancels the factor and leaves . Normalization gives posterior density , for . Its mean is and variance one. The Bayes estimator under squared error loss is therefore , unchanged by multiplying the loss by a positive constant.
A prior predictive check simulates parameters from the prior distribution and observations from their sampling model, then examines whether those observations are plausible before conditioning on data. This reveals unintended information from apparently broad priors, especially after nonlinear transformations or when scales and correlations are coupled. It differs from a posterior predictive check, which uses the posterior distribution.
Exact beta-binomial credibility with unequal exposures by  Codex 0 Created 2026-10-14 Updated 2026-11-05
For a common success chance with beta prior and conditionally independent binomial observations of sizes , put and . Beta-binomial conjugacy gives posterior mean , equal to . Multiplying by the next exposure predicts its expected count. The factor tends to one as exposure increases and to zero as prior concentration increases at fixed prior mean.
For a common gamma distribution (shape , rate ) frequency prior distribution and conditionally independent Poisson distribution yearly counts of means , observed average amounts determine counts . The posterior distribution shape is and rate is . The future per-policy mean is the display, equal to credibility factor times plus the complementary weight times . The data must lie on their count lattice; impossible noninteger recovered counts have zero likelihood.
// Destination: probability-theory.bigb
conditionally independent normal distribution observations of mean and known variance , with normal prior mean and variance , give normal-normal conjugacy with known observation variance. Their posterior mean has the displayed exact credibility estimate form. It minimizes posterior squared-error loss and predicts the conditional expectation of the next observation.
A Bayes act minimizes for a specified parameter distribution . Applying the same minimization to the posterior after observing data gives a Bayes decision rule. The optimal data-based Bayes risk is the expectation of the optimal posterior no-data loss.
For loss , assume , and . The posterior expected loss is a positive constant times absolute-error loss under the posterior distribution reweighted by . Thus its minimizers are the medians of that weighted posterior distribution. More precisely, the weighted cumulative distribution function satisfies ; the one-sided slopes of the convex loss give this condition.
For relative absolute loss on positive parameters, . With a gamma distribution posterior of shape two and rate , reweighting produces an exponential distribution of rate , so the estimate is . The weighted first-moment condition ensures finite loss; without it every finite action can have infinite loss, making a median characterization uninformative.
For integrable real , including points where decreases the integral and including points where increases it. Thus the negative set minimizes the integral, up to null sets and arbitrary choices where . This elementary signed-integral fact derives the Bayes classifier and cost-sensitive Bayes classifier.
With zero cost for correct classifications, assign class one when the displayed inequality holds and class two otherwise. It compares conditional expected losses; ties may be resolved arbitrarily. For positive costs and densities, the log likelihood ratio threshold is .
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact