Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

For and vanishing solid-to-liquid diffusivity ratio, gives the interfacial liquid concentration. It increases from zero to as increases. Its derivative is , which decreases from to zero. For a direct proof, write . Then , so . Differentiation gives : the bracket increases with , and substitution of its lower bound gives only positive polynomial coefficients, including constant . Thus the concentration is strictly concave as a function of melting speed parameter . Combining this with a linearized thermal balance produces one fold on the melting branch and, with the freezing branch, an interval of three possible interface speeds.
For incident and reflected harmonic arterial pressure waves with real , the local pressure and flow phasors are proportional to and . Their maximum-time difference is the displayed phase lag, on the branch . Here is the round-trip phase to the reflector. Its derivative has the sign of . Raising the wave speed reduces the lag when , but increases it when . This conditional harmonic model does not establish an age trend for arbitrary vascular geometry or measurement stations beyond the sole reflector.
The graph kernel of a bicyclic graph satisfies , with all degrees at least three. It therefore has either one degree-four vertex carrying two loops, a bouquet graph, or two degree-three vertices. In the latter case connectivity and degree counting give either three parallel edges, the three-edge Theta graph, or one edge between the vertices and one loop at each, a dumbbell graph. All bicyclic cores are subdivisions of these three kernels, subject to simplicity restrictions on loop lengths and parallel paths.
If counts labelled bicyclic cores on vertices, the bicyclic kernel classification gives . Three internally nonempty paths between two branching vertices give for . Attach a forest with those core vertices as roots to obtain . After division by the relevant sum is . Its upper bound follows from ; its lower bound uses , where this product stays bounded below. The sum is bounded above and below by positive constants. The restriction is necessary: .
Put . In the bialternant formula, substitute with distinct and compare the first nonzero determinant coefficients as . They arise from the distinct degrees in the exponential expansions. The common factor in the and the factorials cancel, leaving the product of differences of the divided by the differences of . This proves the displayed integral specialization without dividing by a vanishing Vandermonde value.
A bialgebra equipped with a coquasitriangular structure, namely a convolution-invertible scalar form satisfying , and , with unit normalization. The induced right-comodule braiding is .
For an injective function that does not increase distances, one stretch-factor convention measures the largest compression that must be undone:If the sharp Lipschitz constant of is one, this equals bi-Lipschitz distortion. Fixing the scale matters: uniform compression has stretch factor two in this convention, but bi-Lipschitz distortion one. In a geometric spanner, the corresponding stretch factor is the largest graph-route distance divided by direct Euclidean distance; the graph-to-Euclidean identification does not increase distances. [ref]
https://people.scs.carleton.ca/~michiel/encyc_geometric_spanners.pdf. Gudmundsson, Narasimhan and Smid, Geometric Spanners, §1: the stretch-factor convention
.De Casteljau's algorithm evaluates a Bézier curve by repeated linear interpolation between neighboring control points. Fix , start with , and computeEach new row has one fewer point. The final point is . Use the same at every stage: it describes the fraction of each line segment traversed from its first endpoint toward its second. A cubic Bézier curve needs three levels containing , , and linear interpolations, respectively.[ref]
https://graphics.stanford.edu/courses/cs164-10-spring/Handouts/handout19.pdf. Stanford CS348a, Handout 19, §2.3, pp. 10–11
For the Bézier curve with control points , , , , evaluation at takes the midpoint of every neighboring pair. The first level givesThe second level givesand the third level givesThe intermediate control polygons shrink toward the evaluated point. Each step is a convex combination, giving a geometric explanation of the convex hull property; every step also commutes with an affine map.
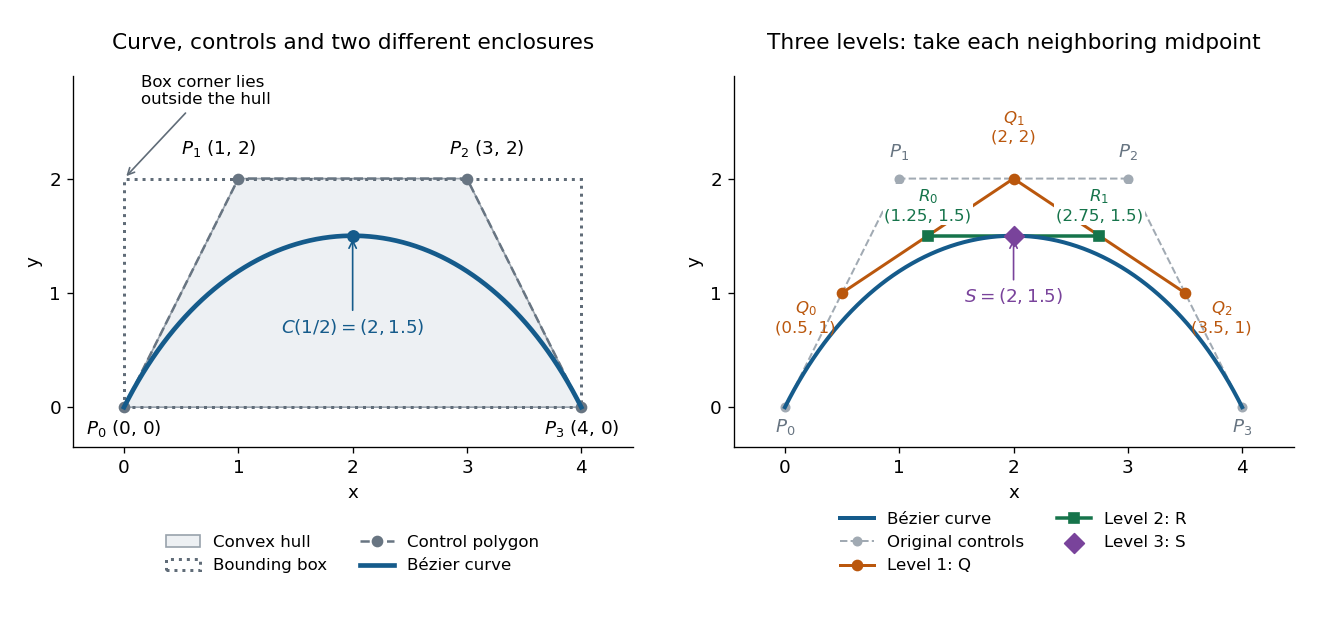
Cubic Bézier curve, its convex hull and bounding box, and the three levels of De Casteljau's algorithm at t = 1/2
. Details. The same construction splits the Bézier curve exactly, with no approximation. The outer edges of the triangular array give the new control points: for a cubic, specify the left piece and specify the right piece.[ref]
https://graphics.stanford.edu/courses/cs164-10-spring/Handouts/handout19.pdf. Stanford CS348a, Handout 19, §2.3, p. 11, subsegment control points
At these two lists areWrite and for the Bézier curves defined by these lists, each with its own parameter . ThenTheir images reproduce the original curve, while their derivatives account for the shorter parameter intervals. At the join,The chain rule gives ; in the original parameter, both pieces have derivative . This is the interval scaling in the parametric first-derivative join of Bézier curves.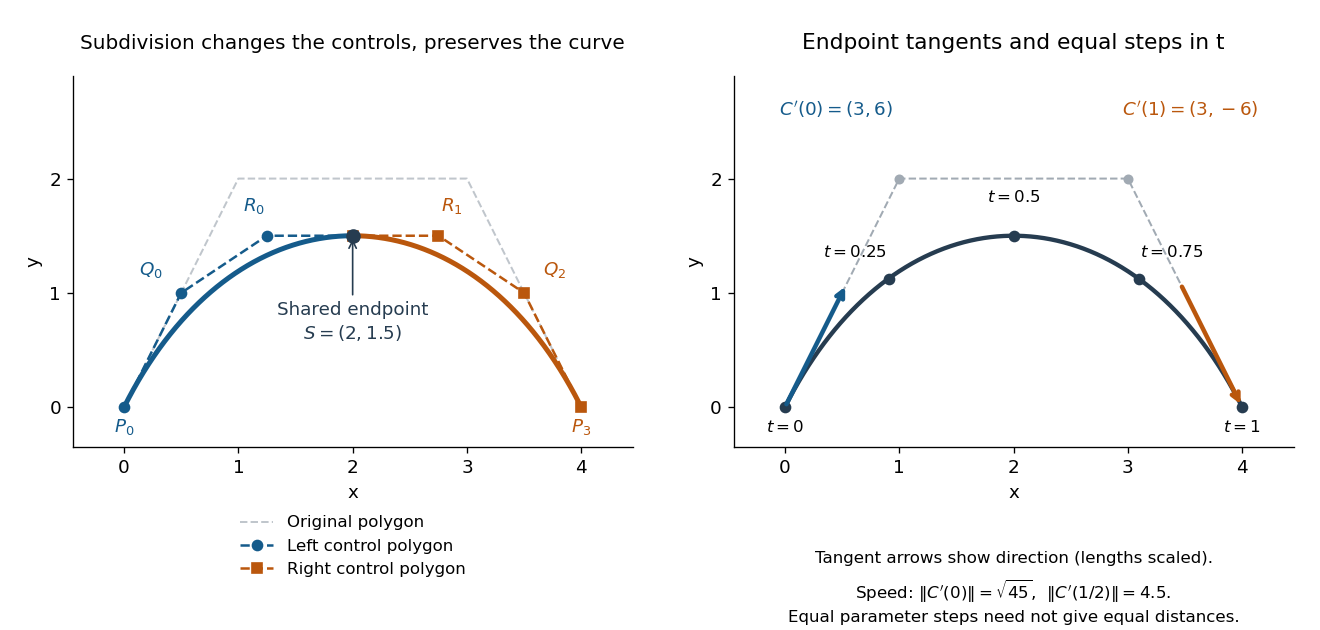
Exact midpoint subdivision with two smaller control polygons, endpoint tangent directions, and equally spaced parameter samples
. Details. Repeated midpoint splitting is useful for drawing vector graphics paths: each piece has a smaller control polygon and its own convex hull enclosure. A renderer can refine pieces until they are sufficiently close to line segments at the chosen display scale. Evaluating and splitting it are thus two results of the same short algorithm.
For a proof outline, expanding the recursion givesPascal's identity proves this by induction; at , it is precisely the Bernstein basis formula for the Bézier curve. The geometric construction remains useful even when expanding the polynomial by hand would be cumbersome.
// Target: analysis.bigb
For a degree- Bézier curve, the th derivative has degree at most and control points . The first derivative follows by differentiating the Bernstein basis and shifting one summation index; iteration proves the general formula. A parameter interval of length multiplies these derivative controls by .
For real and , the displayed integral is the incomplete beta function. The regularized version is , the cumulative distribution function of the beta distribution. It has endpoint values zero and one and derivative . This is a useful explicit scale function of a one-dimensional diffusion when the scale density has two power-law endpoint singularities.
independent gamma distributions and with a common rate yield a Beta distribution . The change of variables , has Jacobian determinant , and factors the joint probability density function into a Beta distribution density in and a gamma distribution density in . In particular, independent chi-squared distributions with and degrees of freedom give the required ratio.
For positive integers , the th order statistic from independent uniform distributions on has Beta distribution . Selecting the observations below and above a value gives its probability density function proportional to , with normalizing factor .
Moment matching for a beta prior turns a desired mean and variance for an unknown probability into the parameters of a beta distribution prior. Choose andSolving the beta distribution mean and variance identities givesThe strict upper bound on the variance makes , so both parameters are positive. Substitution gives mean and variance exactly. A smaller specified variance at fixed mean produces a more concentrated prior distribution.
For example, a desired prior mean and variance give , hence the beta distribution prior . With the same mean and variance , the calculation instead gives and the broader beta distribution prior . Both appear in the concentration diagram above.
The excluded boundary cases have clear meanings. Zero variance would require with certainty, not a beta distribution with finite positive parameters. At the other boundary, any random variable satisfies , hence variance at most ; equality requires to take only the endpoint values zero and one. This is a Bernoulli distribution, not a beta distribution. Thus cannot be matched by positive finite parameters, and or is also excluded.
After observing Bernoulli trials, the Beta-binomial conjugacy makes the posterior mean a weighted average of the prior mean and observed binomial proportion :This formula gives a precise interpretation as the prior's weight relative to the sample size in this posterior mean. It does not require fictitious observed counts: the beta distribution parameters can be any positive real numbers. For the eight-head, two-tail example above, and , so the posterior mean is .
// Target: statistical-inference.bigb
For real functions, let and put . If for every , then is a best approximation in a normed space using the norm. The proof is the pointwise inequality , followed by integration. This is a sufficient criterion even if the residual vanishes on a positive-measure set; a general necessary criterion may choose any subgradient in on that zero set.
For and , existence follows from finite-dimensional compactness and uniqueness from strictly convex normed space geometry. Translation by and negative translation by preserve the target and the error norm. Uniqueness forces the minimizing trigonometric polynomial to be invariant under the first operation and the negative of itself under the second. Invariance removes every nonzero frequency below ; negative invariance removes the remaining constant.
Put in the Bessel density modes of a polytropic expanding universe equation. It becomes . Substituting gives . Since , the fractional pressure correction is small when . For , this is the order-of-magnitude condition . It describes approach to the dust-like growing branch, not an exact universal time at which every initial perturbation starts increasing. The instantaneous Jeans instability balance instead compares with .
A Perron tree is a finite triangular splitting-and-sliding arrangement retaining a prescribed angular range while overlapping its pieces strongly. The compression parameter and the number of generations can make union area an arbitrarily small fraction of total piece area. Suitable longitudinal extensions separate the pieces into disjoint rectangles. This stronger finite geometry is used by the ball-multiplier counterexample; a compact measure-zero Besicovitch set alone does not assert that arbitrary segment translates are disjoint.
Choose a compact with full horizontal projection and zero-length projections for . Then the displayed set is compact, has zero area by the Fubini theorem, and contains a segment of every slope in . Such parameter sets exist by the Baire category theorem in the Hausdorff metric: fine parallel segments approximate any parameter set while making a fixed band of projections uniformly small. Finite grids and a countable intersection make every required projection null. Four rotated copies supply every planar direction.
The typical sequence theorem turns a probability concentration into a coding construction. Assign one binary number index to each weakly typical sequence, plus a reserved index for every word outside the set. The decoder recovers every typical word exactly; the reserved index has one predetermined output. The block code usesbits and has reconstruction-error probability at most .
For this example and , needs 34 bits but permits error up to about . At , 570 bits suffice and the error bound is about . These are existence calculations for an explicitly enumerated collection, rather than claims about an efficient practical encoder. The reduction comes from protecting the whole high-probability collection, rather than just its single most likely member.
The count has binomial distribution with mean and variance . The information content per symbol is an affine function of , so its variance isChebyshev's inequality therefore gives the finite-sample lower boundThe bound is often loose, but it proves that every fixed positive tolerance eventually captures nearly all the probability. Direct summation of the binomial distribution's probability masses gives . A finite sample does not need to have a nearly full typical set: the 40-symbol example above captures only about .
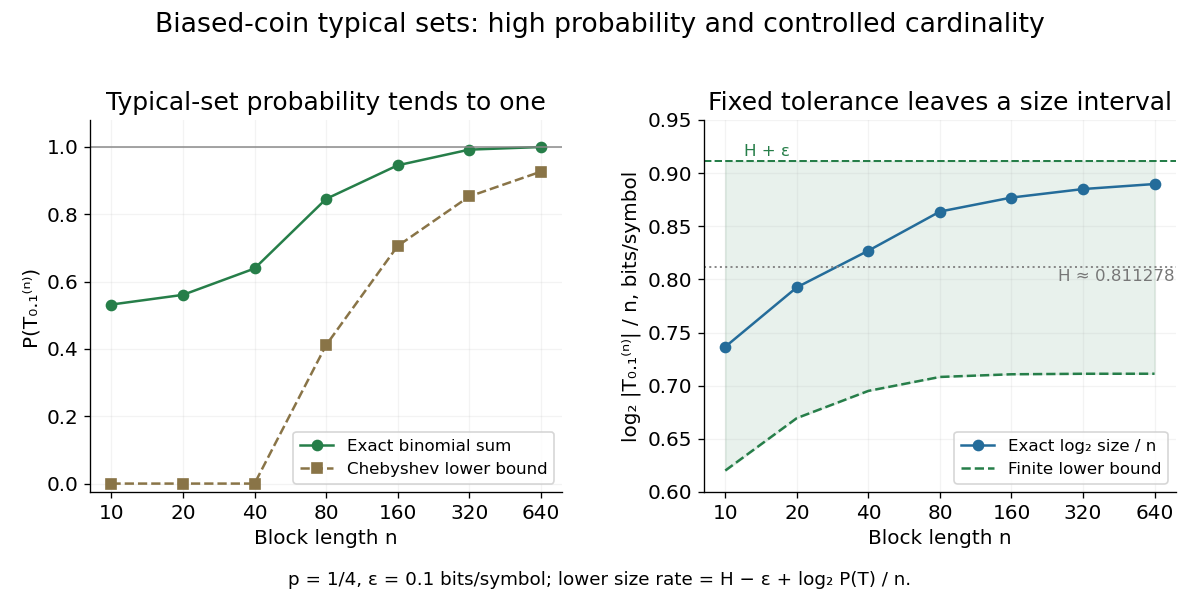
Longer biased-coin messages concentrate in typical sets with controlled size
. The left plot compares exact typical set probabilities with the lower bound from Chebyshev's inequality. The right shows and its finite-sample bounds. The tolerance stays fixed; the curve is not asserted to converge to exactly . All points are exact finite-model calculations. Details. Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact