Two-spin Boltzmann learning
ID: two-spin-boltzmann-learning

Take two visible bipolar units, no hidden units, zero thresholds, , and . As original training data, assign probabilities each to and and each to and . The data pair product averages to . Enumeration of all four states gives two weights and two , hence the partition function andStarting at , the positive-minus-negative difference is . A gradient ascent step of size gives . Each aligned state now has probability and each opposed state , bringing the model toward the data. The log-likelihood increases from to . Solving gives , which reproduces the data exactly. Since , this is the unique maximum. These are exact enumerations and their decimal evaluations, with no sampling or laboratory measurements.
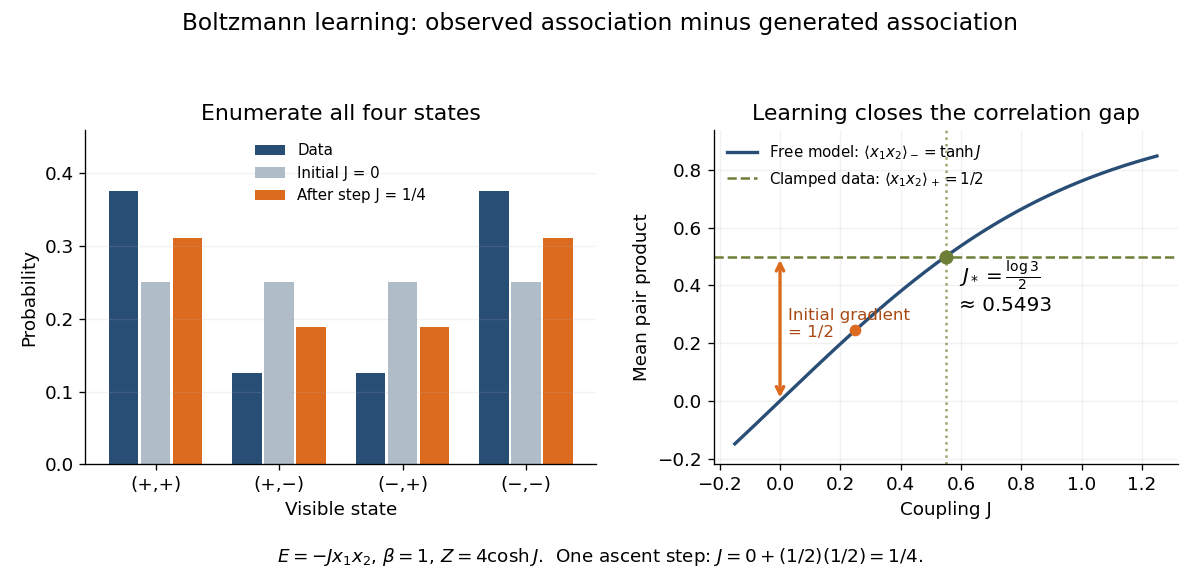
Exact probabilities and positive-minus-negative learning for two visible units
. Left: data and model probabilities before and after one gradient ascent step. Right: the data pair-product average and the model average determine the log-likelihood derivative; their intersection gives the optimal coupling. Details.
New to topics? Read the docs here!