Setting: you are sending bits through a communication channel, each bit has a random probability of getting flipped, and so you use some error correction code to achieve some minimal error, at the expense of longer messages.
This theorem sets an upper bound on how efficient you can be in your encoding, for any encoding.
The next big question, which the theorem does not cover is how to construct codes that reach or approach the limit. Important such codes include:
But besides this, there is also the practical consideration of if you can encode/decode fast enough to keep up with the coded bandwidth given your hardware capabilities.
news.mit.edu/2010/gallager-codes-0121 explains how turbo codes were first reached without a very good mathematical proof behind them, but were still revolutionary in experimental performance, e.g. turbo codes were used in 3G/4G.
But this motivated researchers to find other such algorithms that they would be able to prove things about, and so they rediscovered the much earlier low-density parity-check code, which had been published in the 60's but was forgotten, partially because it was computationally expensive.
Articles by others on the same topic

Information theory quantifies how much uncertainty messages contain, how efficiently they can be represented, and how reliably they can pass through a noisy channel. Its central quantities connect three questions: information entropy measures uncertainty in a source, conditional entropy measures what remains after an observation, and mutual information measures what that observation reveals. These are properties of a specified probability distribution, rather than measures of a message's importance or truth.
For a concrete source, suppose symbols have probabilities . A fixed-length binary representation needs two bits per symbol. Instead assign the prefix code , , , . Reading from left to right gives an unambiguous decoding because no codeword begins another. The expected value of the length isThis saves an average of of a bit per symbol, or of the fixed-length representation, with no loss of symbols. The lengths are exactly , so the average equals the source's Shannon entropy. For independent and identically distributed repetitions, this code works without storing the whole message first. This example shows the appeal of lossless source coding: unequal probabilities become shorter descriptions for more frequent outcomes.
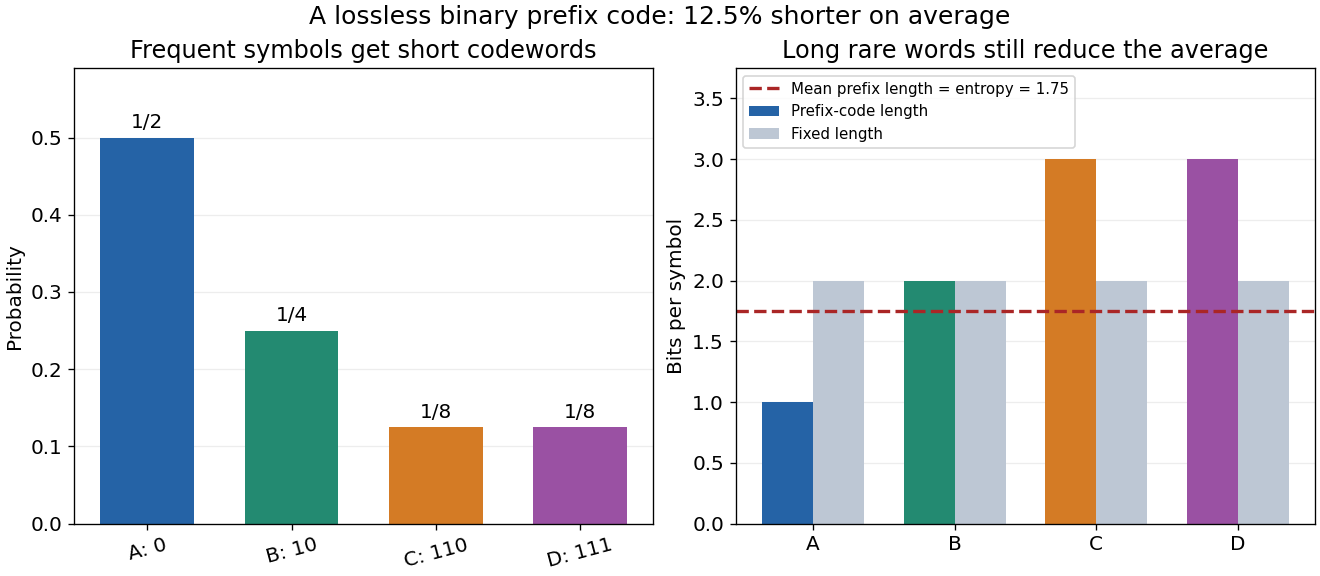
Channel coding addresses a different problem: errors during transmission. A shorter representation removes predictable structure; an error-correcting representation adds carefully chosen structure that helps recover corrupted symbols. Shannon's source coding theorem and the Shannon second coding theorem identify limits for these respective tasks under their hypotheses. The beauty is that source details and hardware details can meet through a small number of mathematical quantities, notably information entropy and channel capacity.
Claude E. Shannon's A Mathematical Theory of Communication appeared in the Bell System Technical Journal in July and October 1948. Its introduction separates the engineering problem of reproducing messages from their semantic meaning; subsequent sections develop probabilistic source models, noiseless coding, and transmission with noise. It also acknowledges earlier work by Harry Nyquist and Ralph Hartley.[ref]


Information theory is a branch of applied mathematics and electrical engineering that deals with the quantification, storage, and communication of information. It was founded by Claude Shannon in his groundbreaking 1948 paper, "A Mathematical Theory of Communication." The field has since grown to encompass various aspects of information processing and transmission. Key concepts in information theory include: 1. **Information**: This is often quantified in terms of entropy, which measures the uncertainty or unpredictability of information content. Higher entropy indicates more information.