
Hash table Created 2026-10-13 Updated 2026-10-18
A hash table stores records by key: for example, a product number can select its current stock count without scanning every product. A hash function selects a hash bucket in an array, and a collision-handling method such as separate chaining retains distinct keys assigned to the same hash bucket. The useful idea is to narrow the search to one small collection, while key equality decides which record actually matches.
Use a map interface with one value per key:
get(k) returns the associated value or an explicit absent result; put(k,v) replaces the value if an equal key is present, otherwise inserts a new record; delete(k) removes the matching record if present. The absent result must be distinguishable from every permitted stored value. Replacing a value does not increase the record count . A hash collision between unequal keys must never cause one record to replace the other.[ref]Lecture 8: Hashing I. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 1, dictionary operations and replacement of an existing key
Let denote the chosen key equality, an equivalence relation, and let be the bucket-index hash function for hash buckets. Correctness requiresThe converse is false: equal bucket indices merely identify candidates for a key equality comparison. If an implementation first computes a full hash value and then reduces it to a bucket index, equal keys must have equal values too. Keep both key equality and the hash function stable while a key is stored; changing the key so it selects another hash bucket can make its record unreachable. This distinction is explicit in the published
hashCode/equals contract.[ref]For a constructed integer example, use modular arithmetic to define and store keys with values . At , three records share hash bucket and one occupies hash bucket . The hash table load factor isIt is the mean number of records per hash bucket, including empty hash buckets, not a bound on the longest chain. With separate chaining, may exceed because records live in the chains rather than one record being confined to each array slot.
Growing this example to changes the bucket-index hash function: key now belongs to hash bucket , while keys still share hash bucket . Every record must be assigned using the new bucket-index hash function; copying the old array of chain heads unchanged is insufficient. The hash table load factor becomes .
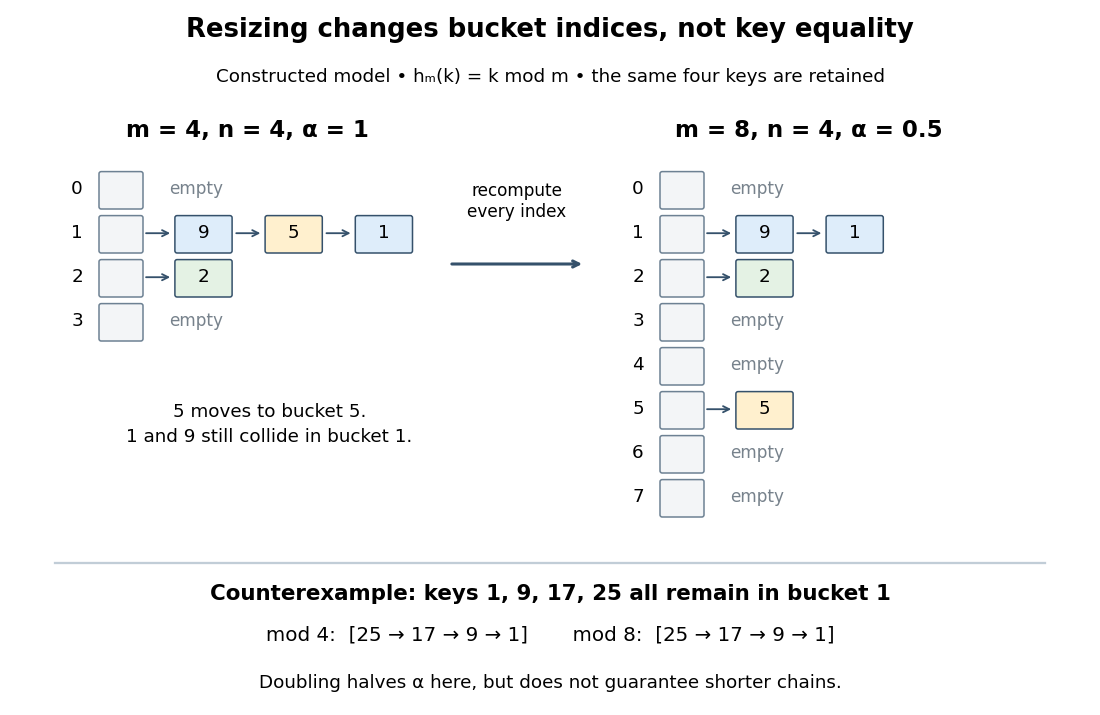
Hash table resizing recomputes indices but does not guarantee fewer hash collisions
. Original deterministic model using , not a measured implementation. The upper panels retain keys in four and eight hash buckets; chain order is illustrative. The lower counterexample retains all four keys in hash bucket even after doubling. Details.
For an insertion-only sequence starting empty with constant initial capacity, one policy doubles before inserting a new key that would make . A rebuild for separate chaining allocates the new array and transfers each existing record directly into its new chain. Since keys are already distinct, transfer needs no duplicate search. With constant-cost hashing and linking, this takes time complexity, hence at a growth threshold. Amortized analysis charges the occasional rebuild across many insertions: the old capacities form a geometric series with sum , so total rebuilding work over insertions is . This gives amortized resizing overhead; an insertion that triggers a rebuild can still take .[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 2, rebuilding cost and geometric table doubling
The search to check for an existing key is additional work. Bounded hash table load factor together with the probabilistic assumptions in separate chaining gives expected amortized insertion, not worst-case . Rehashing alone gives no distribution guarantee: the diagram's keys all collide modulo both and . Even a low hash table load factor permits a long chain. If supporting shrinkage too, leave a gap between growth and shrink thresholds to avoid repeated rebuilding when insertions and deletions alternate near one threshold.[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 3, expected bounds and shrinking at one-quarter occupancy
Hash table resizing Created 2026-10-13 Updated 2026-10-18
Changing the number of hash buckets and reassigning stored records using the new bucket-index hash function. Amortized analysis of rebuilding and expected value bounds for subsequent lookup address different costs.
Rebuild the balanced example from load factor of a hash table with while keeping exactly the same twelve records. Under , keys retain their indices, whereas keys move from hash buckets to hash buckets . The new chain lengths are twelve ones followed by four zeros; . Copying the old eight chain heads and adding eight empty heads would leave those four moved keys unreachable by the new lookup rule.
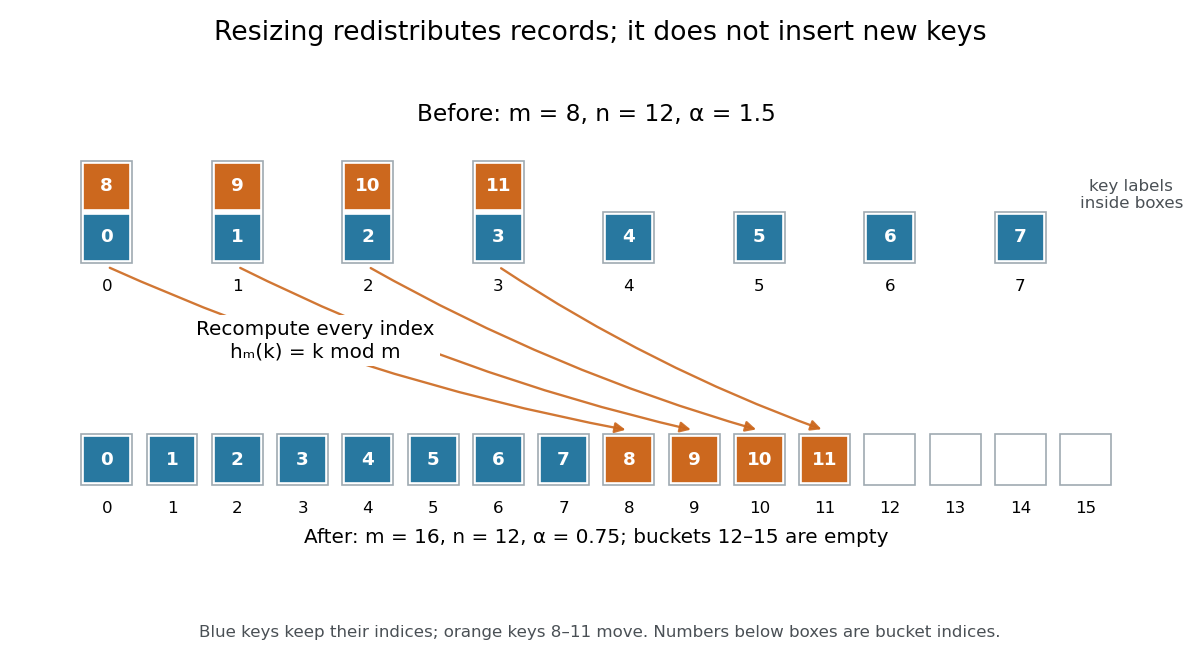
Hash table resizing from eight to sixteen hash buckets redistributes existing records
. Original modular arithmetic example for keys . Blue keys keep their indices; orange keys move because differs from . The record count stays twelve, and empty hash buckets still count towards capacity. Details.
For a short algorithm correctness outline, allocate the new array, visit every old record once, compute its new bucket index, and link it into that hash bucket. At every step, each transferred record is stored exactly once at the index prescribed by the new hash function. Finishing the visit therefore preserves every key-value association and makes the new lookup rule valid. Direct transfer can skip duplicate searches because the old one-value-per-key map already established distinct equivalence classes; rebuilding is not twelve new user insertions.
Under constant-cost hashing, linking and slot initialization, separate chaining rebuilding takes time complexity: initialize new heads, examine old heads, and transfer records. For doubling, , this is in Big O notation. It is when the resize policy makes proportional to , but an enormous mostly empty old array can make scanning its heads dominate. Growing capacity can lower without shortening a particular chain: the concentrated keys all remain in hash bucket after growth from eight to sixteen.
For an insertion-only sequence starting empty, choose initial capacity and double before a genuinely new key would make . The first three growths occur before inserting records and transfer existing records. If distinct records are inserted, the transfer count is . More generally, the transferred old capacities form a geometric series; if the last is , their sum is . Initializing and scanning these geometrically growing arrays also costs in total, giving amortized rebuilding overhead per insertion. A triggering insertion still pays for its whole rebuild.[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 2, Rehashing, How fast to grow?, and Amortized Analysis
The illustrative twelve-record resize above is an explicitly requested rebuild, not a growth triggered by this threshold policy. Checking for an equal key before growing also prevents a value replacement from triggering unnecessary growth. To combine resizing overhead with expected constant insertion time complexity, separately impose the collision and constant-cost assumptions in load factor of a hash table. Amortized analysis distributes rebuilding costs over operations; it does not randomize a poor hash function or bound a single operation's latency. With deletions, separate the grow and shrink thresholds; for example, growing when full and halving at one-quarter live occupancy leaves room for many operations between opposite rebuilds.[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 3, Back to Hashing and Delete: halving when n reaches m/4
// Target: computer-science.bigb