A hash table stores records by key: for example, a product number can select its current stock count without scanning every product. A hash function selects a hash bucket in an array, and a collision-handling method such as separate chaining retains distinct keys assigned to the same hash bucket. The useful idea is to narrow the search to one small collection, while key equality decides which record actually matches.
Use a map interface with one value per key:
get(k) returns the associated value or an explicit absent result; put(k,v) replaces the value if an equal key is present, otherwise inserts a new record; delete(k) removes the matching record if present. The absent result must be distinguishable from every permitted stored value. Replacing a value does not increase the record count . A hash collision between unequal keys must never cause one record to replace the other.[ref]Lecture 8: Hashing I. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 1, dictionary operations and replacement of an existing key
Let denote the chosen key equality, an equivalence relation, and let be the bucket-index hash function for hash buckets. Correctness requiresThe converse is false: equal bucket indices merely identify candidates for a key equality comparison. If an implementation first computes a full hash value and then reduces it to a bucket index, equal keys must have equal values too. Keep both key equality and the hash function stable while a key is stored; changing the key so it selects another hash bucket can make its record unreachable. This distinction is explicit in the published
hashCode/equals contract.[ref]For a constructed integer example, use modular arithmetic to define and store keys with values . At , three records share hash bucket and one occupies hash bucket . The hash table load factor isIt is the mean number of records per hash bucket, including empty hash buckets, not a bound on the longest chain. With separate chaining, may exceed because records live in the chains rather than one record being confined to each array slot.
Growing this example to changes the bucket-index hash function: key now belongs to hash bucket , while keys still share hash bucket . Every record must be assigned using the new bucket-index hash function; copying the old array of chain heads unchanged is insufficient. The hash table load factor becomes .
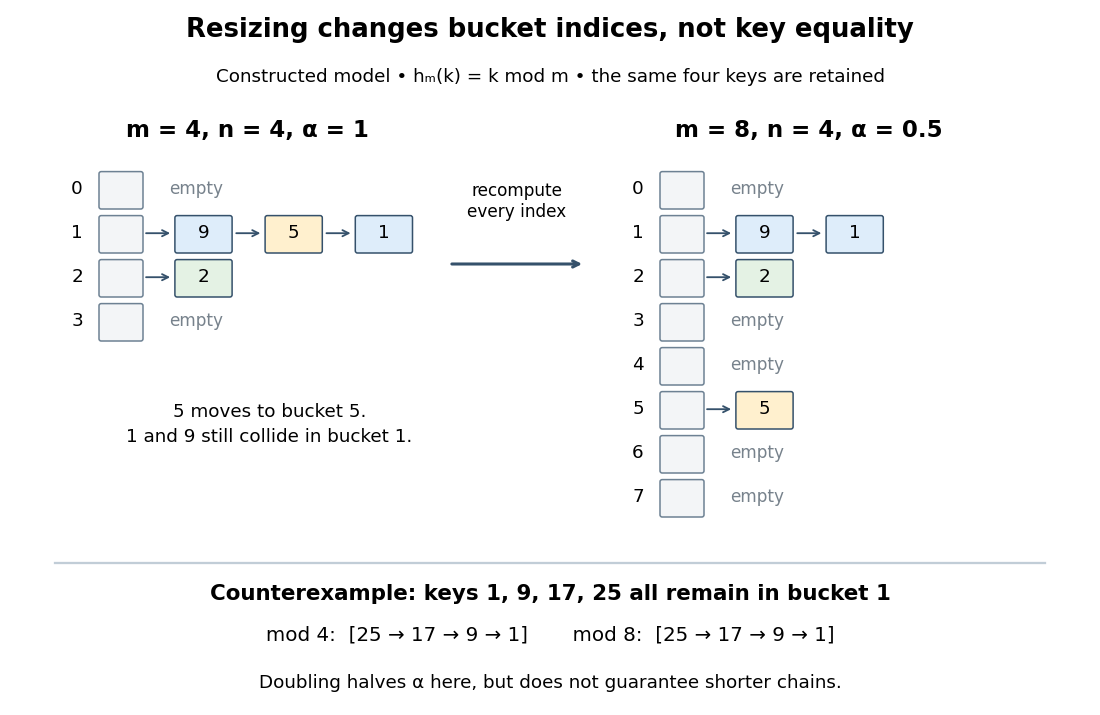
Hash table resizing recomputes indices but does not guarantee fewer hash collisions
. Original deterministic model using , not a measured implementation. The upper panels retain keys in four and eight hash buckets; chain order is illustrative. The lower counterexample retains all four keys in hash bucket even after doubling. Details.For an insertion-only sequence starting empty with constant initial capacity, one policy doubles before inserting a new key that would make . A rebuild for separate chaining allocates the new array and transfers each existing record directly into its new chain. Since keys are already distinct, transfer needs no duplicate search. With constant-cost hashing and linking, this takes time complexity, hence at a growth threshold. Amortized analysis charges the occasional rebuild across many insertions: the old capacities form a geometric series with sum , so total rebuilding work over insertions is . This gives amortized resizing overhead; an insertion that triggers a rebuild can still take .[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 2, rebuilding cost and geometric table doubling
The search to check for an existing key is additional work. Bounded hash table load factor together with the probabilistic assumptions in separate chaining gives expected amortized insertion, not worst-case . Rehashing alone gives no distribution guarantee: the diagram's keys all collide modulo both and . Even a low hash table load factor permits a long chain. If supporting shrinkage too, leave a gap between growth and shrink thresholds to avoid repeated rebuilding when insertions and deletions alternate near one threshold.[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 3, expected bounds and shrinking at one-quarter occupancy
A set data structure backed by a hash table. It stores each key at most once and supports membership tests, insertion, and removal with expected constant time under suitable hashing and load assumptions.
An associative array implemented with a hash table. It associates each stored key with a value and resolves collisions between keys with equal hash locations.
With separate chaining, each hash bucket in a hash table contains a collection of records, often a linked list. Lookup computes the bucket index, then follows that chain until a key equality comparison succeeds or the chain ends. A hash collision therefore affects the search work without merging unequal keys. Deletion searches the same chain and unlinks the matching record; in a singly linked list, remembering the preceding record during the search permits the unlink.[ref]
For the four-key integer example in hash table, insert a new record at the head of its chain after checking that its key is absent. Inserting in that order makes hash bucket hold , hash bucket hold , and the other two hash buckets empty. All five subsequent operations below select hash bucket because :
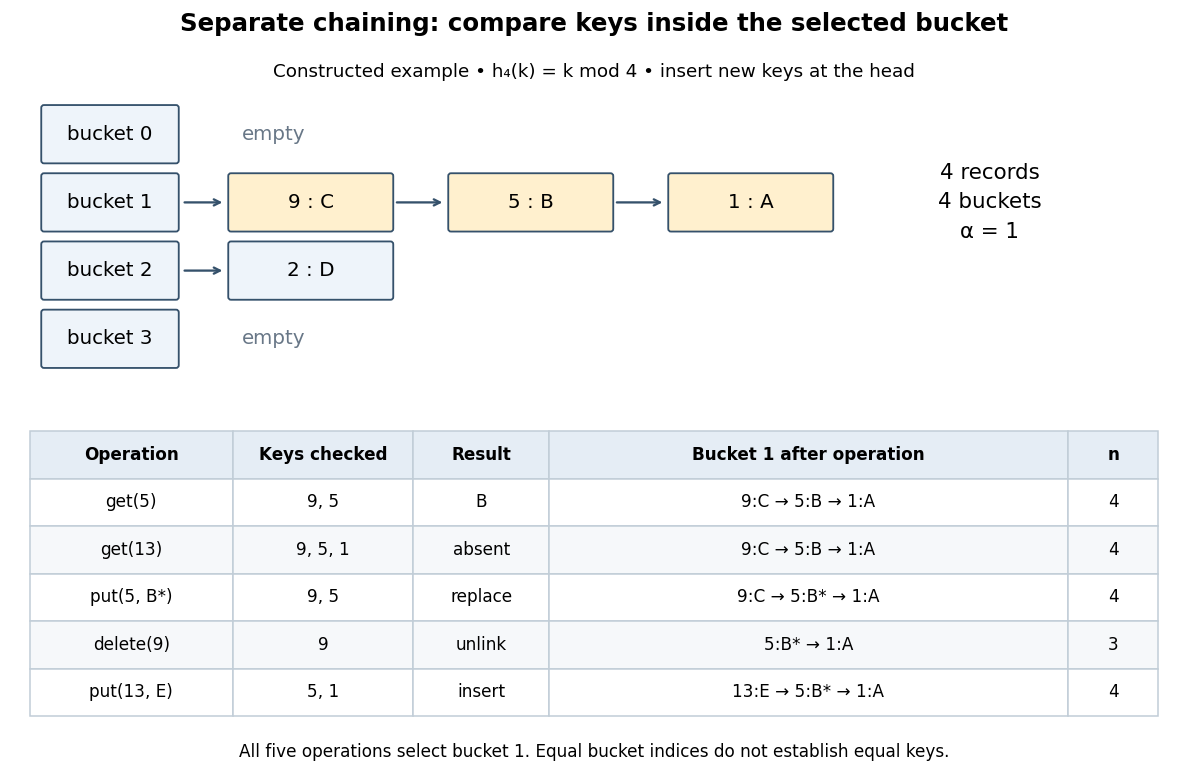
Separate chaining traces lookup, replacement, deletion and insertion through key equality
. Original deterministic model with . The table counts actual keys inspected, not elapsed machine time. Operations occur from top to bottom; only an absent key adds a new record, and the untouched record remains in hash bucket . Details.get(5) rejects key , accepts key , and returns after two key equality comparisons. get(13) rejects and reports absence after three comparisons. put(5,B*) examines and replaces the value without changing . delete(9) examines just the head record, removes it, and gives . Finally, put(13,E) rejects before inserting the new head record; returns to and the chain is . The successive hash table load factors are . These counts follow from the stipulated chain order; a different insertion policy changes the successful-search counts.For a chain of length , lookup and deletion by key take time complexity in Big O notation. The same applies to
put before any resizing, since replacement semantics require checking for an existing equal key. Head insertion alone is if absence is already known; that is a different precondition. These bounds assume bucket-index hashing, array access, key equality comparisons, allocation and link updates. A long string or large integer can make hashing or comparison depend on its encoded length, so counting record visits alone does not establish constant running time.Under simple uniform hashing, each distinct key's bucket index is an independent random variable with a uniform distribution on a finite set of indices. The keys and query are fixed independently of this random assignment. Then lookup has expected time complexity, where is the hash table load factor; it is expected when stays bounded. These are model assumptions, not an automatic consequence of using a deterministic hash function.[ref]
Lecture 8: Hashing I. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; pp. 4–5, chaining worst case and simple uniform hashing assumption
Here is the short calculation. For an absent query and stored keys , let be the indicator random variable of . The number of records inspected has expected valueby linearity of expectation. For a present fixed query, scanning its entire chain inspects at most itself plus all other colliding records, with expected value ; stopping at the match only decreases this upper bound. Adding constant hashing and bucket access yields expected for either query. The argument needs pairwise collision bounds; it does not require all the indicator random variables to be independent. A universal hash family can provide a related bound by random choice of a hash function for a fixed key set, as explained in that article.
The worst case remains , and an absent query takes comparisons if all records occupy its hash bucket. For instance, all collide under . Separate chaining remains correct, but a sequence of insertions that each checks the existing chain can take quadratic total work. Amortized analysis of resizing does not remove this search cost, and an adaptive choice of keys based on a known hash function is outside the stated simple uniform hashing model.
A probabilistic model assigning distinct keys independent bucket indices with a uniform distribution on a finite set. It supplies an expected value bound for separate chaining, not a guarantee for every deterministic hash function or workload.
A hash table collision-handling method storing at most one live record per array slot. A hash function chooses a starting slot, and a probe rule chooses further slots. Unlike separate chaining, records occupy the slots themselves.
An open addressing probe rule that visits modulo , using modular arithmetic, until a matching record or an appropriate stopping slot is found.[ref]
Lecture 10: Hashing III: Open Addressing. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; Lecture 10: Hashing III: Open Addressing, p. 3, Linear Probing formula
For capacity , the hash table probe numbered , starting at zero, inspects the array indexThe hash function gives the first array index. Each subsequent hash table probe moves one slot forward, wrapping from to by modular arithmetic. Keep the hash function and key equality fixed while hash table records are stored.
Use three distinguishable slot states: occupied by a live hash table record; never used since initialization or rebuilding, written
E; or deleted, written D, a tombstone in open addressing. Lookup compares occupied hash table keys using key equality, stops at E, and continues past D.[ref]5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; Section 5.2, three entry types and find: nil stops lookup, del does not
For an original example, take an eight-slot array, integer hash table keys, and the hash function . Start with all slots
E and insert the hash table records in that order. The insertion hash table probe traces, expressed as array indices, areThe resulting array holds hash table keys at array indices , with E in the other four slots. The first three hash table keys have the same initial array index, a hash collision; the fourth begins at but joins the same linear probing cluster. Lookup of examines array indices , rejecting before returning . Lookup of absent examines , including the stopping E: five hash table probes for a hash table load factor .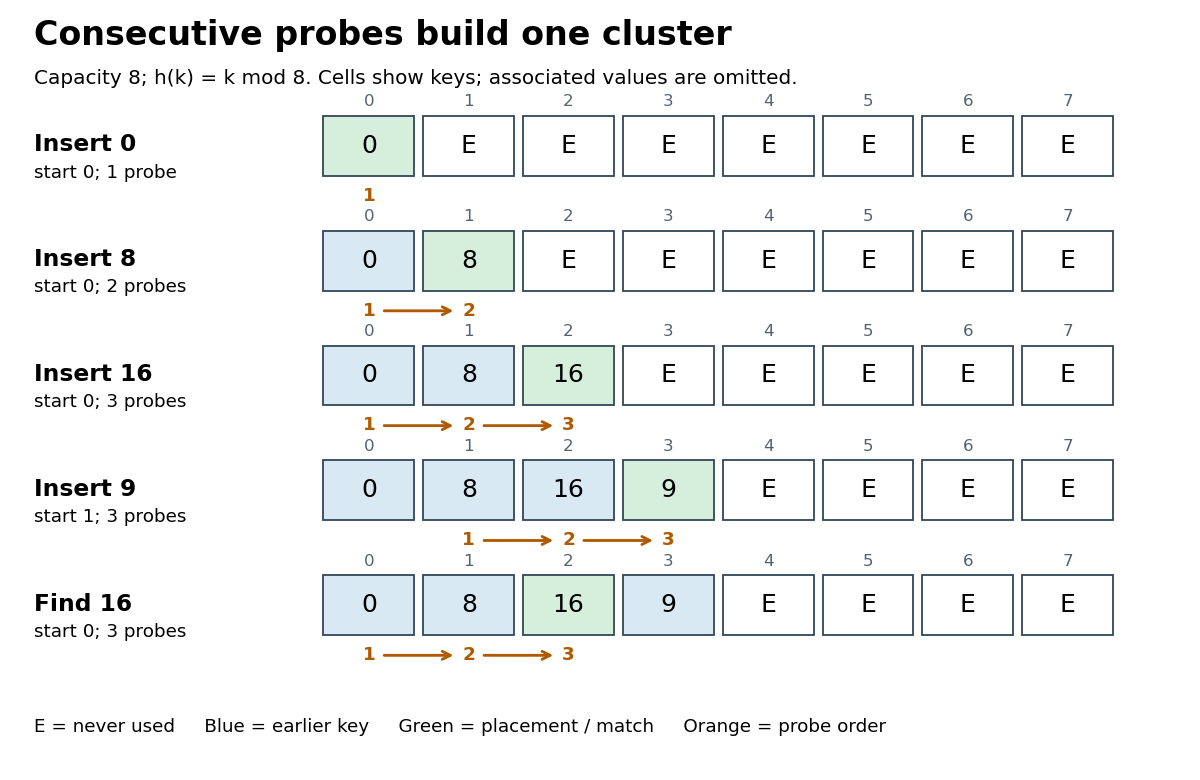
Bound lookup to at most hash table probes, even if no
E remains. For algorithm termination, the first array indices are distinct: equality of and implies that divides by modular arithmetic, and forces . They therefore cover the entire finite set of slots exactly once. If no occupied hash table key matches and no E is encountered, exhausting these hash table probes establishes absence; wrapping around again supplies no new information.[ref]Lecture 10: Hashing III: Open Addressing. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; Lecture 10: Hashing III: Open Addressing, pp. 1–2, probe permutation requirement and Search loop with m trials
The attraction is a compact array and a simple hash table probe rule. Consecutive slots can benefit from spatial locality, although actual memory cache behavior depends on representation and hardware. Correctness rests on preserving the search route; speed depends on how long that route becomes. The linear probing cluster below explains why even a moderate hash table load factor gives no universal constant lookup bound.
A maximal consecutive run of occupied or deleted slots in linear probing, bounded by never-used slots when any exist; adjacency wraps around by modular arithmetic. Deleted slots still belong to the search run.[ref]
5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; Section 5.2.1, definition of a run using non-nil entries and modular indices
In the eight-slot example, array indices form one linear probing cluster. Inserting absent hash table key starts at , passes the occupied slots , and fills . This extends the same linear probing cluster despite having a different initial array index from . A hash collision at the initial slot is enough to make later slots compete too.
For a worst-case family, insert integer hash table keys into an empty capacity- array, using the hash function , where . They occupy array indices . Lookup of absent needs hash table probes. Taking gives hash table load factor at most while the number of hash table probes grows with . Thus occupancy alone cannot promise constant lookup work.
Before any rebuilding, bounded lookup, deletion by hash table key, and insertion with a duplicate check each have worst-case time complexity in Big O notation, assuming constant-cost hash function evaluation, array access and key equality. The counterexample gives a matching linear worst-case growth in the number of hash table probes. Hash table resizing is additional work; expensive string comparisons or hashing also fall outside these constant-cost assumptions.
In an insertion-only table, an absent hash table key starting anywhere inside a linear probing cluster reaches its far end. Filling a one-slot gap can merge two runs, joining hash table keys with different initial array indices into one long search route. The insertion of above exhibits this effect without a hash collision with at their initial slots.[ref]
Lecture 10: Hashing III: Open Addressing. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; Lecture 10: Hashing III: Open Addressing, pp. 3–4, Linear Probing and Figure 4: Primary Clustering
A deleted-slot marker in open addressing. Lookup continues past it because a hash collision may have displaced a match further along. Linear probing can reuse the slot for insertion after checking for an existing equal key. A genuinely empty slot can terminate lookup; this marker cannot.[ref]
5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; section 5.2, find, add, remove, and correctness paragraph distinguishing del from nil
Delete hash table key from the original eight-slot example. Writing
E into array index makes lookup of inspect and incorrectly report absence, although its hash table record remains at . Writing D instead makes lookup pass and reach , returning after three hash table probes. The deleted slot must remember that the search route once continued through it.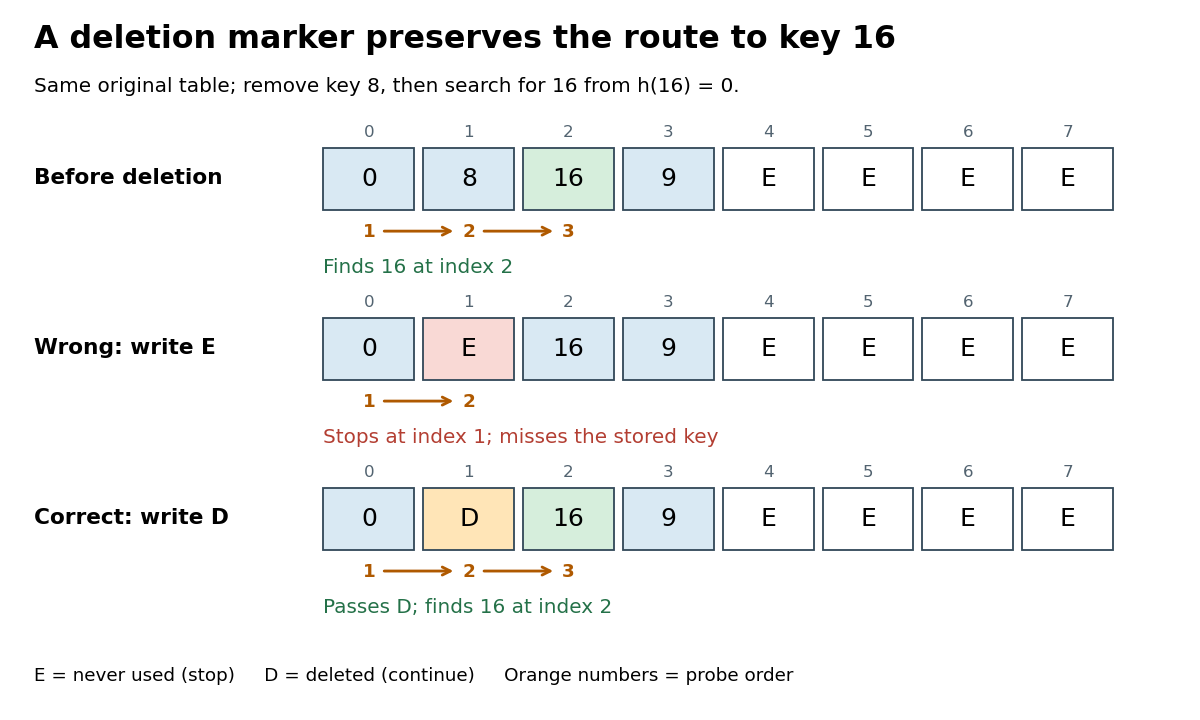
Deleting to an empty slot breaks lookup; a tombstone in open addressing preserves the search route
. Original deterministic comparison: the middle and lower rows are alternative deletions from the top row. E means never used and stops lookup; D means deleted and lets lookup continue. Orange numbers give the hash table probe order for hash table key . Details.A short algorithm correctness proof uses this invariant: no never-used slot precedes a stored hash table key along its linear probing route. Initially the claim is vacuous. Insertion places a new hash table record no later than the first
E, possibly at an earlier D, and cannot create an E before another stored hash table record. Replacing a value leaves all slots occupied as before. Deletion to D also creates no E. By mathematical induction over operations, the invariant persists, so stopping lookup at E is sound. Deletion directly to E invalidates that argument, as the diagram shows.To implement the hash table map operation
put(k,v) in one bounded scan, remember the first D encountered, but keep checking occupied hash table keys. A later key equality match means replace that hash table record's value and stop. Only after reaching E, or completing hash table probes, is absence established. Then insert at the remembered D, if any; otherwise use the stopping E. If all slots are occupied and no match exists, report full or rebuild before trying again. Merely finding D is not permission to create a second equal hash table key.[ref]Continue from the correctly deleted example, with hash table keys at array indices and
D at . put(16,Z) examines and updates the value at , leaving deleted and retaining three live hash table records. Inserting immediately at would instead create two copies of . Now put(24,W) examines , proves absence at E, and places the new hash table record at the remembered array index . The hash table load factor rises from to ; reusing D avoids extending the linear probing cluster to .For a boundary case, fill all eight slots with hash table keys and then delete all eight to
D. The live hash table load factor is zero, but absent lookup of still needs eight hash table probes. put(16,C) also checks eight slots before reusing the first D, at array index . A loop that waits indefinitely for E would never finish in this state. Rebuilding from the live hash table records into a fresh array removes each tombstone in open addressing and restores never-used stopping slots.[ref]5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; Section 5.2, resize: reinsert live elements and reset the non-nil count to the live count
One inspection of an array slot during an open addressing operation. Its array index follows the chosen probing rule; its contents determine whether to continue, return a matching hash table record, or establish absence.
The collection of records assigned to one bucket index by a hash function. In separate chaining, an array slot refers to this collection, which may be empty.
For hash buckets, number them and write for the number of records in hash bucket . Each record belongs to exactly one hash bucket, soAn empty hash bucket contributes zero to this sum but still contributes one to the denominator . The hash table load factor therefore measures records per allocated hash bucket, not records per nonempty hash bucket. A hash bucket is a destination selected by the bucket-index hash function; with separate chaining, its records need not occupy consecutive positions in computer memory.
For the twelve-record concentrated placement in load factor of a hash table, one hash bucket contains twelve records and seven hash buckets are empty. Averaging only over nonempty hash buckets gives , whereas the hash table load factor is . This difference matters when deciding how much array capacity to allocate. For , the largest hash bucket satisfies ; the lower bound follows because at least one entry cannot be below the arithmetic mean. Neither inequality says that an actual hash function achieves a balanced placement.
The equivalence relation used to decide whether two keys name the same record. A hash function must respect key equality; a hash collision does not establish key equality.
The choice of key equality is part of the map's meaning. In the one-value-per-key policy of hash table, one record represents each stored equivalence class of keys:
put(k,v) updates an existing equal key and adds a record only if no equal key is present. A collection that deliberately retains repeated equal keys has a different policy; its load count must count those extra records too. Repeated calls and distinct stored records are different quantities.[ref]Lecture 8: Hashing I. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 1, Dictionary Problem: distinct keys or replacement on repeated insertion
For an original example, restrict keys to two-letter strings using letters
A through Z or a through z. Declare two keys equal when replacing every uppercase letter by its lowercase counterpart gives the same string. Assign each letter its position in the alphabet, ignoring case, and define the bucket-index hash function as the sum of the two positions modulo , using modular arithmetic. Then AB and ab are equal keys and both select hash bucket . Key ba also selects hash bucket because , but is unequal to ab: order still matters. Starting empty, put(AB,7), put(ab,9), put(ba,4) leave two records, with values for the ab equivalence class and for ba; the hash table load factor is , not .The compatibility rule is one-way: . Otherwise a lookup using an equal spelling could search a different hash bucket and incorrectly report absence. Equal indices merely allow a key equality check. Both the equivalence relation and the hash function must stay consistent while records are stored; changing equality-relevant key contents can invalidate the lookup rule. The Java contract imposes these consistency and equality requirements on
equals and hashCode.[ref]Object (Java SE 25 & JDK 25). Java Platform, Standard Edition 25 API Specification by Oracle; Method Details, equals equivalence-relation contract and hashCode general contract
The number of stored records divided by the number of hash buckets. For separate chaining, this is the mean chain length over all hash buckets, including empty ones.
Consider two original separate chaining placements using the deterministic hash function on nonnegative integer keys. With , keys give the balanced chain lengths . Instead, keys all select hash bucket , giving . Both store records, so both have . The maximum chain lengths are and . These are constructed placements, not measured workloads.
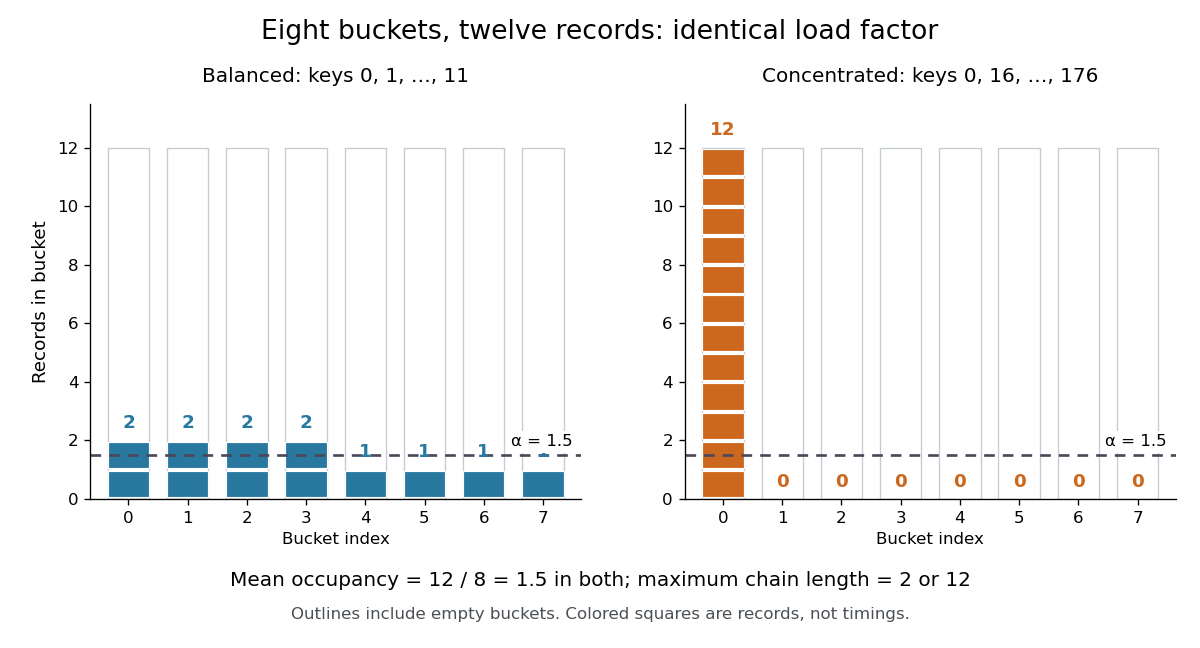
The same hash table load factor permits balanced and concentrated hash bucket occupancies
. Both original examples use eight hash buckets and twelve distinct integer keys. Every outlined column counts towards , including empty ones; each colored square represents one record. The dashed line marks the arithmetic mean , not the maximum chain length. Details.For an absent query, separate chaining inspects every record in the selected hash bucket. Key selects hash bucket in both examples but is stored in neither, so it takes two key equality comparisons in the balanced placement and twelve in the concentrated placement. Key selects hash bucket and instead takes one comparison in the balanced placement and zero in the concentrated placement. If an absent query's bucket index has the uniform distribution on a finite set of eight indices, its mean comparison count is in either fixed placement. That average does not limit the cost of a particular query.
For successful lookups, suppose each of the twelve stored keys is queried with equal probability, with fixed chain order and no rearrangement on access. A chain of length contributes comparison counts , irrespective of its order. ThusThe balanced placement gives comparisons; the concentrated placement gives . Even this average depends on more than : concentration appears through the squared chain lengths. These exact counts exclude computing the hash function, locating the hash bucket, and allocating records. Elapsed lookup time also depends on the cost of key equality, key length, and memory access latency; alone specifies none of them.
The expected time complexity bound for separate chaining needs a probabilistic assumption. Fix distinct stored keys and a query independently of the random choice of hash function, and require for every unequal pair, where is a constant independent of . With constant-cost hashing, array access and key equality, this suffices. The authored chaining analysis cited here uses this pairwise-collision argument; its multiplicative construction has , rather than the of simple uniform hashing.[ref]
5.1 ChainedHashTable: Hashing with Chaining. Open Data Structures: An Introduction by Pat Morin; section 5.1.1, Lemma 5.1 and the indicator-variable proof of Lemma 5.2
For the proof outline, let be the indicator random variable that stored key shares an absent query 's hash bucket. By linearity of expectation,A present query's full chain contains itself plus at most other records, giving . Stopping at the match can only improve this bound. Full independence is unnecessary for this calculation, but fixed known hash functions and keys chosen adaptively to collide are outside the stated assumption. Keeping bounded then controls expected lookup work, while the concentrated example still explains why it gives no worst-case guarantee.
For the balanced twelve-record map,
put(3,new_value) replaces a value, so and remain unchanged. An absent key such as instead adds a thirteenth record, giving if capacity stays fixed. Under a policy that stores every repeated-key record separately, another record with key would also increase ; all equal-key records necessarily share a hash bucket when the hash function respects key equality. State the map policy before interpreting the count.The appeal of the hash table load factor is that one number helps tune a space-versus-search tradeoff: more hash buckets require more array storage and can reduce expected search work under the stated assumptions. The actual chain lengths and query choices still matter.
In open addressing, counts record slots and counts live records, so . A policy retaining at least one genuinely empty slot requires ; being below one is not itself a speed guarantee. For deletion using a tombstone in open addressing, also track , the number of marked slots: counts slots that cannot terminate an unsuccessful probe. For example, gives live occupancy but nonempty-or-marked occupancy . These ratios answer different questions.[ref]
5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; section 5.2, three entry types, counters n and q, and find stopping at nil
Changing the number of hash buckets and reassigning stored records using the new bucket-index hash function. Amortized analysis of rebuilding and expected value bounds for subsequent lookup address different costs.
Rebuild the balanced example from load factor of a hash table with while keeping exactly the same twelve records. Under , keys retain their indices, whereas keys move from hash buckets to hash buckets . The new chain lengths are twelve ones followed by four zeros; . Copying the old eight chain heads and adding eight empty heads would leave those four moved keys unreachable by the new lookup rule.
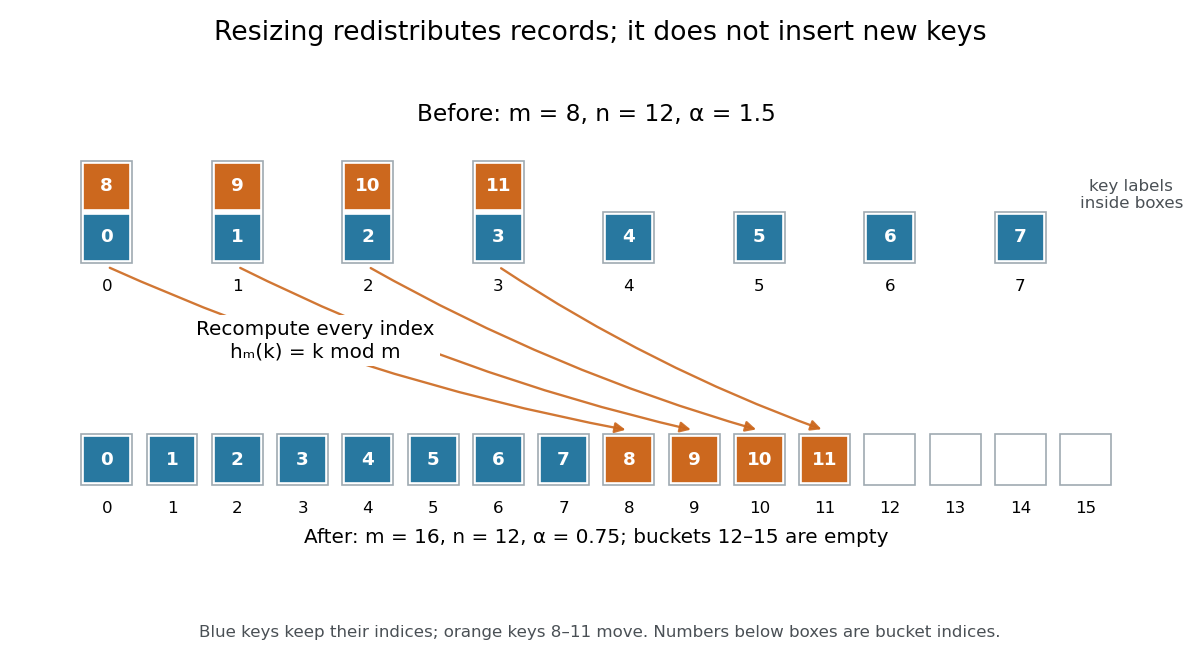
Hash table resizing from eight to sixteen hash buckets redistributes existing records
. Original modular arithmetic example for keys . Blue keys keep their indices; orange keys move because differs from . The record count stays twelve, and empty hash buckets still count towards capacity. Details.For a short algorithm correctness outline, allocate the new array, visit every old record once, compute its new bucket index, and link it into that hash bucket. At every step, each transferred record is stored exactly once at the index prescribed by the new hash function. Finishing the visit therefore preserves every key-value association and makes the new lookup rule valid. Direct transfer can skip duplicate searches because the old one-value-per-key map already established distinct equivalence classes; rebuilding is not twelve new user insertions.
Under constant-cost hashing, linking and slot initialization, separate chaining rebuilding takes time complexity: initialize new heads, examine old heads, and transfer records. For doubling, , this is in Big O notation. It is when the resize policy makes proportional to , but an enormous mostly empty old array can make scanning its heads dominate. Growing capacity can lower without shortening a particular chain: the concentrated keys all remain in hash bucket after growth from eight to sixteen.
For an insertion-only sequence starting empty, choose initial capacity and double before a genuinely new key would make . The first three growths occur before inserting records and transfer existing records. If distinct records are inserted, the transfer count is . More generally, the transferred old capacities form a geometric series; if the last is , their sum is . Initializing and scanning these geometrically growing arrays also costs in total, giving amortized rebuilding overhead per insertion. A triggering insertion still pays for its whole rebuild.[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 2, Rehashing, How fast to grow?, and Amortized Analysis
The illustrative twelve-record resize above is an explicitly requested rebuild, not a growth triggered by this threshold policy. Checking for an equal key before growing also prevents a value replacement from triggering unnecessary growth. To combine resizing overhead with expected constant insertion time complexity, separately impose the collision and constant-cost assumptions in load factor of a hash table. Amortized analysis distributes rebuilding costs over operations; it does not randomize a poor hash function or bound a single operation's latency. With deletions, separate the grow and shrink thresholds; for example, growing when full and halving at one-quarter live occupancy leaves room for many operations between opposite rebuilds.[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 3, Back to Hashing and Delete: halving when n reaches m/4
// Target: computer-science.bigb
The identifier used to select a hash table record. Key equality determines whether two identifiers name the same entry, while a hash function chooses where its lookup begins.
An entry pairing a hash table key with its associated value . In the map interface of hash table, each key equality class has at most one live hash table record.



