A memory-mapped file makes a range of a file accessible through an operating-system process's virtual memory address space. Once the mapping exists, ordinary loads and stores address its contents instead of explicitly reading them into a separate application buffer. This is attractive for jumping between records in a large file: an offset becomes an address calculation, and demand paging can supply the needed memory pages. It removes the application's explicit read-and-copy step; it does not promise that every access avoids copying, input-output, page faults or overhead, or that mapping is universally faster.
The backing file, page cache contents and each operating-system process's page table play different roles. For ordinary buffered Linux kernel mappings, the page cache holds reusable file contents; normal reads and writes also use it. A valid mapping can exist before this operating-system process has a usable page table entry. A first load can therefore trigger a page fault even when another reader has already brought the contents into computer memory. If the contents are absent, servicing the page fault can require input-output; if present, the handler can install an address translation without that read. Special paths that bypass the page cache are outside this explanation.[ref]
Page Cache by The kernel development community. Page Cache, opening paragraph: normal reads, writes and mmaps go through the page cache; bypass paths exist
The following example and diagrams are an original toy model, not an actual benchmark or a trace of a running operating system. They assume ordinary buffered file mappings, successful accesses, two cooperating operating-system processes, no concurrent resizing, and explicitly ordered actions. Memory-mapped file offset translation explains where the accesses land; shared file mappings and private file mappings explain whose contents change; memory-mapped file synchronization explains the separate persistence boundary.
The file supplying a memory-mapped file's initial contents. Its logical file offsets identify data independently of the virtual addresses chosen by different operating-system processes. Modified private file mapping contents have private storage; they are not updates waiting to be written to the backing file.
The POSIX mapping interface. Ordinary Linux kernel file mappings require a positive length and an aligned file offset. A null address lets the operating-system kernel choose an aligned base; length need not be aligned. Check for
MAP_FAILED. After success the file descriptor may be closed without invalidating the mapping; munmap or process termination removes it.[ref]mmap(2) — Linux manual page. DESCRIPTION: address, length, offset and descriptor lifetime; munmap; RETURN VALUE
Mapping does not extend the backing file. Under POSIX, for an initially partial last memory page, the tail beyond the file's end is zero-filled and is not written back as file data; accesses to whole mapped memory pages beyond the end raise
SIGBUS. POSIX leaves access to portions added or removed by later resizing unspecified. Establish the required file size first and coordinate resizing with readers; a mapping's length is not proof that those bytes exist in the file.[ref]mmap — POSIX.1-2024. POSIX.1-2024, DESCRIPTION: partial end page, whole pages beyond the object, and changed file size; RATIONALE: references beyond the end do not extend the object
The Linux kernel documents a tail-cache exception: modified beyond-end bytes can survive in the page cache and appear in later mappings, although never written to the file. Do not use that tail as reliable storage.[ref]
mmap(2) — Linux manual page. BUGS: modified contents beyond the object end can remain in the page cache
Removes a mapping from an operating-system process's address space. Mapping lifetime is separate from file descriptor lifetime; removal also does not supply the completed writeback promised by memory-mapped file synchronization.
Let be the memory page size, the aligned starting file offset, the mapping length and its base virtual address. A valid displacement with corresponds to file offsetHere is the relative memory page index, the floor function selects its integer part, and Euclidean division gives the within-page displacement . The backing page begins at . This identifies file contents; the page table separately selects a resident page frame and enforces permissions.
Take , and bytes in a file of at least 12288 bytes. A has a shared file mapping at . B has a shared file mapping at and a private file mapping at . These bases are illustrative chosen results, not requested fixed addresses. All three mappings cover the same two backing pages: file offsets 4096–8191 and 8192–12287. Displacement selects relative page 1, within-page displacement 37 and file offset . Thus A's
0x10001025, B's shared 0x20001025 and B's private 0x30001025 initially identify the same byte. The adjacent displacement 4134 identifies file offset 8230. Different virtual addresses can reach the same backing contents.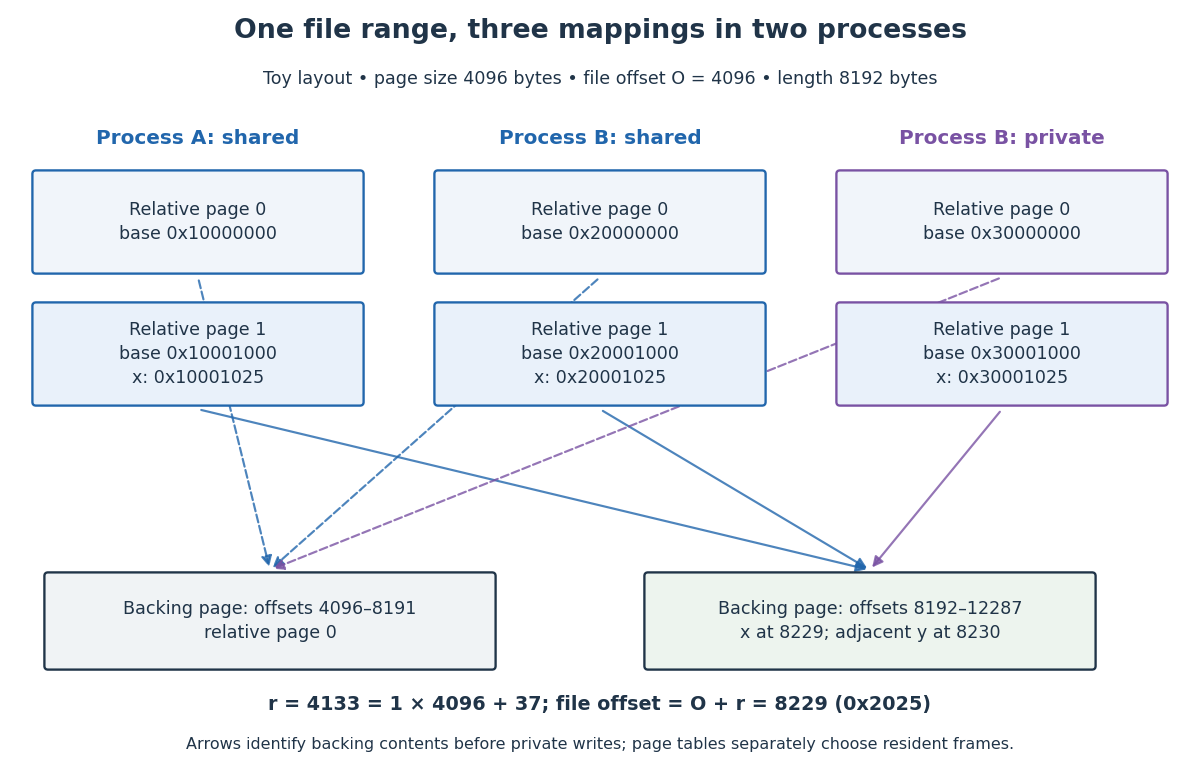
Two operating-system processes map two backing pages at different virtual addresses; displacement 4133 identifies file offset 8229
. Details. 
To access a requested file offset that is not aligned, choose and displacement . Mapping enough bytes to cover that displacement plus the requested length makes the desired data start inside the aligned mapping. Do not pass the unaligned directly as the Linux kernel
mmap offset. For example, uses and displacement 37; that one-page start differs from our two-page mapping's .With
MAP_PRIVATE, copy-on-write initially reuses backing page cache contents. In our model, a private store raises a protection page fault, copies the affected memory page to a private page frame, installs a writable page table entry and retries. The other memory page can remain shared. This page fault needs no storage read.In B's private file mapping, storing copies relative page 1, including its neighbor . Next, A stores through its shared file mapping. After coordination outside the mapped data, B's shared reads give , while its detached private page gives . The untouched first memory page remains backed by the file; this is not a frozen snapshot of the whole file. Neither page writeback of shared contents nor msync publishes B's private 99. To save those private contents, the application needs a separate explicit file update.
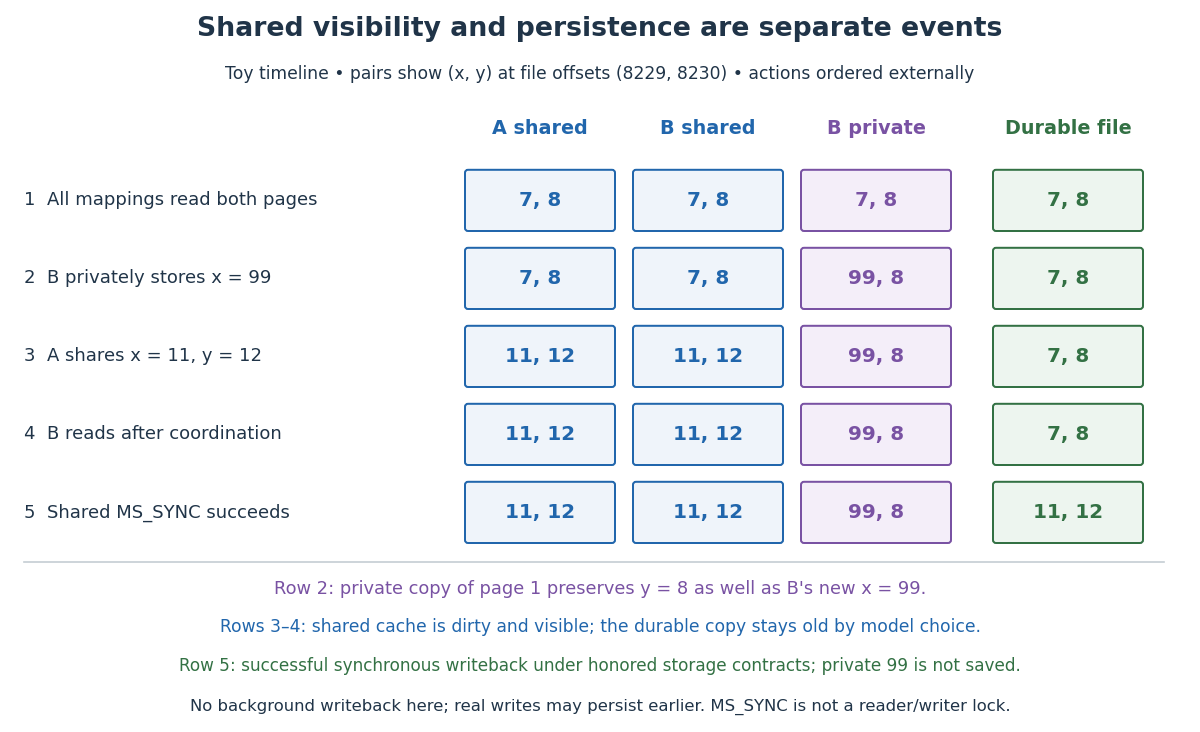
Toy shared file mapping and copy-on-write timeline: visible shared changes precede the chosen durable completion; private changes remain separate
. Details. 
There are two distinct questions: whether another operating-system process can observe shared contents, and whether those contents survive a crash. In the timeline, persistent storage deliberately remains while the shared page cache contains . No background page writeback occurs in this toy interval. Real page writeback may persist some contents earlier; shared visibility alone cannot tell the reader which contents are durable.
For the covered shared range,
msync(base, length, MS_SYNC) requests page writeback and waits for completion; check its return value. MS_ASYNC is not a durable completion acknowledgment, and on modern Linux kernel versions it is a no-op because dirty contents are already tracked. The address must be aligned, so synchronizing our changed second page uses base + 4096, length 4096, rather than base + 4133. Unmapping alone is not a guarantee of completed writeback.[ref]msync(2) — Linux manual page by Linux man-pages project. DESCRIPTION, RETURN VALUE, ERRORS and VERSIONS: covered range, MS_SYNC versus MS_ASYNC, page-aligned address, and Linux MS_ASYNC behavior since 2.6.19
For persistence of the file and associated file metadata, fsync on an open file descriptor is a broader interface; a new directory entry needs separate synchronization of its file-system directory. Retain a suitable file descriptor if the persistence protocol needs it after mapping. Successful storage completion still relies on the file system and device honoring their persistence contracts.[ref]
fsync(2) — Linux manual page by Linux man-pages project. DESCRIPTION, RETURN VALUE and ERRORS: file data and metadata, directory entry, completion and reported failures
Neither fsync nor msync supplies mutual exclusion, an atomic storage write for several memory pages, or an application-wide file-system transaction. Stop or coordinate writers before deciding which update a completion acknowledges. A crash during page writeback can leave a mixture of old and new contents unless a separate recovery protocol provides file-system crash consistency. The last timeline row assumes successful synchronous completion, honored storage flush semantics and no subsequent writer; it illustrates a persistence boundary, not a promise about arbitrary hardware failures.
A mapping-range synchronization interface used by memory-mapped file synchronization. Its
MS_SYNC mode concerns completed updates to a backing file; it does not merge private file mapping changes into that file or coordinate competing readers and writers.// Target: computer-science.bigb
Articles by others on the same topic
There are currently no matching articles.