An operating system manages the resources that let programs run and cooperate. Operating-system processes organize running work, virtual memory supplies protected address spaces, and a file system supplies named files that can outlive the operating-system process that created them. The operating-system kernel enforces the core mechanisms; system calls let programs request its services. Separating these responsibilities makes it possible to share a file while keeping the participating operating-system processes' address spaces isolated. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/file-intro.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 39, introduction: processes, address spaces and persistent storage
A concrete example makes the separation useful: two operating-system processes can each use file descriptor
3, yet refer to different files; two different names can instead refer to the same file through hard links. Neither a name nor a small integer identifies an object without its context. Virtual memory has a related distinction: the same virtual address in different address spaces can designate different physical addresses.Unix provides an influential example of this design. In their July 1974 paper, Dennis M. Ritchie and Ken Thompson date its earliest version to approximately 1969–70 and describe operating-system processes, a hierarchical file system, and inodes separating directory entries from file metadata. This is a documented historical example, rather than a claim that every operating system uses Unix conventions. [ref]
An operating system supporting multiple users with distinct identities and protection requirements. Access control determines which users may access shared resources.
The Portable Operating System Interface standards specify interfaces and observable behaviour for portable programs, including file descriptors, hard links and unlinking an open file. Their requirements do not prescribe one on-storage inode layout. The worked examples below use POSIX Unix semantics for ordinary files. [ref]
https://pubs.opengroup.org/onlinepubs/9799919799/basedefs/V1_chap03.html. The Open Group, POSIX.1-2024, definitions of files, directories and file descriptors
// Target: computer-science.bigb
An operating-system family with process, file and pipe abstractions. The traditional discretionary file-permission model separates owner, group and other users and read, write and execute rights. Individual Unix systems can add richer access control lists and other protection mechanisms.
// Destination: computer-science.bigb
A member of the Windows NT operating-system family. Executive services such as object, memory and input-output management execute in privileged kernel mode. Its object-level access control lists and subject tokens permit finer authorization policies than traditional owner-group-other file permissions.
// Destination: computer-science.bigb
In polled input-output, the CPU explicitly checks a device's status to discover whether work is ready or an operation has completed. Repeatedly checking in a tight loop is busy polling; periodic checks can instead leave time for other work. Interrupt-driven input-output changes how readiness is discovered, while DMA changes how payload data moves. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/file-devices.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 36, sections 36.3–36.5: polling, interrupts and DMA
Use the model drawn under interrupt-driven input-output: device events occur at times , while polls occur at . Assume each event remains pending until detected and an event simultaneous with a poll is visible to that poll. The detection times are , giving delays . Four of the seven checks find no new event. These are event-detection delays, not completion times for servicing the events.
More generally, for polls at with , an event at time is first detected atThe ceiling function chooses the first poll at or after the event. To verify the bound, that poll is less than one interval beyond ; if is itself a poll time, the delay is zero by the stated visibility convention. This argument assumes instantaneous checks, persistent pending status and an uninterrupted poll schedule. It does not describe missed transient events or a CPU too busy to maintain that schedule.
The attraction of polled input-output is simple control and the possibility of processing several ready items in one visit. Busy polling spends CPU time even when nothing is ready, but short waits or frequent events can make avoiding repeated interrupt entry worthwhile. The right choice depends on actual checking, notification and service costs. See interrupt-driven input-output for a documented combination of both strategies. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/file-devices.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 36, section 36.4: polling and interrupt tradeoffs
// Destination: computer-science.bigb
An authorization table with subjects or protection domains as rows, objects as columns, and sets of allowed operations as entries. An access control list stores an object column; a capability list stores a subject row. This representation is not a numerical linear map and has no ordinary floating-point matrix inverse.
// Destination: computer-science.bigb
An unforgeable reference carrying authority to perform specified operations on an object. In seL4, the operating-system kernel stores security capabilities in protected slots; an integer naming a slot is not itself freely forgeable authority. Guessing another operating-system process's slot number does not give access to its security capability. [ref]
Capabilities tutorial by seL4 Project. Capabilities tutorial, Background: What is a capability?; CNodes and CSlots
A security capability authorizing a reply to a particular waiting caller. In the seL4 tutorial's IPC model, a call establishes one-time reply authority, allowing a user-space service to return to the correct client. The exact representation depends on the operating-system kernel configuration. [ref]
IPC tutorial by seL4 Project. IPC tutorial, Background: System calls, seL4_Call and reply capabilities
A file system organizes files, their file metadata, and the names through which they can be found. In the Unix model used here, a file-system directory contains directory entries associating names with inodes; an inode describes the underlying file and how to locate its contents. The file-system namespace answers "what does this name reach?", while the inode answers "which file is it?". These are distinct responsibilities, even though they cooperate on every lookup.
For a computed toy example, let one file-system directory contain names
a and b, both referring to inode 42 in the same file system. That inode has size 6 bytes and two hard links. Its direct references lead to four-byte file data blocks 7 and 9: block 7 holds hell, while block 9 holds o followed by a newline, with two unused slots. Reading either name therefore obtains the same six-byte contents hello followed by a newline. There is one file with two names, not two copies. This direct-reference layout and tiny block size are teaching choices, not requirements on every file system.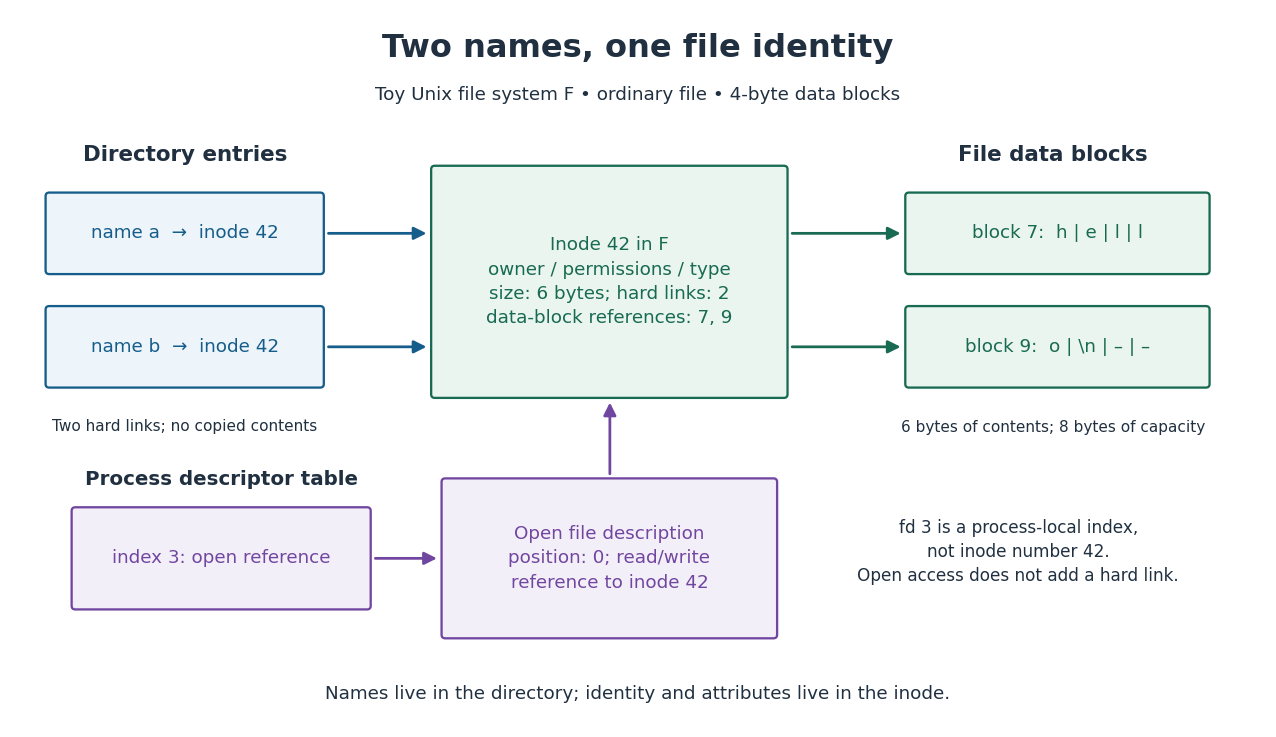
The separation is useful because a rename within this file system, from
a to a previously unused name c, can change a directory entry without copying the six bytes of contents. The remaining name b still reaches inode 42. A successful write changing the first byte through either name changes what both names subsequently read, to jello followed by a newline. This sharing is the attraction of hard links, and also why a hard link is not an independent backup. A program that replaces a named file with a different file can instead make the names diverge. [ref]https://pubs.opengroup.org/onlinepubs/9799919799/functions/rename.html. The Open Group, POSIX.1-2024, rename: changing names and replacing directory entries
A file system organization in which each file data block identifies its successor. It supports sequential traversal and growth without a fixed per-file index tree, but arbitrary file offsets require following the chain. Adding predecessor links permits reverse traversal.
Allocated space unused inside an allocation unit. For a computer file stored in fixed-size file data blocks, the final partially occupied block can waste almost one block.
A representation of currently unallocated disk block numbers, maintained as a list or linked groups of available numbers. Allocation removes a number; deallocation returns it after ownership is relinquished. Reserved structures and blocks still owned by an unnamed but open file are unavailable. A block allocation bitmap is an alternative representation of the same allocation state.
A disk block number identifies a fixed-size storage region on a volume. It locates storage rather than naming a file. A file can occupy several numbered file data blocks, while a disk block containing several inodes can describe several files.
Move file contents to consolidate their allocated regions. A per-file read-then-write cost model charges two transfers and, if specified, two separate seek and rotation overheads for each moved file. That model differs from an ideal sequential transfer of the same total number of bytes.
An object whose contents and attributes can be accessed through operating system interfaces. Here an ordinary file means a byte sequence with file metadata, distinct from a file-system directory or a symbolic link. Its contents need not disappear when the creating operating-system process ends.
A computer file whose logically zero-filled regions need not occupy physical file data blocks. The file offset and byte length describe the logical content independently of the blocks actually allocated.
A byte position measured from the start of a file, beginning at zero. A memory-mapped file combines a starting file offset with a displacement inside its mapping; this is distinct from an open file description's current read/write position.
Information describing a file, such as type, owner, access permissions, size, timestamps and hard link count. In the toy layout, the inode carries these attributes; the directory entries carry the names. The distinction matters because renaming a file need not copy its contents.
A storage unit holding part of a file's contents. The toy inode references two four-byte file data blocks for six bytes of contents: allocated capacity is bytes, while logical size is bytes. This counts only the two file data blocks, excluding storage for the inode and directory entries.
A file containing directory entries. Each entry supplies a name in that file-system directory; two entries in the same file-system directory cannot have the same name. In an inode-based file system, a file-system directory has its own inode, and its contents describe names of other objects. [ref]
https://pubs.opengroup.org/onlinepubs/9799919799/basedefs/V1_chap03.html#tag_03_103. The Open Group, POSIX.1-2024, sections 3.103–3.104: directory and directory entry
An association between a name in a file-system directory and a file. In the toy file system, the pairs are
(a, 42) and (b, 42): each name resolves to the same inode. The name belongs to the directory entry, rather than being the single authoritative name stored in that inode.The organization of names and the rules for resolving them to files. A path such as
/notes/a selects successive directory entries starting from the root file-system directory. Its spelling describes a route, not an immutable identity: replacing the final directory entry can make the same path reach a different inode.A directory entry associating a name directly with an existing file. In the inode-based example, successful
link("a", "b") adds the second name for inode 42 and increases its hard link count from 1 to 2. Both directory entries have equal status; removing a leaves b usable. This example assumes both names are in the same file system, the destination name is unused, and the operation is permitted. [ref]https://pubs.opengroup.org/onlinepubs/9699919799/functions/link.html. The Open Group, POSIX.1-2017, link: adding a directory entry and incrementing the link count
For an ordinary file under the POSIX rules used here, successful
unlink("a") removes the named directory entry and decreases the hard link count. An existing open file description still refers to the same file; removing a name does not detach an already open file descriptor. When the final hard link disappears, the contents remain available through open references until those references close. This distinction is between the lifetime of a name and the lifetime of the underlying file. [ref]https://pubs.opengroup.org/onlinepubs/9699919799/functions/unlink.html. The Open Group, POSIX.1-2017, unlink: removal of names and deferred removal of open-file contents
Start with names
a and b for inode 42 and one file descriptor 3 referring to one open file description. Let count hard links and count live open file descriptions for this file. Assume successful operations, no additional references, and no memory-mapped file. The stages areAfter the first removal, b still works. After the second, neither name works, but a read through the existing file descriptor can still obtain all six bytes if its open file description's current position is at the beginning. The final close releases the last open reference, allowing the inode and its file data blocks to be reclaimed. Freed storage is reusable; this does not promise that old bytes are securely erased. [ref]https://pubs.opengroup.org/onlinepubs/009604499/functions/close.html. The Open Group, POSIX, close: releasing descriptors, open file descriptions and unlinked-file storage
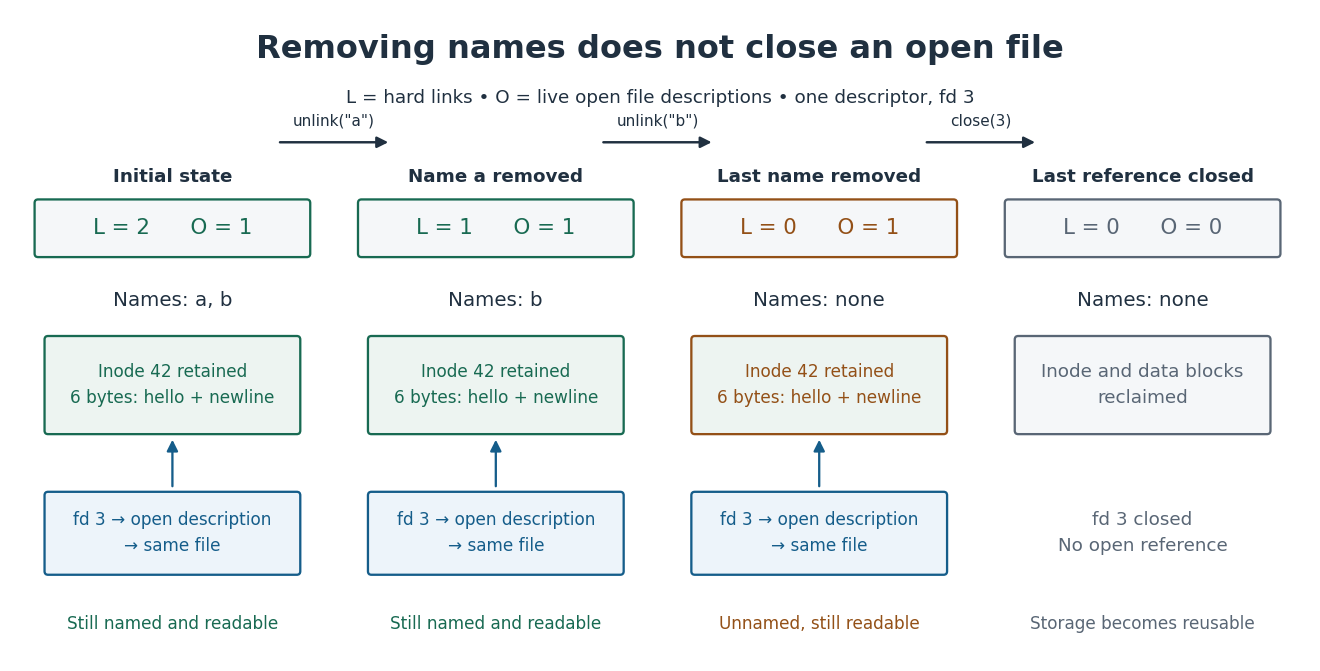
The reasoning is bookkeeping rather than a long proof: each successful removal subtracts one from and leaves unchanged; closing the only file descriptor in this example releases the sole open file description. Storage is reclaimable only at the last stage. is a teaching count, not a count of file descriptors or an asserted internal inode field: several file descriptors can share one open file description, and other references such as a memory-mapped file require additional lifetime accounting. The diagrams are abstract models, not operations on actual user files.
A separate file containing a path string to be interpreted during lookup. A symbolic link to
a stores that spelling rather than adding another hard link to inode 42; it can remain after a disappears and then fail to reach a target. It does not increase the target's hard link count. The diagrams below track only hard links and open references. [ref]https://pubs.opengroup.org/onlinepubs/009695299/functions/symlink.html. The Open Group, POSIX, symlink: storing the supplied path string
// Target: computer-science.bigb
A memory cache of device blocks indexed by device identity and block number. A hit avoids slow device access; a miss obtains a buffer and reads the block. Dirty buffers carry modified data that must be written before reuse, and pinned buffers cannot be evicted while an operation uses them. Deferred writes improve throughput but need explicit durability handling.
A buffer cache can hold both file data blocks and storage containing file metadata, such as inodes and block allocation bitmaps. Reusing a buffered device block saves repeated input-output; retaining several modifications before buffer cache writeback can combine them into one transfer. Section 40.7 of Operating Systems: Three Easy Pieces by Remzi H. Arpaci-Dusseau and others explains these benefits for file systems.[ref]
File System Implementation. pp. 14–16: caching and buffering
The central distinction is that a dirty buffer needs a write, whereas a pinned buffer must retain its identity. A clean buffer can still be pinned, and a dirty buffer can have no client references. Neither releasing a reference nor obtaining a cache hit establishes file-system transaction durability.
A data structure holding the contents of one fixed-size region of a storage device, together with its buffer cache key, buffer cache validity, modification state and lifetime information. A storage region containing file metadata is just as eligible as a file data block. The structure can survive many callers: releasing it usually makes it available for later reuse, rather than immediately deleting the cached contents.
The identity used to find a buffered device block. In the fixed-block-size model, identifies the device and its block number; and are different keys if . A file's pathname or its logical block offset alone is insufficient for this device-indexed model. Interfaces supporting different transfer sizes need to specify the size and overlap rules too.
Maintain at most one logical buffered device block for each buffer cache key within this buffer cache. Otherwise two callers could modify different copies and later overwrite one another's changes. Lookup and reservation must therefore be coordinated by synchronization: even before contents are ready, a reserved key directs a second caller to the same structure. This invariant concerns the participating cache, not every copy of those bytes anywhere in the machine.
Whether a buffered device block's contents are ready for the requested use. Reserving a buffer cache key does not make its previous occupant's contents valid. A read fills the reserved structure before exposing its contents. A second caller finding an unfinished fill must wait; finding the identity is not yet a data cache hit under the convention used here. A failed fill must not expose the stale contents as valid.
A buffered partial write first needs the untouched bytes: read the old contents on a cache miss, change the requested range, and retain the result as a dirty buffer. A complete overwrite can initialize every byte without reading the old contents if the interface permits that path. The buffer cache access trace deliberately uses partial writes, so every cache miss reads the old block.
A valid buffered device block with modifications still owed to its backing location. Until successful buffer cache writeback, simply reassigning its buffer cache key would lose those modifications. “Dirty” records a write obligation; a write of identical contents can still mark the structure dirty. Repeated buffered writes can leave only the latest contents to be transferred.
A valid buffered device block with no outstanding write obligation to the backing location tracked by this cache. It can serve a cache hit. It becomes eligible for buffer cache eviction only when its retention and any pending input-output permit reuse. “Clean” does not assert that a device's volatile memory cache has been flushed to persistent storage.
A buffered device block whose identity is retained for unfinished work. Reference counting can represent both client references and additional pins. Dropping a client reference does not release an outstanding journal pin; dropping a pin does not remove somebody else's reference. In the buffer cache state model, counts all such retained references, so prevents buffer cache eviction. This count keeps the structure alive; a mutex separately controls who can inspect or change its contents. Waiting callers also need lifetime protection.
Transferring a dirty buffer's current contents to its backing location. The buffer cache state model permits no concurrent modification during the transfer and marks the result clean only after successful completion. A failed write preserves the obligation and prevents the proposed buffer cache eviction. A production implementation allowing new writes during input-output must retain their obligation rather than incorrectly clearing it when an older transfer finishes.
A successful transfer can leave data in a device's volatile memory cache. A storage flush or the documented equivalent supplies a persistence boundary; file-system journaling supplies recovery rules for related updates. These are additional obligations, not consequences of becoming a clean buffer.[ref]
Removing a buffer cache key's resident contents so the storage in computer memory can serve another key. An unreferenced clean buffer can be reused directly in the buffer cache state model; an unreferenced dirty buffer requires successful buffer cache writeback first. A pinned buffer cannot be chosen regardless of cleanliness. LRU replacement ranks eligible candidates; it does not override lifetime protection. If every candidate is retained, a cache miss cannot obtain space until something releases a reference or capacity changes. This is a resource shortage, not permission to discard live contents.
Use one fixed-size buffered device block per buffer cache key, serialized operations, successful reads and writes, and no outside changes to the backing contents. Record an absent state or a reserved key with validity , dirty flag , and retained-reference count . The bits describe contents, while the nonnegative integer describes lifetime. Every dirty buffer is valid, so implies . Reservation begins at ; successful fill changes only to 1. Modifying a valid retained structure sets . Releasing a caller changes , not or .
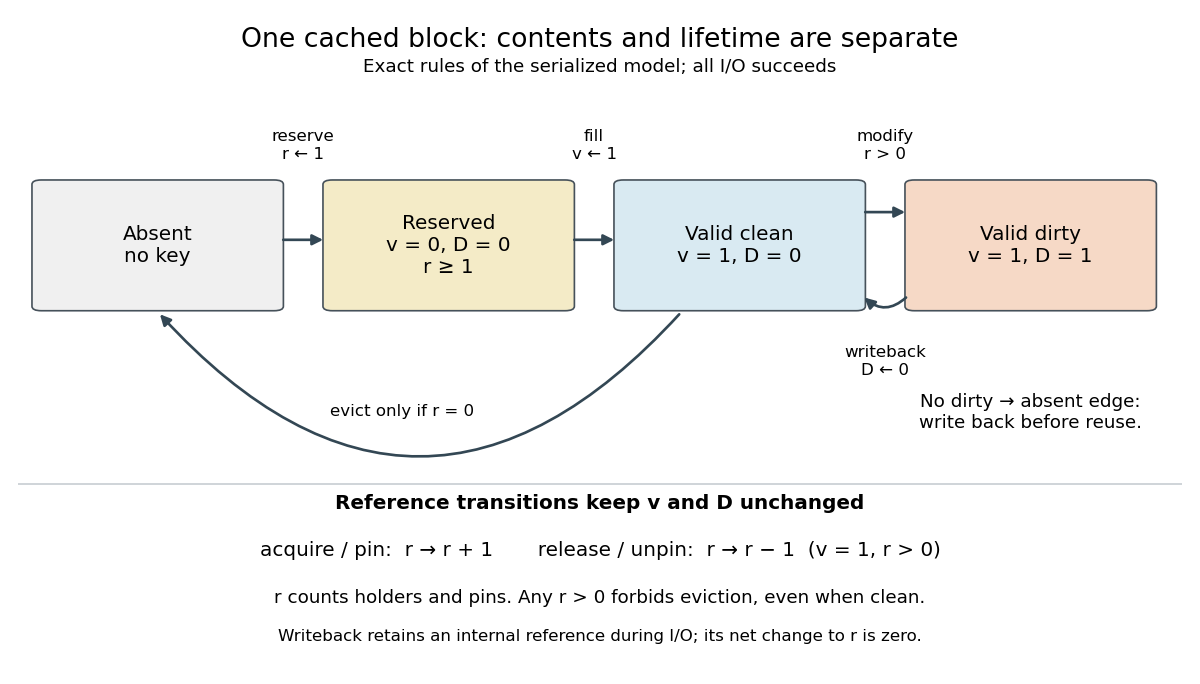
Buffer cache validity, dirty buffers and retained references impose different state-transition rules
. Details. The first diagram separates contents transitions from reference transitions. Buffer cache writeback temporarily retains the structure while transferring its contents; that internal reference is acquired and released inside the single serialized operation shown. Buffer cache eviction requires a valid clean buffer with . The diagram omits read errors, explicit cancellation of invalid reservations, concurrent writes, invalidation and journal ordering. In particular, a journal can forbid otherwise possible buffer cache writeback until its write-ahead logging dependencies are satisfied.
For a small independent check, bound to . Starting absent, allow reservation, acquisition, successful fill, modification, successful buffer cache writeback, release of a valid retained structure, and eligible buffer cache eviction. Exactly nine abstract states are reachable: absent, two invalid reservations with , and six valid states combining with . Every transition preserves ; the only eviction source has . This bounded finite-state machine check supports these safety rules, not a claim that work always completes.
Let be three distinct buffer cache keys on one device. Use two initially empty slots, LRU replacement refreshed at each completed request, and synchronous successful buffer cache writeback of a dirty victim. Each request acquires its target, finishes any fill, reads or partially modifies it, and releases the client reference. An explicit pin on remains after request 2 through request 7; pin and unpin do not refresh recency. No other references, invalidations, background writes or durability operations occur. Initial backing contents are represented by the integers ; partial writes change the tracked value of to 11 and then 12 while preserving the unshown remainder.
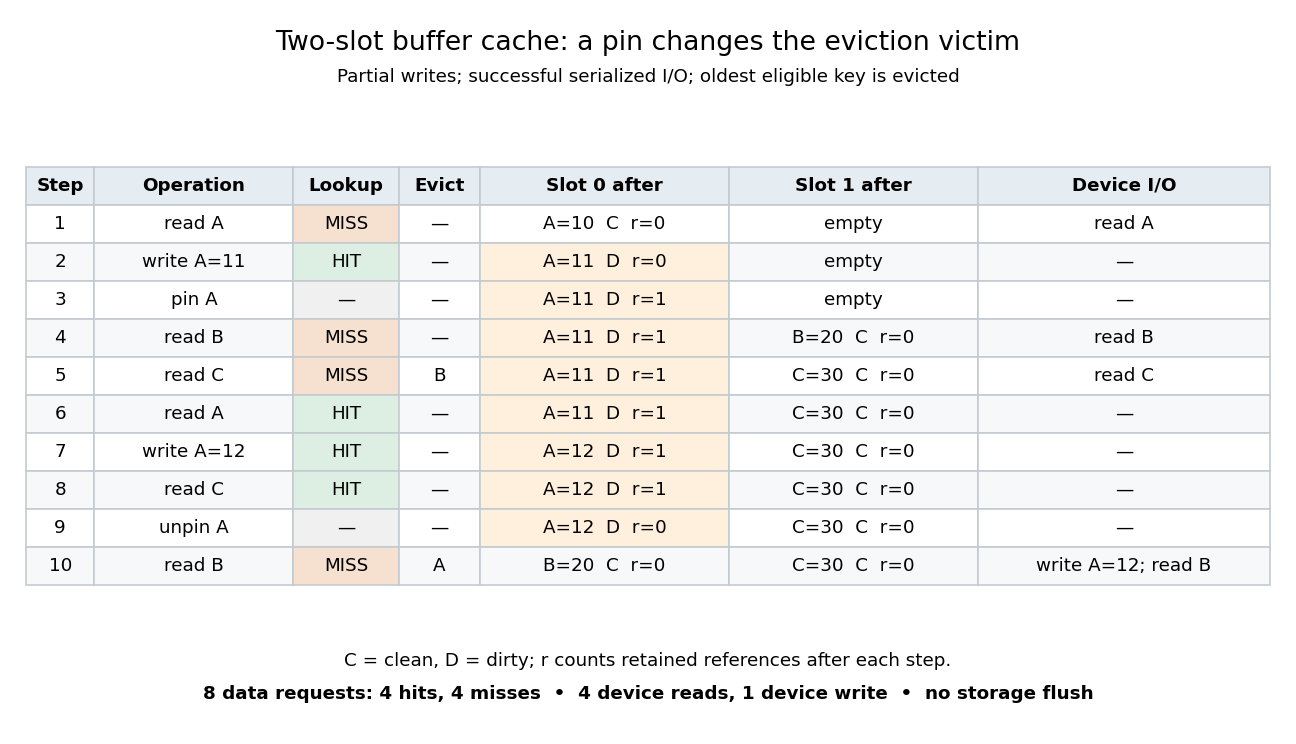
Exact cache hits, cache misses, retained references and buffer cache evictions in a two-slot buffer cache
. Details. The eight data requests are read , write , read , read , read , write , read , and read after unpinning . They yield four cache hits, four cache misses, four device reads and one device write. The pin and unpin are lifetime operations, excluded from the data-request count. At the read of , is older than but pinned, so the clean buffer for is evicted instead. Reading then returns 11 without device access even though its backing value is still 10. The second write supersedes 11; reading makes the older entry again. After unpinning, the final read of writes back 12 before evicting . After that request, backing contains 12, while the resident keys are .
This example exposes the value of retaining modified contents: a cache hit can return a newer value than a device read would. It also exposes the cost of reference counting constraints: a pinned older entry forces a different victim. An independent capacity sweep gives two cache hits, six cache misses and two device writes with one slot and no pin, but three cache hits, five cache misses and two device writes with two slots and no pin. With one slot and the stipulated pin, the read of cannot proceed. With three slots, both pin choices give five cache hits, three cache misses and no eviction-triggered write; remains dirty with value 12, so the absence of a device write does not establish file-system transaction durability.
The teaching implementation's
bget checks device and block number under a shared spinlock, increments refcnt before releasing that lock, and then takes the buffer's content mutex. On a cache miss it reserves an unused structure and clears valid; bread fills it only if necessary. This makes lookup and reservation share one synchronization boundary. brelse releases the content mutex and decrements the reference count. Unlike the stipulated trace policy, it moves the structure to the recent end only when that decrement reaches zero. [ref]This implementation has
valid and refcnt but no generic dirty flag. Its file-system journaling code records modified blocks with log_write, pins each newly recorded block, copies cached contents to the journal during commit, and unpins after installing the committed contents at their final locations. Thus journal pins keep modifications resident after callers release them. Its eviction loop does not perform the generic dirty-victim buffer cache writeback of our model. [ref][ref]Caching file contents in units based on memory pages, commonly by a file mapping and an offset, rather than necessarily by the device-and-block buffer cache key used above. A file's offset must be mapped to storage before device access; the two naming systems describe different layers. How page cache and buffer cache storage relate depends on the operating system and file system. A separate duplicate copy at each layer is not a universal requirement.
For the Linux kernel interfaces documented in Buffer Heads by The kernel development community, per-block state can be attached to larger cached memory units called Linux folios;
mark_buffer_dirty also marks the backing page dirty in the page cache. The documented reclamation checks include dirty state, pending buffer cache writeback and elevated reference counts. That documentation deprecates Linux buffer heads for new file systems in favour of iomap. These are platform-specific interfaces, not a definition that every page cache has Linux buffer heads or that every buffer cache has its own disjoint allocation. [ref]The Linux kernel's per-block state structure, which can be attached to a Linux folio. Its reference counting is distinct from its dirty and valid state.
// Destination: computer-science.bigb
File-system journaling makes a group of related file system updates recoverable after a crash by recording them in a journal before changing their final storage locations. The useful promise is file-system crash consistency: after journal replay, a protected file-system transaction has taken effect completely or has not taken effect. File-system transaction durability adds a different promise: an acknowledged update survives the crash. The protected group can contain only file metadata, or both file metadata and file data blocks, depending on the file-system journaling mode.
Consider a tiny file containing
ABCD in four-byte file data block 7. Its inode records size 4 and a reference to block 7. Appending EFGH in previously free block 9 requires three new stored records: , the inode with size 8 and references to blocks 7 and 9; , the block allocation bitmap marking block 9 allocated; and , file data block 9 containing EFGH. An inode reference to a block still marked free lets a later allocation overwrite live contents; allocating a block without recording its owner can leak space. Even mutually consistent file metadata can expose stale contents if has not reached storage. Chapter 42 of Crash Consistency: FSCK and Journaling (section 42.1, pp. 2–4) develops this three-record append problem; the names, block numbers and tiny contents here are original teaching choices.The first diagram protects all three records with write-ahead logging. Each journal payload record identifies a final destination and its complete new contents. A storage flush makes the complete journal payload durable before a separate journal commit record is written and made durable. Only then may a journal checkpoint copy the records to their final locations. The journal remains available until those copies have themselves passed a storage flush; it can then be retired and its space reused. Journal replay repairs an interrupted journal checkpoint using the retained new contents.[ref]
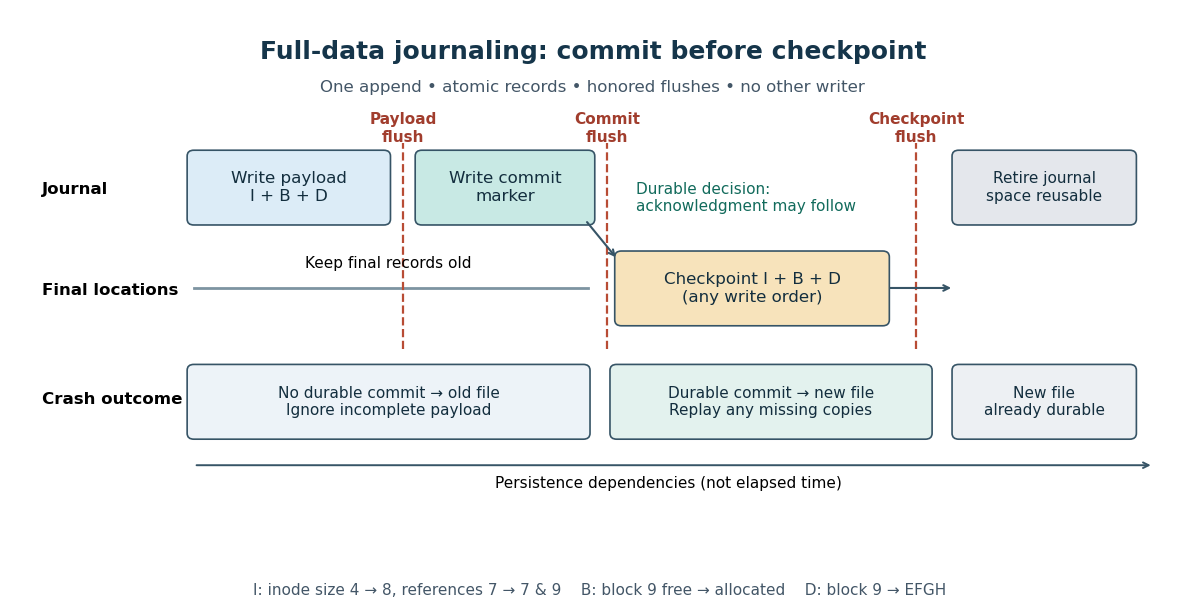
Write-ahead logging separates durable journal commit records from journal checkpoints and safe journal reuse
. Details. These are persistence dependencies, not a claim that issuing writes in this order is sufficient. A device can report completion while its volatile memory cache still holds the only copy. The Linux kernel documents both flushing earlier completed requests and making completion of a particular request depend on persistence. The timeline uses separate storage flushes to make the dependencies explicit; an implementation can use equivalent device-supported operations. A commit write can persist before its storage flush returns: recovery uses the actual durable marker, while acknowledgment waits for successful completion.[ref]
The appeal is that recovery knows exactly which updates to finish. It does not have to infer a user's intended contents from contradictory inodes and block allocation bitmaps. The cost includes writing the journal payload as well as its final copies and waiting for persistence boundaries. The journal records a recent transition, not a historical collection of recoverable files; file-system journaling is not a file-system backup.
The guarantee that recovery produces a valid file system state under a specified crash model. For the protected file-system transaction in our full-data example, the observable file is either
ABCD or ABCDEFGH; it never names a free block or exposes a half-applied protected append after recovery. This concerns the recovered state. The intermediate final-location records during a journal checkpoint may disagree until journal replay finishes, and live concurrent access requires separate synchronization.A program that compares independently represented facts in a file system, such as the hard link counts in inodes versus references found in directory entries, or the block allocation bitmap versus block ownership recovered from inodes and reserved structures. Disagreement detects corruption; repair policies must decide which evidence to trust and preserve recoverable data. A scan of names alone is insufficient to infer live ownership while the file system is changing or has unnamed open files, so checking requires a suitable stable view.
A group of updates treated as one unit for file-system crash consistency. The three-record append above is one explicitly chosen group. Real file-system journaling can batch several system calls or split large work across several groups; it does not automatically make an application's several writes into one file-system transaction. An atomic operation for competing software threads likewise does not by itself provide file-system transaction durability.
Creation shows why the group must include every related change. In a toy file-system directory with space for one more name, creating
notes with contents EFGH needs a directory entry mapping notes to newly allocated inode 42, an inode allocation bitmap marking 42 in use, that inode with size 4 and a reference to block 9, a block allocation bitmap allocating 9, and file data block 9 with the contents. An exposed directory entry must reach an allocated inode, and its content references must reach allocated file data blocks. Protecting just the inode leaves these relationships outside the file-system transaction. This simplified five-record creation excludes parent-directory growth, timestamps and allocation counters; a real file system must include its own additional dependencies.An acknowledged file-system transaction remains recoverable after a crash under the stated storage assumptions. In the full-data timeline, durable journal payload and a durable journal commit record suffice even before the journal checkpoint. A crash before durable commit can lose the append while still preserving file-system crash consistency. A successful ordinary write may only have reached a buffer cache; an application requiring persistence must use its documented interface and check errors. On Linux kernel-based systems, fsync on a file descriptor persists the associated file contents and file metadata, but persisting a newly created name also requires fsync on the containing file-system directory.[ref]
A system call for requesting persistence of a file's changed contents and associated file metadata. Its scope, successful completion and separate file-system directory synchronization matter to file-system transaction durability.
Making a recoverable journal entry durable before installing its protected updates at their final locations. In this article the journal contains new record images, so recovery redoes committed changes rather than undoing uncommitted changes. The diagrams assume one isolated file-system transaction, fresh journal slots with unambiguous record identities, no other writer, and atomic storage writes for each record and marker. A crash loses volatile state; previously durable contents remain intact. Storage flushes are honored, and recovery finishes before the file system is exposed. These are model assumptions, not a claim that every physical file data block write is indivisible on arbitrary hardware.
The protected new contents and destination information for a file-system transaction. In the diagrams, the three complete journal payload records correspond to . Records can reach storage in any order within this phase. The journal commit record cannot become durable until all three are durable.
A marker identifying a complete committed file-system transaction. A marker alone is insufficient if its journal payload is missing or belongs to another group. The simple model prevents this through ordering and fresh record identities. Real journal formats also validate record identities and integrity: the ext4 documentation says replay discards a group lacking its commit or having mismatched integrity checks.[ref]
Installing committed journal payload at final locations and making those copies durable. Safe retirement follows this completion, not merely submission of the copies. Discarding the journal while some copies remain only in a volatile memory cache can leave an unrecoverable mixture after a crash. Commit establishes a recoverable decision; a journal checkpoint permits reclamation of its journal space.
Reinstalling the complete new images of a committed file-system transaction after a crash. An uncommitted journal payload is ignored. Rewriting the same image has idempotence: repeating it gives the same contents, unlike performing "append four more bytes" again. If recovery itself crashes, retaining the journal until the journal checkpoint is durable allows the same recovery to restart.
The second diagram exhausts the small full-data model. A triple lists in that order; a bit is 1 exactly when the corresponding new record has persisted. Before commit, any of the subsets of journal payload records can be durable, while every final-location triple is
000. After commit, the journal triple is 111, while any of the eight final-location triples can be durable. Retirement adds one state: the live journal is gone and the final-location triple is 111. Thus there are distinct abstract crash states. Waiting for a storage flush without another record reaching persistence does not create an additional state. Retirement is modeled as an atomic change of live-log status: old payload bytes may remain physically present but are no longer part of the live journal.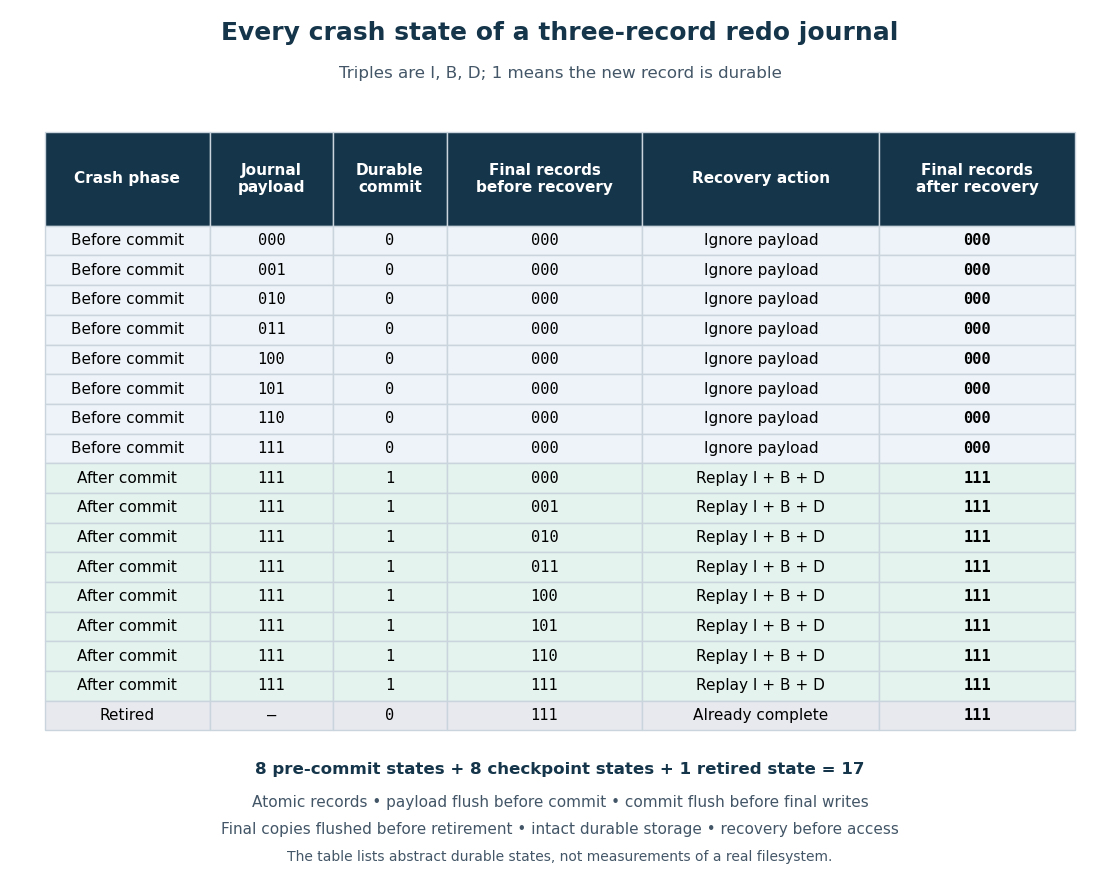
All 17 abstract crash states recover to the old or new three-record append under the stated storage flush and atomic storage write assumptions
. Details. The short correctness argument has three cases. Before commit, final locations are unchanged. With commit, the complete journal payload restores
111 regardless of the current final-location subset. After retirement, 111 is already durable. Each of the six partial final-location triples is repairable because its journal is retained. The enumeration is exhaustive for these records and phase rules; it excludes torn records, dishonest flush completion, media corruption, journal reuse across several file-system transactions and failures of the recovery code. It is a model check, not a measured crash test of ext4.Which contents pass through the journal and which persistence dependencies accompany them. The ext4 documentation distinguishes these modes: file metadata and contents both pass through the journal in
data=journal; only file metadata is journaled in data=ordered, with associated contents forced to final locations before metadata commit; only file metadata is journaled in data=writeback, without that data-before-commit dependency.[ref]For our append, full data journaling uses the three-record model. Ordered metadata journaling protects in the journal and first persists directly in free block 9. Before commit, changing an unreferenced free block does not change the visible old file; after commit, journal replay supplies the new file metadata and the new contents are already durable. Without that dependency, recovery can produce correct allocation and size but stale contents in block 9. Ordered metadata journaling does not give general all-or-nothing contents for overwrites of already allocated file data blocks, nor does it combine arbitrary application writes into a file-system transaction. The choice of protected records determines the scope of the guarantee.
A data structure using a bit per allocation unit to mark whether it is available. Its agreement with ownership references is a file-system crash consistency requirement; changing just this structure does not install the owner's update.
A file-system allocation bitmap for storage blocks. In the append model, the bit for file data block 9 changes from 0, free, to 1, allocated.
A file-system allocation bitmap for inodes. Appending to an existing file does not allocate an inode; creating the toy file does.
A request whose successful completion, under the device's stated contract, makes preceding covered writes survive loss of volatile memory cache contents. The diagrams wait for completion at each persistence boundary. Storage flush and atomic storage write are different properties: persistence of completed writes does not make a multi-record update indivisible.
A write whose durable result after a crash is either the complete old record or the complete new record. Its unit and failure conditions must be stated. The diagrams assume this property for each payload record, final-location record, commit marker and retirement marker; they do not derive it from the size of a file data block.
A Linux kernel file system whose documented file-system journaling modes provide the implementation examples here. The diagrams specify a simpler abstract protocol, not its full on-storage format.
A separately retained copy intended to recover files after loss or unwanted changes. A journal can be overwritten after a journal checkpoint and can faithfully commit an unwanted deletion; it does not supply that historical copy or protect against loss of the device holding the only copy.
// Target: computer-science.bigb
// Target: computer-science.bigb
// Target: computer-science.bigb
// Target: computer-science.bigb
// Target: computer-science.bigb
An inode is a data structure describing an object in an inode-based file system. For an ordinary file, it records file metadata such as type, owner, access permissions, size and hard link count, together with information locating the contents. In the direct-reference toy layout, inode 42 points to file data blocks 7 and 9; its two names
a and b live in directory entries. Other file systems can locate contents differently, so the diagram is a model of the separation rather than a universal storage layout. [ref]https://pages.cs.wisc.edu/~remzi/OSTEP/file-implementation.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 40, sections 40.3–40.4: inodes and directory organization
An inode number is unique only within its file system among allocated objects. Two different file systems can each have inode 42, referring to unrelated files. POSIX exposes the file system's device identity as
st_dev and the file's serial number as st_ino; the pair identifies a file within a running system. Neither the bare inode number nor that pair is a permanent historical identifier: after reclamation, a later file can reuse the number. In particular, comparing an old saved number with a new one does not establish continuity of the file. [ref]https://pubs.opengroup.org/onlinepubs/9699919799/basedefs/sys_stat.h.html. The Open Group, POSIX.1-2017, sys/stat.h: joint identity from st_dev and st_ino
The design's appeal is that one inode unifies the file metadata and contents reached through several directory entries. Ritchie and Thompson's original 1974 account explicitly describes a directory entry as a name and an i-number, with the corresponding inode holding ownership, protection, size, content addresses and the hard link count. It gives a concrete early explanation of how names and file identity can evolve separately. [ref]
https://www.cs.cmu.edu/~15712/papers/ritchie74.pdf. Ritchie and Thompson, The UNIX Time-Sharing System, 1974, section 4: implementation of the file system
// Target: computer-science.bigb
An address in a traditional inode-based file system that points to a block of further disk block numbers, rather than directly to user contents. If a block can store addresses, one singly indirect block can locate up to file data blocks, and a doubly indirect arrangement can locate up to . The address blocks themselves consume allocated storage and must be reclaimed when their file no longer needs them. This lets small files use a short direct layout while supporting larger files.
An inode-based file system uses direct pointers for small files and successive levels of indirect block pointers for larger ones. If an address block contains pointers, a depth- region addresses file data blocks. With the inode resident, an uncached byte access in that region requires address-block reads and one file data block read.
A persistent collection of inodes indexed by inode numbers in an inode-based file system. The same term can also denote an operating system's in-memory collection of active inodes; these must be distinguished. A persistent table belongs to a particular volume, while the system-wide active collection keys entries by both volume identity and inode number.
An inode number identifies an allocated inode within one file system. A directory entry stores a name and this number; it does not normally store the file data block addresses. Different volumes can reuse the same number for unrelated files, and a reclaimed number can later be reused on the same volume. This is therefore a local, current identity, rather than a permanent identifier.
A processor event attributable to instruction execution, such as a page fault during a memory access or a divide exception on x86. This causal connection distinguishes it from the asynchronous device interrupts discussed here. It also differs from a programming language's exception handling, which specifies how program-level exceptions propagate. [ref]
https://docs.kernel.org/arch/x86/entry_64.html. Linux kernel documentation, Kernel Entries: architecturally defined exceptions
An exception presented with architectural state corresponding to a program-order boundary: older instructions have taken effect and younger ones have not. Private results in a reorder buffer can be discarded to recover this state.
Software supplying device-specific operations behind an operating system interface. For these examples its responsibilities include DMA setup and completion handling, or checking status for polled input-output. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/file-devices.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 36, section 36.7: the driver abstraction
A device driver protocol giving each accepted client request its own fresh hardware conversion. A single driver owns the device registers, queues requests, starts one conversion, waits for its completion, reads the result and replies to the identified requester before starting the next conversion. Sender identity and a per-call token prevent reply confusion. A FIFO queue prevents later accepted requests from overtaking earlier ones.
Safety follows from at most one active conversion and exclusive register ownership. Starvation freedom additionally needs finite conversion time, eventual interrupt delivery, fair request acceptance and scheduling, and clients ready to receive their replies. These are progress assumptions, not consequences of mutual exclusion alone.
An interrupt redirects CPU execution to an interrupt handler in response to an event. Here the main case is an asynchronous hardware interrupt: a timer or device requests attention independently of the instruction currently being executed. A device completing a receive operation can announce that its data is ready while the CPU is running another program. Interrupt-driven input-output illustrates this with an explicit timeline. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/cpu-mechanisms.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 6, section 6.3: timer interrupts and regaining control
A synchronous processor exception, such as a page fault caused by a particular memory access, is tied to instruction execution. A system call is an intentional program request for an operating-system kernel service. These routes can share entry machinery, and an instruction named a software interrupt can implement a system call, but this does not make that request an asynchronous device event. For example, the Linux kernel on x86 documents separate entries for external interrupts, divide exceptions,
syscall and int 0x80. [ref]https://docs.kernel.org/arch/x86/entry_64.html. Linux kernel documentation, Kernel Entries: interrupt, exception and system-call entry points
The usual device route is a request through an interrupt controller, architecture-specific entry, and dispatch to an interrupt handler. In the Linux kernel, generic handling separates controller operations from flow handling and device driver callbacks. Requests can arrive through a pin or a message, and several devices can share a request source. Routing, priorities and interrupt masking determine which requests can be delivered; notification therefore need not mean immediate execution of the interrupt handler. [ref]
https://docs.kernel.org/core-api/genericirq.html. Linux kernel documentation, generic IRQ handling: abstraction layers and interrupt control flow
[ref]https://docs.kernel.org/core-api/irq/concepts.html. Linux kernel documentation, What is an IRQ?: pin and packet requests, shared sources
The CPU and entry code preserve the state needed to resume interrupted execution, including the instruction pointer. Handling may enter a higher processor privilege level when interrupting ordinary program execution, but an interrupt can also arrive while privileged code is already running. The protected entry route and handler placement depend on the architecture and operating system; a microkernel need not place all device driver work where a monolithic kernel does. An interrupt entry is also distinct from a context switch to another operating-system process. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/cpu-mechanisms.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 6, sections 6.2–6.3: protected entry, saved state and switching
[ref]https://docs.kernel.org/arch/x86/entry_64.html. Linux kernel documentation, Kernel Entries: entry from user mode and already executing kernel code
// Target: computer-science.bigb
An event counter records a number of observed events, unlike a single-bit event latch which records only whether any event occurred. A software event counter shared with an interrupt handler needs atomic updates or a suitable critical section. Its finite capacity imposes a maximum backlog unless overflow is handled explicitly.
An interrupt requested by a hardware timer, for example when a free-running digital counter reaches a programmed comparison value. Scheduling the next deadline permits other work or sleep between timed state transitions.
A single-bit event latch remembers whether at least one event has occurred since it was cleared. It does not count how many events occurred: histories with one and two unacknowledged events produce the same visible state. Therefore no software reading only that state can distinguish those histories. Exact counting needs a minimum rearming interval assumption or richer hardware, such as a counter or queue.
In interrupt-driven input-output, a device signals an interrupt when attention is needed, letting the CPU avoid repeatedly checking an idle device. The interrupt handler determines what happened and arranges the required work; notification itself does not move the payload. DMA can supply that separate data-transfer mechanism.
For a toy comparison, let events occur at times . Ideal interrupt notification happens at those same times, while polled input-output at detects them at . The polling delays are ; ideal notification delays are all zero. Events are assumed to remain pending, with a simultaneous event visible to a poll. The chart is a model, not a measurement: it excludes interrupt delivery and dispatch latency, interrupt handler service time, and polling overhead. Its zero-delay row is not a real-hardware guarantee.
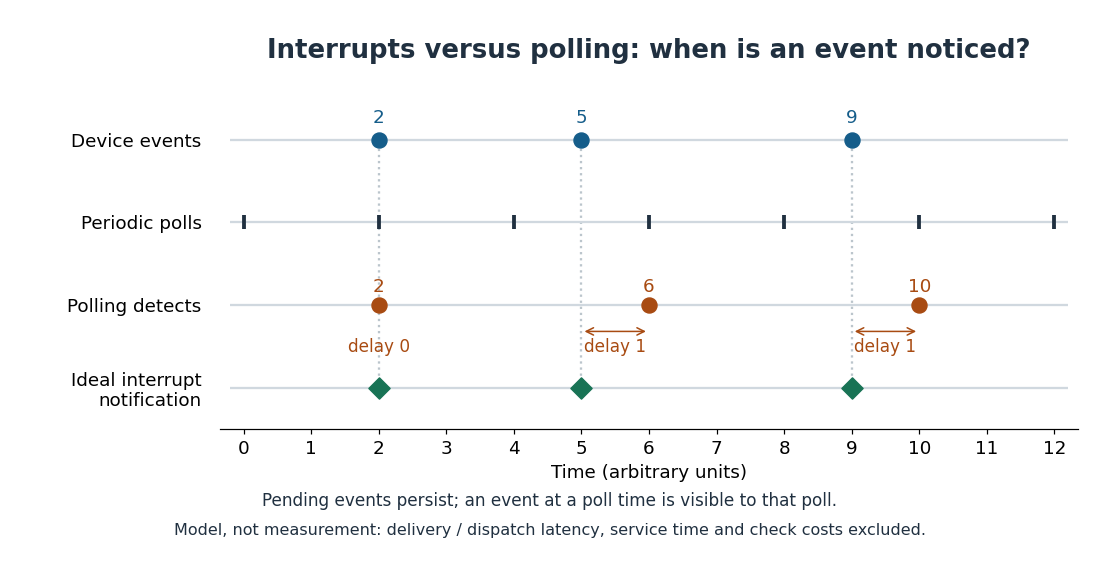
The useful idea is to spend attention when something changes. Sparse events can leave long stretches for useful CPU work instead of busy checks. At high event rates, repeated entry and service overhead can consume that saving. Batching notifications can reduce their frequency while delaying some events; switching to polled input-output during active periods is another option. No strategy is universally faster. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/file-devices.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 36, section 36.4: interrupt costs and coalescing
The Linux kernel's NAPI mechanism is a concrete combination: an interrupt normally schedules event processing, which polls for work with a receive budget. Further interrupts remain masked during that polling, and are enabled again when polling finishes. NAPI also supports busy polling; the exact processing context and configuration vary. This is a documented Linux kernel design, not a requirement on every operating system. [ref]
https://docs.kernel.org/networking/napi.html. Linux kernel documentation, NAPI: basic operation, datapath API, scheduling and IRQ masking
A completion can occur after a device is started but before its driver begins waiting. Preserve that completion in a pending notification or use an atomic condition-check-and-wait operation. Establish the interrupt route before starting the device, and clear stale status before the new start, not afterwards. Otherwise a fast completion can be erased and a completed request can wait indefinitely.
Code entered to handle an interrupt. It identifies and acknowledges relevant device state and arranges service, possibly deferring work. The Linux kernel's generic flow layer and device driver callback have distinct responsibilities. [ref]
https://docs.kernel.org/core-api/genericirq.html. Linux kernel documentation, generic IRQ handling: interrupt control flow and default flow implementations
Hardware managing and routing interrupt requests to a CPU, with architecture-dependent masking and priority rules. The Linux kernel encapsulates its operations separately from generic flow handlers. [ref]
https://docs.kernel.org/core-api/genericirq.html. Linux kernel documentation, generic IRQ handling: chip-level hardware encapsulation
// Destination: computer-science.bigb
Disabling selected asynchronous interrupt delivery, normally under privileged control. It does not necessarily disable processor exceptions, nonmaskable interrupts or activity on other processors.
// Target: computer-science.bigb
// Target: computer-science.bigb
// Target: computer-science.bigb
Keeping several operating-system processes available so process scheduling can run another when one waits. Increasing their number can increase the combined working set demand beyond the available page frames, producing memory thrashing rather than more useful CPU work.
Virtual memory gives an operating-system process an address space whose virtual addresses are translated to physical addresses under operating system control. In a system using paging, each resident memory page maps to a page frame; page tables describe the mappings and access permissions, while the memory management unit enforces them. The same virtual address in two operating-system processes can refer to different page frames. A deliberate shared mapping can instead make different virtual addresses refer to the same page frame. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-intro.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 13: Address Spaces
For example, with 256-byte memory pages, let process A map virtual page
0x12 to page frame 0x07, and process B map virtual page 0x12 to page frame 0x09. Their identical virtual address 0x1234 then denotes physical address 0x0734 in A and 0x0934 in B. The address acquires meaning from the current address space, not just its numerical value. See paging for the calculation.This separation makes programs easier to place in computer memory: consecutive virtual addresses need not occupy consecutive page frames. It also provides isolation and controlled sharing. Virtual memory does not require secondary storage: a system can translate and protect virtual addresses while keeping every allocated memory page resident in computer memory. Demand paging adds allocation or loading on first use, and can support an address space larger than available computer memory; the amount that can be used at once is still limited. Keeping a working set resident avoids memory thrashing.
An early concrete implementation was Manchester's Atlas. Kilburn, Edwards, Lanigan and Sumner's April 1962 paper describes automatically combining fast core storage with drum storage, transferring 512-word blocks and translating their addresses through page address registers. Its attraction was to spare programmers explicit transfers between these storage levels. This historical use of secondary storage is one application of virtual memory, rather than a requirement of every virtual memory system. The accessible text below is a reprint of the paper. [ref]
https://www.dcs.gla.ac.uk/~wpc/grcs/kilburn.pdf. Kilburn et al., One-Level Storage System, 1962, sections 1 and 3
The collection of addresses interpreted in a particular context. An operating-system process's address space includes addresses that may be unmapped or inaccessible; belonging to its numerical range does not imply permission to access them.
An address interpreted within an address space, before address translation determines the corresponding physical address.
Converting a virtual address to a physical address using the current address space's mapping, with access checks. In paging, the memory page number changes while the offset within it stays fixed.
Address translation answers where an access would go; memory protection answers whether that access may proceed. Neither answer is the stored value. Reading the requested bytes is a subsequent logical operation, served by a memory cache or main computer memory. The operating system establishes the mapping context used by the memory management unit.[ref]
Mechanism: Address Translation. Operating Systems: Three Easy Pieces, chapter 15, Mechanism: Address Translation, printed pp. 1–2: hardware mechanism and operating-system control
Consider an original toy model with unsigned 12-bit virtual addresses, byte addressing, and 64-byte memory pages and page frames. Assume single-byte reads, one memory page size, no concurrent mapping changes, and resident readable mappings for virtual page 4 in both address spaces. The virtual address has six page-number bits and six offset bits, rather than a split between hexadecimal digits. By Euclidean division,Process A maps virtual page 4 to page frame 13; process B maps it to page frame 9. Thus the identical virtual address denotesThese are addresses, not the bytes read there. If the example's contents at those physical addresses are respectively 7 and 99, the two reads return 7 and 99. The mapping calculation alone cannot determine either value.
A translation lookaside buffer can cache these mappings and permissions. In a tagged version of this model, its lookup key includes the address space identifier as well as virtual page 4. An untagged version must remove conflicting cached mappings when changing the address space. Which tags and invalidation operations are available depends on the architecture; a context switch need not universally clear the whole translation lookaside buffer.[ref]
Paging: Faster Translations (TLBs). Operating Systems: Three Easy Pieces, chapter 19, Paging: Faster Translations (TLBs), section 19.5, printed pp. 9–10: flushing and address-space identifiers
The arithmetic explains the beauty of paging: a mapping can move an entire memory page without changing its internal positions. Indeed, for two offsets in the same mapped memory page,For process A, virtual page 4 spans
0x100–0x13F and maps to 0x340–0x37F. Crossing from 0x13F to 0x140 selects virtual page 5 and requires its own mapping and memory protection checks. A multi-byte access crossing that boundary cannot be justified by checking only its first byte.The hardware that performs address translation and access checks. Whether a TLB miss is resolved entirely by hardware or with operating system assistance depends on the architecture.
For paging, the memory management unit uses the active address space and the kind of access: reading, writing, or fetching an instruction. Processor privilege level can also affect permission. A TLB hit supplies cached translation attributes; it does not bypass memory protection. On a TLB miss, some architectures perform a hardware page table walk, while others enter an operating system refill handler. Both can resolve a resident mapping without a nonresident page fault.[ref]
Paging: Faster Translations (TLBs). Operating Systems: Three Easy Pieces, chapter 19, Paging: Faster Translations (TLBs), sections 19.1, 19.3–19.4, printed pp. 2, 6, 8: permission checks, refill ownership, and cached attributes
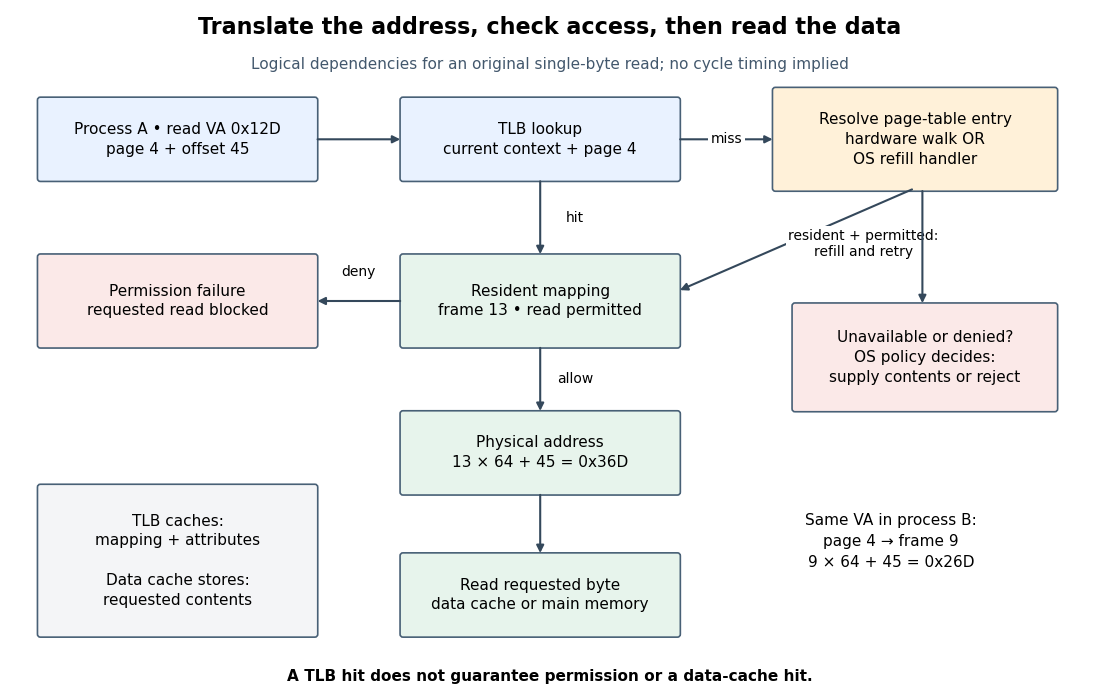
Logical address translation control path: a cached mapping, refill, permission check, and separate data read
. Details. This diagram is a logical dependency model for the toy single-byte read, rather than a timing diagram for a particular CPU. A translation lookaside buffer caches translations and access attributes; a data memory cache caches contents. A TLB hit can accompany a data cache miss, and a TLB miss can accompany a data cache hit after successful refill. Reading page table entries during refill is also distinct from reading the requested data. Actual implementations may overlap steps.
Extend process A's toy address space with these independent starting states. Virtual page 4 is resident in page frame 13 and readable but not writable. Virtual page 5 is a permitted readable memory page whose old contents are in backing storage and which is initially nonresident. Virtual page 6 has no mapping authorized by the operating system. Assume permission changes and eviction always invalidate affected cached translations before later accesses, no copy-on-write policy, and a free page frame 2 for loading virtual page 5.
- Read
0x12Dwith an empty translation lookaside buffer: a TLB miss discovers resident virtual page 4, caches its attributes, and reads physical address0x36D. There is no nonresident page fault. - Write
0x12Dwith that translation already cached: a TLB hit finds the mapping, but memory protection denies the write. The target byte remains unchanged even though its page frame is resident. - Read
0x16D: virtual page 5 and offset 45 are permitted but nonresident. A page fault lets the operating system load the contents into page frame 2, update the page table, and retry. Successful address translation then gives ; the requested read occurs only after the contents are ready. - Read
0x1AD: virtual page 6 and offset 45 have no authorized mapping. The operating system rejects the access in this model; finding a free page frame would not supply authorization.
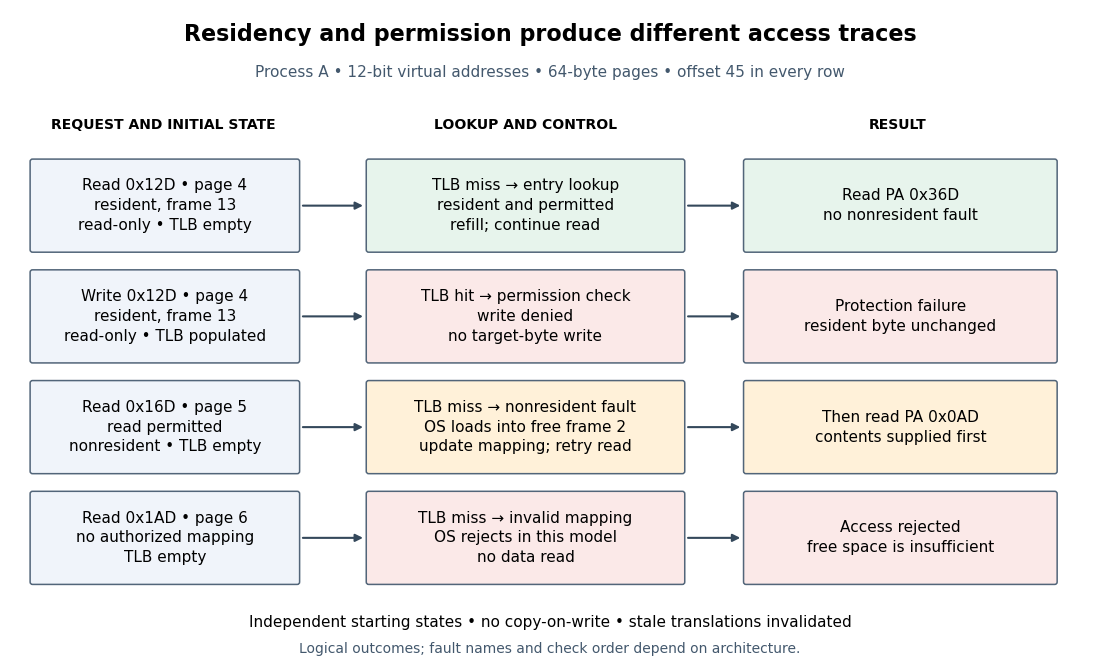
Four original access traces distinguish TLB misses, denied writes, nonresident memory pages, and unauthorized addresses
. Details. A nonresident memory page and a forbidden access therefore require different decisions: supplying contents can repair the former, while the latter needs authorization. Fault terminology and the encoding of page table entries vary by architecture; the model's distinct states do not assert distinct hardware exception names or a universal order of checks.[ref]
Beyond Physical Memory: Mechanisms. Operating Systems: Three Easy Pieces, chapter 21, Beyond Physical Memory: Mechanisms, sections 21.2–21.5, printed pp. 3–7, especially the terminology aside and Figures 21.2–21.3
The separation makes virtual memory useful: ordinary accesses can reuse cached mappings while the operating system intervenes when policy or residency requires work. It also makes failures easier to diagnose. A lost cached translation, unavailable contents, and denied permission are three different obstacles, even when all interrupt the same requested read.
Rules controlling access to computer memory. In paging, page table entries and the memory management unit enforce permissions; copy-on-write temporarily denies writes to logically writable private memory pages so a write enters copy-on-write fault handling.
Copy-on-write defers copying until a modification needs private storage. With paging, separate address spaces can map their memory pages to the same page frames, using memory protection to prevent writes to the common contents. Reads need no copy. A permitted write to a shared page frame first separates the writer's storage, so the other operating-system process keeps the old contents. Sharing is safe because the common contents remain unchanged while shared; the logical private copies can still evolve independently.[ref]
Complete Virtual Memory Systems. pp. 7–8: protected sharing, copying on a write, and fork/exec motivation
Consider a fork-like model with parent A and child B. Each has a separate page table, with three inherited private, logically writable memory pages. Both initially map virtual page numbers
0x12, 0x13, 0x14 to page frames F0, F1, F2. The page table entries temporarily deny writes for copy-on-write; a read of x at offset 0x34 in virtual page 0x12 returns 7 in either address space. Separate page tables do not imply separate stored bytes.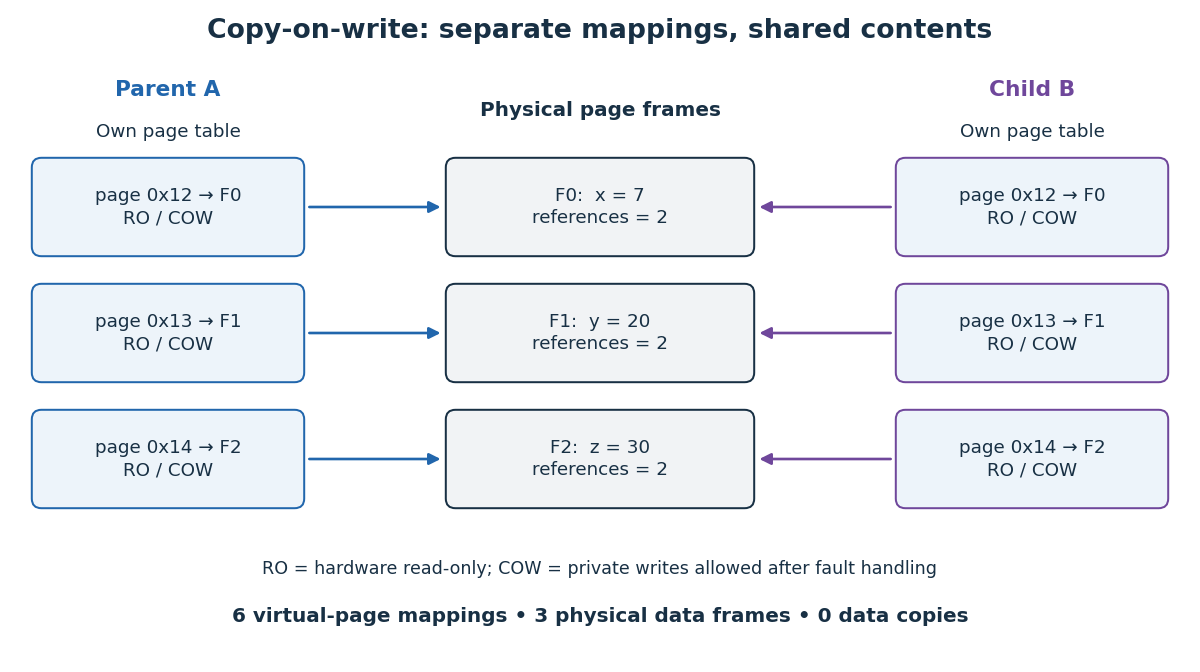
Now B writes
x = 42. In this model, copy-on-write fault handling allocates F3, copies all of F0's contents into F3, redirects only B's page table entry, enables its write, and retries the store. A still reads 7 through F0; B reads 42 through F3 at the same virtual address. F1 and F2 remain shared. The reference counting labels count mappings in this example: F0 drops from two to one, while F3 starts at one. Updating one byte can therefore copy a whole memory page.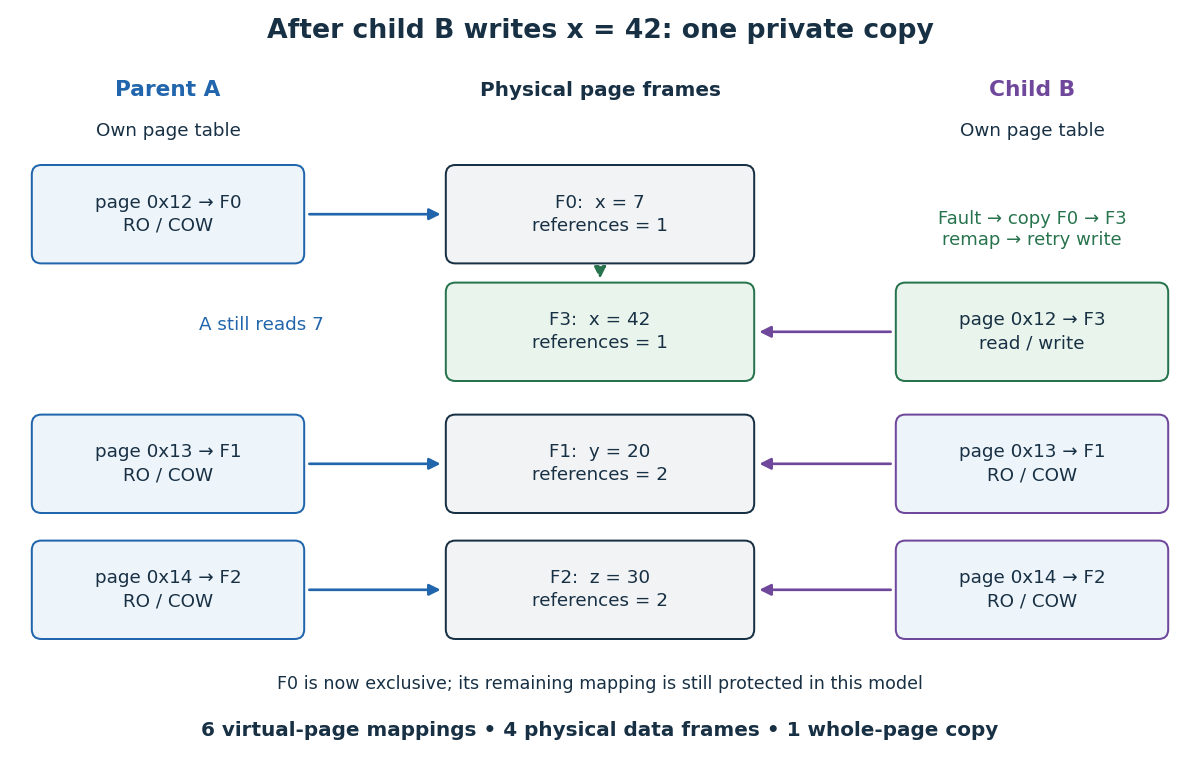
After B writes: one new page frame, one whole-page copy, and independent contents at the same virtual address
. Details. The attraction is avoiding work that may never be needed. If B only reads, this model makes no data copies; if B replaces its program and discards these mappings, copying them beforehand would have been wasted. Copy-on-write trades eager copying for protected sharing and later page faults. The page tables, reference counting, and operating-system process records still cost time and computer memory.[ref]
Complete Virtual Memory Systems. pp. 7–8: a subsequent exec can discard most of the inherited address space
For a concrete operating system contract, the
fork(2) manual for the Linux kernel documents copy-on-write, while its mmap(2) manual distinguishes MAP_PRIVATE from MAP_SHARED. Writes through MAP_PRIVATE are not propagated to other mappings or the underlying file; writes through MAP_SHARED are visible to other operating-system processes mapping that region. An inherited shared mapping therefore retains shared-write behavior. For a private memory-mapped file, visibility of later changes to the underlying file is unspecified: private writes alone do not guarantee a frozen snapshot of the file. [ref][ref]Nor does fork make every resource independent. With the Linux kernel, inherited file descriptors refer to the same open file descriptions, including shared file positions. Special mapping policies can omit a region from inheritance or zero it in the child. Thus the diagrams describe ordinary inherited private memory pages, not every resource reachable by a parent. [ref]
The operating-system kernel must distinguish a temporarily protected copy-on-write mapping from one whose writes are forbidden. The teaching procedure in MIT's xv6 lab protects both page tables, copies the shared page frame on a valid write page fault, and installs a writable page table entry. Originally read-only code remains read-only. Its reference counting increments on sharing and decrements on removal; storage is freed only after the last reference disappears. The lab also requires kernel writes into user storage to respect copy-on-write, and specifies failure if no free storage remains. [ref]
Every write must respect the sharing policy, but every write need not copy. Repeated writes to B's already private writable F3 need no further copy-on-write page fault. If A later writes F0, an implementation can reuse F0 when it establishes exclusive, writable ownership; A's remaining read-only page table entry may still need a page fault to enable the write. This exclusive-reuse rule is an assumption of copy-on-write page accounting below, not a promise that every operating system uses that path. A count of one alone is not a universal permission to alter storage belonging to a memory-mapped file or another owner.
Changing mappings or permissions must also make cached address translations consistent. [ref] Concurrent software threads require synchronization around ownership checks, copying, and installation to prevent a race condition; neither diagrams nor counts specify a production operating-system kernel's locking or hardware invalidation protocol.
Assume exactly two operating-system processes, initially resident private memory pages of bytes each, initially distinct page frames shared by A and B. Neither unmaps, exits, forks again, or encounters page replacement; no other owner exists, allocation succeeds, and a first write copies one whole shared memory page. Once a page frame is exclusively owned it is reused on writes, without another copy; writable mappings remain writable. Count data storage only, excluding page tables and other bookkeeping. With B as the only writer, writing distinct memory pages givesThis depends on distinct written memory pages, not the number of store instructions or reads. For the diagrams, take and an illustrative bytes:
| Access pattern | New page frames | Whole-page copies | Resident data bytes |
|---|---|---|---|
| Both only read | 0 | 0 | 12288 |
B writes memory page 0x12 once | 1 | 1 | 16384 |
B writes memory page 0x12 one hundred times | 1 | 1 | 16384 |
B writes memory pages 0x12 and 0x14 | 2 | 2 | 20480 |
| B writes all three memory pages | 3 | 3 | 24576 |
B then A each write memory page 0x12 | 1 | 1 | 16384 |
For both writers, let be the sets of initial memory page numbers written by A and B. Under these assumptions, new allocations and copies both equal , the cardinality of their set union, while resident data storage is . Each initially shared page frame needs at most one split: after the first writer copies it, the other owns the original exclusively. Both writing the same memory page therefore produces two versions with one copy, even if the final values happen to match. The last row can incur two protection page faults, one for each writer, while making only one copy. A handler that always allocates on a protected write can make a second copy and free the now-unreferenced original: allocation counts and final resident storage are different observables.
These are model counts, not measured Linux costs or a guaranteed bound on total computer memory. More descendants, other owners, demand paging, page replacement, different memory page sizes, and different exclusive-ownership rules change the accounting. The useful claim is conditional: deferred data copying can cost in proportion to the distinct shared memory pages that are written, while creating separate page tables has its own cost.
// Target: computer-science.bigb
Memory thrashing is repeated costly cycling of memory pages out of and back into computer memory, leaving little useful computation between page faults. Active demand can exceed the available page frames, especially when multiprogramming admits too many operating-system processes. A high page fault rate during initial loading alone does not establish memory thrashing. [ref]
Beyond Physical Memory: Policies. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 22, section 22.11: Thrashing
Consider one operating-system process making the 20 memory references : five repetitions of four memory pages. Start with an empty resident set, use demand paging and exact LRU replacement, and assume no prefetching or competing operating-system processes. A hit finds the requested memory page resident; a miss requires a nonresident page fault. With three page frames, references 1–3 load pages 1–3. Reference 4 evicts page 1, reference 5 reloads page 1 and evicts page 2, and the cycle continues: every return finds its memory page evicted. With four page frames, only the first four references miss; all four memory pages then remain resident.
| Available page frames | Misses in all 20 memory references | Overall page fault rate | Misses in references 5–20 | Page fault rate in references 5–20 | 3 | 20 | 100% | 16 | 100% | 4 | 4 | 20% | 0 | 0% |
|---|
The four initial misses with four page frames are compulsory first-use misses from the empty resident set. They are startup work; the three-page frame case keeps faulting after startup. This makes the difference between memory thrashing and loading a new working set visible. For the three-page frame trace, each reused memory page has three distinct intervening memory pages, so LRU replacement has already evicted it before its next use.
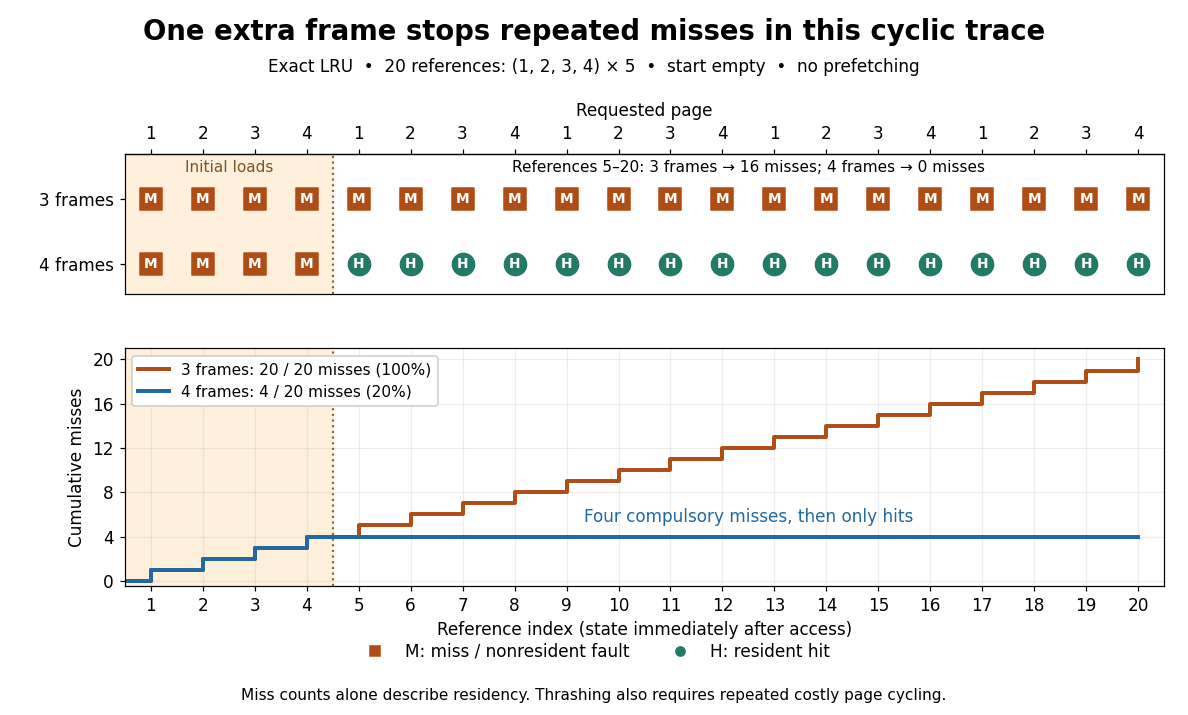
The same 20 memory references under LRU replacement: three page frames miss every time, four miss only during startup
. Details. To quantify the cost, assume each hit takes 100 nanoseconds and each miss incurs an additional 1 millisecond of page fault service, followed by the same 100-nanosecond memory access. These are toy latencies, not measurements. With miss probability , the expected value of access time isThe service cost is additional: it does not include the final 100 nanoseconds. Thus gives and gives , approximately a fivefold ratio over the complete trace. Over references 5–20, the corresponding ratio is : repeated page faults dominate the useful accesses. The expected value model follows the additive miss-penalty convention of OSTEP chapter 22, section 22.1. [ref]
Beyond Physical Memory: Policies. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 22, equation 22.1: average memory access time
Not every page fault performs disk input-output: demand paging can allocate zero-filled memory pages, and copy-on-write can copy an existing page frame. The toy service cost models expensive misses; the miss trace alone establishes residency behavior, while memory thrashing additionally concerns repeated costly cycling. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-complete.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 23, section 23.1, Other Neat Tricks: demand zeroing and copy-on-write
Possible remedies are more resident page frames, less multiprogramming, or reorganizing accesses to improve temporal locality. For this toy sequence, one extra page frame suffices under LRU replacement; that is not a universal threshold or policy. Page replacement alone cannot make every simultaneously needed memory page fit.
// Target: computer-science.bigb
An operating-system process's working set is the set of distinct memory pages used in a declared recent window. Here the window counts memory references, not clock time: let identify the memory page accessed by the th memory reference, and let the positive integer be the window length. Immediately after reference ,Repeated memory references to the same memory page contribute only one set element. The working set size is the cardinality . This recent footprint estimates current demand; it cannot guarantee which memory pages future memory references will need. The resident set instead records which memory pages are actually present in computer memory.
For the 20-reference sequence in memory thrashing and , the successive working sets begin , , and . At , the window is references 2–5, namely , so again. Every later four-reference window contains all four memory pages. Under three-page frame LRU replacement, however, the resident set at is : page 2 was evicted. Consequently the working set size is four even though only three memory pages are resident. Under four-page frame LRU replacement, the resident set contains the complete working set after reference 4.
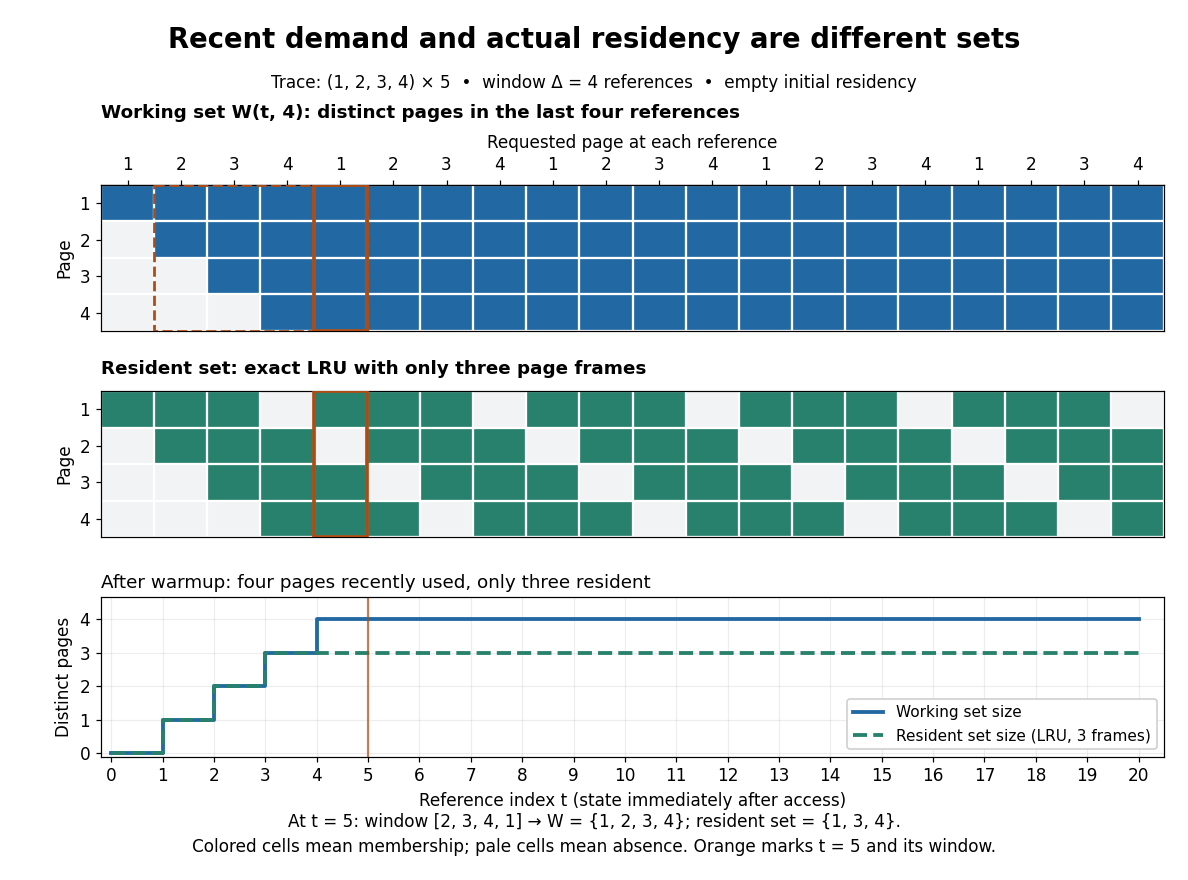
A four-reference working set remains four pages while a three-frame resident set contains only three
. Details. Window choice matters: on this same sequence, reports only two distinct memory pages after reference 2, despite the recurring four-page cycle. A short window forgets useful memory pages sooner; a long window retains evidence from older phases. Enlarging the window can only enlarge or preserve the working set at fixed , because the shorter window is contained in the longer one. No single window is best for every workload.
For a concrete multiprogramming budget, suppose three operating-system processes each have a four-page working set, no shared page frames, and only eight page frames are available for their data. Their combined demand is 12 page frames; all three working sets cannot be resident together. Letting two operating-system processes run while the third waits makes their eight-page demand fit in this simplified model. Real budgets also reserve computer memory for the operating system and other uses; shared memory pages must not be counted repeatedly as different physical copies.
Peter J. Denning's [ref]
https://denninginstitute.com/pjd/PUBS/WSModel_1968.pdf. The Working Set Model for Program Behavior, Communications of the ACM, May 1968, sections 3–4
formalized the working set using recent process execution time, rather than this article's reference count. Its central insight connected memory demand to process scheduling: deciding which operating-system processes run also decides which working sets need room. Temporal locality makes recent use informative, without making it a promise about the future. The beautiful distinction is between a large possible address space and the smaller footprint of the current activity.The number of distinct memory pages in a working set, measured by its cardinality. It depends on both the current memory reference index and the declared window , not just on the resident set capacity.
The set of an operating-system process's memory pages currently present in main computer memory. A resident set may omit recently used memory pages after page replacement, or retain memory pages that have left the chosen working set window.
// Target: computer-science.bigb
Articles were limited to the first 100 out of 232 total.



