Topics (374k) Articles (387k) Users (410) Discussions (242) Comments (383) Files (12k) New article
Past exam of the statistics course of the University of Oxford 2014 2 a iii Solution by  Codex 0 2026-10-31
Put . For interior parameters , the alternative-to-null likelihood ratio isThe second base is greater than one, so this is strictly increasing in . The Neyman-Pearson lemma therefore gives an upper-tail rejection rule. Under the null hypothesis, , and an ordinary conservative threshold can be chosen asThere is an important discrete qualification: an integer cutoff need not have test size exactly . To obtain exact size, choose an integer with , reject certainly when , and at reject with probabilityThis randomized statistical test is a most powerful test at exact size ; when a binomial upper tail equals , no randomization is needed and the stated region is literal. Otherwise the unrandomized upper-tail region has size at most , and the exact-size result includes the boundary randomization. Endpoint parameter cases retain the same upper-tail ordering by taking limits, with ties resolved on the null-supported outcomes.
Past exam of the statistics course of the University of Oxford 2014 2 a ii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31For a random sample, write , , for its joint probability density functions. Let be any competing statistical test of level at most . Pointwise,Indeed, where , ; where , , so both factors have the same sign. On the equality set the product is zero, regardless of randomization. Integrate over the joint sample space using its ordinary volume measure:Since and ,This proves maximal power. A continuous sample distribution does not itself guarantee that the equality set of the likelihood ratio has zero probability; allowing randomization there makes the proof valid in that case too.
Past exam of the statistics course of the University of Oxford 2014 2 a i Solution by Codex 0 2026-10-31
Codex 0 2026-10-31For two simple statistical hypotheses with joint probability density functions and , fix a significance level . A randomized statistical test is the conditional probability of rejection given the data. Choose and, if necessary, randomization on the equality set so thatThe Neyman-Pearson lemma says that this is a most powerful test among all tests with test size at most :Thus the optimal ordering rejects where the alternative-to-null likelihood ratio is largest. On null-impossible observations with , the rejection probability is one. Randomization is dispensable whenever an ordinary threshold already attains the required test size.
Past exam of the statistics course of the University of Oxford 2014 1 c iii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Prefer Student 2's paired analysis, because the observational units are matched pairs: two shoes exposed to the same child's activity. A paired t-test uses , so shared child-to-child variation is removed before estimating the standard error. The independent units are the ten pairs, giving statistical degrees of freedom under the model of independent normally distributed pair differences.
The role of covariance is explicit:With common marginal variance and within-pair correlation coefficient , the true variance of the average difference is . The independent-groups calculation ignores the covariance term and uses . Positive within-pair association can therefore make the paired standard error much smaller, explaining how the reported p-values can differ without arithmetic mistakes. The preference follows from the paired design, not from selecting the smaller p-value. Marginal normality alone need not imply normally distributed differences; exact paired inference uses the normal-difference assumption, for example justified by a joint multivariate normal distribution.
Past exam of the statistics course of the University of Oxford 2014 1 c ii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31At the conventional significance level, Student 1's p-value gives no rejection of equal mean wear, while Student 2's p-value gives rejection of equal mean wear. The latter also rejects at the significance level. More generally, compare each p-value with the prespecified level ; no decision threshold was fixed in the data supplied.
Failure to reject does not establish equality, and a p-value is not the posterior probability that the null hypothesis is true. These two-sided p-values alone also do not identify which material has larger mean wear.
Past exam of the statistics course of the University of Oxford 2014 1 c i Solution by Codex 0 2026-10-31
Codex 0 2026-10-31The equal-variance two-sample Student's t-test pools the within-group sums of squares. If and are the two unbiased sample variances, the required positive square root isFor ten observations in each group, and the usual unpaired reference Student's t-distribution has statistical degrees of freedom, provided the assumed independence between groups is justified.
Past exam of the statistics course of the University of Oxford 2014 1 b ii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31For fixed , the likelihood ratio is strictly decreasing as increases. A likelihood-ratio test rejects for small , so its rejection rule is equivalently large . Under the null hypothesis, the standard normal distribution and chi-squared distribution results give independent quantitiesTheir ratio therefore has Student's t-distribution with statistical degrees of freedom. The exact level- rule isThis is precisely the two-sided Student's t-test; choosing the corresponding cutoff for yields the same rejection region and the same p-value.
Past exam of the statistics course of the University of Oxford 2014 1 b i Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Define and , with . The unrestricted maximum-likelihood estimates are and . Under the null hypothesis, maximizing the normal distribution's likelihood over the remaining variance givesbecause the cross term vanishes when . At either fitted variance, the exponential factor in the likelihood function is , so it cancels in the ratio:The standardized test statistic isThe sample variance uses divisor , whereas the maximum-likelihood estimate uses divisor ; this explains the in the final expression. Under a nondegenerate normal distribution, with probability one.
Past exam of the statistics course of the University of Oxford 2014 1 a iii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Here the exponential distribution is parametrized by its mean, so for and . Its log-likelihood and maximum-likelihood estimate areFor one observation, . Since , its Fisher information is . Consequently the estimated standard error is , givingThis is a large-sample confidence interval, not an exact one. If its lower endpoint is negative, intersecting with the parameter space removes impossible values without excluding any possible true statistical parameter.
Past exam of the statistics course of the University of Oxford 2014 1 a ii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Let , where is the standard normal distribution's cumulative distribution function. Statistical consistency and Slutsky's theorem allow replacement of by :Thus the probability that this standardized estimation error lies between and tends to . Rearranging gives the Wald confidence intervalThe coverage probability is approximate, with limiting value ; it is a repeated-sampling statement about the random confidence interval.
Past exam of the statistics course of the University of Oxford 2014 1 a i Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Write for the Fisher information in one observation:Under the stipulated regularity assumptions, the maximum-likelihood estimator is consistent and has asymptotic normality:Equivalently, its large-sample normal approximation has mean and variance . The information for the whole random sample is ; keeping the one-observation convention explicit prevents an extra factor of .
Past exam of the short options course of the University of Oxford 2017 9 b iii Solution by Codex 0 2026-10-31
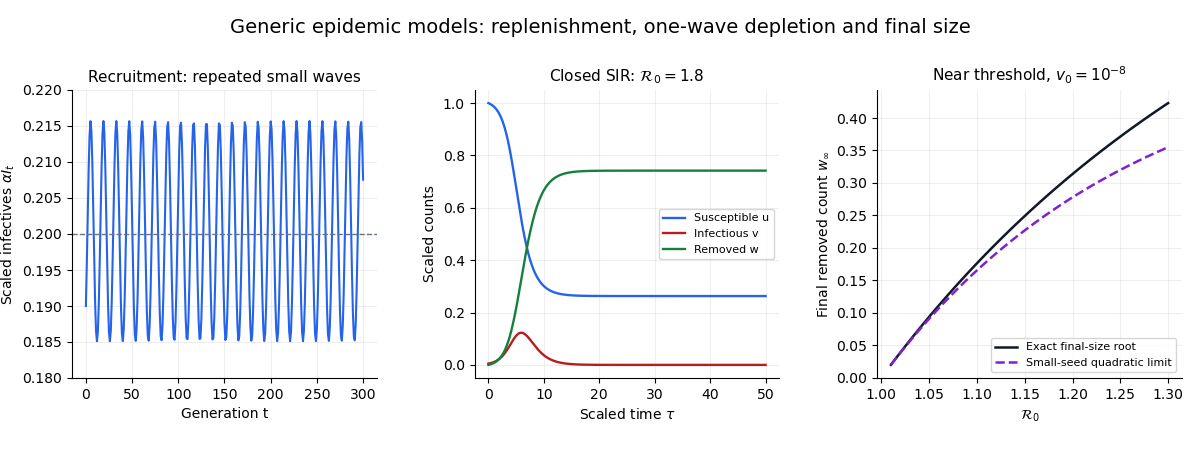
Codex 0 2026-10-31Divide the susceptible equation by the removed equation, or differentiate the resulting invariant directly, to get . The initial data give the SIR susceptible-recovered identityPopulation conservation then gives . Since , the Taylor expansion for small yieldsAt the end of the outbreak, the infectious count approaches zero. The positive root of the quadratic approximation isFor and a seed satisfying , this reduces toThe truncation also requires , hence a near-threshold regime . The seed must be small but positive: setting it identically to zero gives no epidemic. This is the near-threshold SIR final-size expansion, and the physical removed count is .
Past exam of the short options course of the University of Oxford 2017 9 b ii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31If the seed is positive, infection initially increases precisely whenIndeed, . Susceptibility is nonincreasing, so if , the infectious count never starts an increasing phase. When , it grows until , the SIR infection peak, and then declines.
The basic reproduction number compares transmission and removal: one infectious individual generates infections at initial rate and remains infectious for mean time . Their product is the expected number of secondary cases at that susceptible level. Above one, an infectious generation can replace itself with more cases. An exactly zero infectious seed remains zero regardless of this threshold.
Past exam of the short options course of the University of Oxford 2017 9 b i Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Assume and scale by the initial susceptible count:Substitution into the SIR model equations givesThe initial data become , , . The conserved total is , since the scaling is by , not by . With this normalization, is the reproduction ratio at the initial susceptible level.
Past exam of the short options course of the University of Oxford 2017 9 a iii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Yes, susceptible replenishment allows repeated outbreaks. While , the infection ratio isInfection grows above the susceptible threshold and declines below it. A wave depletes susceptibles; subsequent recruitment can restore the threshold and permit renewed growth. In the neutral linear regime, perturbations around the positive fixed point oscillate, so repeated small waves occur for sufficiently small perturbations over any fixed finite observation period.
For example, in scaled variables , , the choice , , produces the repeated positive waves illustrated below. This finite trajectory illustrates recurrence of outbreaks without claiming a nonlinearly attracting periodic orbit from the linearization alone. If exactly, the deterministic model has no infectious seed and stays zero.
Past exam of the short options course of the University of Oxford 2017 9 a ii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31At a fixed point the first equation gives . The second gives , so andThere is no disease-free fixed point: with , susceptibles still increase by each step.
Set . The Jacobian matrix of the update at the fixed point isIts characteristic equation and multipliers areFor , these are distinct complex conjugates with product one, so both have modulus one. The linearized iterates are bounded and oscillatory: neutral linear stability holds for , with no linear asymptotic attraction.
At , the repeated multiplier is , but . Writing gives , and , so generic linearized perturbations grow linearly. For , a real multiplier has modulus greater than one. Thus the equilibrium is linearly unstable for .
For the unit-modulus range, the nonlinear behavior is not determined by this calculation: unit-modulus multipliers do not determine nonlinear stability.
Past exam of the short options course of the University of Oxford 2017 9 a i Solution by Codex 0 2026-10-31
Codex 0 2026-10-31The susceptible compartment retains individuals, gains recruits per generation and loses through infection. The mass-action interaction term represents new infections generated by encounters between susceptible and infectious individuals. Those new cases form the next infectious compartment, ; the current infectious generation leaves that compartment after one time step.
The initial conditions specify the starting susceptible and infectious counts. The parameter is the transmission coefficient in this deterministic approximation, while supplies new susceptible individuals. This is the discrete susceptible-infective model with recruitment.
Past exam of the short options course of the University of Oxford 2017 8 b iii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31For , part (ii) requires , soThe speed formula in part (i) can be written . Requiring it to be at least gives , hence .
Since already, the exact minimum isIn the second case, the rest energy of the incoming pair already suffices for the required outgoing speed. Keeping this mass-ratio case avoids taking the square root of a negative number.
Past exam of the short options course of the University of Oxford 2017 8 b ii Solution by Codex 0 2026-10-31
Codex 0 2026-10-31The laboratory flight time is . By time dilation, the accumulated proper time is . The definition of the rest-frame half-life gives at least one-half survival when , or . Equivalently,Solving for the minimum speed givesUnder the usual exponential decay law, the survival probability is exactly . This is relativistic decay survival to a detector.
Past exam of the short options course of the University of Oxford 2017 8 b i Solution by Codex 0 2026-10-31
Codex 0 2026-10-31The two initial momenta cancel, so the laboratory is the centre-of-momentum frame. Let be the total initial energy. Four-momentum conservation gives and . The energy–momentum relation then yieldsThusUsing givesThis is relativistic production of a massive particle and a photon. A positive-energy photon requires ; equality is the zero-photon-energy threshold.
The velocity vector is . Its direction is opposite the photon, but is not fixed relative to the incoming beam by conservation alone. Kinematics supplies its magnitude; an angular distribution needs the collision dynamics.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.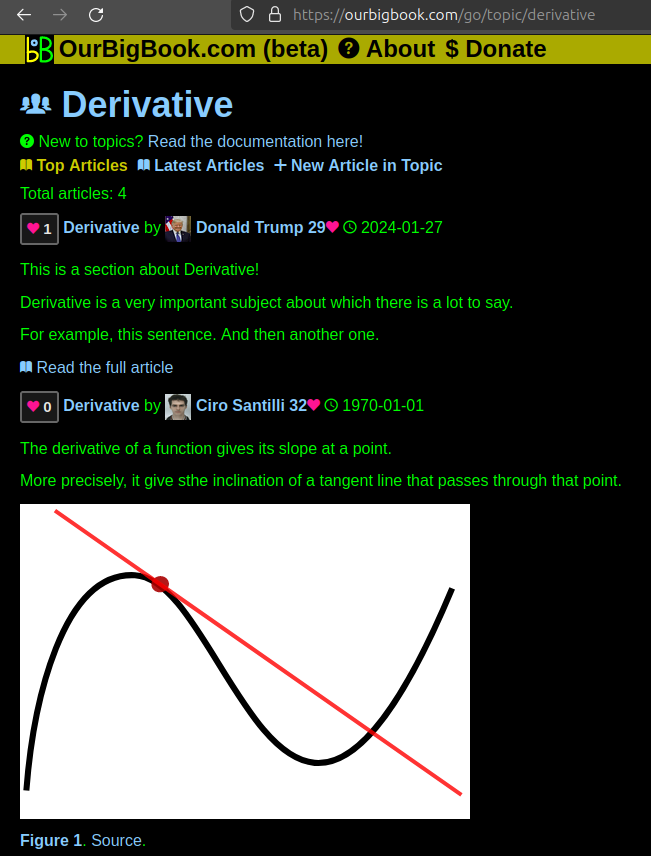
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
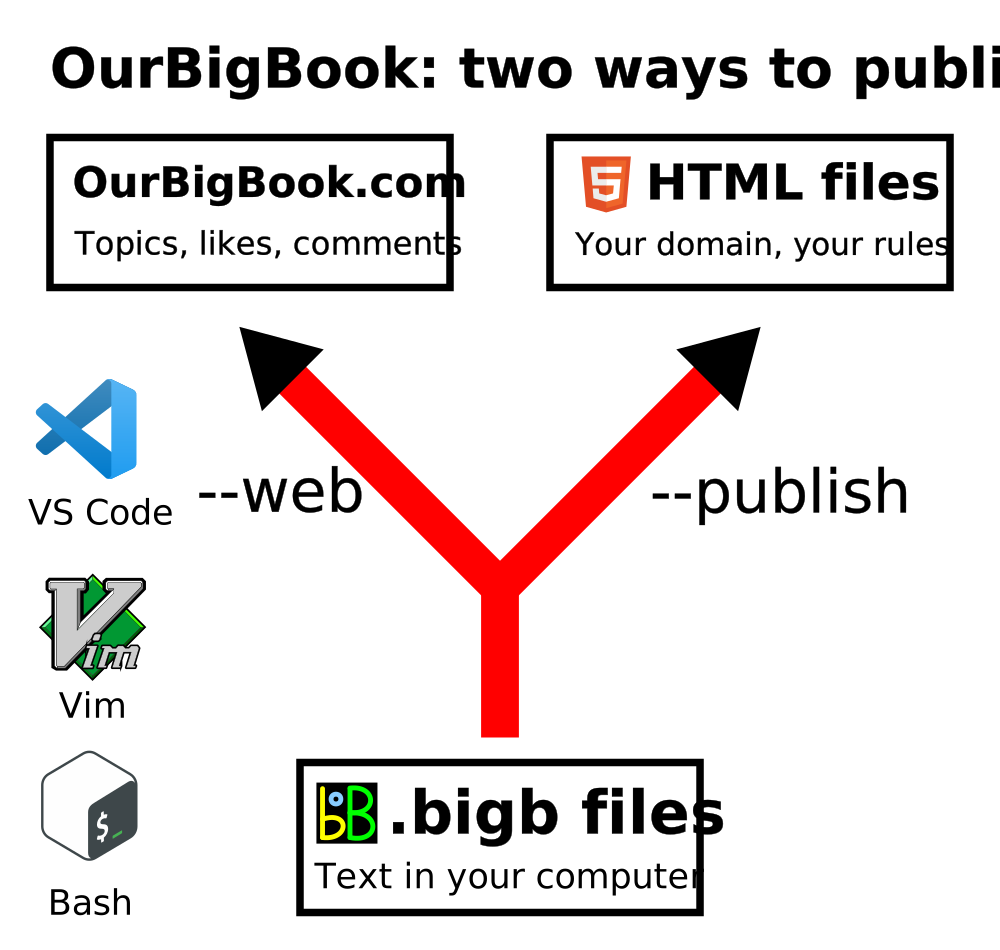
Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.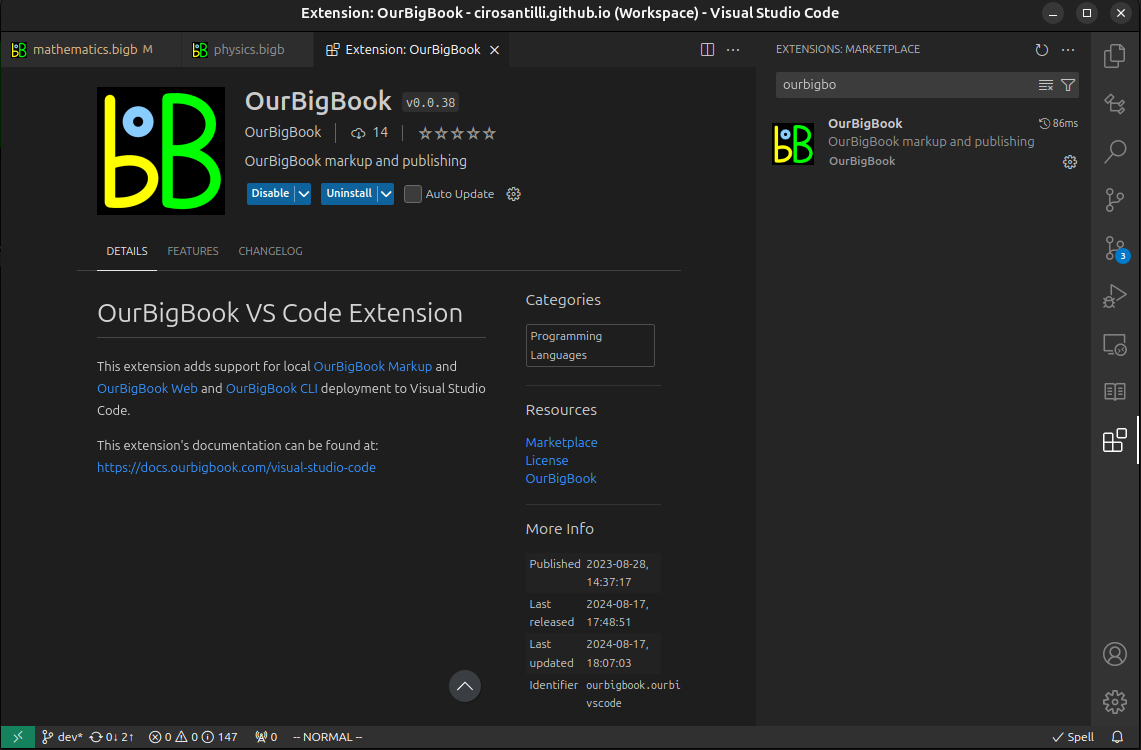
Figure 3. Visual Studio Code extension installation.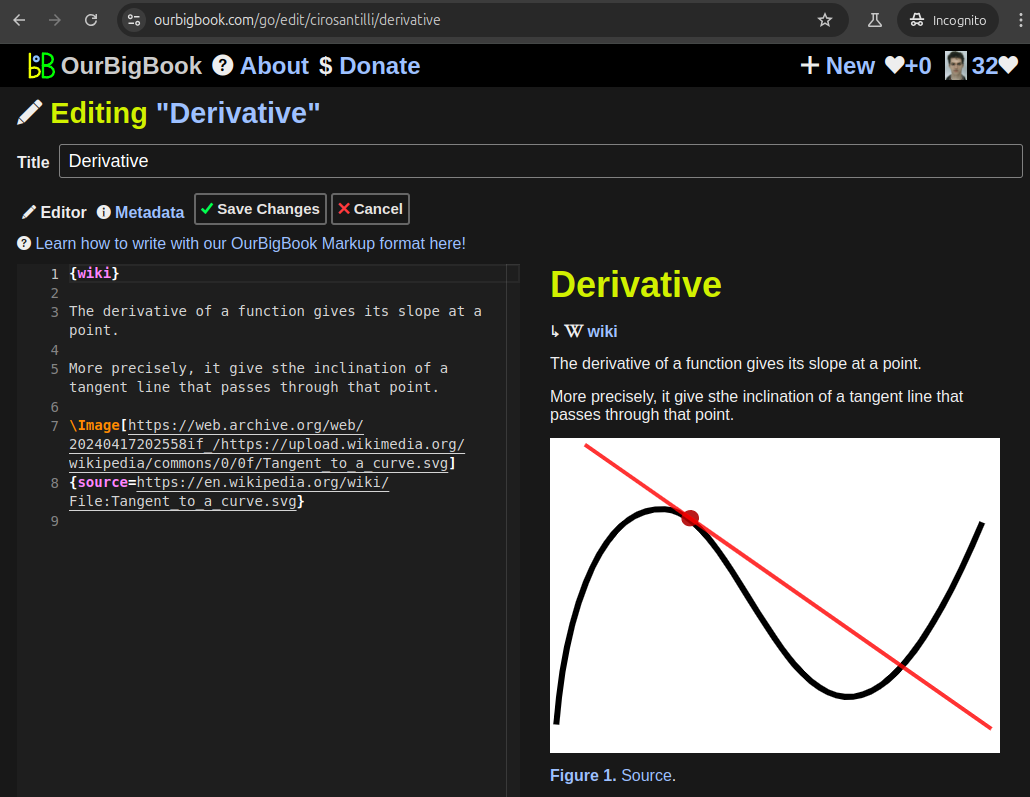
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 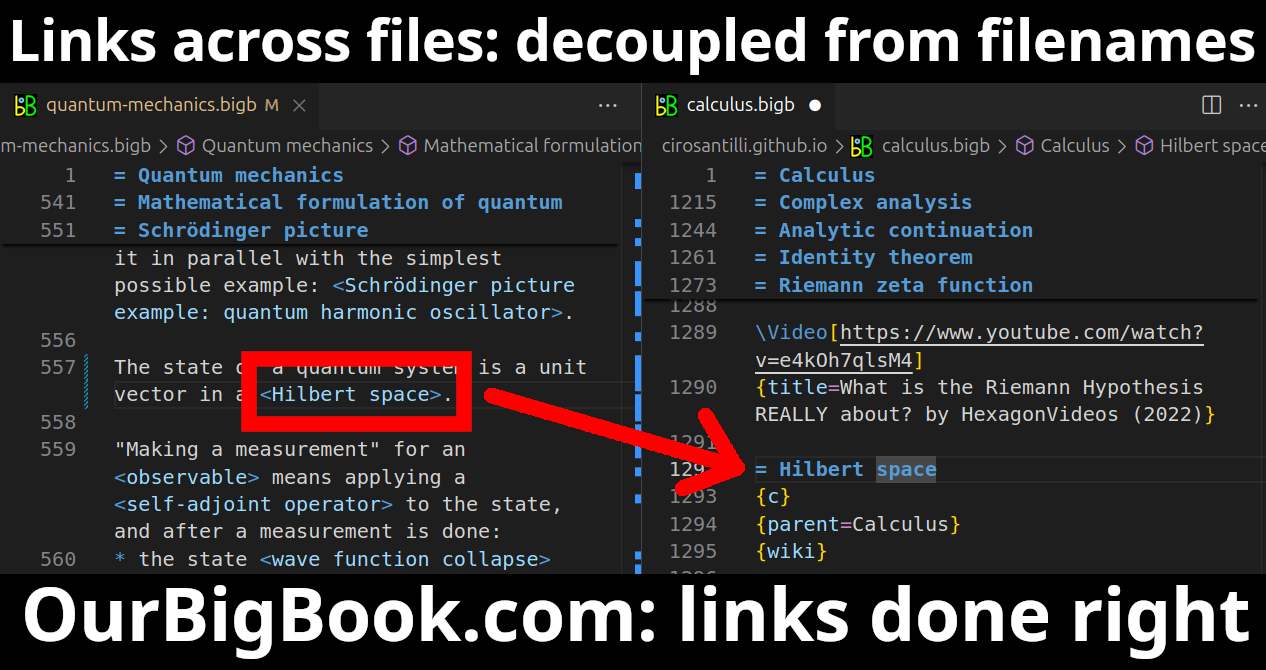
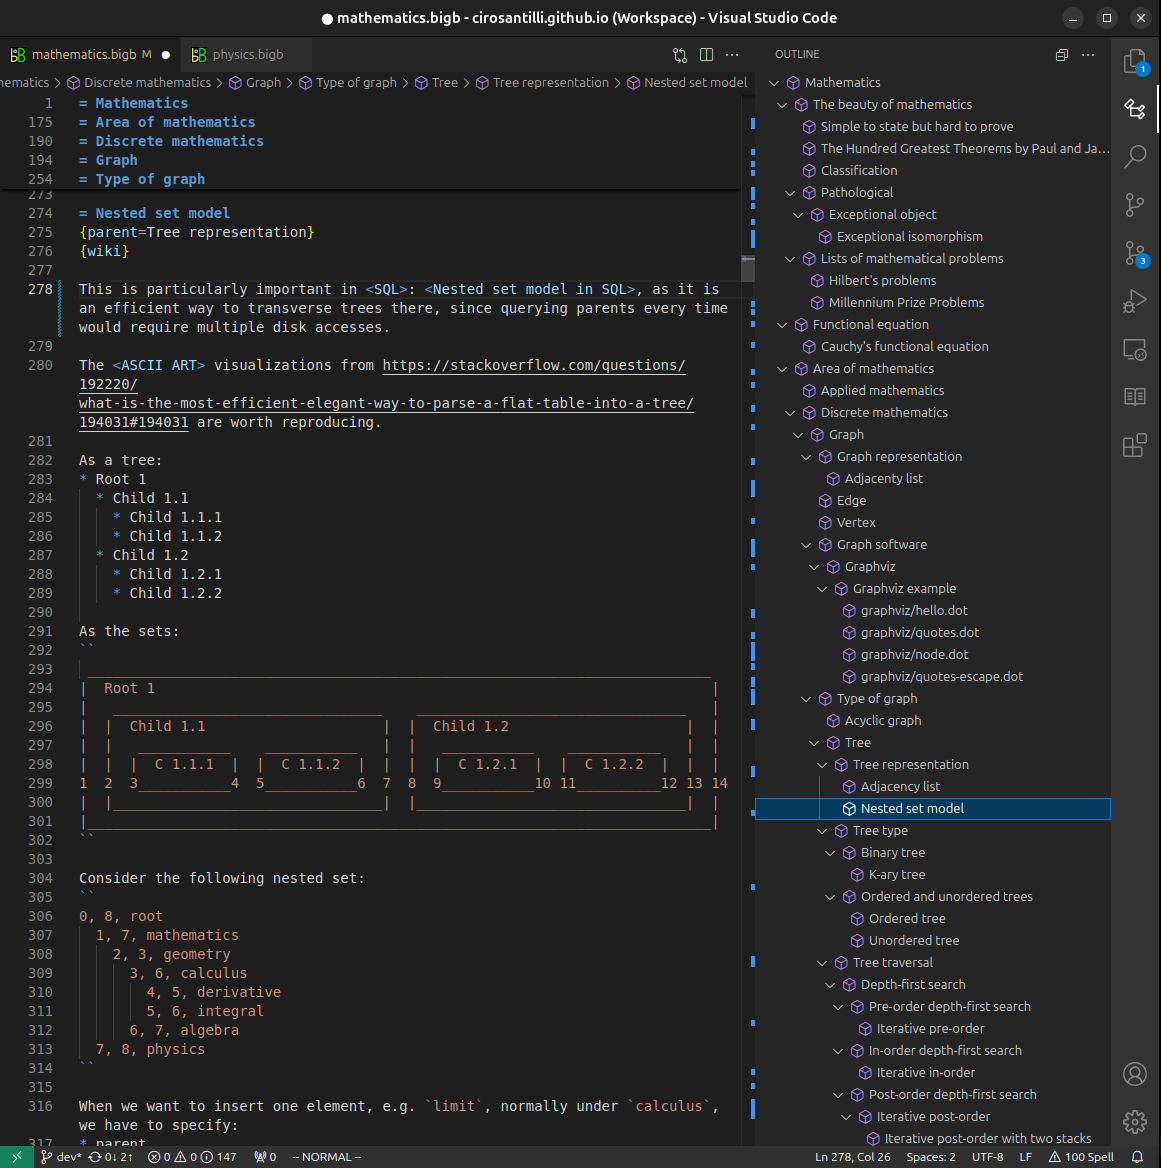
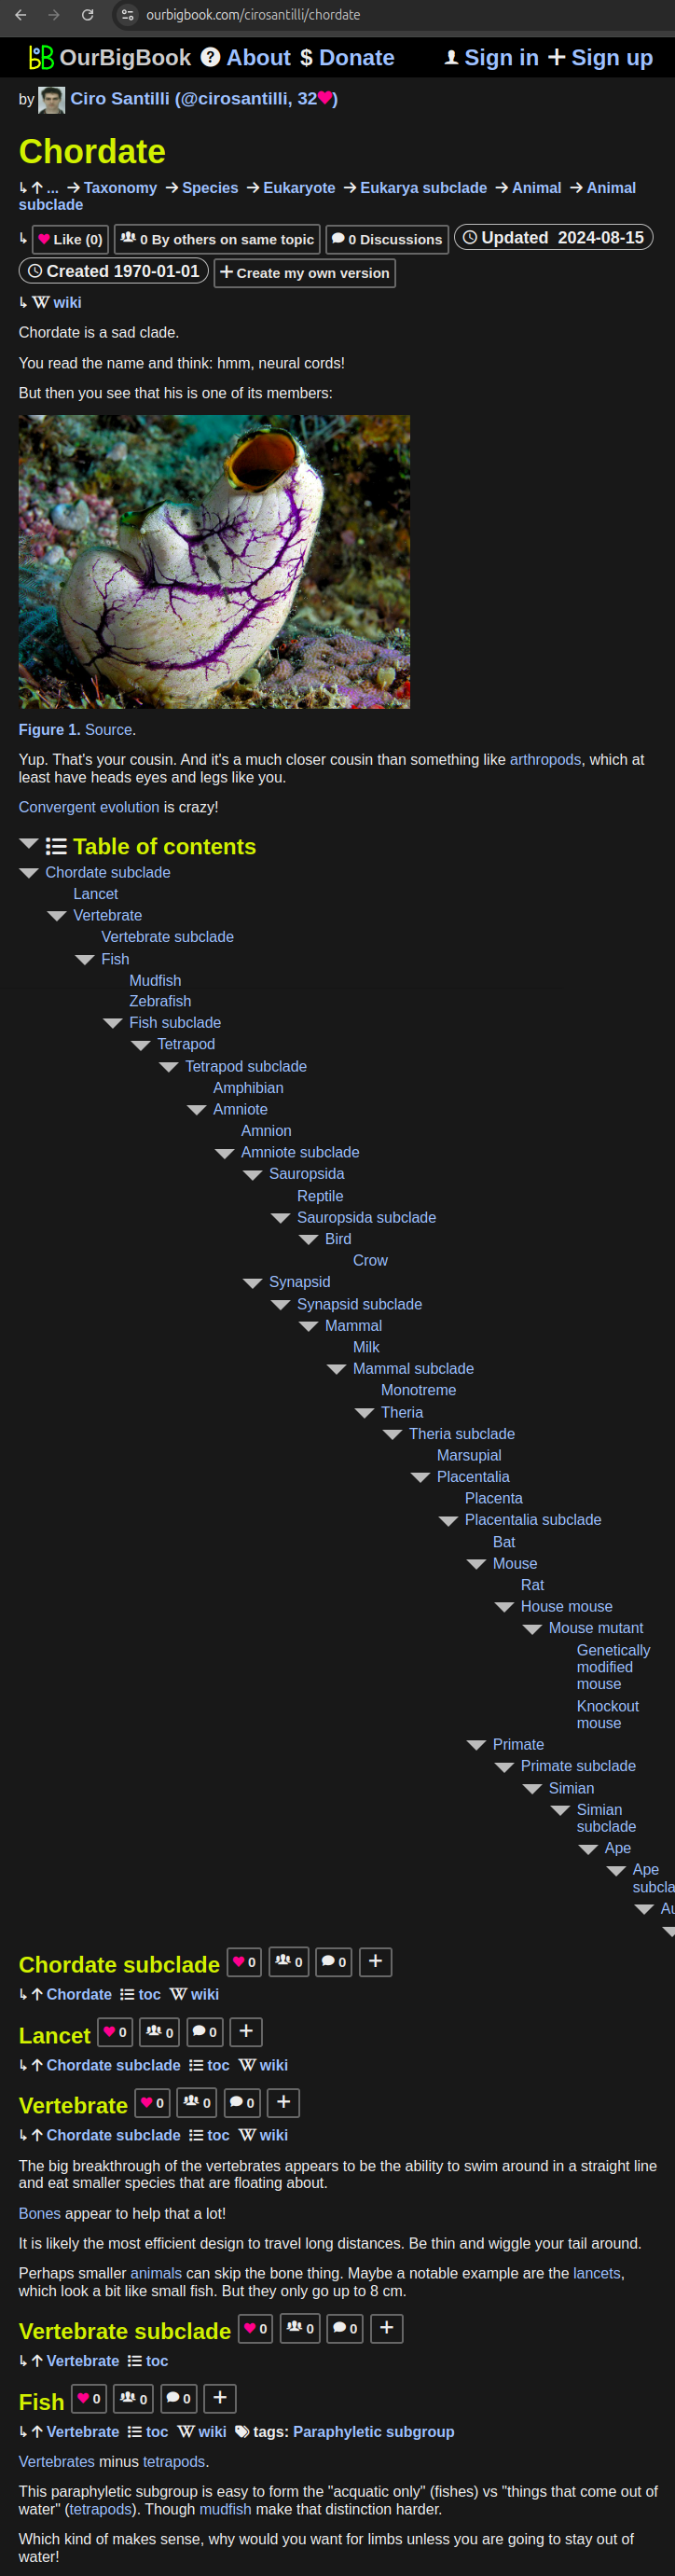
- Infinitely deep tables of contents:

All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact