Topics (254k) Articles (260k) Users (325) Discussions (237) Comments (383) Files (1k) New article
The Graham–Pollak theorem is a result in graph theory that pertains to the relationships between the edges of a complete graph and the configurations of points in Euclidean space. Specifically, it states that for a complete graph on \( n \) vertices, the number of edges that can be embedded in \( \mathbb{R}^d \) (real d-dimensional space) without any three edges crossing is limited.
Frucht's theorem is a result in graph theory that states that for any finite group \( G \), there exists a finite undirected graph (called a "Frucht graph") that is a Cayley graph of \( G \) and is also vertex-transitive (meaning that for any two vertices in the graph, there is some automorphism of the graph that maps one vertex to the other).
The Expander Mixing Lemma is a result from the field of graph theory, particularly in the study of expander graphs. Expander graphs are sparse graphs that have strong connectivity properties, which makes them useful in various applications, including computer science, combinatorics, and information theory. The Expander Mixing Lemma provides a quantitative measure of how well an expander graph mixes the vertices when performing random walks on the graph.
Elementary Number Theory, Group Theory, and Ramanujan Graphs are three distinct yet important topics in mathematics, particularly in the fields of number theory, algebra, and graph theory. Here's a brief overview of each: ### Elementary Number Theory Elementary number theory is a branch of mathematics that deals with the properties and relationships of numbers, particularly integers. It does not involve advanced mathematical tools such as calculus or abstract algebra.
Edmonds matrix is a mathematical concept used in the context of graph theory and combinatorial optimization, particularly in relation to the Edmonds-Karp algorithm for finding maximum flows in flow networks. However, some confusion arises because the term might also relate to different objects depending on the context. 1. **In Graph Theory**: The Edmonds matrix is sometimes referred to in discussions of cut matrices or adjacency matrices related to specific types of graphs.
In the context of graph theory and computational mathematics, edge and vertex spaces can refer to the associated vector spaces constructed from the edges and vertices of a graph. These concepts are often utilized in the study of networks, combinatorial structures, and various applications in computer science and mathematics.
An **edge-transitive graph** is a type of graph that has a high degree of symmetry. Specifically, a graph is called edge-transitive if, for any two edges in the graph, there exists an automorphism (a graph isomorphism from the graph to itself) that maps one edge to the other. This means that all edges of the graph are essentially indistinguishable in terms of the structure of the graph.
In graph theory, a dual graph is a construction that relates to a planar graph. To understand dual graphs, it's important to start with the concept of a planar graph itself. A planar graph is a graph that can be drawn on a plane without any edges crossing. ### Key Concepts of Dual Graphs 1. **Vertices of the Dual Graph**: For every face (region) in the original planar graph, there is a corresponding vertex in the dual graph.
A distance-transitive graph is a type of graph that exhibits a high degree of symmetry with respect to the distances between vertices.
A distance-regular graph is a specific type of graph that has a high degree of regularity in the distances between pairs of vertices. Formally, a graph \( G \) is said to be distance-regular if it satisfies the following conditions: 1. **Regularity**: The graph is \( k \)-regular, meaning each vertex has exactly \( k \) neighbors.
In the context of graph theory, the degree matrix is a square diagonal matrix that is used to represent the degrees of the vertices in a graph. Specifically, for a simple undirected graph \( G \) with \( n \) vertices, the degree matrix \( D \) is defined as follows: 1. The matrix \( D \) is of size \( n \times n \). 2. The diagonal entries of \( D \) are the degrees of the corresponding vertices in the graph.
In the context of graph theory, a **cycle space** is a fundamental concept associated with the study of cycles in graphs. Specifically, it is a vector space formed by the cycles of a graph when considered over a field (typically the field of two elements, often denoted as GF(2)). Here’s a more detailed breakdown: 1. **Graph Basics**: A graph is defined as a collection of vertices (or nodes) connected by edges.
In graph theory, a **cycle basis** of a graph is a minimal set of cycles such that any cycle in the graph can be expressed as a combination of these cycles. Specifically, for a connected graph, a cycle basis serves as a framework for the cycles of the graph. ### Key Points: 1. **Cycles**: A cycle in a graph is a path that starts and ends at the same vertex, with no other vertices repeated.
A conference matrix is a concept mainly used in combinatorics, specifically in the study of error-correcting codes, design theory, and graph theory. It is related to structured arrangements of points and lines, usually in the context of finite groups and their applications. More formally, a conference matrix is an \( n \times n \) matrix, where \( n \) is an even integer, that has specific properties: 1. The entries of the matrix are either 0 or 1.
A **conference graph** is a specific type of graph studied in graph theory, related to combinatorial designs.
In graph theory, conductance is a measure that indicates how well a graph can conduct flow between its parts. It is typically used in the context of studying random walks or the mixing properties of a graph. Conductance helps understand how well connected different regions (or communities) of a graph are.
The complex network zeta function is a mathematical tool used in the study of complex networks, which are structures characterized by interconnected nodes (or vertices) and edges (or links). This zeta function is often associated with certain properties of the network, such as its topology, dynamics, or spectral characteristics. ### Key Concepts 1. **Complex Networks**: These are graphs with complex structures, which can represent various real-world systems, such as social networks, transportation systems, biological networks, etc.
The clustering coefficient is a measure used in network theory to quantify the degree to which nodes in a graph tend to cluster together. It provides a way to understand the local structure of a network. There are two main types of clustering coefficients: the local clustering coefficient and the global clustering coefficient.
Centrality is a concept used in various fields, including mathematics, network theory, sociology, and data analysis, to measure the importance or influence of a node (such as a person, organization, or computer) within a network. The idea is that some nodes hold more power or are more significant than others based on their position and connections within the network.
Brouwer's conjecture, proposed by the Dutch mathematician L.E.J. Brouwer in the early 20th century, is a statement in the field of topology, particularly concerning the nature of continuous functions and fixed points. Specifically, the conjecture asserts that every continuous function from a compact convex set to itself has at least one fixed point.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.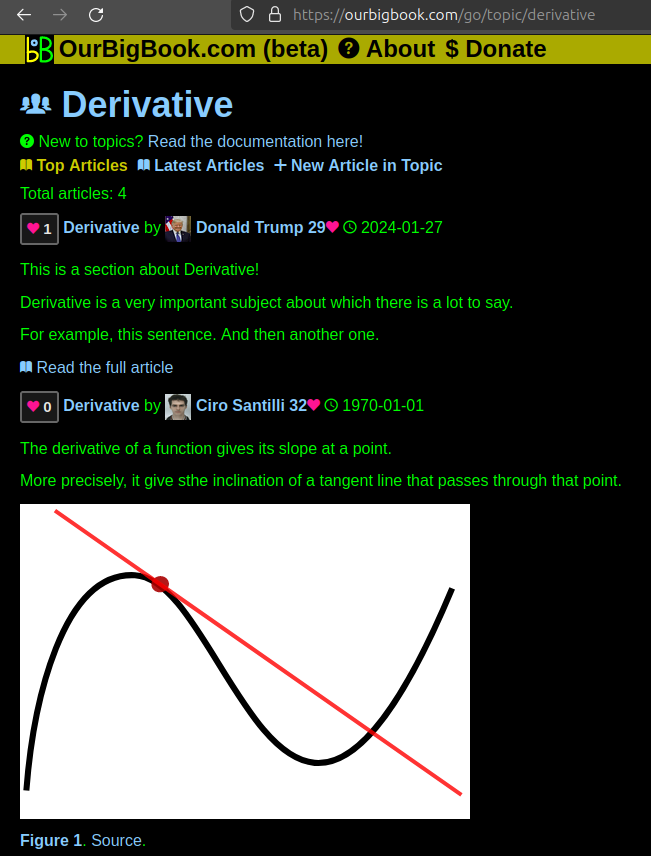
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.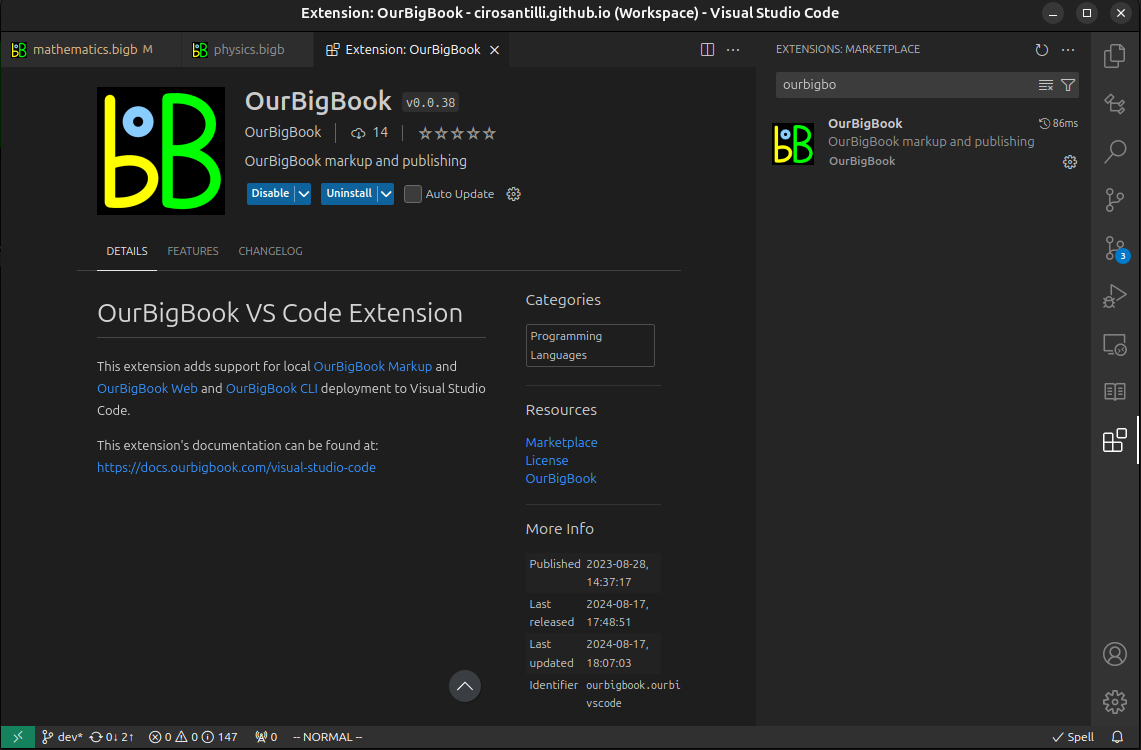
Figure 3. Visual Studio Code extension installation.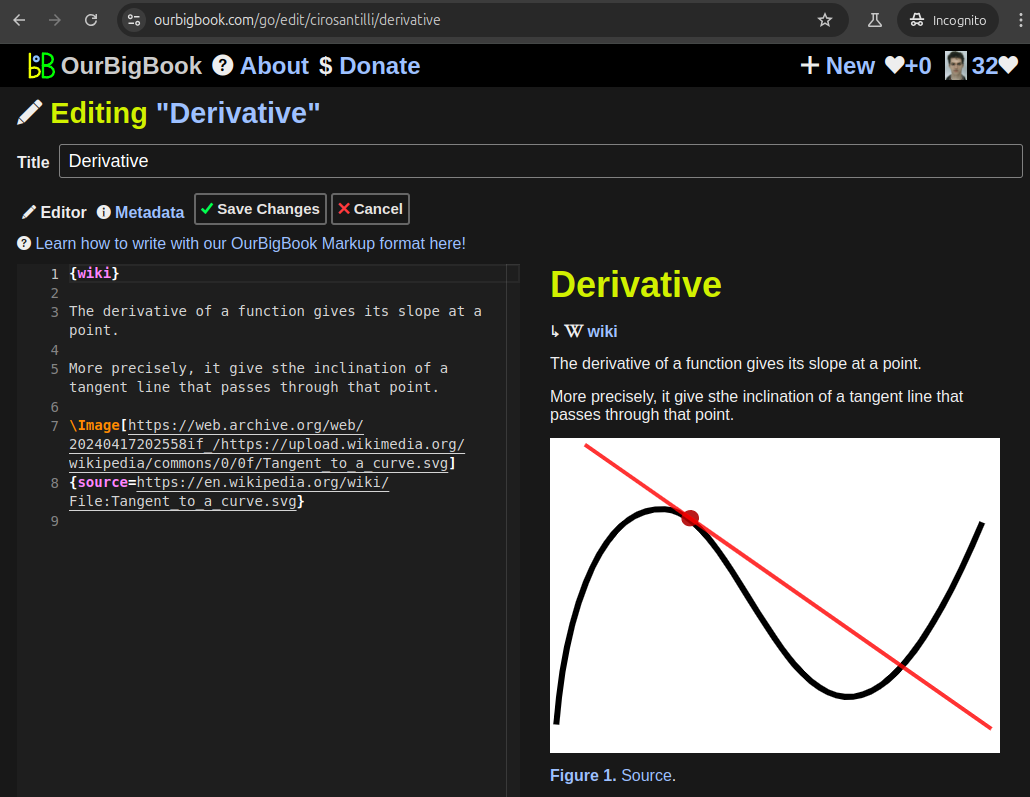
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 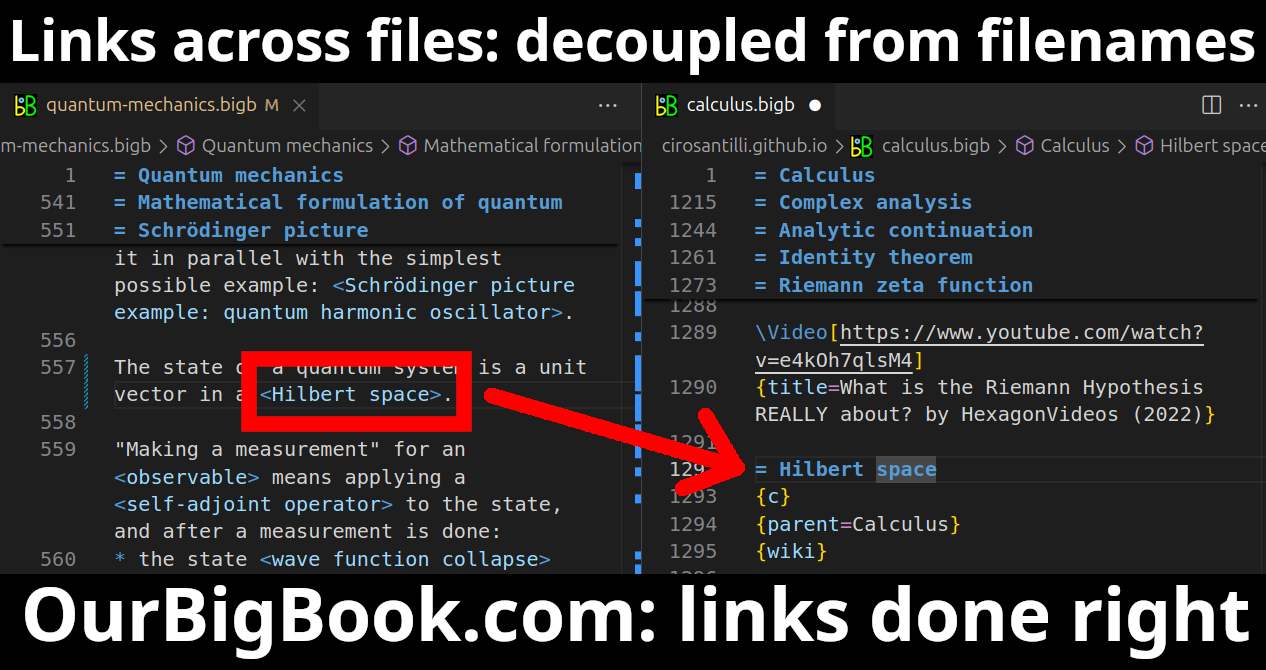
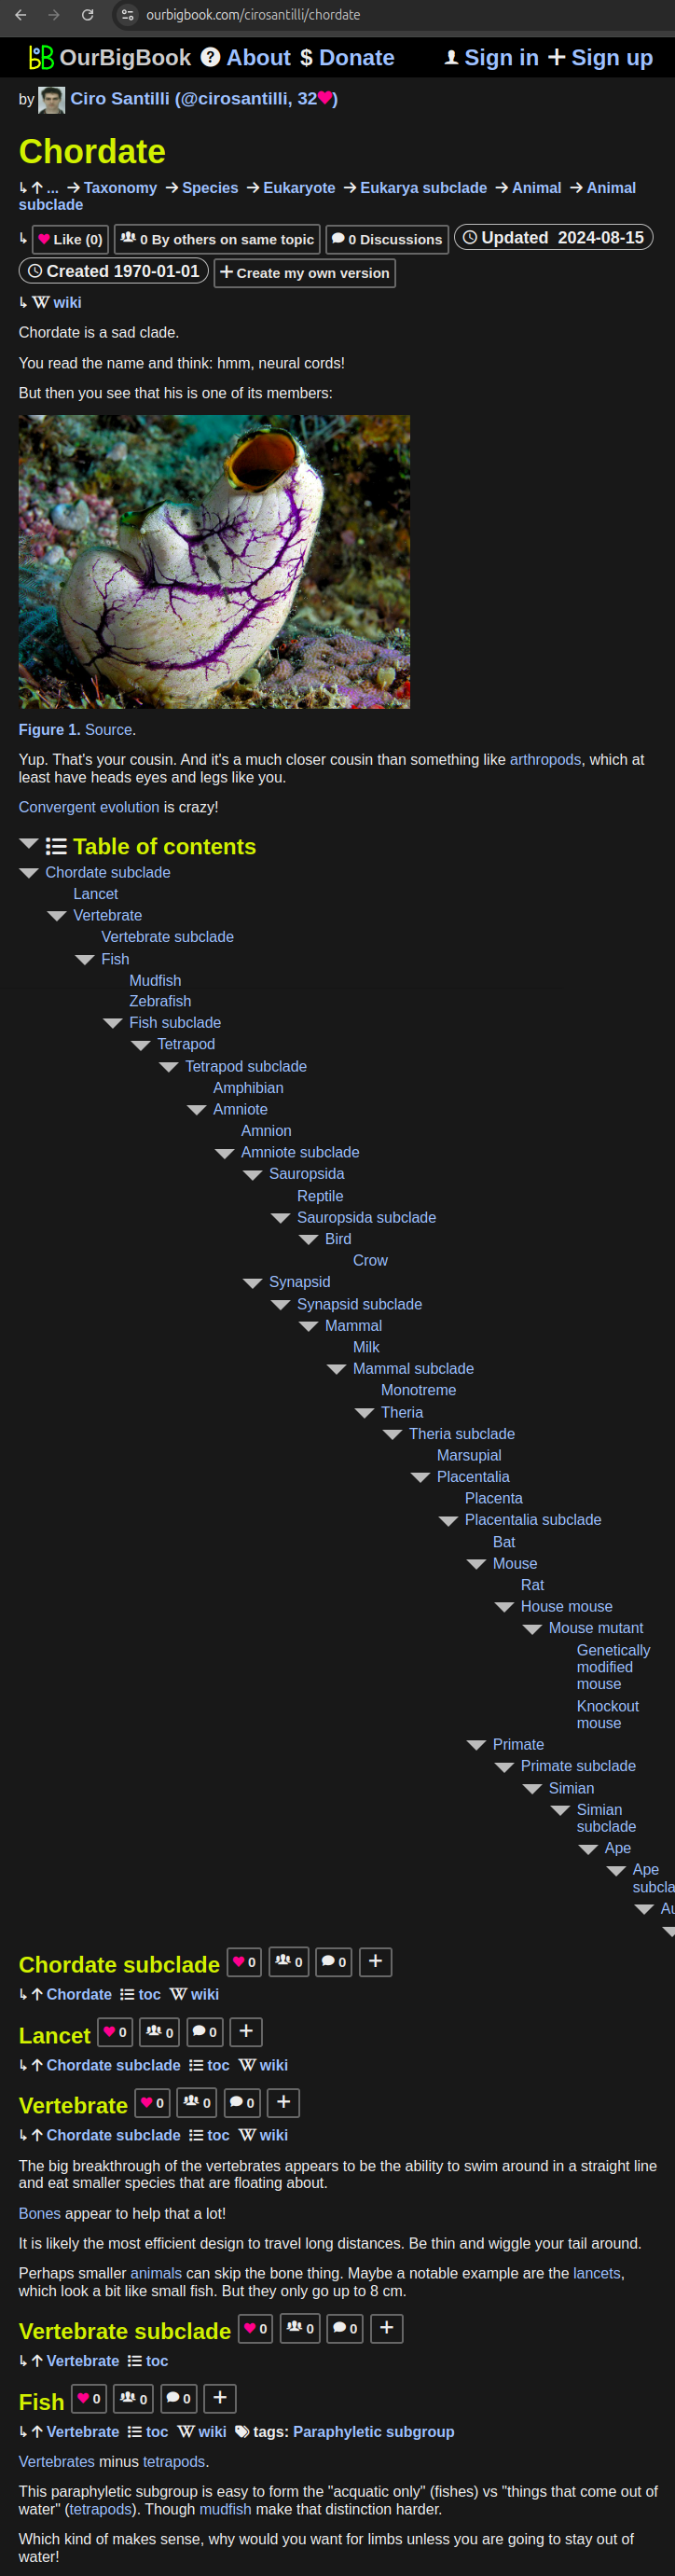
- Infinitely deep tables of contents:
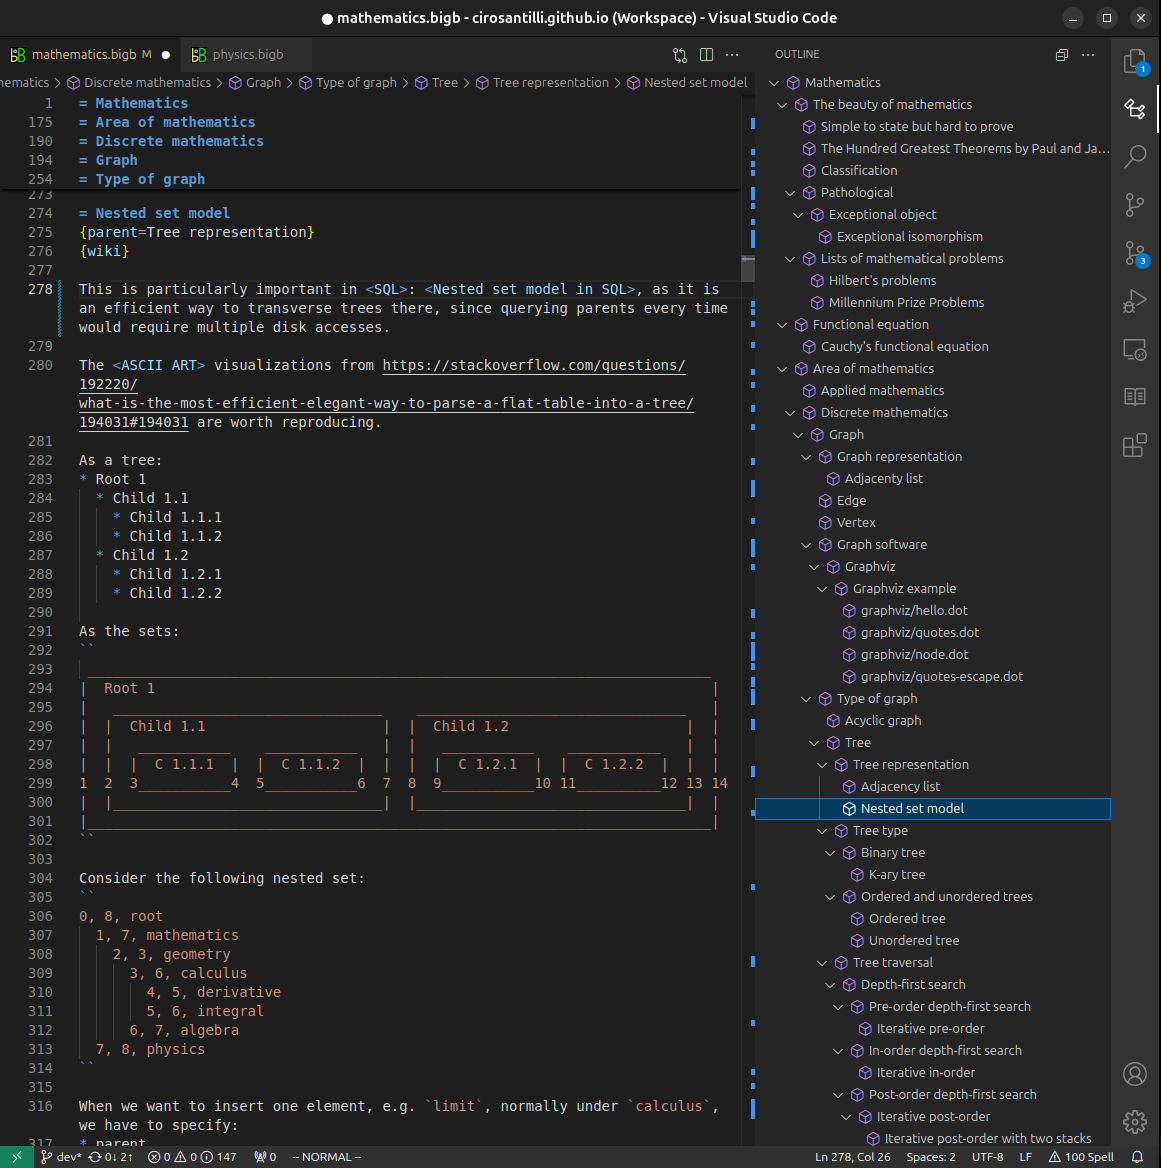
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact