Topics (349k) Articles (361k) Users (420) Discussions (237) Comments (383) Files (12k) New article

In information theory, the concept of a "typical set" is a fundamental idea introduced by Claude Shannon in his work on data compression and communication theory. The typical set is used to describe a subset of sequences from a larger set of possible sequences that exhibit certain "typical" properties in terms of probability and information. ### Definition 1. **Source and Sequences**: Consider a discrete memoryless source that can produce sequences of symbols from a finite alphabet.
Triangular network coding is a specific approach to network coding that involves the way data is transmitted across a network. This method can generally be explained in the context of multiple nodes that communicate with each other in a way that allows them to efficiently share information. The core idea behind network coding is that instead of simply relaying the messages as they are received, intermediate nodes can encode the messages they have in a way that allows for greater throughput and reduced data transmission redundancy.
Total correlation is a concept from information theory and statistics that measures the amount of dependence or shared information among a set of random variables. Unlike mutual information, which quantifies the shared information between two variables, total correlation extends this idea to multiple variables.
Information theory is a mathematical framework for quantifying information, developed in the mid-20th century. Below is a timeline highlighting key events and developments in the field: ### Early Concepts (Pre-1940s) - **Shannon's Foundation (1948):** Claude Shannon published "A Mathematical Theory of Communication," which is considered the founding document of information theory. In this work, he introduced key concepts such as entropy, redundancy, and the capacity of communication channels.
The term "three-process view" often refers to a framework in psychology that models the processes involved in how people perceive, encode, store, and retrieve information. Though the exact content and context might vary depending on the field or specific model being discussed, a common application of the three-process view is in the context of memory, specifically the information processing model of memory.
The Theil index is a measure of economic inequality that assesses the distribution of income or wealth within a population. It is named after the Dutch economist Henri Theil, who developed this metric in the 1960s. The Theil index is part of a family of inequality measures known as "entropy" measures and is particularly noted for its ability to decompose inequality into within-group and between-group components.
Surprisal analysis is a concept rooted in information theory, primarily developed by Claude Shannon. It measures the amount of information or "surprise" associated with the occurrence of a particular event, which is based on the probability of that event. The basic idea is that events that have low probability are more surprising when they occur than events that are highly probable.
Structural Information Theory (SIT) is an interdisciplinary framework that combines principles from information theory, structure, and semantics to analyze and understand the information content and organization of complex systems. While there may not be a single, universally accepted definition, Structural Information Theory is often associated with several key concepts: 1. **Information Content**: It focuses on quantifying the information stored within structures, be they biological, social, computational, or linguistic.
A **statistical manifold** is a mathematical construct that arises in the field of statistics and information geometry. It is a differentiable manifold whose points correspond to probability distributions, and it has a rich structure that allows for the study of statistical inference and the geometry of information. ### Key Concepts: 1. **Points as Probability Distributions**: Each point on the statistical manifold represents a distinct probability distribution.
Spectral efficiency, often measured in bits per second per Hertz (bps/Hz), is a key performance metric in telecommunications and signal processing. It quantifies how efficiently a given bandwidth is utilized for transmitting information. Essentially, it measures the amount of data that can be transmitted over a given spectral bandwidth of a communication channel. Key points regarding spectral efficiency include: 1. **Units**: Spectral efficiency is typically expressed in units of bps/Hz.
Specific information refers to detailed, precise, and contextually relevant data or facts about a particular subject, issue, or query. It contrasts with general information, which may be broader and less detailed. Specific information often includes specific numbers, dates, examples, and explanations that help clarify a topic or answer a particular question comprehensively.
A spatiotemporal pattern refers to the occurrence or arrangement of phenomena in both space and time. It involves the analysis of how certain variables or events are distributed across different locations and how these distributions change over time. Spatiotemporal patterns can be found in various fields, including: 1. **Geography and Environmental Science**: Patterns of climate change, land use, species migration, and natural disasters can be analyzed to understand spatial distributions and their temporal changes.
Spatial multiplexing is a technique used in multiple-input multiple-output (MIMO) communication systems to enhance data transmission rates and improve spectral efficiency. In spatial multiplexing, multiple spatial streams (data streams) are transmitted simultaneously over the same frequency channel using multiple antennas, both at the transmitter and the receiver. Here are the key aspects of spatial multiplexing: 1. **Multiple Antennas**: The technique relies on having multiple antennas at both the transmitter and receiver ends.
Shearer's inequality is a result in information theory related to the concept of conditional independence. It provides a way to bound the joint information of a collection of random variables in terms of the information of subsets of those variables.
The Shannon-Weaver model, also known as the Shannon-Weaver communication model or the mathematical theory of communication, was developed by Claude Shannon and Warren Weaver in 1948. It is a foundational concept in the field of communication theory and seeks to explain how information is transmitted from a sender to a receiver through a channel. The model emphasizes the technical aspects of communication and includes the following key components: 1. **Sender (Information Source):** The entity that generates the message that needs to be communicated.
The Shannon–Hartley theorem is a fundamental principle in information theory that provides a formula for calculating the maximum data rate (or channel capacity) that can be transmitted over a communication channel, given a certain bandwidth and signal-to-noise ratio (SNR). The theorem is mathematically expressed as: \[ C = B \log_2(1 + \text{SNR}) \] Where: - \( C \) is the channel capacity in bits per second (bps).
The Shannon capacity of a graph is a concept in information theory that relates to the maximum rate at which information can be transmitted over a noisy channel represented by the graph, while ensuring that the probability of error in the transmission approaches zero as the number of transmitted messages increases. Specifically, the Shannon capacity \( C(G) \) of a graph \( G \) is defined as the supremum of the rates at which information can be reliably transmitted over the channel represented by the graph.
Shannon's source coding theorem is a fundamental result in information theory, established by Claude Shannon in his groundbreaking 1948 paper "A Mathematical Theory of Communication." The theorem provides a formal framework for understanding how to optimally encode information in a way that minimizes the average length of the code while still allowing for perfect reconstruction of the original data.
Self-dissimilarity refers to a property of certain patterns, structures, or systems where the components or parts of the system exhibit a form of dissimilarity or variance from each other, despite being derived from the same overall entity or source. This concept is often discussed in various fields, including mathematics, physics, and art.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.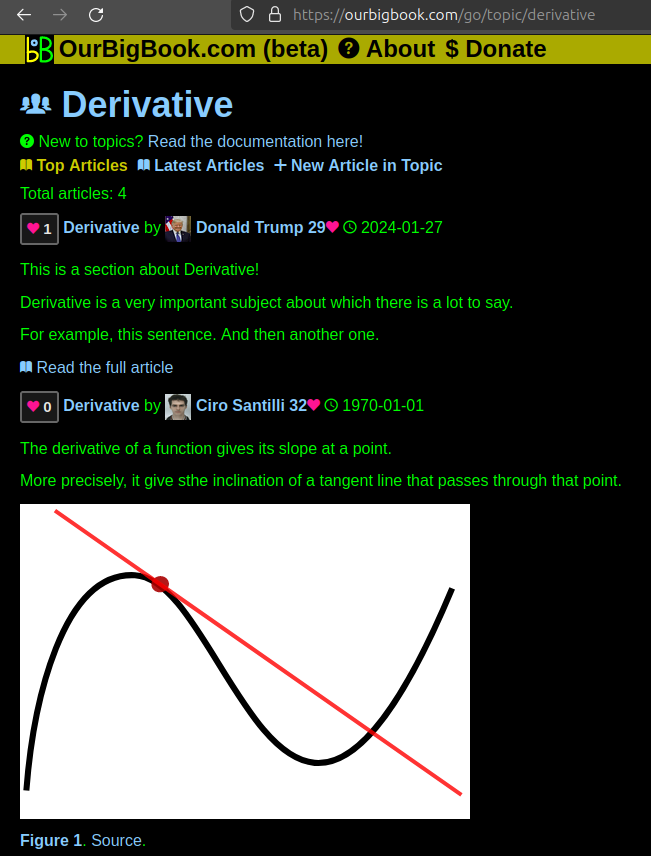
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
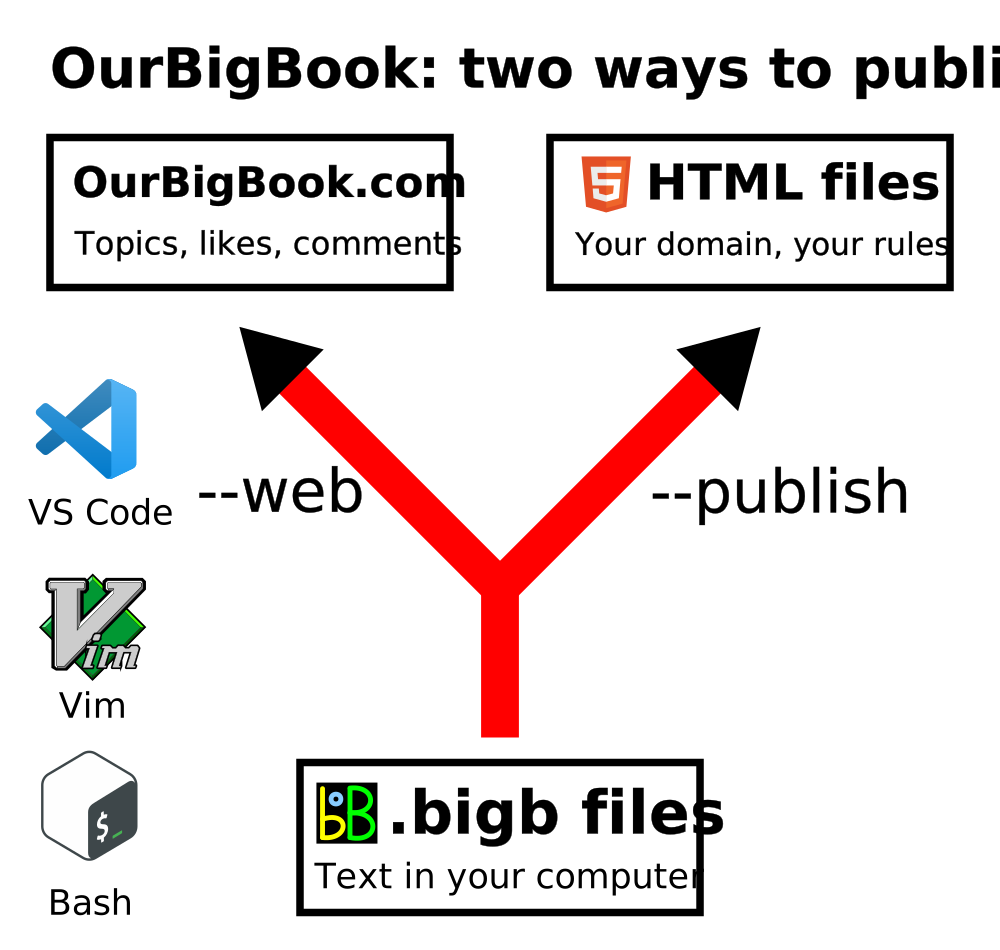
Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.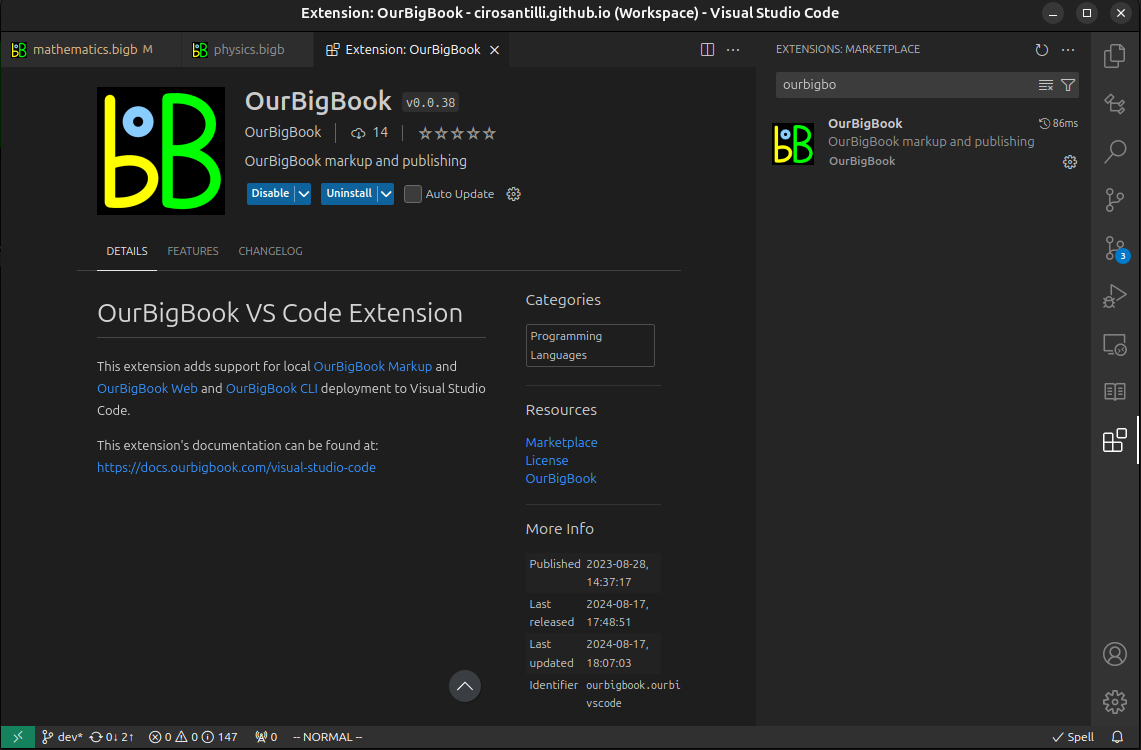
Figure 3. Visual Studio Code extension installation.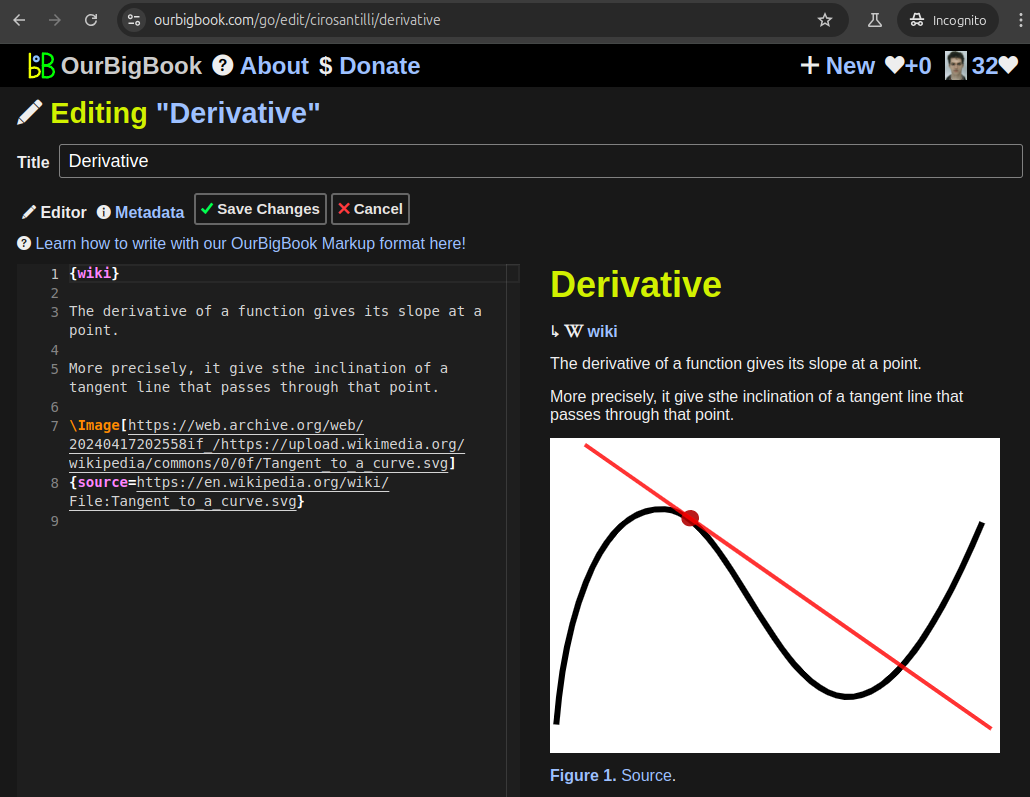
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 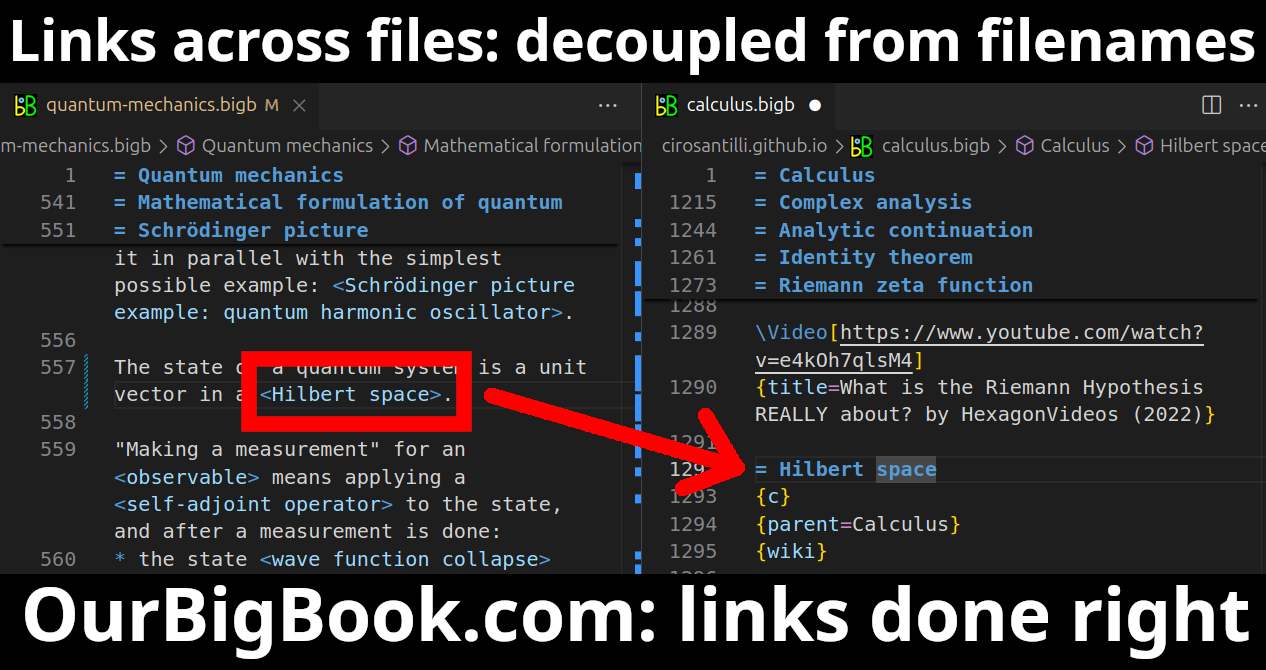
- Infinitely deep tables of contents:
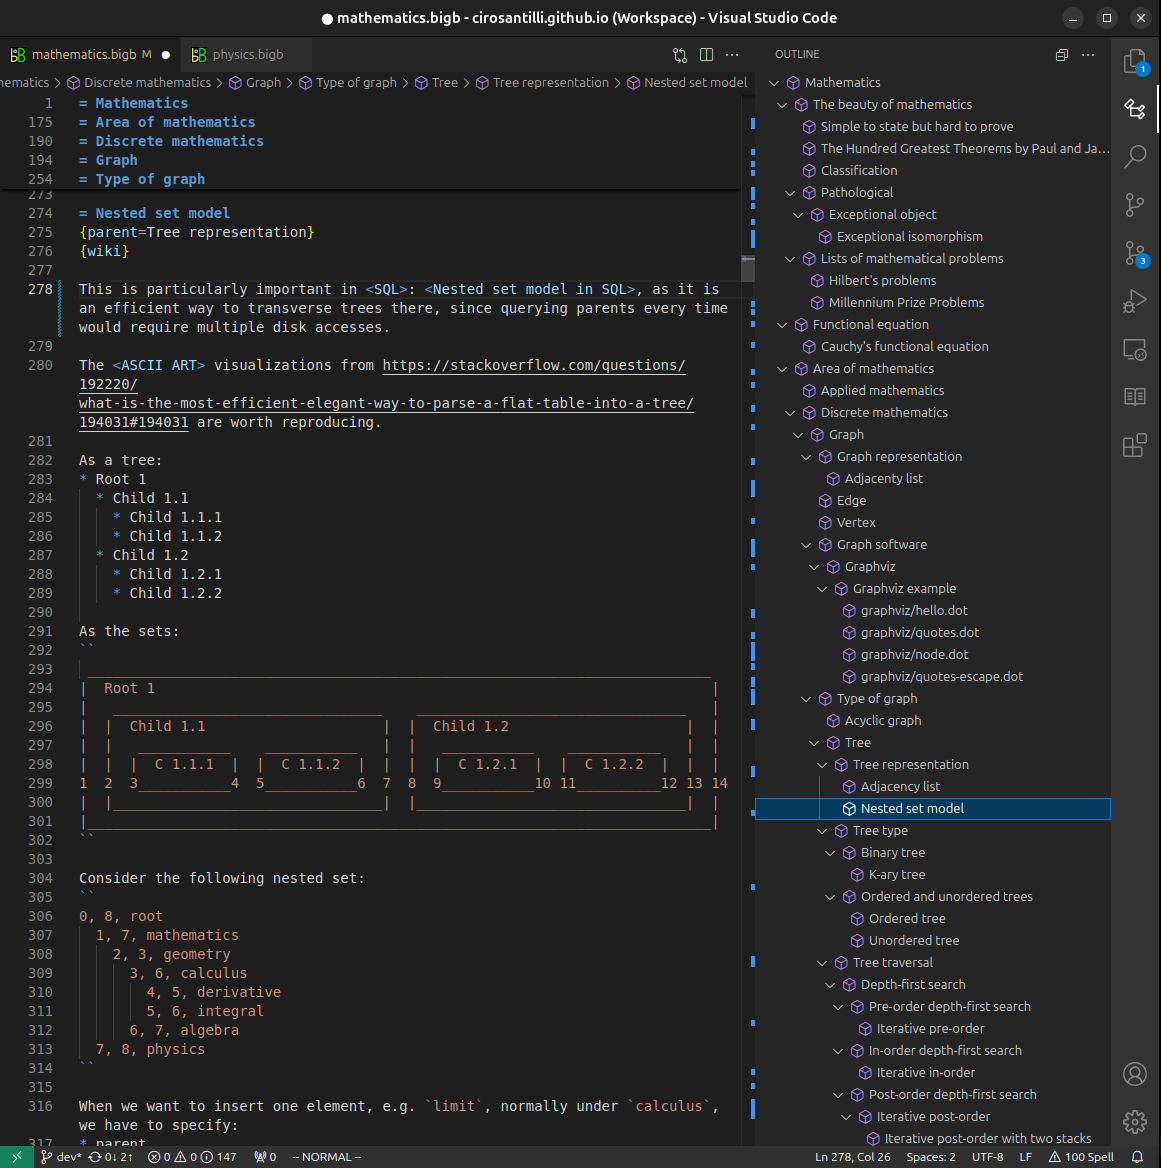
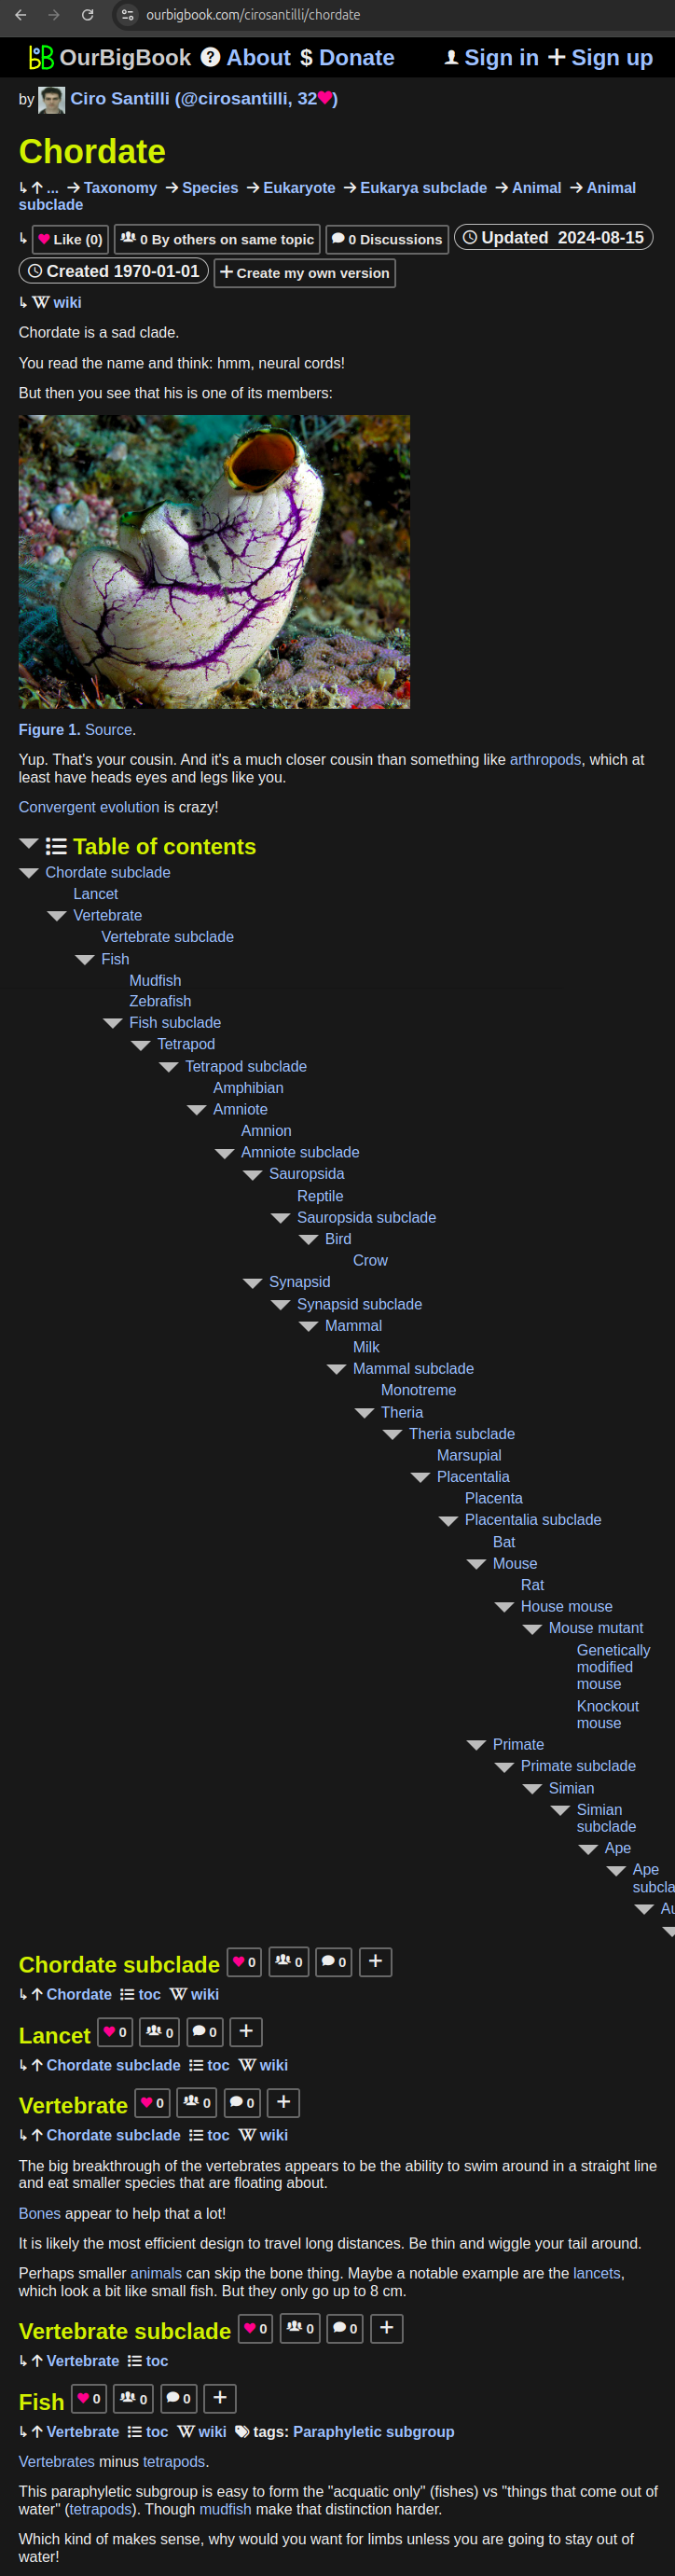
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact