Topics (349k) Articles (361k) Users (420) Discussions (237) Comments (383) Files (12k) New article

The Entropy Power Inequality (EPI) is a fundamental result in information theory that relates the entropy of a sum of independent random variables to their individual entropies.
Entropy estimation is a statistical method used to estimate the entropy of a probability distribution based on a sample of data. Entropy, in the context of information theory, is a measure of the uncertainty or randomness in a probability distribution. Specifically, it quantifies the expected amount of information produced by a stochastic source of data.
In information theory, entropy is a measure of the uncertainty or unpredictability associated with a random variable or a probability distribution. It quantifies the amount of information that is produced on average by a stochastic source of data. The concept was introduced by Claude Shannon in his seminal 1948 paper "A Mathematical Theory of Communication.
The term "entropic vector" does not refer to a widely recognized concept in mainstream scientific literature as of my last knowledge update in October 2023. However, it may be helpful to consider the context in which the term could be used. 1. **Entropy in Physics and Information Theory**: In physics and information theory, entropy is a measure of disorder or uncertainty. It quantifies the amount of information that is missing when we do not know the exact state of a system.
Entropic uncertainty refers to a concept in quantum mechanics and information theory that quantifies the uncertainty or lack of predictability associated with measuring the state of a quantum system. It is often expressed in terms of entropy, particularly the Shannon entropy or the von Neumann entropy, which measure the amount of information that is missing or how uncertain we are about a particular variable.
Entropic gravity is a theoretical framework that attempts to explain gravity not as a fundamental force, but as an emergent phenomenon arising from the statistical behavior of microscopic degrees of freedom in a system, particularly in the context of thermodynamics and information theory. The concept was notably developed by physicist Erik Verlinde in a paper published in 2011. According to this viewpoint, gravity emerges from the entropy associated with the information of the positions of matter.
Dual total correlation is a concept from information theory and statistics, often related to the analysis of complex systems and their information structures. While it is less commonly referenced than some other measures, it can be understood in the context of how information is measured and shared among variables in a system. ### Background Concepts 1. **Total Correlation**: Total correlation is a measure of the amount of information that is shared among multiple random variables. It quantifies the redundancy or dependency between variables in a joint distribution.
Distributed source coding is a concept in information theory that involves the compression of data coming from multiple, potentially correlated, sources. The idea is to efficiently encode the data in such a way that the decoders, which may have access to different parts of the data, are able to reconstruct the original data accurately without requiring all data to be transmitted to a central location.
Directed information is a concept in information theory that is used to quantify the flow of information between two stochastic processes (or random variables) over time. This concept is particularly useful in the analysis of complex systems where one process can influence or cause changes in another process.
Differential entropy is a concept in information theory that extends the idea of traditional (or discrete) entropy to continuous probability distributions. While discrete entropy measures the uncertainty associated with a discrete random variable, differential entropy quantifies the uncertainty of a continuous random variable.
The Damerau–Levenshtein distance is a metric used to measure the difference between two strings by quantifying the minimum number of single-character edits required to transform one string into the other. It extends the Levenshtein distance by allowing for four types of edits: 1. **Insertions**: Adding a character to the string. 2. **Deletions**: Removing a character from the string.
DISCUS stands for the "Data Integration and Sharing in Clinical and Biomedical Research" initiative. It is typically associated with efforts aimed at improving the integration, sharing, and accessibility of clinical and biomedical data among researchers, institutions, and public health entities. The initiative seeks to enhance collaboration in scientific research, facilitate better data management practices, and promote the use of standardized protocols for data sharing. By streamlining these processes, DISCUS aims to accelerate the advancement of medical research and improve outcomes in healthcare.
"Cycles of Time" can refer to various concepts depending on the context, including literature, philosophy, science, and even spirituality. Generally, it pertains to the idea that time is not a linear progression but rather consists of repeating or cyclical patterns. Here are a few interpretations of the concept: 1. **Philosophical/Spiritual Perspective**: Many cultures and philosophical traditions view time as cyclical.
Cooperative MIMO (Multiple Input Multiple Output) is a wireless communication technique that enhances the performance of MIMO systems by enabling cooperation among multiple users or nodes in a network. Traditional MIMO relies on multiple antennas at both the transmitter and receiver ends to increase capacity and improve signal quality. Cooperative MIMO extends this concept by allowing different users to jointly transmit and receive signals by leveraging their individual antenna resources.
In information theory, a constraint refers to a limitation or restriction that affects the way information is processed, transmitted, or represented. Constraints can come in various forms and can influence the structure of codes, the capacity of communication channels, and the efficiency of data encoding and compression. Here are some examples of constraints in information theory: 1. **Channel Capacity Constraints**: The maximum rate at which information can be transmitted over a communication channel without error is characterized by the channel's capacity.
Conditional mutual information (CMI) is a measure from information theory that quantifies the amount of information that two random variables share, given the knowledge of a third variable. It extends the concept of mutual information by introducing a conditioning variable, allowing us to understand relationships between variables while controlling for the influence of the third variable.
Conditional entropy is a concept from information theory that quantifies the amount of uncertainty or information required to describe the outcome of a random variable, given that the value of another random variable is known. It effectively measures how much additional information is needed to describe a random variable \( Y \) when the value of another variable \( X \) is known.
Computational irreducibility is a concept introduced by Stephen Wolfram in his work on cellular automata and complex systems, particularly in his book "A New Kind of Science." It refers to the idea that certain complex systems cannot be easily predicted or simplified; instead, one must simulate or compute the system's evolution step by step to determine its behavior.
A communication source refers to the origin or starting point of a message in the communication process. It can be a person, group, or organization that initiates the communication by encoding and transmitting information, ideas, or feelings to a receiver. The source plays a crucial role in determining the effectiveness and clarity of the message being communicated. Key characteristics of a communication source include: 1. **Credibility**: The perceived trustworthiness and expertise of the source can significantly impact how the message is received.
Communication complexity is a branch of computational complexity theory that studies the amount of communication required to solve a problem when the input is distributed among multiple parties. It specifically investigates how much information needs to be exchanged between these parties to reach a solution, given that each party has access only to part of the input. Here are some key points about communication complexity: 1. **Setting**: In a typical model, there are two parties (often referred to as Alice and Bob), each having their own input.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.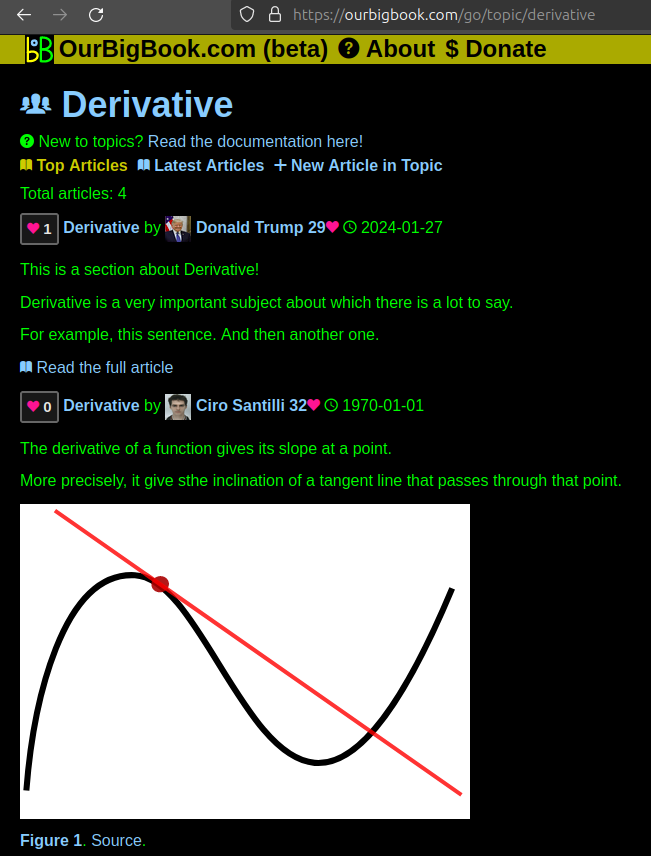
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
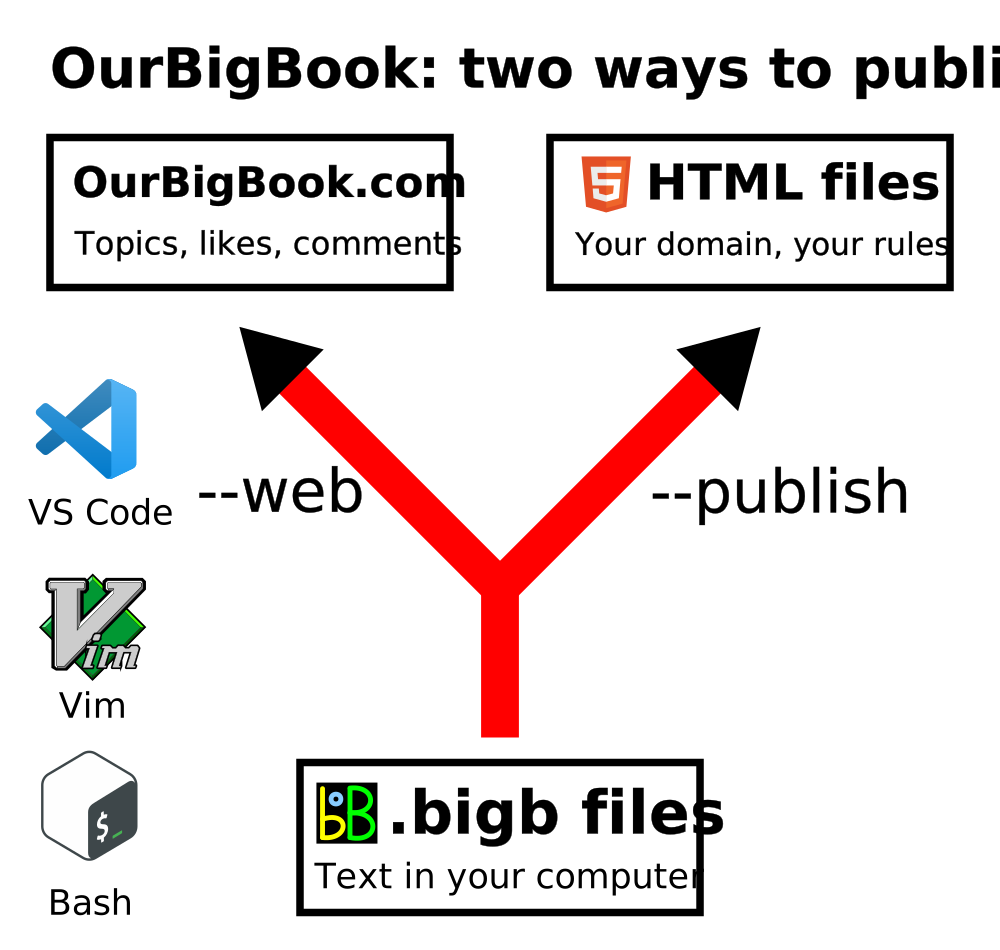
Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.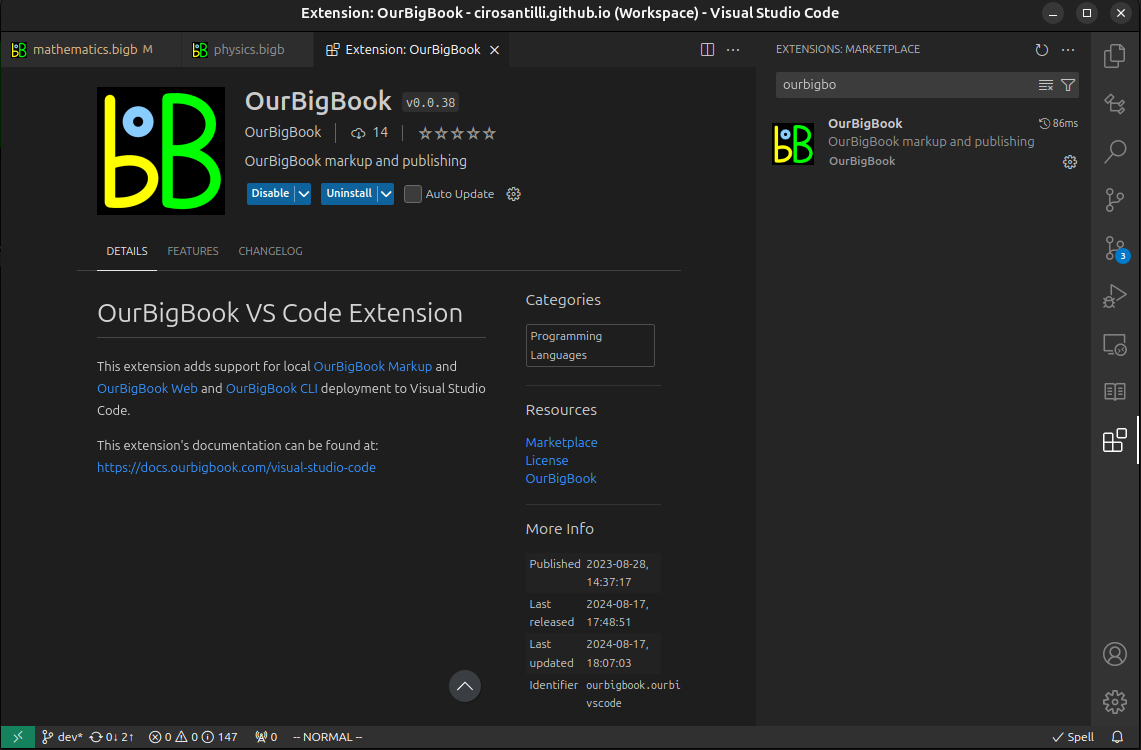
Figure 3. Visual Studio Code extension installation.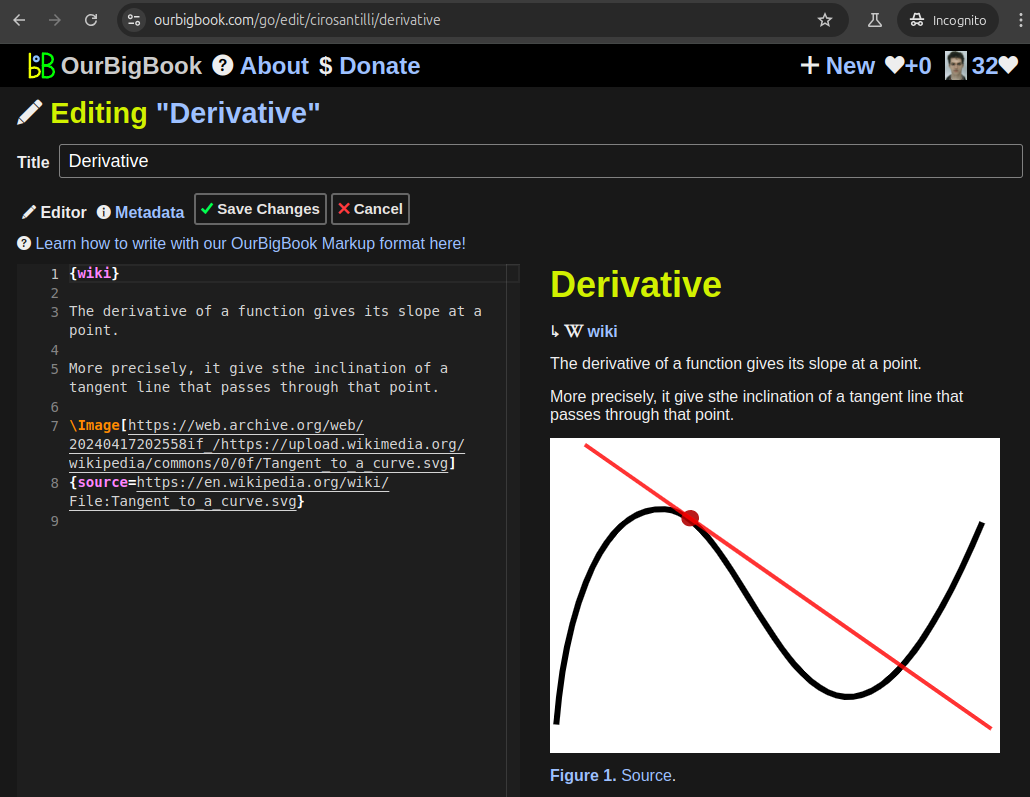
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 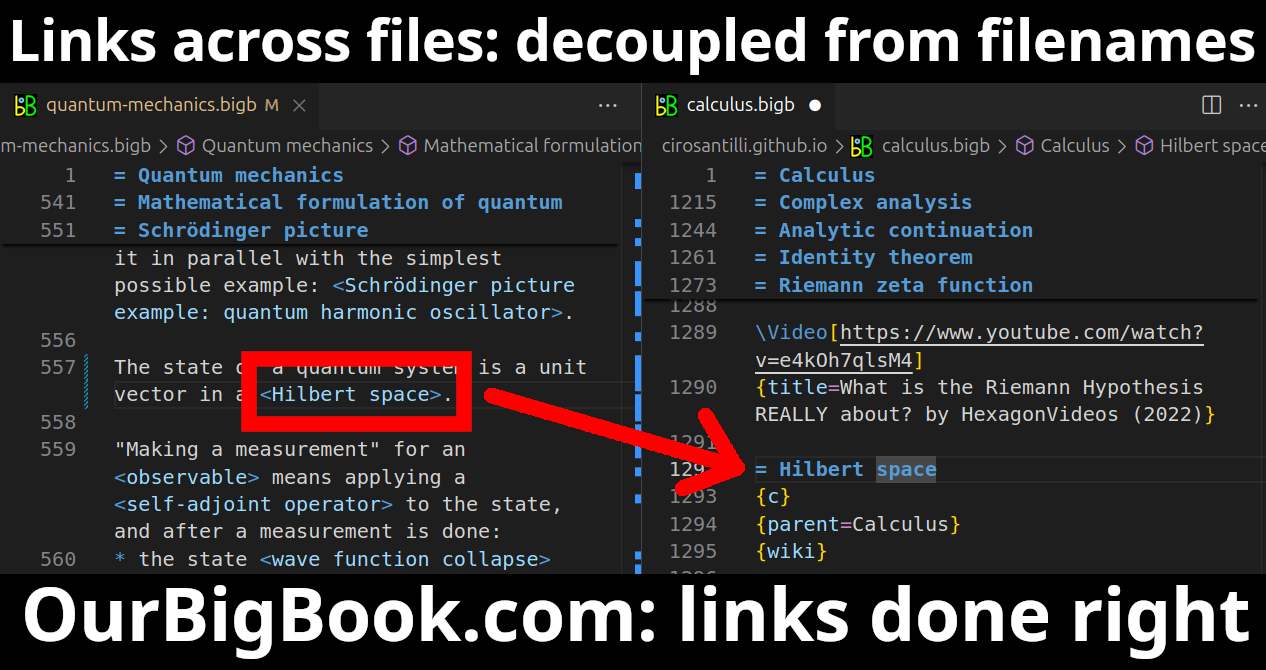
- Infinitely deep tables of contents:
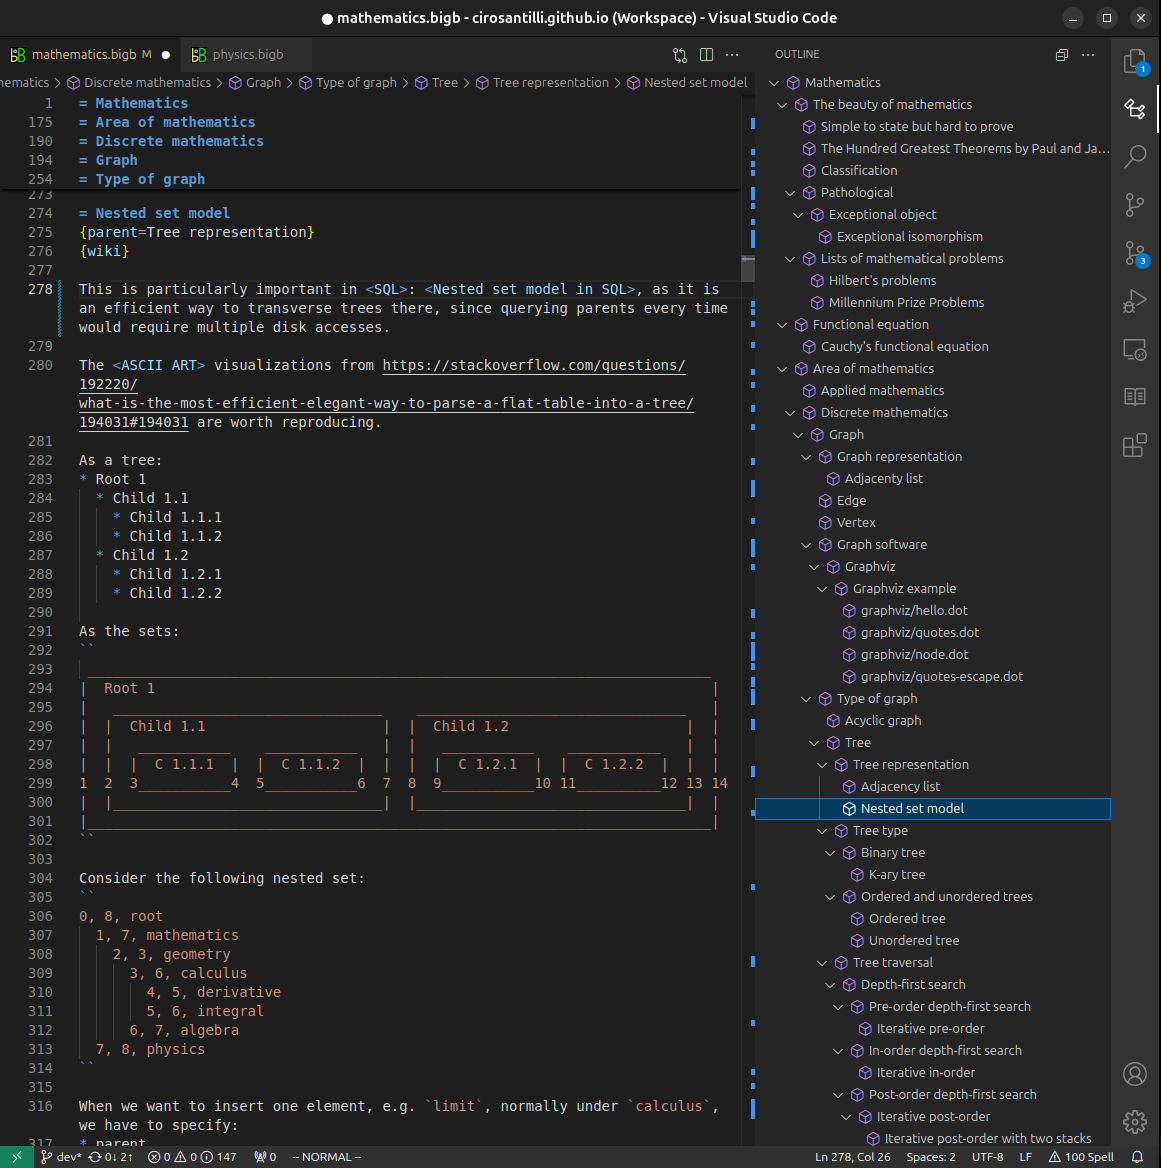
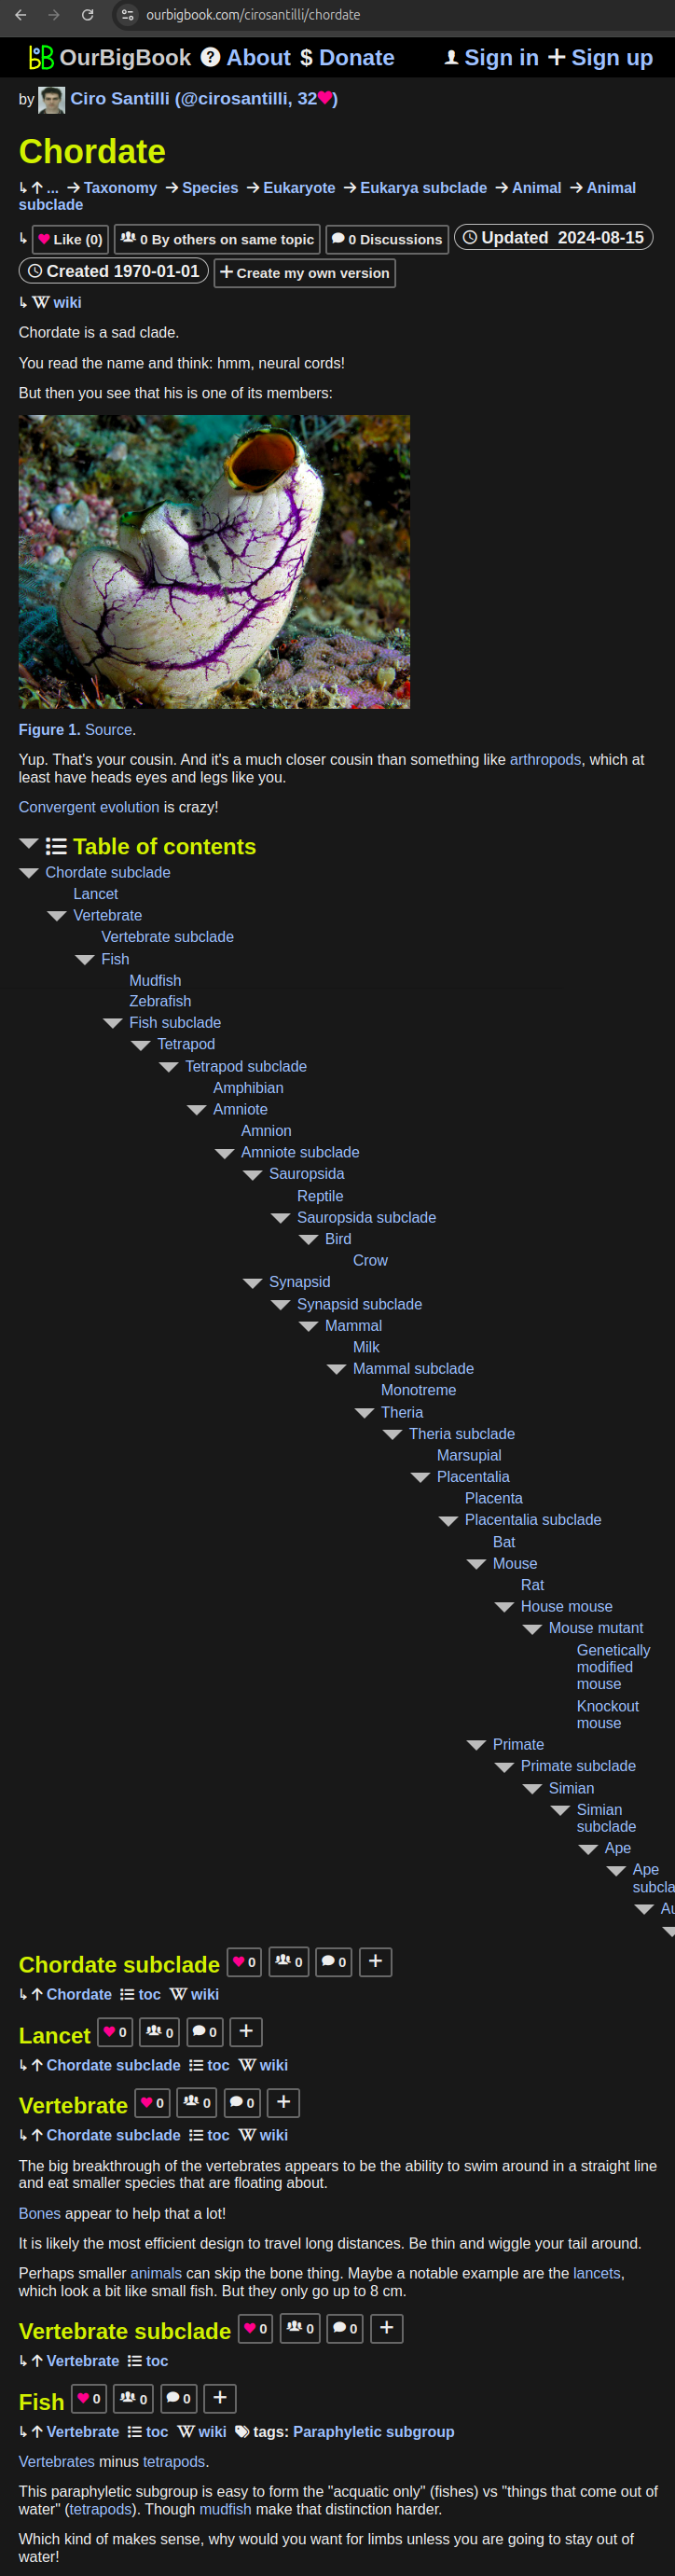
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact