Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
The cosmological constant problem is the unexplained smallness of the gravitationally observable vacuum energy compared with the contributions expected from quantum field theory. In units with , an ultraviolet cutoff generically gives contributions of order , whereas the observed dark-energy density is of order . The Einstein equation depends on the sum of a bare cosmological constant and these contributions; subtracting a constant from a nongravitational Hamiltonian does not remove its gravitational effect. Exact global supersymmetry gives zero energy to a supersymmetric vacuum, but supersymmetry breaking generally reintroduces a much larger positive scale.
Nonrelativistic matter dilutes as , while a cosmological constant has constant energy density. The ratio of vacuum energy density to matter density consequently scales as , so comparable contributions occur during a limited epoch. The cosmic coincidence problem asks why observers find these very different components comparable near their own epoch. This timing puzzle is distinct from the cosmological constant problem, which concerns the tiny absolute vacuum-energy scale.
For an open matter-dominated Friedmann solution, put , and . The cosmological bolometric background from conserved sources has , since and . At fixed , the limit is , whereas the Einstein-de Sitter universe gives . Keeping the cosmic age fixed instead reverses this ordering: the two values are respectively and .
For nonevolving comoving number density , identical spectra , and no attenuation, the cosmological background intensity from comoving emissivity in an Einstein-de Sitter universe is proportional to . The improper integral is finite exactly for , with value . Equality gives logarithmic divergence; larger gives a power-law divergence. A formation epoch or a spectral break can regularize this idealized model.
A finite visibility width averages photon sources over emission time and radial position. For a Gaussian visibility profile, a plane-wave radial phase has the displayed damping factor; its power has the square of this amplitude factor. An acoustic source also varies with frequency , so its rapid oscillations are averaged. This averaging is distinct from Silk damping, which smooths the perturbations by photon diffusion before decoupling. Angular projection and source evolution prevent a universal isotropic damping coefficient based only on radial width.
The extension of the cosine to the complex plane is . Splitting the complex exponential function into its real part and imaginary part gives the displayed formula in terms of hyperbolic cosine and hyperbolic sine.
For a homogeneous isotropic point process of galaxies with mean number density , the galaxy two-point correlation function gives the excess pair probability at distinct positions. Dividing the factorial pair density by the probability of a central galaxy gives conditional neighbouring-galaxy density . Choosing a central location uniformly in volume does not perform this conditioning.
Isotropic cosmological correlation-power-spectrum relation by  Codex 0 Created 2026-10-14 Updated 2026-11-05
For the Fourier transform convention and covariance , inversion gives . Isotropy reduces the angular integral to , where is the order-zero Spherical Bessel function. At zero separation this gives the variance if the spectrum integral converges. A nonnegative spectrum can produce negative correlations away from the origin.
The correlation function with a single field insertion is its expectation value. In a translation-invariant vacuum it is independent of position. A tadpole subtraction chooses a linear counterterm, or shifts the expansion point of the field, so that this expectation is zero. This removes attached tadpole diagrams from higher connected correlation functions without discarding the physical need to renormalize the chosen vacuum.
The four-point correlation function measures a time-ordered product of four field insertions. For a centered scalar field its disconnected terms are the three products of two-point functions, and subtracting those products leaves the connected correlation function. In a free Gaussian scalar vacuum the connected four-point function vanishes, by Wick's theorem, so only the three paired products remain. The connected four-point function of phi-fourth theory starts with one quartic vertex; amputation removes its external propagators. The full correlator, its connected part and the four-point one-particle-irreducible correlation function should therefore be distinguished.
In a set family, replace a set containing by its deletion of only when that deletion is absent. This preserves cardinality and cannot increase maximum pairwise Hamming distance. If a new set and a retained set gave a larger distance, the retained set's deletion would already have been present; that deletion and the original uncompressed set would give the same distance. Repeated downward compressions yield a down-set.
For the Fourier transform convention , integration gives , with value one at zero. The convolution theorem makes the transform of the -fold convolution its th power. This is a simple way to construct compactly supported functions with prescribed polynomial Fourier decay.
This integral smoothness condition on a convolution kernel controls how translations change the kernel away from the translation scale. It need not imply differentiability. Coupled with an operator bound, it yields a weak type (1,1) bound through the Calderón–Zygmund decomposition. It is distinct from the bracket-generating condition for differential operators also named after Hörmander.
A convolution kernel is the fixed function in an operator . It specifies how shifted input values are weighted. The averaging kernel above has nonnegative values and integral one; arbitrary convolution kernels need not have either property. A linear time-invariant system uses its impulse response as a kernel when its output admits this representation.
A convex polygon is a two-dimensional convex polytope, equivalently the convex hull of a finite planar set with nonempty interior. Its vertices are the extreme points of that hull. Saying that given points form a convex polygon means every specified point is a vertex; points inside the hull or in the interior of a straight boundary segment do not count as vertices.
A lattice polytope is the convex hull of finitely many points of a Euclidean lattice. It need not contain the origin. Integral translation changes its associated homogeneous semigroup ring by a grading-preserving isomorphism.
// Target: geometry-and-topology.bigb
A zonotope is a Minkowski sum of finitely many line segments, equivalently an affine map image of a cube. For vectors , the set is the support of the associated box spline. A centred version uses instead. In two dimensions, sums of differently directed segments give centrally symmetric polygons; repeated directions lengthen their corresponding edges without adding new edge directions.
Every point in the convex hull of a subset of is a convex combination of at most points of that subset. Thus in the plane three ingredients always suffice, however many samples were supplied. The representation of in convex hull illustrates this bound. Two ingredients need not suffice: the centroid of a triangle with only its three vertices as input is on none of their three pairwise line segments.
A short proof outline removes redundant ingredients. With more than points, the augmented vectors are linearly dependent. A dependence lets the weights vary while preserving both their sum and the represented point. Move along it until one positive weight first becomes zero; all weights stay nonnegative. Repeating leaves at most positive weights.
In his 1911 paper, Constantin Carathéodory used convex geometry to investigate the possible Fourier coefficients of positive harmonic functions. Its introduction interprets convex mixtures through the center of mass, connecting finite-dimensional geometry to constraints on a function's coefficients.[ref]
Über den Variabilitätsbereich der Fourier’schen Konstanten von positiven harmonischen Funktionen by Constantin Carathéodory. English translation by Nicholas J. Williams, Introduction §4, original printed p. 195; §I concerns the smallest containing convex domain
Jensen's inequality says that applying a convex function to a weighted mean cannot exceed the same weighted mean of its outputs. For nonnegative weights with and inputs in a convex set,Nonnegative weights are essential: this is a convex combination, rather than an arbitrary affine combination. For two inputs it is precisely the defining inequality for a convex function; repeatedly grouping inputs gives the finite weighted version.
Take , weights and , and inputs and . Their weighted mean is , so the two sides areThe Jensen gap is . The inequality measures the effect of replacing distinct inputs by one representative input before applying a nonlinear function.
The probabilistic form uses an integrable random variable taking values in an interval where is a convex function. If is also an integrable random variable and belongs to that interval, thenThe direction reverses for a concave function. For a strictly convex function, equality in the finite weighted form requires all inputs having positive weight to be equal; in the probabilistic form it requires to be constant almost surely. An affine function gives equality for any admissible distribution. [ref]
https://stanford.edu/~boyd/cvxbook/bv_cvxslides.pdf. Boyd and Vandenberghe's slides, section 3.14, state the expectation form
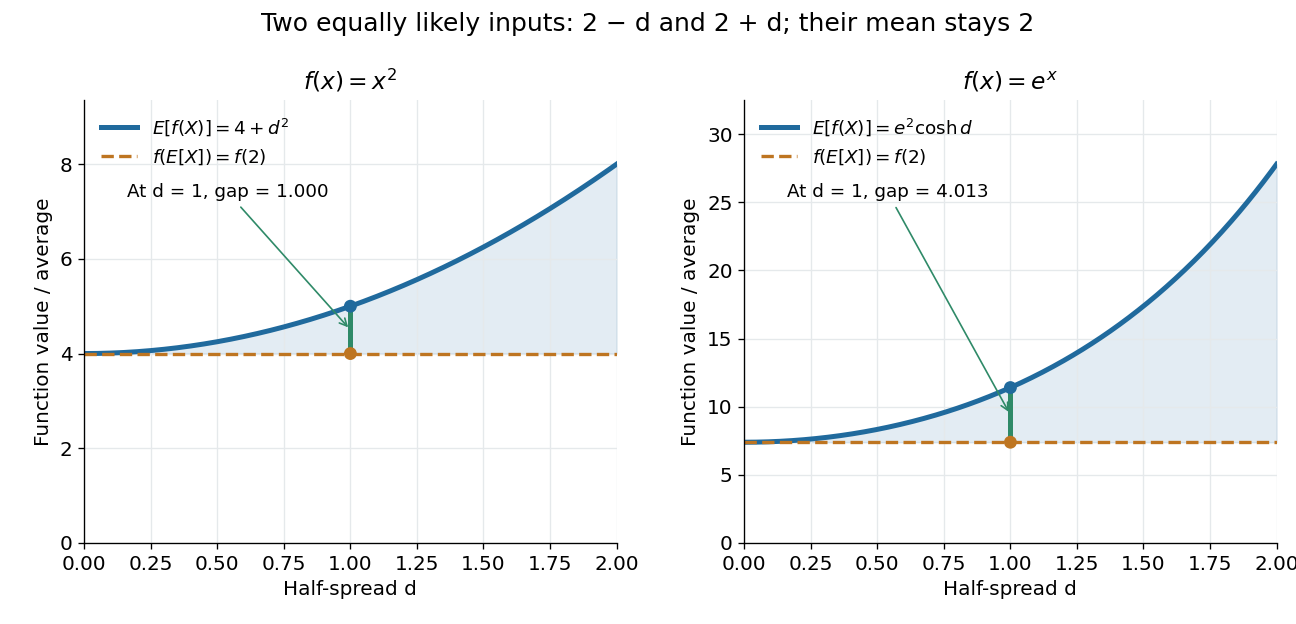
.For the quadratic function and a random variable with a finite second moment, the difference between the two sides is exactly its variance:Consider two equally likely values and . Their expected value stays at as increases, but their variance is . Thus the expected value of the square grows from to . For the exponential function, the same two-point distribution gives , while . Both are examples of Jensen's inequality, but their Jensen gaps depend differently on the spread of the inputs.
Another useful choice is the concave function on positive inputs. Its version of Jensen's inequality gives . Applying the increasing exponential function shows that the weighted geometric mean cannot exceed the weighted arithmetic mean. For the equally weighted inputs and , these are and . This recovers the arithmetic-geometric mean inequality and illustrates how choosing one function can generate an entire family of bounds.
A short proof idea explains the probabilistic form. If has a subgradient at , the supporting affine function gives . Taking the expected value cancels the linear term because . This argument applies, for example, to finite convex functions on ; more general domains of a function need attention to endpoints and the existence of a subgradient.
Johan Jensen's 1906 paper “Sur les fonctions convexes et les inégalités entre les valeurs moyennes” is an early source for the connection between convex functions and inequalities for means. [ref]
https://zenodo.org/records/2371297. Jensen's original article and publication record, DOI 10.1007/BF02418571
.For a real number , its absolute value is when and otherwise; for a complex number , it is the nonnegative magnitude .
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact