Counting sort uses integer sort keys in directly as indices into an array of counts. Constant-cost counting and indexing give time complexity in Big O notation. To retain complete sorting records, cumulative counts locate their output ranges; filling each range from its end while scanning the input backwards gives stable sorting. Emitting bare sort keys from counts would discard associated data. The term matters when the key range is large.[ref]
11.2 Counting Sort and Radix Sort. Open Data Structures: An Introduction by Pat Morin; Theorem 11.7 and stability
For an original worked example, take complete sorting records and possible integer sort keys:The letters label the associated data, and are never compared. Both input and output array indices start at zero, so their valid positions are ; the count array has array indices . Stable sorting must produceThe equal-sort key groups retain and in arrival order. Counting sort prefix ranges explain where those groups belong; stable record placement in counting sort explains how to fill them without losing that order or the complete sorting records.
For sorting records with integer sort keys in , where , let count the input occurrences of sort key . Define two prefix sums:The empty sum gives . Here are counts of sorting records. Exactly sorting records have smaller sort keys, so the output positions for sort key form the half-open integer intervalIts right endpoint is excluded: the last occupied array index is when .[ref]
11.2 Counting Sort and Radix Sort. Open Data Structures: An Introduction by Pat Morin; §11.2.1 Counting Sort, paragraphs after Figure 11.7: running sums count keys at most k and determine the output block
For the seven-sorting record example, the frequency array, inclusive cumulative count array, and start array areThus sort keys zero, one, two and three occupy the integer intervals , , and , respectively. In particular, the three sorting records with sort key two belong at array indices three, four and five. The inclusive cumulative count counts all six sorting records with sort keys at most two; six is the exclusive endpoint, not the final position of a sorting record with sort key two.
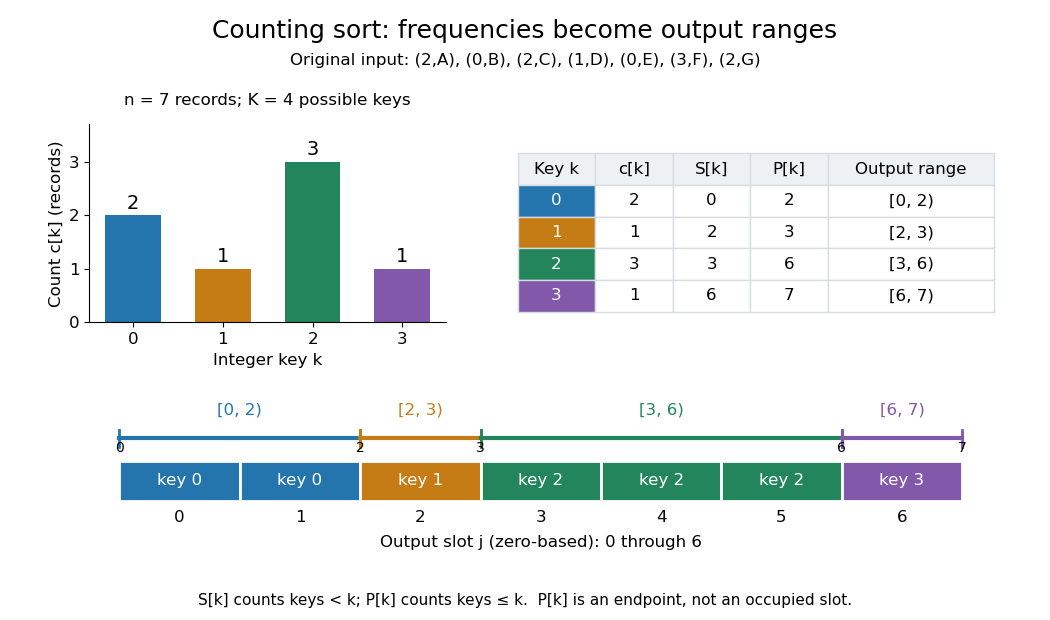
These integer intervals fit together because for , and . Their lengths add to , so they partition all output positions without overlaps or gaps. An absent sort key contributes an empty integer interval: with frequencies , the endpoints are and sort key two has range . For empty input, every count and endpoint is zero; every reserved integer interval is empty. This makes the same formulas cover missing sort keys and the empty case.
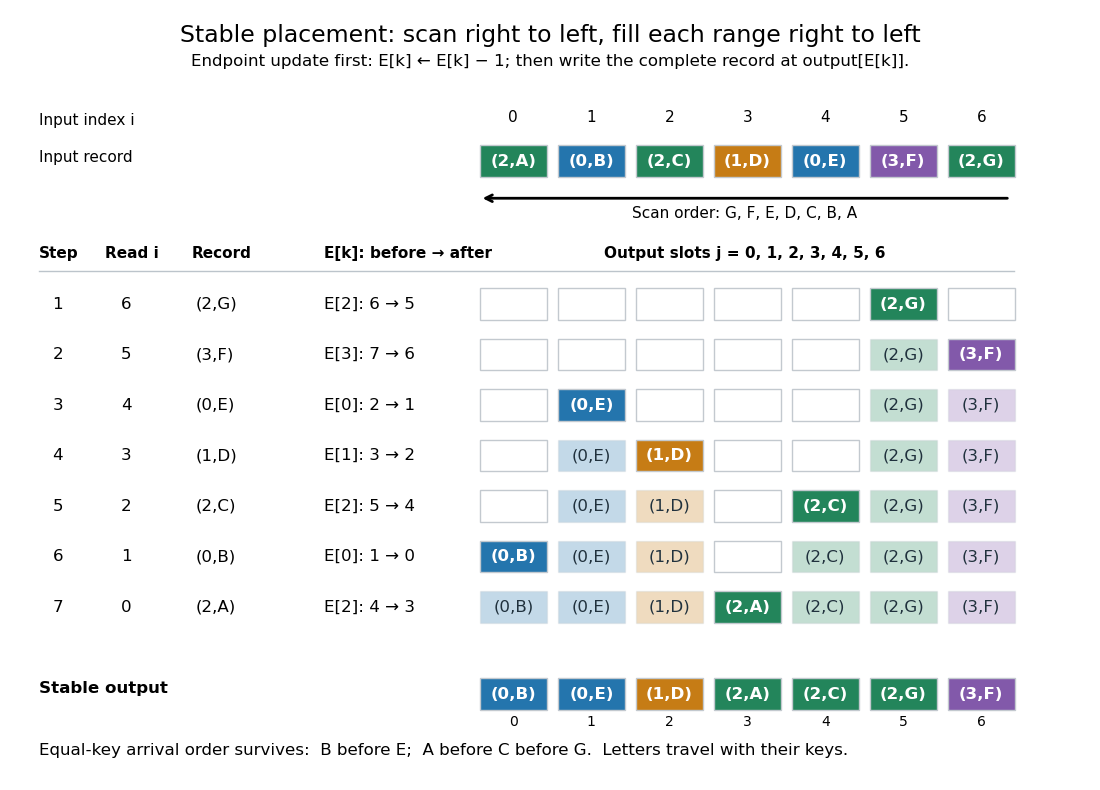
Initialize a mutable endpoint array to the inclusive cumulative counts . Scan input array indices . For each complete sorting record with sort key , first decrement , then write at output array index . This is equivalent to writing at the old endpoint minus one and then decrementing the endpoint.[ref]
11.2 Counting Sort and Radix Sort. Open Data Structures: An Introduction by Pat Morin; §11.2.1 Counting Sort, final scan paragraph and stability paragraph after Theorem 11.7
In the worked example, the first input sorting record read is at array index six. Its endpoint changes from to , so the complete sorting record goes to . Next, changes from seven to six and goes to . Writing before the decrement at the old endpoint would put outside its reserved integer interval and try to put beyond the output array. All seven writes are:Each endpoint changes only when a sorting record with its own sort key is placed. Consequently, stays at five through the placements of before dropping to four for .
Here is a complete implementation under the stated input contract; each sorting record is a pair whose first component is its integer sort key:
def counting_sort_records(records, K):
    end = [0] * K
    output = [None] * len(records)
    for key, data in records:
        end[key] += 1
    for key in range(1, K):
        end[key] += end[key - 1]
    for i in range(len(records) - 1, -1, -1):
        key = records[i][0]
        end[key] -= 1
        output[end[key]] = records[i]
    return output
The same array
end successively stores frequencies, inclusive cumulative counts, and moving exclusive endpoints; the formulas describe their mathematical values without requiring three stored arrays. The write copies the complete sorting record, including its associated data. In particular, two occurrences of an identical pair still cause two separate writes.For a short algorithm correctness proof, let be the number of already placed sorting records with sort key . A loop invariant isAll integer intervals here mean output array indices. Initially , so each whole reserved integer interval is unfilled. When the next sorting record has sort key , fewer than such occurrences have been placed, giving . Decrementing selects a fresh slot inside its reserved integer interval. At termination, and : every output slot has been filled exactly once with a complete input occurrence. The disjoint, increasing sort key ranges establish sortedness, while the fresh-slot property establishes sorting permutation preservation.
For stable sorting, take two input occurrences with equal sort keys at array indices . The backward scan visits first and puts it farther right in their shared integer interval. When is visited, the endpoint has decreased at least once, so its output position is smaller. Thus their original order survives. A forward scan with this same decrement rule reverses every equal-sort key group: it would put at positions five, four, three. A forward scan can instead be stable if it starts from and fills each integer interval left to right, incrementing after each write. The scan direction and endpoint convention must agree.
Count initialization takes writes, output initialization takes writes, counting takes updates, the prefix sum pass takes updates, and placement takes writes. Hence time complexity and auxiliary storage are in Big O notation, assuming constant-cost sort key access, integer arithmetic, array indexing and complete sorting record movement. Large records can instead be represented by constant-size references.[ref]
11.2 Counting Sort and Radix Sort. Open Data Structures: An Introduction by Pat Morin; §11.2.1 Counting Sort, auxiliary counter and output arrays, loop-cost discussion and Theorem 11.7
For example, three sorting records with sort keys zero, and zero require one million counters if ; unused sort keys still incur initialization and prefix sum work. The bound is therefore linear in the input length only when . Empty input skips the record scans, but this implementation still initializes counters and accumulates their prefix sums. For nonempty input, counting all records and filling their ranges gives a concrete termination argument.
Direct sort key indexing is a different operation from a binary comparison. The comparison sorting lower bound concerns comparison sorts; counting sort uses its restricted integer sort keys as array indices. Its small- speed is particularly useful for categorical numerical labels and for each stable sorting pass of radix sort: the reserved integer intervals turn group sizes into exact destinations.
Articles by others on the same topic



Counting sort is a non-comparison-based sorting algorithm that works by counting the occurrences of each distinct element in the input array. It is particularly efficient for sorting integers or objects that can be mapped to a finite range of integer keys. The basic idea is to determine the number of occurrences of each value in the input, and then use this information to place those values in their correct positions in the output array. ### How Counting Sort Works 1.