Solutions to all three questions of the examination dated 3 June 2015. The cover permits answers to two questions.[ref]
Use classical relational algebra with set semantics. Write for the paper's
Car, Sales, Customer and Salesperson database relations. A natural join between and matches serialnumber; joins involving a salesperson explicitly match salespersonid to empid. Identifiers, rather than names, distinguish customers and salespeople. The calculations use the ordinary non-null relational model; the SQL aggregate below also explains its empty-input behavior.First use relational selection to keep the Saab cars, then a natural join to find their sales, and finally a relational join to identify the corresponding salespeople. A relational projection givesThe foreign keys ensure that every sale has the referenced car and salesperson. Several qualifying sales by the same person produce just one occurrence of their name under set semantics. Two distinct people with the same name also yield that name only once: this is the requested relational projection onto names.
Construct the required models and the actual customer–model purchases using relational projection and a natural join:The Cartesian product lists every obligation: every customer paired with every model present in
Car. The relational difference consists of unfulfilled obligations. Remove the customer identifiers occurring in this database relation and only then recover names:This is an explicit relational division construction with all customers as the candidate universe. If there are no models, there are no missing obligations, so every customer qualifies. A version starting solely from customers occurring in would incorrectly omit customers with no purchases in that empty-model case.The quantified object here is the
model database attribute, so two makes sharing a model value contribute one required value. If a different application identified a model by the pair (make, model), both the required and purchased relational projections would use that pair. Also, Car contains unsold cars: a model available only in unsold inventory is still a required model, and then nobody qualifies. Testing identifiers before names prevents different customers with the same name from pooling their purchases.An arithmetic mean is database aggregation, which is outside classical relational algebra. Use SQL:For non-null prices of qualifying sales, the result isEach sale contributes once, even when a car was sold on several invoices. Do not use
SELECT AVG(s.price) AS average_sale_price
FROM Sales AS s
JOIN Car AS c ON c.serialnumber = s.serialnumber
WHERE c.make = 'Saab';DISTINCT inside AVG: two different sales at the same price must both count. The car's database primary key makes the relational join match each sale to exactly one car, so the relational join introduces no extra weighting.If there are no qualifying non-null prices,
AVG returns SQL NULL. It ignores null prices if the implementation permits them; it does not replace an absent arithmetic mean with zero.[ref]Aggregate Functions in the PostgreSQL documentation. Section 9.21,
avg and the paragraph on aggregates with no selected rowsThe right-hand relational projection lists the models of cars for which at least one recorded sale was made by a salesperson earning strictly more than . The outer relational difference removes precisely those models from all models present in
Car. Thus the answer isThis includes models with no sales at all, as well as models sold exclusively by salespeople whose salaries are at most . A model sold by both a low-paid salesperson and a high-paid salesperson is excluded. A salary exactly equal to does not trigger exclusion. These are model-level statements: one unsold car of a model does not rescue that model if a different car of the same model had a qualifying sale.Assume the two database queries have compatible output database attributes. ThenFor a finite input database, the result of the relational difference is a subset of the finite result of , so it is finite and introduces no new values. For the usual domain independence of a database query, let be the input database and let be two ambient value domains containing its data and the query constants. Database query safety givesand thereforeAlthough a domain relational calculus expression for the relational difference uses negation, its positive membership requirement in supplies the necessary range restriction. Negation is not by itself a reason for failure of database query safety.
Take a unary database relation and the positive domain relational calculus queryFor the finite input , every pair and belongs to , for every value in the ambient domain. On an infinite ambient domain the answer is infinite. Even if one compares only finite ambient domains, adding a fresh value changes the answer while leaving fixed, violating domain independence of a database query.
The logical disjunction leaves unrestricted in its first branch and unrestricted in its second branch. Thus both variables occur in relational atoms somewhere in the formula, yet database query safety still fails. No negation or implication symbol occurs.
Find the salesperson identifiers satisfying each price condition using relational selection and relational projection:Intersect these identifier sets, relational join the result to the salesperson records, and apply relational projection to names:If intersection is not a primitive of the chosen relational algebra, use with relational difference. There is no need to access
Car: the foreign key already ensures that every sale refers to a car.Intersecting names instead of identifiers is wrong. Two different salespeople called Alex, one making only sales and the other only sales, would make Alex appear in both name sets although neither person satisfies the condition. Nor can one sale satisfy both price tests: the two distinct prices require distinct sale records.
A simple valid database query plan uses a block nested-loop join with the salesperson records on the outside, checking both sale conditions during the same inner scan. It avoids materializing the potentially much larger set of matching sale pairs.
- Read a block of salesperson records. Retain each
empid, its name, and two initially false flags, one for each target price. - Scan all of
Sales. Apply relational selection to disregard other prices. For each retained sale, matchsalespersonidagainst the identifiers in the current outer block, and set the corresponding price flag. Several matching sales only set the same flag again. - After the inner scan, output the names of outer records with both flags true. Repeat for the next outer block, then eliminate repeated names to implement set semantics.
Let be the actual number of salesperson data pages and the number of outer data pages that fit along with the flags and working buffers. With the usual convention of outer pages, one inner input page and one output page, take for . If flag storage requires an extra reserved page, reduce accordingly. The number of outer records is at most , and there are outer blocks. Every such block requires a complete scan of the sales data pages.
Count a database page read or write as one I/O. Conservatively charge to locate the first salesperson leaf and to locate the start of each inner scan; this permits a small double charge if a definition of height includes a data leaf. The estimated read cost isIn the common convention that scan startup and cached internal pages are ignored, the usual upper estimate isFor an empty outer input there are no inner scans. This database query plan requires neither a sorted sale input nor a price index. In particular, the clustered database index on
invoiceno cannot locate records by price. The quantities and describe the amount of qualifying data; they do not justify replacing a complete scan cost by . They can bound the retained work within each scan by roughly sale records, if those page counts describe packed qualifying records. Comparison cost against the outer block is CPU work rather than additional I/O.Finally let be the extra I/O for eliminating repeated output names, including any temporary writes and reads, and let be the final result size in database pages if materialization is required. The total estimate isIf enough additional memory is available to retain all distinct qualifying names while producing the stream, then . This extra memory is an additional assumption, separate from the join buffers. More generally, for pages of raw qualifying names, external merge sort gives for , including spooling. Names can be deduplicated during the merges. Counting this work matters because a database primary key on
empid does not make names unique. No claim of optimality is needed for this database query plan.Use fan-out four to mean at most four child pointers per internal node. A height increase requires a B+ tree node split at the root. Immediately after that B+ tree node split, the new root has exactly two children.
One further insertion follows one search path. Any chain of B+ tree node splits along that path can pass at most one additional separator and child pointer to the root. Its number of children therefore rises from two to at most three, below the maximum four. ThusThe argument includes an initially leaf-only B+ tree: its first root split likewise creates a root with two children. Even if the next insertion causes a child split immediately, the new root still has room. The conclusion assumes the standard insertion operation with one overflowing node split into two; it does not depend on whether height counts edges or levels.
A serial database schedule is obtained by running the three database transactions in the order :A genuinely interleaved conflict-serializable database schedule with the same serial order isThe early conflicts with nothing: all accesses to are reads. The conflicts on give edges , and in the database precedence graph, while the writes to give the already present edge . This database precedence graph has no directed cycle and admits the order . Moving the early after swaps it only past non-conflicting operations, recovering the displayed serial database schedule.
For a database schedule that is not a conflict-serializable database schedule, takeOn , before forces . On , before forces . The resulting directed cycle prevents any serial ordering from preserving all conflicts. Each of the three displayed database schedules preserves the operation order inside every database transaction.
Use an entity-relationship model with
Customer, Conference, Event, Venue and Building. The following entity-relationship diagram uses minimum–maximum cardinalities at each end: the label beside an entity counts how many instances of that entity can be associated with one instance at the opposite end. A double link into the specialization circle means total specialization; its d means disjoint.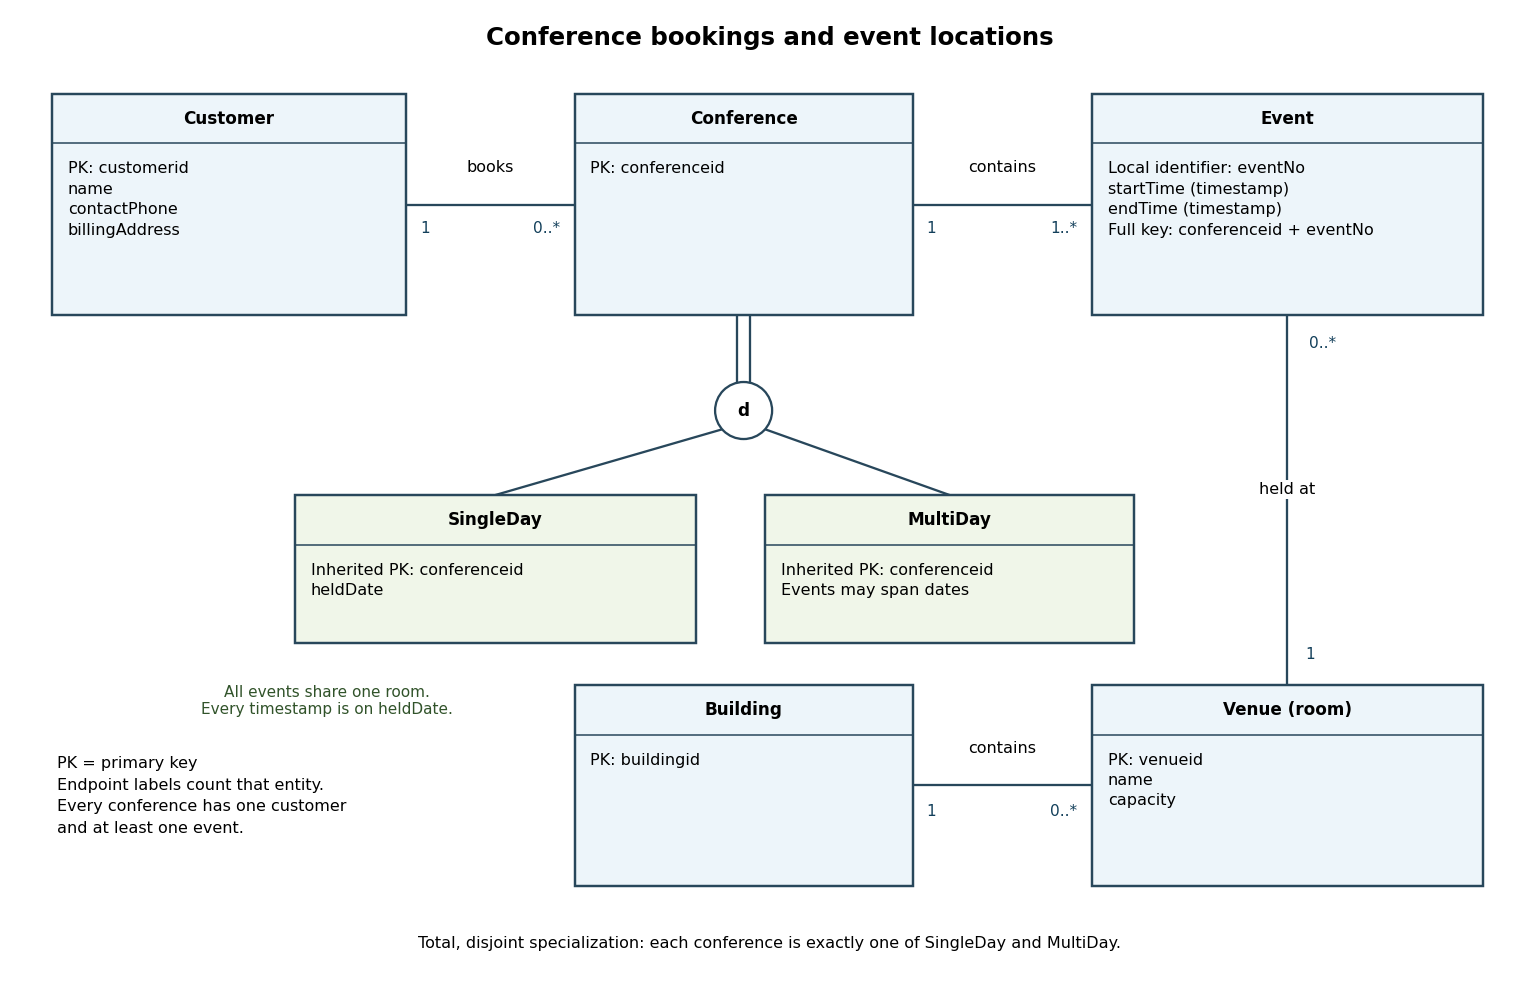

Every conference belongs to exactly one customer and contains at least one event. A customer may book zero or more conferences. Every event belongs to exactly one conference and occurs at exactly one venue; a venue may host zero or more events. The event identifier is local to its conference, so its full candidate key is
(conferenceid, eventNo). Choosing an event number is an explicit additional identifier assumption; a globally unique event identifier would be another valid design.Every conference is exactly one of the two entity subtypes,
SingleDay and MultiDay. Both inherit the conference identifier and the customer and event relationships. For SingleDay, store heldDate, and enforceThese cross-event database integrity constraints accompany the diagram; simple endpoint cardinalities alone cannot express them. Since there is at least one event, their common venue determines the conference's single room.For this design, a venue is a room with the given identifier, name and capacity, and each room belongs to exactly one building. A building may contain zero or more rooms. Introducing
Building and its identifier is an explicit modeling choice that makes the single-building requirement enforceable: one common room implies one common building. If an application also used non-room venues, it could instead introduce a room entity subtype and restrict SingleDay events to it.The start and end values are full timestamps, not times of day alone, and each event has .
MultiDay events may use different dates and rooms; the design does not force every pair of events to use different rooms or dates. It imposes no uniqueness of customer names, no venue-exclusivity rule, and no attendance–capacity rule because no attendance data are supplied. Such extra scheduling restrictions could be added as further database integrity constraints without altering the basic entity-relationship model.Abbreviate the database attributes by for
EventId, ConfId, BuildingId, StartTime, EndTime and ConfOrganizer. Write for the full relational schema.The explicit event assumptions give the functional dependencyI additionally interpret the conference's organizer as a single organizer for the whole conference, giving . This is the natural reading of
ConfOrganizer, but it is stronger than saying only that each event has one organizer. Under this interpretation a compact generating basis of functional dependencies isThere is no premise that an EventId is globally unique, that a conference has one building, or that a start time determines an end time. In particular, the single-room requirement for one subtype in part (a) must not be imposed on this entire database relation.To specify all non-trivial functional dependencies without listing every augmented version, the attribute closure isExactly the functional dependencies with and are non-trivial consequences of the assumptions. In particular, is the only candidate key: both and must be present because neither is generated from other database attributes.
Every functional dependency implies the corresponding multivalued dependency. Thus and, by complementation, hold. Also holds for every , with the usual trivial cases omitted. A complete compact description, including all augmented and complemented cases, isFor a non-trivial multivalued dependency, additionally require and . To see the criterion, if either side of the split is determined by , swapping that side requires no new database tuple. Conversely, if both sides contain a database attribute outside , choose two database tuples agreeing exactly on . They satisfy every functional dependency in , but a mixed database tuple required by the proposed multivalued dependency is neither of them. The two-row database relation is therefore a counterexample.
There is no independent many-valued fact such as buildings freely combining with event times. For example, two events of one conference might have and . A multivalued dependency would require the building to be swappable independently of the event and its times, which these assumptions do not require and the event functional dependency may forbid.
Since is not a superkey, violates Boyce-Codd normal form. The corresponding non-trivial multivalued dependency violates fourth normal form. Use the decompositionTheir common database attribute is , which determines the whole first component. Consequently the decomposition is a lossless-join decomposition: each event joins to exactly its own conference's organizer, producing no spurious database tuples.
In the first component, the only basic non-trivial functional dependency is , whose determinant is a candidate key. In the second it is , again with a candidate key determinant. No independent non-trivial multivalued dependencies with determinants that are not superkeys are implied in either component, so both are in fourth normal form, and therefore in Boyce-Codd normal form. This reaches the strongest normal form tested here. The decomposition is a dependency-preserving decomposition: is enforced in the first component, in the second, and together they imply .
If only the explicitly stated event-level organizer uniqueness is assumed, omit . The basis is then just ; when and otherwise. Under those weaker assumptions the original database relation is already in fourth normal form and Boyce-Codd normal form, so no decomposition is necessary. In particular, separating under that reading could create extra database tuples when different events of one conference have different organizers.
Take the relational schema and functional dependencyThe attribute closure of is , so is a candidate key. The attribute closure of is just , so it is not a superkey. The set is a superkey but is not a candidate key, because removing leaves the superkey . Thus the only candidate key is , and occurs in none.
For example, records illustrate that the same value may occur at different values. The conclusion about candidate keys follows from the declared functional dependencies, rather than from accidental uniqueness in any one sample.
Let contain the database attributes of , and let contain the given functional dependencies for . To compute the attribute closure , start with and repeatedly add for every functional dependency with , stopping when a full scan adds nothing.
Enumerate every . For each, test whether is not a superkey but becomes one on adding :If no enumerated passes both tests, return no. A direct implementation isIf a candidate key contains , choose . Minimality makes fail the superkey test while passes it, so the algorithm finds a witness.
for each subset X of attributes(R) minus {a}:
    if closure(X, F) != attributes(R):
        if closure(X union {a}, F) == attributes(R):
            return yes
return noConversely, suppose an enumerated passes. Starting from , repeatedly discard any database attribute other than whose removal preserves the superkey property. The process terminates at a superkey minimal with respect to these deletions. Removing cannot leave a superkey: , and a subset of , which is not a superkey, cannot determine more database attributes than . Hence is a candidate key containing . The algorithm need not carry out this minimization to return the correct yes/no answer; it establishes why the witness test suffices.
For an explicit analysis of algorithms, let be the total encoded length of the functional dependencies, counting their left and right database attribute occurrences and delimiters. With Boolean membership arrays, one complete dependency scan costs . There are at most productive scans, followed by one unproductive scan, so a naive attribute closure costs . There are subsets and at most two attribute closure computations per subset. ThusThis is an exponential-time algorithm in the number of database attributes, not a polynomial-time claim. Subsets can be generated successively rather than stored all at once. The argument applies to functional dependencies within the database relation ; dependencies belonging to unrelated database relations do not constrain its candidate keys.
Articles by others on the same topic
There are currently no matching articles.