Topics (119k) Articles (119k) Users (302) Discussions (245) Comments (383) Files (707) New article
Manual: www.tp-link.com/uk/support/download/archer-vr2800/ In particular, the user guide: static.tp-link.com/1910012125_Archer%20VR2800(EU)_V1_UG.pdf
Admin IP address: 192.168.1.1/ It also works over Wifi and people don't know how to disable that: community.tp-link.com/en/home/forum/topic/1460
JAR, SWF and CGI-bin scanning by path only is fine, since there are relatively few of those. But .js scanning by path only is too broad.
One option would be to filter out by size, an information that is contained on the CDX. Let's check typical ones:Ignoring some obvious unrelated non-comms files visually we get a range of about 2732 to 3632:This ignores the obviously atypical JavaScript with SHAs from iranfootballsource, and the particularly small old menu.js from cutabovenews.com, which we embed into ../cia-2010-covert-communication-websites/cdx-post-js.sh.
grep -f <(jq -r '.[]|select(select(.comms)|.comms|test("\\.js"))|.host' ../media/cia-2010-covert-communication-websites/hits.json) out | out.jshits.cdx
sort -n -k7 out.jshits.cdxnet,hollywoodscreen)/current.js 20110106082232 http://hollywoodscreen.net/current.js text/javascript 200 XY5NHVW7UMFS3WSKPXLOQ5DJA34POXMV 2732
com,amishkanews)/amishkanewss.js 20110208032713 http://amishkanews.com/amishkanewss.js text/javascript 200 S5ZWJ53JFSLUSJVXBBA3NBJXNYLNCI4E 3632 CIA 2010 covert communication websites Wayback Machine CDX scanning with Tor parallelization by  Ciro Santilli 40 Updated 2025-07-16
Dire times require dire methods: ../cia-2010-covert-communication-websites/cdx-tor.sh.
First we must start the tor servers with the and then use it on a newline separated domain name list to check;This creates a directory
tor-army command from: stackoverflow.com/questions/14321214/how-to-run-multiple-tor-processes-at-once-with-different-exit-ips/76749983#76749983tor-army 100./cdx-tor.sh infile.txtinfile.txt.cdx/ containing:infile.txt.cdx/out00,out01, etc.: the suspected CDX lines from domains from each tor instance based on the simple criteria that the CDX can handle directly. We split the input domains into 100 piles, and give one selected pile per tor instance.infile.txt.cdx/out: the final combined CDX output ofout00,out01, ...infile.txt.cdx/out.post: the final output containing only domain names that match further CLI criteria that cannot be easily encoded on the CDX query. This is the cleanest domain name list you should look into at the end basically.
Since archive is so abysmal in its data access, e.g. a Google BigQuery would solve our issues in seconds, we have to come up with creative ways of getting around their IP throttling.
Distilled into an answer at: stackoverflow.com/questions/14321214/how-to-run-multiple-tor-processes-at-once-with-different-exit-ips/76749983#76749983
This should allow a full sweep of the 4.5M records in 2013 DNS Census virtual host cleanup in a reasonable amount of time. After JAR/SWF/CGI filtering we obtained 5.8k domains, so a reduction factor of about 1 million with likely very few losses. Not bad.
5.8k is still a bit annoying to fully go over however, so we can also try to count CDX hits to the domains and remove anything with too many hits, since the CIA websites basically have very few archives:This gives us something like:sorted by increasing hit counts, so we can go down as far as patience allows for!
cd 2013-dns-census-a-novirt-domains.txt.cdx
./cdx-tor.sh -d out.post domain-list.txt
cd out.post.cdx
cut -d' ' -f1 out | uniq -c | sort -k1 -n | awk 'match($2, /([^,]+),([^)]+)/, a) {printf("%s.%s %d\n", a[2], a[1], $1)}' > out.count12654montana.com 1
aeronet-news.com 1
atohms.com 1
av3net.com 1
beechstreetas400.com 1- 2023 vimalabs.github.io/ VIMA: General Robot Manipulation with Multimodal Prompts
echo '[{"a": 1, "b": 2}, {"b": 3}]' | jq '.[] | select(.a) | .a'1They didn't care about MLperf as of 2019: www.zdnet.com/article/cerebras-did-not-spend-one-minute-working-on-mlperf-says-ceo/
- 2023: www.eetimes.com/cerebras-sells-100-million-ai-supercomputer-plans-8-more/ Cerebras Sells $100 Million AI Supercomputer, Plans Eight More

Yet another awk-like domain-specific language to do things from the CLI in a ridiculously short humber of character? Oh yes.
The website was dead as of February 2025. Last archive: web.archive.org/web/20240418004442/http://www.themathgenome.com/ Pings:They were seeking help on May 2024:
so its likely the followup death. LinkedIn post gives basic stack: MERN stack, Heroku, Supabase/MongoDB Atlas.
A discussion on the Lean Zulip: leanprover.zulipchat.com/#narrow/stream/113488-general/topic/The.20Math.20Genome.20Project/near/352639129. Lean people are not convinced about the model in general it seems however.
TODO not viewable without login?
Has conjectures feature.
Built by this dude John Mercer:He must be independently wealthy or something to do such a project? What a hero. But he seems to have jobs. On the side? Hardcore.
Ciro Santilli asked: discord.com/channels/1096393420408360989/1096393420408360996/1137047842159079474Owner:So apparently there will be proof checking, but no dependencies between proofs, you still have to pull request everything back and face the pain.
Does the website actually automatically check the formal proofs, or is this intended to be implemented at some point? And if yes, is it intended to allow proofs to depend on other proofs of the website (possibly by other people)
Hi Ciro, yes we will be releasing in-browser proof assistant environments/checkers (e.g. Lean). Our goal is not to replace the underlying open-source repos (e.g. Mathlib) so the main dependency will be on the current repos; then when statement formalizations and proofs come in and are certified they can be PR'd to the respective repos. So we will be the source of truth for the informal latex code but only a stepping stone and orchestration layer on the way to the respective formal libraries.
Bibliography:
A more verbose description of this at: Section "Website front-end for a mathematical formal proof system".
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.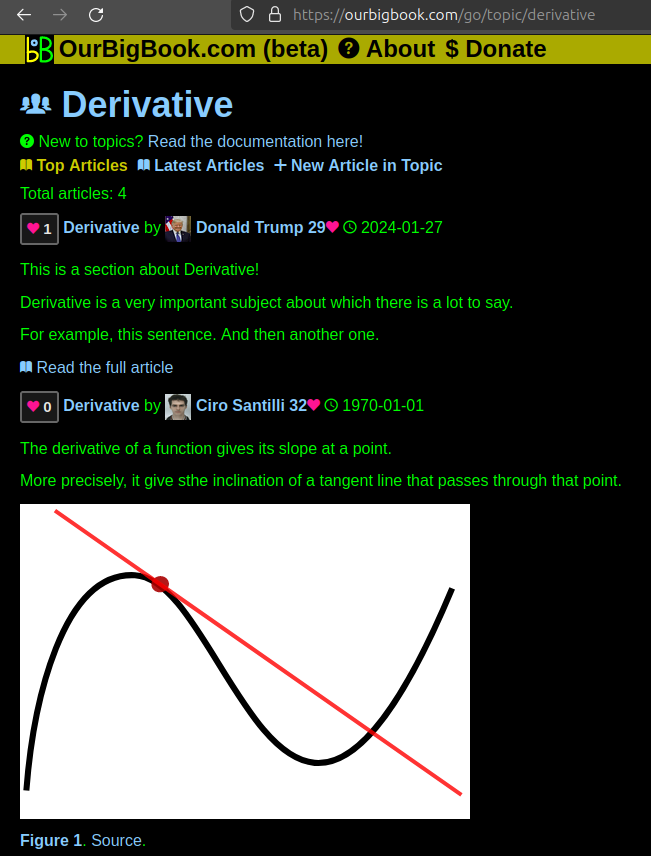
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
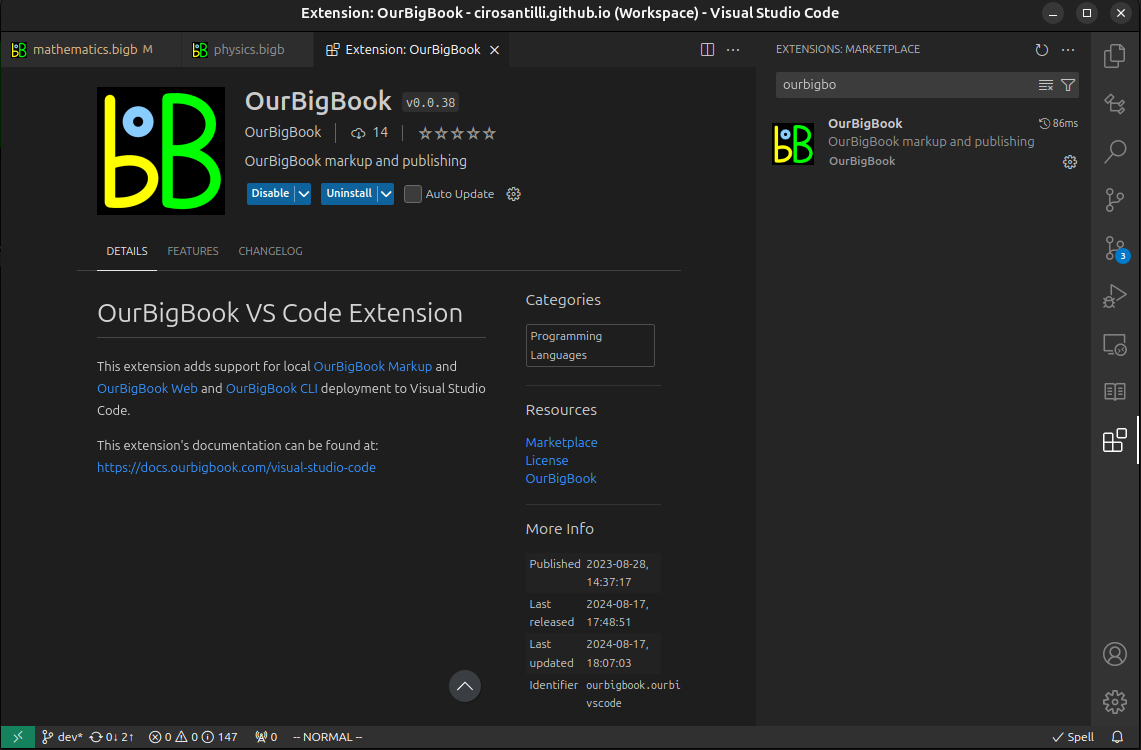
Figure 3. Visual Studio Code extension installation.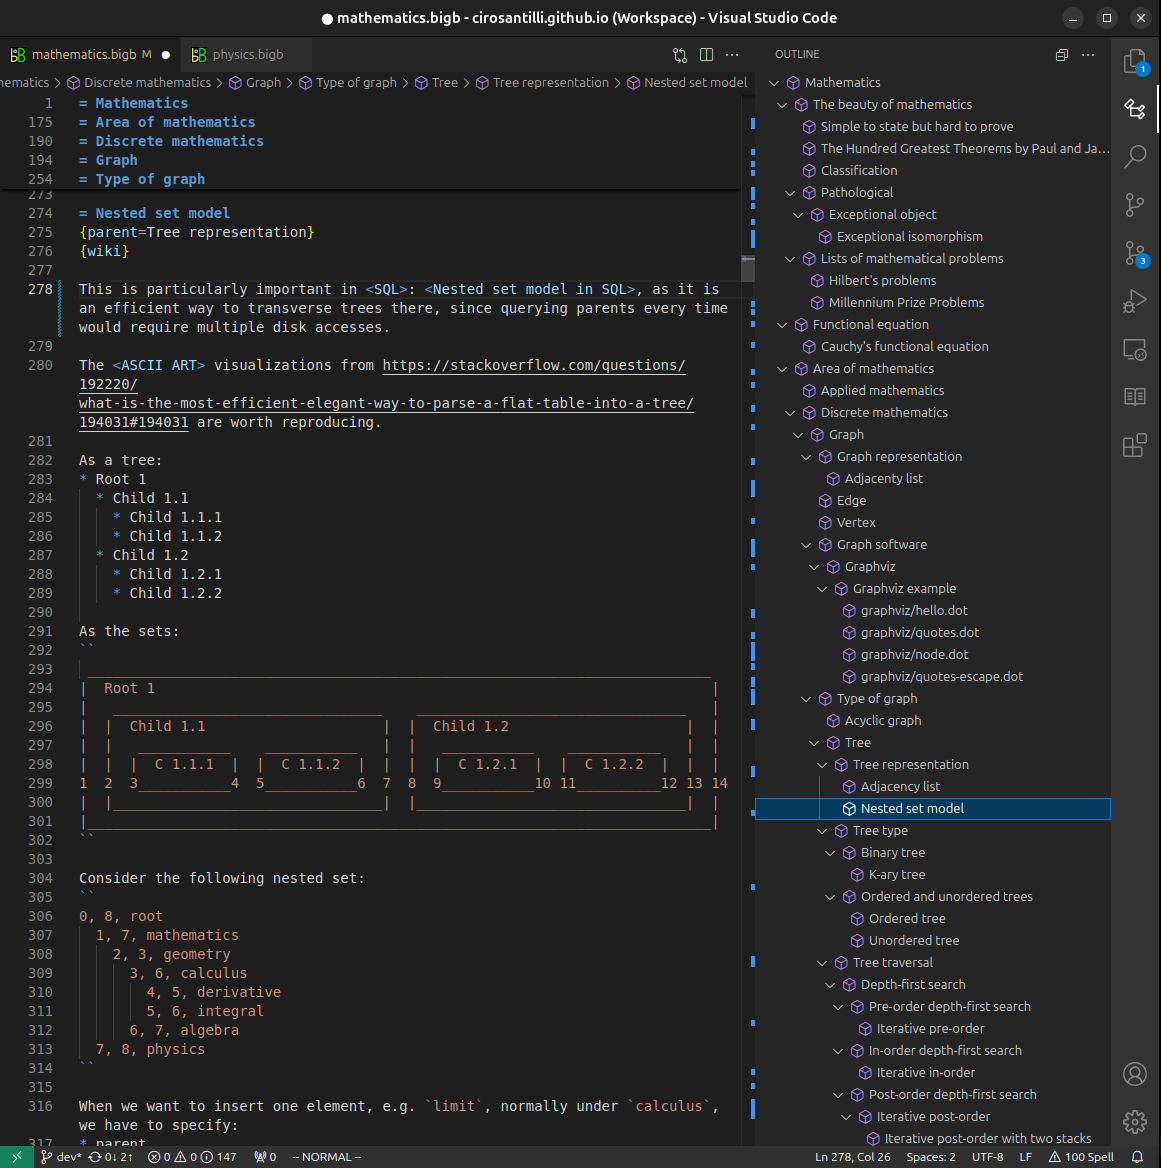
Figure 4. Visual Studio Code extension tree navigation.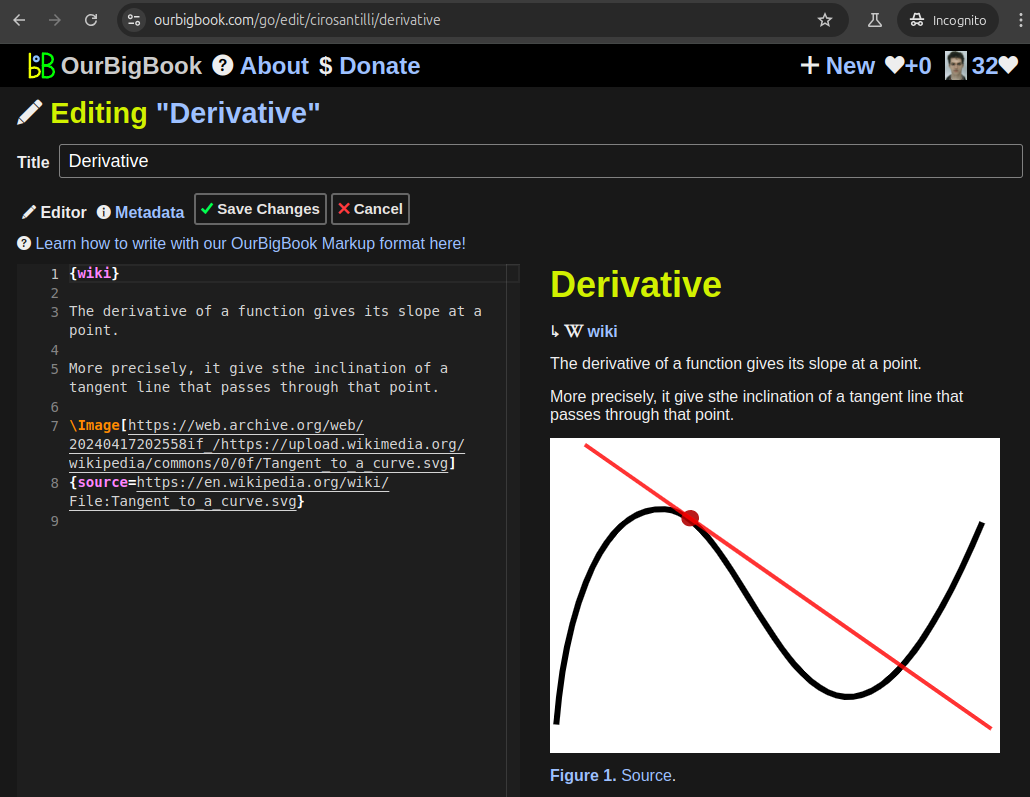
Figure 5. Web editor. You can also edit articles on the Web editor without installing anything locally.Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension.Video 4. OurBigBook Visual Studio Code extension editing and navigation demo. Source. 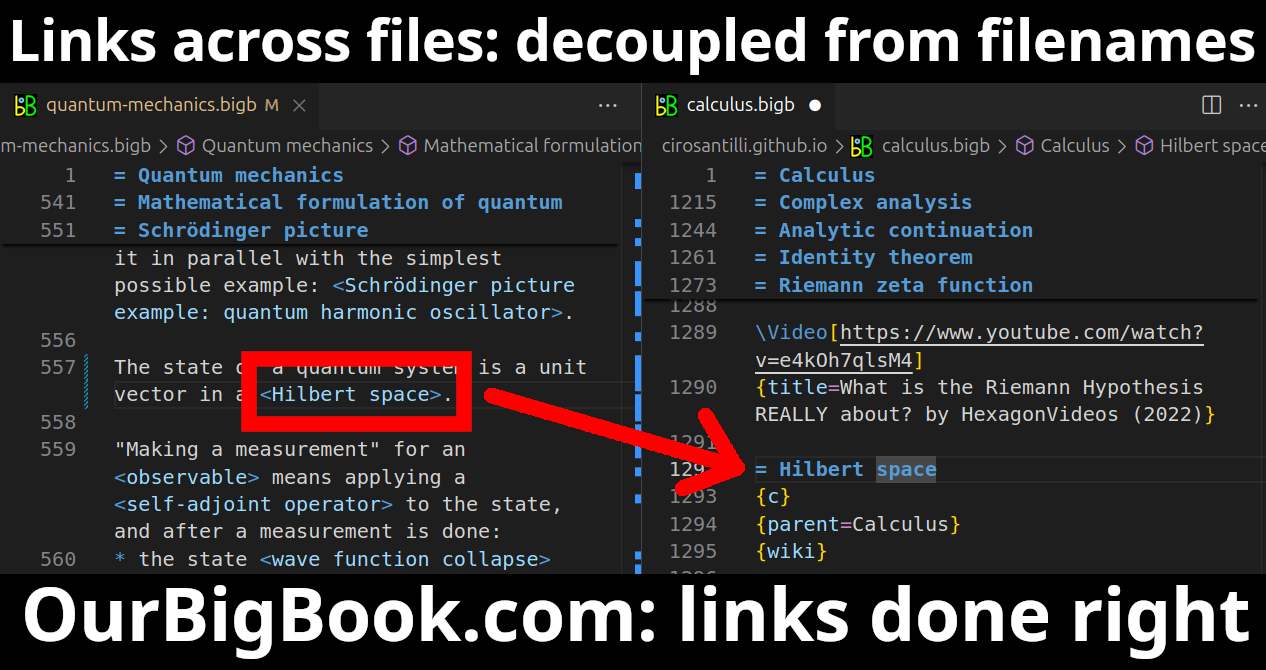
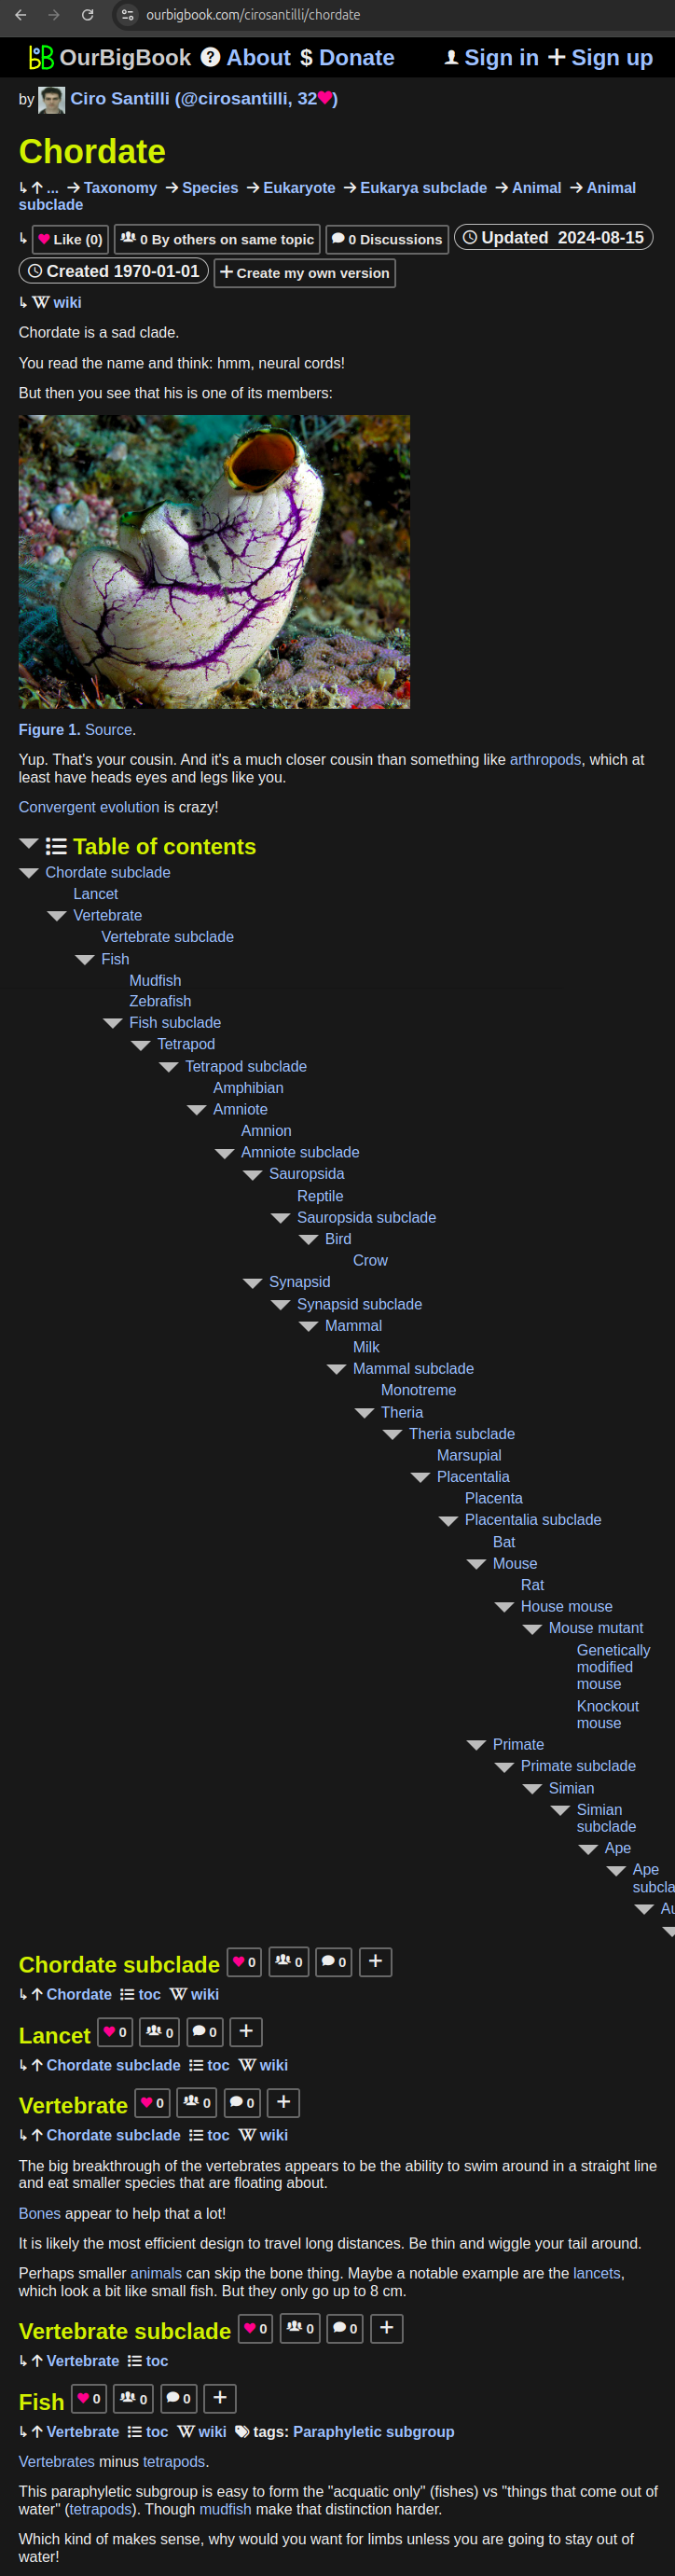
- Infinitely deep tables of contents:

All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact