When TLB is filled up, older addresses are overwritten. Just like CPU cache, the replacement policy is a potentially complex operation, but a simple and reasonable heuristic is to remove the least recently used entry (LRU).
With LRU, starting from state:adding
  valid  linear  physical
  -----  ------  --------
> 1      00003   00005
  1      00007   00009
  1      00009   00001
1 0000B 000030000D -> 0000A would give: valid linear physical
----- ------ --------
1 0000D 0000A
> 1 00007 00009
1 00009 00001
1 0000B 00003Using the TLB makes translation faster, because the initial translation takes one access per TLB level, which means 2 on a simple 32 bit scheme, but 3 or 4 on 64 bit architectures.
The TLB is usually implemented as an expensive type of RAM called content-addressable memory (CAM). CAM implements an associative map on hardware, that is, a structure that given a key (linear address), retrieves a value.
Mappings could also be implemented on RAM addresses, but CAM mappings may required much less entries than a RAM mapping.
linear  physical
------  --------
00000   00001
00001   00010
00010   00011
FFFFF 00000When the process changes,
cr3 change to point to the page table of the new current process.A simple and naive solution would be to completely invalidate the TLB whenever the
cr3 changes.However, this is would not be very efficient, because it often happens that we switch back to process 1 before process 2 has completely used up the entire TLB cache entries.
The solution for this is to use so called "Address Space Identifiers" (ASID) as mentioned in sources such as:
Basically, the OS assigns a different ASID for each process, and then TLB entries are automatically also tagged with that ASID. This way when the process makes an access, the TLB can determine if a hit is actually for the current process, or if it is an old address coincidence with another process.
Information about ARM paging can be found at: cirosantilli.com/linux-kernel-module-cheat#arm-paging
Convert virtual addresses to physical from user space with
/proc/<pid>/pagemap and from kernel space with virt_to_phys:Dump all page tables from userspace with
/proc/<pid>/maps and /proc/<pid>/pagemap:Read and write physical addresses from userspace with
/dev/mem:The Linux Kernel reserves two zones of virtual memory:
- one for kernel memory
- one for programs
The exact split is configured by
CONFIG_VMSPLIT_.... By default:- on 32-bit:
- on 64-bit: currently only 48-bits are actually used, split into two equally sized disjoint spaces. The Linux kernel just assigns:
- the bottom part to processes
00000000 00000000to008FFFFF FFFFFFFF - the top part to the kernel:
FFFF8000 00000000toFFFFFFFF FFFFFFFF, like this:------------------ FFFFFFFF Kernel ------------------ C0000000 (not addressable) ------------------ BFFFFFFF Process ------------------ 00000000
- the bottom part to processes
Kernel memory is also paged.
In previous versions, the paging was continuous, but with HIGHMEM this changed.
There is no clear physical memory split: stackoverflow.com/questions/30471742/physical-memory-userspace-kernel-split-on-linux-x86-64
For each process, the virtual address space looks like this:
------------------ 2^32 - 1
Stack (grows down)
v v v v v v v v v
------------------

(unmapped)

------------------ Maximum stack size.


(unmapped)


-------------------
mmap
-------------------


(unmapped)


-------------------
^^^^^^^^^^^^^^^^^^^
brk (grows up)
-------------------
BSS
-------------------
Data
-------------------
Text
-------------------

------------------- 0
The kernel maintains a list of pages that belong to each process, and synchronizes that with the paging.
If the program accesses memory that does not belong to it, the kernel handles a page-fault, and decides what to do:
When an ELF file is loaded by the kernel to start a program with the
exec system call, the kernel automatically registers text, data, BSS and stack for the program.The
brk and mmap areas can be modified by request of the program through the brk and mmap system calls. But the kernel can also deny the program those areas if there is not enough memory.brk and mmap can be used to implement malloc, or the so called "heap".mmap is also used to load dynamically loaded libraries into the program's memory so that it can access and run it.Stack allocation: stackoverflow.com/questions/17671423/stack-allocation-for-process
Calculating exact addresses Things are complicated by:
- Address Space Layout Randomization.
- the fact that environment variables, CLI arguments, and some ELF header data take up initial stack space: unix.stackexchange.com/questions/145557/how-does-stack-allocation-work-in-linux/239323#239323
Why the text does not start at 0: stackoverflow.com/questions/14795164/why-do-linux-program-text-sections-start-at-0x0804800-and-stack-tops-start-at-0
Those page faults only happen when a process tries to write to the page, and not read from it.
When Linux forks a process:
- instead of copying all the pages, which is unnecessarily costly, it makes the page tables of the two process point to the same physical address.
- it marks those linear addresses as read-only
- whenever one of the processes tries to write to a page, the makes a copy of the physical memory, and updates the pages of the two process to point to the two different physical addresses
In
v4.2, look under arch/x86/:include/asm/pgtable*include/asm/page*mm/pgtable*mm/page*
There seems to be no structs defined to represent the pages, only macros:
include/asm/page_types.h is specially interesting. Excerpt:#define _PAGE_BIT_PRESENT 0 /* is present */
#define _PAGE_BIT_RW 1 /* writeable */
#define _PAGE_BIT_USER 2 /* userspace addressable */
#define _PAGE_BIT_PWT 3 /* page write through */ x86 Paging Tutorial Single level paging scheme visualization by  Ciro Santilli 40 Updated 2025-07-16
This is how the memory could look like in a single level paging scheme:
Links   Data                    Physical address

      +-----------------------+ 2^32 - 1
      |                       |
      .                       .
      |                       |
      +-----------------------+ page0 + 4k
      | data of page 0        |
+---->+-----------------------+ page0
|     |                       |
|     .                       .
|     |                       |
|     +-----------------------+ pageN + 4k
|     | data of page N        |
|  +->+-----------------------+ pageN
|  |  |                       |
|  |  .                       .
|  |  |                       |
|  |  +-----------------------+ CR3 + 2^20 * 4
|  +--| entry[2^20-1] = pageN |
|     +-----------------------+ CR3 + 2^20 - 1 * 4
|     |                       |
|     .    many entires       .
|     |                       |
|     +-----------------------+ CR3 + 2 * 4
|  +--| entry[1] = page1      |
|  |  +-----------------------+ CR3 + 1 * 4
+-----| entry[0] = page0      |
   |  +-----------------------+ <--- CR3
   |  |                       |
   |  .                       .
   |  |                       |
   |  +-----------------------+ page1 + 4k
   |  | data of page 1        |
   +->+-----------------------+ page1
      |                       |
      .                       .
      |                       |
      +-----------------------+  0
Notice that:
- the CR3 register points to the first entry of the page table
- the page table is just a large array with 2^20 page table entries
- each entry is 4 bytes big, so the array takes up 4 MiB
- each page table contains the physical address a page
- each page is a 4 KiB aligned 4 KiB chunk of memory that user processes may use
- we have 2^20 table entries. Since each page is 4 KiB == 2^12, this covers the whole 4 GiB (2^32) of 32-bit memory
x86 Paging Tutorial Single level paging scheme numerical translation example by Ciro Santilli 40 Updated 2026-10-19
Ciro Santilli 40 Updated 2026-10-19Suppose that the OS has setup the following page tables for process 1:and for process 2:
entry index   entry address       page address   present
-----------   ------------------  ------------   -------
0             CR3_1 + 0      * 4  0x00001        1
1             CR3_1 + 1      * 4  0x00000        1
2             CR3_1 + 2      * 4  0x00003        1
3             CR3_1 + 3      * 4                 0
...
2^20-1 CR3_1 + 2^20-1 * 4 0x00005 1entry index entry address page address present
----------- ----------------- ------------ -------
0 CR3_2 + 0 * 4 0x0000A 1
1 CR3_2 + 1 * 4 0x12345 1
2 CR3_2 + 2 * 4 0
3 CR3_2 + 3 * 4 0x00003 1
...
2^20-1 CR3_2 + 2^20-1 * 4 0xFFFFF 1When process 1 tries to access a linear address, this is the physical addresses that will be actually accessed:
linear     physical
---------  ---------
00000 001  00001 001
00000 002  00001 002
00000 003  00001 003
00000 FFF  00001 FFF
00001 000  00000 000
00001 001  00000 001
00001 FFF  00000 FFF
00002 000  00003 000
FFFFF 000  00005 000
To switch to process 2, the OS simply sets
cr3 to CR3_2, and now the following translations would happen:linear physical
--------- ---------
00000 002 0000A 002
00000 003 0000A 003
00000 FFF 0000A FFF
00001 000 12345 000
00001 001 12345 001
00001 FFF 12345 FFF
00004 000 00003 000
FFFFF 000 FFFFF 000Step-by-step translation for process 1 of logical address
0x00000001 to physical address 0x00001001:- split the linear address into two parts:
| page (20 bits) | offset (12 bits) | - look into Page table 1 because
cr3points to it. - The hardware knows that this entry is located at RAM address
CR3 + 0x00000 * 4 = CR3:
*0x00000because the page part of the logical address is0x00000
*4because that is the fixed size in bytes of every page table entry - since it is present, the access is valid
- by the page table, the location of page number
0x00000is at0x00001 * 4K = 0x00001000. - to find the final physical address we just need to add the offset:
00001 000 + 00000 001 --------- 00001 001The offset is always simply added the physical address of the page. - the hardware then gets the memory at that physical location and puts it in a register.
Another example: for logical address
0x00001001:- the page part is
00001, and the offset part is001 - the hardware knows that its page table entry is located at RAM address:
CR3 + 1 * 4(1because of the page part), and that is where it will look for it - it finds the page address
0x00000there - so the final address is
0x00000 * 4k + 0x001 = 0x00000001
x86 Paging Tutorial Multiple addresses translate to a single physical address by Ciro Santilli 40 Updated 2025-07-16
Ciro Santilli 40 Updated 2025-07-16The same linear address can translate to different physical addresses for different processes, depending only on the value inside
cr3.Both linear addresses
00002 000 from process 1 and 00004 000 from process 2 point to the same physical address 00003 000. This is completely allowed by the hardware, and it is up to the operating system to handle such cases.This often in normal operation because of Copy-on-write (COW), which be explained elsewhere.
Such mappings are sometime called "aliases".
FFFFF 000 points to its own physical address FFFFF 000. This kind of translation is called an "identity mapping", and can be very convenient for OS-level debugging.When an exception happens, the CPU jumps to an address that the OS had previously registered as the fault handler. This is usually done at boot time by the OS.
This could happen for example due to a programming error:but there are cases where it is not a bug, for example in Linux when:
int *is = malloc(1);
is[2] = 1;- the program wants to increase its stack.
- the page was swapped to disk.The OS will need to do some work behind the processes back to get the page back into RAM.
The exact format of table entries is fixed by the hardware.
The page table is then an array of
struct.On this simplified example, the page table entries contain only two fields:so in this example the hardware designers could have chosen the size of the page table to b
bits   function
-----  -----------------------------------------
20     physical address of the start of the page
1 present flag21 instead of 32 as we've used so far.All real page table entries have other fields, notably fields to set pages to read-only for Copy-on-write. This will be explained elsewhere.
It would be impractical to align things at 21 bits since memory is addressable by bytes and not bits. Therefore, even in only 21 bits are needed in this case, hardware designers would probably choose 32 to make access faster, and just reserve bits the remaining bits for later usage. The actual value on x86 is 32 bits.
Here is a screenshot from the Intel manual image "Formats of CR3 and Paging-Structure Entries with 32-Bit Paging" showing the structure of a page table in all its glory: Figure 1. "x86 page entry format".
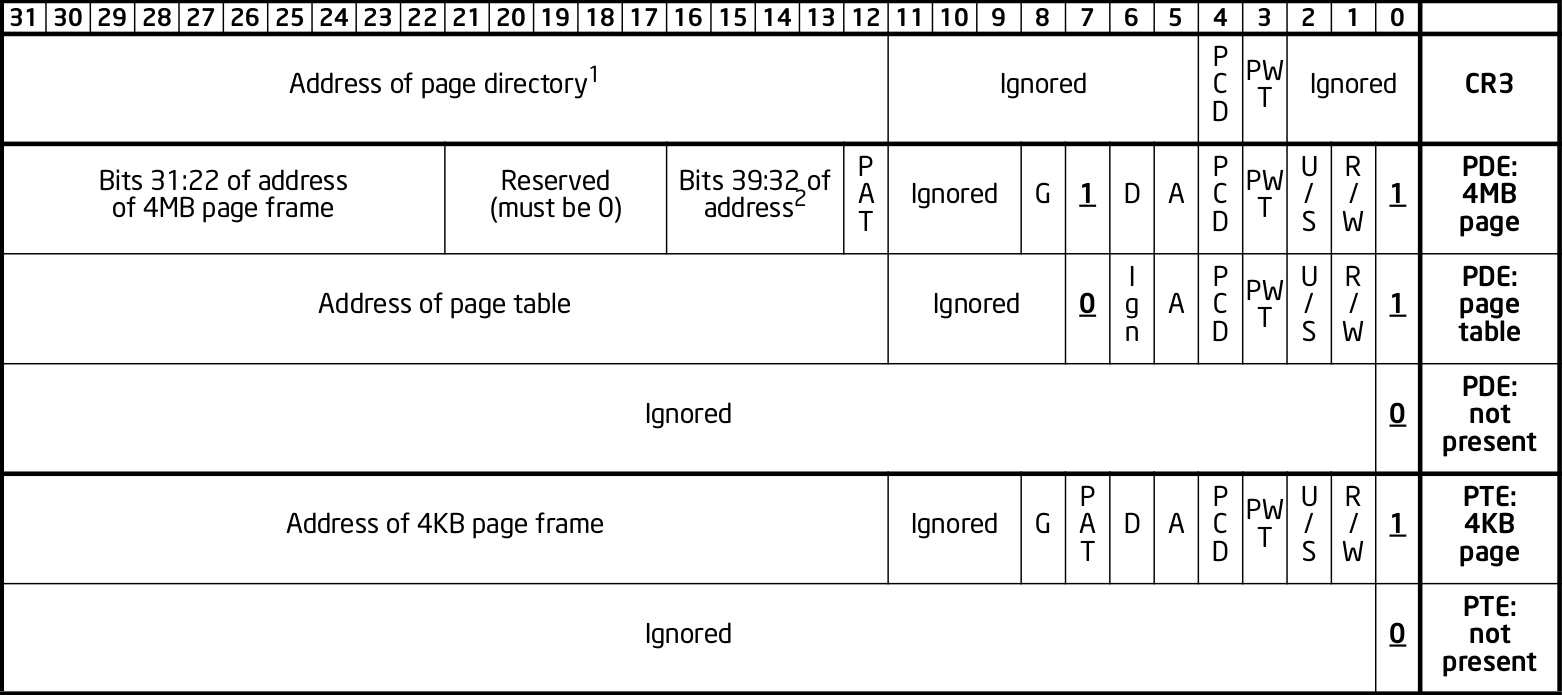
The fields are explained in the manual just after.
The problem with a single-level paging scheme is that it would take up too much RAM: 4G / 4K = 1M entries per process.
If each entry is 4 bytes long, that would make 4M per process, which is too much even for a desktop computer:
ps -A | wc -l says that I am running 244 processes right now, so that would take around 1GB of my RAM!The algorithmically minded will have noticed that paging requires associative array (like Java
Map of Python dict()) abstract data structure where:The single level paging scheme uses a simple array implementation of the associative array:and in C pseudo-code it looks like this:
- the keys are the array index
- this implementation is very fast in time
- but it is too inefficient in memory
linear_address[0]      = physical_address_0
linear_address[1]      = physical_address_1
linear_address[2]      = physical_address_2
...
linear_address[2^20-1] = physical_address_N
But there another simple associative array implementation that overcomes the memory problem: an (unbalanced) k-ary tree.
Using a K-ary tree instead of an array implementation has the following trade-offs:
In C-pseudo code, a 2-level K-ary tree with and we have the following arrays:
K = 2^10 looks like this:level0[0] = &level1_0[0]
level1_0[0] = physical_address_0_0
level1_0[1] = physical_address_0_1
...
level1_0[2^10-1] = physical_address_0_N
level0[1] = &level1_1[0]
level1_1[0] = physical_address_1_0
level1_1[1] = physical_address_1_1
...
level1_1[2^10-1] = physical_address_1_N
...
level0[N] = &level1_N[0]
level1_N[0] = physical_address_N_0
level1_N[1] = physical_address_N_1
...
level1_N[2^10-1] = physical_address_N_Nand it still contains
2^10 * 2^10 = 2^20 possible keys.K-ary trees can save up a lot of space, because if we only have one key, then we only need the following arrays:
Learned readers will ask themselves: so why use an unbalanced tree instead of balanced one, which offers better asymptotic times en.wikipedia.org/wiki/Self-balancing_binary_search_tree?
Addresses are now split as:
| directory (10 bits) | table (10 bits) | offset (12 bits) |Then:
- The top table is called a "directory of page tables".
cr3now points to the location on RAM of the page directory of the current process instead of page tables.Page directory entries are very similar to page table entries except that they point to the physical addresses of page tables instead of physical addresses of pages.Each directory entry also takes up 4 bytes, just like page entries, so that makes 4 KiB per process minimum.Page directory entries also contain a valid flag: if invalid, the OS does not allocate a page table for that entry, and saves memory.Each process has one and only one page directory associated to it (and pointed to bycr3), so it will contain at least2^10 = 1Kpage directory entries, much better than the minimum 1M entries required on a single-level scheme. - Second level entries are also called page tables like the single level scheme.Each page table has only
2^10 = 1Kpage table entries instead of2^20for the single paging scheme. - the offset is again not used for translation, it only gives the offset within a page
One reason for using 10 bits on the first two levels (and not, say,
12 | 8 | 12 ) is that each Page Table entry is 4 bytes long. Then the 2^10 entries of Page directories and Page Tables will fit nicely into 4Kb pages. This means that it faster and simpler to allocate and deallocate pages for that purpose. There are unlisted articles, also show them or only show them.