Topics (349k) Articles (361k) Users (420) Discussions (237) Comments (383) Files (12k) New article

Not everything is perfect.
One big problem of many big open source projects is that they are contributed to by separate selfish organizations, that have private information. Then what happens is that:
- people implement the same thing twice, or one change makes the other completely unmergeable
- you get bugs but can't share your closed source test cases, and then you can't automate tests for them, or clearly demonstrate the problem
- other contributors don't see your full semi secret important motivation, and may either nitpick too much or take too long to review your stuff
Another common difficulty is that open source maintainers may simply not care enough about their own project (maybe they did in the past but lost interest) to review external patches by people they don't know.
Therefore, if you ever submit patches and they get ignore, don't be too sad. It just comes down to a question of maintenance cost, and means that you will waste some extra time on the next rebase. You just have to decide your goals and be cold about it:
- are you doing the right thing and going for a specific goal backward design? Then just fork, run as fast as possible towards a minimum viable product, and if you start to feel that rebase is costing you a lot, or feel you could get some open source fame for cheap, open reviews and see what upstream says. If they ignore you, politely tell yourself in your mind silently "fuck them", and carry on with the MVP
- otherwise, e.g. you just want to randomly help out, you have to ask them before doing anything big "how can I be of help". If I propose a patch for this issue, do you promise to review it?
Writing documentation in an open source project in which you don't have immediate push rights is another major pain due to code reviews. Code code reviews tend to be much less subjective, because if you do something wrong, stuff crashes, runs slower, or you need more lines of code to reach the same goal. There are tradeoffs, but in a limited number. Documentation code reviews on the other hand, are an open invitation to infinite bike-shedding, since you can't "run" documentation through a standardized brain model. Much better is for one good documenter person to just make one cohesive Stack Overflow post, and ping others with more knowledge to review details or add any missing pieces :-)
Open source development model in which developers develop in private, and only release code to the public during releases.
Notable example project: Android Open Source Project.
Ciro Santilli can accept closed source on server products more easily than offline, because the servers have to be paid for somehow (by stealing your private data).
The opposite of open source software.
Knock knock.
Ciro Santilli once visited the chemistry department of a world leading university, and the chemists there were obsessed with NMR. They had small benchtop NMR machines. They had larger machines. They had a room full of huge machines. They had them in corridors and on desk tops. Chemists really love that stuff. More precisely, these are used for NMR spectroscopy, which helps identify what a sample is made of.
Introduction to NMR by Allery Chemistry
. Source. - only works with an odd number of nucleons
- apply strong magnetic field, this separates the energy of up and down spins. Most spins align with field.
- send radio waves into sample to make nucleons go to upper energy level. We can see that the energy difference is small since we are talking about radio waves, low frequency.
- when nucleon goes back down, it re-emits radio waves, and we detect that. TODO: how do we not get that confused with the input wave, which is presumably at the same frequency? It appears to send pulses, and then wait for the response.
How to Prepare and Run a NMR Sample by University of Bath (2017)
Source. This is a more direct howto, cool to see. Uses a Bruker Corporation 300. They have a robotic arm add-on. Shows spectrum on computer screen at the end. Shame no molecule identification after that!This video has the merit of showing real equipment usage, including sample preparation.
Says clearly that NMR is the most important way to identify organic compounds.
- youtu.be/uNM801B9Y84?t=41 lists some of the most common targets, including hydrogen and carbon-13
- youtu.be/uNM801B9Y84?t=124 ethanol example
- youtu.be/uNM801B9Y84?t=251 they use solvents where all protium is replaced by deuterium to not affect results. Genius.
- youtu.be/uNM801B9Y84?t=354 usually they do 16 radio wave pulses
NMR spectroscopy visualized by ScienceSketch
. Source. 2020. Decent explanation with animation. Could go into a bit more numbers, but OK. Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.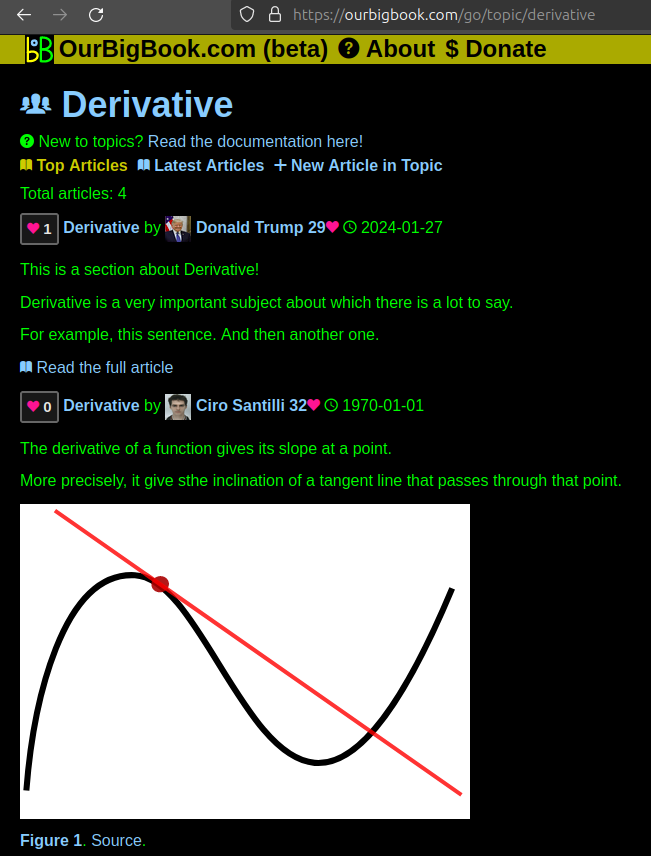
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
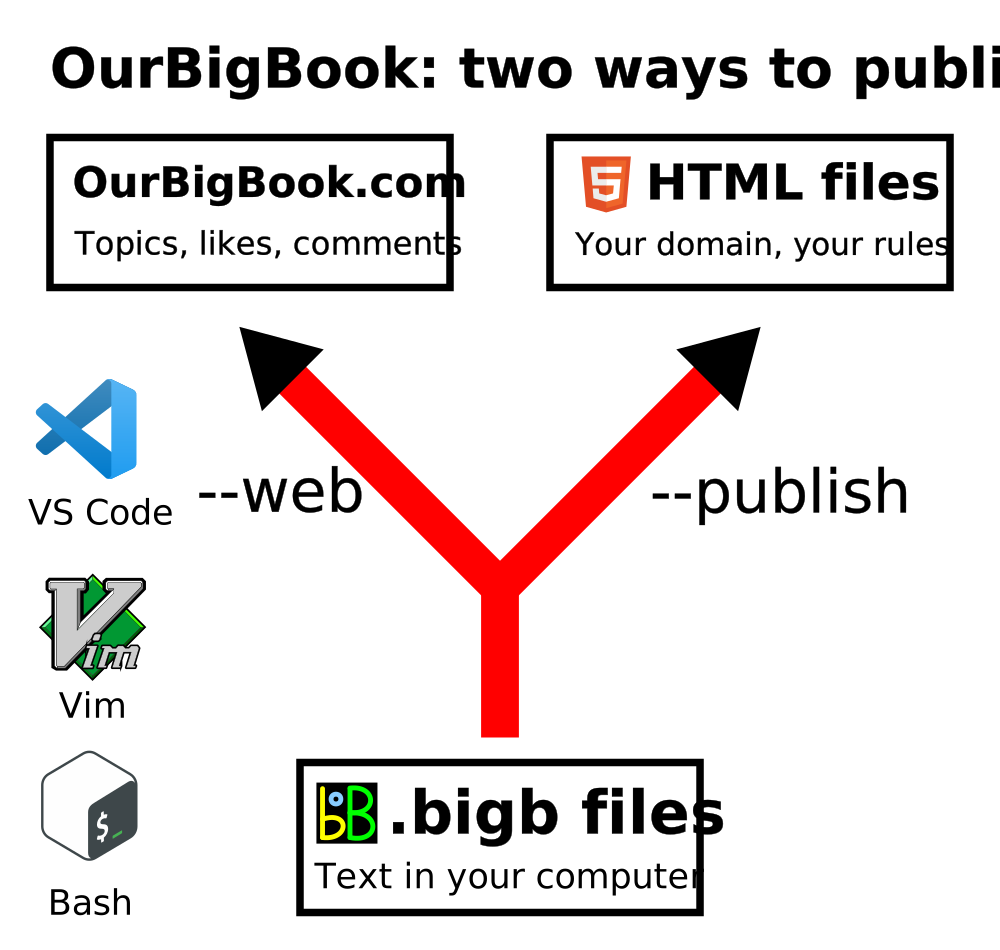
Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.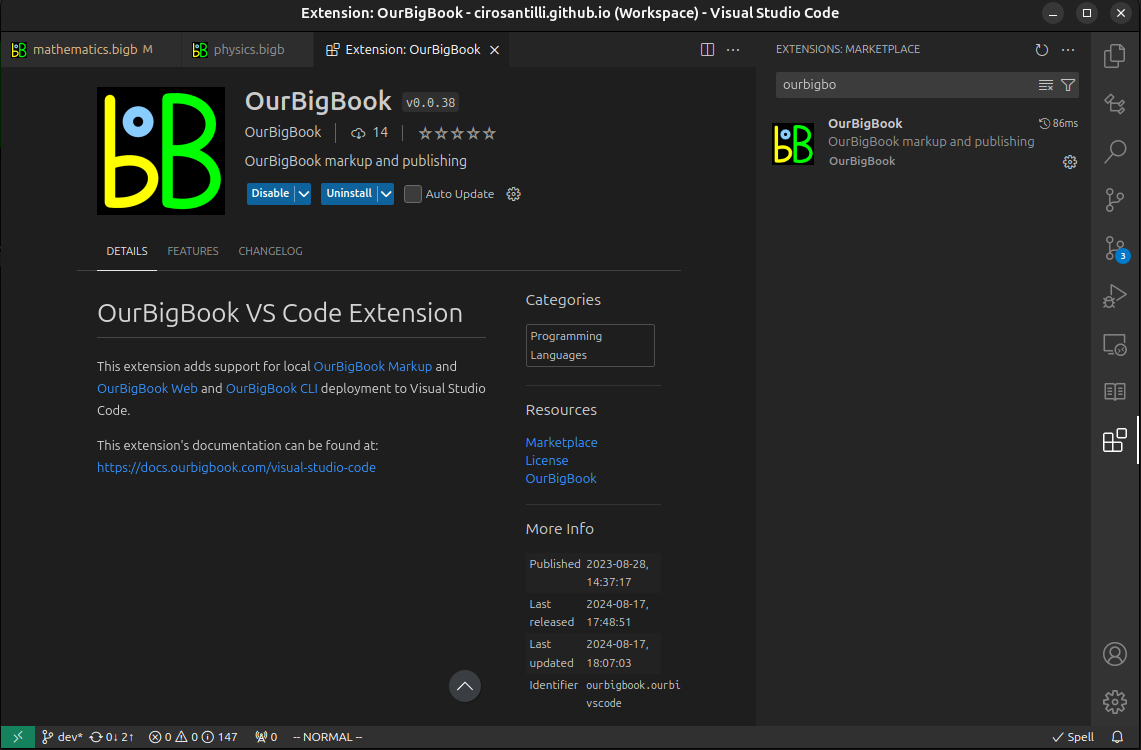
Figure 3. Visual Studio Code extension installation.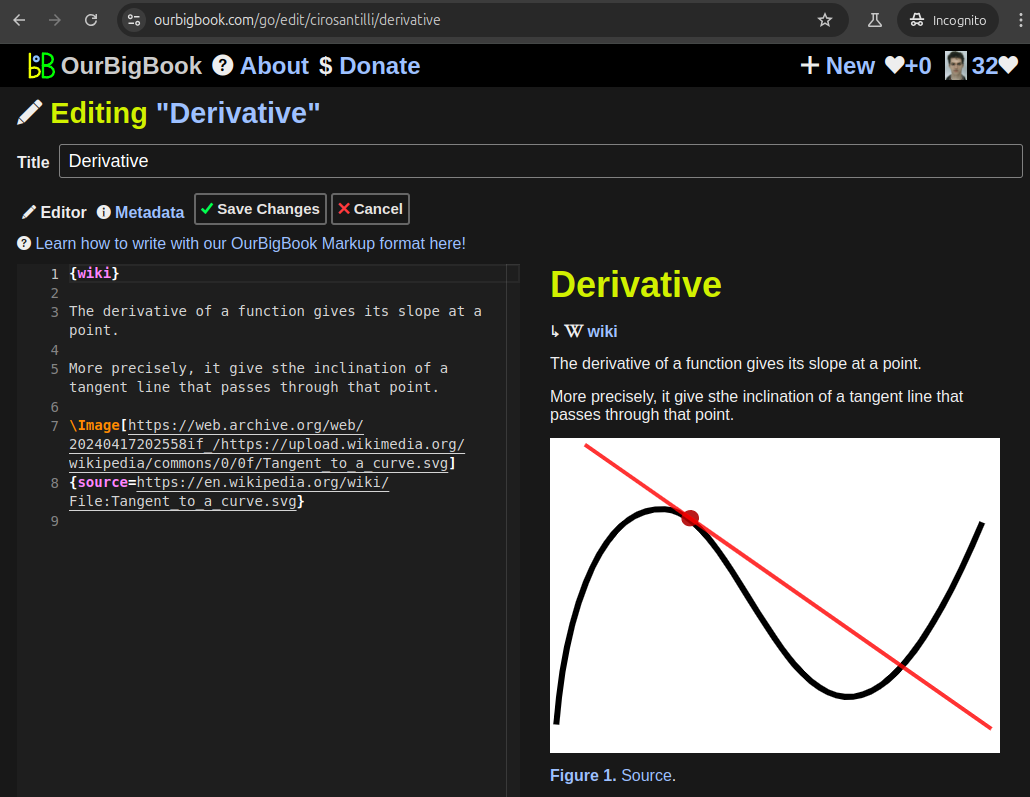
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 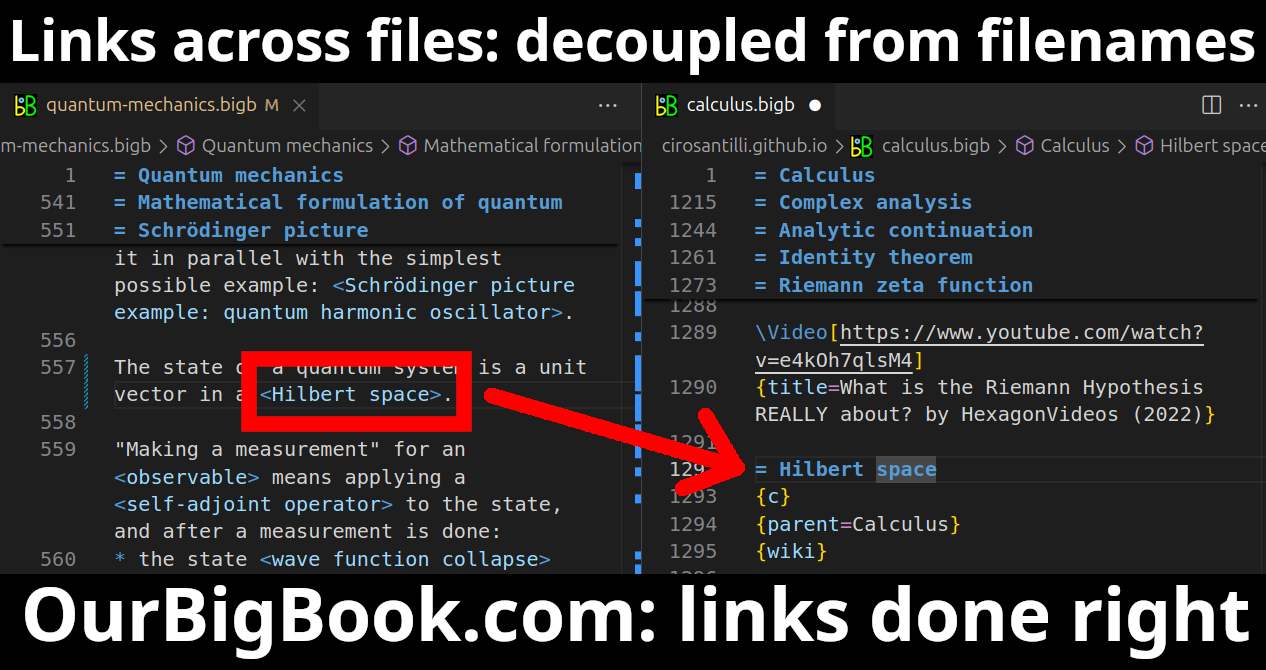
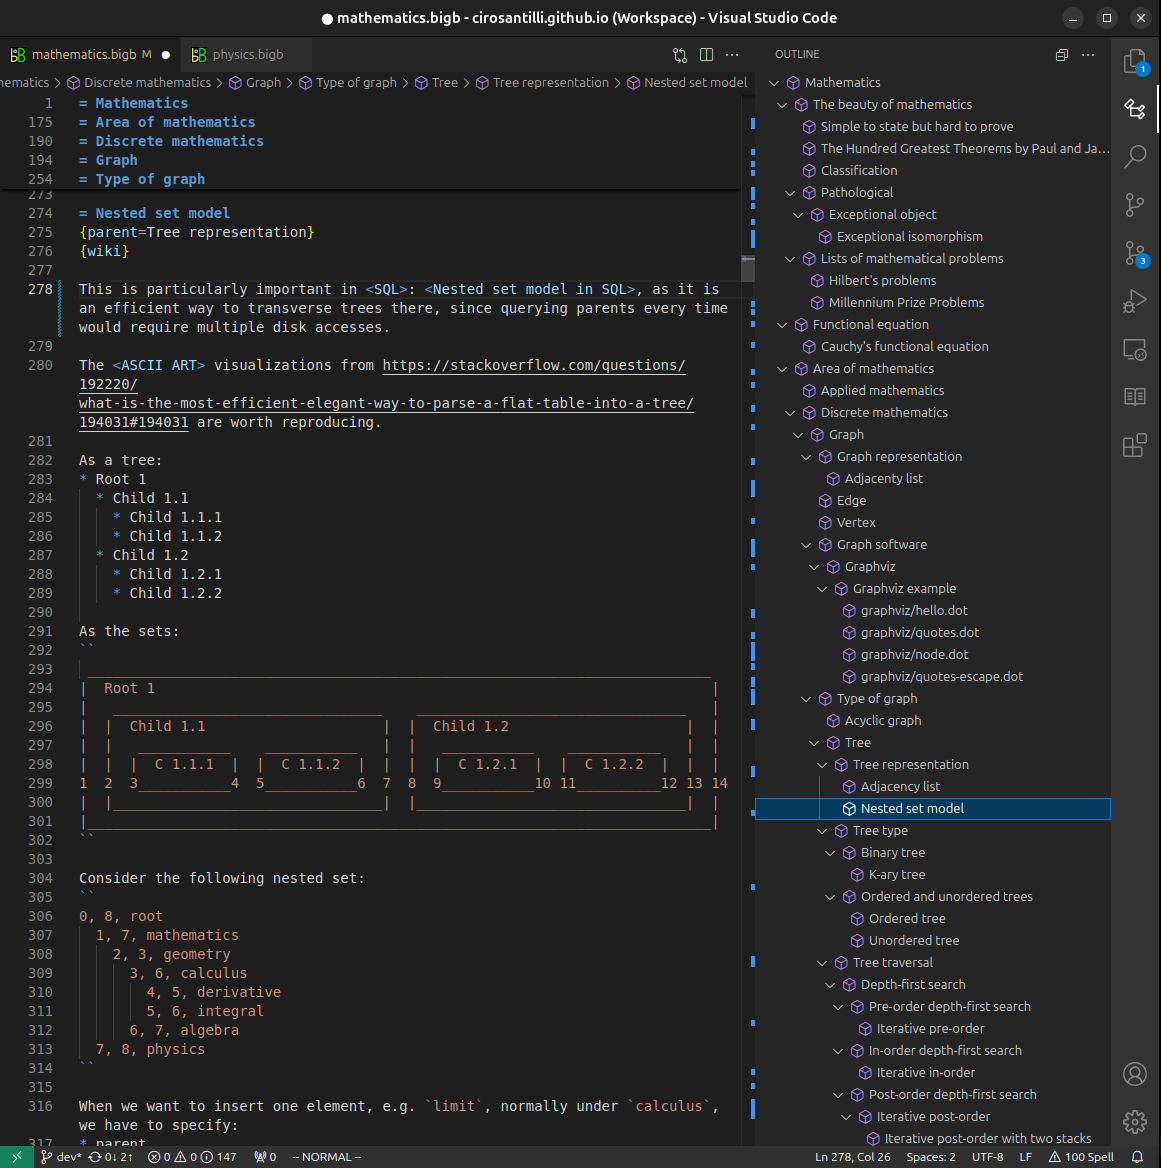
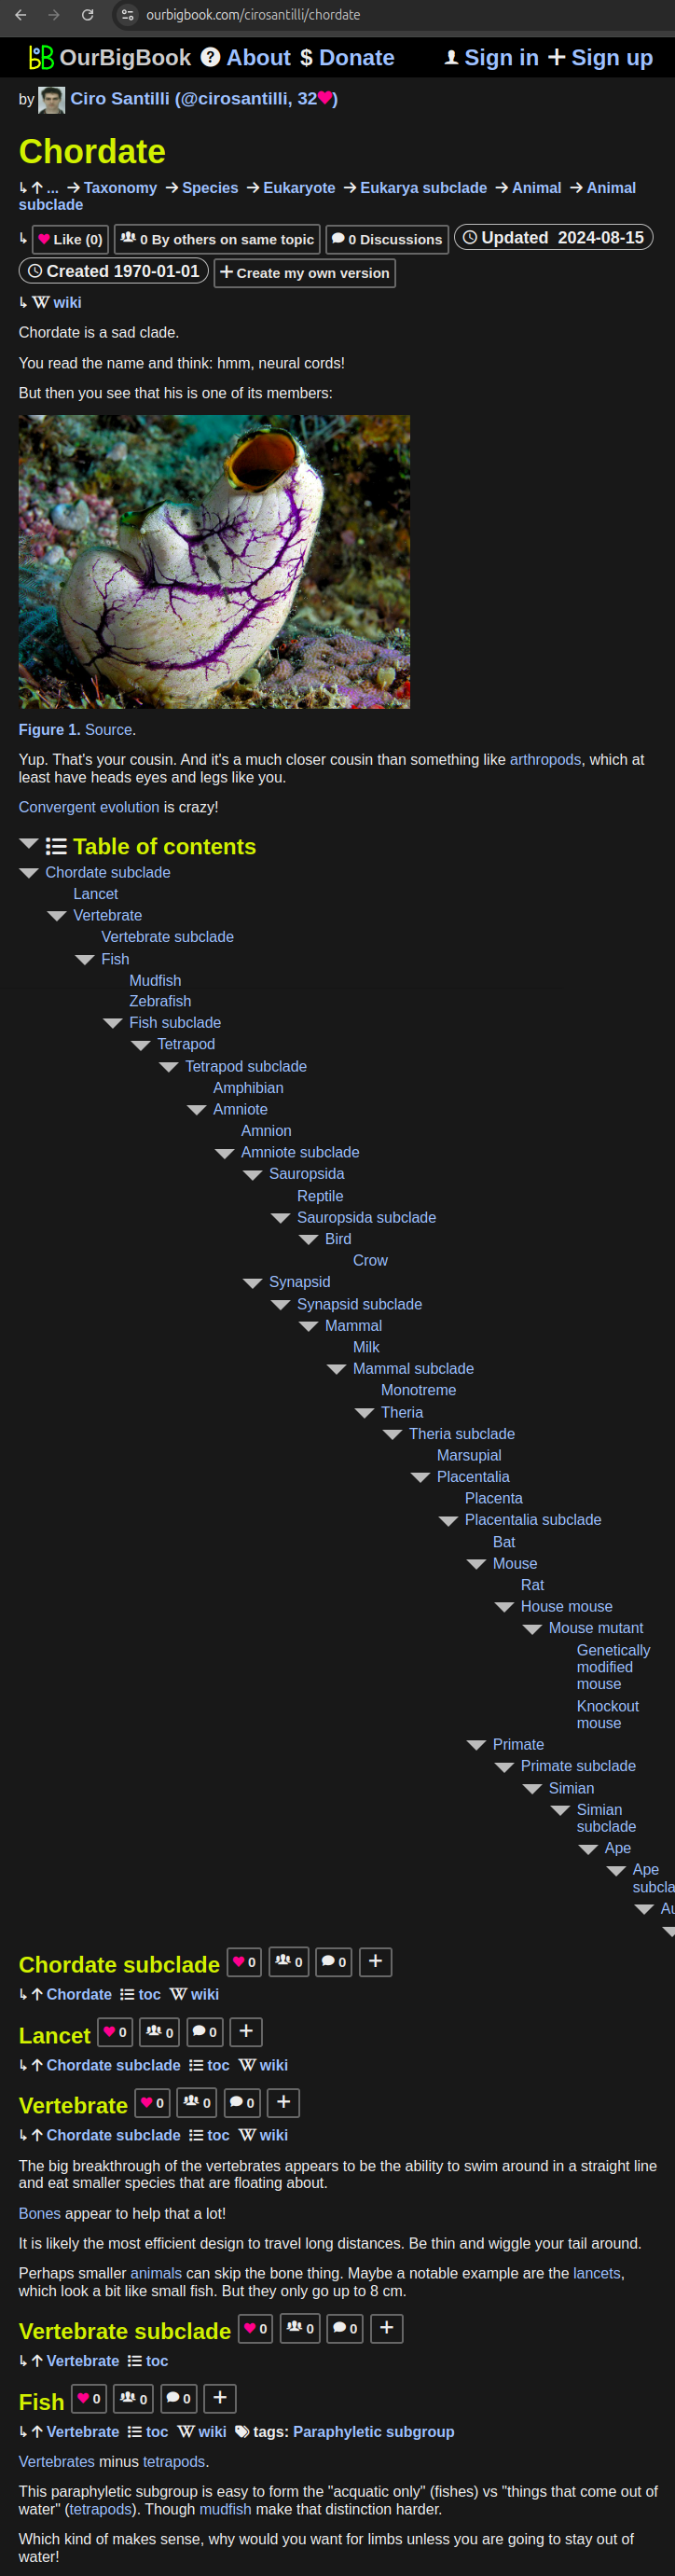
- Infinitely deep tables of contents:
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact