Durk Kingma is a computer scientist who publishes as Diederik P. Kingma. His personal profile describes research on machine learning and generative models, and records a 2017 doctorate at the University of Amsterdam.[ref]
Personal research homepage of Durk Kingma. Brief Bio: formal name, nickname and2017 doctorate
The institutional thesis front matter gives his full formal name as Diederik Pieter Kingma.[ref]
Kingma and Max Welling coauthored Auto-Encoding Variational Bayes by Diederik P. Kingma and Max Welling. A variational autoencoder couples a latent-variable model with an approximating posterior distribution that can be optimized through variational inference. Their reparameterization gradients represent a simulated random variable as a differentiable transformation of parameter-independent noise, allowing derivatives through the transformation.[ref]
Auto-Encoding Variational Bayes by Diederik P. Kingma and Max Welling. §§2.3–2.4, equations4–5 and Gaussian construction
Kingma also coauthored the Adam paper with Jimmy Lei Ba.[ref]Adam: A Method for Stochastic Optimization by Diederik P. Kingma and Jimmy Lei Ba. Full byline and Algorithm1
An original scalar calculation makes the noise handling concrete. Use the Gaussian reparameterization , with having the standard normal distribution and . For , a one-draw reparameterization gradient with respect to isThe derivative holds the sampled fixed. This pathwise gradient is justified here by direct calculation; a general interchange of derivative and expected value requires differentiation under the integral sign conditions.
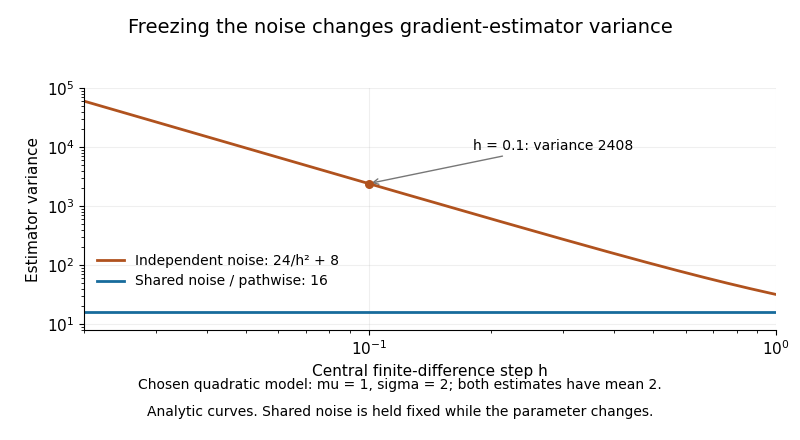
Noise coupling matters even for a central finite difference. If the evaluations at and share the same , the difference of the two squares gives exactly for every . This is a use of common random numbers. If instead the evaluations use independent standard normal distributions for their noise draws, the estimatorstill has expected value , but independence gives the variance of Gaussian-square finite-difference gradientsIndeed, a normal random variable of mean and variance has squared-value variance ; sum the two independent squared-value variances and divide by . Thus shrinking need not suppress simulation noise.
For chosen , and , both estimators have expected value 2, while their variances are 16 with shared noise and 2408 with independent noise. The example is a separate exact quadratic model; its purpose is to explain the role of keeping base noise fixed, not to reproduce a published variational-autoencoder benchmark.

Articles by others on the same topic
There are currently no matching articles.