Consider a binary Markov source with fair initial bit and flip probability . Its exact -symbol information entropy is . At ,This includes the uncertainty of the initial bit; the entropy rate itself is bits per symbol. The finite-block difference is .
For any finite block distribution, the entropy lower bound for prefix codes gives expected codeword length , while Shannon coding achieves . These bounds apply to each block as one source symbol, without requiring consecutive blocks to be independent. Here Huffman coding on all possible 16-symbol words gives the independently calculated value bits per block, or bits per symbol. The noninteger value is an expected value; each actual codeword has an integer length. As the block length grows, the prefix code bounds squeeze towards the entropy rate when an optimal code is used.
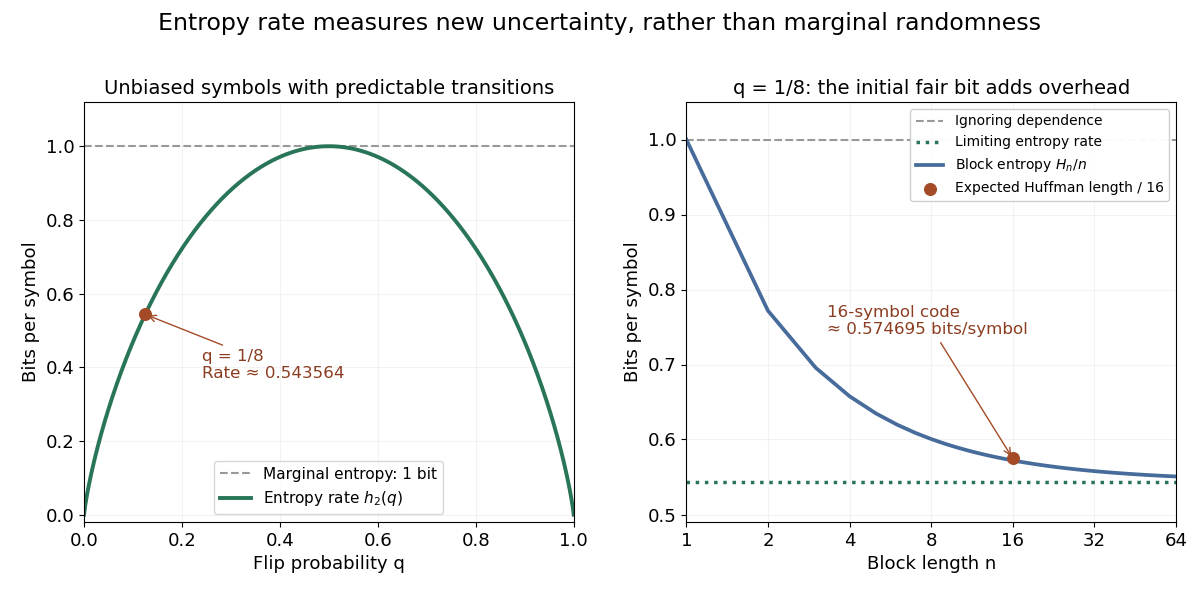

An entropy rate below one does not allow every word to fit into a shorter fixed binary word with zero error. For , all binary words are possible, so an injective fixed-length code needs at least bits. Compression instead exploits variable codeword lengths, or the vanishing-error convention in reliable source encoding at a rate. These are different guarantees.
Articles by others on the same topic
There are currently no matching articles.