Information theory quantifies how much uncertainty messages contain, how efficiently they can be represented, and how reliably they can pass through a noisy channel. Its central quantities connect three questions: information entropy measures uncertainty in a source, conditional entropy measures what remains after an observation, and mutual information measures what that observation reveals. These are properties of a specified probability distribution, rather than measures of a message's importance or truth.
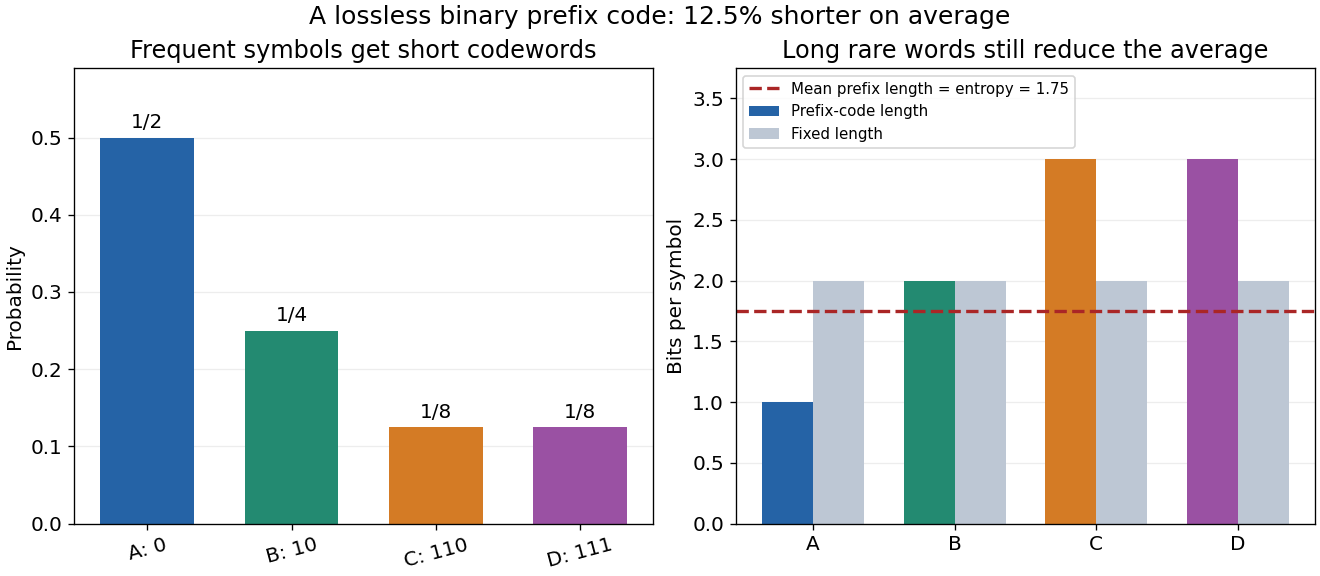
For a concrete source, suppose symbols have probabilities . A fixed-length binary representation needs two bits per symbol. Instead assign the prefix code , , , . Reading from left to right gives an unambiguous decoding because no codeword begins another. The expected value of the length isThis saves an average of of a bit per symbol, or of the fixed-length representation, with no loss of symbols. The lengths are exactly , so the average equals the source's Shannon entropy. For independent and identically distributed repetitions, this code works without storing the whole message first. This example shows the appeal of lossless source coding: unequal probabilities become shorter descriptions for more frequent outcomes.
Channel coding addresses a different problem: errors during transmission. A shorter representation removes predictable structure; an error-correcting representation adds carefully chosen structure that helps recover corrupted symbols. Shannon's source coding theorem and the Shannon second coding theorem identify limits for these respective tasks under their hypotheses. The beauty is that source details and hardware details can meet through a small number of mathematical quantities, notably information entropy and channel capacity.
Claude E. Shannon's A Mathematical Theory of Communication appeared in the Bell System Technical Journal in July and October 1948. Its introduction separates the engineering problem of reproducing messages from their semantic meaning; subsequent sections develop probabilistic source models, noiseless coding, and transmission with noise. It also acknowledges earlier work by Harry Nyquist and Ralph Hartley.[ref]
A ternary digit, taking one of three values. A codeword of length over a three-symbol alphabet uses trits. If the trit is uniform its information entropy is bits; an arbitrary ternary digit can have less information entropy. Expected codeword length in trits must therefore be distinguished from source information entropy measured in bits.
For probability distributions on the same finite alphabet, the Bhattacharyya coefficient measures their square-root overlap:The vectors and have unit Euclidean norm, so the Cauchy-Schwarz inequality gives . Equality holds exactly when the distributions agree; holds exactly when they assign positive probability to disjoint outcomes. For and , . This overlap is not the probability that two independent draws agree, which here is .
The fidelity of commuting mixed states reduces to this coefficient. More generally, the measurement characterization of quantum fidelity minimizes it over outcome distributions of a common quantum measurement, connecting classical overlap to the unsquared quantum fidelity.
The Bhattacharyya distance is the negative natural logarithm of the Bhattacharyya coefficient, with . It is zero for identical probability distributions and infinite for disjoint probability supports. Despite the name, it need not satisfy the triangle inequality required of a metric.
A communication channel describes how transmitted inputs become received outputs. In a probabilistic model, conditional probabilities specify which outputs each input can produce. A discrete memoryless channel uses the same finite transition law independently on successive symbols; channel capacity quantifies its optimal reliable transmission rate.
Information about earlier received outputs made available to the channel encoder while choosing subsequent inputs. For repeat-until-success coding over an erasure channel, an erasure report tells the sender to repeat the current bit, while a success report tells it to advance. A forward code rate calculation must specify whether this return communication is supplied freely or included in the resource count.
A bit is a binary classical symbol with two distinguishable values, zero and one. A uniform random bit has one bit of information entropy, while a biased binary symbol has less. Sending one bit means transmitting one symbol from this binary alphabet; the mutual information it carries about a particular input need not be one.
A bit vector is a fixed-length sequence of bits. An unsigned interpretation of a bit string assigns positional weights ; the vector itself need not represent an integer, since its coordinates can instead encode independent Boolean conditions.
The unit for information content or information entropy computed with natural logarithms. Converting to bits divides the numerical value by , so .
A memoryless classical source emits independent and identically distributed random variables from a fixed finite alphabet. Its block probability mass function factors as shown, and its information per symbol is the Shannon entropy . Zero-probability symbols never occur and contribute zero to the entropy. The typical sequence theorem describes the size and probability of the high-probability block set used for reliable compression.
The finite alphabet of symbols permitted on the stack of a pushdown automaton. It may contain nonterminal symbols, terminal symbols, and a fresh stack bottom marker, independently of the input alphabet.
A finite alphabet is an alphabet whose symbols form a finite set. The binary alphabet and a finite vocabulary of possible messages are examples.
For finite discrete random variables, conditional entropy is the average remaining information entropy of after the value of is known:Each observation changes the probability distribution used to describe ; the average weights that uncertainty by how often the observation occurs. An observation can increase uncertainty for one particular outcome, even though conditioning reduces entropy on average for finite variables.
For example, let choose with probabilities , and let report whether . If it reports yes, there is no remaining uncertainty. Otherwise the conditional probabilities are , whose information entropy is bits. The two reports each occur with probability , so of a bit. The original uncertainty was bits: this observation removes exactly one bit on average.
If is a function of , then : the observation determines the answer. If and are independent random variables, then : the observation gives no improvement. These endpoints make conditional entropy useful for separating relevant observations from irrelevant ones. They also lead to the chain rule for information entropy, , which counts the first uncertainty and the remaining uncertainty without double counting.
For discrete random variables with finite information entropy , Gibbs inequality givesEquality holds exactly when and are independent random variables. Finiteness matters: if has infinite information entropy and is independent of a fair bit , then and are dependent but .
// Target: probability-and-statistics.bigb
For classical finite random variables, . Each identity follows by inserting the corresponding joint entropy into . The two orders are particularly useful when one variable is a deterministic function of the others, as in Fano's inequality via an error indicator.
If is a bijection of for every fixed , thenIn particular, translating a random variable in a finite group by a value determined by the conditioning variable does not change its conditional entropy.
For finite discrete random variables , knowing reduces the information entropy of on average:Equality holds exactly when and are independent random variables. The average over observations is essential: can exceed for a particular . All logarithms here have base two, giving bits, and zero-probability terms contribute zero.[ref]
For Bayesian inference, this compares a prior distribution with the posterior distributions produced by possible observations. An unexpected report can make previously unlikely alternatives plausible, while useful reports reduce uncertainty overall. For lossless source coding, an observation shared by encoder and decoder lets them choose descriptions for the appropriate conditional distribution; sending that observation also has a cost. The example below makes both the saving and that cost explicit.
In A Mathematical Theory of Communication by Claude Shannon (1948), the definition of conditional entropy is already an average over observations, followed by the inequality and its independence condition in section 6, property 6. The phrase “knowledge reduces uncertainty” must be read with that averaging convention.[ref]
A Mathematical Theory of Communication by Claude Shannon. p. 12; title page identifies C. E. Shannon and the 1948 journal publication
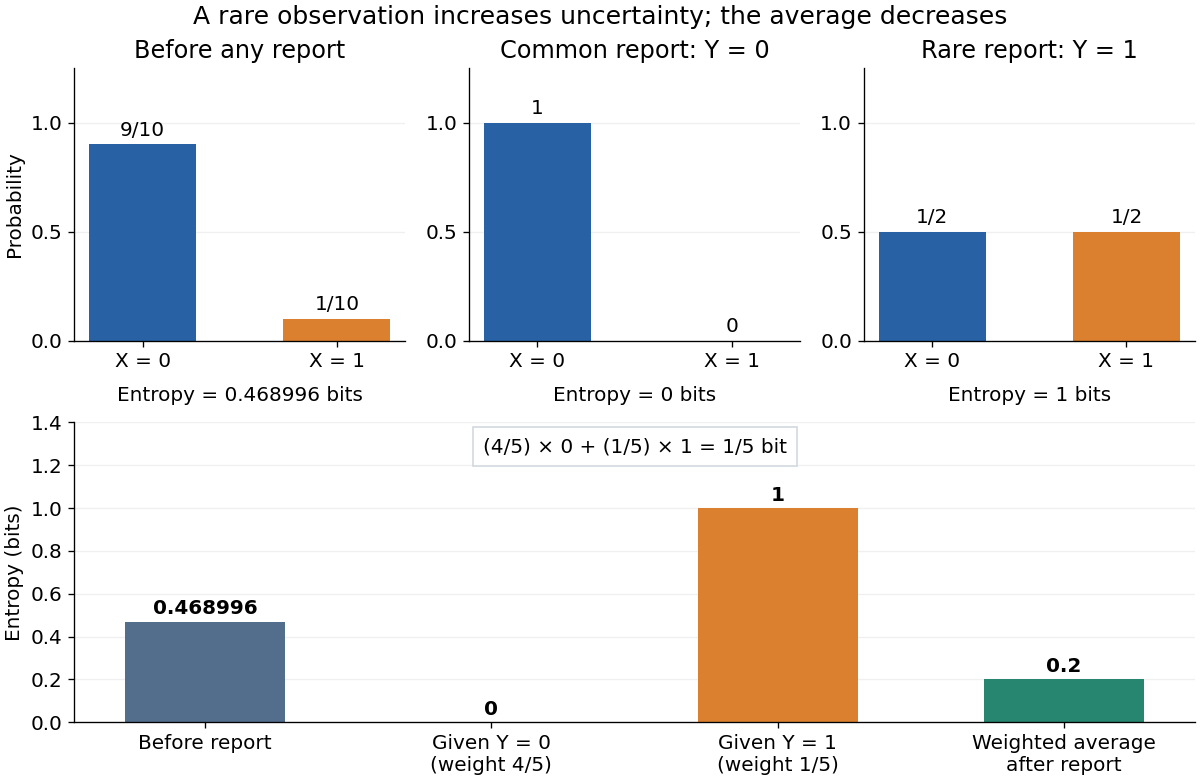
Consider a binary state and a report with the following joint probability mass function:Before the report, is strongly favored: its information entropy is bits, where is binary entropy. A report makes the two states equally likely, so bit, strictly larger than before. This report occurs with probability . The more common report determines , giving . Therefore the averaged conditional entropy isThe resulting mutual information is bits. The rare report increases uncertainty about the state; that increase does not make the report useless. Together the reports remove uncertainty on average. These are stipulated probabilities in an exact model, not measured frequencies.
Let be a Bernoulli random variable with . Independently of , a Bernoulli random variable with decides whether to reveal it:The symbol means “hidden” and is distinct from both binary states. This is a binary erasure channel with erasure probability . The hidden report leaves the posterior distribution equal to the prior distribution, because hiding is independent of the state. Either visible report determines . Weighting these three reports gives the exact conditional entropy and mutual information:For and , bits, while bits. With the report tells us nothing; with it reveals the state completely. If , every positive reveal probability makes the conditioning inequality strict. At or , the state was already known and every value of gives equality.
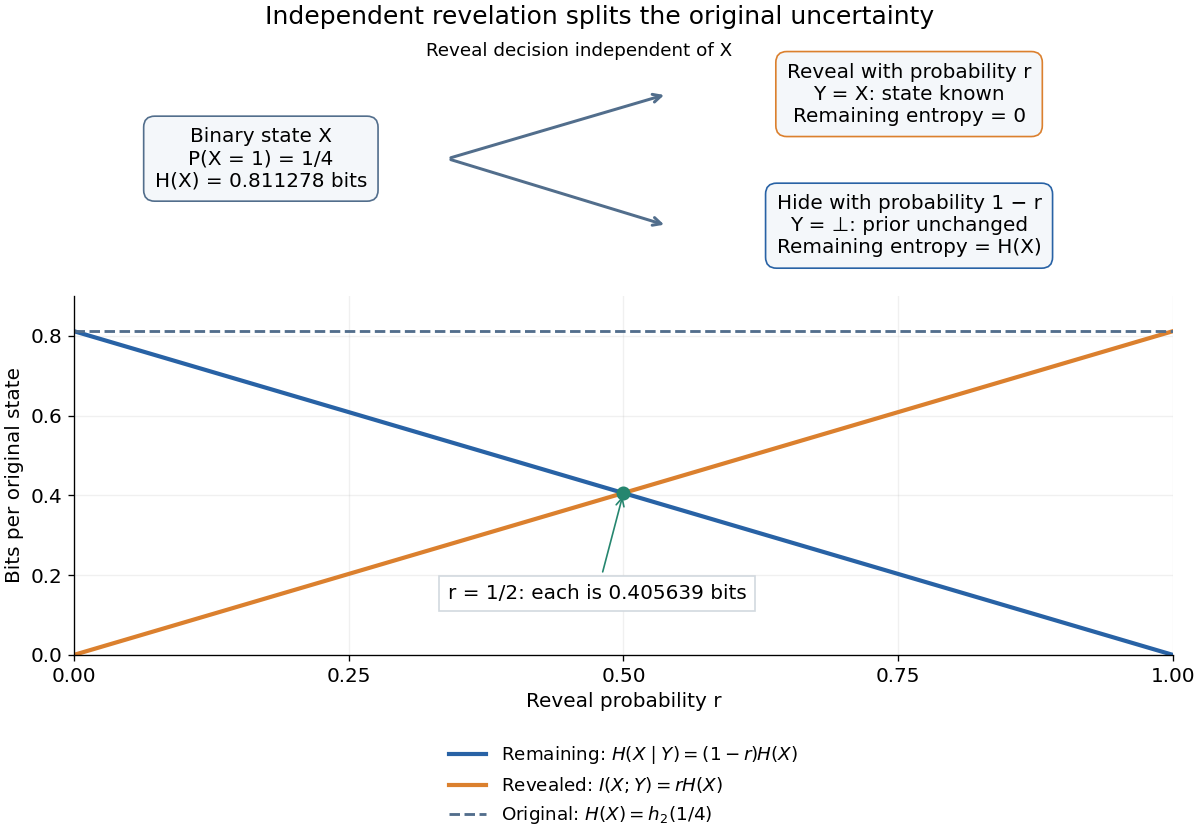
For a Bayesian inference problem, this model distinguishes an uninformative missing report from a decisive observed state. If hiding depended on , even could carry mutual information, and the displayed calculation would change. In lossless source coding, suppose both encoder and decoder already know the reveal pattern for repeated independent and identically distributed pairs. Only the hidden states require descriptions. Applying Shannon's source coding theorem to those states gives an asymptotic average rate bits per original state. A single hidden state need not have a codeword of that fractional length.
The reveal pattern itself has information entropy . If that pattern must also be sent, the chain rule for information entropy gives , since and are independent random variables. Equivalently, and . Thus a saving in the description of given assumes that is already available; it is not a free saving in the description of the whole pair.
For finite discrete random variables , retaining and also observing givesEquality means conditional independence of and given . Both sides average over reports; the additional observation is retained alongside .[ref]
Chapter 2: Information Measures: Mutual Information. Definition 2.4 and Theorem 2.5(1), printed pp. 26–27
A short proof of the original inequality uses Kullback-Leibler divergence:Gibbs inequality makes each term nonnegative, vanishing exactly when : independence for every possible report. Applying this within each and averaging proves the additional-conditioning inequality.[ref]
With appropriate probability density functions and finite differential entropies, , with equality iff independence. Differential entropy does not reverse the inequality; infinite or undefined quantities cannot justify subtraction.[ref]
Chapter 2: Information Measures: Mutual Information. Theorem 2.4(3), printed p. 24: density and finiteness hypotheses for the differential-entropy identity
However, differential entropy can be negative and depends on the choice of coordinates. For with a uniform distribution on an interval of length , ; in particular gives . Rescaling by a constant adds to both and , whenever they are finite, leaving the mutual information unchanged.[ref]
A Mathematical Theory of Communication by Claude Shannon. pp. 37–38: coordinate dependence, negative entropy, and linear rescaling
If a continuously distributed is revealed exactly, its conditional distribution is a Dirac measure with no ordinary probability density function. The discrete identity has no finite differential entropy counterpart. Mutual information, defined through relative entropy, is infinite here.[ref]
Fano's inequality turns remaining uncertainty into a constraint on decision errors. If an observation leaves many plausible answers, a decoder cannot usually recover the answer reliably. Its elegant idea is to separate two uncertainties: whether the guess was wrong, and which alternative was correct when it was wrong.
Let be discrete random variables, with taking values in a finite alphabet of cardinality . Choose any deterministic decoder whose output lies in , and define its average error probability . With base-two logarithms, Fano's inequality statesHere is conditional entropy and is binary entropy, with at the endpoints. Both sides are measured in bits; using natural logarithms throughout gives the same inequality in nats. No uniform source, independence of , or optimality of the decoder is assumed. Requiring its output to belong to the same alphabet is what leaves at most alternatives after an error.[ref]
For an exact toy example, give the discrete uniform distribution on . A channel reports with probability and reports each of the other three symbols with probability , where . Use the decoder . The output is uniform, and the conditional probabilities after any report areThus and direct calculation of the conditional entropy givesThis is equality in Fano's inequality for every . At , each report leaves probabilities , up to their order, and bits. The two contributions are bits for the error flag and bits for identifying the correct alternative after an error. These are theoretical probabilities, not measured data.
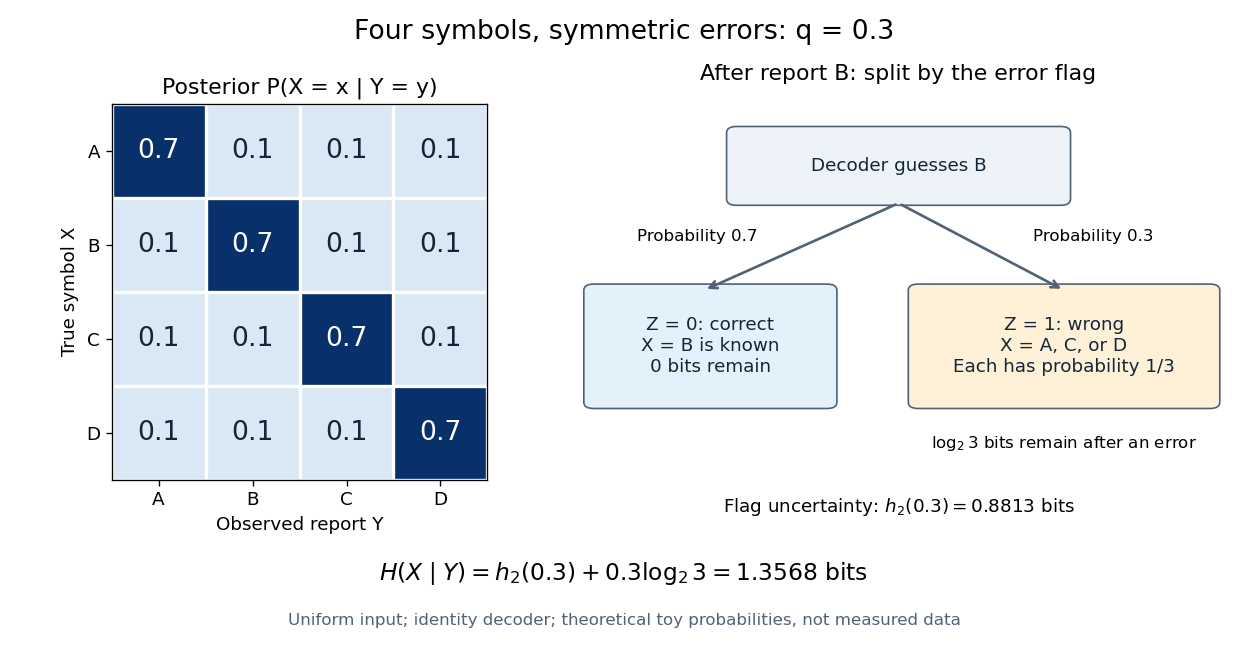
The identity decoder in this example minimizes error only for : its guessed symbol has the largest posterior probability exactly when . At , are independent random variables and all four guesses tie. For , guessing any one of the three other symbols has error probability . Equality in Fano's inequality therefore does not certify an optimal decoder.
For usefulness, combine with to obtain the simpler consequenceFor a uniform , , so this becomes . This connects mutual information to unavoidable decision error in channel coding or classification in statistical learning; it can rule out reliable recovery regardless of the chosen decoder.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_notes.pdf. Weissman, Ochoa and Tatwawadi, EE376A course notes, Sections 5.7–5.8
The sharper right-hand side increases from zero to on , then decreases: in the interior, . When interpreting the inequality by inverting a curve, use its increasing branch to obtain a lower error threshold. A decoder that chooses a largest posterior probability, as in maximum a posteriori decoding, always has , since the largest of conditional probabilities is at least . Arbitrary decoders can have larger error. In particular, low conditional entropy does not force every decoder to work well: with a fair binary and , the rule has even though . Fano's inequality supplies a constraint, not an exact error prediction for each rule.
Under the hypotheses of Fano's inequality, let , , and let be the indicator random variable of an error. Its probability of being one is . The in the displayed bound denotes binary entropy in bits. Since is a deterministic function of , . Applying the chain rule for conditional entropy in both orders gives the exact decompositionThe first term is bounded by , because conditioning reduces entropy. For the second term, fix a report : if , then is known; if , then lies among at most other symbols. Maximum entropy on a finite alphabet bounds the latter uncertainty by . Averaging over the reports and the error flag givesThis proves Fano's inequality. Events of zero probability contribute zero to this average, so the proof also covers without assigning a conditional distribution to an impossible event.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_notes.pdf. Weissman, Ochoa and Tatwawadi, EE376A course notes, Section 5.7, proof of Theorem 46
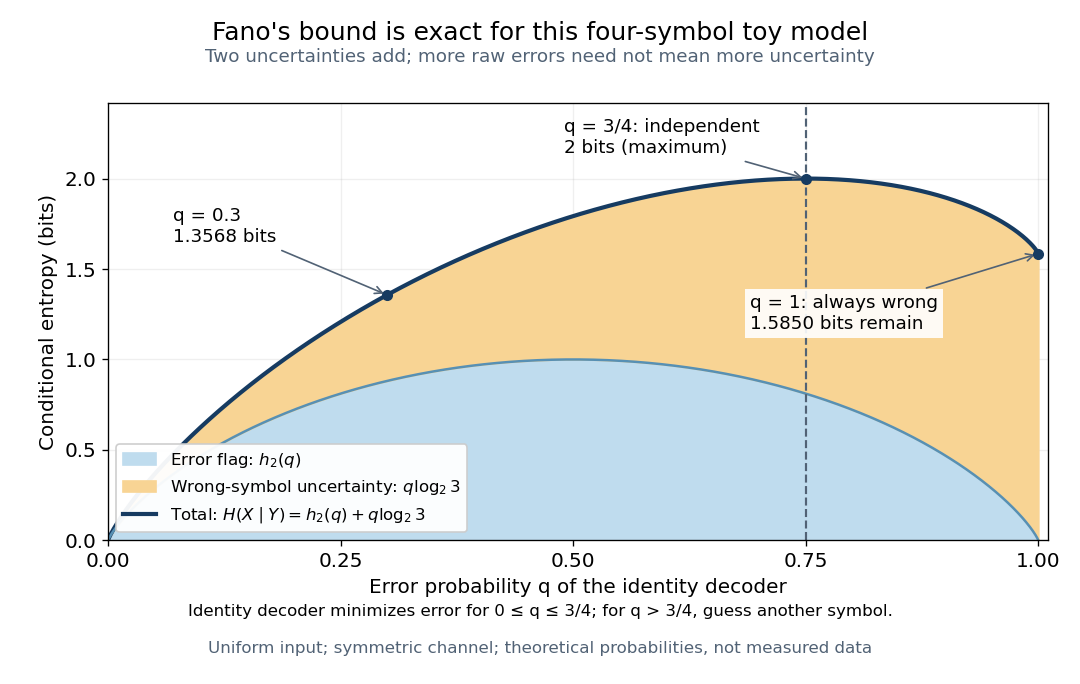
The four-symbol entropy budget peaks at chance-level error and separates the error flag from the three alternatives
. Details. The decomposition also explains equality. The first bound is exact when the indicator random variable and are independent random variables: knowing the report does not change the error probability. The second is exact when, for every report with positive error probability, the wrong-symbol conditional distribution is uniform on all alternatives. Both conditions hold in the four-symbol toy channel of Fano's inequality. At , the second condition is vacuous; at , the flag is constant but three alternatives remain, giving . For , there is just one alternative after an error, so the second term vanishes: all remaining uncertainty is whether the single alternative must replace the guess.
If a uniform index has possibilities and every proposed success neighbourhood contains at most possibilities, then any estimator has failure probability at least the displayed expression. Condition on its success indicator: conditional entropy is at most . Subtract this from to bound the mutual information and rearrange. A metric Hamming ball gives approximate recovery rather than exact index decoding.
If independent random variables take values in a finite additive group, thenIndeed, , and symmetrically for . Independence is essential: taking makes the sum constant.
For finite discrete random variables, mutual information is the reduction of information entropy provided by observing the other variable:The last expression makes the symmetry visible. It is nonnegative and is zero exactly when and are independent random variables. One way to see both facts iswhere is the Kullback-Leibler divergence with base-two logarithms. The Gibbs inequality gives nonnegativity; equality means that the joint probability distribution factors. The statement extends to more general distributions via relative entropy, but differences of infinite information entropies must not be used as if they were finite numbers.
A binary symmetric channel gives a useful example. Let be a fair bit, let be an independent Bernoulli random variable with error probability , and set , where is exclusive or. The output is also a fair bit, but knowing the input leaves just the error uncertainty:Here is binary entropy. At , , so the output carries about bits of mutual information about the input per use. This is an average uncertainty reduction, not a claim that each observed symbol can be divided into fractional physical bits.
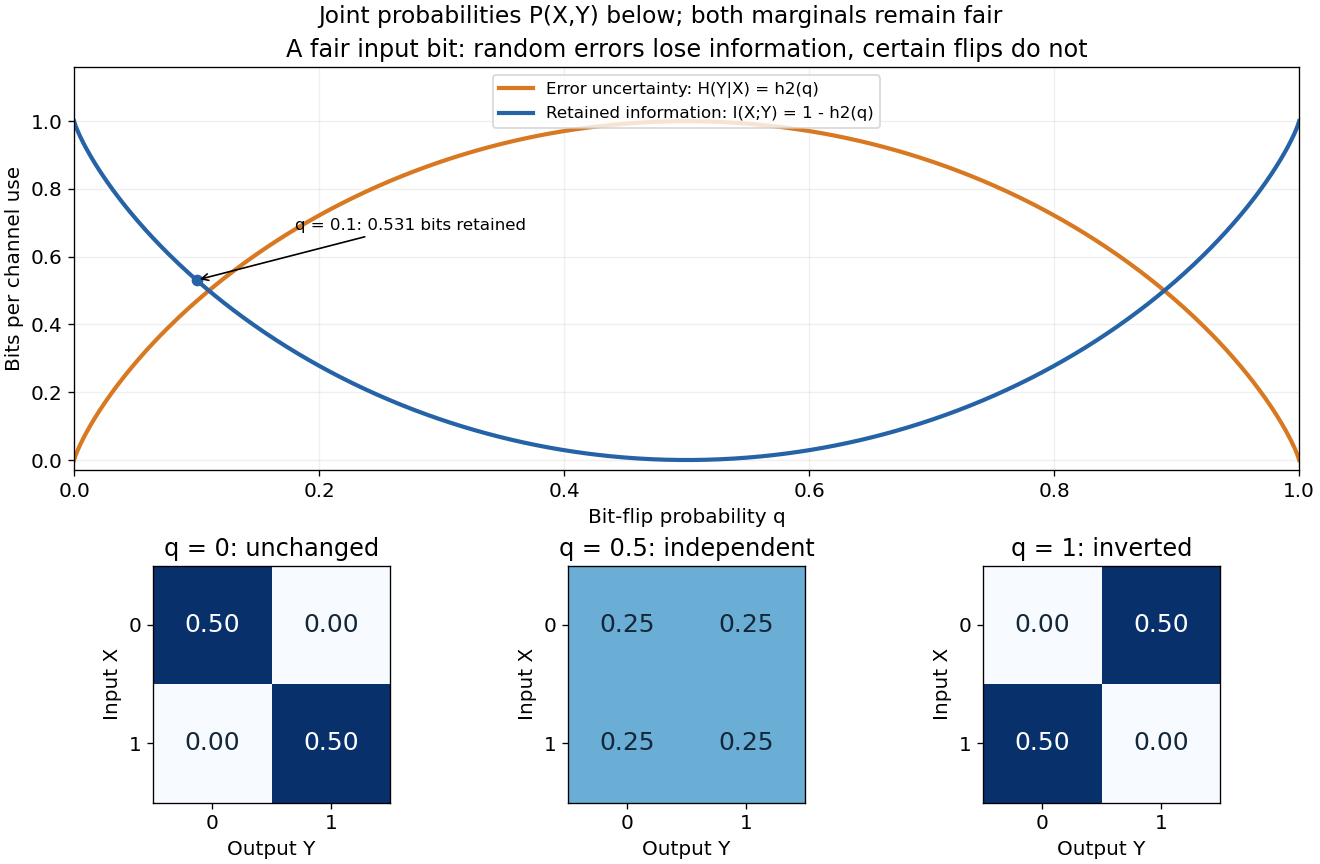
Binary entropy and retained information distinguish noisy transmission from predictable bit inversion
. Details. At , every output is equally likely for either input, so . At , the output is always the inverted input: knowing this rule lets the receiver recover the input exactly, so again. A high raw error rate need not mean low mutual information when the errors are predictable. For this particular channel the fair input is optimal, giving the binary symmetric channel capacity .
Mutual information detects dependence that ordinary correlation can miss. Let be uniform on and . Symmetry gives , hence zero covariance and zero correlation, while is completely determined by . Thus . This distinction is useful whenever a relationship is nonlinear: knowing one variable can reveal another without a linear trend.
For a fixed finite discrete memoryless channel , the function is concave on the input probability simplex. Indeed, the induced output law is linear in , the output Shannon entropy is concave, and is linear. Their difference is therefore concave. Equivalently, at a mixture , the concavity gap is by Gibbs inequality. Thus every local maximum is a global maximum, and averaging over symmetries of the fixed channel cannot decrease mutual information.
For discrete random variables ,The difference between the left- and right-hand sides is the nonnegative conditional mutual information .
A union-intersection compression can only decrease the sum of information entropies for a finite-valued random vector . Each elementary step follows from entropy submodularity; iteration proves the assertion with multiset multiplicities. Uniform coordinate multiplicity gives Shearer inequality by compressing to repeated full sets and empty sets.
Let be a finite multiset of subsets and let count its occurrences of coordinate . Its nested compression consists of . Then , by repeated entropy submodularity. This is the compression formulation in Balister and Bollobás, "Projections, Entropy and Sumsets".
For a nonempty ordered coordinate set , write and . An exact -cover satisfies . A short proof uses the chain rule for information entropy contributions : each conditional subset entropy bounds on the appropriate side, by conditioning reduces entropy. Weighting gives the lower inequality for a fractional packing and the upper inequality for a fractional cover. See Madiman and Tetali, "Information Inequalities for Joint Distributions".
Let be a discrete random vector, and let be a collection of subsets of in which every index occurs at least times. ThenApply the chain rule for information entropy to each projection and use conditioning reduces entropy to compare every term with the corresponding conditional entropy in the full chain rule.
If every pair of graphs in a family on has a graph intersection without an isolated vertex, the family has at most members. At each vertex, its possible graph neighbourhoods form an intersecting family, of size at most . Every edge occurs in two such neighbourhood projections. Shearer inequality bounds twice the full information entropy by the sum of their information entropies.
For finite discrete random variables, conditional mutual information measures the average reduction in uncertainty about from observing , when is already known. With base-two logarithms, it is measured in bits:The second expression follows from the chain rule for conditional entropy and makes the symmetry in visible. Equivalently, compute the mutual information separately in each conditional probability distribution and then average:Here is the Kullback-Leibler divergence, also computed with base-two logarithms; zero-probability terms contribute zero. The Gibbs inequality gives , with equality exactly when and have conditional independence given : the conditional joint probability mass function factors for every of positive probability.[ref]
For a fully computed example, take independent random variables that are fair bits, and let , where is exclusive or. The complete joint probability distribution has only these four positive entries:
Table 1. .
Every pair has probability , so . But . Given , the pairs each have conditional probability , while both conditional marginals are fair. ThusGiven , the pairs give the same calculation. ThereforeThe conditional entropy calculation tells the same story: because either value of leaves fair, whereas because . Learning the exclusive or does not reveal either bit alone; it reveals whether they agree, so learning one then determines the other.
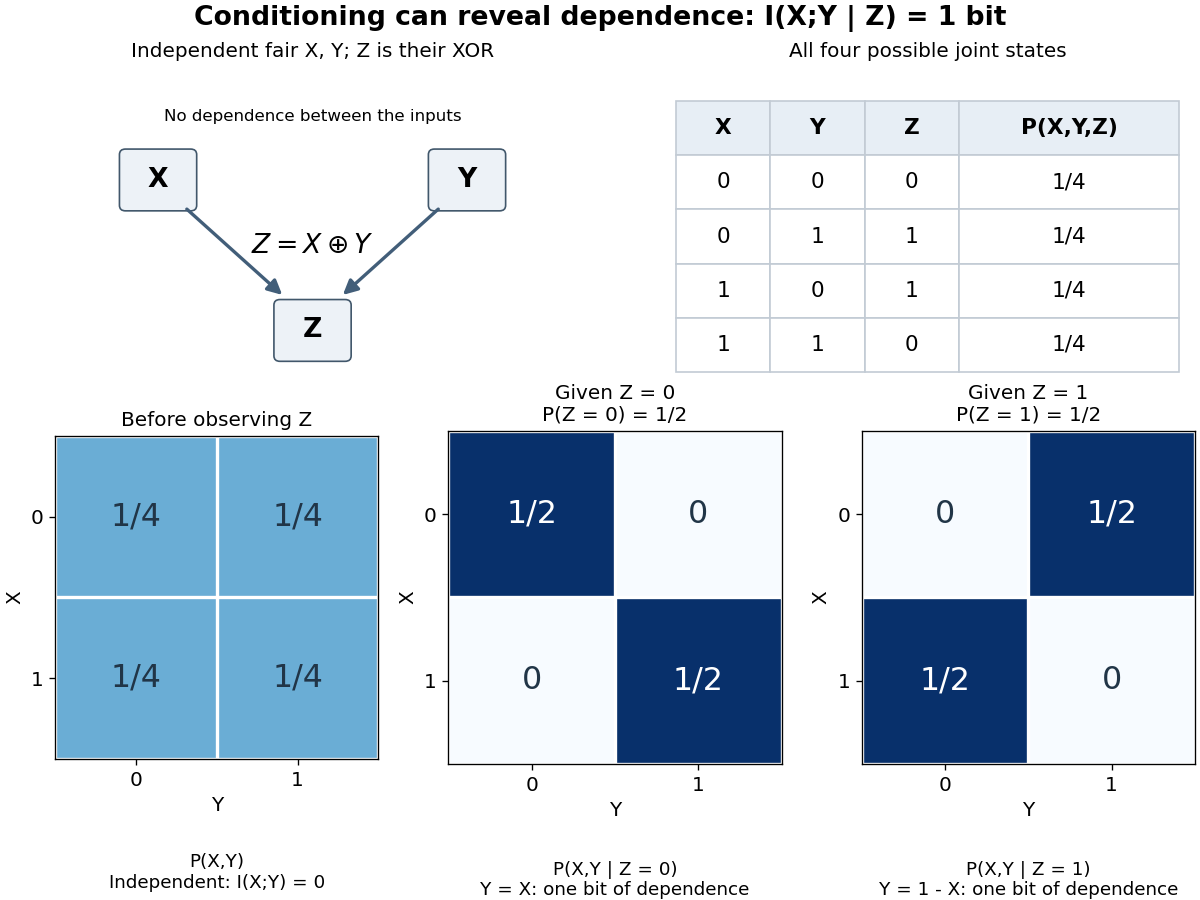
This example distinguishes conditional independence from ordinary independence. It also disproves the claim that conditioning always reduces mutual information, despite conditioning reduces entropy. There is no general ordering between and : the example above increases it from zero to one, while taking and for a fair bit decreases it from one to zero. The chain rule for mutual information explains why both are possible.[ref]
Conditional mutual information is useful for asking whether an additional observation tells us anything after information already available has been accounted for. Its zero case expresses conditional independence exactly; in a Markov chain, this is the step that turns the chain rule for mutual information into the data processing inequality.
If outputs are conditionally independent given , then . Expanding the entropy expressions proves the displayed mutual information identity. The chain rule also gives , while the identity and nonnegativity give the upper bound by their sum. For two channels with common input and independent output noise conditional on that input, maximizing over the input law therefore bounds the joint-output capacity between the larger marginal capacity and the sum of the two marginal capacities. Their unconditional output dependence need not vanish: the subtracted measures information shared through the common input.
Suppose a fair input bit is independent of a publicly known channel-position label . At position , let the channel be a binary symmetric channel with error probability . Forgetting gives a binary symmetric channel with error . ThereforeThe chain rule for mutual information and show that their difference is the nonnegative conditional mutual information . Equivalently, the inequality follows from concavity of binary entropy. For with equal position weights, the known-position value is bits and the pooled value is bits. These quantities answer different statistical questions.
For finite discrete random variables, the mutual information supplied by two observations equals the information supplied by the first plus the additional conditional mutual information supplied by the second:The order changes the individual contributions but leaves the total unchanged.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_3.pdf. Stanford EE376A/STATS376A, Lecture 3, Definition 7 and equations (48)–(51)
To prove the first identity, add and subtract the intermediate conditional entropy:With base-two logarithms, all contributions are in bits. Repeatedly inserting intermediate conditional entropies makes them cancel, as in a telescoping series, and gives the rule for any finite list of observations:where the term is . The same calculation with already known gives .For the fair-bit exclusive or example in conditional mutual information, observing alone tells nothing about , but observing after tells everything:Here by independence and because . In the reverse order, , so and : the two observations are individually uninformative but jointly reveal one bit. Simply adding their separate mutual informations would miss all of it.
The chain rule is useful for measuring the value of each new observation without double counting information already supplied. It also guarantees by nonnegativity of conditional mutual information. Keeping and adding can help, even though discarding and retaining only a processed is constrained by the data processing inequality. Equating the two observation orders gives the precise identitywhich explains why there is no general rule that conditioning decreases mutual information.
For finite discrete random variables, suppose is a Markov chain: the final channel uses only , so and have conditional independence given . In terms of the joint probability mass function,and hence . Then the two data processing inequalities areAll mutual informations here use base-two logarithms. Thus deterministic or randomized processing cannot increase the information shared with an unprocessed variable.[ref]
https://web.stanford.edu/class/cs229t/scribe_notes/12_05_final.pdf. Stanford CS229T/STATS231, Theorem 2.1 and its chain-rule proof
For a concrete cascade, take a fair bit and Bernoulli random variables with probabilities , of being one. Assume are jointly independent random variables, and pass through two binary symmetric channels:The second noise is independent of both and , so this is a Markov chain. Both and are fair bits. The net exclusive or error is one exactly when one noise flips the bit and the other does not:Using the binary entropy , the three mutual informations are fully determined:All numbers are in bits. The two losses are and . Thus the cascade retains less information about the original source than either individual channel shares between its own input and output.
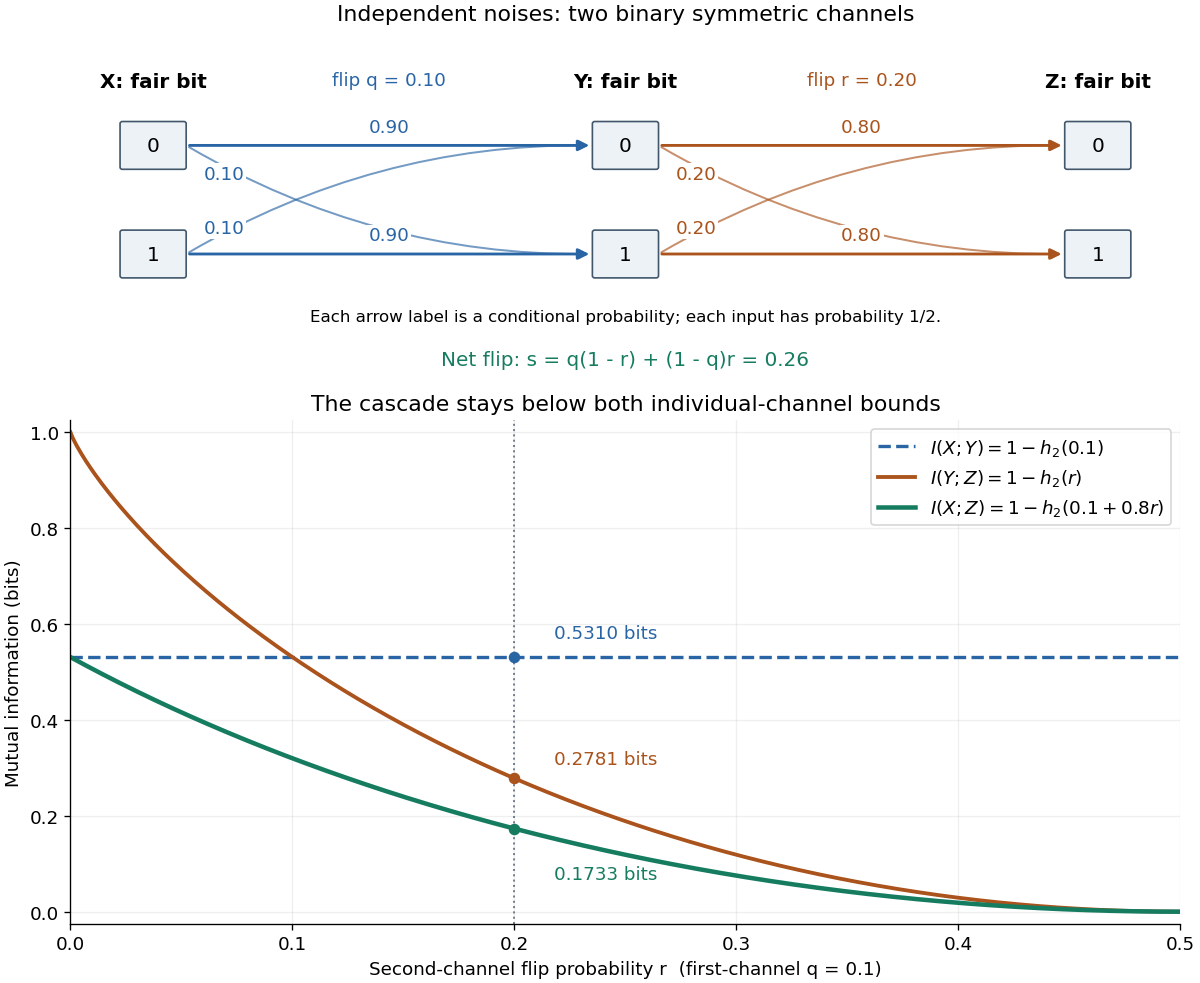
With fixed and , the effective error is . At , and ; at , is independent of the previous variables and . The diagram plots these endpoints and the computed example.
The data processing inequality is useful for testing what a proposed decoder or data summary could possibly reveal: if its only input is , even randomized processing cannot provide more mutual information about than already contains. The Markov chain hypothesis matters. In the exclusive or example from conditional mutual information, allowing a processor to use both and reveals exactly; that processor has additional input, so the conclusion for processing alone does not apply.
The chain rule for mutual information proves both inequalities and identifies their exact gaps. First expand the information about in the two observation orders:Therefore . Next use as the variable being learned:Symmetry of mutual information gives . Both signs follow from the nonnegativity of conditional mutual information; the first gap also gives equality in data processing inequality.
Under the finite Markov chain hypothesis , the gap identity in the data processing inequality givesBy the zero criterion for conditional mutual information, equality means that and have conditional independence given . After seeing the processed output, the original observation provides no additional information about . Similarly, equality in the other bound, , holds exactly when .
Equality does not require retaining every detail of . Let be independent fair bits, put , and let the processed output be , the first coordinate of . This is a Markov chain, andAlso . The output discards the entire unrelated bit , reducing to , while preserving all mutual information about . This is what makes equality useful for choosing a compact observation that retains all information about the quantity of interest.
If is a Markov chain conditionally on , thenIt follows by applying ordinary data processing inside every conditional distribution and averaging over .
Send a uniform bit twice through independent binary symmetric channels of crossover probability . The first received bit supplies bits. Since the received bits disagree with probability , the additional information in the second bit is
For finitely supported random variables in a finite additive group, let be independent variables with their respective marginal distributions. The entropic Ruzsa distance isIt is symmetric and nonnegative, but can have .
For finitely supported random variables, the conditional entropic Ruzsa distance isThus the two conditioning values are sampled independently. If only one variable is conditioned, write .
The simultaneous conditional distance samples one value of the conditioning variable for both arguments:It differs in general from , which uses two independently sampled conditioning values.
If are independent random variables in , thenIndeed, conditioning reduces entropy and independence giveIn , , so conditional entropy under a deterministic change of variables shows that the left-hand side is unchanged when and are exchanged. Averaging the displayed bound with its exchanged version gives the result.
For finitely supported random variables in an abelian group,To prove it, take two conditionally independent copies and of given . Since , entropy submodularity givesThe first two terms are at most . The last joint entropy isConsequently . Subtractingfrom this bound proves the theorem.
If is -relevant to and are mutually independent copies, then is -relevant to . The entropy submodularity for three independent sums impliesand similarly for . The Entropic Ruzsa triangle inequality boundswhich proves the claim after addition.
For independent finitely supported random variables in a finite additive group,This is the data processing inequality for mutual information applied to the Markov chain .
For independent with and identically distributed,This additive form of entropy submodularity follows from data processing and invariance of conditional entropy under translations.
For two probability mass functions , a decision region accepts . Its two error probabilities are and .
An error exponent is the limiting exponential decay rate of an error probability as sample size grows. Different constraints on the type I error and type II error give different optimal rates. The Chernoff information describes the optimal average-error rate for simple Bayesian hypotheses; Stein's lemma gives the optimal type-II rate when type-I error is held below a fixed nontrivial bound.
For a null hypothesis , a type I error rejects when it is true, while a type II error does not reject when the alternative is true. If a test does not reject on an event , their conditional probabilities are and . Nonrejection does not establish the truth of the null hypothesis.
Chernoff information measures how quickly repeated independent evidence can distinguish two fixed probability distributions. Suppose a statistical hypothesis test observes independent and identically distributed random variables, with common law under one simple hypothesis and under the other. Give the two hypotheses fixed positive prior probabilities, and let be the smallest achievable average error probability. For distinct positive probability mass functions on a common finite alphabet,Here is the natural logarithm, so the error exponent is measured in nats per observation. This optimal rate is unchanged by choosing different fixed positive prior probabilities; the best decision rule and finite-sample error can still change.[ref]
Information Theory: From Coding to Learning, October 2022 draft by Yury Polyanskiy and others. §16.1, Corollary 16.2 and equation (16.2), printed pp. 261–262: fixed-prior Bayesian error exponent
The interpretation is : a larger Chernoff information means fewer observations are needed at the leading exponential scale. It does not assert the exact finite-sample identity . The finite-sample Chernoff error bound and the explicit Chernoff information for complementary Bernoulli distributions make this distinction concrete. This is useful when designing repeated measurements or comparing sensors whose output probability distributions differ under two candidate conditions.
For probability mass functions with zero entries, define the affinity for and use , taking endpoint limits when needed. This avoids an ambiguous convention. Identical laws give ; disjoint probability supports give , because one observation separates them perfectly. The displayed finite-rate theorem concerns fixed laws with common positive support, not laws that change with or arbitrarily dependent repeated observations.
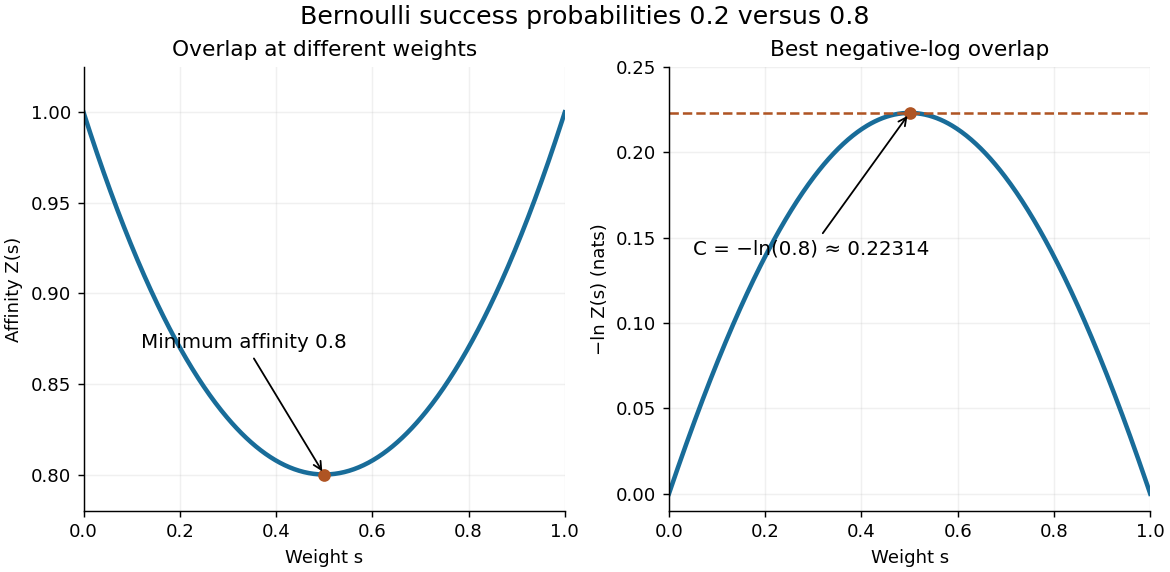
For probability mass functions , their Chernoff affinity at is the sum . It weights pointwise agreement between the two laws. The weighted arithmetic-geometric mean inequality gives , hence . With positive common support, . Smaller affinity means a stronger separation at that weighting.
At , is the Bhattacharyya coefficient. The quantity is the Bhattacharyya distance. Allowing all weights gives Chernoff information at least this large. Symmetry under exchanging sends to , so Chernoff information is symmetric even though an optimizing weight need not be .
For equal prior probabilities and independent and identically distributed observations on a finite alphabet, minimum sum of errors in a simple hypothesis test givesFor nonnegative and , . Applying this termwise and using the independence of random variables to factor the sum yieldsOptimizing , with an infimum if needed, proves . This short argument gives a bound for every . The theorem identifying the optimal error exponent also needs the converse: no decision rule can achieve a strictly larger limiting exponent. A log-likelihood ratio is a sum of independent contributions, so large deviation principle supplies the relevant converse idea.
Let be the Bernoulli distribution with success probability and the Bernoulli distribution with success probability . For ,The two summands have product . Their arithmetic mean is at least their geometric mean, with equality at . ThusThe same argument gives for complementary parameters . At the laws agree and .
With equal prior probabilities, count the successes among observations. The likelihood ratio is , so choose when and when . If is even, either decision or a fair tie randomization gives the same average error at . Under , has the binomial distribution with parameters . Symmetry therefore gives the exact optimal average errorThe last term applies only for even ; it represents half the tie probability. Direct finite sums give , and . Twenty observations reduce the optimal average error to about 0.158%. The finite-sample Chernoff error bound at is , a guarantee rather than the exact error.
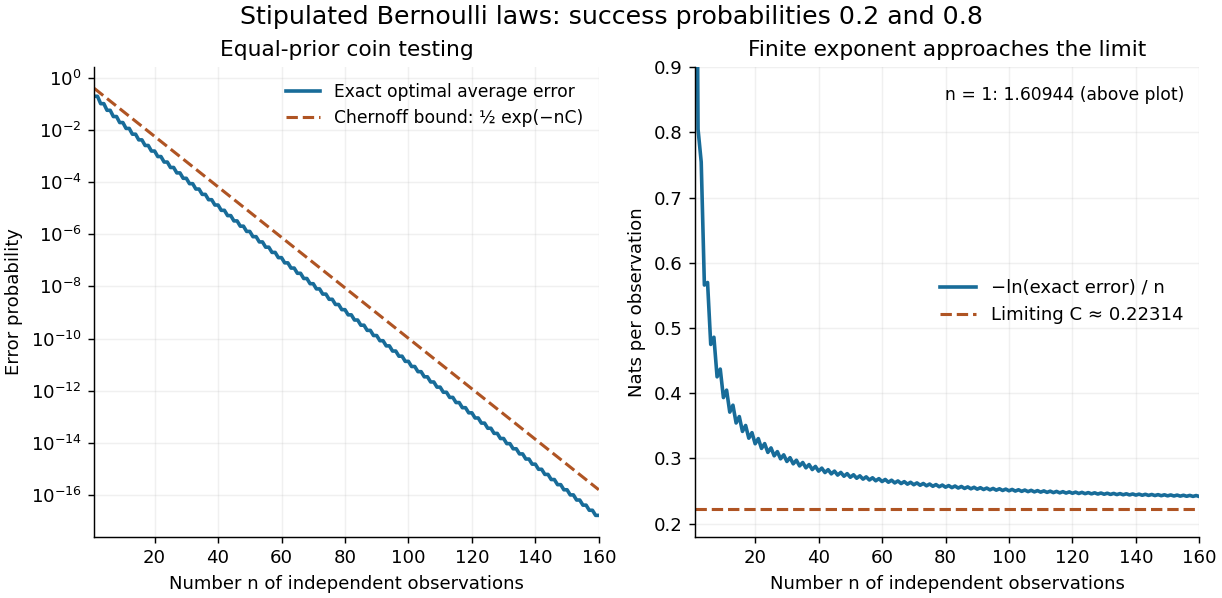
Exact repeated-coin error, the finite-sample Chernoff error bound, and the limiting error exponent
. Original finite-binomial calculations under two fixed independent coin laws with equal priors. The first panel uses a logarithmic scale. The normalized negative log error approaches ; finite-sample error need not equal the simple exponential. Details.Reducing the exact error from to illustrates the value of repeated evidence. The example assumes a single fixed coin law throughout the experiment. If repeated sensor readings share an unmodelled common error, increasing their number need not supply this much independent information.
Stanford's archive records a technical report by Herman Chernoff, dated November 1951, on asymptotic efficiency of hypothesis tests based on sums of observations.[ref]
A Measure of Asymptotic Efficiency for Tests of an Hypothesis Based on the Sum of Observations, technical report by Herman Chernoff. Stanford Statistics technical-report record: SOL ONR 6, author H. Chernoff, report date November 1951
This is historical source metadata, rather than a claim to have inspected the report's full proof. The modern theorem cited above connects that efficiency question to the log-likelihood ratio accumulated across repeated observations.For distinct probability distributions , the optimal error exponents in hypothesis testing give type-II error decay rate among tests whose type-I error stays below any fixed number in .
The Neyman-Pearson lemma says that an optimal region accepting has the likelihood-ratio formwith possible randomization on the boundary.
Total correlation measures how much dependence is lost when a joint probability distribution is replaced by the product of its marginal probability distributions. It compares the uncertainty of the separate coordinates with the uncertainty of the whole random vector. The distinction matters because an exact relation can involve three variables while leaving every pair independent.
For random variables with finite alphabets, defineHere is information entropy, the entropy of the full random vector is joint entropy, and is relative entropy. Base-two logarithms give bits; natural logarithms give nats. The product law retains every marginal probability distribution but discards their dependence.[ref]
Information Theoretical Analysis of Multivariate Correlation by Satosi Watanabe. Abstract, printed p. 66: total correlation for the partition into individual variables
A positive joint probability guarantees positive marginal probabilities at that outcome, so the displayed relative entropy is finite in this finite-alphabet setting.For two variables, total correlation is exactly mutual information. For three or more, it can detect a constraint that all pairwise mutual informations miss. Relative entropy nonnegativity gives , with equality exactly when the coordinates are jointly independent random variables.
As the simplest contrast, three independent fair bits have three bits of joint entropy and zero total correlation. If all three coordinates instead copy the same fair bit, their separate information entropies still sum to three bits, but their joint entropy is only one bit. Their total correlation is therefore two bits. The separate uncertainties count the same underlying choice three times.
Let be independent fair bits and set , their exclusive or. The four possible triples are , each with probability . Every coordinate is fair, and every pair has all four outcomes with equal probability. Thus each pair's mutual information is zero, as in pairwise independence does not imply joint independence.
The full random vector has joint entropy bits, while the marginal information entropies sum to three bits. ConsequentlyThe product of the marginals predicts probability for every triple, including the four impossible ones. On each possible triple, the ratio of true to product probability is ; averaging its base-two logarithm gives the same one bit of relative entropy.
The example gives a concrete use for joint information measures. A lossless source coding scheme that treats the three coordinates separately needs three bits here. If the decoder knows the integer parity rule, the encoder can send just and let the decoder reconstruct exactly. Pairwise independence does not reveal that saving. This is a stipulated source law and an explicit two-bit code, rather than a promise that arbitrary data can be shortened.
Keep as independent fair bits, introduce an independent Bernoulli random variable with , and set . The extra bit flips the integer parity rule with probability . For each even-integer parity triple the probability is ; for each odd-integer parity triple it is .
Every coordinate remains fair, and every pair remains independent for every . For example, after fixing , the fair independent makes fair regardless of . A pair's joint probability distribution therefore does not change as noise destroys the three-way relation.
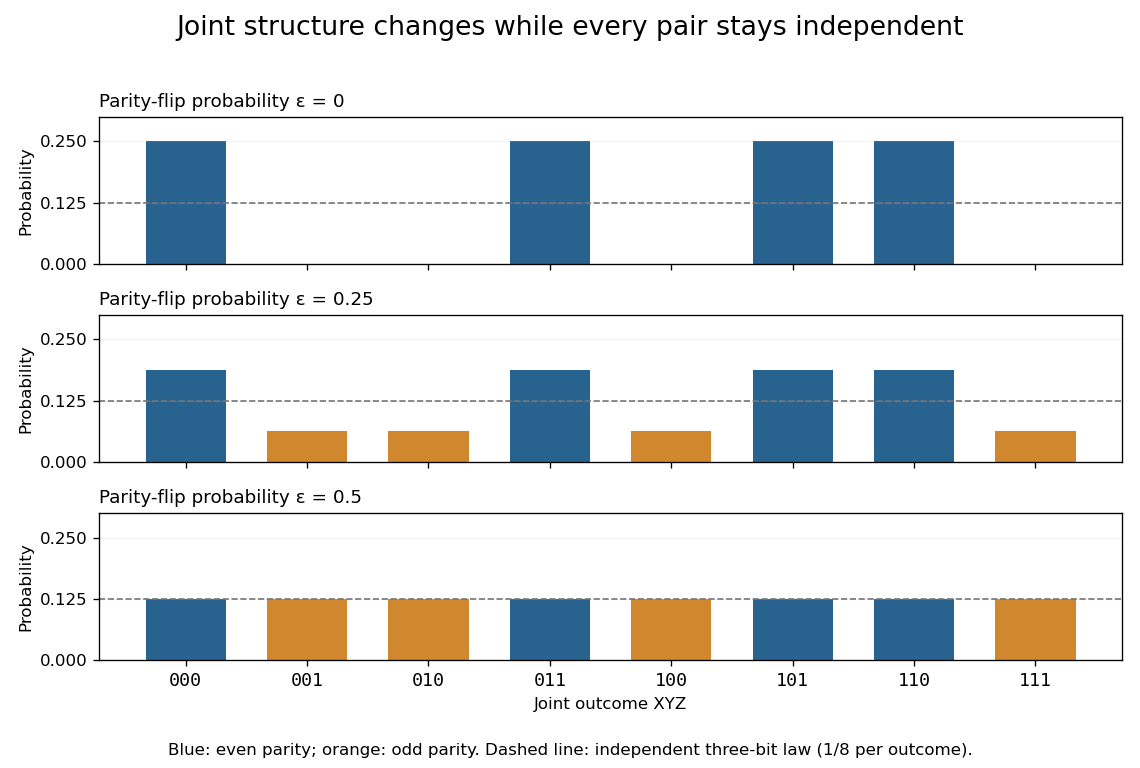
Knowing , uncertainty in is exactly the uncertainty in . The chain rule for information entropy giveswhere is binary entropy. HenceAt , the result is approximately bits, although all three pairwise mutual informations are zero. At , all eight triples have probability , giving joint independence and zero total correlation. At , the complementary integer parity rule is deterministic again, so total correlation returns to one bit.
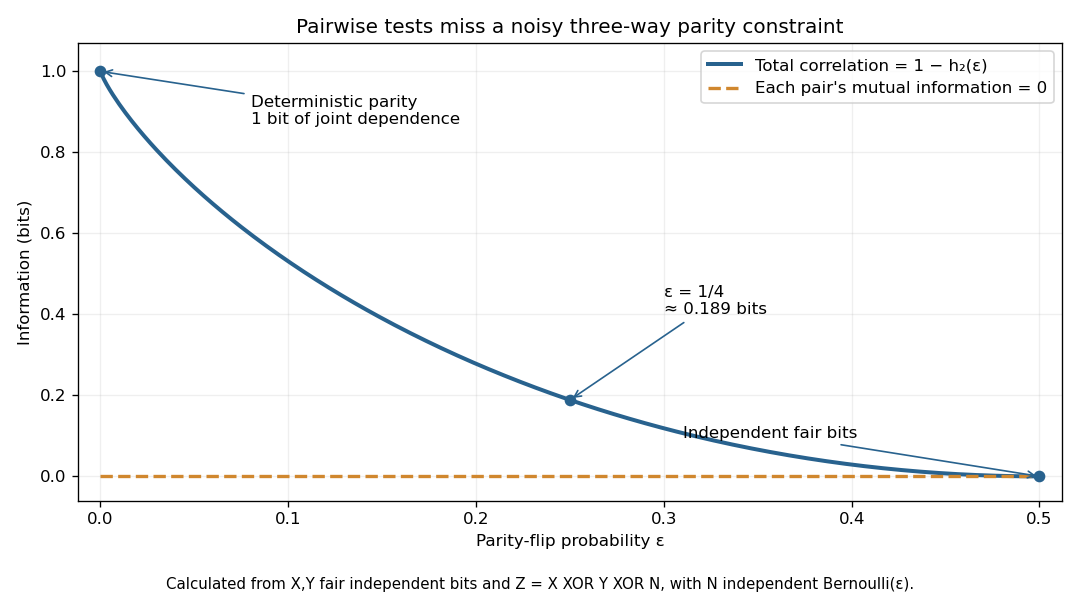
The example distinguishes "there is a dependence" from "a pair reveals it." Once are known together, is predictable at zero noise; knowing either one alone leaves a fair bit. Total correlation detects the joint departure from independence, but does not by itself specify which variables cause which others.
For finite alphabets, expanding joint entropy with the chain rule for information entropy givesEach term is mutual information with an entire preceding block, rather than necessarily with one preceding variable. Changing the order changes these individual terms but leaves their sum unchanged.
For the noiseless parity constraint and total correlation, and bit. The conditional block term supplies exactly the dependence that the pairwise comparisons missed. For three identical copies of a fair bit, the two block terms are both one bit. Thus total correlation counts total departure from the product law, not merely the presence of a single irreducible multiway relation.
Let be a joint probability distribution on a finite product alphabet, with marginals . Compare it with a product model , assuming wherever . Adding and subtracting the logarithm of givesThe first term is the unavoidable error from discarding dependence; the other terms are errors in the individual marginal probability distributions. Averaging a term that depends only on under is the same as averaging it under , which proves the identity directly.
Among product laws, the choice minimizes this relative entropy, leaving exactly total correlation. The related cross-entropy equals entropy plus relative entropy identity interprets this as extra average logarithmic loss from using the independent model. It is a statement about a specified joint law and loss function, not a claim that fitting a finite sample automatically recovers that law.
For finite alphabets, , soFor identical copies of one fair bit, the upper bound is attained and total correlation is bits. Adding another copy increases the result without introducing a new underlying random choice. The choice of coordinates and their grouping therefore matters when comparing systems of different sizes.
For more general random variables, the relative entropy against the product of the marginals supplies a definition of total correlation that may be infinite. Subtracting differential entropies is justified only when those quantities are finite and the entropy identity is valid; an undefined difference of infinities is not a definition. The finite-alphabet examples above avoid that problem entirely.
The abstract of Information Theoretical Analysis of Multivariate Correlation by Satosi Watanabe (1960, printed p. 66) names the sum of individual information entropies minus joint entropy "total correlation." It presents this as the finest grouping of the variables and identifies applications to geometric pattern recognition and shuffling cards marked zero or one. The name therefore connects the uncertainty of a system with the structure linking its parts; the worked integer parity and noisy-integer parity models here are separate examples calculated from their stated laws.
A type summarizes a string by how often each symbol occurs. Fix a finite alphabet of cardinality and a positive length . For a string , its empirical distribution is the probability mass functionThe empirical distribution forgets order. The strings and both assign probability to each binary symbol; assigns to zero and to one. Thus a long string can have a short summary even though that summary does not reconstruct the original order.
For independent and identically distributed symbols, this loss of order has a useful consequence: all strings with the same empirical distribution have the same probability. The method of types uses this symmetry to turn questions about exponentially many strings into counting questions about relatively few frequency profiles.[ref]
The Method of Types by Imre Csiszár. §I, printed p. 2505: partition by empirical distribution and equiprobability under a memoryless model
For a nonempty string, assign a character its occurrence count divided by the string length. Counts partition the character positions, proving normalization. Empty input has no total count to normalize and needs an explicit alternative contract or rejection. A Scala Char implementation counts UTF-16 code units unless a separate code-point representation is introduced.
For independent and identically distributed observations from a probability mass function on a finite alphabet, expected relative entropy of the empirical distribution from is nonincreasing in sample size. The leave-one-out identity for empirical distributions and convexity of relative entropy in its first argument giveEvery deletion sample has the law of observations from . Taking expected values proves the assertion without requiring independence between deletion samples. Zero-probability symbols are absent almost surely. Since , the identity also shows that expected empirical information entropy increases towards the source information entropy. Convergence follows from the strong law of large numbers for empirical frequencies and boundedness and continuity of information entropy on a finite probability simplex.
Given observations, let be the empirical distribution of the observations remaining after deleting observation . Their average is the empirical distribution of the full sample. For each symbol, its indicator function for a particular observation appears in exactly deletion samples. Summing the empirical counts and dividing by therefore gives its full-sample frequency. This identity is deterministic and needs neither independence nor identical distributions.
The type class contains all length- strings with empirical distribution . Each must be a nonnegative integer and the counts must sum to ; otherwise the class is empty. Distinct type classes partition : every string belongs to exactly one class.
For four binary symbols there are five type classes, indexed by the number of ones. Their cardinalities are , which sum to . The balanced class contains exactly . These are six different strings, not six different empirical distributions.
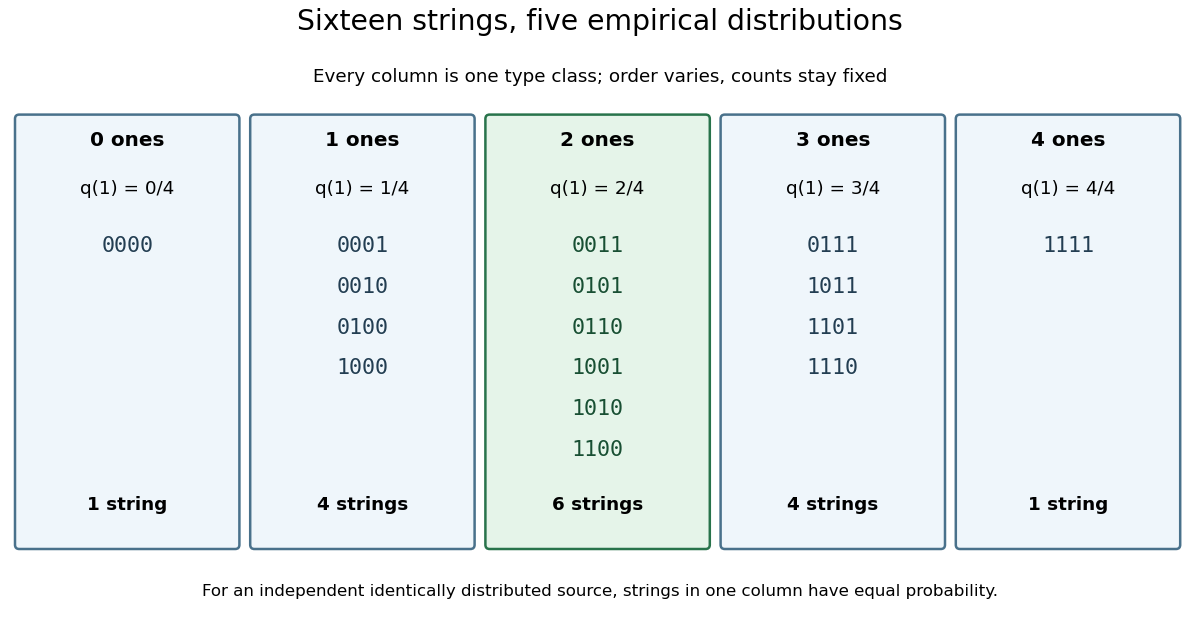
Sixteen binary strings form five type classes
. An exact enumeration of all four-symbol strings. Each column fixes the number of ones; the central column has six orderings of the same empirical distribution. Details.Write . Arranging copies of each symbol gives the multinomial coefficientThe division by the factorials removes permutations among identical copies. In the balanced four-symbol example, . For binary symbols this becomes the binomial coefficient ; for three symbols with counts , the class contains strings.
If a decoder already knows the length, alphabet and empirical distribution, it only needs to distinguish possible strings. A fixed-length index therefore needs bits. List the six balanced four-symbol strings in increasing lexicographic order and number them through . A three-bit index identifies any one of them, whereas writing the original binary string directly takes four bits.
Knowing the empirical distribution is essential to that calculation. If it must also be sent, a simple fixed-length description of which of the five classes was used costs another bits. That naive balanced-string message totals six bits and is longer than the raw four-bit string. The example demonstrates the benefit of shared constraints, rather than a free lossless source coding scheme for every input. For long strings over a fixed alphabet, the overhead for identifying a class grows only logarithmically with length, while the information entropy of its frequency profile controls the leading cost within the class.
The method of types combines two facts: there are few possible empirical distributions, and strings within each type class are equiprobable under an independent and identically distributed source. Information entropy determines how many strings share a frequency profile; relative entropy determines how unlikely that profile is under a specified source law. The connection is useful both for lossless source coding and for understanding rare observations.
The following formulas use natural logarithms, so information entropy and relative entropy are measured in nats. DefineHere is the source probability mass function and is an attainable empirical distribution. Use ; first assume every . Base-two logarithms give the equivalent formulas with and .
A possible empirical distribution corresponds to nonnegative integer counts with sum . Stars and bars therefore givesThe bound also follows by letting each count independently range from zero to , which overcounts tuples whose sum is wrong. With the alphabet fixed, the count grows polynomially in , whereas there are strings when . For binary symbols there are exactly profiles: the number of ones can be any integer from zero through .
This reduces a rare-event calculation to a sum over profiles when the event depends only on counts. An event that depends on order may instead require counting the relevant subset inside each type class. A source with statistical dependence need not make strings of the same empirical distribution equiprobable; the memoryless assumption cannot simply be dropped.
For an attainable empirical distribution on a fixed finite alphabet of size ,Thus differs from by at most , uniformly over attainable profiles. Information entropy is the leading logarithmic count; the polynomial factor matters at short lengths.[ref]
The Method of Types by Imre Csiszár. §II, Lemma II.2, equation (II.4), printed pp. 2506–2507: type-class cardinality bounds
The upper bound has a short explanation. Under an independent and identically distributed source whose law is itself, each string in has probability . Multiplying by the number of such strings cannot give a probability above one. A corresponding polynomial lower bound follows from the multinomial coefficient; the Stirling's approximation gives sharper prefactors when needed.
For the balanced four-symbol class, , so the upper bound is , while the exact size is six. Information entropy is not an exact count for a short string. On the leading scale it becomes precise: the difference divided by tends to zero as grows with the alphabet fixed.
For a string of empirical distribution , independence givesMultiplying this by the size of a type class gives its exact probability. The entropy bounds for a type class then implyThese bounds apply to one attainable empirical distribution, not automatically to a tail event containing many classes.[ref]
The Method of Types by Imre Csiszár. §II, equation (II.1) and Lemma II.2, equation (II.5), printed pp. 2506–2507
If but , every string in that class is impossible and .As an exact example, take an independent and identically distributed binary source with . Each balanced four-symbol string has probability . There are six such strings, soThe relative entropy is . The exponential upper bound is , visibly larger than the exact probability. It captures the cost of an atypical frequency without supplying the exact finite-length prefactor.
For , the exact probability of twenty ones iswhile the exponential upper bound is approximately . At the source frequency , relative entropy is zero and the upper bound is one; the exact probability of ten ones is only about . A likely neighborhood of frequencies need not give a large probability to a single exact profile.
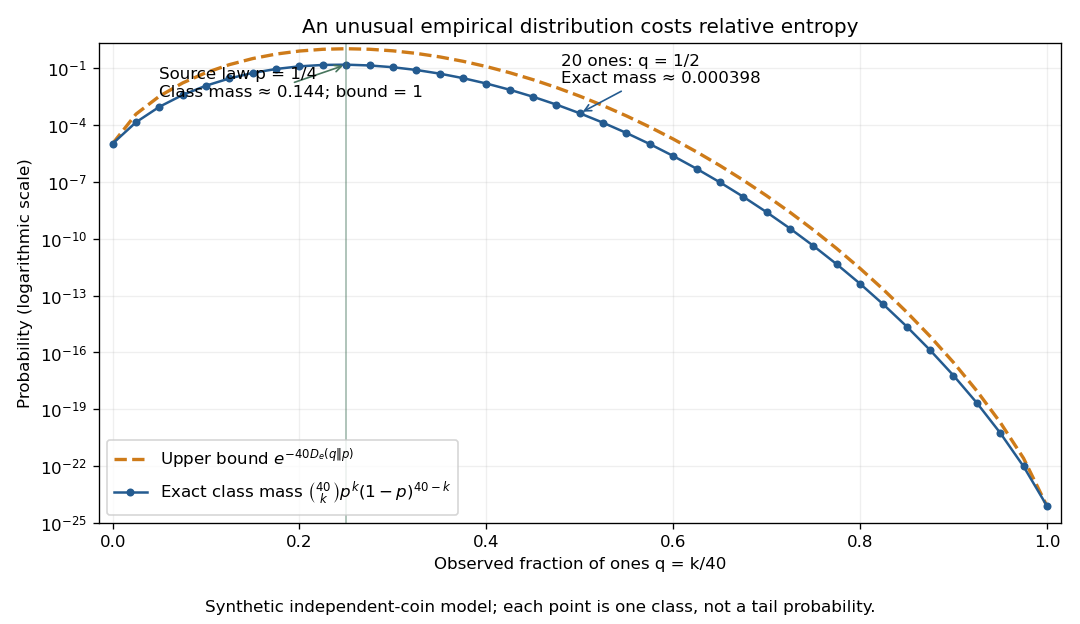
The striking cancellation is that there are about strings in a class, but each costs about . The information entropy terms cancel, leaving relative entropy as the rarity exponent. Summing over polynomially many classes preserves that leading exponential scale. This is the elementary counting mechanism behind finite-alphabet versions of Sanov theorem and many error exponents in hypothesis testing.
In his 1998 retrospective, Imre Csiszár describes the method of types as a 1970s refinement of the typical set approach, with older counting ingredients. He credits his research group with turning those ingredients into a general tool, while explicitly declining to give a complete discovery history.[ref]
The Method of Types by Imre Csiszár. §I, printed pp. 2505–2506: the refinement in the 1970s and the author's qualified historical account
The useful shift is from an approximately typical collection to exact frequency classes: the latter retain enough structure to study how fast error probabilities decay.Sanov's theorem is the large deviation principle for empirical distributions of independent identically distributed observations. On a finite alphabet with sampling law , its rate function is .
An information projection chooses the probability distribution that satisfies a constraint while departing least from a reference law in relative entropy. The constraint might specify an expected value, several marginal probability distributions, or another convex set of permissible laws. The reference is held fixed: the variable is the first argument of . Reversing the arguments gives a different minimization problem.
For a finite alphabet , take a positive reference probability mass function and a nonempty closed convex set in the probability simplex. ThenThe minimum exists and its minimizing probability distribution is unique. In this article, natural logarithms give nats. Using base-two logarithms rescales the objective without changing the minimizer.[ref]
Information Theory and Statistics: A Tutorial by Imre Csiszár and Paul C. Shields. §3, printed pp. 440–441: finite-alphabet information projection onto a closed convex set
If already meets the constraint, its information projection is itself by relative entropy nonnegativity. If not, a constraint can change the relative weights of outcomes without specifying every weight individually. Relative entropy minimization under a mean constraint gives an especially useful example: it tilts the reference law rather than choosing an arbitrary distribution with the right average.
Let the possible numerical outcomes be , and give the reference law uniform distribution on a finite set: . We want a law with expected value . Write the three probabilities in outcome order as . The mean constraint is , while normalization requires .
These conditions leave a whole line of possible probability distributions:For example, and both have the required mean. The constraint alone does not choose between them. Information projection selects the point on this line with the smallest relative entropy from the reference.
Exponential tilting gives weights proportional to . Set and multiply these weights by to obtain . Enforcing the mean givesThe positive root is , henceThe most favored outcome becomes , but all three remain possible. This is an exact constructed example with a stipulated reference law and constraint, not a fitted distribution from measurements.
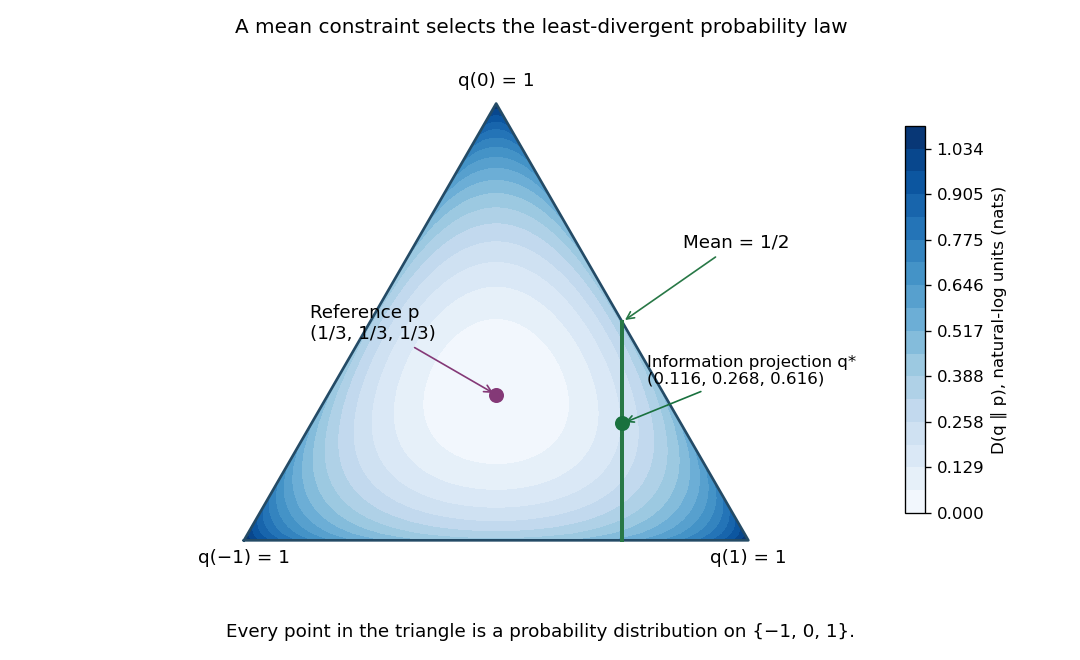
The word "projection" does not mean ordinary perpendicular projection in the plotted Euclidean space. For the same reference and mean constraint, minimizing the squared Euclidean distance in the three probability coordinates instead givesThus the Euclidean minimizer is , whereas the information projection has . The squared Euclidean objective at its own minimum is ; its relative entropy is approximately nats, larger than the optimum nats. Both distributions satisfy the same constraint.
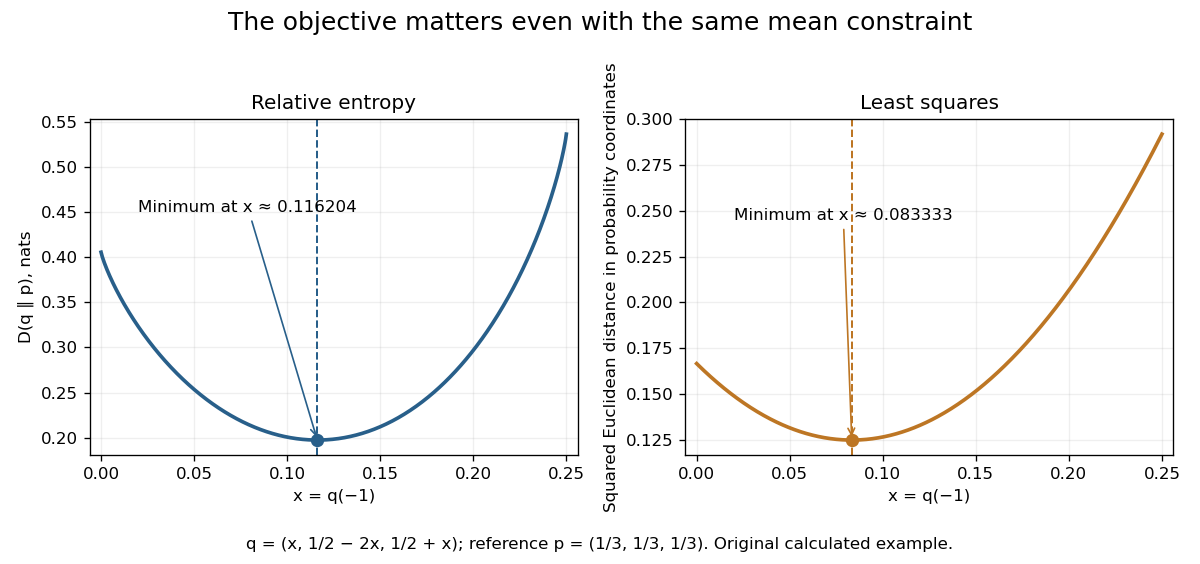
The reference and objective encode what "least change" means. Relative entropy is asymmetric and is not a metric; its minimization answers a different question from linear least squares. The useful geometric analogy comes from a Pythagorean inequality for information projection, rather than from an assertion that the colored contours are circles.
For a uniform distribution on a finite set of outcomes, direct expansion of relative entropy giveswhere is information entropy in nats. Therefore minimizing relative entropy from this particular reference is equivalent to maximizing information entropy subject to the same constraint. This statement depends on the uniform reference; an arbitrary reference contributes its own weights.
In the three-outcome example, nats. The mean fixes one aggregate quantity, and information projection chooses how to distribute the remaining uncertainty. This extends maximum entropy on a finite alphabet, whose unconstrained maximizer is the uniform law itself.
Under the finite-alphabet, positive-reference, closed-convex set assumptions above, every feasible law satisfiesThus a feasible law's excess relative entropy above the optimum is at least its relative entropy from the optimizer. The information projection supplies a quantitative comparison with every other feasible law, not merely the location of a minimum.[ref]
For affine expected value constraints, the result becomes a Pythagorean identity for relative entropy. In relative entropy minimization under a mean constraint, the logarithm of is an affine function of the outcome . Any feasible has the same normalization and mean as , making the residual in the three-point identity for relative entropy zero.[ref]
Let be a probability mass function on a finite alphabet with numerical outcomes . Prescribe a mean strictly between the smallest and largest outcomes. Exponential tilting giveswith chosen so that . For any other feasible law , direct substitution yieldsRelative entropy nonnegativity therefore proves optimality and uniqueness. At an extreme prescribed mean, feasible laws may have zero probabilities; a finite tilting parameter need not realize them, although a limit can.
Take independent and identically distributed draws from the uniform three-outcome reference above. An observed sample mean at least is unusual because the source expected value is zero. For two draws, the only successful ordered pairs are , giving probability .
For long samples, the relevant empirical distributions have mean at least . The method of types assigns a profile a leading probability cost . The least costly admissible profile is the information projection on three outcomes: in this example the minimizing mean is on the boundary , and the leading exponent is approximately nats per draw. The exponential scale is not an exact finite-sample probability formula.[ref]
The attraction of this connection is that a constrained optimization problem predicts the most probable way an unusual aggregate observation can occur. It links relative entropy, expected value constraints and rare empirical distributions without identifying a rare event with just one exact attainable type class.
In Information Theory and Statistics: A Tutorial by Imre Csiszár and Paul C. Shields (2004, Historical Notes, §3, printed p. 522), the authors connect systematic studies of information projection with earlier relative entropy minimization principles and geometric work, including Imre Csiszár's I-Divergence Geometry of Probability Distributions and Minimization Problems by Imre Csiszár (1975). This is the tutorial's historical account, rather than a claim of one isolated invention. Its finite-alphabet treatment makes the projection identities available without the additional machinery needed for general probability spaces.
Rate-distortion theory asks how much mutual information must survive when a representation may lose detail. Lossy compression groups different inputs into one reconstruction; a distortion measure specifies which differences matter. The rate-distortion function then gives a quantitative tradeoff between allowed expected distortion and the required number of bits. A smaller file is useful only if its reconstruction retains the distinctions that the application needs.
Fix a finite source alphabet , a probability mass function , a finite reconstruction alphabet , and a nonnegative distortion measure . The information rate-distortion function isThe source probability distribution stays fixed; the conditional distribution of the reconstruction is what we optimize. Each feasible test channel must keep expected distortion at most . The objective is mutual information, measured in bits when the logarithms have base two. If no test channel satisfies the constraint, the infimum is .[ref]
Consider independent and identically distributed fair bits and Hamming distortion, which charges one for an incorrect bit. At zero expected distortion, every bit must be reconstructed correctly, and . If an average fraction of incorrect bits is allowed, the binary rate-distortion function givesHere is binary entropy. This is an asymptotic limit for long block codes, rather than a claim that a single bit can be stored in physical bits. The three-bit lossy Hamming code gives a small, fully explicit version of the same tradeoff, with rate and expected distortion .
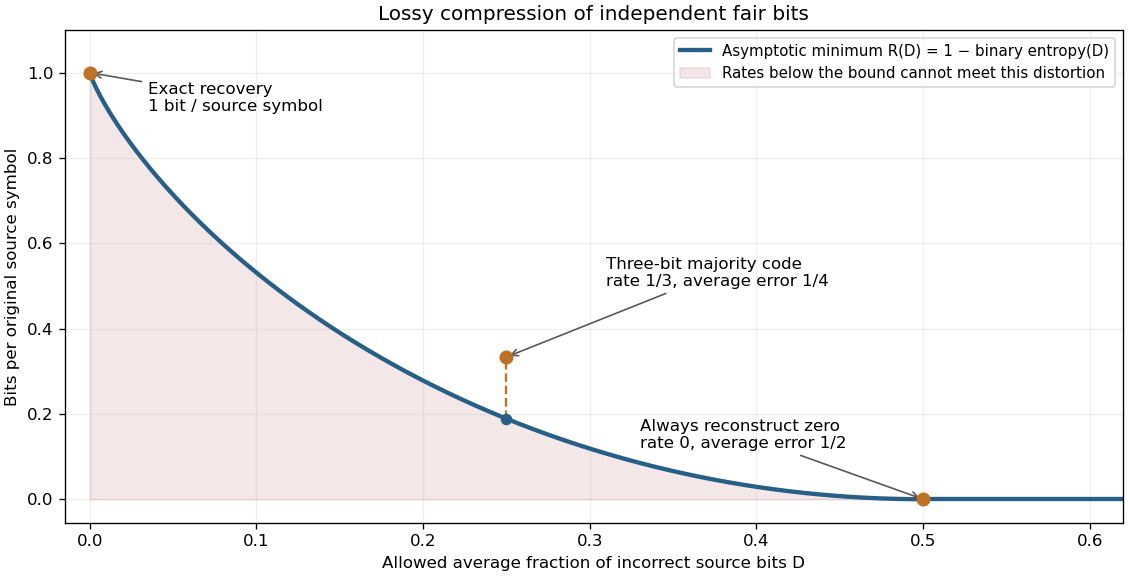
Allowing more incorrect fair bits lowers the asymptotic information rate
. The curve is the exact binary rate-distortion function. The marked three-symbol code has rate at expected distortion ; its gap above the curve shows that a small explicit block code need not attain the asymptotic bound. Rates count bits per original source symbol. Details.Rate-distortion theory separates the question of what is possible from the design of a practical encoder and decoder. It also forces the fidelity criterion to be explicit. Hamming distortion treats all symbol mismatches alike; mean squared error instead penalizes larger numerical errors more strongly. Those objectives can favor different reconstructions of the same data. An average error criterion does not by itself control the error on every individual input.
Claude Shannon's Coding Theorems for a Discrete Source With a Fidelity Criterion by Claude Shannon was published in 1959. Its formulation fixes a cost for replacing one source letter by another and studies the communication rate compatible with the allowed average cost. The important shift is to quantify which distinctions may be discarded, rather than requiring exact recovery of every letter.[ref]
A distortion measure assigns a nonnegative cost to replacing a source symbol by a reconstruction . It need not be a metric: the two alphabets may differ, and neither symmetry nor the triangle inequality is required. Choosing the cost is part of the model. For numerical symbols, gives mean squared error after averaging; for exact symbol agreement, use Hamming distortion.
The reconstruction alphabet is the set of values that the decoder may output. It need not equal the source alphabet. A restricted reconstruction alphabet can prevent zero expected distortion, even if the representation is allowed arbitrarily many bits.
Expected distortion is the expectation of the reconstruction cost under the joint probability distribution of and . It weights common source outcomes more strongly than rare ones. A bound on expected distortion is therefore different from a bound on the cost for every input, or on the probability of exceeding a specified cost.
For a block code, separable distortion is the average of the individual symbol costs. With Hamming distortion it is the fraction of incorrectly reconstructed symbols, rather than the unnormalized number of mismatches. This normalization makes expected distortion comparable across different block lengths.[ref]
A test channel is a proposed conditional distribution of a reconstruction given the source symbol. It describes a candidate joint probability distribution for evaluating mutual information and expected distortion. It need not be a physical transmission channel, or an implementable one-symbol encoder; the Shannon rate-distortion theorem relates this optimization to long block codes.
Hamming distortion is zero for a correctly reconstructed symbol and one for a mismatch. Its expected distortion is the symbol-error probability:For strings of length , separable distortion divides their Hamming distance by . Thus reconstructed as has Hamming distance one and average Hamming distortion . Counting only whether the whole string is correct would give a different criterion.
Let be independent fair bits. The encoder sends their majority bit: zero when at least two inputs are zero, and one otherwise. The decoder reconstructs or by repeating that received bit three times. This is lossy compression: different original strings deliberately share a reconstruction.
There are eight equally likely inputs. The strings and have zero Hamming distance from their reconstructions; each of the other six has Hamming distance one. One transmitted bit represents three source symbols, soEvery input has average Hamming distortion at most , whereas the population average is . The actual block code therefore obeys , but does not reach the optimal long-block rate.
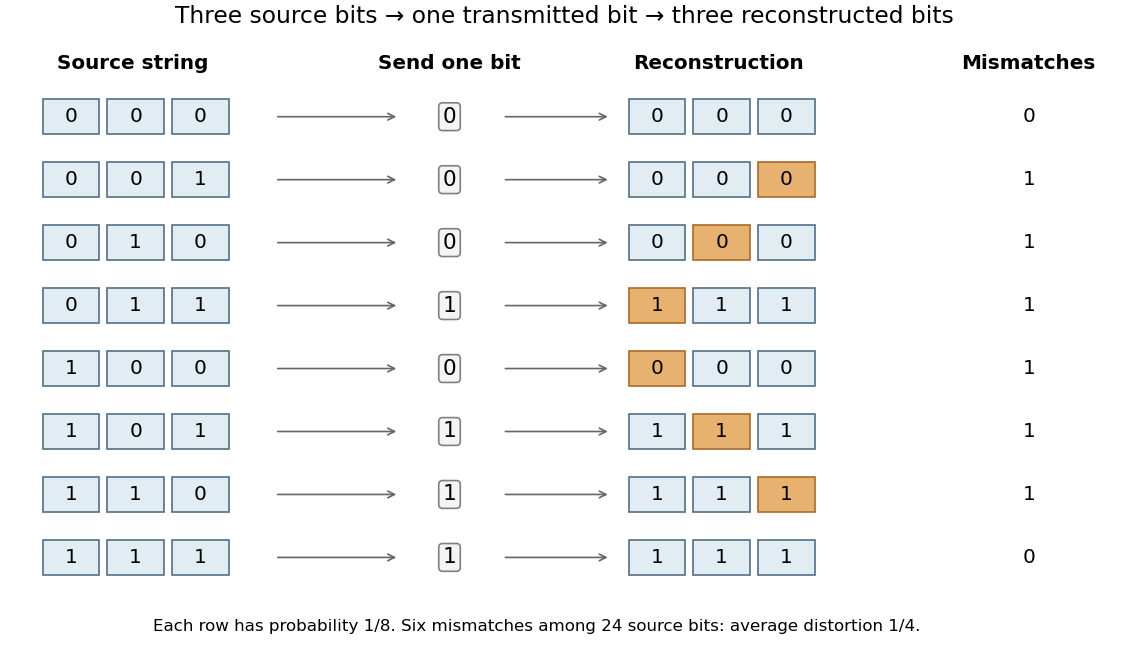
This construction uses the same reconstruction strings as the threefold binary repetition code, but the tasks differ. An error-correcting encoder expands one source bit into three transmitted bits; this lossy compression example compresses three source bits into one transmitted bit. The source distribution and the direction of the mapping matter.
For a stationary source of independent and identically distributed fair bits, with Hamming distortion and binary reconstruction alphabet,The binary entropy convention is . Once , always reconstructing zero meets the distortion constraint without sending any bits. The formula must not be extended to : a looser constraint cannot increase the required rate.[ref]
Chapter 25: Evaluating R(D). Lossy Source-Channel Separation. §25.1.1, Bernoulli Source, printed p. 255
The short argument identifies both sides of the optimum. For any feasible binary reconstruction, put , using exclusive or. Knowing makes and determine one another, so the conditional entropy obeyswhen . The last step uses the increase of binary entropy on that interval. Hence . Conversely, choose with an independent Bernoulli random variable of parameter . This binary symmetric channel has expected distortion and mutual information , attaining the bound.
Articles were limited to the first 100 out of 211 total.
Articles by others on the same topic

Information theory is a branch of applied mathematics and electrical engineering that deals with the quantification, storage, and communication of information. It was founded by Claude Shannon in his groundbreaking 1948 paper, "A Mathematical Theory of Communication." The field has since grown to encompass various aspects of information processing and transmission. Key concepts in information theory include: 1. **Information**: This is often quantified in terms of entropy, which measures the uncertainty or unpredictability of information content. Higher entropy indicates more information.



