The initial table of content was limited to the first level because it is larger than 1000 articles. There are 5767 articles in total. Expand a branch to load its children.
A probability plot compares order statistics with plotting positions or model quantiles to diagnose whether a proposed probability distribution describes data. If the model can be transformed into a linear identity , plot against . Approximate linearity supports that model's shape; systematic curvature suggests a mismatch.
The plotting position comes from the exact mean of the th uniform order statistic, by the probability integral transform. It does not assert equality between the expectation of a nonlinear transformation and that transformation of the expectation. Fitted slope and intercept can estimate model parameters, but the visual plot alone is not a calibrated hypothesis test.
For a sample or finite biological population of positive size , the relative frequency of a category represented times is . It is a proportion and differs from an oscillation frequency.
Random variation represented by a probability distribution or stochastic process, whether from intrinsic events or an uncertain environment.
Descriptive statistics summarizes observed data, for example through location and spread statistics or graphical summaries such as a histogram.
A table of category counts, often accompanied by sample proportions or percentages. Its denominator must be stated, especially when observations contain missing data.
The expected value of the number of observations in a category under a specified statistical model. For observations with common category probability , linearity of expectation gives ; the calculation does not itself require independence. In a contingency table, fitting independence gives . These are model-based counts, which may be fractional, rather than an additional set of observed responses. Pearson's chi-squared test compares observed counts with their corresponding expected frequencies.
The sum of category percentages up to a specified position in an ordering. It has a substantive interpretation for an ordinal categorical variable; the cumulative percentage of an arbitrarily ordered nominal categorical variable changes when the labels are reordered.
A percentage whose denominator excludes observations missing the variable being summarized. It can differ from a percentage calculated over the complete dataset's sample size. Valid percentages for two different variables need not use the same observations.
A mode is a value at which a probability mass function or specified probability density function attains its largest value. There may be more than one. For the normal distribution the unique mode equals the mean; the Maxwell speed distribution has mode and a larger mean speed. For a continuous probability distribution, a mode maximizes density rather than the probability of an exact value, which is zero. Density modes can change under a nonlinear change of variables, as the distinction between Maxwell-Boltzmann velocity distribution and Maxwell speed distribution illustrates.
A scatter plot represents paired quantitative observations as points in a coordinate plane. Group labels, uncertainty and transformations can reveal nonlinear patterns or heterogeneous associations that a single correlation coefficient conceals. A visual association does not establish causation.
A box plot compresses a statistical sample into a box spanning its lower and upper quartiles , a line at its median , and two whiskers. It makes location and central spread easy to compare across groups on a common value axis. The box represents the central half in terms of quantile levels; with ties or interpolated quartiles, it need not contain exactly half the observations. Whisker endpoints require a stated convention: they can be the observed extremes, or they can stop short of separately marked observations. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/boxplot.htm. NIST/SEMATECH, Box Plot, definition and variants
Here is one explicitly toy dataset, reused under histogram: twelve invented, unitless values, with repeated values counted separately, already arranged as order statistics:For this box plot we choose the interpolated quartiles defined under quartile, using R's type-7 rule. This givesThe interquartile range is . Our whisker convention uses the fencesThe whiskers end at the smallest and largest observations in the closed interval : here and . Values strictly outside the fences receive separate outlier markers: here only . An observation exactly on a fence is retained within the whisker under this convention. The fences are thresholds, not observed whisker endpoints; the upper whisker is at , not . R's documented whisker rule likewise includes observations no more than box lengths away, although its box uses hinges, which can differ from our type-7 quartiles. [ref]
https://stat.ethz.ch/R-manual/R-devel/library/grDevices/html/boxplot.stats.html. R grDevices documentation, boxplot.stats, coef and hinges
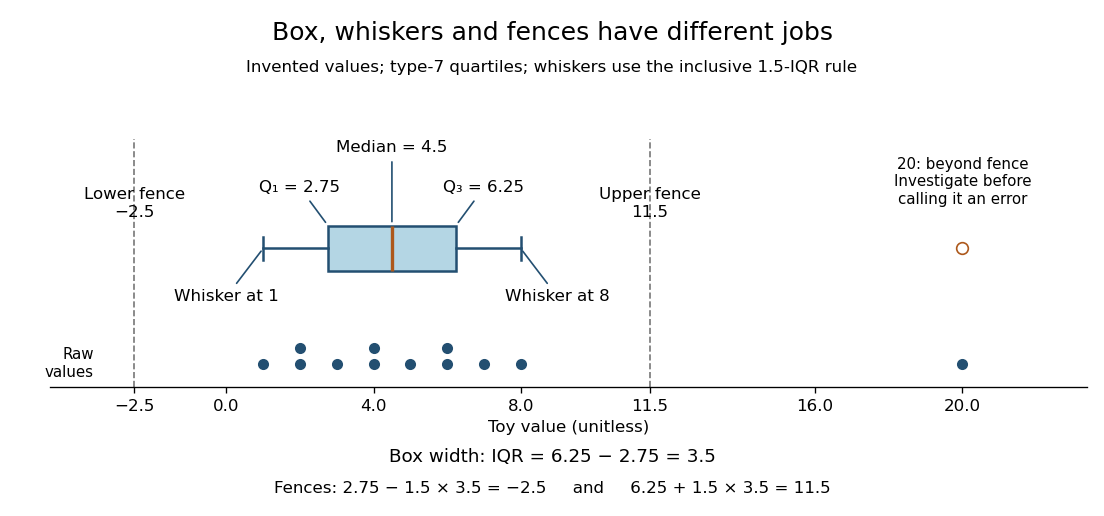
A separate outlier marker is a prompt to investigate, not a finding that the value is bad data and not an instruction to delete it. A distant observation can be a recording error, a legitimate unusual outcome, or evidence that the assumed statistical model misses some behavior. Check its provenance and context before deciding how to analyze it. No measurement-error claim is possible for our invented : we deliberately put it there to demonstrate the rule. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/eda35h.htm. NIST/SEMATECH, Detection of Outliers, labeling and investigation
The beauty of a box plot is its compact comparison of ordered positions rather than every observation. That compression also loses information: many different statistical samples have the same quartiles and whiskers, so the box alone cannot reveal every cluster or gap that a histogram might show. For example, replacing the two invented values by and leaves the type-7 quartiles, whiskers and separate marker unchanged. Displaying the individual values alongside the box plot is especially helpful for such a small statistical sample. Always state both the quartile rule and the whisker rule; changing either can change which values are marked.
Quartiles are the quantiles at probability levels ; is a median. For a population we can use its quantile function, for . Finite-sample conventions differ. Our box plot uses linear interpolation between order statistics: for and , setThen . This is R's type-7 convention, described in the documentation authored by Ivan Frohne and Rob J Hyndman. It differs from the generalized-inverse sample quantile defined elsewhere in this wiki: for the twelve toy values, that rule selects ranks and gives , rather than . These are different stated conventions, not arithmetic disagreements. [ref]
https://stat.ethz.ch/R-manual/R-devel/library/stats/html/quantile.html. Frohne and Hyndman, R stats documentation, sample quantile types
The interquartile range measures the width between the lower and upper quartiles, in the same units as the observations. It describes central spread rather than the distance between the observed extremes. In our toy box plot, ; moving the largest value from to would leave the quartiles and interquartile range unchanged under the chosen rule, because the order statistics used in their interpolation would not change.
A histogram groups numerical observations into adjacent intervals called bins and draws one rectangle per bin. Its attraction is that a long list of values becomes a visible pattern of concentration, gaps and skewness. Specify the bin edges, the treatment of values on those edges, and what the vertical axis means: count, proportion, or density. Those choices are part of the graphic. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/histogra.htm. NIST/SEMATECH, Histogram, definition and normalization
Let observations be covered by disjoint bins with positive widths and counts , so . For example, use left-closed, right-open bins, closing the final right edge too. The three common height choices have different meanings:
For the density convention, a histogram is a piecewise constant probability density function estimate:Its normalization follows by adding rectangular areas:If the observations have units, density has reciprocal units; a density height is not a probability and can exceed . With equal bin widths, count heights and density heights differ only by a common scale factor. With unequal widths, count-height areas give wider bins extra visual weight unrelated to their counts. Dividing by width removes that distortion. R's histogram documentation explicitly describes area-one normalization for unequal bins. [ref]
https://stat.ethz.ch/R-manual/R-devel/library/graphics/html/hist.html. R graphics documentation, hist, frequency versus density
Reuse the twelve invented values under box plot, with bins . The counts are and the widths are . Hence the density heights and areas are exactlyThe second and third bars have equal density heights even though the third contains twice as many observations: it is also twice as wide. The last bar contains only two observations; its count-height area would be , larger than the six-observation bar's . Its correct density area is only .
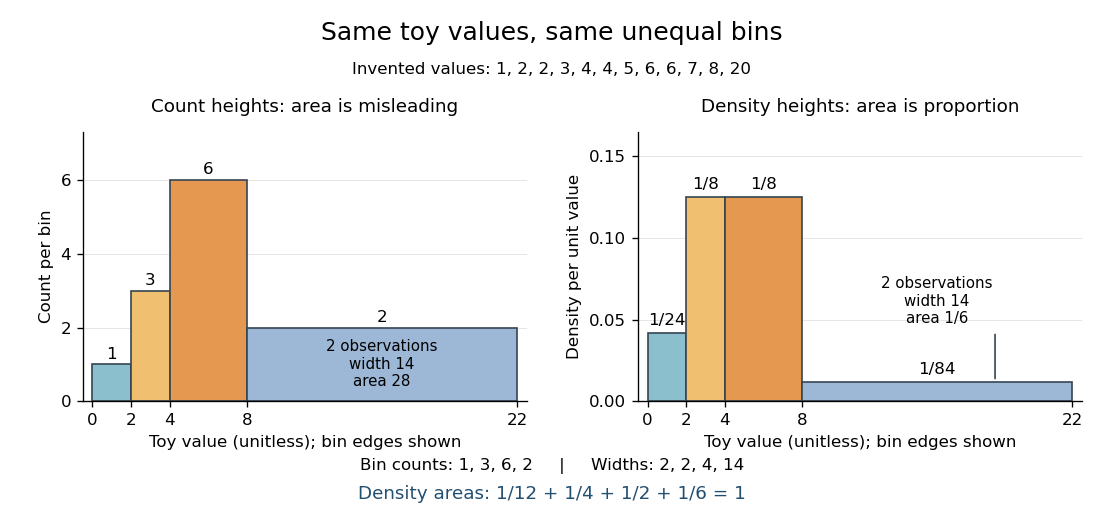
Bin choice trades detail against stability. Broad bins merge distinctions: the toy bin hides the empty stretch between and . Narrow bins expose gaps but can make each individual observation dominate a bar. With one-unit bins starting at , the bins each contain two values and appear equally prominent; that apparent pattern depends on grouping the repeated integers together. Moving the bin origin also changes membership without changing the observations. For density estimation, this is a form of the bias-variance tradeoff: averaging over broad bins loses local detail, while narrow bins give more variable density estimates across repeated statistical samples. [ref]
https://www.stat.cmu.edu/~cshalizi/uADA/24/lectures/ch14.pdf. Cosma Rohilla Shalizi, Estimating Distributions and Densities, Section 14.1
A useful practice is to compare a few plausible widths and offsets, keeping common edges when comparing groups. Automatic bin selectors are starting points, rather than guarantees of a unique correct picture. [ref]https://numpy.org/doc/stable/reference/generated/numpy.histogram_bin_edges.html. NumPy documentation, histogram_bin_edges, Notes on bin selectors
A histogram retains only bin membership. Its density estimate spreads each bin's fraction uniformly across that bin, so our last bar assigns density throughout even though the only toy values there are and . It does not recover within-bin positions or observation order, and a visually convincing shape does not establish a population probability distribution. A box plot provides a complementary compact summary of quartiles; neither graphic replaces the original observations.
The birthday problem asks for the probability that at least two members of a group share a birthday. Use the explicit model of independent random variables taking labels with a uniform distribution on a finite set. Let and be integers. For calendar examples below, stipulate equally likely labels and omit leap days. For , the probability of at least one matching pair isAt , the empty product is one and . At , a repeat is certain by the pigeonhole principle. Count the complement to obtain the formula: the first label has choices, then a distinct second label has , and so forth, out of equally likely label sequences.[ref]
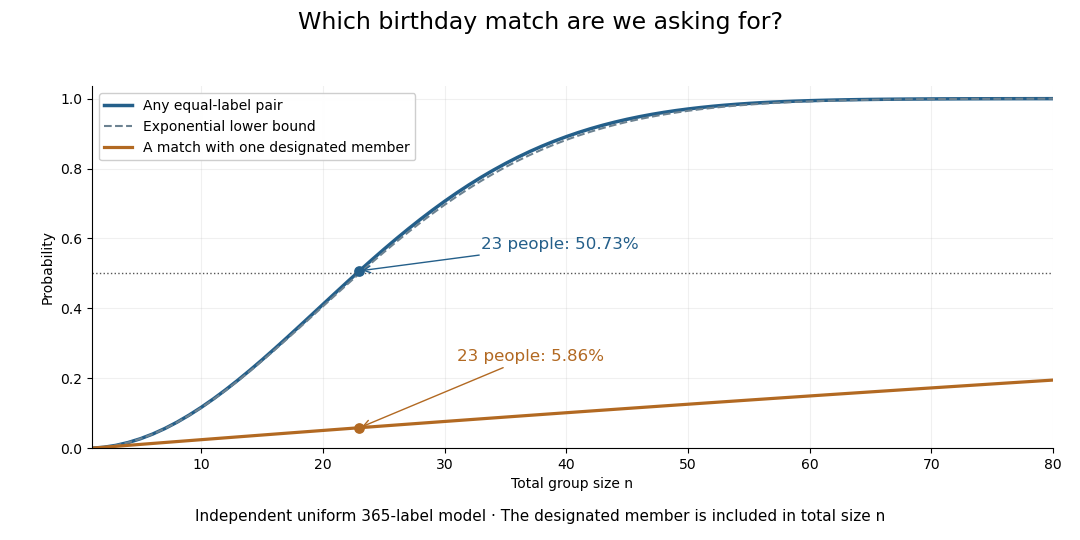
For the stipulated calendar, and . Only 23 people suffice to put the probability above one half. There are possible pairs, each with matching probability . The many comparison opportunities explain why a small group can contain a repeat.
The distinction also matters for hash collisions. If independently generated outputs of a hash function are uniformly distributed over possible labels, the same counting formula governs repeats. The birthday square-root scale explains why looking for any repeated output requires far fewer labels than trying to match one predetermined output. The uniform-independent model is an assumption about those outputs; the birthday problem does not itself establish that a particular implementation meets it.
In a group of total size , designate one member and ask whether any of the other labels equals that member's label. Conditional on the designated label, all the other draws avoid it with probability . Independence givesFor , this is approximately , while the probability of some matching pair is approximately . The designated-member question examines pairs; the any-pair question examines all . A repeated label elsewhere in the group does not require a match with its designated member.
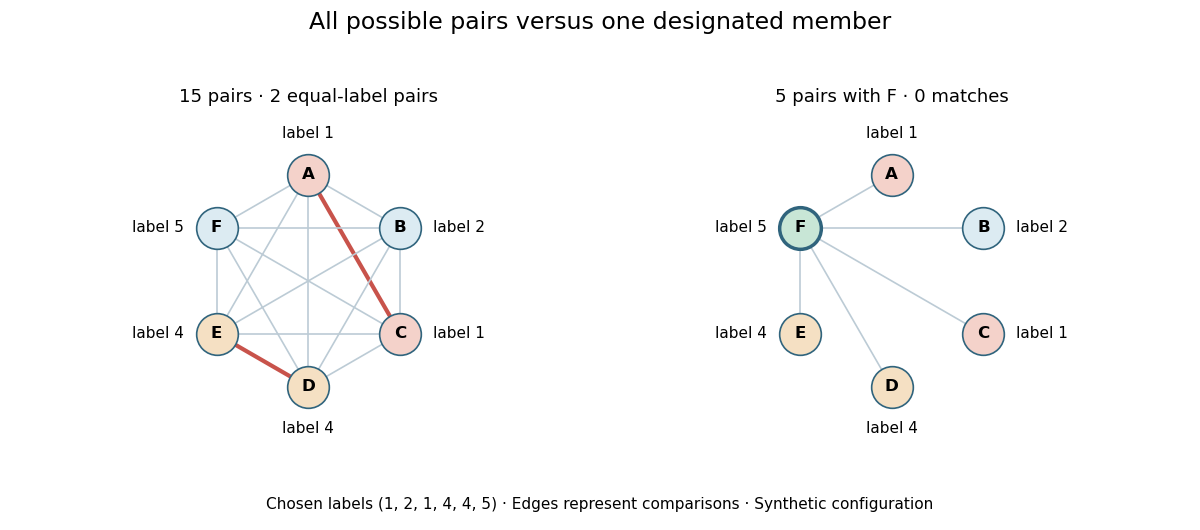
Fifteen possible pairs versus five comparisons with one designated member
. Original illustrative labels for six members: . The complete graph includes every possible pair and marks the two equal-label pairs in red. The right panel uses only pairs containing member F, whose label 5 is unique. This chosen configuration illustrates the two different events; it is not a random sample of measured birthdays. Details.The birthday collision count counts equal-label unordered pairs. Write it as a sum of indicator random variables:This uses linearity of expectation; mutual independence of the pair indicators is unnecessary. For 23 uniform calendar labels, , whereas . A configuration with three equal labels contributes three pairs, so counting pairs and recording whether any pair exists are different random variables.
Treating every pair event as mutually independent would give the wrong exact formula. For three draws, and force . The probability that all three equalities hold is , while the product of their individual probabilities is for . This distinguishes independence of the original label draws from mutual independence of events built from overlapping draws.
The union bound gives . Using on the distinct-label product givesThe lower bound reaches at least one half when . The simple approximation predicts a group size near 23 for . It is the quadratic number of pairs that makes the square root appear.
For a precise limiting statement, let and . Expanding the logarithm of the complement yieldsOn this scale the remainder tends to zero. Thus a fixed substantial collision probability appears after order draws. For uniform output labels, the corresponding scale is order ; matching one specified birthday instead involves a number of draws of order .
Suppose two independent random variables have the same categorical distribution, with label probabilities . The disjoint equal-label events giveFor the original chosen probabilities , this is , rather than the uniform four-label value . The Cauchy-Schwarz inequality gives , so uniform probabilities minimize this two-draw collision probability. This pair formula alone does not supply the entire group collision probability for a nonuniform model.
Actuarial statistics uses probability theory and statistical inference to quantify insurance claims, premiums, and the uncertainty of future losses. Aggregate claims model describes portfolios, reinsurance redistributes losses, and the Bühlmann model combines experience with population information.
A policyholder's future insurance premiums depend on a finite discount level, updated according to whether a claim is submitted in each year. With independent yearly accidents and repair costs, and a claim decision depending only on the current level and cost, the level is a Discrete-time Markov chain. Accident probability and submitted-claim probability differ when the policyholder pays small repair costs without claiming.
In a no claims discount system with discounts , a reported claim resets next year's discount to zero. With no later accidents, the next two premiums after reporting are . At the zero level, not reporting instead gives ; at either other level it gives . Their differences give the displayed repair-cost thresholds. A fully reimbursed loss above its threshold should be reported under this undiscounted two-year rule. Current premiums cancel. Different thresholds generally produce state-dependent submitted-claim probabilities, even with a common accident mechanism.
Let a policyholder have one fixed exponential distribution intensity of rate , with conditionally independent annual Poisson distribution counts. Its one-year marginal count is geometric, but averaging that count does not make the discount process a Markov chain. In the three-level rule, start at zero discount. At time three, the histories and both end at the same top level. The first means three no-claim years, giving next no-claim probability . The second means a positive count followed by two zero counts, giving : divide the integrals of and . These are distinct, so the Markov property fails when only the current discount is recorded. Conditioning on the intensity, or recording its Bayesian posterior, restores the required predictive information.
Suppose annual claim counts are independent with geometric distribution mass , . In a no claims discount system with discounts , a claim returns either of the first two levels to zero; at the top, one claim sends the level to and two or more send it to zero. The transition matrix is . Solving gives the displayed stationary distribution. With full premium , the stationary expected value of the premium is . Independent annual sampling is essential; a persistent random intensity does not justify this marginal transition matrix.
For a three-level birth-death chain whose down-or-stay claim probabilities are , with each in , detailed balance is and . Normalizing gives the displayed stationary distribution. The finite chain is irreducible and has endpoint holding probabilities, so it is aperiodic and its level proportions converge to this distribution from any initial level.
For a no claims discount system with discounts , assume a policyholder starts at , the first claim lowers next year's discount to , and a second claim in the same year lowers it to zero. With no further losses and undiscounted future premiums, claiming for the first loss costs in extra premium. Once that claim is submitted, the second claim adds next year and the year after, a total . Thus the second decision uses the incremental threshold, not the cost of both claims relative to no claim. For independent unit-rate exponential distribution losses the probabilities are and , respectively; the latter remains the conditional probability given submission of the first claim.
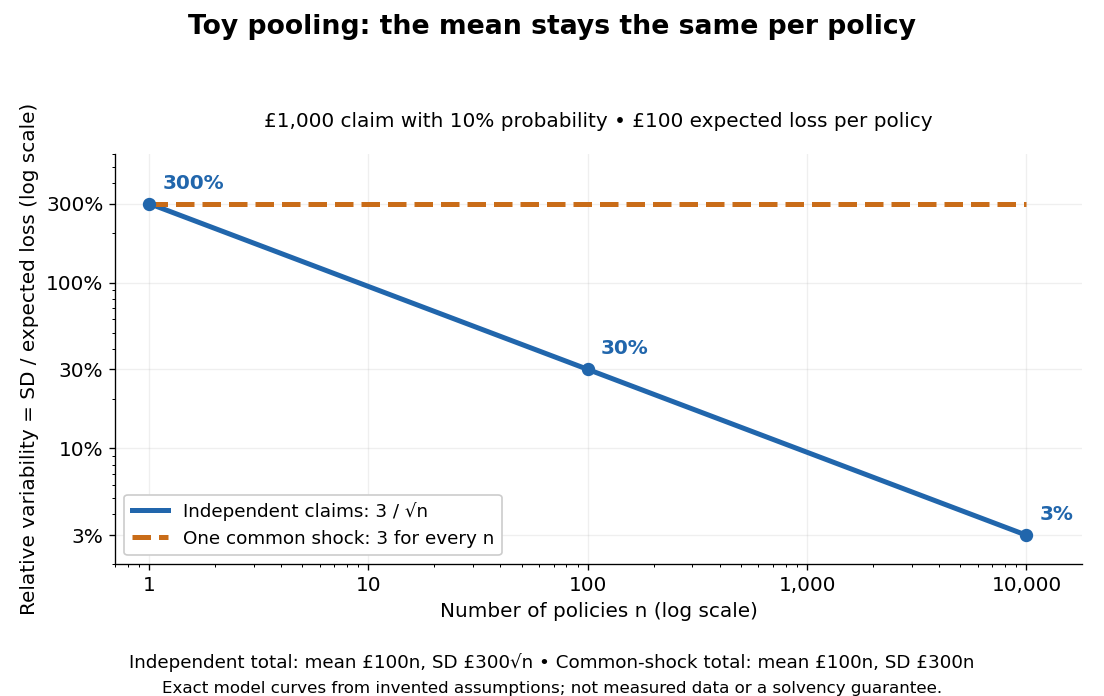
Toy claim pooling: relative variability falls with independence but survives a common shock
. Details. A credibility estimate combines a risk's individual experience with population information. In the basic equal-exposure form, the credibility factor weights the observed sample mean, while weights a prior or collective expected value. The Bühlmann credibility premium is the best affine estimate under mean squared error; an exact Bayesian posterior mean can also have this form, as in the natural conjugate credibility identity.
Bayesian credibility estimates a risk's conditional mean by its Bayesian posterior expected value under squared-error loss. When that posterior mean is an affine combination of exposure-weighted individual experience and a prior mean, the coefficient of the experience is its credibility factor. Exact Bayesian credibility is distinct from merely selecting the best affine estimator when the true posterior mean is nonlinear.
Conditionally independent normal distribution observations of mean and known variance , with normal prior mean and variance , give normal-normal conjugacy with known observation variance. Their posterior mean has the displayed exact credibility estimate form. It minimizes posterior squared-error loss and predicts the conditional mean of the next observation.
For conditionally independent annual averages and prior , the posterior mean is , with . Completing the quadratic likelihood gives posterior precision . This is an exact Bayesian credibility version of the Bühlmann–Straub credibility estimate. Increasing the between-risk prior variance increases the experience weight; increasing process variance decreases it. The next total pure premium is times the estimated per-life mean.
For a common gamma distribution (shape , rate ) frequency prior distribution and conditionally independent Poisson distribution yearly counts of means , observed average amounts determine counts . The posterior distribution shape is and rate is . The future per-policy mean is the display, equal to credibility factor times plus the complementary weight times . The data must lie on their count lattice; impossible noninteger recovered counts have zero likelihood.
// Destination: probability-theory.bigb
For a common success chance with beta prior and conditionally independent binomial observations of sizes , put and . Beta-binomial conjugacy gives posterior mean , equal to . Multiplying by the next exposure predicts its expected count. The factor tends to one as exposure increases and to zero as prior concentration increases at fixed prior mean.
Given a latent risk parameter , observations are independent and identically distributed random variables with conditional expectation and conditional variance . The Bühlmann credibility premium estimates by an affine function of past observations under mean squared error. Its population parameters are , expected process variance , and variance of hypothetical means .
Conditional on a common latent variable , annual averages are independent, have common conditional expectation , and have conditional variance for known positive exposures . Its structural parameters are , expected process variance and variance of hypothetical means . It generalizes the equal-exposure Bühlmann model.
For total exposure and weighted average , the best affine mean squared error estimate of the conditional mean is , where . If the coefficients sum to , their error is . Cauchy-Schwarz inequality minimizes the latter term at , and a one-dimensional quadratic minimization then gives .
With a Poisson-gamma conjugacy with unequal exposures model, and , so the Bühlmann–Straub credibility factor is . The credibility estimate simplifies to , exactly the posterior mean and hence the Bayes estimator under squared error loss. The agreement is exact because that posterior mean is already affine in the exposure-weighted data.
The experience weight is , where is total observed exposure, the variance of hypothetical means, and the expected process variance. With positive , it is . More exposure raises the weight; larger process noise lowers it. If , the unknown conditional mean is constant and one can set .
For independent comparable risks observed over years, estimate the expected process variance by the average within-risk sample variance. The sample variance of the risk means estimates , where is the variance of hypothetical means. Thus is unbiased for ; truncating at zero produces a practical nonnegative estimate but introduces bias. Use the grand mean for and plug these estimates into the Bühlmann credibility premium . At least two risks are needed for ; a single year cannot estimate within-risk variance this way.
Let a fixed policy intensity have prior density on , and let annual claim counts be conditionally independent with Poisson distribution mean . The expected process variance is and the variance of hypothetical means is , so the Bühlmann credibility factor is . A total count gives the displayed credibility premium. By contrast, the Bayesian posterior density is proportional to on . Its mean is the ratio . For , that Bayesian credibility estimate is , whereas the affine estimate is .
In the Gamma prior for an inverse-gamma scale model, assume . The variance of hypothetical means is , and the expected process variance is . The Bühlmann credibility factor is , giving the displayed expression. The optimal affine credibility estimate is . Its fixed-weight arithmetic-mean form differs from the reciprocal-based posterior mean.
With fixed structural parameters and , the Bühlmann credibility estimate has form . The next observation updates it by the displayed rule. Consequently the estimate decreases exactly when the new observation is less than the previous credibility estimate, with strict equality handled separately.
The credibility factor in the Bühlmann model is the weight placed on the sample mean after observations. The remaining weight is placed on the population expected value. More experience or larger variance of hypothetical means increases ; larger expected process variance decreases it.
The variance of hypothetical means in the Bühlmann model is the between-risk variance of the conditional claim expected value. It creates the shared covariance between different years of the same risk and determines how much individual experience should influence the premium.
The expected process variance in the Bühlmann model averages within-risk conditional variance over the population of risks. It measures variation that repeated observations can average out and contributes to the variance of the sample mean.
The classical risk model has surplus , where is a Poisson process of rate , independent claim sizes are positive, and premiums flow in at constant rate . The relative safety loading is . Ruin is the first time surplus becomes negative.
In a classical risk model, is the time of the th claim. The displayed probability restricts ruin to the first claims and increases to the ultimate ruin probability. Conditioning on the first arrival and severity gives , with . For exponential distribution claims of mean and relative safety loading , put and . Then and . The recursion follows because a surviving first claim leaves fresh independent future arrivals and claims. The formulas follow by integrating the rate- first-arrival density; the claim-arrival rate cancels with .
Starting from capital , ruin occurs exactly when the aggregate loss exceeds . Positive relative safety loading and the strong law of large numbers make tend to minus infinity, so its supremum is finite almost surely. For exponential distribution claims of rate , has an atom at zero, and, conditional on , has exponential distribution of rate . The ultimate ruin probability determines this mixture directly.
For a nonnegative claim size of finite positive mean , its equilibrium claim-size distribution has this density and survival function . The tail integral formula for moments normalizes the density. Its moment-generating function is wherever finite, so at an adjustment coefficient it equals one plus the safety loading.
A nonnegative lifetime or claim law is new better than used in expectation if its mean residual life at every age with positive survival is at most its original mean. The displayed equivalent inequality says that its equilibrium claim-size distribution is no larger in stochastic order than the original law. For an Erlang distribution of shape two and rate one, the two survival functions are and , so the condition holds.
For NBUE claims in the classical risk model, the equilibrium claim size is stochastically bounded by . The positive exponential tail integral formula for moments gives . Since and , rearrangement proves the displayed bound.
The probability that the insurance surplus in a classical risk model becomes negative at some finite time, starting from capital . Ultimate survival has probability . A finite-horizon ruin probability instead restricts the crossing time to a specified time interval.
For rate- exponential distribution claims and , the ruin integro-differential equation reduces to . Differentiate the convolution and use its equation to eliminate it. Positive relative safety loading implies as , and the zero-capital survival probability gives . These two conditions determine the displayed solution. The adjustment coefficient is .
In the classical risk model, condition on the first arrival of the Poisson process. If available capital just before it is , ruin has probability . Integrate this expression at against and change variables from to . Differentiating the lower limit gives the displayed equation. The claim-density convolution is continuous for bounded , so the first-arrival representation also supplies the differentiability required by the equation.
In the classical risk model with density and relative safety loading , the claim mean is and . The convolution terms satisfy . Applying to yields . Its solution is fixed by , and , giving the displayed probability. The derivative condition comes from the original integral equation and excludes spurious solutions of the higher-order equation.
For positive claims with finite variance and , the classical risk model has ruin probability one from any finite capital. At claim times, surplus increments are independent copies of with mean . Negative mean sends their partial sums to minus infinity by the strong law of large numbers. At zero mean, the increments have finite nonzero variance. For every fixed , the central limit theorem gives limiting probability of a partial sum below . The probability of unboundedness below is therefore at least ; as a tail event it has probability zero or one by the Kolmogorov zero-one law, and hence one.
Independent positively loaded portfolios with zero initial capitals have separate joint survival probability . Pool their claims and premium incomes to obtain zero-capital merged survival . This is the premium-weighted average of the individual survival probabilities and is at least their product. The event of aggregate solvency permits transfers of surplus between the original portfolios.
The ultimate survival probability satisfies . Condition on the first arrival of the Poisson process, differentiate the resulting exponentially weighted integral, and integrate the convolution derivative equation from zero. Tonelli theorem converts the claim-density convolution to the tail convolution. The kernel mass is , so this is a defective renewal equation.
In the classical risk model with premium rate and claim Poisson process rate , the first-claim decomposition for survival probability implies the displayed equation for ultimate survival probability. Change the first-claim integral to an integral over available capital and differentiate its lower limit. The bounded survival probability function convolved with the integrable claim probability density function is continuous, so this also establishes the needed differentiability. In particular .
For an Erlang distribution claim density and , write . The survival integro-differential equation gives . The convolution satisfies , because . Applying to the first equation eliminates and gives the displayed third-order equation. The original integral equation also supplies and ; these conditions must not be lost when solving the higher-order equation.
For a mixture distribution of exponential distributions, introduce one convolution state for each rate . It satisfies . Together with the survival integro-differential equation these form a constant-coefficient first-order system; applying the differential operators eliminates the convolution states. For equal mixing weights at rates one and one half, with , the result is . The original integral equation supplies initial conditions lost in elimination.
In a classical risk model, before the first claim at time , available capital is . A claim of size leaves future survival probability by the Markov property. Integrating over the independent first-arrival exponential distribution and claim density gives .
In a classical risk model with positive relative safety loading, zero initial capital has ultimate survival probability , where is the claim-arrival rate, the claim expected value and the premium rate. It depends on the claim law through its mean alone. It is not the event of never receiving a claim: premium accumulates between arrivals.
The adjustment coefficient is a positive root of in the classical risk model. When the moment-generating function is finite at , the process is a continuous-time martingale. It yields the Lundberg inequality and, under the relevant tilted integrability, the Cramér–Lundberg ruin asymptotic.
The gamma distribution of shape one half and rate has moment-generating function . With mean and positive relative safety loading , write . Dividing out the zero root after squaring the adjustment equation gives . Its unique positive root lies between zero and one, so it belongs to the transform domain and gives the display.
Replacing a shape-one-half gamma claim law by an exponential distribution with the same mean overestimates the adjustment coefficient. Indeed because the difference of the squared terms is . The resulting putative Lundberg inequality bound is smaller than the valid true-model bound for ; the former is not justified for the true claim law. The true variance is twice the assumed variance, and its exponential tail decays more slowly.
For positive claims with a finite positive moment-generating function neighbourhood, use and for in the defining adjustment coefficient equation. They imply the displayed strict upper bounds, where is the positive quadratic root. Its defining polynomial is negative at zero and positive at , proving . Higher exponential-series truncations similarly yield upper bounds from more raw moments.
Fix positive claim expected value and relative safety loading in a classical risk model. Assume the random claim law has an adjustment coefficient . By Jensen inequality, . Thus . The expression on the left is strictly convex, has negative derivative at zero and tends to infinity, so its unique positive zero satisfies . If the claim size is not almost surely constant, strict Jensen inequality gives . Consequently the Lundberg inequality upper bound for deterministic claims is smaller for . Comparing these upper bounds alone does not establish an ordering of actual ultimate ruin probabilities.
For an Erlang distribution of shape two and rate , the claim expected value is and its moment-generating function is for . The adjustment coefficient equation is . With , divide out the zero root to get . The smaller quadratic root lies in when ; the larger root lies beyond the finite-transform domain and must be rejected. This proves the displayed coefficient.
If each claim includes an independent expense , replace its payment law by the convolution of independent random variables . Its moment-generating function is and its expected value is . Keeping the relative safety loading fixed therefore changes the premium rate as well. The new coefficient solves , within the common finite-transform domain.
For positive claims with finite nonzero expected value , the function is continuous and strictly increasing on the positive finite-transform domain, starting at . If diverges at a finite upper endpoint, or is finite for all positive arguments, the secant slope tends to infinity. In the latter case use for some of positive tail probability. Every target with positive relative safety loading therefore has exactly one positive root.
For a classical risk model with adjustment coefficient , the ultimate ruin probability from capital satisfies . Stop the exponential continuous-time martingale at ruin or a finite horizon, bound its value on the ruin event, and then increase the horizon.
In a classical risk model, an adjustment coefficient makes . The random-sum transform identity and independent increments show that . This nonnegative martingale starts at one. At the ruin stopping time , . Applying the optional stopping theorem only to yields ; passage to increasing horizons proves the Lundberg inequality without an unjustified expectation identity at an unbounded stopping time.
In the classical risk model with positive relative safety loading and adjustment coefficient , tilting the ruin defective renewal equation gives a proper renewal equation. The key renewal theorem yields . The constant is positive if the denominator is finite and zero if it is infinite; the claim-size density provides the nonarithmetic hypothesis.
If the Cramér–Lundberg ruin asymptotic has a finite positive constant, compare it with the leading nonzero term of a finite exponential representation. An adjustment coefficient smaller than that term's decay rate would give limit zero; a larger coefficient would give infinity. Thus the two rates agree and the prefactor is the leading coefficient. Terms with zero coefficient are absent and do not determine a decay rate.
When the adjustment coefficient lies inside the finite domain of the claim moment-generating function, the tilted kernel has finite mean . The forcing integral is . Their ratio is the constant in , by the key renewal theorem. An extra exponential moment controls the forcing tails and proves direct Riemann integrability.
For unit-rate Erlang distribution of shape two claims put . The adjustment coefficient satisfies , so . In the interior-adjustment prefactor , substituting gives the displayed expression. It is positive for and tends to one as the loading tends to zero.
If the expected claim outflow per unit time is , the relative safety loading is . Positive loading means expected premium income exceeds expected claim outflow. This is the net profit condition in the classical risk model.
Reinsurance transfers part of an insurer’s claim liability to another insurer. If aggregate claims are , a retained payout with leaves the reinsurer with . Quota share reinsurance retains a fixed fraction, whereas aggregate stop loss reinsurance retains losses only up to a fixed aggregate threshold.
A threshold limiting the insurer's retained payment under a reinsurance contract. Under excess of loss reinsurance it applies to each claim size; under aggregate stop loss reinsurance it applies to the total loss over the stated period. These contracts therefore cap different quantities even when their thresholds have the same numerical value.
For independent exponential claims of mean and a zero-based geometric count of parameter , excess of loss reinsurance at per-claim reinsurance retention has expected recovery . The zero-based geometric sum of exponential variables has tail , so aggregate stop loss reinsurance at reinsurance retention has expected recovery . Equating them gives the displayed reinsurance retention relation. This comparison concerns claim payouts, before any reinsurance premium is charged.
Per-claim reinsurance under which the insurer retains each claim up to a level and the reinsurer pays its positive part . The annual retained amount is a sum of capped claims, so it is generally different from the cap of the annual sum in aggregate stop loss reinsurance.
A reinsurance layer with attachment and payment limit pays nothing below , the excess between and , and above that. Its expected recovery is , by the tail integral formula for moments. For continuous claims, conditioning on penetration of the layer divides this expectation by .
For a lognormal distribution, let for . The truncated lognormal moment formula gives the recovery numeratorDivide by to condition on . This handles both the partially penetrating claims and the capped payments beyond the upper attachment.
For positive inflation factor , . The conditioning event also changes to . If claims have a lognormal distribution, the same result follows by replacing their log-mean by and keeping the contractual attachment and limit fixed. Merely multiplying the original conditional mean by would hold those effective thresholds incorrectly fixed.
For positive claim sizes with finite second moment in a compound Poisson distribution aggregate of parameter , the two excess of loss reinsurance payouts are and . The derivative of their total aggregate variance is . Thus the displayed condition characterizes stationarity. When the tail probability is positive it says that the retention equals the mean residual life. Global minimality requires an additional sign or comparison argument.
For a Pareto distribution of shape three and minimum with count rate , the sum of insurer and reinsurer aggregate variances is for , and for . The first branch has its unique minimum at ; the second is increasing. The branches agree in value and slope at , giving the displayed global minimum. This criterion minimizes the sum of party variances; the total portfolio variance includes their covariance and remains .
For exponential distribution claims of mean and compound Poisson distribution count parameter , the total party variance under excess of loss reinsurance is . Its derivative is , so is the unique global minimum, with value .
For a positive claim and , the tail integral formula for moments gives the displayed expression. In particular the first moment is and the raw second moment is . If the claim law has a density, capping adds an atom of a measure at with mass .
With aggregate retention , the direct insurer pays and the reinsurer pays , where denotes the positive part. The threshold applies to the whole annual loss; applying a threshold to individual claims is a different contract.
If has exponential distribution with expected value , the tail integral formula for moments gives and , where . At matching retained expected value, the excess variance under quota share reinsurance is .
Among retained payouts with and the same expected value as , aggregate stop loss reinsurance minimizes the variance. Pointwise , and subtracting the identical squared distance of their common expected value from proves the claim. Equality requires equal payouts almost surely.
Articles were limited to the first 100 out of 5767 total.
Articles by others on the same topic



**Probability and Statistics** are two related but distinct branches of mathematics that deal with uncertainty and data analysis. ### Probability Probability is the branch of mathematics that deals with the likelihood or chance of different outcomes occurring. It provides a framework for quantifying uncertainty and making predictions based on known information. Some key concepts in probability include: - **Experiment**: A procedure that yields one of a possible set of outcomes (e.g., rolling a die).