Extreme value theory studies limiting probability distributions of normalized sample maxima and related extremes. The standard limits for maxima include the Fréchet distribution, negative Weibull distribution, and Gumbel distribution.
The question is often practical: if a batch finishes only when its slowest task finishes, its completion time is a sample maximum. A typical individual delay or a sample mean does not answer that question. The central limit theorem describes suitably normalized sums and sample means under its assumptions; it does not give a limit law for sample maxima. Extreme value theory instead describes how the largest observation changes as the number of opportunities for a large observation grows.
For independent and identically distributed random variables with distribution function , define the sample maximumThe event means that every observation is at most , so independence givesExtreme value theory asks whether there are constants and for which has convergence in distribution to a non-degenerate probability distribution. Equivalently, must tend to a limiting distribution function at its continuity points. The extremal types theorem says that any such limit belongs, up to a change of location and positive scale, to the Gumbel distribution, Fréchet distribution, or negative Weibull distribution. It does not guarantee that a limit exists for every . [ref]
https://rls.sites.oasis.unc.edu/s834-2023/ExtremeValues.pdf. Smith and Weissman, Extreme Values, Section 1.2.1: the three types theorem
.The maximum of independent exponential random variables gives a particularly transparent worked example: its center grows as , and its fluctuations have a Gumbel distribution limit on the scale . Here and below denotes the natural logarithm. This normalization depends on the exponential distribution. Other survival functions can lead to the Fréchet distribution or negative Weibull distribution, with different constants ; the Gumbel distribution and the exponential example's normalization are not universal.
Independence is essential to the product calculation. If instead for one rate- exponential random variable, then for every . Its distribution function stays for and zero below zero, and its median stays . Perfect dependence creates no logarithmic growth: repeating the same random variable supplies no new chance of a larger value.
A historical starting point is R. A. Fisher and L. H. C. Tippett's 1928 paper on limiting laws of the largest or smallest sample member, published in volume 24, issue 2, pages 180–190 of the Proceedings of the Cambridge Philosophical Society. Its abstract studies the possible limiting forms and emphasizes that approach to a limit can be slow. [ref]
https://www.cambridge.org/core/journals/mathematical-proceedings-of-the-cambridge-philosophical-society/article/abs/limiting-forms-of-the-frequency-distribution-of-the-largest-or-smallest-member-of-a-sample/7BE8DE65FCDFC3ABECFE1054DFB56CB5. Fisher and Tippett (1928), Limiting forms of the frequency distribution of the largest or smallest member of a sample: publisher metadata and abstract
.Let be an integer and let be independent and identically distributed random variables with an exponential distribution of rate . Their sample maximum is nonnegative. Substituting the exponential distribution's cumulative distribution function into the distribution functions of independent minima and maxima gives the exact lawFor example, at each observation is below the threshold with probability , but all observations are below it with probability . Thus an individual observation's median becomes an increasingly unlikely upper bound for the whole batch. The general order statistic density in Siegrist's treatment, with , also gives this law on integration. [ref]
https://www.randomservices.org/random/sample/OrderStatistics.html. Siegrist, Random Services: exponential order statistics
.Solving gives the exact quantile function, for ,In a toy model with , the median maximum is seconds for , seconds for , and seconds for . All three use the exact distribution function; the increase comes from taking a maximum over more observations. The case connects to the existing maximum of two exponentials as a scaled sum.
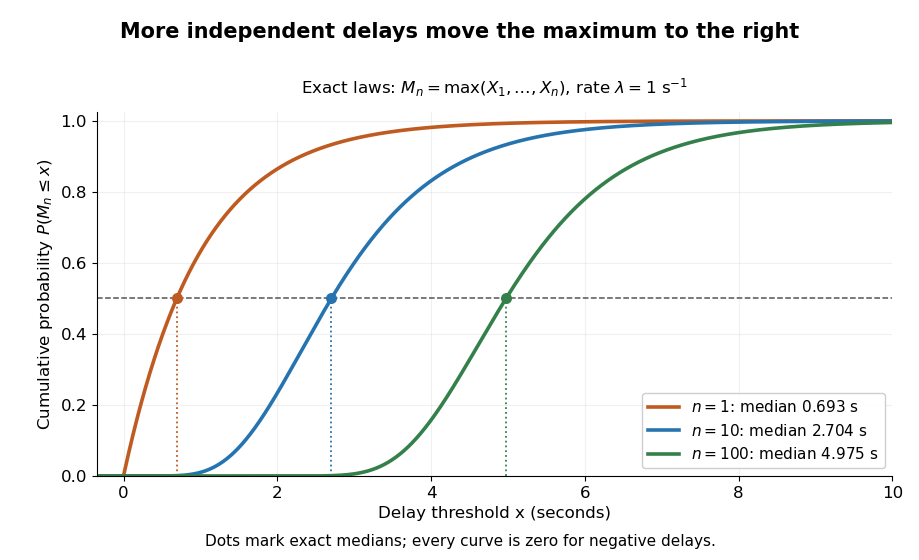
Exact cumulative distribution functions of exponential sample maxima, with rate one per second and median markers
. Details. The Gumbel distribution explains the logarithmic shift visible here: after subtracting and measuring deviations in units of , the distribution functions approach one fixed shape. The next derivation makes that convergence in distribution explicit.
For and a positive threshold , the Hill estimator averages the logarithmic ratios of the top order statistics to . For a Fréchet distribution domain with shape , it estimates the reciprocal tail index . At an untied threshold it equals the empirical distribution function plug-in tail integral . At a tied threshold the plug-in denominator counts strictly larger observations and the identity needs adjustment. Fixed does not by itself yield a consistent tail-index estimate.
Every non-degenerate limit in convergence in distribution of positively scaled and centered sample maxima is a max-stable distribution. Up to positive affine transformations its law is the Gumbel distribution, a Fréchet distribution with positive shape parameter, or a negative Weibull distribution with positive shape parameter. This classifies possible limits, without asserting that every distribution function admits a limiting normalization.
A non-degenerate distribution function is max-stable when every sample maximum of independent and identically distributed random variables can be positively scaled and centered to have the original law. Thus for every integer there are with . The extremal types theorem classifies these laws, up to affine changes, as the Gumbel distribution, Fréchet distribution, and negative Weibull distribution.
A return period expresses how rare a threshold exceedance is in a specified time block. Let be the sample maximum in block , fix a threshold , and suppose is the same for every block. The conventional return period is blocks; blocks of duration give a time of . Thus an annual exceedance probability means a 100-year return period. This names a frequency scale, not a schedule or a guarantee of one exceedance in each century. The annual convention and the misleading “once every 100 years” interpretation are discussed in USGS: the 100-year flood.
To derive a waiting-time interpretation, assume the exceedance indicators are independent and identically distributed random variables with the Bernoulli distribution of parameter . Define , counting the successful block as well as all preceding blocks. The first Bernoulli trials must fail and the th must succeed, so independence gives the geometric distributionThe expected value can also be read directly from the geometric series: . This counts blocks from the starting boundary, not the exact time of an exceedance within its block. Counting only failed blocks instead would give expected value . The waiting law and its memorylessness of the geometric distribution are developed in Kyle Siegrist, Random Services: the geometric distribution.
For a horizon of complete years, at least one exceedance is the complement of no exceedances. Under the same independence and constant- assumptions,For the toy choice , this gives in 10 years, in 30 years, in 50 years, and in 100 years. Even after 100 years there is a chance of no exceedance. These numbers are exact model calculations rounded to one decimal place, not measured frequencies. The median waiting count is 69 years, since ; the expected value is 100 years. A mean and a median answer different questions.
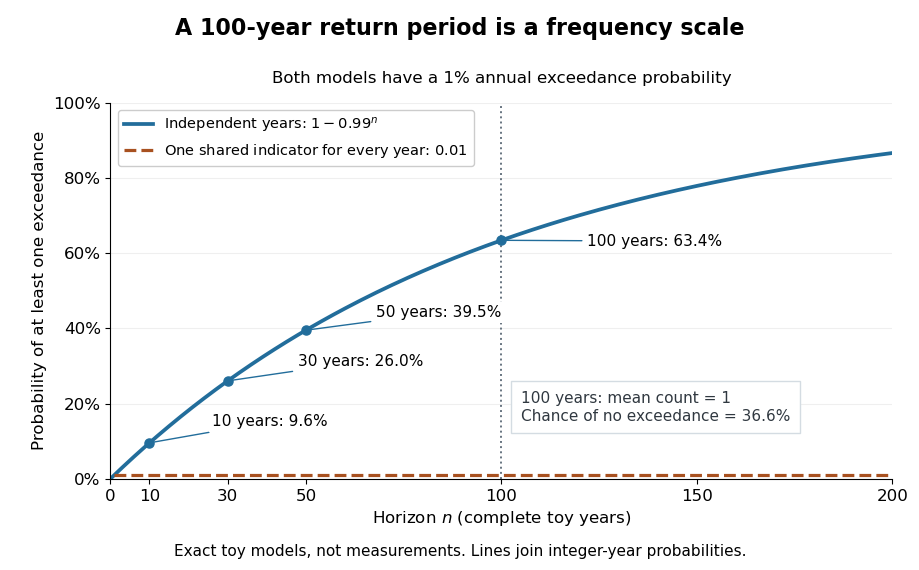
The exceedance count has the binomial distribution under independence, with expected value . Thus has expected value one, although its probability of being at least one is only : some realizations contribute several exceedances. For , the memorylessness of the geometric distribution gives . A long quiet spell does not make the next independent year's exceedance overdue, and an exceedance this year does not force a quiet interval. Two specified consecutive years both exceed with probability in this toy model.
A reproducible tabletop experiment makes the assumptions tangible. Put 100 identical slips numbered 1 to 100 in a bag; after thoroughly mixing, draw one and record whether it is 100. Replace the slip and mix again before every draw. Treat each draw as one toy year, so the exceedance indicator is a Bernoulli random variable with , provided the sampling is uniform and successive draws are independent. Repeat complete 30-draw runs and record the fraction containing at least one 100; separately repeat runs stopped at the first 100 and record their waiting counts. The first fraction targets ; the waiting-count histogram targets . Replacement keeps fixed, mixing is intended to support independence, and repeated runs expose sampling variation. This is a proposed demonstration of the toy model; no experimental results are asserted here.
Stationarity supports a time-invariant annual probability distribution, but does not imply independence. For an extreme counterexample, draw just one Bernoulli random variable of parameter and set for every year. This is a stationary process, yet the probability of any exceedance in every finite horizon is ; from an arbitrary starting boundary the wait is infinite with probability . The reciprocal marginal frequency therefore need not equal that forward waiting expected value. With equal marginal probabilities and arbitrary dependence, only the general bounds follow, the upper bound being the union bound. Linearity of expectation still gives without independence. Mere zero correlation does not restore the product formula; even pairwise independence does not imply joint independence. If annual probabilities change to , independence instead gives , and one fixed return period no longer describes all years.
A return level answers the inverse question to a return period: which threshold has the specified rarity? Let be the common cumulative distribution function of annual sample maxima in a model with stationarity. For a continuous, strictly increasing and , the -year return level isIt has the same units as , whereas is a count of annual blocks. Independence between years is unnecessary for this one-year quantile definition; it is needed for the geometric waiting and multi-year formulas under return period. For a discrete probability distribution, use the generalized quantile function . Then , with equality not guaranteed at jumps; an exact requested exceedance probability may be unattainable.
For a concrete standard model, choose the maxima convention of the Gumbel distribution, with location and scale :The second formula follows by taking logarithms twice and solving . The maxima cumulative distribution function and its inverse are given in NIST: extreme value type I distribution, maximum case. With the deliberately chosen toy values and in arbitrary units, , , and , rounded to three decimals. In particular, is approximately the annual quantile at cumulative probability ; it is not a prediction of the largest observation in the next 100 years. Under independence, the probability that all those annual sample maxima stay below the exact is .
The time block matters. If a toy year contains independent daily blocks, each with exceedance probability at one fixed threshold, its annual exceedance probability is , giving annual return period . The reciprocal counts daily blocks. Dependence among daily exceedances requires their joint law instead; a threshold crossed on several successive days still produces only one exceedance indicator for that year's sample maximum. The peaks-over-threshold method and declustering of extremes address a different choice of extreme-event sampling.
A return level plot graphs horizontally and vertically, often using a logarithmic scale for . To read it, choose a return period, move up to the curve, and read the corresponding return level. Conversely, a threshold's horizontal coordinate gives the reciprocal of its annual exceedance probability. The usual plot of fitted quantiles against return periods, and optional pointwise confidence intervals, are documented in Mathieu Ribatet, POT package: return level plot.
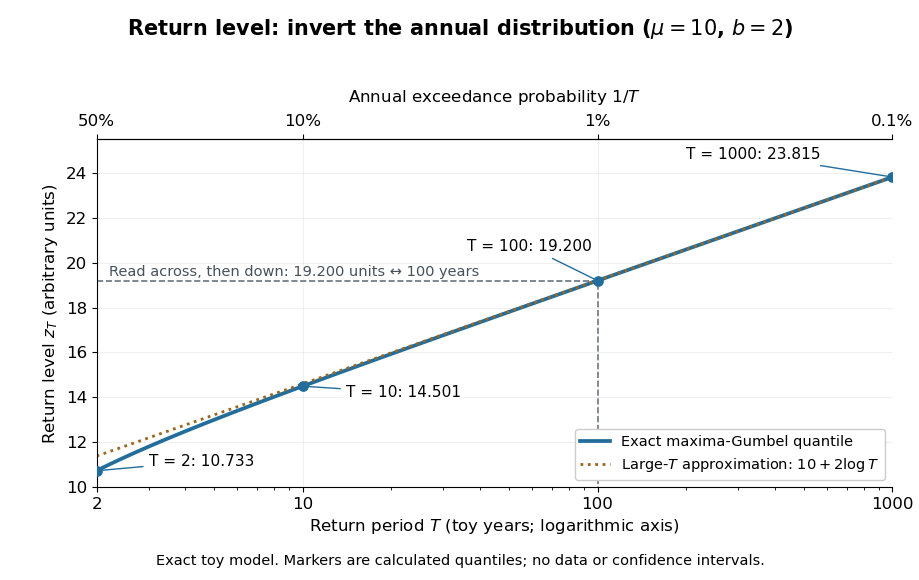
The near-straight shape has a mathematical explanation: since as , the Gumbel distribution gives . Multiplying a large return period by ten therefore increases the return level by approximately , about units for this toy curve. A curve indexed by rarity puts several thresholds on one common scale while retaining their measurement units.
For a fitted curve, a pointwise confidence interval concerns uncertainty in the estimated quantile at a specified ; it is distinct from a prediction interval for a future annual sample maximum, and pointwise intervals need not form a simultaneous confidence band. A far-right curve value can also be an extrapolation beyond the observation record: extending the line adds no observations to support the chosen tail model. The diagram above uses fixed toy parameters, so it shows neither estimation uncertainty nor an observational record. Its interpretation throughout assumes the stated annual block and stationarity.
For scale and shape , the generalized Pareto distribution on nonnegative excesses has cumulative distribution functionThe case is the continuous limit . Positive gives a power-law tail, zero gives an exponential distribution, and negative gives a finite upper endpoint . Its role in modelling high-threshold excesses is explained by the Pickands-Balkema-de Haan theorem.
For the positive-shape generalized Pareto distribution with shape and scale , the expected Fisher information matrix for one observation isThe orthogonalization equation for two statistical parameters gives at fixed new nuisance coordinate. Thus is a global interest-respecting reparametrization. In coordinates , the information is diagonal with entries and .
The peaks-over-threshold method fits a generalized Pareto distribution to exceedances of a high threshold and also estimates their frequency. Together these determine tail probabilities and return levels. For dependent observations, threshold exceedances may occur in clusters; declustering of extremes can separate extreme events before fitting a model for independent events.
Declustering groups dependent threshold exceedances into extreme-event clusters and retains a representative, commonly the cluster maximum. It aims to make the events used in a peaks-over-threshold method approximately independent. The event rate must be estimated consistently with the retained clusters when computing return levels.
For a distribution in an extreme-value domain of attraction, the conditional distribution of the excess above a high threshold is asymptotically approximated by a generalized Pareto distribution with a threshold-dependent scale and a limiting shape parameter. This theorem justifies the peaks-over-threshold method. Threshold selection must balance approximation error against the reduced number of excess observations.
The standard Gumbel distribution for maxima has distribution function for every real . Its probability density function is the derivative of its distribution function:This article uses the maxima convention throughout. Reflecting a standard Gumbel distribution random variable to gives the minima convention, with distribution function . The two conventions have opposite directions of asymmetry, so their formulas must not be interchanged. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/eda366g.htm. NIST: extreme value type I distributions for maxima and minima
.For a location and positive scale , let . This location-scale family has cumulative distribution function and probability density functionSolving gives the standard quantile function , , and hence the standard medianThe median of is therefore . Location is not the median: at the cumulative distribution function is .
To derive the Gumbel distribution as an extreme-value limit, take the maximum of independent exponential random variables with rate and setThe exact distribution function isThe finite- lower boundary is required because . For each fixed real , eventually , and the natural logarithm of the first branch satisfiesExponentiating proves convergence in distribution to the standard Gumbel distribution. It is the familiar limit with : a simple calculation reveals a whole limiting shape. The name honors Emil Gumbel; Siegrist gives this exponential-maxima derivation and the standard Gumbel distribution formulas. [ref]
https://www.randomservices.org/random/special/ExtremeValue.html. Siegrist, Random Services: the Gumbel distribution and its exponential-maxima limit
.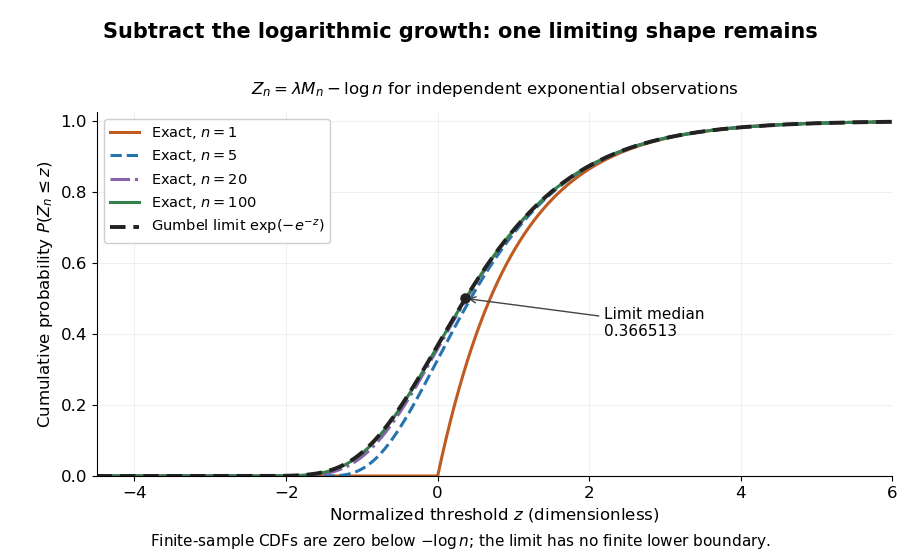
Centered exponential sample maxima for n equal to 1, 5, 20 and 100 approach the standard Gumbel cumulative distribution function
. Details. For the toy delay model , , the limiting Gumbel distribution approximation to has and . Its predicted median iscompared with the exact median . The approximation is about seconds lower in this example. It is not an exact finite-sample probability distribution: the approximating Gumbel distribution assigns positive probability to negative delays, while the exact sample maximum cannot be negative.
The maximum domain of attraction of the Gumbel distribution is characterized by an exponential tail ratio on the scale of a Gumbel auxiliary function. This allows many original probability distributions to share the limiting shape, but it does not make the centering appropriate to all of them.
If has cumulative distribution function , put . For , the decreasing transformation gives , while this probability is zero for . Hence has the rate-one exponential distribution. Conversely, if has that exponential distribution, then has the standard Gumbel distribution.
For fixed and , the factor is a translated Gumbel distribution cumulative function, with transition near . Integration by parts transforms the integral to an exponentially small boundary term plus . Expanding the latter against its finite logarithmic moments gives the displayed two terms because , with Euler's constant. The smooth cutoff shifts the first correction even though replacing it by a step gives the leading tail.
For the Gamma distribution with fixed positive integer shape and rate one, the survival function is . Its sample maximum centered by has convergence in distribution to the standard Gumbel distribution, without an additional scale factor.
A positive Gumbel auxiliary function makes as approaches the right endpoint of a distribution, for every real . Under the Von Mises conditions for extreme values, the reciprocal hazard function is a valid choice.
For , the standard negative Weibull distribution has distribution function for and one for . This is the probability distribution of the negative of a standard positive Weibull distribution variable.
For , the standard Fréchet distribution has distribution function for and zero for . Its maximum domain of attraction consists of distribution functions with an infinite right endpoint of a distribution and a survival function with regular variation of index .
A distribution function lies in the maximum domain of attraction of if at every continuity point of for some and real . This expresses convergence in distribution of normalized sample maxima.
For a distribution function with tail , let solve . Then for , so the normalized sample maximum tends to the shape-one Fréchet distribution. The inequalities for large show , allowing that simpler scale too.
For an absolutely continuous distribution function with positive probability density function near its right endpoint of a distribution, write for its hazard function. The limits at an infinite endpoint or at a finite endpoint imply attraction to the Fréchet distribution or negative Weibull distribution, respectively. A continuously differentiable reciprocal hazard function with implies attraction to the Gumbel distribution, provided the survival function tends to zero at the endpoint.
Articles by others on the same topic



Extreme value theory (EVT) is a statistical field that focuses on the analysis and modeling of extreme deviations or rare events in a dataset. It is primarily concerned with understanding the behavior of maximum and minimum values in datasets, especially under the assumption that the data follows some underlying distribution.