Probability theory describes uncertainty through a probability space: possible outcomes form a sample space, observable questions are events, and a probability measure assigns them numbers between zero and one. The Kolmogorov axioms make those assignments consistent. They let us combine information about several events, update it through conditional probability, and study random variables without listing every possible outcome separately.
For example, roll two dice whose results are independent random variables, each with a discrete uniform distribution on . There are 36 equally likely ordered outcomes. Only have sum seven, so that event has probability . The sum itself is not uniformly distributed: sum two has only one outcome. Choosing a probability distribution for the elementary outcomes is part of the model; equal likelihood does not follow merely from counting the named possibilities.
The subject becomes especially useful when complete outcome lists are enormous or infinite. Independence turns a joint calculation into simpler pieces, expected value summarizes a random variable, and the law of large numbers explains how averages can become predictable even when individual observations are uncertain. The central limit theorem describes the scale and shape of many remaining fluctuations. These are distinct claims: a small variance of an average does not make every observation close to its expected value.
There is a satisfying unity here: dice, hidden causes, and Brownian motion all use the same rules for events and conditional probability. A model still needs justification. Its exact deductions describe what its assumptions imply; comparison with observations belongs to statistical inference.
The initial table of content was limited to the first level because it is larger than 1000 articles. There are 2776 articles in total. Expand a branch to load its children.
A mathematical account of random outcomes using a probability space and specified random variables. It determines probabilities for events or observed data. A statistical model commonly supplies a family of such probability distributions with unknown parameters; choosing a model and estimating its parameters are distinct tasks.
The study of choices under uncertainty and consistency conditions on preferences. In a quantum application, recovering Born rule weights from preferences requires specifying how physically equivalent games and irrelevant branch refinements affect value; it is not a consequence of decoherence alone.
A choice task in which options differ in immediate outcomes and their accumulated future consequences. Performance combines learning, valuation, human memory and uncertainty; disadvantageous choices do not uniquely diagnose one emotional mechanism.
Choosing between options that differ in benefits and required effort. Varying reward and effort independently helps distinguish reduced reward sensitivity from increased effort cost.[ref]
Distinct effects of apathy and dopamine on effort-based decision-making in Parkinson's disease by Campbell Le Heron and others. 2018, reward and physical-effort choice
Consider a logistic choice rule with and fixed noise scale. At one positive offer , changes satisfying leave utility and acceptance probability unchanged. One offer therefore cannot identify reward gain and effort cost separately.
For example, and both give at . Their predictions differ at other offers. Independently varying reward and effort can identify the two coefficients within this model when the design has rank two and choice data are informative. If noise scale is also unknown, its tradeoff with the coefficients requires additional constraints.
Reduction in the subjective attractiveness of an outcome as required effort increases. The form and strength of the reduction must be estimated under a specified model and task.
Evaluation of a reasoning strategy in relation to the informational structure and task environment in which it operates. The claim that an algorithm works well for natural sampling must be tested separately from whether a particular probability-worded task supplies that representation.
A random number generation technique that retains the unused equally likely outcomes after a rejected trial in rejection sampling. Instead of discarding those outcomes, it uses their conditional probability to obtain a new uniform distribution on a finite set for the input state of the next trial.
Poissonization replaces a fixed number of independent trials by a Poisson process clock. Independent exponential arrival clocks can then simplify occupancy and collection problems, after which the original counting quantity is recovered from the clock rate.
A testing strategy that pools samples to determine which individuals satisfy a binary condition. A negative pool rules out every member, whereas a positive pool requires more information to identify the affected individuals. Conditional probabilities and dynamic programming can determine an efficient adaptive strategy under a specified model.
Different precise measures on random chords give different probabilities; the phrase “random chord” does not select a unique probability distribution. In a circle of radius , a chord exceeds the side of an inscribed equilateral triangle exactly when its midpoint distance from the center is below . Uniform midpoint area gives probability , independent uniform endpoints give , and uniform midpoint distance gives . The difference is in the sampling laws, not a contradiction in probability theory.
For independent lengths with the uniform distribution on , the probability of forming a nondegenerate polygon is . The necessary and sufficient condition is that every length is less than the sum of the others. The failure events are disjoint except on sets of probability zero. The sum of lengths has probability density function on , by repeated convolution of probability densities. A specified rod is too long with probability ; summing over the rods proves the formula. For three and four rods the probabilities are and .
The probability that independent uniformly oriented open hemispheres cover a sphere is the displayed quantity. Coverage fails exactly when their normals lie in a closed hemisphere. With probability one, no three normals are coplanar and no pair is antipodal; a closed hemisphere containing the normals can then be perturbed into an open one. Condition on the unoriented axes of the normals. Their orientation signs remain independent fair bits, and the regions of a general-position great-circle arrangement realize exactly of the possible sign vectors. Each such vector corresponds to normals that fit into one open hemisphere, proving the complementary probability. The argument counts equiprobable orientation choices, not equal-area regions.
Pairwise independent events describe a subtle kind of uncertainty: learning that one event occurred leaves each other event's probability unchanged, yet learning that two occurred can reveal a third completely. Checking every pair therefore answers a weaker question than checking the whole collection. The parity construction of pairwise independent bits makes this distinction visible with just four equally likely outcomes.
A family of events is pairwise independent whenIf , this is equivalent to the conditional probability identity . The product definition also handles events of probability zero. Independent events, meaning mutually independent events, require the same product rule for every finite subfamily, including triples. For three events, the three pair equations and the triple equation are four separate requirements. [ref]
https://www.randomservices.org/random/prob/Independence.html. Kyle Siegrist, Random Services: independence of two events and general independence of events
.For a worked example, take independent fair bits : the sample space is with probability per outcome. Set , , and , using exclusive or, which is one precisely when its inputs differ. The events , , and each contain two outcomes. Their pair intersections areThus each event has probability and each pair intersection has probability : these are pairwise independent events. But forces , soThe three are not independent events. This is the complementary-third-event version of the two-toss example in Tsitsiklis and Jaillet, MIT Introduction to Probability, Lecture 3, slides 7–8.
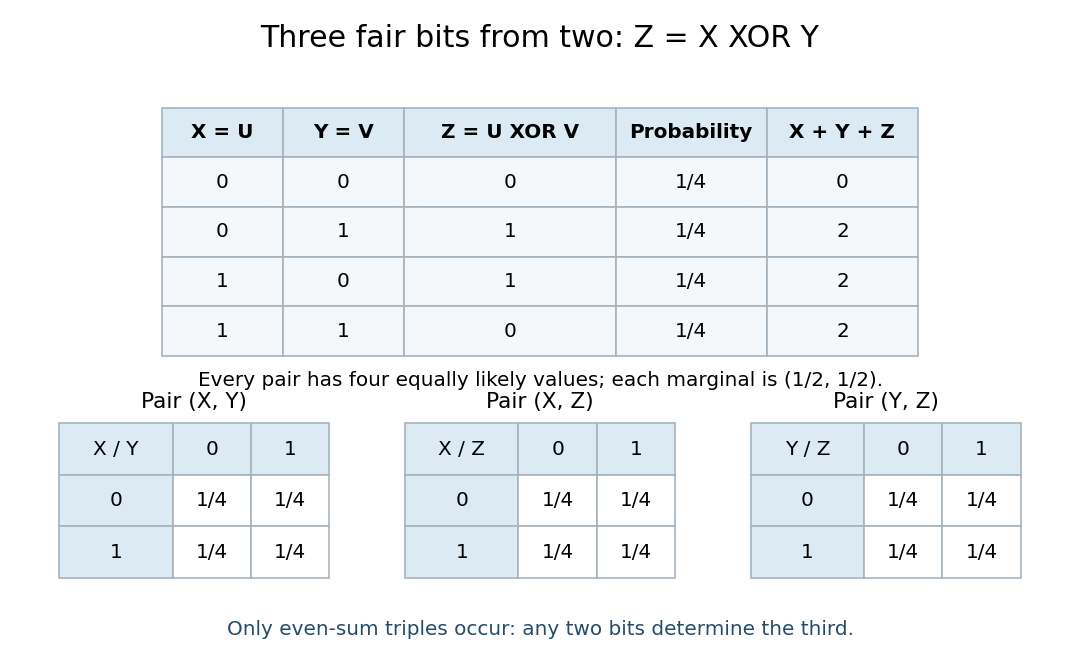
Another useful diagnostic preserves a special common-intersection case. Suppose three events have common probability and every pair and triple intersect in the same event, of probability . Pairwise independence requires , while mutual independence additionally requires . Both hold only for or . For a concrete nontrivial instance, assign probability to each of four outcomes, let all three events contain the first outcome, and give each event one different additional outcome. Then and : the pair equations hold, while the triple equation fails. Unlike the exclusive or example above, this triple intersection is nonempty.
The parity construction of pairwise independent bits turns two independent fair bits into three pairwise independent random variables. With , , and , their allowed triples are , each of probability . Every coordinate has the Bernoulli distribution with parameter . Every pair has the same joint probability mass function:All twelve pair cells equal the product of the corresponding probabilities in their marginal distributions. This establishes pairwise independent random variables, a requirement involving every pair of value-events, rather than merely one chosen event per coordinate. For general real-valued random variables , the requirement isfor every pair of Borel sets . For these binary random variables, checking all four cells of each pair suffices: any value-event is a union of the checked cells. In fact, for binary random variables, independence of their one-value events also gives the other cells by taking complements. Siegrist gives the all-set definition and its connection to indicator random variables in Random Services: independence of random variables.
The full joint probability mass function tells a different story:The integer parity of is always even. Any two bits determine the third: , , and . Each coordinate is independent of either other coordinate individually, but is dependent on the pair together. For example, the conditional probabilities satisfy and . See also pairwise independence does not imply joint independence for the general distinction.
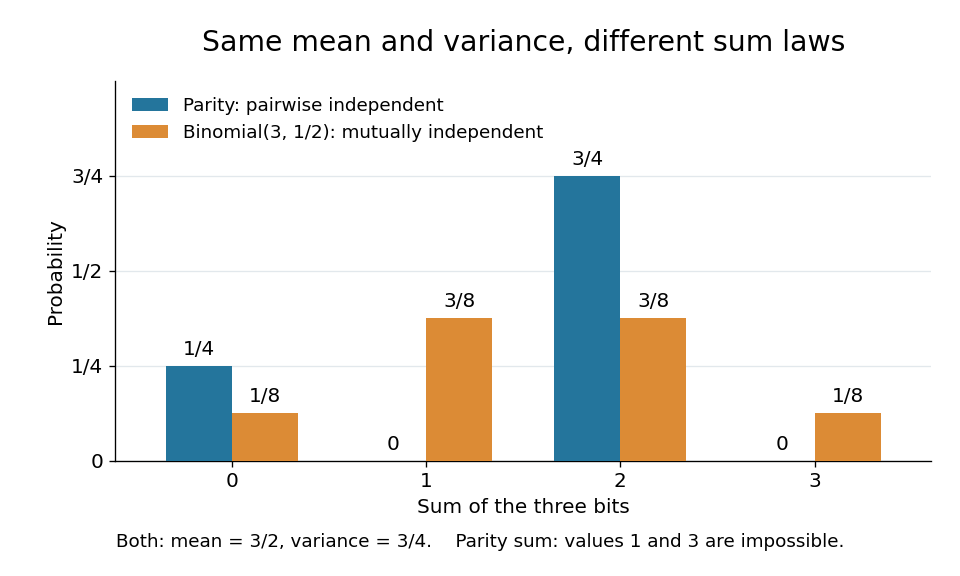
The constraint changes the sum's probability distribution without changing its expected value or variance. Let . Only gives ; each other allowed triple gives . Direct calculation givesThe same variance follows from the variance of a sum: each Bernoulli distribution has variance , and pairwise independent random variables have zero cross covariances. Linearity of expectation gives the expected value even without independence.
For comparison, the sum of three mutually independent fair bits has the binomial distribution :Both sums have identical expected values and variances, but never takes the values one or three. Even their third moments differ: , whereas . Pairwise independence preserves these first two sum summaries while allowing a different joint probability distribution and a different sum law. The calculation is an exact finite example.
A point process records random locations by a random measure that counts them. Examples include arrival times of a queue, positions of stars, and the finite eigenvalue configuration of a random matrix. The count in an observation window is a random variable; its expected value is supplied by the intensity measure of a point process, while its fluctuations and relationships with other windows require more information.
For a precise spatial convention, take with its Borel sigma-algebra and a probability space . A locally finite point process is a measurable function from to the space of locally finite point measures, equipped with the sigma-algebra generated by evaluations for Borel sets . Each realization has the formwhere is finite or countable and repeated locations are allowed; is a Dirac measure. Here a point measure is a counting measure with possible multiplicities, rather than the counting measure of a set of distinct locations.[ref]
Lectures on the Poisson Process by Günter Last and others. Section 2.1, Definition 2.1, printed pp. 10-11: point measures and the sigma-algebra generated by evaluations
Local finiteness means for every bounded Borel set , on a single almost sure event. In it suffices to check the countable collection of balls of integer radius centered at the origin, and this is equivalent to finiteness on every compact set. On a general measurable space there is no notion of boundedness without additional structure: state a metric or an explicit family of observation windows. Another convention on locally compact spaces requires finiteness on compact sets; this need not coincide with finiteness on all bounded sets outside . Local finiteness does not require finitely many points in all of .[ref]
Lectures on the Poisson Process by Günter Last and others. Section 2.4, Definitions 2.11 and 2.13, printed pp. 16-17: bounded-set local finiteness and the countable ball exhaustion
A point process is simple when, on a single almost sure event, every location has multiplicity at most one. Its realizations are simple locally finite point measures. For instance, is locally finite but not simple: it has four points counted with multiplicity at three distinct locations. Simplicity is a statement about each entire realization. Checking separately for every fixed is insufficient: with having the uniform distribution on passes every such fixed-location check, yet always has a double point.[ref]
Lectures on the Poisson Process by Günter Last and others. Section 6.2, Definitions 6.6 and 6.8, printed p. 49: simple measures and simple point processes
For a bounded Borel set , the window count of a locally finite point process is a finite nonnegative integer random variable. It counts multiplicities, and the convention for window boundaries matters. On the time half-line, is a counting process and . For pairwise disjoint observation windows , the measure identityis valid for every realization. Additivity of counts supplies no independence assumption.
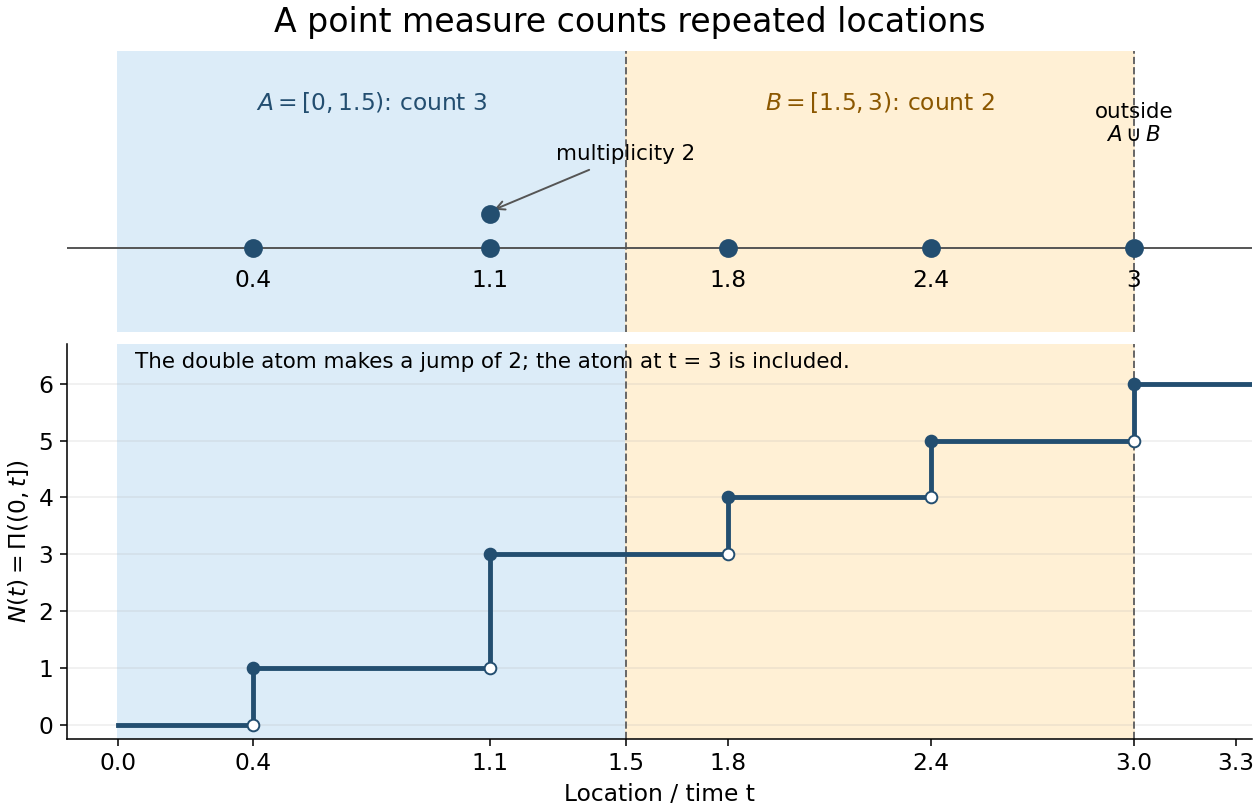
Window counts include multiplicity and depend on boundary conventions
. One locally finite point measure is . The half-open windows and have counts three and two; . The atom at three lies outside both windows. Two stacked dots denote the double atom at , and the step plot records , which includes the atom at three. Details.Observation windows are measurable sets used to count points of a point process. They are pairwise disjoint when for every . Half-open intervals such as and meet at a boundary without sharing any point, whereas the closed intervals and both contain one. A disjoint union makes window counts additive; it does not make their random variables independent.
A point process on is stationary if every translation preserves its probability law. If its mean count in a unit cube is finite, its intensity measure is for some , where denotes Lebesgue measure. This follows because stationarity makes the mean measure invariant under translations. A constant intensity function of a point process describes only these mean counts, and by itself asserts neither stationarity of the entire law nor independence.[ref]
Lectures on the Poisson Process by Günter Last and others. Section 8.1, Proposition 8.2, printed pp. 69-70: stationarity and constant intensity under a finite unit-cube mean
A Neyman-Scott process places independent offspring clusters around points of a Poisson parent process, with an independently drawn offspring count and displacements. Poisson offspring counts make the offspring process conditionally Poisson given the parents, and therefore give a Cox process. Arbitrary offspring counts need not have that property.
The intensity measure of a point process is its expected counting measure:It may take the value .[ref]
Lectures on the Poisson Process by Günter Last and others. Section 2.2, Definition 2.5, printed p. 12: intensity as the expected counting measure
Countable additivity follows by applying the monotone convergence theorem to the counts of finite unions of pairwise disjoint observation windows. If is locally finite and absolutely continuous with respect to Lebesgue measure, its Radon-Nikodym derivative is the intensity function of a point process :This is an expected number per unit volume, not a probability density function for a randomly selected point. For example, a single deterministic point has , a Dirac measure, and no Lebesgue measure density. The density representation requires its own assumption.[ref]Spatial Point Processes and their Applications. Section 2.1, Definitions 2.1-2.2, printed pp. 26-27: expected counts and intensity functions
For a bounded Borel set , , but local finiteness alone does not ensure that this expected value is finite. Conversely, implies almost surely, even when is unbounded. A constant finite intensity function of a point process on all of has infinite total intensity measure, although every bounded window has finite expected value.
Here is an explicit example even within simple point processes. Let be a positive integer with probability mass function . The telescoping series sums to one, is finite almost surely, but . Conditional on , sample independent points with the uniform distribution on . The resulting point process has finitely many distinct points almost surely, while . Thus finite counts in each realization and finite mean counts are separate requirements; local finiteness of the intensity measure is an integrability assumption.
The same intensity measure can belong to very different point processes. A Poisson point process with a locally finite intensity measure adds two requirements: each finite-intensity window count has the Poisson distribution of mean , and counts in pairwise disjoint observation windows are mutually independent. These requirements determine its probability law; they do not follow from the formula for .[ref]
Lectures on the Poisson Process by Günter Last and others. Section 3.1, Definition 3.1 and Proposition 3.2, printed pp. 19-20: Poisson count laws, independence, and uniqueness
A randomly shifted lattice point process, a unit-rate Poisson point process, and the shared random rate gives dependent point counts construction all satisfy on the real line. Nevertheless, their counts in have respectively variance zero, one, and two. Counts in the disjoint observation windows and have respectively covariance , zero, and . These exact calculations show why measuring mean density cannot identify a spacing or statistical dependence model.
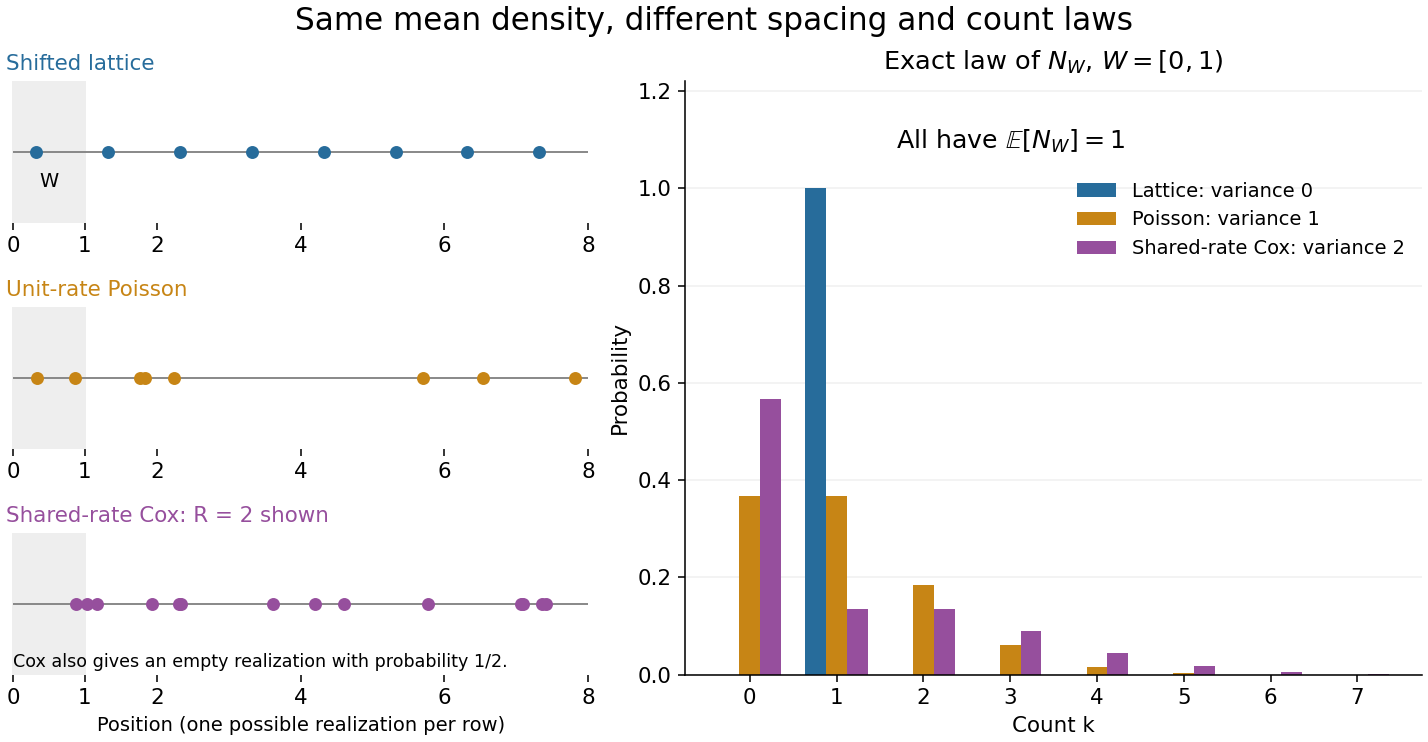
Equal intensity permits regular spacing, Poisson counts, and shared-rate dependence
. All three laws have intensity measure . Left: illustrative realizations of a randomly shifted lattice point process, a unit-rate Poisson point process, and the shared random rate gives dependent point counts construction conditional on rate two; the latter also has a completely empty outcome with probability . Right: exact probability mass functions of the count in , with the axis displayed through seven. Equal expected values of one coexist with variances zero, one, and two. Realizations illustrate spacing; the bars describe laws, not frequencies estimated from those realizations. Details.Let have the uniform distribution on and place a point at every , . This is a simple point process, locally finite, and a stationary point process: a translation only changes the phase modulo one, preserving its uniform distribution. For every Borel set , the Tonelli theorem givesIts consecutive points are exactly one unit apart, despite having the same intensity measure as a unit-rate Poisson point process. This is the one-dimensional translated-grid construction.[ref]
Spatial Point Processes and their Applications. Section 2.1, Example 2.3, printed pp. 26-27: randomly translated grids have constant intensity
Every half-open interval of length one contains exactly one point. For and , , each count has the Bernoulli distribution with parameter , andMore generally, an interval of length , with a nonnegative integer and , contains or points with probabilities and . Its count variance is , while a unit-rate Poisson point process has count variance .
The void probability functional assigns to a measurable set the probability that it contains no atom of a random point measure. For a Poisson random measure of intensity , it is . The exponential void probabilities characterize a Poisson random measure result uses simplicity; doubling every atom of a Poisson measure preserves void probabilities but changes count distributions.
If bounded intervals have void probabilities for Lebesgue measure , a fixed deterministic point has zero chance of being an atom. Surround it by intervals of lengths tending to zero and use . This holds for each fixed endpoint, not simultaneously for all real points of a nonempty point process.
A point measure is a countable sum of Dirac measures. It is simple if all its atoms have mass one, and locally finite if every bounded set has finite mass. Simplicity lets fine enough cells count individual points, whereas occupation indicators would lose multiplicities in a nonsimple measure.
For a fixed bounded interval with no atoms at its endpoints, the occupation count of fully contained half-open dyadic intervals increases to the true count of a simple locally finite point measure. Refinement cannot reduce occupancy. Finitely many distinct atoms in a bounding interval have positive minimum separation; for fine enough cells each atom lies alone, and every interior atom's cell is contained in the target interval. Thus the counts eventually agree, path by path.
A point process is determinantal with kernel relative to a specified reference measure if every correlation function of a point process is the indicated determinant. A rank- finite-rank projection kernel gives an exactly -point process, whose symmetric joint density is .
The th correlation function is the density of the th factorial moment measure: integrating a nonnegative test function against gives the expectation of its sum over ordered -tuples of distinct points. For exactly exchangeably labelled points with symmetric joint density , it is times the marginal density of labels. It is not normalized to have total mass one.
A random matrix is a matrix whose entries are random variables. Its eigenvalues form a random configuration, and its empirical spectral measure records their distribution with equal mass on each eigenvalue. Entry assumptions and normalization determine the spectral regime.
In the unscaled convention with diagonal variance one, a Gaussian unitary ensemble matrix is a Hermitian matrix with independent real diagonal entries and upper off-diagonal entries , where all the and diagonal entries are independent and have the standard normal distribution. Its density on the real coordinates of Hermitian matrices is proportional to . Its exchangeably labelled real eigenvalues have symmetric joint probability density function proportional to . The squared Vandermonde determinant suppresses coincident eigenvalues; orthogonal polynomial projection kernels express the correlation functions of a point process as determinants.
In the unscaled variance-one convention, a Gaussian orthogonal ensemble matrix is a real symmetric matrix whose upper-triangular entries are independent, with for and . Its joint probability density function relative to the upper-triangular coordinates is proportional to . The scaled convention uses ; the scaling must be stated. If has independent standard normal entries, realizes the unscaled convention. Expanding in the entries of gives the covariance identity , with Kronecker deltas.
A standard real Gaussian random matrix has independent and identically distributed standard normal entries. Each column is an orthogonally invariant random vector: its probability density function is proportional to . Consequently multiplying on either side by a fixed orthogonal matrix preserves the joint distribution. Its singular values are random; the expressions for an matrix describe useful spectral scales, not deterministic endpoints that hold for every realization.
For integer , the sum of independent vectors has a Wishart distribution. Its positive-definite density extends to real and is proportional to . It is a conjugate prior for the precision matrix of a multivariate normal distribution. Its mean is .
The WinBUGS declaration
dwish(R, nu) uses ; the density convention is documented in the NIMBLE BUGS-language manual. For it is proper, while the expected inverse matrix does not exist: that expectation requires . Specifying a Wishart prior on precision is therefore a substantive covariance assumption.If has the Wishart distribution, then has the inverse-Wishart distribution. For , its expected value is ; below this threshold the matrix mean does not exist. It commonly models a covariance matrix, but couples the prior behavior of variances and correlations.
For an -by- Hermitian matrix, the empirical spectral measure puts mass at each eigenvalue, counted with multiplicity. It is a probability measure. Integrating a test function against it gives the average of that function evaluated at the eigenvalues.
A real Wigner matrix is a real symmetric matrix whose upper off-diagonal entries are independent centered copies of a fixed random variable, scaled to have variance of order . Diagonal conventions may vary and should be specified separately. A common version has variance-one unscaled off-diagonal entries and either zero diagonal entries or independent diagonal entries with a bounded second moment.
Truncate the unscaled entries of a Wigner matrix at a fixed threshold and subtract their expected values. The difference between original and truncated entries is with , so its variance is bounded by . The centering term cannot be discarded for an asymmetric entry law.
For a fixed mean-zero variance-one real entry law, centered truncation of a Wigner matrix satisfies , where . The spectral Lipschitz bound from Frobenius distance and Markov inequality give probability at most for a spectral test-function discrepancy exceeding . Thus works uniformly in matrix size. A varying entry-law family requires uniform second-moment tail decay instead.
A complex Wishart matrix is the Gram matrix of an -by- matrix of independent centered complex Gaussian random variables with an indicated variance convention. It is a positive semidefinite matrix. In the standard convention with joint entry density proportional to and , its eigenvalue density contains the weight and a squared Vandermonde determinant.
The Laguerre unitary ensemble is the positive-eigenvalue ensemble with joint density proportional to , for . Integer is realized by a complex Wishart matrix. The Laguerre projection kernel expresses its correlation functions of a point process as determinants.
For a metric space with a probability measure , the concentration function is , where is the metric neighbourhood of radius . A sequence exhibits concentration of measure if these functions tend to zero for every fixed positive radius. The metric scale is part of this definition.
A Lévy family of graphs consists of finite connected graphs with their uniform probability measures and graph distances divided by their diameters, whose concentration of measure functions vanish at every fixed positive normalized radius. Equivalently, every family occupying at least half the vertices has a radius- neighbourhood occupying a proportion tending to one, uniformly over such families. Harper theorem and binomial distribution tail bounds prove this for the hypercube graphs.
Equip with uniform probability measure and its nearest-neighbour graph distance divided by , for fixed positive . The set has at least half the vertices. Its radius- graph neighbourhood still omits a proportion tending to when . These grids therefore do not form a Lévy family of graphs.
Equip the Boolean hypercube with uniform probability measure and graph distance divided by its graph diameter. These spaces form a Lévy family of graphs. The vertex-isoperimetric inequality in the discrete cube reduces the complement of a positive-density set's radius- graph neighbourhood to a binomial distribution tail. For fixed density , Chebyshev's inequality puts a lower density quantile at least . After enlarging by , the omitted mass is at most , which tends to zero.
A random vector is positively associated if for every pair of coordinatewise nondecreasing bounded functions . The same inequality holds when both are nonincreasing, by negating them. Repeatedly applying it to products of nonnegative increasing indicators gives for increasing events; the same is true for decreasing events. Thus associated rejection indicators have familywise error rate no greater than independent indicators with the same marginals. Pairwise positive correlation coefficients alone do not give this stronger property. The classical definition is in Esary, Proschan and Walkup (1967).
Extreme value theory studies limiting probability distributions of normalized sample maxima and related extremes. The standard limits for maxima include the Fréchet distribution, negative Weibull distribution, and Gumbel distribution.
The question is often practical: if a batch finishes only when its slowest task finishes, its completion time is a sample maximum. A typical individual delay or a sample mean does not answer that question. The central limit theorem describes suitably normalized sums and sample means under its assumptions; it does not give a limit law for sample maxima. Extreme value theory instead describes how the largest observation changes as the number of opportunities for a large observation grows.
For independent and identically distributed random variables with distribution function , define the sample maximumThe event means that every observation is at most , so independence givesExtreme value theory asks whether there are constants and for which has convergence in distribution to a non-degenerate probability distribution. Equivalently, must tend to a limiting distribution function at its continuity points. The extremal types theorem says that any such limit belongs, up to a change of location and positive scale, to the Gumbel distribution, Fréchet distribution, or negative Weibull distribution. It does not guarantee that a limit exists for every . [ref]
https://rls.sites.oasis.unc.edu/s834-2023/ExtremeValues.pdf. Smith and Weissman, Extreme Values, Section 1.2.1: the three types theorem
.The maximum of independent exponential random variables gives a particularly transparent worked example: its center grows as , and its fluctuations have a Gumbel distribution limit on the scale . Here and below denotes the natural logarithm. This normalization depends on the exponential distribution. Other survival functions can lead to the Fréchet distribution or negative Weibull distribution, with different constants ; the Gumbel distribution and the exponential example's normalization are not universal.
Independence is essential to the product calculation. If instead for one rate- exponential random variable, then for every . Its distribution function stays for and zero below zero, and its median stays . Perfect dependence creates no logarithmic growth: repeating the same random variable supplies no new chance of a larger value.
A historical starting point is R. A. Fisher and L. H. C. Tippett's 1928 paper on limiting laws of the largest or smallest sample member, published in volume 24, issue 2, pages 180–190 of the Proceedings of the Cambridge Philosophical Society. Its abstract studies the possible limiting forms and emphasizes that approach to a limit can be slow. [ref]
https://www.cambridge.org/core/journals/mathematical-proceedings-of-the-cambridge-philosophical-society/article/abs/limiting-forms-of-the-frequency-distribution-of-the-largest-or-smallest-member-of-a-sample/7BE8DE65FCDFC3ABECFE1054DFB56CB5. Fisher and Tippett (1928), Limiting forms of the frequency distribution of the largest or smallest member of a sample: publisher metadata and abstract
.Let be an integer and let be independent and identically distributed random variables with an exponential distribution of rate . Their sample maximum is nonnegative. Substituting the exponential distribution's cumulative distribution function into the distribution functions of independent minima and maxima gives the exact lawFor example, at each observation is below the threshold with probability , but all observations are below it with probability . Thus an individual observation's median becomes an increasingly unlikely upper bound for the whole batch. The general order statistic density in Siegrist's treatment, with , also gives this law on integration. [ref]
https://www.randomservices.org/random/sample/OrderStatistics.html. Siegrist, Random Services: exponential order statistics
.Solving gives the exact quantile function, for ,In a toy model with , the median maximum is seconds for , seconds for , and seconds for . All three use the exact distribution function; the increase comes from taking a maximum over more observations. The case connects to the existing maximum of two exponentials as a scaled sum.
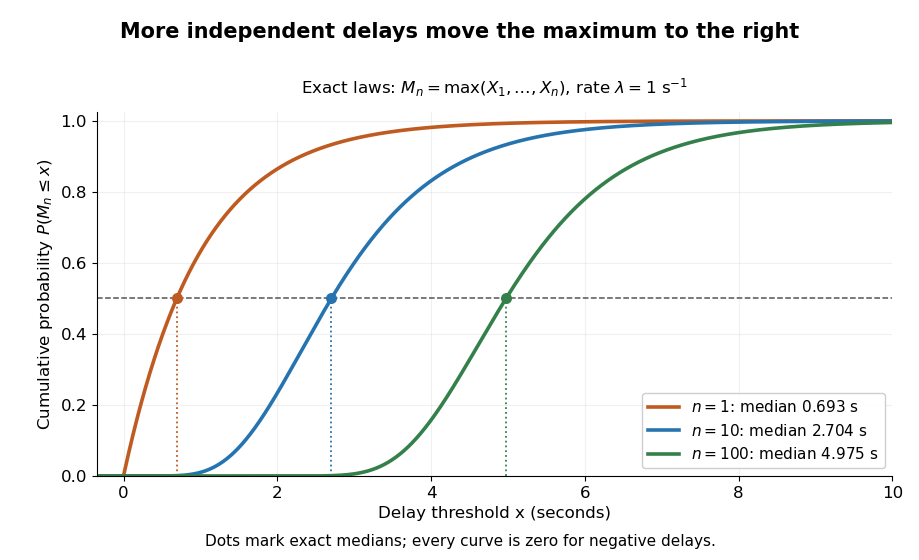
Exact cumulative distribution functions of exponential sample maxima, with rate one per second and median markers
. Details. The Gumbel distribution explains the logarithmic shift visible here: after subtracting and measuring deviations in units of , the distribution functions approach one fixed shape. The next derivation makes that convergence in distribution explicit.
For and a positive threshold , the Hill estimator averages the logarithmic ratios of the top order statistics to . For a Fréchet distribution domain with shape , it estimates the reciprocal tail index . At an untied threshold it equals the empirical distribution function plug-in tail integral . At a tied threshold the plug-in denominator counts strictly larger observations and the identity needs adjustment. Fixed does not by itself yield a consistent tail-index estimate.
Every non-degenerate limit in convergence in distribution of positively scaled and centered sample maxima is a max-stable distribution. Up to positive affine transformations its law is the Gumbel distribution, a Fréchet distribution with positive shape parameter, or a negative Weibull distribution with positive shape parameter. This classifies possible limits, without asserting that every distribution function admits a limiting normalization.
A non-degenerate distribution function is max-stable when every sample maximum of independent and identically distributed random variables can be positively scaled and centered to have the original law. Thus for every integer there are with . The extremal types theorem classifies these laws, up to affine changes, as the Gumbel distribution, Fréchet distribution, and negative Weibull distribution.
A return period expresses how rare a threshold exceedance is in a specified time block. Let be the sample maximum in block , fix a threshold , and suppose is the same for every block. The conventional return period is blocks; blocks of duration give a time of . Thus an annual exceedance probability means a 100-year return period. This names a frequency scale, not a schedule or a guarantee of one exceedance in each century. The annual convention and the misleading “once every 100 years” interpretation are discussed in USGS: the 100-year flood.
To derive a waiting-time interpretation, assume the exceedance indicators are independent and identically distributed random variables with the Bernoulli distribution of parameter . Define , counting the successful block as well as all preceding blocks. The first Bernoulli trials must fail and the th must succeed, so independence gives the geometric distributionThe expected value can also be read directly from the geometric series: . This counts blocks from the starting boundary, not the exact time of an exceedance within its block. Counting only failed blocks instead would give expected value . The waiting law and its memorylessness of the geometric distribution are developed in Kyle Siegrist, Random Services: the geometric distribution.
For a horizon of complete years, at least one exceedance is the complement of no exceedances. Under the same independence and constant- assumptions,For the toy choice , this gives in 10 years, in 30 years, in 50 years, and in 100 years. Even after 100 years there is a chance of no exceedance. These numbers are exact model calculations rounded to one decimal place, not measured frequencies. The median waiting count is 69 years, since ; the expected value is 100 years. A mean and a median answer different questions.
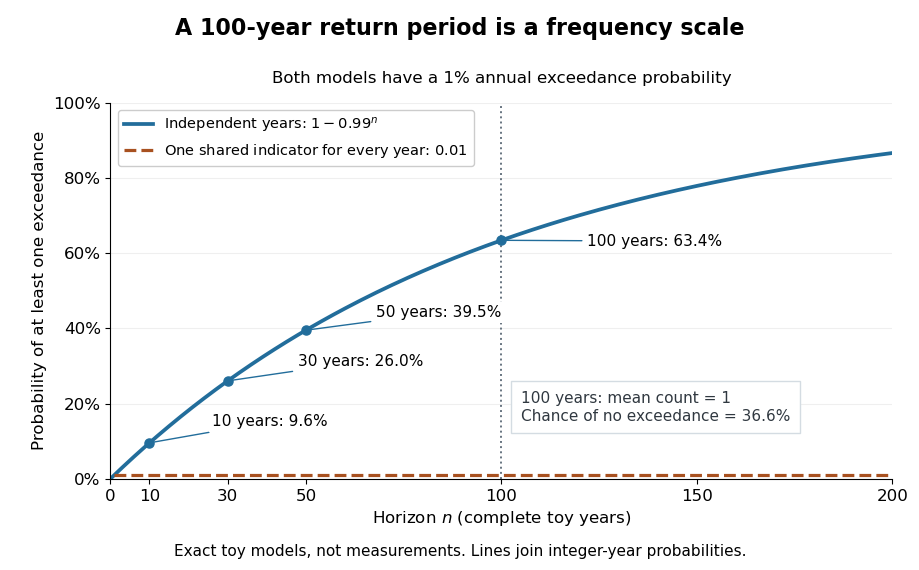
The exceedance count has the binomial distribution under independence, with expected value . Thus has expected value one, although its probability of being at least one is only : some realizations contribute several exceedances. For , the memorylessness of the geometric distribution gives . A long quiet spell does not make the next independent year's exceedance overdue, and an exceedance this year does not force a quiet interval. Two specified consecutive years both exceed with probability in this toy model.
A reproducible tabletop experiment makes the assumptions tangible. Put 100 identical slips numbered 1 to 100 in a bag; after thoroughly mixing, draw one and record whether it is 100. Replace the slip and mix again before every draw. Treat each draw as one toy year, so the exceedance indicator is a Bernoulli random variable with , provided the sampling is uniform and successive draws are independent. Repeat complete 30-draw runs and record the fraction containing at least one 100; separately repeat runs stopped at the first 100 and record their waiting counts. The first fraction targets ; the waiting-count histogram targets . Replacement keeps fixed, mixing is intended to support independence, and repeated runs expose sampling variation. This is a proposed demonstration of the toy model; no experimental results are asserted here.
Stationarity supports a time-invariant annual probability distribution, but does not imply independence. For an extreme counterexample, draw just one Bernoulli random variable of parameter and set for every year. This is a stationary process, yet the probability of any exceedance in every finite horizon is ; from an arbitrary starting boundary the wait is infinite with probability . The reciprocal marginal frequency therefore need not equal that forward waiting expected value. With equal marginal probabilities and arbitrary dependence, only the general bounds follow, the upper bound being the union bound. Linearity of expectation still gives without independence. Mere zero correlation does not restore the product formula; even pairwise independence does not imply joint independence. If annual probabilities change to , independence instead gives , and one fixed return period no longer describes all years.
A return level answers the inverse question to a return period: which threshold has the specified rarity? Let be the common cumulative distribution function of annual sample maxima in a model with stationarity. For a continuous, strictly increasing and , the -year return level isIt has the same units as , whereas is a count of annual blocks. Independence between years is unnecessary for this one-year quantile definition; it is needed for the geometric waiting and multi-year formulas under return period. For a discrete probability distribution, use the generalized quantile function . Then , with equality not guaranteed at jumps; an exact requested exceedance probability may be unattainable.
For a concrete standard model, choose the maxima convention of the Gumbel distribution, with location and scale :The second formula follows by taking logarithms twice and solving . The maxima cumulative distribution function and its inverse are given in NIST: extreme value type I distribution, maximum case. With the deliberately chosen toy values and in arbitrary units, , , and , rounded to three decimals. In particular, is approximately the annual quantile at cumulative probability ; it is not a prediction of the largest observation in the next 100 years. Under independence, the probability that all those annual sample maxima stay below the exact is .
The time block matters. If a toy year contains independent daily blocks, each with exceedance probability at one fixed threshold, its annual exceedance probability is , giving annual return period . The reciprocal counts daily blocks. Dependence among daily exceedances requires their joint law instead; a threshold crossed on several successive days still produces only one exceedance indicator for that year's sample maximum. The peaks-over-threshold method and declustering of extremes address a different choice of extreme-event sampling.
A return level plot graphs horizontally and vertically, often using a logarithmic scale for . To read it, choose a return period, move up to the curve, and read the corresponding return level. Conversely, a threshold's horizontal coordinate gives the reciprocal of its annual exceedance probability. The usual plot of fitted quantiles against return periods, and optional pointwise confidence intervals, are documented in Mathieu Ribatet, POT package: return level plot.
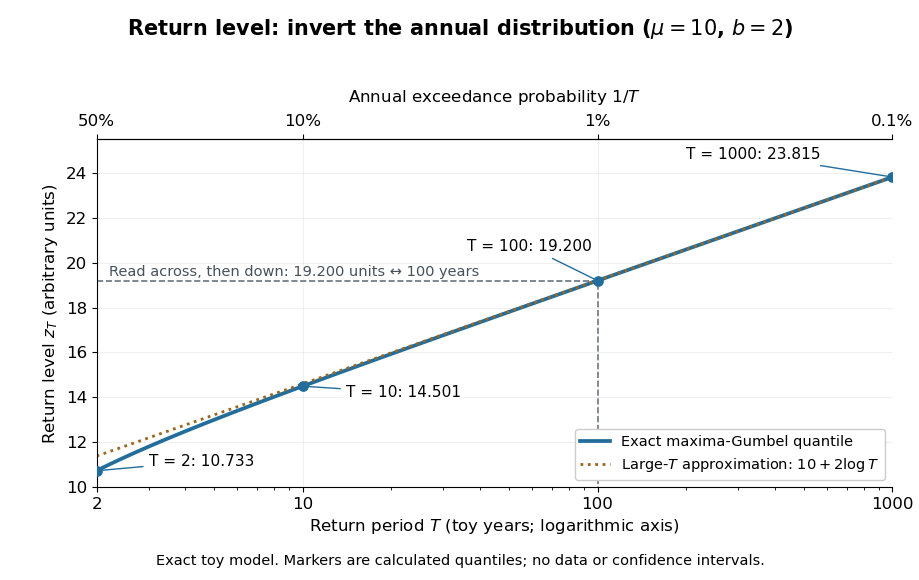
The near-straight shape has a mathematical explanation: since as , the Gumbel distribution gives . Multiplying a large return period by ten therefore increases the return level by approximately , about units for this toy curve. A curve indexed by rarity puts several thresholds on one common scale while retaining their measurement units.
For a fitted curve, a pointwise confidence interval concerns uncertainty in the estimated quantile at a specified ; it is distinct from a prediction interval for a future annual sample maximum, and pointwise intervals need not form a simultaneous confidence band. A far-right curve value can also be an extrapolation beyond the observation record: extending the line adds no observations to support the chosen tail model. The diagram above uses fixed toy parameters, so it shows neither estimation uncertainty nor an observational record. Its interpretation throughout assumes the stated annual block and stationarity.
For scale and shape , the generalized Pareto distribution on nonnegative excesses has cumulative distribution functionThe case is the continuous limit . Positive gives a power-law tail, zero gives an exponential distribution, and negative gives a finite upper endpoint . Its role in modelling high-threshold excesses is explained by the Pickands-Balkema-de Haan theorem.
For the positive-shape generalized Pareto distribution with shape and scale , the expected Fisher information matrix for one observation isThe orthogonalization equation for two statistical parameters gives at fixed new nuisance coordinate. Thus is a global interest-respecting reparametrization. In coordinates , the information is diagonal with entries and .
The peaks-over-threshold method fits a generalized Pareto distribution to exceedances of a high threshold and also estimates their frequency. Together these determine tail probabilities and return levels. For dependent observations, threshold exceedances may occur in clusters; declustering of extremes can separate extreme events before fitting a model for independent events.
Declustering groups dependent threshold exceedances into extreme-event clusters and retains a representative, commonly the cluster maximum. It aims to make the events used in a peaks-over-threshold method approximately independent. The event rate must be estimated consistently with the retained clusters when computing return levels.
For a distribution in an extreme-value domain of attraction, the conditional distribution of the excess above a high threshold is asymptotically approximated by a generalized Pareto distribution with a threshold-dependent scale and a limiting shape parameter. This theorem justifies the peaks-over-threshold method. Threshold selection must balance approximation error against the reduced number of excess observations.
The standard Gumbel distribution for maxima has distribution function for every real . Its probability density function is the derivative of its distribution function:This article uses the maxima convention throughout. Reflecting a standard Gumbel distribution random variable to gives the minima convention, with distribution function . The two conventions have opposite directions of asymmetry, so their formulas must not be interchanged. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/eda366g.htm. NIST: extreme value type I distributions for maxima and minima
.For a location and positive scale , let . This location-scale family has cumulative distribution function and probability density functionSolving gives the standard quantile function , , and hence the standard medianThe median of is therefore . Location is not the median: at the cumulative distribution function is .
To derive the Gumbel distribution as an extreme-value limit, take the maximum of independent exponential random variables with rate and setThe exact distribution function isThe finite- lower boundary is required because . For each fixed real , eventually , and the natural logarithm of the first branch satisfiesExponentiating proves convergence in distribution to the standard Gumbel distribution. It is the familiar limit with : a simple calculation reveals a whole limiting shape. The name honors Emil Gumbel; Siegrist gives this exponential-maxima derivation and the standard Gumbel distribution formulas. [ref]
https://www.randomservices.org/random/special/ExtremeValue.html. Siegrist, Random Services: the Gumbel distribution and its exponential-maxima limit
.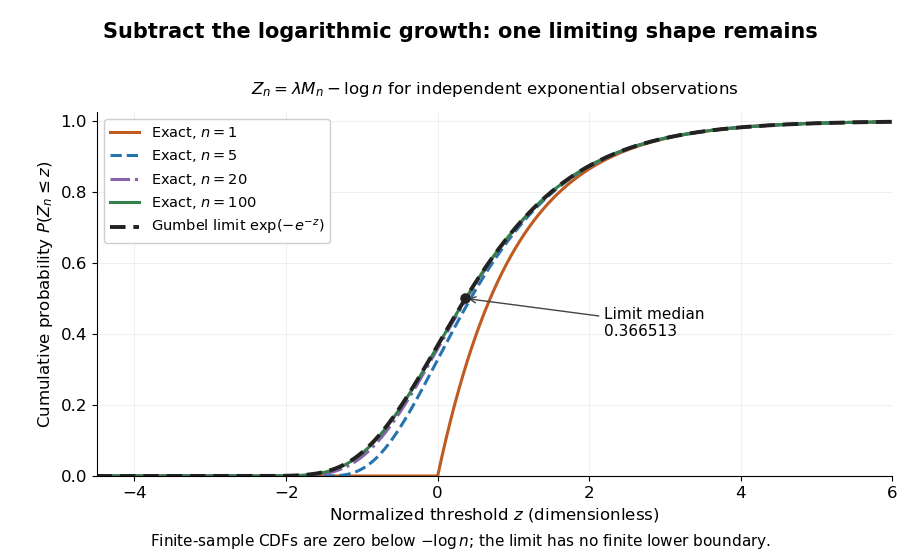
Centered exponential sample maxima for n equal to 1, 5, 20 and 100 approach the standard Gumbel cumulative distribution function
. Details. For the toy delay model , , the limiting Gumbel distribution approximation to has and . Its predicted median iscompared with the exact median . The approximation is about seconds lower in this example. It is not an exact finite-sample probability distribution: the approximating Gumbel distribution assigns positive probability to negative delays, while the exact sample maximum cannot be negative.
The maximum domain of attraction of the Gumbel distribution is characterized by an exponential tail ratio on the scale of a Gumbel auxiliary function. This allows many original probability distributions to share the limiting shape, but it does not make the centering appropriate to all of them.
If has cumulative distribution function , put . For , the decreasing transformation gives , while this probability is zero for . Hence has the rate-one exponential distribution. Conversely, if has that exponential distribution, then has the standard Gumbel distribution.
For fixed and , the factor is a translated Gumbel distribution cumulative function, with transition near . Integration by parts transforms the integral to an exponentially small boundary term plus . Expanding the latter against its finite logarithmic moments gives the displayed two terms because , with Euler's constant. The smooth cutoff shifts the first correction even though replacing it by a step gives the leading tail.
For the Gamma distribution with fixed positive integer shape and rate one, the survival function is . Its sample maximum centered by has convergence in distribution to the standard Gumbel distribution, without an additional scale factor.
A positive Gumbel auxiliary function makes as approaches the right endpoint of a distribution, for every real . Under the Von Mises conditions for extreme values, the reciprocal hazard function is a valid choice.
For , the standard negative Weibull distribution has distribution function for and one for . This is the probability distribution of the negative of a standard positive Weibull distribution variable.
For , the standard Fréchet distribution has distribution function for and zero for . Its maximum domain of attraction consists of distribution functions with an infinite right endpoint of a distribution and a survival function with regular variation of index .
Let be independent and identically distributed random variables taking positive integer values with , and put . For , independence givesIndeed and as . For the probability is zero. The limiting cumulative distribution function is continuous, including at zero, and is a Fréchet distribution with shape one. Its scale grows linearly with sample size even though the individual random variables have infinite expectation.
A distribution function lies in the maximum domain of attraction of if at every continuity point of for some and real . This expresses convergence in distribution of normalized sample maxima.
For a distribution function with tail , let solve . Then for , so the normalized sample maximum tends to the shape-one Fréchet distribution. The inequalities for large show , allowing that simpler scale too.
For an absolutely continuous distribution function with positive probability density function near its right endpoint of a distribution, write for its hazard function. The limits at an infinite endpoint or at a finite endpoint imply attraction to the Fréchet distribution or negative Weibull distribution, respectively. A continuously differentiable reciprocal hazard function with implies attraction to the Gumbel distribution, provided the survival function tends to zero at the endpoint.
The probability of an event is its value under a probability measure, a real number between zero and one. It compares the mass assigned to that event with the unit mass of the whole sample space. For a finite sample space with equally likely outcomes, . For unequal outcome masses, add their individual probabilities instead.
For example, selecting a coin with head probability with chance , or a coin with head probability with chance , gives head probability . This is the law of total probability: averaging over the hidden selection is part of calculating the outcome's probability.
A statistical fluctuation is variation between repeated random outcomes or samples. Its scale can be quantified by variance or standard deviation. For independent signal counts with a Poisson mean proportional to deposited energy, the absolute fluctuation grows as the square root of energy and its relative size decreases as the inverse square root.
For an event in a sample space , the complementary event occurs exactly when does not occur. The complement rule of probability follows from the Kolmogorov axioms: and are disjoint, their union is , and their probabilities therefore add to .
This rule is useful when an event is easier to describe through its failure. For a nonnegative integer-valued random variable , turns an at-least-one calculation into a single value of the probability mass function. In sampling without replacement, the hypergeometric distribution gives the chance of missing all marked objects, so its complement gives the chance of finding at least one.
For an event of probability , its odds in favor are . They compare the probability of the event with that of its complement. Conversely . For example, probability gives odds , or one to three in favor. The same transformation applies to a conditional probability; an odds ratio compares these transformed probabilities in two groups, while a risk ratio compares the probabilities themselves.
For a real random variable , an upper-tail probability has the form and a lower-tail probability has the form . Each is the probability of an event lying beyond a chosen threshold in one direction. A tail probability need not be small: the threshold determines how much of the probability distribution it includes. A concentration inequality bounds such probabilities, often for deviations from an expected value.
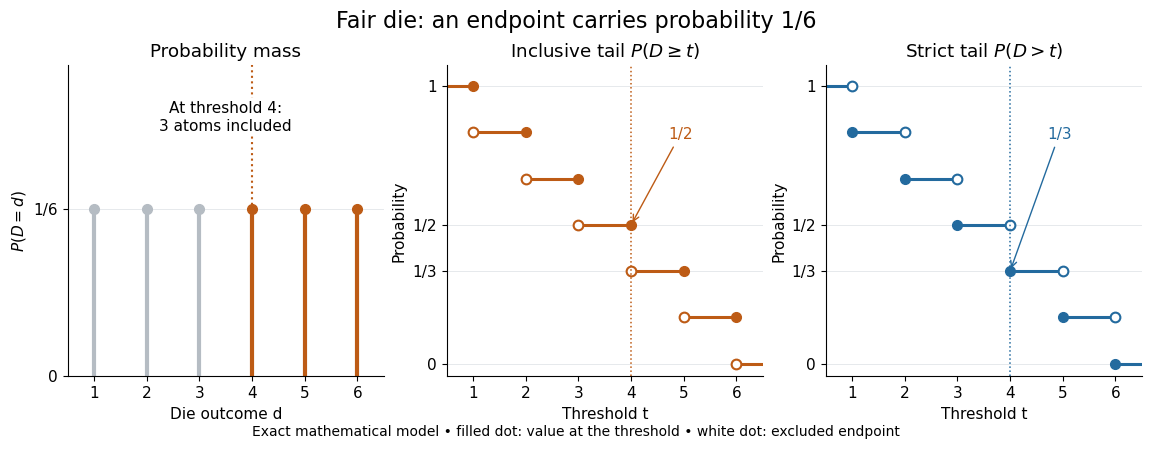
Endpoint conventions matter. Write for the cumulative distribution function and . The complement rule of probability gives four distinct formulas:The strict upper-tail convention is the survival function . Its value differs from the inclusive upper tail probability by exactly the probability mass at the threshold:A singleton with positive probability mass is an atom of a measure. Thus excludes an atom of a measure at , whereas includes it. These endpoint identities follow directly from the cumulative distribution function properties in Kyle Siegrist, Distribution and Quantile Functions: endpoint probabilities and right tails.
As the threshold increases, both upper tail probabilities are nonincreasing functions. The strict survival function is a right-continuous function; the inclusive upper tail probability takes the upper endpoint value at a downward jump, equal to the left limit of the survival function. Both tend to zero as for a real random variable, but the speed of that decay differs across probability distributions. The cumulative distribution function properties and their proof from continuity of probability measures are given in MIT 6.436J, Lecture 4: random variables and cumulative distribution function properties.
For a fair six-sided die , the discrete uniform distribution assigns probability mass to each of . At threshold four,Between four and five, both upper tail probabilities equal . At the largest possible outcome the distinction is especially visible: , but . The diagram shows exact probabilities for this mathematical model; its dots specify which endpoints belong to each step function.
If a probability distribution has a probability density function , then every singleton has zero probability mass andFor an exponential distribution of rate two, for and zero otherwise, so for and for . Hence . This tail probability is an integral of the probability density function, not its height . A mixed probability distribution retains endpoint jumps even with a smooth component: give zero probability mass and choose this exponential distribution with probability . Then , , and for .
A two-sided tail probability can measure the absolute value of displacement from a specified center . For , the two extreme events are disjoint events, soFor strict displacement , replace the last expression by . The condition prevents overlap; at adding inclusive tails double-counts any probability mass at . For a uniform distribution on , take and : the two tail probabilities are each and their sum is . Equal tails follow from this symmetric probability distribution, not from the phrase two-sided alone; for a uniform distribution on with , the two tail probabilities are zero and .
The tail-sum formula for expectation turns a whole curve of tail probabilities into an expected value. For any nonnegative random variable , without assuming a probability density function or a finite expected value,For a proof outline, write pointwise and exchange the expected value and Lebesgue integral using Tonelli theorem; is an indicator function. The inclusive version has the same Lebesgue integral: positive probability masses occur at only a countable set of thresholds, which has Lebesgue measure zero. For a nonnegative integer-valued random variable , the tail-sum formula instead gives . The integer hypothesis is essential for these sums. The integral identity, its indicator function proof, and the integer version appear in Kyle Siegrist, Additional Properties of Expected Value: integration and summation of right tails.
For the fair die, this tail-sum formula yields , equal to the direct weighted arithmetic mean . For the rate-two exponential distribution, the area under the survival function is , its expected value. The first panel below shades an integral of the probability density function for a single threshold; the second shades an integral of the survival function across all nonnegative thresholds. These are analytical illustrations, with the displayed curves truncated at three; their exact total areas use an infinite integration range.
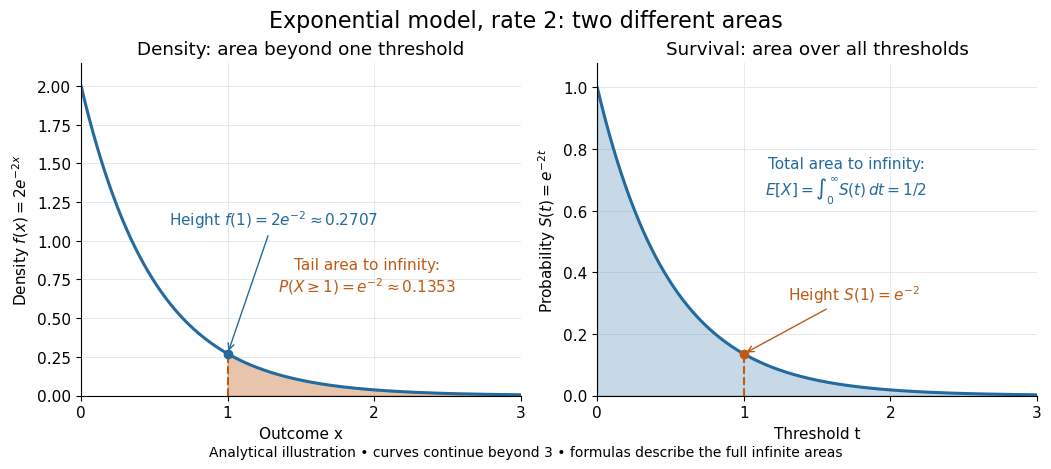
Nonnegativity is essential to interpreting the upper tail probability area as : for a general real random variable that area equals the expected value of its positive part. An integrable random variable satisfies , subtracting the expected value of its negative part; infinite terms cannot be canceled. Even when is finite almost surely, its expected value can be infinite. For the shape-one Pareto distribution on , on and for , so the area is . The finite versus infinite expected value distinction is illustrated in Kyle Siegrist, Definitions and Basic Properties: exponential and Pareto expected values.
Why are tail probabilities useful? They answer threshold questions directly, and a concentration inequality can bound them without knowing the full probability distribution. For nonnegative with finite expected value, Markov inequality gives for : a large threshold relative to the expected value forces rarity. The quantile function reverses the question by choosing a threshold for a prescribed cumulative level. If with , then ; an atom of a measure may prevent equality. For the die, , with strict upper tail probability zero and inclusive upper tail probability .
A tail probability describes rarity under a specified probability distribution; it is not automatically a conditional probability after extra information. For with ,because the threshold events are nested. Thus the die has but . Conditioning changes the sample space and renormalizes its probability measure; the same extreme outcomes can become common in that restricted population.
Percolation theory asks how many local connections must be available before a large connected structure appears. Start with a graph, randomly retain some edges or vertices, and study the resulting percolation clusters. In independent bond percolation, every edge is open with probability , independently of the others. In independent site percolation, the random decisions concern vertices instead. A percolation cluster is a connected component of a graph formed by the available connections; an open path joins two vertices exactly when they belong to the same percolation cluster.
The attraction is that a local rule can produce a global change. One open edge says little about travel across a large graph. Many alternative graph paths can nevertheless make distant connections likely. The model separates the geometry of possible connections from the probability distribution of which connections are usable. This was the central perspective of Broadbent and Hammersley's 1957 paper, which discussed porous solids and disease transmission as interpretations of the same mathematical structure: [ref]
https://courses.physics.ucsd.edu/2019/Spring/physics235/Broadbent_Hammersley.pdf. Percolation processes I: Crystals and mazes, introduction
. Independent bond percolation supplies a simplified model of those systems; the physical interpretation still requires justification of its independence assumptions.For a completely calculable example, consider the four edges around a square and ask whether opposite corners and are connected. There are two graph paths, each using two edges. Each open path has probability . Their events are independent events because the paths share no edges, even though they share endpoints. The inclusion-exclusion principle therefore givesAt , the connection probability is , larger than the for either chosen graph path. Counting all sixteen equally likely edge configurations gives the same answer: two configurations with exactly two open edges, four with three, and one with four connect to . Connectivity benefits from alternative routes; adding their probabilities without subtracting their overlap would count the all-open configuration twice.
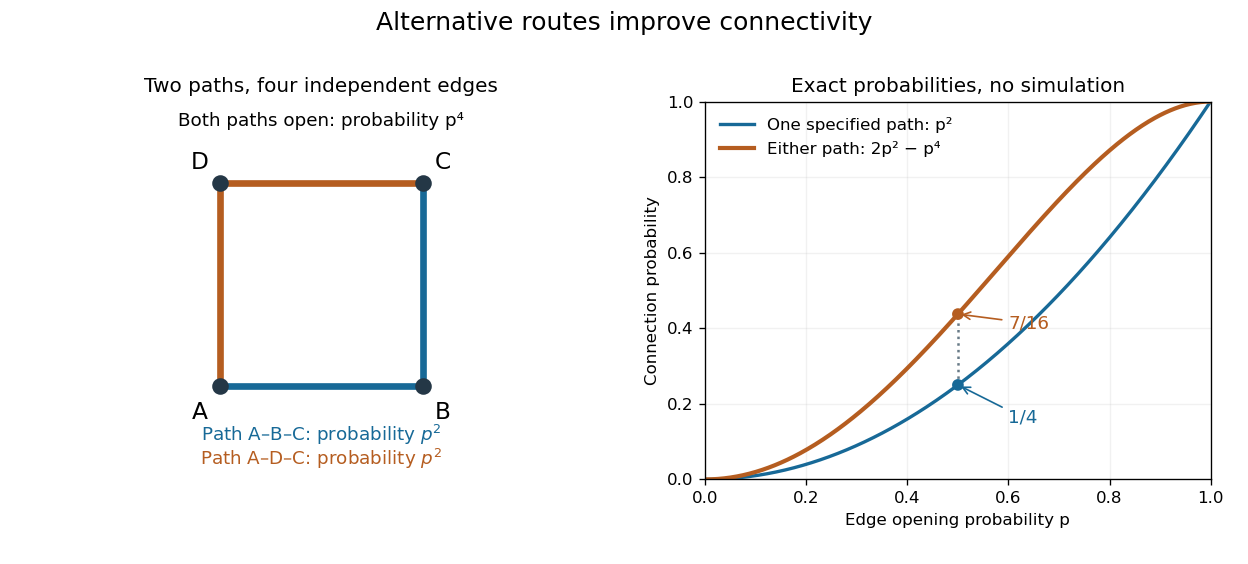
Two alternative paths increase the probability of connecting opposite corners
. Details. This finite calculation is already useful for studying redundant connections. The deeper question is what happens as the graph becomes arbitrarily large: does connectivity remain confined to finite percolation clusters, or can an infinite percolation cluster appear? The percolation probability and percolation critical probability make that question precise. A finite picture can illustrate the geometry, but cannot establish the existence of an infinite percolation cluster.
In bond percolation on a directed graph, independently open each directed edge with probability . The out-cluster of consists of vertices reachable by open directed paths. In site percolation, independently open vertices and require every vertex of the directed path, including , to be open. The same definitions allow a multigraph. The orientation matters: an infinite underlying connected graph need not contain an infinite out-cluster from a specified root.
Independently open vertices of a directed graph with common probability , and require every vertex of an infinite directed path to be open, including its root. Conditioning the root to be open changes the survival probability by a factor and does not change the critical probability. This model gives an independent comparison process in the independent oriented-percolation comparison for the contact process.
Independently open the bonds of a directed graph with a common probability , and ask whether an infinite open directed path starts at a specified root. On the oriented square lattice, edges run from to with even. The critical probability is the infimum of parameters with positive survival probability. The incoming-edge coupling of site and bond percolation compares this threshold with that of oriented site percolation.
Take a directed graph with vertices and parallel bonds from to . This is a locally finite graph, although the incoming degrees are unbounded. For bond percolation, whenever : the failure probabilities are summable, so the infinite product is positive. For site percolation, survival requires every vertex of the ray to be open, which has probability zero for . Thus the survival and susceptibility thresholds for directed percolation satisfy and .
Suppose every vertex of a directed graph has at most incoming bonds. In bond percolation with parameter , open a site whenever at least one incoming bond is open. Incoming bond sets have different heads and hence are disjoint, so these site indicators are independent random variables. Supplement their probabilities to . Every vertex reached by a nontrivial open directed path is now open. Conditioning the root to be open gives , since a simple directed path from the root never uses a bond entering the root. Thus .
For the out-cluster in directed percolation, define and , with value when the relevant set is empty below . The first is a survival threshold; the second is a percolation susceptibility threshold. Both depend on the root in a general directed graph. Exploring a site percolation cluster and using each fresh vertex coin for its first tested incoming bond gives a coupling of probability distributions with bond percolation such that and . Consequently and .
For critical site percolation on the triangular lattice, scaling-limit crossing probabilities transform naturally under conformal maps between planar domains. This rigorously established property supports descriptions of interfaces by SLE and calculations of planar percolation critical exponents. Transferring it to a different lattice or to bond percolation requires a separate universality argument.
An iterative expansion of long-range connectivity functions that separates an approximately random-walk contribution from corrections caused by loops and intersections. In suitable high-dimensional percolation models it controls these corrections and proves mean-field percolation exponents. It also applies to other models, including self-avoiding walks; its use always requires model-specific estimates.
In independent bond percolation with parameter , every edge of a graph is open with probability and closed with probability . The choices are independent random variables with a Bernoulli distribution. All vertices remain present; only the usable connections change. The percolation clusters are the connected components of a graph formed by the open edges, including isolated vertices.
A specified simple graph path with edges is an open path with probability , by independence. Connecting its endpoints is a different event: other graph paths may also connect them. The four-edge example in percolation theory makes that distinction explicit. Interpreting open edges as usable channels makes the model useful for connectivity questions; it does not by itself assign a travel time, flow rate, or capacity to a channel.
For the induced square lattice subgraph in , is the probability of an open graph path from its left boundary to its right boundary under independent bond percolation of density . Width and height count lattice spacings. Dual bond percolation exchanges failure with a top-to-bottom dual crossing of dimensions , with the usual exterior boundary vertices.
Take the increasing event that a finite square torus graph contains some long horizontal or vertical rectangle crossing. Translations and a quarter turn make this a transitive increasing event on its bonds. A positive critical crossing bound and the Friedgut-Kalai sharp threshold theorem make its supercritical probability tend to one. A bounded family of shorter, thicker rectangles intercepts every possible long crossing. The square-root trick for positively associated events transfers the high probability to each fixed intercepting rectangle. Using every possible translate would lose the useful bounded exponent.
A path in the underlying graph all of whose edges are open. Connectivity of open paths determines the percolation clusters. A ray in a graph with all edges open is an infinite ray in a graph.
If independent edges of a locally finite graph receive fair orientations, exploring outward from a root tests each fresh reached-to-unreached boundary edge with success probability . Deferred decisions give exactly the exploration law of the root cluster in bond percolation of density . Thus the two reachable graph vertex sets have the same distribution. An infinite out-cluster contains an infinite simple directed ray by the König infinity lemma. Geometrically biased orientations do not generally give the same uniform edge-success law.
Here is critical two-point connectivity. The condition controls the intersection effects that spoil a branching approximation. It is a sufficient criterion for important mean-field percolation exponents, including the order-parameter, percolation susceptibility and cluster-tail exponents. Establishing detailed spatial asymptotics is a further task, commonly addressed by lace expansion.
The two-point percolation two-point connection probability is the probability that two fixed graph vertices belong to the same percolation cluster. On a translation-invariant lattice it depends on their displacement. Restricting the permitted connecting graph paths to a subgraph gives the corresponding confined percolation two-point connection probability. The Harris-FKG inequality implies .
For bond percolation on the square lattice, write and . A maximal-probability boundary graph vertex can be placed at by symmetry. Reflection about identifies its connection probability from with that from . The Harris-FKG inequality yields for .
For nearest-neighbour bond percolation with on the strip , put . The Harris-FKG inequality and translation invariance imply . Thus is a subadditive sequence, and the Fekete lemma givesThe direct horizontal graph path gives . Enlarging the strip increases every percolation two-point connection probability, so is nonincreasing in and has a nonnegative limit of a sequence.
Let be the unrestricted planar two-point percolation two-point connection probability. Every finite connecting graph path is contained in some strip, so for each fixed . ThereforeThe equality uses commuting infima and monotonicity, not an unjustified interchange of two general limits. The right-hand side is the whole-plane connection decay rate by the Fekete lemma.
A vertical cut between consecutive columns of contains edges. All are closed with probability . Cuts in different columns use disjoint edges, so their closed-cut events are independent. A connection from column zero to column must cross each of the intervening cuts. ConsequentlyThis finite-width obstruction persists even when the unrestricted planar percolation is supercritical.
The independent edge law of bond percolation on is ergodic under lattice translations: every translation-invariant event has probability zero or one.
Articles were limited to the first 100 out of 2776 total.
Articles by others on the same topic



Probability theory is a branch of mathematics that deals with the analysis and quantification of uncertainty. It provides the framework for modeling random events and phenomena, allowing one to calculate the likelihood of different outcomes. Here are some key concepts and components of probability theory: 1. **Random Experiment**: An experiment or process that leads to one or more outcomes, where the result cannot be predicted with certainty. For example, tossing a coin or rolling a die.