The iterated prisoner's dilemma is a repeated game with a prisoner's dilemma at each round. Earlier choices can change later best responses: a present gain from defection may be outweighed by lost future cooperation. A pure strategy now specifies an action after every possible observed history, including histories that its own prescribed play would never reach. The horizon, observations, initial actions, and payoff convention must be specified before assessing a Nash equilibrium or subgame perfect equilibrium.
For the following worked example, repeat the prisoner's dilemma above infinitely at rounds . Assume public perfect monitoring: after each round both players observe both actions exactly, without error. They share a discount factor and evaluate a path of stage payoffs using the normalized discounted payoffThe round-zero weight is one before normalization, including when . A larger discount factor gives future payoffs more weight; the geometric series makes a constant stage payoff have the same normalized value. These assumptions and normalization follow [ref]
https://ocw.mit.edu/courses/6-254-game-theory-with-engineering-applications-spring-2010/5a158a7558165d0e22b5b27fcfa01713_MIT6_254S10_lec15.pdf. Asu Ozdaglar, MIT 6.254, lecture 15, slides 6–15
. The numerical payoffs here are our example; the lecture uses a different table.Suppose both players use grim trigger: play initially and while every past action of both players was ; after any observed , play forever. With no unilateral deviation, each gets normalized payoff . A first unilateral deviation to earns now, then at most each round because the opponent switches permanently to always defect. The deviator attains that continuation payoff by choosing thereafter. At any history of mutual cooperation, the comparison is thereforeCooperation is a best response precisely whenEquivalently, without normalization the geometric series givesMultiplying both unnormalized payoffs by the same positive factor leaves the best response comparison unchanged.
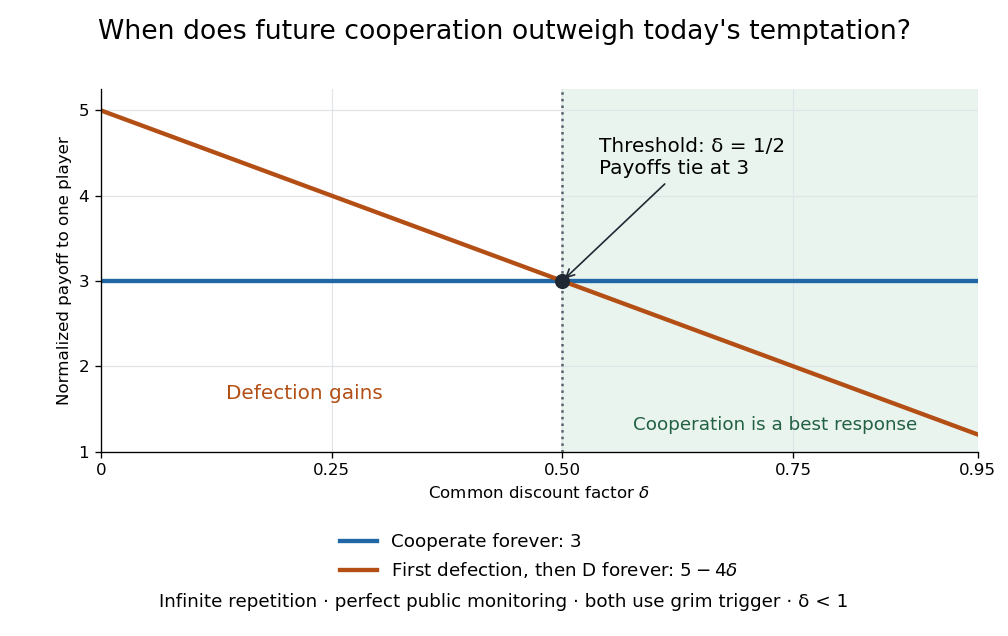
Repeated prisoner's dilemma: normalized cooperation and first-deviation payoffs cross at discount factor one half
. Details. 
For example, with discount factor , the first unilateral deviation gives normalized payoff , so mutual grim trigger is not a Nash equilibrium. At , it gives , so cooperation is preferable. At the two payoffs tie: the incentive to cooperate is weak, which is sufficient for a subgame perfect equilibrium.
The punishment is credible after every history containing a defection: the opponent's pure strategy then prescribes forever, and remains the stage best response, earning rather than . Together with the cooperative-history comparison, this establishes mutual grim trigger as a subgame perfect equilibrium for . Delaying the first unilateral deviation merely delays the same gain or loss; further cooperation during punishment only lowers the deviator's payoff. Mutual always defect also remains a subgame perfect equilibrium, so patience permits cooperation without making it inevitable.
This calculation assumes an infinite horizon and ; it does not define a discounted payoff at . With a finite, commonly known final round and positive weight on each round, backward induction instead gives mutual defection in every round of this stage game. Observational errors change the model too: one mistaken defection permanently activates grim trigger. Historical dependence, initial memories, and the payoff time convention also affect whether a cooperative rule resists or invades other pure strategies; the existing reactive strategy and Tit for tat discussions concern those additional questions.
A grim trigger is a history-dependent pure strategy in a repeated game that switches permanently to punishment after a trigger event. In the iterated prisoner's dilemma above, the trigger is any player's observed defection, and punishment is always defect. Unlike Tit for tat, grim trigger never restores cooperation after the opponent cooperates again. Whether mutual grim trigger is a subgame perfect equilibrium depends on the stage payoffs, discount factor, and monitoring assumptions; it is not an unconditional property of the rule. See Ozdaglar, lecture 15, slides 12–15.
A reactive strategy cooperates with probability after the opponent cooperated and probability after the opponent defected. It ignores its own previous action. Independent behavioural randomization gives a four-state joint-action Markov chain. The reduced marginal recurrences depend on the prescribed initial action distribution.
Tit for tat cooperates initially and then repeats the opponent's previous action. Two such players cooperate forever without mistakes under this initial convention. It retaliates against defection and returns to cooperation after the opponent cooperates.
In a symmetric two-action stage game write for mutual cooperation, mutual defection, sole defection and sole cooperation payoffs. Suppose , and . Against an initially cooperative Tit for tat, every action sequence has limiting upper average payoff at most .
For a deviator's actions , put , and . The opponent at time plays . Check the four transitions: to and to satisfywith equality; to uses , and to uses . A telescoping sum gives the displayed finite-horizon bound. Divide by the horizon and let it increase. Mutual Tit for tat yields every round, so it is a Nash equilibrium under the long-run average payoff criterion. The argument is pathwise and therefore covers arbitrary deviations representable by finite-state machines, as well as action sequences outside that class.
For a reactive resident with , let and . Its self-payoff and both ordered cross-payoffs against Tit for tat equal . At introduced Tit for tat frequency , its fitness difference is therefore the displayed expression. If , it is positive for because . Fully cooperative reached histories tie; the deterministic opposite-response strategy needs a separate cycle calculation. Initial advantage is order frequency rather than a positive invasion exponent at zero.
In an -round iterated prisoner's dilemma, Tit for tat against always defect gets once and thereafter; the defector gets once and thereafter. Their self-payoffs are . At introduced frequency , subtracting mixed-population payoffs gives . The displayed positive threshold applies when its denominator is positive and the threshold is less than one. Taking first removes this finite entry cost, so the horizon and rare-mutant limits cannot be casually interchanged.
Under cooperative initial memories, matches involving only Tit for tat and always cooperate contain only cooperation, so all four payoffs equal . The two-condition criterion for evolutionary stability has both differences zero. Thus Tit for tat is not an evolutionarily stable strategy against a strategy space containing unconditional cooperation, even if it is a Nash equilibrium. This counterexample is valid for finite horizons and discounting as well as infinite averages.
With initially independent actions, same-round independence is preserved by reactive updates: each next action uses the other independent previous action and fresh independent randomization. Marginal cooperation follows , . If the product of response slopes has modulus below one, these recurrences converge and the joint distribution is their product. Averaging over that distribution gives the long-time payoffs. At deterministic response slopes of modulus one, initial-memory-specific cycles must instead be averaged directly.
Articles by others on the same topic
There are currently no matching articles.