Game theory studies decisions whose consequences depend on what other decision makers choose. A bidder's gain depends on competing bids in an auction; a driver's travel time depends on other drivers in a congestion game. This strategic interdependence makes choosing well a different problem from optimization against a fixed environment: each participant's best response depends on the others' choices.
A normal-form game specifies the players, their available pure strategies, and their payoffs for each strategy profile. Larger payoffs mean more preferred outcomes for that player. Unless stated otherwise, a two-player table below lists : the row player's payoff first, the column player's second. Each player maximizes their own expected utility; the numbers need not represent money, and comparing different players' numerical scales is unnecessary.
The central question is whether everyone's choices fit together. A Nash equilibrium consists of mutual best responses: no unilateral deviation improves a player's expected payoff. It can involve definite choices, or mixed strategies that deliberately randomize. Matching pennies shows why randomization can be essential; the coordination game shows how players can share an interest in coordinating while disagreeing over which outcome to choose. Such shared gains are absent from a two-player zero-sum game, where one player's gain is exactly the other's loss.
These ideas are useful both for analyzing incentives and for designing them. Mechanism design asks how changing the rules changes participants' best responses; evolutionary game theory studies how successful strategies spread. The mathematical appeal is that local comparisons of payoffs can reveal a globally consistent pattern of choices. Consistency alone does not imply Pareto efficiency, uniqueness, or that actual play will converge to a Nash equilibrium.
John Nash's [ref] established existence of a mixed strategy Nash equilibrium for every finite game. His [ref]
https://cs.uwaterloo.ca/~klarson/teaching/F04-886/papers/nash51.pdf. 1951 paper, Non-Cooperative Games, Annals of Mathematics 54, 286–295
developed the theory beyond two-player zero-sum games. The distinction between conflicting and shared interests is fundamental to the subject.A search game models a strategic interaction between a searcher and an opponent choosing what is hidden, where it is hidden, or how it moves. The searcher chooses a search policy; the payoff may be detection probability, discovery time or search cost. The information and allowed motion must be stated before solving the game.
For a simple zero-sum game, an object is hidden at one of two locations. Checking either location costs one time unit and always detects the object if present. Searching location one first with probability gives expected discovery times when the object is there and when it is at location two. Minimizing the worst case sets , with value .
A deterministic first choice permits the hider to force time two. Thus mixed strategies have a concrete value even in this small example. Adding unequal travel costs or an evading target changes both the strategy space and the optimization problem.
A routing game models users choosing paths through a flow network, where each user's travel time depends on the traffic using the selected edges. A nonatomic model treats each user as infinitesimal; at equilibrium, every used path has minimum latency among the available paths. An atomic model instead lets individual players move a nonzero amount of traffic.
Consider one unit of nonatomic demand and two parallel edges with latencies and . Sending all flow on the first edge is an equilibrium: its latency is one, and an infinitesimal user cannot obtain less on the second. If a planner sends fraction on the first edge, total travel cost isThis is minimized at , with cost , below the equilibrium cost one. The example exhibits a price of anarchy of and separates individual latency minimization from minimum total cost.
Algorithmic game theory studies the interaction of algorithms with strategic behavior. It asks both how hard equilibria are to compute and how mechanisms should be designed when participants choose actions to improve their own utility.
For example, a shortest-path algorithm optimizes travel time for one specified traveler, while a routing game asks what happens when many travelers each choose a route. A Nash equilibrium can have a larger total delay than a centrally chosen allocation. Quantifying that loss by a price of anarchy links incentives with computational optimization. The input representation, equilibrium concept and allowed running time must all be specified.
For a cost-minimization game with positive social optimum and a nonempty set of the specified Nash equilibria, the price of stability isIt measures the cost of requiring stability even when the best equilibrium can be selected. The equilibrium class, such as pure or mixed, and social-cost convention must be stated.
In a symmetric two-player game with actions , let each player's cost be one at , two at and three when the actions differ. Both coordinated choices are Nash equilibria; the best equilibrium has total cost two, matching the optimum, so the price of stability is one. The worst equilibrium instead costs four, giving price of anarchy two. The distinction matters when a designer can recommend an outcome but cannot force anyone to remain at an unstable one.[ref]
The Price of Stability for Network Design with Fair Cost Allocation by Elliot Anshelevich and others. Introduction, best equilibrium and stability interpretation
For a cost-minimization game, the price of anarchy is the ratio of the worst equilibrium social cost to the best feasible social cost:Here is the specified equilibrium set, the feasible profiles, and the chosen nonnegative social cost. The ratio requires a positive denominator; zero optimum costs and empty equilibrium sets need separate conventions. A payoff-maximization formulation uses the reciprocal orientation to keep a larger number meaning worse efficiency.
In the two-edge routing game with one unit of flow and latencies and one, the equilibrium costs one while the optimum costs , so the price of anarchy is . The best equilibrium instead defines the price of stability. Bounds depend on the equilibrium notion and the allowed game class; one example does not establish a universal bound for all games.
A game whose players' utility are specified separately, without assuming a fixed sum. Improving one player's utility need not worsen another's. A finite perfect-information game can be solved by backward induction using entire utility tuples and each moving player's own coordinate, as in max-n search.
A turn-based game on a directed graph in which a player tries to force a designated target set. Its winning region is a least fixed point: add that player's vertices with some winning successor and the opponent's vertices with all successors winning. The finite-graph version uses the same construction as a winning-position attractor in an infinite game.
With disjoint terminal wins for two players and infinite plays valued as draws, compute both reachability attractors while keeping terminals fixed. Entry ranks give terminating winning strategies; positions outside both regions admit defence avoiding a forced loss. A cycle alone is not a certificate of a draw if it also offers a forceable winning exit.
A decision problem in which the same information set can be reached more than once along a single path, so the decision-maker does not know which visit is occurring. It violates perfect recall. A behavioural strategy uses a common probability at each visit and independent random draws, making terminal probabilities nonlinear in that probability.
For instance, let stopping at the first visit pay zero, continuing and then stopping pay eight, and continuing twice pay one. With continuation probability , expected payoff is . Its maximum exceeds the best deterministic-plan payoff of one. Randomizing once between the deterministic plans cannot reproduce the two fresh decisions.
An assignment of an action probability distribution to every information set of a player in an extensive-form game. Randomization is fresh at each encounter. It differs from a mixed strategy, which chooses a complete deterministic plan once before play. Perfect recall is central to equivalence of their induced outcome distributions.
Consider a zero-sum game in which a player chooses a binary action, forgets it, and chooses again, while an opponent makes one hidden binary choice. The first player's payoff is one if all three choices agree and zero otherwise. The later information set merges both initial-action histories. This violates perfect recall without revisiting the same information set, unlike an absent-minded decision problem.
A behavioural strategy chooses the first and second actions with independent left probabilities . Its security level payoff is , since the opponent selects the less favorable target action. This minimum is at most , attained at .
A mixed strategy instead samples the all-left or all-right complete plan with equal probabilities, guaranteeing . Against an opponent who chooses each target equally often, each complete constant plan earns and each nonconstant plan earns zero, so no mixed strategy can guarantee more. The separation comes from correlation between a sampled plan's actions; fresh independent randomizations cannot retain it after the initial action is forgotten.
A player has perfect recall when the information sets never erase that player's previously available information or earlier chosen actions. With perfect recall, randomizing once over complete pure strategies and using suitable independent randomizations at information sets can induce the same outcome distributions.
Without perfect recall, one information set may be encountered twice on the same play path. A behavioural strategy then uses the same probabilities with fresh draws at both encounters; its outcome distribution need not be attainable by any mixed strategy over deterministic plans.
In a finite extensive-form game with perfect recall, each mixed strategy has a realization-equivalent behavioural strategy, and every behavioural strategy has a realization-equivalent mixed strategy. The latter direction samples all contingent actions independently in advance. For the former, condition the random complete plan on the player's own action and information history leading to an information set; perfect recall makes that own history common to its nodes. Conditional action probabilities then reproduce the terminal path factors. At an information set reached with zero probability under that player's own plan distribution, choose any action distribution. The result does not assert equivalence without perfect recall.[ref]
Extensive games and the problem of information by Harold W. Kuhn. original article, pp. 193–216, perfect-recall equivalence
An extensive-form game in which each information set contains a single decision node. Each acting player knows the entire preceding sequence of moves. Finite games with this property can be solved for a subgame perfect equilibrium by backward induction.
A collection of decision nodes that the acting player cannot distinguish when choosing an action in an extensive-form game. All nodes in an information set have the same acting player and available actions. A behavioural strategy assigns the same action probabilities throughout that set.
In an extensive-form game, a player has imperfect information when some decision information set contains more than one node. The player cannot distinguish those histories at the time of acting. This does not itself imply failure of perfect recall: a player can remember all their own earlier information and actions while never having observed an opponent's hidden choice. Conversely, merging histories in which the player's own earlier actions differ violates perfect recall.
A game described by a game tree, with the acting player and available actions specified at each decision node, payoffs at terminal nodes, and information sets indicating which decision nodes a player can distinguish. A pure strategy specifies an action at every information set belonging to that player, including ones not reached during realized play.
Two players alternate proposals for dividing a pie, with a fixed final round. Agreement ends the game; rejection shrinks the next available pie by a factor . Final rejection gives both players zero. Offers range continuously over the entire available pie. Backward induction in games determines immediate agreement and the proposer's share through the continuous-offer bargaining acceptance lemma and the finite-horizon bargaining parity effect. Discrete offer grids can change both the boundary behavior and the exact shares.
In finite-horizon alternating-offer bargaining, the proposer with rounds left retains fraction of the currently available pie. Terminal acceptance gives . After rejection, the responder becomes proposer and can obtain fraction of the current pie. The continuous-offer bargaining acceptance lemma therefore gives . Summing the resulting finite geometric series proves the displayed formula.
Odd horizons give shares above , decreasing toward it; even horizons give shares below it, increasing toward it. Between two available horizons , choose if is odd and if is even. This concerns the initial proposer and immediate agreement, rather than waiting until the selected final round to obtain its share.
Let a proposer divide a pie of size by continuously offering its responder . Rejection gives fixed continuation payoffs to the proposer and to the responder, with and . Then a subgame perfect equilibrium must have the responder accept with probability one. The proposer offers exactly , retaining .
Sequential rationality forces rejection for and acceptance for . If acceptance at had probability , that offer would give the proposer . Every larger offer gives less than and can be improved by a smaller offer still above ; every smaller offer gives . The supremum would therefore be unattained. Randomizing offers cannot attain it either: the nonnegative gap from would be strictly positive almost surely and hence have positive expectation. No best response would exist, contradicting equilibrium. Acceptance at removes this gap and makes the unique optimal proposal. The assumptions and exclude degenerate indifference of the proposer.
In a finite perfect-information game without chance moves, solve terminal decision points first. At each earlier decision point, its player chooses an action maximizing its own payoff among the already solved continuations. Record a choice in every subgame, including those not reached by the root choice. This constructs a subgame perfect equilibrium. Tied choices may yield several equilibrium strategies and several outcomes. The name refers to Ernst Zermelo; the computational procedure is an application of backward induction.
Suppose a finite perfect-information game has no chance moves, and every player strictly ranks the possible outcome labels. Different terminal histories may have the same outcome label and thus the same payoff. Every subgame then has a unique subgame perfect equilibrium outcome, even though its equilibrium strategy need not be unique.
The proof is backward induction. Each child subgame has a unique continuation outcome. The moving player's strict ranking selects exactly one best label among those outcomes. Several actions can tie only by leading to that same label, which proves uniqueness at the current node. For a sequential election, the labels may be winning candidates: a voter can have several optimal ballots, all producing its same favourite achievable winner. If preferences have ties between different labels, the conclusion can fail.
Two strategies for the same player are realization-equivalent when they induce the same probability distribution on terminal histories against every fixed opposing strategy profile. The requirement is stronger than having equal expected payoff against one particular opponent. For a finite extensive-form game with perfect recall, Kuhn's theorem gives this equivalence between appropriate mixed strategies and behavioural strategies.
A finite game represented succinctly by propositional logic. Each player controls a disjoint collection of Boolean variables and chooses their truth values. Together those choices determine a Boolean valuation. A player's goal is a propositional formula, with payoff one if satisfied and zero otherwise. The control sets normally form a set partition of all variables.
A pure strategy strategy profile is a Nash equilibrium if every unsatisfied player remains unsatisfied after every change to that player's controlled variables. Checking a candidate can therefore require solving a Boolean satisfiability problem, even though evaluating its current payoffs is easy.
Given a succinct Boolean game and a complete pure strategy strategy profile, determine whether it is a Nash equilibrium. The problem is co-NP-complete for goal propositional formulas, even with one player. This differs from existential equilibrium checking in a Boolean game, which searches for some qualifying Nash equilibrium.
A negative instance has a short complexity certificate: a currently unsatisfied player and new truth values for that player's controlled Boolean variables that make the goal true. Evaluating the current and changed propositional formulas takes polynomial time, proving membership in co-NP.
For hardness, given a propositional formula , let one player control and a fresh variable , with goal . The all-false candidate has payoff zero. It is a Nash equilibrium exactly when is an unsatisfiable Boolean formula, since any satisfying assignment permits an improvement by also setting true. This is a polynomial-time many-one reduction from unsatisfiability. The fresh guard ensures that the candidate loses independently of the input formula's value there.
For nonnegative additive valuations, the requirement that each allocated item be assigned to an agent who values it strictly positively. This condition alone does not require allocating every item.
Let and restrict agent 's constraint domain to subsets of , or to nonempty subsets when required. If , the two bundles are automatically disjoint and each agent values the other's bundle at zero. Both directional envy-free allocation binary constraints are then automatic. Thus positive-support overlaps determine which pairs can still matter in the residual constraint graph.
An allocation of bundles is envy-free if each agent weakly prefers its own bundle to every other agent's bundle, evaluating both through its own value function. With an additive valuation,The reverse comparison uses , so both directions are independent requirements. Ties are permitted. Empty bundles and unallocated items are separate modelling choices, not consequences of envy-freeness.
A bundle-value function for which an agent's value for a set of items is the sum of its item values. Different agents may assign different values to the same item. With nonnegative item values, a bundle containing no positively valued item has value zero. The formula excludes interactions such as a pair of items being valuable only when held together.
Allocation of resources among agents according to a specified fairness requirement. For indivisible items, each bundle is a set of whole items, and a complete allocation assigns every item exactly once. An envy-free allocation is one fairness criterion. Existence depends on the permitted allocations: indivisibility can prevent fairness that would be possible after splitting resources or permitting unallocated items.
Combinatorial game theory studies positions in alternating-move games with fully specified legal moves, usually perfect information and no chance. A position can be defined recursively by the positions available to each player. Under the normal-play convention, a player with no legal move loses.
An impartial game gives both players the same moves; Nim is the standard example. A partizan game allows different moves for Left and Right. The disjunctive sum lets a player move in exactly one component on each turn, making it possible to study how game positions combine algebraically. Infinite play or misère play requires additional conventions; normal-play results do not automatically transfer.
Wythoff's game is an impartial game played with two finite heaps. A move removes any positive number of objects from one heap, or removes the same positive number from both heaps. Under the normal-play convention, the player with no legal move loses.
For example, is losing, while with is winning because one move empties both heaps. The position is losing: its possible moves lead to , , or , each of which can be emptied by the next player. This directly checks a first nontrivial losing position.
The equal-removal diagonal move distinguishes the game from two-heap Nim, where only one heap may change in a turn. A winning strategy is determined by moving to a losing position whenever possible; identifying the complete family of losing positions is a further number-theoretic result.
Misère play is the terminal convention in which the player making the last legal move loses. For finite games without draws, this means a player whose turn begins with no legal move wins. The same move rules with the normal-play convention instead make that player lose.
A one-heap removal game makes the difference immediate. If a single object remains and the only move removes it, the player to move loses under misère play and wins under normal play. With two unit heaps in Nim, the first player removes one heap and forces the other player to take the last object, so the position is misère winning even though its normal-play nim-sum is zero.
Changing the terminal condition changes the recursive winning/losing classification. Normal-play formulas, including unrestricted use of Sprague-Grundy theory, therefore cannot be transferred unchanged. Infinite play requires a separate draw or outcome convention.
An alternating grid-removal game in which choosing an occupied cell removes it and every occupied cell above and to its right. The player who removes the designated lower-left poison cell loses. Reachable occupied-cell sets are order ideals for coordinatewise order. A nonempty reachable position always contains the poison cell, and removing that cell empties the board. The monotone boundary representation of a grid order ideal supports compact board updates.
A partizan game gives the two players, traditionally Left and Right, potentially different legal moves from the same position. Its recursive notation is , listing Left's and Right's options. An impartial game is the special case where those option sets agree at every reachable position.
For example lets Left move to zero while Right has no move. The game reverses the roles, and their disjunctive sum is zero in game value: responding in the other component leaves the previous player winning. Such comparisons concern behavior in sums, rather than simply counting moves available to one player.
A game value lying strictly between and for every positive rational number , in the ordering of partizan games. Infinitesimal values can determine a sum whose numerical part is zero, while they cannot overturn a nonzero integer advantage.
The impartial game , so either player can move to zero. It is equivalent to a Nim heap of size one. It is incomparable with zero, and under the disjunctive sum of games.
The up game is the short partizan game , where is the star game. If Left starts, moving to zero wins. If Right starts, the only move leaves star to Left, who again moves to zero and wins. Thus up is strictly positive in the game ordering.
Its value is nevertheless smaller than every positive real number: it is an infinitesimal combinatorial game. This makes it useful for separating numerical advantage from a tiny advantage that can decide an otherwise balanced disjunctive sum. Reversing the players gives down, .
A partizan game played on a graph attached to the ground. Left removes blue edges and Right removes red edges; after a removal, all edges disconnected from the ground disappear. The player with no legal move loses under the normal-play convention.
A Hackenbush stalk is a Hackenbush position whose graph is a single path attached to the ground at one endpoint. Read its blue and red graph edges upward from the ground; Left may cut blue edges and Right red edges, with every edge above the cut falling away. Finite red-blue stalks are number games with dyadic rational values.
Here is the explicit value rule. Give blue sign and red sign . If the initial monochromatic run has length and sign , it contributes . If more edges remain, edge , of sign , contributes . ThusFor example, a blue-red stalk has value , blue-red-red has value , and blue-blue-red has value . The recursive number game rule verifies the first example directly: its Left option is , its Right option is , and the simplest surreal number between them is . Repeating this comparison after successive cuts gives the dyadic rule.
In combinatorial game theory, a cold game is a position with no gain from taking the next move, as illustrated by number games. For , Left can only lower the value to zero, while Right can only raise it to one; either player would prefer to leave the position untouched if another component offered a useful move.
This contrasts with a hot position such as , where either player benefits from moving first. The distinction matters when choosing which component of a disjunctive sum to play. Exact definitions at zero temperature depend on the adopted cooling convention; a cold numerical component need not be a losing position by itself.
A number game is a recursively defined normal-play partizan game whose options are number games and every left option is smaller than every right option. Its value is the simplest surreal number between those options. Finite number games have dyadic rational values.
A pagoda function assigns a weight to each location in a move puzzle so that the total weight of occupied locations never increases under a legal move. Comparing the initial and desired totals can then prove that the desired position is unreachable.
In peg solitaire, a jump removes pegs at and adds one at . Weights satisfying for every allowed jump make nonincreasing. If a target has larger than the initial board, no move sequence can reach it. Finding suitable weights is the creative step; failure of one chosen weight function does not prove reachability.
A mathematical game specifies participants, available choices, information and consequences of combined choices. A normal-form game records complete strategies and payoffs; an extensive-form game records the sequence of decisions and what each player knows at them.
For example, matching pennies gives each player two actions and opposing payoffs depending on whether their choices agree. Its equilibrium requires mixed strategies. A puzzle with one decision maker is often called a game informally, but strategic interaction and game theory enter when outcomes depend on several decision makers' choices. The rules determine the mathematical object; a physical board alone does not.
Peg solitaire is a one-player finite board puzzle in which a peg jumps over an adjacent peg into an empty hole, and the jumped peg is removed. In a standard orthogonal version, the three holes must lie consecutively in one row or column. Board shape, initial occupied holes and the desired final configuration are part of the problem specification.
Every move decreases the number of pegs by exactly one, so a play starting with pegs has at most moves if at least one peg remains. A solution reducing to a single peg must have exactly moves. This is a counting necessity, not a guarantee of solvability.
The puzzle illustrates state-space search: a position is a subset of occupied holes, and directed edges are legal jumps. Backtracking explores possible continuations, while board symmetries can identify equivalent states. Algebraic invariants and monotone weight functions can prove some target configurations unreachable without enumerating every play.
A two-player game on nine positions arranged in a three-by-three grid. Players alternate marking empty positions and stop when one has a full row, column or diagonal, or when the board is full. A game search must stop at the first win. Distinct move histories can reach the same position; canonical occupancy sets or bitboards make that equality available to memoization. Quotienting by board symmetry changes the requested output unless distinct oriented positions are subsequently restored.
The Tower of Hanoi has three pegs and differently sized discs. Start with all discs stacked largest below smallest on one peg; move one exposed disc at a time, never placing a larger disc on a smaller one, and transfer the stack to another peg.
To move the largest disc, the upper discs must first be collected on the third peg. After its move they must be transferred again. Hence the minimum satisfies , , giving . The recursive construction attains this lower bound. The problem shows how a short recursive procedure can require exponentially many executed moves.
A stochastic game combines a state space with strategic choices and probabilistic state transitions. At each stage, the current state and players' actions determine immediate payoffs and a probability distribution for the next state. A discounted, average-reward or finite-horizon rule specifies how stage rewards are aggregated.
With a single decision maker this reduces to a Markov decision process. With several players, a policy that is best against one fixed opponent may cease to be best when that opponent changes policy. A two-player zero-sum game discounted model leads to a statewise minimax Bellman equation, connecting strategic reasoning with dynamic programming.
A game tree is a rooted tree whose nodes are possible histories of play and whose edges are legal next actions. Internal nodes specify the acting player or a chance move; terminal nodes carry outcomes or payoffs. In an extensive-form game, information sets additionally say which decision histories the acting player can distinguish.
Distinct histories may reach the same board position, so a game tree can contain repeated states that a state graph would merge. For finite two-player zero-sum games with perfect information, minimax search propagates terminal values upward. Chance nodes require expectations instead of maximizing or minimizing their outcomes.
Backward induction with an -component utility vector. At a node controlled by player , evaluate each child, choose a child maximizing coordinate and copy its entire vector. A fixed tie rule makes the returned vector well defined. By mathematical induction from terminal positions, the selected continuation is a best response at every node of a finite perfect-information game, giving a pure strategy subgame perfect equilibrium. The vector must be copied intact; separate coordinatewise maxima need not describe any attainable outcome.
Suppose every terminal pair satisfies . At a B-node with immediate A-parent, let be the A-coordinate of a completed alternative already retained by the parent. If a completed B-child supplies B-coordinate , then every eventual B-selected pair has and hence . Therefore permits discarding this B-option and skipping its remaining children. Equality is also safe if the parent keeps its existing option on a tie.
The inequality remains valid at completed subtrees because max-n search copies one terminal pair. If the observed pair is , then , so and is a weaker sufficient test. At this reduces to the usual MIN-node alpha-beta pruning cutoff. A discarded option is not assigned a fabricated exact pair; the proof uses a certified alternative at the immediate parent.
A game tree node whose successor is chosen according to a specified probability distribution. Its expected utility is a weighted sum of successor values, rather than the maximum or minimum used at a player's decision node.
Backward induction on a finite deterministic game tree of a two-player zero-sum game. Terminal payoffs are propagated by maximization at one player's decision nodes and minimization at the other's. With full information, the resulting choices give an optimal strategy against the opposing player's best response. A cyclic state graph requires a winning condition on infinite plays and a graph algorithm rather than unrestricted recursive unfolding.
Alpha-beta pruning evaluates a minimax search tree while omitting branches that cannot change an already available decision. The parameter bounds what Max can already secure, and bounds what Min can already enforce along the current search path. Once , further children of that node cannot improve the relevant ancestor's choice.
If Max already has an alternative worth five, and a new Min node has a child worth three, that node's value is at most three. Its remaining children can be skipped. Full-depth pruning preserves the root minimax value; applying it to a depth-limited evaluation preserves that truncated value, not necessarily the true game result. Good move ordering makes cutoffs occur sooner.[ref]
https://www.cs.cmu.edu/~15281-f23/coursenotes/search/index.html. CMU 15-281, Search and Games, alpha-beta pruning
The order in which legal child positions are searched. Good move ordering supplies useful alternatives early and increases alpha-beta pruning; poor move ordering can leave the worst-case time complexity of full minimax search unchanged.
The convention that a player unable to move loses. In a finite impartial game without draws, a position is winning exactly when it has a move to a losing position.
An impartial game is a game in which both players have the same legal moves from any given position. Under the normal-play convention, a player with no legal move loses. For finite games without draws, Grundy numbers encode positions for the Sprague-Grundy theorem.
An impartial game played under the normal-play convention.
Sprague-Grundy theory studies finite acyclic impartial games under the normal-play convention by assigning each position a Grundy number. The assignment recursively takes the minimum excludant of the values of all legal followers. The Sprague-Grundy theorem then reduces a disjunctive sum of games to the bitwise exclusive or of its component values. This framework explains both why a zero value is losing and how independently understood games can be combined without exploring the entire product of their state spaces.
Every finite acyclic impartial game under the normal-play convention has a Grundy number. The Grundy number of a sum of independent games is the bitwise exclusive or of their individual Grundy numbers, so the sum is losing exactly when that value is zero.
A subtraction game has a heap of nonnegative integer size. A legal move subtracts an allowed positive amount without making the size negative; normal play declares an empty move set losing.
In a disjunctive sum of games, each move changes exactly one component game. Under normal play, a player loses when no component has a legal move.
Fibonacci Nim is a normal play impartial game on one heap. Start with counters. The first move removes between and counters; thereafter a move removes at least one and at most twice the number just removed by the opponent, without exceeding the remaining heap. Taking the last counter wins.
For a position with counters and permitted maximum , let be the smallest Fibonacci number appearing in the Zeckendorf representation of , using the sequence . The position is losing exactly when . If , removing is a winning move. When this does not empty the heap, the next smallest summand exceeds , so the opponent's new limit is too small. Conversely, the Zeckendorf subtraction lemma gives whenever , so every legal move from a losing position leaves a winning one.[ref]
Fibonacci Nim by Michael J. Whinihan. Pages 9–12: rules, least-summand criterion and proof
Initially , so the losing initial heap sizes are precisely the Fibonacci numbers. For example, : take , leaving the opponent counters and a limit of , a losing position. The move limit is part of the state; heap size alone does not determine later positions.
A Euclid game is an impartial game based on subtraction steps of the Euclidean algorithm.[ref]
A Game Based on the Euclidean Algorithm and a Winning Strategy for It by A. J. Cole and A. J. T. Davie. Original paper introducing Euclid; terminal convention is specified explicitly below
Here use the following normal-play convention: a position is an ordered pair ; if , remove a positive multiple from and reorder. A position with has no legal move and is losing. Thus moving to a zero coordinate wins; variants that instead stop at equal positive coordinates require a different endpoint convention.The sum of the coordinates strictly decreases, so every play terminates. If divides , subtract and win immediately. If , there is only one move, to , so the position has the opposite winning status from that successor.
If with and , two legal choices leave or . The latter has exactly one move, to the former, so exactly one of these two successors is losing. Choose it. For example, is losing because its only move reaches , where the opponent takes the whole larger coordinate. From , subtract to leave that losing position. These cases give a recursive strategy without exploring every subtraction amount.
The value of a game position, where mex is the smallest nonnegative integer missing from the values of its legal successors. Terminal positions have value zero. The Sprague-Grundy theorem explains why these values combine by exclusive or.
For finite nimbers, multiplication is recursively defined from smaller arguments bywhere is Nim-sum and mex selects the smallest missing nonnegative integer. Thus zero times anything is zero and one times is . For , the displayed set is , so .
Together with Nim-sum, this is field arithmetic on finite nimbers, rather than ordinary integer multiplication. In particular cannot be computed by a usual integer product or bitwise exclusive or.[ref]
https://circles.math.ucla.edu/circles/lib/data/Handout-4717-4806.pdf. Aaron Anderson, Nimbers, 3 October 2021, multiplication definition
An impartial game played with heaps of counters: a move removes a positive number of counters from exactly one heap. Under the normal-play convention, a position is losing exactly when the bitwise exclusive or of its heap sizes is zero.
A Nim heap of size contains counters and permits removing any positive number, leaving a heap of any size . Under the normal-play convention, its Grundy number is : the reachable values are exactly , whose mex is .
For several heaps, a turn changes exactly one heap. Their combined value is the Nim-sum of the heap sizes, so heaps of sizes three and three form a losing position even though either heap alone is winning. The ability to remove arbitrarily many counters is part of the rule; a bounded-removal subtraction game has different values.
The bitwise exclusive or of a list of nonnegative integers. For heap sizes in ordinary Nim, a zero nim-sum characterizes a losing position under the normal-play convention.
In a finite impartial game with the normal-play convention and no draws, a losing position is one from which the player whose turn it is cannot force a win against best play. It is also called a P-position, since the previous player wins.
A terminal position is losing. Recursively, a position is winning if it has at least one move to a losing position, and losing if every legal move goes to a winning position. Induction on the finite remaining game tree proves this classification. For a single Nim heap, only the empty heap is losing. Infinite plays and misère play need separate conventions and can change the base case.
Two people can each have a clear incentive to choose an outcome that leaves both worse off. The prisoner's dilemma isolates this tension between individual best responses and Pareto efficiency. For example, two partners can each save effort by withholding a promised contribution, yet both would prefer a successful joint project to mutual withholding. The model applies when each person's payoffs really have the ordering below; the names “cooperate” and “defect” alone do not establish a prisoner's dilemma.
In the symmetric two-player normal-form game, each player chooses cooperation or defection simultaneously, without observing the other's current choice. The four payoffs are the mutual-cooperation reward , mutual-defection punishment , sole-defector temptation , and sole-cooperator payoff , with . Defection is a strictly dominant strategy: it beats cooperation against either opposing pure strategy. This definition and the resulting one-shot Nash equilibrium are discussed in Steven Kuhn, Prisoner's Dilemma, Stanford Encyclopedia of Philosophy, section 1.
Take the concrete payoffs , , , . Each entry below gives the row player's payoff followed by the column player's payoff:
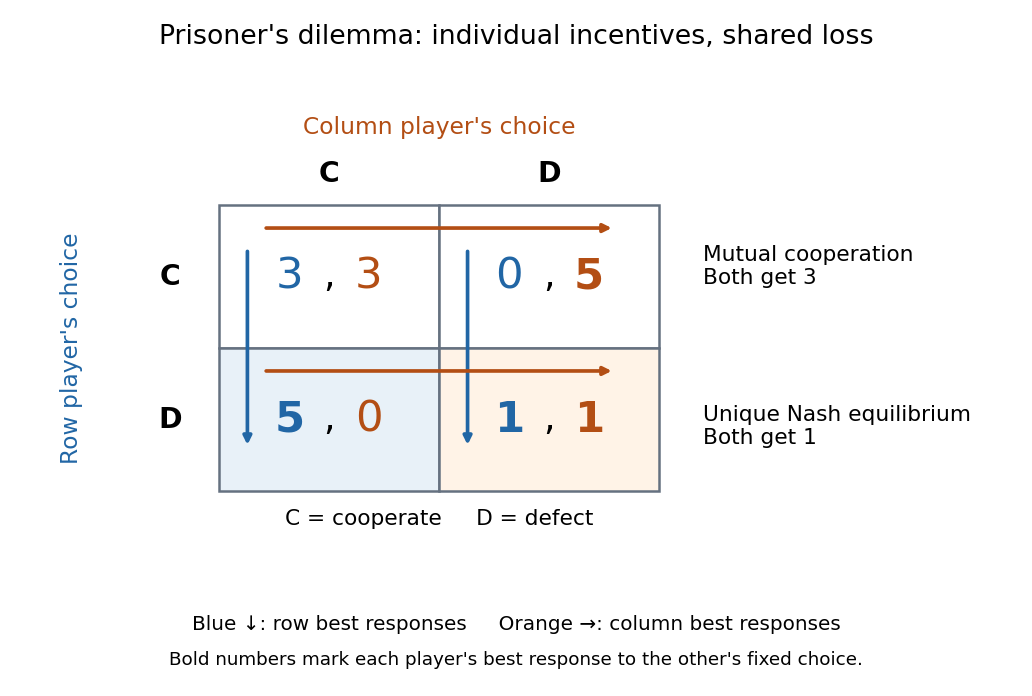
Prisoner's dilemma: best-response arrows lead to mutual defection despite the gains from mutual cooperation
. Details. For the row player, switching from to improves the payoff from to against , and from to against . The column player has the same comparisons, so is a strictly dominant strategy for each. Even against a mixed strategy choosing with probability , the expected payoff advantage is . Thus cooperation cannot appear with positive probability in a best response, and is the unique one-shot Nash equilibrium, including mixed strategies.
At , a unilateral deviation to lowers the deviator's payoff from to . A joint change to instead raises both payoffs from to : mutual cooperation Pareto dominates mutual defection, making the Nash equilibrium fail Pareto efficiency. A Nash equilibrium tests unilateral deviations, so it need not maximize shared gains. This is the useful lesson: improving the available outcome may require changing incentives, rather than telling each participant to choose a better best response.
The additional inequality says that mutual cooperation gives each player at least as much average payoff as equal-time alternation between the two asymmetric outcomes. It is a further assumption, not a consequence of . Here it holds strictly: , and alternating exploitation gives each player average payoff . This comparison concerns equal-time averages, not every discounted sequence. See Kuhn, section 3, on the additional cardinal-payoff condition.
A social game in which cooperation costs its actor and benefits its partner by , with . Mutual cooperation yields to each, unilateral defection yields to the defector and to the cooperator, and mutual defection yields zero.
The iterated prisoner's dilemma is a repeated game with a prisoner's dilemma at each round. Earlier choices can change later best responses: a present gain from defection may be outweighed by lost future cooperation. A pure strategy now specifies an action after every possible observed history, including histories that its own prescribed play would never reach. The horizon, observations, initial actions, and payoff convention must be specified before assessing a Nash equilibrium or subgame perfect equilibrium.
For the following worked example, repeat the prisoner's dilemma above infinitely at rounds . Assume public perfect monitoring: after each round both players observe both actions exactly, without error. They share a discount factor and evaluate a path of stage payoffs using the normalized discounted payoffThe round-zero weight is one before normalization, including when . A larger discount factor gives future payoffs more weight; the geometric series makes a constant stage payoff have the same normalized value. These assumptions and normalization follow [ref]
https://ocw.mit.edu/courses/6-254-game-theory-with-engineering-applications-spring-2010/5a158a7558165d0e22b5b27fcfa01713_MIT6_254S10_lec15.pdf. Asu Ozdaglar, MIT 6.254, lecture 15, slides 6–15
. The numerical payoffs here are our example; the lecture uses a different table.Suppose both players use grim trigger: play initially and while every past action of both players was ; after any observed , play forever. With no unilateral deviation, each gets normalized payoff . A first unilateral deviation to earns now, then at most each round because the opponent switches permanently to always defect. The deviator attains that continuation payoff by choosing thereafter. At any history of mutual cooperation, the comparison is thereforeCooperation is a best response precisely whenEquivalently, without normalization the geometric series givesMultiplying both unnormalized payoffs by the same positive factor leaves the best response comparison unchanged.
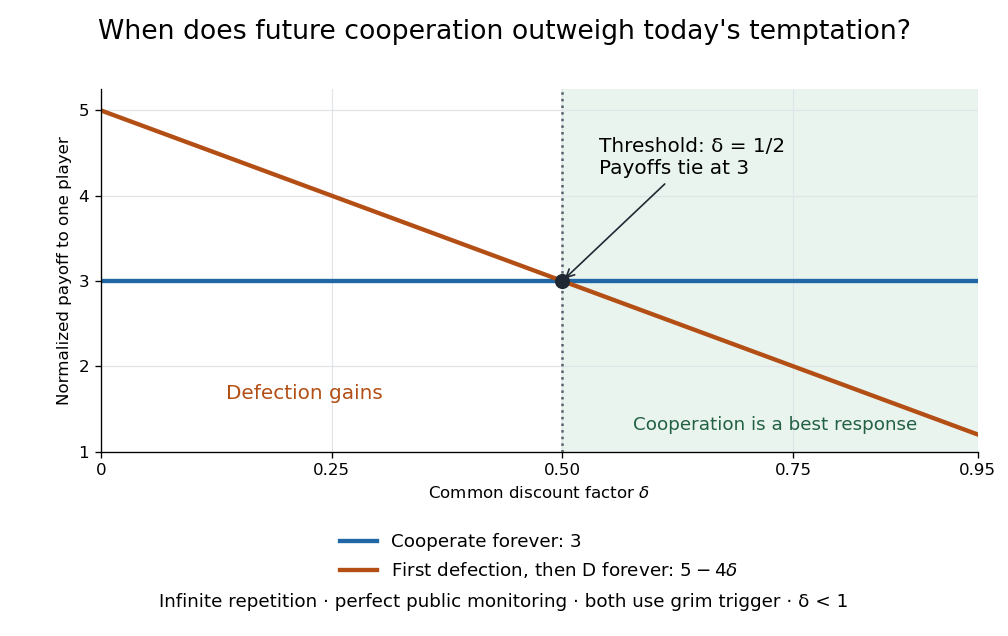
Repeated prisoner's dilemma: normalized cooperation and first-deviation payoffs cross at discount factor one half
. Details. For example, with discount factor , the first unilateral deviation gives normalized payoff , so mutual grim trigger is not a Nash equilibrium. At , it gives , so cooperation is preferable. At the two payoffs tie: the incentive to cooperate is weak, which is sufficient for a subgame perfect equilibrium.
The punishment is credible after every history containing a defection: the opponent's pure strategy then prescribes forever, and remains the stage best response, earning rather than . Together with the cooperative-history comparison, this establishes mutual grim trigger as a subgame perfect equilibrium for . Delaying the first unilateral deviation merely delays the same gain or loss; further cooperation during punishment only lowers the deviator's payoff. Mutual always defect also remains a subgame perfect equilibrium, so patience permits cooperation without making it inevitable.
This calculation assumes an infinite horizon and ; it does not define a discounted payoff at . With a finite, commonly known final round and positive weight on each round, backward induction instead gives mutual defection in every round of this stage game. Observational errors change the model too: one mistaken defection permanently activates grim trigger. Historical dependence, initial memories, and the payoff time convention also affect whether a cooperative rule resists or invades other pure strategies; the existing reactive strategy and Tit for tat discussions concern those additional questions.
A grim trigger is a history-dependent pure strategy in a repeated game that switches permanently to punishment after a trigger event. In the iterated prisoner's dilemma above, the trigger is any player's observed defection, and punishment is always defect. Unlike Tit for tat, grim trigger never restores cooperation after the opponent cooperates again. Whether mutual grim trigger is a subgame perfect equilibrium depends on the stage payoffs, discount factor, and monitoring assumptions; it is not an unconditional property of the rule. See Ozdaglar, lecture 15, slides 12–15.
A reactive strategy cooperates with probability after the opponent cooperated and probability after the opponent defected. It ignores its own previous action. Independent behavioural randomization gives a four-state joint-action Markov chain. The reduced marginal recurrences depend on the prescribed initial action distribution.
Tit for tat cooperates initially and then repeats the opponent's previous action. Two such players cooperate forever without mistakes under this initial convention. It retaliates against defection and returns to cooperation after the opponent cooperates.
In a symmetric two-action stage game write for mutual cooperation, mutual defection, sole defection and sole cooperation payoffs. Suppose , and . Against an initially cooperative Tit for tat, every action sequence has limiting upper average payoff at most .
For a deviator's actions , put , and . The opponent at time plays . Check the four transitions: to and to satisfywith equality; to uses , and to uses . A telescoping sum gives the displayed finite-horizon bound. Divide by the horizon and let it increase. Mutual Tit for tat yields every round, so it is a Nash equilibrium under the long-run average payoff criterion. The argument is pathwise and therefore covers arbitrary deviations representable by finite-state machines, as well as action sequences outside that class.
For a reactive resident with , let and . Its self-payoff and both ordered cross-payoffs against Tit for tat equal . At introduced Tit for tat frequency , its fitness difference is therefore the displayed expression. If , it is positive for because . Fully cooperative reached histories tie; the deterministic opposite-response strategy needs a separate cycle calculation. Initial advantage is order frequency rather than a positive invasion exponent at zero.
In an -round iterated prisoner's dilemma, Tit for tat against always defect gets once and thereafter; the defector gets once and thereafter. Their self-payoffs are . At introduced frequency , subtracting mixed-population payoffs gives . The displayed positive threshold applies when its denominator is positive and the threshold is less than one. Taking first removes this finite entry cost, so the horizon and rare-mutant limits cannot be casually interchanged.
Under cooperative initial memories, matches involving only Tit for tat and always cooperate contain only cooperation, so all four payoffs equal . The two-condition criterion for evolutionary stability has both differences zero. Thus Tit for tat is not an evolutionarily stable strategy against a strategy space containing unconditional cooperation, even if it is a Nash equilibrium. This counterexample is valid for finite horizons and discounting as well as infinite averages.
With initially independent actions, same-round independence is preserved by reactive updates: each next action uses the other independent previous action and fresh independent randomization. Marginal cooperation follows , . If the product of response slopes has modulus below one, these recurrences converge and the joint distribution is their product. Averaging over that distribution gives the long-time payoffs. At deterministic response slopes of modulus one, initial-memory-specific cycles must instead be averaged directly.
Evolutionary game theory studies how a population's composition changes when the success of a pure strategy depends on which other pure strategies it encounters. The central feedback is a frequency-dependent payoff: becoming common changes the opponents a strategy meets, which can change whether it does well. In a coordination game, common behaviour can reinforce itself; in the coexistence example below, being rare is an advantage. This makes evolutionary game theory useful for asking which behaviours can persist and which initial compositions lead to different outcomes, without assuming that each participant solves an optimization problem.
In the basic model, a large, well-mixed population has finitely many inherited pure strategies; interactions sample opponents according to their population frequencies. Assume that a strategy's expected payoff determines its per capita net reproductive growth rate, with a common baseline allowed. These are modelling assumptions: reproduction must transmit the strategy, encounters must match the proposed sampling rule, and the conversion from payoff to growth must be justified for an application. The replicator equation below describes the resulting continuous-time frequencies. Taylor and Jonker's [ref]
https://static1.squarespace.com/static/5dc9917c4cdb1467e1e54c4c/t/6526a5647942e33b89ab7af1/1697031525653/1978%2Bevolutionarily%2Bstable%2Bstrategies%2Band%2Bgame%2Bdynamics.pdf. Evolutionarily Stable Strategies and Game Dynamics (1978), section 3, pp. 148–149
explicitly derive this growth model.For learned behaviour, reproduction can instead be replaced by an assumed copying rule: an individual samples another individual uniformly and copies a better-performing pure strategy at a rate proportional to the positive payoff difference. At frequencies , the net flow from to is , because the two directional positive parts subtract to . Summing over gives , the replicator equation. This derivation states a particular mechanism; an arbitrary rule for learning or imitation need not give the same dynamical system.
Three questions must be distinguished. A symmetric Nash equilibrium tests whether an individual can improve its expected payoff against the resident composition. An evolutionarily stable strategy tests whether each distinct rare mutant is outperformed after it is introduced. Dynamical stability tests the response of an actual dynamical system to small changes of composition, and asymptotic stability additionally requires nearby trajectories to converge. For a finite symmetric bimatrix game under the continuous-time replicator equation, every evolutionarily stable strategy is a symmetric Nash equilibrium and a locally asymptotically stable rest point; the converse from asymptotic stability to an evolutionarily stable strategy fails in general. See Ross Cressman and Yi Tao, The replicator equation and other game dynamics (2014), Theorems 1–2 and Example 1. These statements refer to stability on the full probability simplex, including perturbations introducing currently absent pure strategies.
A concrete experiment makes the frequency feedback visible. In 2009, Gore, Youk and van Oudenaarden competed two yeast strains: a producer of the enzyme invertase, which enables sucrose hydrolysis, and a mutant lacking the corresponding SUC2 gene. Released sugars can feed neighbours, so avoiding production can be advantageous. They used shaken 5 mL cultures with 5% sucrose at , diluted daily after 23 hours of growth. Different labelled proteins allowed the two strains to be counted separately by flow cytometry; selective plating periodically checked the counts. The cooperator required externally supplied histidine, so restricting that amino acid imposed an adjustable growth disadvantage. See Snowdrift game dynamics and facultative cheating in yeast, pp. 253 and 255–256, Methods Summary.
Starting with rare producers and, separately, rare nonproducers tested both invasion directions. Under the reported coexistence conditions each rare strain increased; changing histidine or added glucose shifted the eventual composition. Their explanation used nonlinear growth benefits, rather than a fixed pairwise payoff matrix. This motivates testing both rarity regimes before inferring an evolutionarily stable strategy or fitting a replicator equation; it does not identify the illustrative tables below with measured payoffs. See Gore, Youk and van Oudenaarden, Figures 1–3.
An early motivation was understanding why animal contests can involve restraint even when escalation might win an individual encounter. Maynard Smith and Price's [ref]
https://public.ek-cer.hu/~szabo/EGT20/library/maynard_n73.pdf. The Logic of Animal Conflict (1973), Nature 246, 15–18
introduced the evolutionarily stable strategy in this setting. Taylor and Jonker's [ref] then studied explicit continuous and discrete dynamics. Static resistance to invasion and the paths populations follow are related questions, but they require separate definitions.A signalling equilibrium is a stable pattern of signal production and response in a game where one participant has information another lacks. A sender's strategy selects a signal according to its type; the receiver's strategy chooses a response after observing that signal. Equilibrium requires both choices to be best responses under consistent beliefs or a specified evolutionary stability criterion.
A separating pattern uses different signals for different types, while a pooling pattern uses the same signal. A costly signal can support separation only if each type prefers its assigned signal and response to mimicking another type. In evolutionary game theory, stability concerns resistance to invading strategies; it is a stronger, separately specified condition than merely observing a correlation between signals and types.
A conditional strategy prescribes actions according to specified observations, states, or histories. The conditioning information must be available to the player when the action is chosen; the rule does not require conscious calculation.
In an iterated prisoner's dilemma, Tit for tat conditions on the opponent's previous action, whereas a grim trigger strategy remembers whether any defection has occurred. Both can choose the same action in the first round and then respond differently to the same most recent move because their retained histories differ. A finite-state strategy records the relevant past information in an automaton state. In an extensive-form game, the prescription must be constant across an information set, since its nodes cannot be distinguished when choosing an action.
The replicator equation says that a strategy grows in frequency when its expected payoff exceeds the population's current mean payoff. It is an ordinary differential equation for a composition, rather than for total population size. The subtraction of the mean is what makes relative success matter: even a type growing in absolute number can shrink as a fraction if other types grow faster.
Let be the frequency of pure strategy , with available pure strategies andIn a symmetric bimatrix game, let the payoff matrix have entry equal to the payoff to strategy against . The other player's payoff in that encounter is : symmetry between player roles does not require . Uniform random encounters give the expected payoffs and their population meanAfter choosing the time unit so that the growth-rate scale is one, the continuous-time replicator equation isHere a payoff is measured on a scale proportional to net growth per unit time, not merely as an arbitrary preference ranking. More generally one can specify locally Lipschitz frequency-dependent payoffs directly; the same equation with then defines a unique frequency trajectory. The linear pairwise model and its reproductive interpretation are given in Taylor and Jonker (1978), sections 2–3; the formulas here also follow by the following direct normalization.
Suppose the number of type obeys , where the baseline is identical for all types. Set and . The quotient rule givesThus the common baseline cancels. Adding the same constant to every entry of leaves the replicator equation unchanged; multiplying by a positive constant changes only the speed along trajectories. The same payoff matrix can therefore describe frequency evolution at different growth-rate baselines and time scales.
The probability simplex is invariant in forward time. On ,Normalization alone would not exclude negative frequencies. Nonnegativity follows as well: along a solution,An absent type remains absent, and a positive frequency remains positive at every finite time. For the fixed payoff matrix model, bounded rates on the compact probability simplex give global forward solutions. Frequencies can still tend to zero as . Each face is invariant, so this model has no spontaneous introduction of new pure strategies; mutation or outside introductions would require additional terms. For two present types the logarithm of their frequency ratio satisfies , directly expressing the accumulated payoff advantage.
For two pure strategies, write the composition as , where is the frequency of strategy 1, and letTheir payoff difference and the resulting scalar ordinary differential equation areIn the interior , the sign of the payoff difference determines the direction of motion. The endpoints are always equilibrium points, and an additional interior equilibrium point exists precisely when the affine payoff difference has a zero strictly between them. At a simple interior zero , : a negative value gives asymptotic stability, a positive value gives instability. At the endpoints and , with stability understood relative to . A zero derivative requires examining the actual flow rather than this strict sign test.
For an original coordination game, imagine two conventions that reward matching, with convention 1 giving the larger matching reward. ChooseThe crossing is . Below it, convention 1 loses frequency; above it, convention 1 gains frequency. The endpoint equilibrium points and have one-sided asymptotic stability, while is unstable: the corresponding derivatives are and , respectively. Every initial tends to , every initial tends to , and exactly stays there. Even the convention with the larger matching reward can disappear if it starts below the threshold. This is bistability, not selection of a universally best convention.
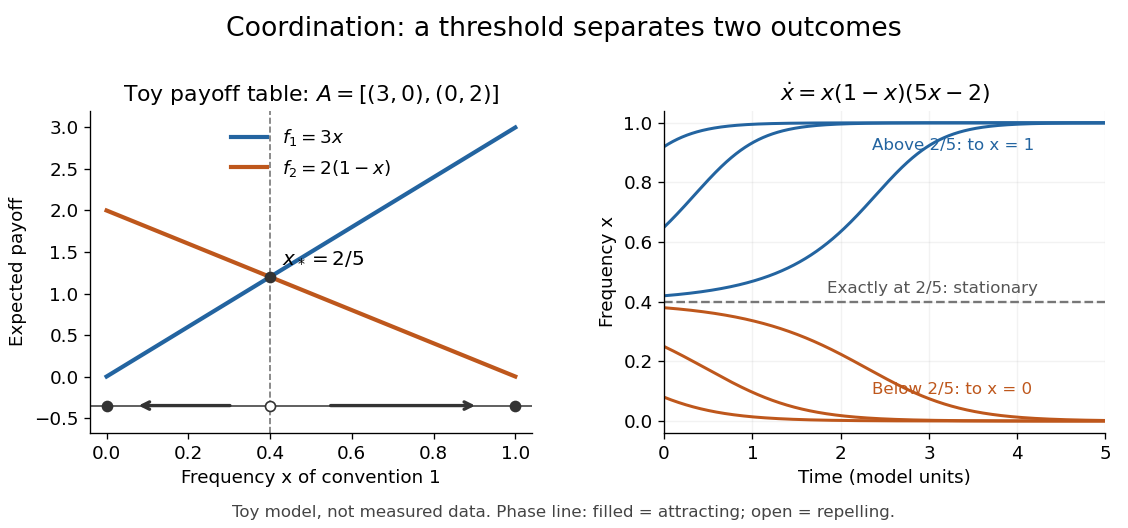
Toy coordination model: an unstable frequency threshold separates attraction to the two pure conventions
. Details. The compositions giving a symmetric Nash equilibrium in this coordination game are the two pure conventions and the mixed composition . Both pure conventions are evolutionarily stable strategies because a mutant convention has strictly lower payoff against the pure resident. The mixed symmetric Nash equilibrium is not an evolutionarily stable strategy: against that resident both conventions tie, but after a pure convention-1 mutant is introduced its payoff advantage is . Equal payoffs at a symmetric Nash equilibrium need not provide resistance to invasion or asymptotic stability.
For an original coexistence model, choose payoffs making each convention advantageous when sufficiently rare:Here attracts every initial composition with both types present: below it and above it. The interior derivative is , while and make both endpoints unstable to introduction of the other type. The endpoints nevertheless remain stationary if the other type is exactly absent; the attraction statement excludes those boundary initial states.
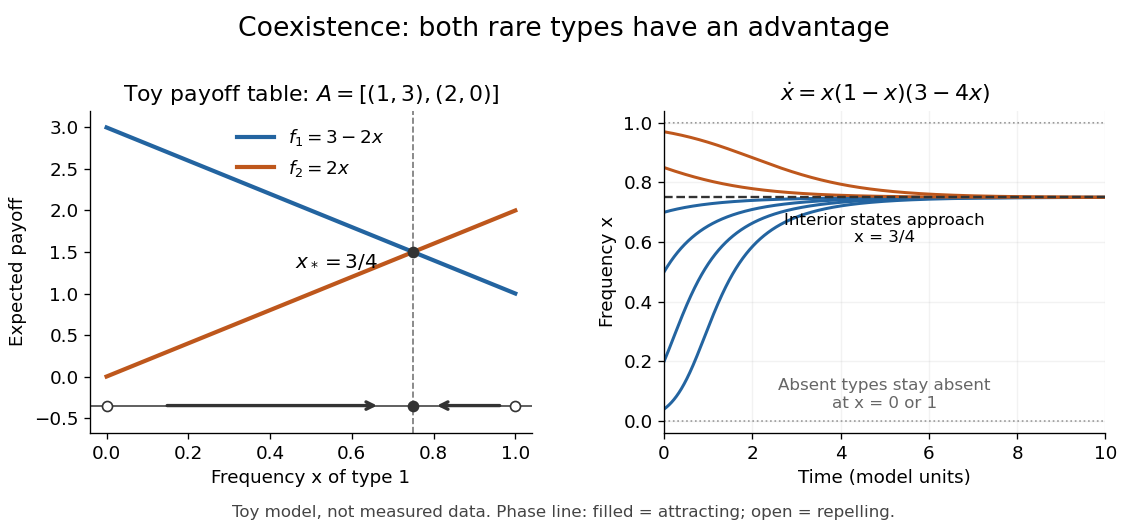
Toy coexistence model: both rare types can invade, and every interior composition approaches frequency three quarters
. Details. The sole symmetric Nash equilibrium in this coexistence model is . It is also an evolutionarily stable strategy. For any different mixed strategy , the first comparison in the two-condition criterion for evolutionary stability ties because . Its second comparison is strictly positive:Thus restoring frequency feedback can protect a mixture even though all present types earn equal payoffs at the mixture. Coexistence here means different individuals using different pure strategies; it does not require every individual to randomize with a mixed strategy.
Frequency evolution need not increase the mean payoff. In the coexistence example , whose maximum occurs at , whereas the attracting composition is . For , the frequency increases while . Individual payoff advantages drive the equation; maximizing collective mean payoff is a different optimization problem.
More generally, a rest point only equalizes payoffs among present types: implies . A symmetric Nash equilibrium additionally requires for every absent type. All vertices are rest points even when an absent type could invade. For finite symmetric bimatrix games, a rest point with Lyapunov stability on the full probability simplex is a symmetric Nash equilibrium; an interior trajectory that converges has a symmetric Nash equilibrium as its limit. These are conditional results, not a convergence theorem for every trajectory. See Cressman and Tao (2014), Theorem 1.
The rock paper scissors payoff matrix gives an explicit obstruction to universal convergence:Since , , and in the interior . Thus is conserved. Its maximum on the probability simplex occurs only at , the unique symmetric Nash equilibrium, so an interior trajectory starting elsewhere cannot converge to that composition. Every other interior product level is a closed curve without a rest point, giving a periodic orbit. The existence of these cycles is also discussed in Cressman and Tao (2014), Example 1. The useful lesson is to inspect the specified payoff feedback and dynamical system, rather than infer convergence from the existence of an evolutionarily stable strategy or a Nash equilibrium.
A frequency-dependent payoff is an expected payoff depending on the population composition . Under random pairwise encounters with a fixed payoff matrix it is the linear function . The relative advantage can change sign as opponents become more or less common. The replicator equation converts this feedback into changes of frequency; nonlinear frequency-dependent payoffs allow interactions not represented by a fixed pairwise table.
A repeated game plays a stage game over several rounds, allowing actions to depend on earlier observations. Its payoff convention must specify a finite horizon, a discount factor or a long-time average; these need not have identical invasion properties.
A history-dependent pure strategy represented by a finite-state machine with an initial automaton state, an action output for each state, and an automaton transition after each observed completed joint action. A grim trigger strategy uses a following state and an absorbing punishment state. Two such deterministic machines jointly form a finite deterministic state system, so their action path is eventually periodic. Its long-run average payoffs are the averages over the eventual cycle; a finite initial prefix has vanishing weight.
The normal-form game played once in each round of a repeated game. Its actions and payoffs are distinct from the repeated interaction's history-dependent pure strategies and aggregate payoffs. The same stage game can produce different incentive constraints under a finite sum, discounting or long-run average payoff criterion.
A family of results describing the large set of Nash equilibrium payoffs available in indefinitely repeated interaction. For a finite game with observed past play, the discounted Nash version supports any feasible, strictly individually rational payoff in a repeated game when players are sufficiently patient.[ref]
Lecture 15: Repeated Games by Asu Ozdaglar. Slide 24, Nash folk theorem; slides 25–27, permanent minmax punishments and the distinction from subgame perfection
The mechanism is to prescribe a path and punish the first deviator by holding that player's future payoff to its minmax payoff. With long-run average payoffs, a finite gain disappears from the average; with discounting, the promised future loss must outweigh the gain. Weak boundary points require care when a stated theorem assumes strict inequalities. A construction proving a Nash equilibrium need not prove a subgame perfect equilibrium, because the punishers' continuation incentives may fail.
A payoff vector in a repeated game is individually rational when it gives every player at least that player's minmax payoff. It is strictly individually rational when every inequality is strict. These comparisons use each player's own payoff scale.
For a two-player finite stage game, the minimax theorem identifies this bound with the player's maximum guaranteed expected payoff. For example, in a prisoner's dilemma with , defection guarantees , and the cooperative payoff vector is strictly individually rational. This does not by itself prove that cooperation is an equilibrium under any specified horizon or monitoring rule.
With several opponents, the permitted correlation in their punishment strategies matters: a minmax over independent opposing mixed strategies need not equal the player's maximin guarantee against a coordinated coalition. Therefore one must state the repeated-game information and punishment conventions before interpreting the bound as an enforceable guarantee. This use is distinct from the participation constraints called individual rationality in mechanism design.
The lowest expected payoff to which a player's opponents can hold that player when the player chooses a best response. The opponents' permitted randomization and correlation conventions should be specified for games with several opponents. In a two-player finite game, this equals the player's maximum guaranteed expected payoff by the minimax theorem applied to that player's payoff matrix. This equality does not make the original two-player game a zero-sum game.
The convex hull of the stage game's attainable payoff vectors. Public randomization or deterministic sequences with prescribed limiting frequencies produce such average payoffs. It can be larger than the set attainable using independent mixed strategies in a single stage.
A repeated game criterion evaluating the average stage payoff over increasingly long horizons. State how paths without a limit are treated, for example by using a lower limit. Changing a finite prefix does not change a convergent long-run average payoff. Thus a one-time gain can be outweighed by permanent future punishment without specifying a discount factor.
A payoff is the number assigned to a player's outcome at a strategy profile, with larger numbers preferred. In the usual expected utility model, expected payoffs are probability-weighted averages of these numbers. If a payoff is specified as money and a player has preferences involving risk, first apply the relevant utility function; maximizing expected money assumes risk neutrality. In a two-player zero-sum game, one player's payoff is the negative of the other's. General bimatrix games instead require a payoff matrix for each player.
For a finite game, let range over all pure strategy strategy profiles, and let be player 's probability of choosing . Under independent mixed strategies, the probability of is . The displayed sum is the expected value of player 's payoff. Holding everyone else's mixed strategy fixed makes a linear function of ; this is why checking pure strategy deviations suffices to check all mixed strategy deviations.
Each voter chooses whether to incur a voting cost. The collective result changes each voter's payoff, and abstention can be optimal when other voters are likely to determine the outcome. The payoff difference between voting and abstaining is the benefit of being pivotal, weighted by the pivotal probability, minus the turnout cost.
// Target: mathematical-optimization.bigb
Suppose turnout costs , each supporter gains on passage, and the opponent loses . The symmetric-supporter Nash equilibria are and . Allowing different supporter probabilities adds and . These follow by comparing the pivotal voting probabilities with the turnout cost; no player benefits by changing their mixed strategy.
// Target: mathematical-optimization.bigb
A voter is pivotal when changing only that voter's participation changes the election result. For an opponent facing two independent supporters with participation probabilities , under a rule requiring strictly more votes in favour, the opponent is pivotal when exactly one supporter votes. This probability is .
// Target: mathematical-optimization.bigb
In a nonatomic congestion game, a divisible population chooses resources whose costs depend on aggregate usage. Each individual has negligible size, so changing their choice does not alter those costs. For traffic on a flow network, strategies are routes and an equilibrium is a Wardrop equilibrium: every route with positive flow has minimum delay for its source-sink pair. This differs from a finite-player congestion game, where a deviation changes the load used to evaluate the deviator's new cost. Continuous nondecreasing link delays give a Beckmann potential whose minimizers are exactly the traffic equilibria.
Articles were limited to the first 100 out of 343 total.
Articles by others on the same topic

Game theory is a mathematical framework used for analyzing situations in which multiple players make decisions that affect one another's outcomes. It provides tools to model and predict the behavior of individuals or groups when they are confronted with competitive or cooperative situations. Key concepts in game theory include: 1. **Players**: The decision-makers in the game, which can be individuals, groups, or organizations. 2. **Strategies**: The plans of action or choices available to the players.



As mentioned at Human Compatible by Stuart J. Russell (2019), game theory can be seen as the part of artificial intelligence that deas with scenarios where multiple intelligent agents are involved.