The term Markov chain commonly denotes a Markov process on a finite or countable state space. Time may be discrete, as for a daily record, or continuous, as for a continuous-time Markov chain. Some authors also use “Markov chain” for discrete-time processes on more general state spaces; specifying both time and state space avoids this ambiguity.
For a Discrete-time Markov chain, its initial probability distribution and transition matrix specify the probability of each finite path:This is the Markov factorization, obtained by applying conditional probability repeatedly. See Hao Wu's MIT lecture 1, definition and distribution evolution.
For the constructed sunny/rainy Markov chain below, starting sunny makes the path sunny, rainy, sunny have probability . Starting instead with stationary distribution makes that path's probability . The transition probabilities are identical in both experiments; the initial probability distribution distinguishes them.
A two-phase inspection model alternates between inspecting every item and inspecting each item with probability , where . Suppose item defects are independent with probability . The first phase ends after good items have been accumulated, while the second ends upon detecting a defect. With state equal to the cumulative number of good items found during the current full-inspection phase, the Markov chain has transitions , , , .
Its stationary distribution is for and . Indeed, balance gives equal mass to every phase-A state and ; normalization fixes the common mass. The finite chain is irreducible and aperiodic, so the Markov chain ergodic theorem identifies these probabilities with long-run occupation fractions. The long-run inspected fraction is . The fraction of all production consisting of undetected defective items is .
An important modeling choice is whether defects during full inspection preserve accumulated good items or reset the count. Resetting produces the distinct consecutive-clearance inspection model and changes the long-run fractions.
In the consecutive-clearance inspection model, a run of consecutive good items is required to leave full inspection. With , , its Markov chain has transitions , for , and , . Thus every defect in the clearance phase resets the count, rather than preserving the cumulative total.
Writing , the stationary distribution isTo prove this, balance at gives , while balance at gives . Summing the geometric series and normalizing gives ; balance at zero follows as well. The inspected fraction is . The fraction of all production that is both defective and uninspected is ; the fraction among defective items alone is . All these long-run limits follow from the Markov chain ergodic theorem and the independent inspection coins. The distinction from cumulative clearance matters already at .
Fix . The immigration chain with complete population resets has states : from zero it moves to one, and from a positive state it moves to zero with Probability or to with Probability . Its Stationary distribution isStationarity gives and for . Summing the geometric tail yields total mass , giving the normalization.
Every state communicates with zero, and a return from zero takes one initial step plus a positive-support geometric waiting time of mean . Thus the chain is irreducible and positive recurrent. Return lengths two and three have positive Probability, making it aperiodic. The ergodic occupation fraction above a positive integer is the stationary tail .
The endpoint cases have different behavior. At , the closed class alternates deterministically and is periodic; the full countable chain is not irreducible. At , the chain increases forever and the displayed zero weights do not normalize. The strict parameter interval is therefore needed for the irreducibility and aperiodicity claims.
On the finite path , take interior neighbor probabilities , endpoint inward Probability , and holding Probability , with . Detailed balance gives the displayed invariant distribution: endpoint weights are half the interior weights. For the chain is irreducible and aperiodic, so transition probabilities converge to it. At parity alternates and the period is two.
Let be a time-homogeneous Markov chain with transition matrix , and let be a positive integer. Then is a Markov chain with transition matrix and the same initial distribution. The Markov property and the Chapman-Kolmogorov equation give . Conditioning again on the smaller history leaves the right-hand side unchanged, since it is determined by . This proves the Markov property of the sampled sequence, rather than only identifying its marginal transition probabilities. Periodicity of the original chain may split the sampled chain into several closed classes.
The empirical occupation proportion is the fraction of the observed Markov chain states equal to . These nonnegative fractions sum to one. To simulate them from a transition matrix, sample an initial state and then draw each successive state from the current state's row, accumulating visit counts. They are empirical frequencies for a finite path, whether or not the chain is already stationary. Long-run convergence to a Stationary distribution requires the corresponding recurrence and irreducibility hypotheses.
A finite stock decreases by choosing a uniformly random positive number of its remaining items at every step. The remaining stock is a Markov chain with for and . State is an absorbing state, and every positive state is a transient state. If denotes the expected number of positive-stock steps before absorption, a first-step decomposition gives and . Subtracting consecutive equations yields , so , the th harmonic number.
Refill the stock to a fixed positive size immediately whenever a step empties it. The resulting Markov chain has state space and transitions for and . It is irreducible and aperiodic, since every state reaches , reaches every state, and . Its unique stationary distribution is and for . Normalization is the harmonic number identity. For , stationarity follows from ; the same telescoping sum starting at gives stationarity at . The finite-state convergence theorem therefore makes this stationary distribution the limiting distribution from every initial state.
Let be independent and identically distributed random variables, independent of an initial state , and let be a measurable function. The displayed recursion defines a time-homogeneous Markov chain: conditioning on the state history leaves with its original probability distribution, so its next-state law depends only on . Its Markov kernel is . Running sums use ; running maxima use . independence from the complete past, rather than merely from the current state, supplies the Markov property.
For a time-homogeneous Markov chain started at , condition on a return to at a fixed later time , assuming that event has positive Probability. The Markov property factors the Probability of a visit to at time and a later return into the two transition probabilities in the numerator. Conditional probability then gives the formula. At the midpoint with and , it reduces to , where . If for , this midpoint return Probability tends to even when unconditional returns tend to zero.
An irreducible Markov chain is transient when its states are transient states. Starting at any one state, there is a positive Probability of never returning, and the number of visits to any fixed state is finite almost surely.
A model of random exchange between two containers, associated with Paul Ehrenfest and Tatyana Afanasyeva-Ehrenfest. In the discrete-time Ehrenfest urn model, choose one of balls uniformly at each step and change its container. The count in the first container decreases with probability and increases with probability . A continuous-time version lets each particle change container independently at rate , giving birth-death process transition rates and . Its sequence of visited states is the discrete urn Markov chain. Stopping when one container becomes empty produces an absorbing variant, rather than changing the transition rule of the unstopped model.
The Ehrenfest urn model moves one uniformly chosen ball between two boxes at each step. For balls, the count in one box is a Markov chain on . Its stationary distribution is , and detailed balance makes it a reversible Markov chain. The chain has period two, but its mean recurrence time to the all-in-one-box state is still .
Stop the four-ball Ehrenfest urn model upon reaching count zero or four. From count , the transitions are to with Probability and to with Probability . First-step analysis with absorbing boundary values gives the displayed vector of probabilities of absorption at zero and vector of expected hitting times of either endpoint. For instance, and , with , give . From any interior state, absorption has Probability at least within two steps; the resulting geometric tail bound proves both almost-sure absorption and finiteness of the expectations.
Suppose motion within each level ends on hitting one of two boundaries, and each boundary transition resets the process to a fixed entry state of an adjacent level. Observe only the successive level exits. The resulting level process is a Markov chain, with transition probabilities equal to the within-level boundary-hitting probabilities. The fixed-entry condition matters: without it, retaining only the level may discard information needed for the next transition law.
For a simple symmetric random walk on local rooms , starting each excursion at room , the gambler's ruin probability of reaching first is . Thus the level chain moves up with probability and down with probability . Independent future decisions, or more generally the Strong Markov property, justify restarting this calculation after each exit.
For two active levels between absorbing levels and , starting on level , put and . The success probabilities satisfy and , henceFor , the result is . This compression illustrates how unbiased microscopic choices can produce a biased coarse random walk when entry points are close to one boundary.
In the Bernoulli-Laplace diffusion model, two urns each contain balls, with red and blue balls in total. Independently choose one ball uniformly from each urn and exchange them. The red count in the first urn is a Markov chain on , withThe upward event exchanges a blue ball from the first urn with a red ball from the second; the downward event reverses the colors. HenceStarting from , the mean is , with the initial value understood separately if the geometric factor is zero. For , this mean tends to . For , however, the only two configurations alternate and the expected imbalance does not decay.
The Stationary distribution is the hypergeometric distributionIt counts uniformly allocated red/blue configurations. The ratio verifies Detailed balance with the displayed transitions. The chain is irreducible; for an interior holding Probability also makes it aperiodic, while the chain has period two. This model separates convergence of an average imbalance from the full probability law and its periodicity.
A possible value of a Markov chain at one time. The collection of such values is its state space. A pair of molecule counts is one Markov chain state when two chemical species are tracked together.
On a finite state space, an acyclic Markov chain has no directed cycle among its nonabsorbing states. Order those states topologically by their possible transitions. Hitting probabilities and expected absorption times can then be calculated in reverse order, because a state's equations involve only later states.
For example, let go to or to an Absorbing state with equal probabilities, and let go directly to . The expected absorption times are , and . This is dynamic programming on the transition graph, rather than a general simultaneous linear solve.
If a convention permits self-transitions while forbidding cycles between distinct nonabsorbing states, the holding probabilities must be retained. Provided , the same backward calculation usesA self-loop at of Probability , with probabilities each to , gives instead of . The finite-state assumption is substantive: an infinite deterministic chain is acyclic but has no terminal Absorbing state and no finite reverse recursion of this kind.
A Markov chain with at least one absorbing state, such that from each state an absorbing state can be reached. In a finite such chain, absorption occurs with probability 1. Expected times to absorption satisfy a linear system obtained by conditioning on the first transition.
A harmonic function assigns a value to each state of a Markov chain such that one transition leaves its expected value unchanged. This turns a question about many possible future sample paths, such as which endpoint is reached first, into a local averaging rule. For a transition matrix , a real-valued function is harmonic at state whenHere means expected value conditional on starting at ; on a countable state space the sum must be absolutely convergent. If this holds at every state, write . At an absorbing state the equation is automatic, so prescribed boundary conditions supply information that the averaging rule cannot.
For a finite Markov chain, choose a boundary set that can be reached from every state, and assign boundary values . If is its first hitting time, the harmonic extension isChoosing to be the indicator function of one target within gives a hitting probability. This is a discrete Dirichlet problem: enforce the averaging rule outside and fix the values on . See Hao Wu's MIT lecture 8, harmonic extension, slide 5. The construction extends the mean-value idea of a harmonic function; for a random walk on a graph it is a discrete harmonic function.
Take a birth-death chain on . At each interior state, move up one state with probability and down one state with probability . The endpoints are absorbing states: . This is a small gambler's ruin model in which the state can represent capital, and reaching is success.
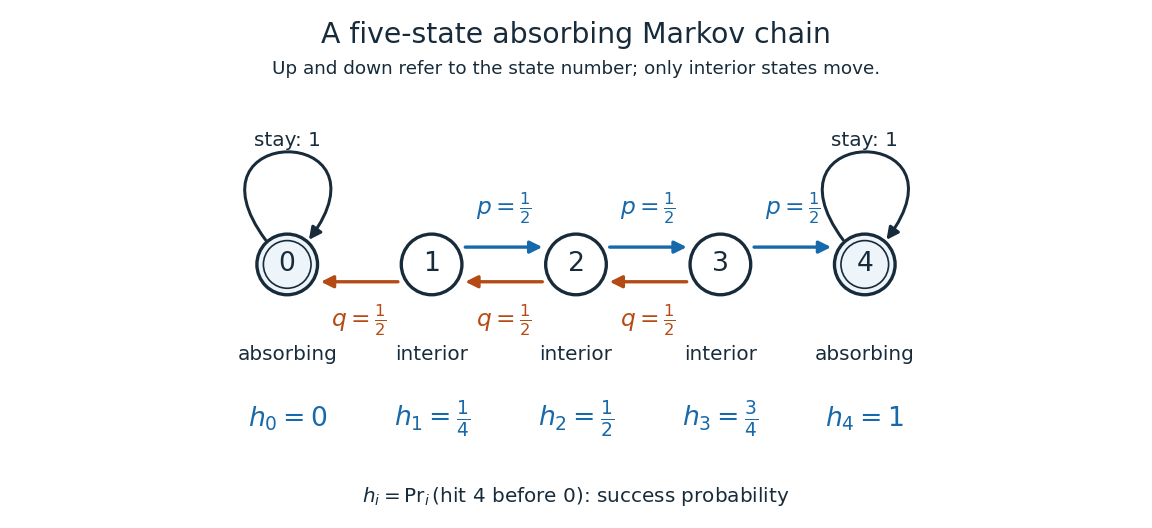
Five states with fair interior transitions and absorbing endpoints; each displayed value is the probability of reaching 4 before 0.
Details. Let be the hitting time of endpoint , and let be the first endpoint hitting time. The desired hitting probability is . First-step analysis and the Markov property giveThe interior equation says adjacent differences are equal. Four equal increments must bridge the boundary values and , soFor example, from state the hitting probability is , and its one-step average is . Individual sample paths can wander back and forth, but the same averaging rule already accounts for all of them.
Now ask how long it takes to reach either endpoint. The expected hitting time counts steps, including the transition that first reaches an endpoint. First-step analysis givesThis is a discrete Poisson equation, in the interior. The extra counts the step just taken. The quadratic valuessatisfy the equations; from state , steps. The hitting probability is harmonic, whereas the expected hitting time has a nonzero source term. These are special cases of expected duration of symmetric gambler's ruin; see Hao Wu's MIT lecture 16, gambler's ruin, slide 9.
For a biased random walk with upward and downward, keep the same absorbing states. The interior harmonic equation becomes . Using biased gambler's ruin probability with these boundary values givesThe three interior hitting probabilities are approximately , , and . Thus starting at now succeeds about of the time. A direct check is . The curved profile reflects the unequal transition weights: its successive increments shrink by the factor . The formula, with the endpoint denoted there, is verified in Karger and Lynch's MIT lecture 26, sections 2.3-2.4; the five-state numbers here are direct substitutions.
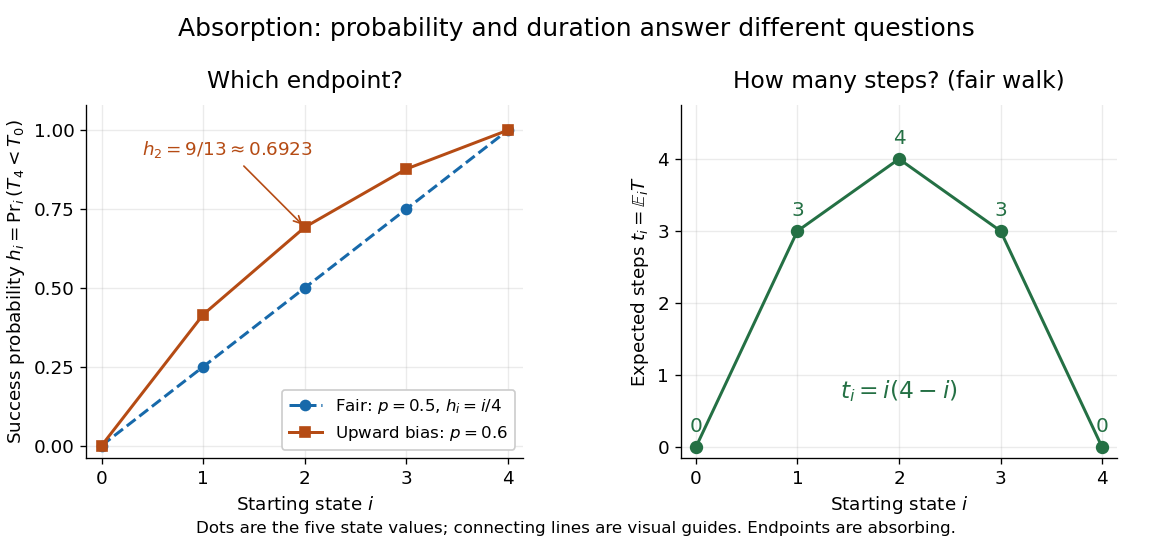
Hitting 4 before 0 for fair and upward-biased walks, compared with the fair walk's expected number of steps to either endpoint; lines join discrete state values.
Details. Why does harmonic averaging produce the correct hitting probability? With the natural filtration , the Markov property gives the conditional expectation identityFor a function harmonic everywhere, this makes a martingale whenever it is integrable. For a function harmonic only in the interior, is a stopped martingale. In either five-state example, . Also, from any interior state at most three consecutive upward steps reach , with probability at least . Repeated three-step blocks give , so is almost surely finite and has finite expected value; compare finite-interval exit times have geometric tails. Applying optional stopping at and then the bounded convergence theorem givesThe boundedness and finite hitting time justify this passage to the limit. See Steven Lalley's notes, harmonic functions and stopped expectations, theorem 1, and stopped martingale in discrete time for this bounded version of optional stopping.
Uniqueness has a short maximum principle explanation. On a finite state space, the difference of two harmonic extensions with the same boundary conditions is zero on the boundary. If its positive maximum occurs inside, the weighted average forces every successor with positive transition probability to have the same maximum. A path to the boundary propagates that maximum to zero, a contradiction. Applying the argument to the negative of the difference proves uniqueness. Reachability of the boundary is essential: an interior closed communicating class can retain an arbitrary constant.
// Target: markov-process.bigb
Take states for , with deterministic and transitions with probability , with probability , with probability , and with probability . The Markov chain is transient for , null recurrent for , and positive recurrent for . To see the Markov chain recurrence threshold, eliminate the primed-state hitting probabilities to obtain , with characteristic roots and . Boundedness forces return with probability one when the second root is at least one. When it is below one, the minimal nonnegative solution gives return probability from . In the positive recurrent case, put and . The stationary distribution is , and . It follows from balance across each level cut and sums to one; at criticality the invariant weights cannot be normalized.
For , observe a discrete-time Markov chain only when its state changes. The probability that its next different state is is . Its holding times are finite geometric waiting times. This construction deletes self-transitions and differs from the existing continuous-time jump-chain concept.
An irreducible recurrent discrete-time Markov chain with at least two states has everywhere. Removing repeated consecutive states from a positive-probability path proves irreducibility of its discrete-time jump chain. Each sojourn in a state is almost surely finite; infinitely many visits to a recurrent state therefore correspond to infinitely many distinct returning sojourns. The jump chain remains recurrent, although deleting holding times may change periodicity.
Fix and put . For independent geometric random variables with for , the Reflected chain with geometric downward jumps obeys . Its transition probabilities are for and .
The Probability of hitting zero from is one when and when . The first-step boundary equation at is essential for the extra exponent. Before reflection the mean increment is : downward drift corresponds to .
The chain is positive recurrent for , with Stationary distribution for . The ratio ensures these weights sum to one. It is null recurrent at and transient for . The parameter restriction matters: does not define the displayed geometric distribution, and produces deterministic upward motion rather than an irreducible chain.
At a junction, let be the Probability that one excursion leaves through branch and never returns. If , repeated returns restart the same probabilities by the Strong Markov property. Thus the Probability of returns is , and eventual escape through is . When the branches have outward random-walk drift, the final infinite excursion tends to the corresponding end almost surely.
A time-homogeneous Discrete-time Markov chain is a sequence of random variables indexed by nonnegative integers, with the displayed conditional probabilities. Here is its natural filtration and is a row-stochastic transition matrix. The Markov property removes dependence on earlier observations once is specified; the time-homogeneous Markov property makes independent of .
Consider states (sunny) and (rainy), with the constructed transition matrixRows give today's state and columns tomorrow's, in order . These numbers define an illustrative model, with one step interpreted as one day; they are not estimates of real weather. Let . The law of total probability gives the recurrence relationSubtracting makes the deviation multiply by at each step. ThusStarting sunny gives , , and ; starting rainy gives and . The two predictions approach the same stationary distribution while retaining a shrinking trace of the initial probability distribution.
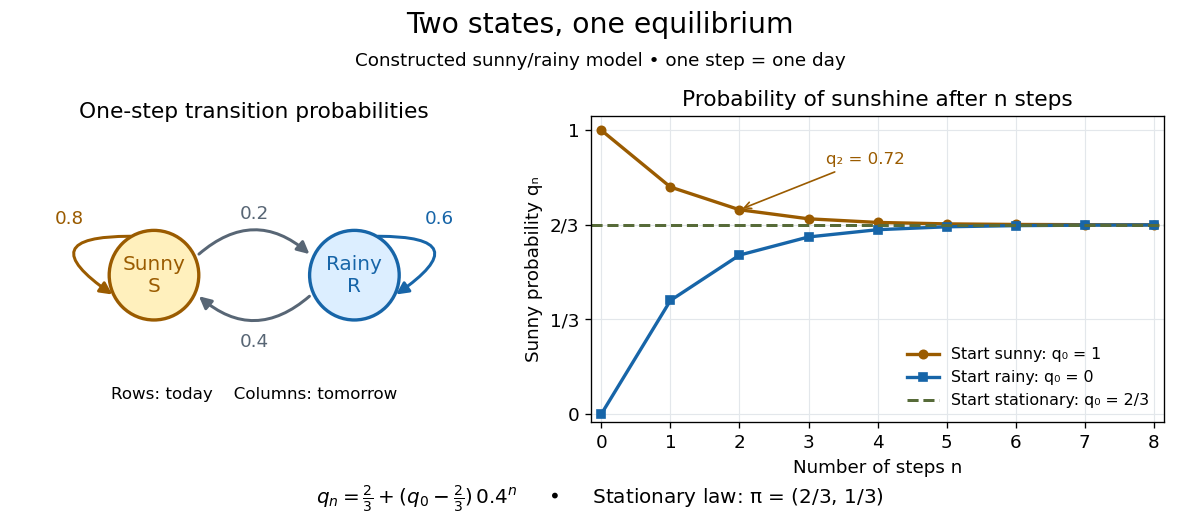
Constructed sunny/rainy transitions and the exact sunny probabilities from three initial distributions.
Details. An expected hitting time answers a different question. Starting sunny, let . Every day before the first rain remains sunny, soThis geometric distribution has finite expected value. A first-step calculation gives , with , hence days. The same result follows from the geometric series . This is a mean waiting time, not a prediction that rain first occurs exactly five days later.
A probability row vector is a stationary distribution when . The Markov chain is reversible in that law when detailed balance holds: . Multiplying those equations along a finite path gives equal forward and reversed stationary path probabilities.
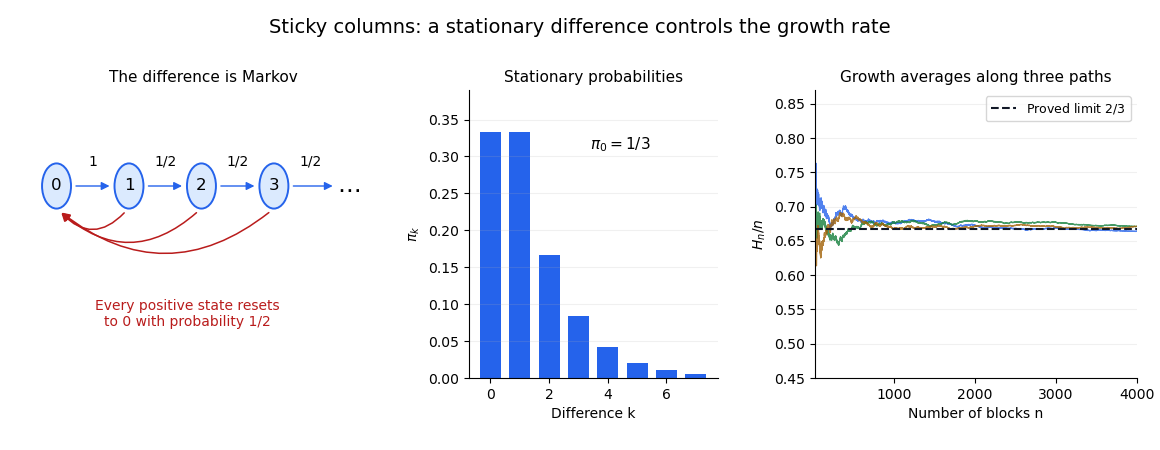
For , consider the Markov chain on the nonnegative integers with the displayed transition probabilities. From zero it starts a new upward run; from each positive state it either increments or resets. Writing , its stationary distribution isThe balance equations give and for ; the geometric series normalizes the result, and the zero-state equation agrees. It is an irreducible Markov chain and is positive recurrent. Equivalently, its first return time to zero is one plus a geometric random variable with success probability , so its mean recurrence time is . Return paths of lengths two and three also make it aperiodic.
Suppose each new unit block independently selects one of two columns with equal probability. On the taller column it increases the maximum height; on the shorter column it sticks level with the other column, leaving the maximum unchanged. If the columns have equal height, the next block increases the maximum. Their absolute height difference is the reset-or-increment Markov chain with .
For the maximum height , each increment obeys . The stationary distribution has . Applying the countable-state Markov chain ergodic theorem to the bounded indicator function of the positive states givesalmost surely, from any fixed finite starting configuration. The reward average depends only on whether a reset occurred, even though the difference chain has infinitely many states.
An adapted process on a finite or countable state space has the Markov chain transition matrix exactly when the displayed process is a martingale for every bounded test function . The forward implication follows by taking the conditional expectation of its increment. Conversely, the Martingale property gives ; testing individual-state indicators recovers the entire conditional transition law. Stopping these martingales turns equations and into hitting probabilities and expected hitting times.
For a transition matrix , a finite-valued function on its state space is nonnegative superharmonic when . Thus and its expected value cannot increase after one step. Replacing transitions on a target set by identity rows preserves . Iterating this inequality gives , a useful bound for hitting probabilities without a separate optional-stopping theorem.
An irreducible Markov chain is recurrent exactly when every nonnegative superharmonic function for a Markov chain is constant. In the recurrent case, absorb the chain at . The inequality and almost-sure hitting give ; exchange . In the transient case, the hitting probability of a state is one there and satisfies the superharmonic inequality, but its one-step average at is the strictly smaller return Probability. It is a nonconstant example.
A nonnegative row vector , not necessarily of total mass one, is an invariant measure for a Markov chain if . On an irreducible Markov chain, every nonzero invariant measure has positive coordinates: iterate stationarity and use a positive Transition probability along a path.
For a recurrent Markov chain, start at and stop at its first positive return . The expected visits to each state before that return form the excursion occupation measure. Its th coordinate is one. Counting the return endpoint instead of the start gives the same measure. It is invariant by shifting the occupation sum one time step and using the Markov property. Any Markov chain invariant measure normalized by dominates it: iterate the stationarity equations on the state space with removed, then retain the nonnegative excursion-path terms.
On the nonnegative integers, every positive state decreases by one, while zero jumps to with Probability , . Its return time from zero is one plus this geometric jump, so it has mean . Return lengths two and three occur, establishing aperiodicity; deterministic downward motion and positive jumps establish irreducibility.
For the geometric-jump countdown Markov chain, regeneration at zero givesA cycle visits positive state precisely when its jump reaches at least , with Probability . Dividing this expected occupation by the mean cycle length proves the formula. Mean recurrence times are , and the limiting Probability away from zero is .
A partition of a Markov chain state space is strongly lumpable when, for every target block , the sum is identical for all source states in a given source block. These sums define the transition matrix of the block-valued Markov chain, independently of the initial law. Failure of this condition means the projection is not guaranteed to be a homogeneous Markov chain for every initial law, although special initial laws may still produce a Markov process.
A phi-irreducible Markov chain is Harris recurrent when every set of positive irreducibility measure is hit almost surely from every state. With an invariant Probability, it becomes a positive Harris recurrent Markov chain.
A discrete-time model describes individual transitions between states at successive steps. State occupancy counts, first-entry counts and transition counts are distinct quantities, especially when a state has a self-loop. With independent individuals and fixed transition probabilities, destination counts conditional on the source count have a multinomial distribution.
The Discrete-time multi-state diagnosis model tracks the delay between infection and diagnosis. Let be the expected number of new infections at step , with for . An infection at step has one early opportunity for diagnosis at step , with Probability . If not diagnosed early, it has a diagnosis opportunity with Probability at each step , conditional on still being undiagnosed. Assume and , with the same transition probabilities for all cohorts.
The expected early and late diagnosis counts at step arewhere an empty sum is zero. Each term in the second expression is a cohort size multiplied by its Probability of avoiding early diagnosis, surviving the earlier late opportunities, and being diagnosed now. The waiting time in the late state therefore has a positive-support geometric distribution.
For a single cohort with , , , and no later infections, the expected counts are , , , and . The ratio , when its denominator is positive, is the early fraction of the expected diagnosis intensity. It is not generally the expected value of the observed random fraction: taking a ratio and taking an expected value do not commute. Initial infections before step zero require additional cohort terms, so the time origin must be stated.
A Harris recurrent chain visits every measurable set of positive irreducibility measure almost surely. Positive Harris recurrence additionally supplies an invariant Probability measure. The ergodic theorem for a positive Harris recurrent Markov chain gives consistency of time averages of integrable functions.
For a positive Harris recurrent Markov chain with invariant Probability and , its time average converges almost surely to the invariant expectation:This is the consistency result for Markov chain Monte Carlo averages. Independent-observation variance formulas do not follow from this theorem.
Choose two positions independently and uniformly from and swap them. This Markov chain on the symmetric group holds with Probability and assigns Probability to each unordered transposition. Its stationary distribution is uniform, and its ordinary spectral gap is for . The latter follows from the Aldous spectral gap theorem: the single-label continuous-time Markov chain has rate between every pair of positions, whose mean-zero eigenvalues are all .
Place six positions on a cycle and distinguish two labels. At each step choose one of the fifteen unordered pairs of distinct positions uniformly and transpose their contents. This convention excludes identity moves. The shorter circular distance between the distinguished labels takes values . Cycle symmetry and exchangeability of the other labels make this distance a Lumped Markov chain.
Counting transpositions gives the transition matrix and Stationary distributionThe stationary weights also follow by counting unordered position pairs: six pairs have distance one, six have distance two, and three are opposite. If has every row equal to , then and . Starting with adjacent labels, the Probability of opposite labels after steps is therefore .
The parent Random transposition shuffle uses a different convention: two positions are sampled independently, allowing an identity move with Probability . Under that convention the distance transition matrix is , and the opposite-label Probability is . Explicitly stating the sampling convention prevents a spurious change in the convergence rate.
On the symmetric group , this Markov chain chooses uniformly from the identity and the adjacent transpositions, and multiplies on the right. Its stationary distribution is the uniform distribution on a finite set, because the generators are self-inverse. A fixed label's position is a lumped Markov chain on a path graph with off-diagonal transition probabilities to existing neighbours.
For the random adjacent transposition shuffle with , the generator is the interchange process on a path graph with each edge rate . The Aldous spectral gap theorem reduces its spectral gap to that of the single-label random walk. The eigenfunctions , for , have generator eigenvalues ; direct substitution verifies both the interior and endpoint equations. Consequently .
For the random adjacent transposition shuffle on with , the position of one label is uniform on in equilibrium, so . Each adjacent transposition moves the label with Probability , giving . The Poincare inequality for a reversible Markov chain variational formula therefore gives . In particular the continuous uniform distribution on has variance , not .
For a finite, time-homogeneous Discrete-time Markov chain with row-stochastic transition matrix , a state is absorbing exactly when . Nonnegativity and the row sum then force for : once entered, is never left. Equivalently, is a closed communicating class. A larger closed communicating class may keep moving internally; closure means confinement to a set, whereas absorption at a state means remaining at one point.
An absorbing state is useful for recording a terminal outcome: after a toy routine finishes, keep its outcome in the state space so that the same transition matrix still describes subsequent steps. Calling a finite Markov chain absorbing usually also requires that some absorbing state be accessible from every state. Merely containing an absorbing state is insufficient: another closed communicating class could prevent absorption. See Grinstead and Snell, Introduction to Probability, section 11.2 for this convention.
Consider a constructed routine with unfinished modes and terminal outcomes . All the following transition probabilities are chosen for illustration, not estimated from observations. In state order , takeThe communicating class is open, while and are closed communicating classes consisting of absorbing states. Both terminal outcomes are accessible from both unfinished modes, sometimes by an indirect path.
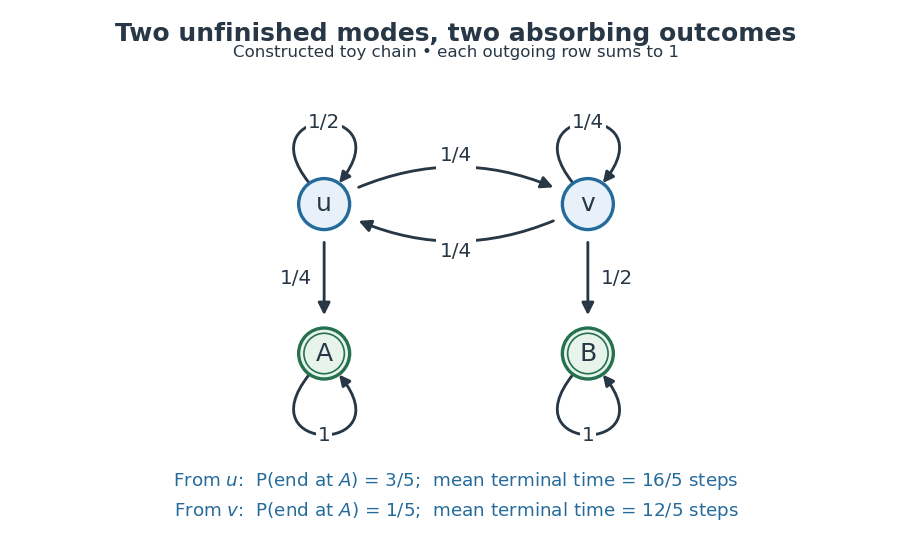
A constructed four-state routine: arrows give transition probabilities, and the two absorbing outcomes have different eventual probabilities and waiting times.
Details. Let be the terminal hitting time. Write for the absorption probability and for the expected hitting time, with the subscript denoting the starting state. First-step analysis givesHere , , and . Solving these two pairs of linear equations yieldsStarting at therefore ends at with probability and takes steps on average to reach either terminal state. The terminal hitting time counts the transition into the outcome, but no later self-transitions. Outcome and duration answer different questions: from , outcome is less likely, yet termination is faster on average.
The matrix power gives the probability distribution after two steps from asThus , and the probability of having already reached is , still below its eventual absorption probability . From either unfinished mode, each next step has terminal probability at least . Consequently , proving termination almost surely and finite expected hitting time directly. The Fundamental matrix of a finite absorbing Markov chain packages both calculations and counts visits to unfinished modes.
For a finite Markov chain in which an absorbing state is accessible from every state, order the nonabsorbing states first and writeHere is the identity matrix and is the matrix inverse of . With the first hitting time of the absorbing set,Thus gives the expected occupation count before absorption, including the initial visit; is the absorption probability of state ; and is the expected hitting time of the absorbing set. The vector has every entry one. See Grinstead and Snell, section 11.2, theorems 11.4-11.6.
For the toy routine in absorbing state, direct matrix multiplication givesThe first row of says that starting at gives visits to and to before termination. Their sum is the mean duration . The identities , , and independently verify the inverse, outcome, and duration calculations. The absorbing set must be reachable from every state for these finite formulas: applying them to all nonabsorbing states in the closed-cycle example would leave a persistent cycle in and make singular.
A Markov kernel from a measurable space to a measurable space is a function satisfying two conditions: for each , is a Probability measure; for each , is a measurable function. The second condition makes integrals against a distribution of current states well defined.
If the current state has probability distribution , the next-state distribution isOn a finite or countable state space with all subsets measurable, a transition matrix gives . A deterministic measurable map gives , so the kernel formalism includes deterministic dynamics as well as random transitions.
Successive kernels compose by . The tower property of conditional expectation explains this rule: first condition on the intermediate state, then average over it. For a homogeneous Markov chain, the -step transition kernel is ; its composition law is the Chapman-Kolmogorov equation.
A probability density function for the conditional future state of a Markov process given its current state. Integrating over a measurable region gives its transition probability. A transition kernel need not admit a density; discrete or partly atomic transition laws require a different reference measure or a separate atomic part.
A Birth-death chain is a discrete-time Markov chain on nonnegative integers that can move only to the same state or a neighbouring state.
In a positive recurrent birth-death-immigration jump chain, let and count immigration events and upward steps before time . The centered immigration indicators form bounded martingale differences; the strong law for martingales with bounded increments and the countable-state Markov chain ergodic theorem give almost surely. The analogous argument for upward steps gives . Summing detailed balance gives , since every step is upward or downward. Therefore converges to the displayed fraction. For this chain the explicit stationary distribution reduces the fraction to .
Here , , and the upward step is either a birth or immigration, the latter having conditional probability . At zero immigration occurs with probability one. Put , and . The stationary weights of a reflected birth-death chain areTheir successive ratio tends to , so they are summable for . For , makes the weights strictly increasing, ruling out a stationary distribution. Thus positive recurrence holds exactly for . In that case the binomial series gives , andEvery step reverses parity and a two-step return has positive probability, so the period of a state in a Markov chain is two. Starting at zero, , whereas .
Consider an irreducible Markov chain on the nonnegative integers with up-step probabilities and down-step probabilities for , reflected at zero. The displayed weights satisfy detailed balance. Every stationary distribution is proportional to them: the stationary equation at zero sets the edge flow to zero, and the remaining stationary equations make the flow constant along all edges. Hence positive recurrence is equivalent to , and then . This also allows holding probabilities of a Markov chain.
A strictly increasing sequence for which is a martingale along the birth-death chain before hitting its boundary. With upward and downward probabilities , harmonicity means . This coordinate is useful for hitting probabilities and optimal stopping.
For a nearest-neighbour Markov chain on with positive right-step probabilities in its interior, let and be their minimum. From every interior state, at most consecutive right steps reach , with Probability at least . The Markov property then gives for the first boundary hitting time. Thus is almost surely finite and has finite expectation, regardless of the holding probability of a Markov chain at each interior state.
// Target: probability-theory.bigb
The interior equation for a harmonic function for a Markov chain on the integers gives . Positive scale increments satisfy . For absorbing boundaries , the lower exit Probability from isThis satisfies the harmonic equation and the boundary values and therefore is the hitting probability. For parity-dependent probabilities, with ; geometric sums distinguish rightward, balanced and leftward escape.
// Target: markov-process.bigb
For a birth-death chain on the integers with right/left probabilities depending on parity , define . It is a harmonic function for a Markov chain exactly whenequivalently . The correction is bounded. Stopping this martingale at boundaries gives a lower exit Probability tending to as , even though the original position need not be a Martingale.
// Target: markov-process.bigb
Consider an irreducible Birth-death chain on . At zero let and . At , let and , with . DefineIn the recurrent case, is the expected number of visits to during a cycle started at zero, counting times . The initial visit gives . Each upward crossing of an edge before the return is paired with a downward crossing, giving and the product formula. Tonelli's theorem then gives . Consequently the recurrent chain is positive recurrent exactly when this sum is finite, and its Stationary distribution is .
The finiteness criterion also rules out transience without assuming recurrence in advance. Put and . Then . If , then , so and . The birth-death scale-function hitting formula therefore implies recurrence. This separates stationary occupation weights from the inverse-direction scale weights , which serve different purposes.
independent Markov chains with transition matrices and form a product chain with transition matrix . If their stationary distributions are and , the product distribution is stationary.
Take independent copies of the simple random walk on the integer line, each stepping left or right with equal probability at every integer time. Their product Markov chain moves all coordinates at once; each of its diagonal increments has probability . At odd times a return to the origin is impossible. At time , independence gives the displayed return probability, whose asymptotic equivalence follows from Stirling's approximation. The recurrence criterion by return probabilities and the p-series therefore imply recurrence for and a transient Markov chain for .
For the chain from the origin visits only the sublattice whose coordinates all have the same parity. This is one communicating class; restricting to it gives an irreducible Markov chain. The period of a state in a Markov chain is two here. The conclusion applies to that class, without incorrectly claiming Markov chain irreducibility on all of . This walk moves diagonally; the usual axis-step simple random walk has different transition probabilities, even though the same dimensional recurrence threshold holds.
A row-stochastic matrix has nonnegative entries and each row sums to one. For a time-homogeneous Discrete-time Markov chain, its transition matrix has entriesIf a state has zero probability at time , this row is specified by the model's Markov kernel, rather than recovered by conditioning on that zero-probability event. Rows index departure states and columns arrival states. Writing the current probability distribution as a row vector givesThe row-sum condition ensures that matrix multiplication preserves total probability. Under a column convention the evolution uses the transpose; the convention must accompany the formula.
For the sunny/rainy transition matrix, direct matrix multiplication givesIn particular, . The two terms sum the disjoint paths and . Requiring both subsequent days to be sunny has probability ; requiring only the second day to be sunny permits the extra path through rain.
Generally is the -step transition probability. The identity is the discrete-time Chapman-Kolmogorov equation: sum over the intermediate state. This makes matrix powers useful for forecasting many steps without enumerating every path individually.
The Transition probability is the Conditional probability that a Markov chain moves to state on its next step given that its current state is .
At state , the holding Probability of a discrete-time Markov chain is the self-transition Probability . It is the Conditional probability that the next state remains . In a nearest-neighbour birth-death chain, it is , where and are the probabilities of stepping right and left. Holding changes the elapsed time but not the embedded chain of actual moves or its boundary exit probabilities.
For a finite, time-homogeneous Discrete-time Markov chain with row-stochastic transition matrix , irreducibility meansEquivalently, all states form one communicating class. The step count may depend on ; irreducibility does not require every one-step transition probability to be positive. Drawing an arrow whenever makes the condition exactly that of a strongly connected directed graph. It is a property of the entire chosen state space, independent of the initial probability distribution.
Irreducibility describes where the Markov chain can travel; aperiodicity describes the possible lengths of return paths. For example, restricting the second diagram in communicating class to its closed pair giveswhere is the identity matrix. This Markov chain is irreducible, but each state's period of a state in a Markov chain is two. Every destination is reachable, yet a given destination cannot be reached at every sufficiently large step count. Starting at produces alternating one-time probability distributions. See Hao Wu's MIT lecture 2, irreducibility and periods for the definitions.
Adding a holding probability of a Markov chain at each state, with , givesThe arrows between the two states remain, so the Markov chain remains irreducible. A positive one-step return makes it an aperiodic Markov chain. At , both rows are and for every : the initial state is forgotten after one step. At , however, both states become absorbing states, giving two separate communicating classes and losing irreducibility.
For a finite Markov chain, irreducibility guarantees a unique stationary distribution with positive weight at every state. Adding aperiodicity guarantees convergence for every initial probability distribution; see Hao Wu's MIT lecture 4, convergence theorem. The Markov chain ergodic theorem gives convergence of empirical visit frequencies even for an irreducible periodic Markov chain. These results explain why checking connectivity is a useful first step before studying equilibrium. Conversely, any absorbing state prevents irreducibility if there is another state: it cannot reach that state. The one-state Markov chain is the exception.
A Markov chain with transition kernel is -irreducible if is a nonzero sigma-finite measure and every measurable set with satisfies from every starting state . This is positive reachability, not certain eventual hitting.
A state is aperiodic when the greatest common divisor of its positive-probability return times is one. A Markov chain is aperiodic when all its states are aperiodic.
The mean recurrence time of is . In a finite irreducible Markov chain with stationary distribution , it equals .
Suppose two finite Markov chains on the same state space have transition matrices satisfyingEvery positive-probability path and return cycle for is also possible for . Thus irreducibility passes from to . For a state aperiodic under , its positive return lengths under contain those under , so their greatest common divisor is still one. Hence aperiodicity also passes to .
Individual-state recurrence need not be preserved when the original chain is reducible. For example, take on andState zero is recurrent under but transient under : once the chain leaves it, it never returns. The added transition opens an escape from its former closed class. If is finite and irreducible, however, then is also finite and irreducible, so every state remains positive recurrent. Mean recurrence times can still change because the Stationary distribution depends on transition probabilities, not merely on their support.
For independent random variables with a common law, satisfies . The next-state law therefore depends on the past only through .
A moving sum of independent random variables need not be a Markov chain. Let be independent Bernoulli random variables with success Probability , and define for .
Knowing only leaves the two possibilities and equally likely. independence of givesBut the positive-probability event forces , soThe previous observed sum therefore changes the next-state Conditional distribution even after conditioning on the current sum, violating the Markov property. The hidden overlap variable is the reason. By contrast, retaining the pair as the state gives a Markov chain.
A stationary Markov chain is reversible in equilibrium when it has the same finite-dimensional distributions as its time reversal . Equivalently, its stationary flow satisfies Detailed balance.
On the matchings in a graph, a lazy Markov chain proposes adding an edge, deleting an edge, or exchanging an edge for the unique matching edge incident with it. A proposal incident with two matching edges is rejected. Select the proposed edge uniformly and use the Metropolis–Hastings acceptance probability for the displayed weights. Symmetric proposals give detailed balance; deletions connect every state to the empty matching in a graph. The normalizing constant is the matching generating function.
Here the graph has vertices and edges. The bound is a deliberately loose canonical paths Poincare bound, sufficient for polynomial mixing time when both activity and reciprocal activity are polynomially bounded. Order the alternating graph paths and cycles of canonically. Convert each component from initial matching in a graph to final matching in a graph by moving an unmatched endpoint using exchanges; open a cycle with one deletion and finish it with one addition.
At an intermediate matching in a graph , the complementary encoding is a matching in a graph away from the active component and has at most two degree-two vertices. Remove at most two edges to obtain a matching in a graph . Record those edges and one bit selecting the initial alternating colour on the active component. For a fixed directed transition this data reconstructs , , the active component and its ordering, and then ; common edges are . There are at most auxiliary records per .
If , then . The transition capacity is at least , and the path length is at most . Summing over the injective encodings proves the displayed path congestion bound.
Let a Reversible Markov chain start in its Stationary distribution , and let . Define to be the first time an occurrence of has been followed strictly later by an occurrence of :For each fixed , the event says that the path segment contains before . Reversing that segment changes the event into the existence of before . Stationary reversibility therefore gives for every , so the two completion times have the same distribution.
For a finite irreducible chain, all these expected hitting times are finite. Let and , with . The Strong Markov property at gives . Applying the same argument with reversed yieldsIf the diagonal is instead defined by the positive mean return time , its contribution to each stationary-weighted mean is one by Kac's lemma. Those equal additions cancel in the displayed difference.
Let be a reversible Markov kernel with stationary Probability measure , and let the initial Probability measure have Radon-Nikodym derivative . After steps, Detailed balance givesfor -almost every . To prove the identity, integrate a bounded measurable test function against the evolved measure: , because reversibility makes self-adjoint in the integral pairing.
To express the result with ordinary probability density functions, fix a reference measure , write , and let . On the support where , , so the evolved density isThis formula uses the initial density , not the Probability measure evaluated at a point. The unknown normalizing constant cancels. Reverse simulation from can estimate this expression without evaluating the Transition density, provided the displayed integrand can be evaluated.
For example, the symmetric two-state kernel with holding Probability has Stationary distribution . Starting at state zero gives , then ; multiplying by the stationary masses recovers the one-step distribution .
For a finite irreducible Markov chain satisfying detailed balance with , its transition matrix is a self-adjoint operator for . For a real orthonormal eigenbasis with eigenvalues ,Indeed, apply the spectral decomposition of to the function , whose coefficient against is . For , every eigenvalue multiplier is interpreted as one.
For a Markov chain with transition matrix , Detailed balance with a probability distribution meansThe left side is the equilibrium Probability of the directed transition ; Detailed balance equates it to the reverse flow. Summing over gives , so Detailed balance implies stationarity. Under the stationary initial law, repeated application of the pairwise identity equates a finite path's Probability to that of its reversal, establishing reversibility.[ref]
Mixing Time Bounds via the Spectral Profile by Sharad Goel and others. Section 1.1: invariant measure and reversibility
For example, takeThe off-diagonal flows are both , which verifies Detailed balance and the Stationary distribution directly. A directed three-state cycle has a uniform Stationary distribution but no reverse transitions, so it is not reversible. Stationarity alone therefore does not imply Detailed balance, and Detailed balance alone does not imply rapid convergence.
Detailed balance does not imply that a Markov chain is an irreducible Markov chain: the identity transition matrix is reversible for every probability distribution. Even for an irreducible Markov chain with aperiodicity, the two-state matrix with diagonal and off-diagonal , , has uniform stationary distribution and nontrivial eigenvalue . From either fixed state its total variation distance after steps is , so convergence can be arbitrarily slow. Invariance, reachability and mixing time are distinct questions.
For a continuous-time Markov chain with transition rates , Detailed balance isfor every pair of distinct states. A probability distribution satisfying these equations is an invariant distribution of a continuous-time Markov chain, because summing over incoming rates gives . Under the standard nonexplosion assumptions, the equilibrium chain is reversible.
For a finite irreducible Markov chain with at least two states satisfying detailed balance, its Dirichlet form of a Markov chain obeysExpand in an orthonormal eigenbasis. The denominator is , and the numerator is . Their ratio is at least and equality holds for the second eigenfunction. Thus the optimal Poincare inequality for a reversible Markov chain constant is , for the ordinary rather than absolute spectral gap.
For a finite undirected graph with unit edge conductances, define the Discrete Dirichlet energy of a real-valued function byEach undirected edge is counted once. More generally, multiply each term by its edge conductance. The energy is nonnegative and vanishes exactly when is constant on every connected component. Large differences across strongly conducting edges are expensive; this is why Discrete Dirichlet energy appears in harmonic extension and electrical-network principles.
Normalization depends on the chain. For simple random walk on a finite connected unweighted graph with edges, the Stationary distribution is , so its Dirichlet form of a Markov chain is . On the three-vertex path with values , the graph energy is , whereas the simple-random-walk energy is . Stating which normalization is used matters when comparing spectral gaps or effective resistances.
The Canonical paths comparison theorem transfers a spectral-gap estimate from a reference Reversible Markov chain to another chain by routing reference transitions along allowed target transitions. Let and be finite reversible transition matrices with the same positive Stationary distribution . For every ordered pair with and , choose a path from to using positive transitions. Let count occurrences of a directed edge and putThen for every real-valued function . Indeed, telescope along the path and apply the Cauchy-Schwarz inequality, multiply by , and sum over ordered pairs. Collecting the contribution of each directed edge gives the stated capacity-normalized congestion.
The variational Poincare inequality for a reversible Markov chain now gives for the ordinary spectral gaps. Choosing the reference chain gives and , recovering the Canonical paths Poincare bound. This makes a local-transition chain comparable to a chain that resamples its entire state in one step. The common invariant distribution and directed-edge counting convention are part of this formulation.
Choose a directed path of positive-probability transitions for each ordered pair of states in a finite reversible Markov chain. Write for a directed edge , and let count its occurrences. DefineThe Cauchy-Schwarz inequality bounds by times the sum of squared differences along the path. Multiply by , sum and interchange finite sums. The identity proves the bound. This convention counts directed edges and retains the factor in the Dirichlet form of a Markov chain.
For a family of transition graph paths, Path congestion is the largest, over transitions, ratio of routed pair weight times path length to stationary transition capacity. The canonical paths Poincare bound makes this an upper bound on the relaxation time.
For a transient weighted graph, is the completion of the finitely supported functions in the norm . Its elements have finite Dirichlet energy and vanish at infinity in the energy sense.
The Relaxation time of a finite reversible lazy Markov chain is the reciprocal of its spectral gap: .
For a finite irreducible Markov chain with at least two states that is an aperiodic Markov chain and a reversible Markov chain, put and . This is the reciprocal of the absolute L2 spectral gap of a reversible Markov chain. It agrees with the reciprocal of the ordinary spectral gap for a lazy Markov chain, but need not agree when there are negative eigenvalues.
The Spectral profile records the energy needed to concentrate a function on sets of a given stationary mass. For a finite irreducible Reversible Markov chain with Stationary distribution , defineHere is its Dirichlet form of a Markov chain, and ensures that admissible nonempty sets exist. This is the variance-normalized convention.[ref]
The profile is nonincreasing in , because enlarging permits more supports. The ordinary spectral gap is a lower bound on every , but small supports can force a larger Rayleigh quotient. For the symmetric two-state chain with off-diagonal Transition probability , a function supported on one state has energy and variance , so .
The denominator matters. Replacing variance by gives a restricted Dirichlet eigenvalue instead. On a support of mass at most , the Cauchy-Schwarz inequality gives , relating the two conventions within a factor .
For a finite irreducible Reversible Markov chain with Stationary distribution , let and define its conductance profile byFor and the variance-normalized Spectral profile,The star here names the small-set profile on this restricted domain; some sources reserve a star for its extension truncated at .[ref]
Mixing Time Bounds via the Spectral Profile by Sharad Goel and others. Section 2.2, Definition 2.2 and Lemma 2.4
For the upper bound, test the spectral-profile quotient with . Its energy is and its variance is . For the lower bound, take a nonnegative function supported on a set of mass at most . Applying the level-set integral identity to bounds by . Factoring the difference of squares and applying the Cauchy-Schwarz inequality bounds this last expression by . Squaring and using proves the lower bound. Thus a geometric obstruction to boundary flow produces an analytic obstruction to relaxation.
For a reversible Markov chain with stationary flow , the conductance of a set isIts Cheeger constant minimizes the boundary flow divided by the smaller stationary mass of the two sides of the cut.
The conductance profile records bottlenecks at different stationary sizes in a finite irreducible Markov chain with at least two states. With stationary distribution and stationary flow , one convention isThis domain ensures that the minimizing family is nonempty. Other normalizations use the smaller side of a cut, so a convention must accompany a quoted profile.
For a lazy nearest-neighbor walk on an -cycle, holding with probability , a consecutive block of vertices has boundary flow and stationary mass , hence conductance . A profile therefore reveals how bottlenecks change with set size rather than retaining only one global minimum.[ref]
Mixing Time Bounds via the Spectral Profile by Sharad Goel and others. Section 2.2, conductance-profile comparison; cycle calculation supplied here
The Cheeger constant of a finite reversible chain is the least stationary boundary flow divided by the smaller stationary mass of a set and its complement.
The -mixing time is the least for which every initial state has total variation distance at most from the invariant distribution after steps.
Articles were limited to the first 100 out of 404 total.




