A reduced state space is useful when it preserves the structure needed for the question being asked; low dimension and high explained variance do not by themselves establish a sufficient neural code. Start with a clear observation model. A vector of binned spike counts from neurons may be approximated through latent coordinates, but the choices of bins, transformations, noise model and preserved criterion all affect the result.
For centered observations, principal component analysis chooses an orthonormal projection to minimize expected squared reconstruction error,where . The identity follows by expanding the square and using . Diagonalize . The trace term is , with for the columns of . Here and because the columns of are orthonormal. Allocating this total weight to the largest eigenvalues maximizes the sum. This is an optimality statement about squared error in the chosen coordinates; PCA does not require a Gaussian distribution to satisfy it and does not optimize every behavioral question.
An exact counterexample makes the limitation decisive. Let be independent balanced signs, define , and let the remembered class be . Zero means and independence giveThe first component retains of total variance. Yet : no classifier using that component alone exceeds one-half expected accuracy. The second component determines the class exactly. Positive rates give the same example after centering. These are constructed rates, not experimental recordings.
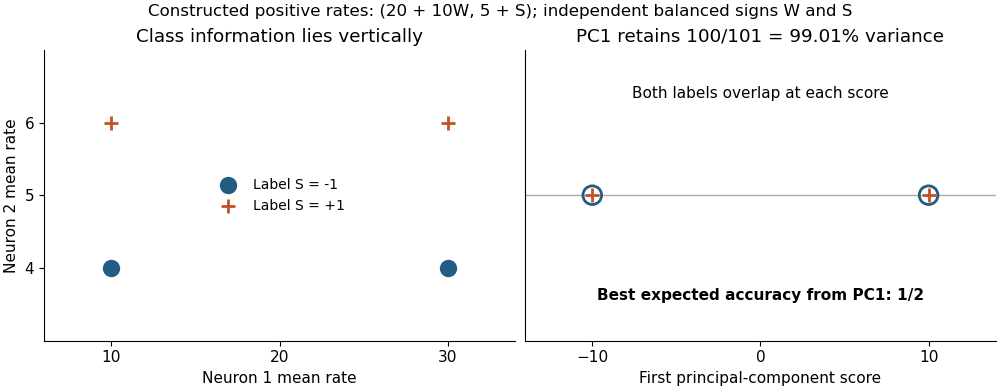

This example also exposes a scaling assumption. Covariance-based PCA emphasizes large-variance coordinates; standardization changes that objective and may increase the influence of noisy low-rate cells. Neither preprocessing choice is automatically correct. Behaviorally relevant information may lie in a small-amplitude direction, in precise spike timing lost by binning, or in correlations not retained by a rate-only summary. Dimensionality must therefore be evaluated against decoding, reconstruction and the scientific question separately.
Byron M. Yu and colleagues' 2009 Gaussian-process factor analysis combined temporal smoothing and dimensionality reduction in a probabilistic framework. Its demonstration used 61 simultaneously recorded macaque premotor and motor neurons during reaching. It shows a method for estimating single-trial trajectories, not direct evidence that episodic memories have the same dimensional structure.[ref]
Gaussian-process factor analysis for low-dimensional single-trial analysis of neural population activity by Byron M. Yu and others. 2009, observation model, temporal priors and motor-recording demonstration
In a linear observation model , the noise and latent temporal assumptions matter. A Gaussian observation approximation can be imperfect for sparse counts; independent residual errors can misassign shared fluctuations; a smooth temporal prior can suppress abrupt transitions. Trial averaging can manufacture a smooth path while concealing different single-trial paths. A useful low-dimensional description must also generalize beyond the sampled cells, session and task: unrecorded populations may encode variables absent from the fitted coordinates.
Latent axes require care as well. In , an orthogonal rotation gives the identical reconstruction through and , because . Reconstruction alone therefore cannot label one axis a unique psychological process. Model priors and constraints can restrict this ambiguity. Similarly, attractive geometry does not establish intrinsic dynamics: unobserved inputs, behavior or the analysis itself may shape the apparent trajectory. If a true dynamical state is claimed, the retained coordinates should predict relevant future activity under a specified model, not merely provide a convenient picture.
Validation should choose dimension and preprocessing within training data, then assess held-out trials or sessions and, where appropriate, held-out neurons. Behavioral labels must be kept out of unsupervised fitting decisions used to claim independent prediction. Comparing multiple dimensions and reporting uncertainty is more informative than selecting the most compelling two-dimensional plot. A reduced representation can support a useful decoder without being a complete causal explanation of the circuit.
Low-dimensional state spaces are testable approximations whose value depends on retained information, model fit and generalization. The projection, scaling, temporal and sampling assumptions should remain explicit, especially when a high-variance view is being interpreted as the mechanism of episodic memory.
Articles by others on the same topic
There are currently no matching articles.