Advanced options, practical training and optional project or dissertation combinations; BA exit after three years.
Part II advanced option in the held 2022 papers. The source examination is shared by the psychology (experimental) course of the University of Oxford and the psychology, philosophy and linguistics course of the University of Oxford.
Solutions to all six options in this undergraduate Part II paper. The cover identifies the Second Public Examination; the Part II classification follows the audited paper record.
Phonology and syntax usually show a left-hemisphere bias, whereas semantic processing depends on a more bilateral system with task-dependent asymmetries. None is confined absolutely to one cerebral hemisphere, and lateralisation of an experimental contrast is not equivalent to localisation of a representation. Phonology concerns structured sublexical units, semantics concerns meaning, and syntax concerns relations that organise words into sentences. These processes interact, so tasks must isolate the relevant contrast rather than merely require language.
Historical lesion observations motivated left language dominance, but their anatomical interpretation needs care. Modern MRI of Paul Broca's preserved cases showed damage extending beyond the conventional cortical region named after him. Severe impaired speech after a left lesion therefore supports lateralisation without proving that a small superficial patch alone constitutes the speech system. Large vascular lesions can also damage connections between surviving regions.[ref]
Paul Broca's historic cases by Nina F. Dronkers and others. Brain 130, 1432–1441; high-resolution MRI of preserved historical brains
For phonological processing, Robert J. Zatorre and colleagues used PET while participants judged different attributes of the same speech material. Phonetic discrimination increased left inferior-frontal activity, whereas pitch discrimination recruited right prefrontal regions; acoustically matched speech engaged secondary auditory cortices bilaterally. Holding the signal relatively constant while changing the decision supports functional differentiation beyond a contrast between unrelated stimuli. It does not show that all phonological representations reside in inferior frontal cortex: articulatory recoding, attention and decision demands can contribute to the phonetic contrast.[ref]
Lateralization of phonetic and pitch discrimination in speech processing by Robert J. Zatorre and others. Science 256, 846–849; ten-volunteer PET, matched syllables and phonetic versus pitch instructions
The distinction matters because speech perception begins with bilateral auditory analysis, whereas selecting, sequencing or rehearsing phonological forms can have a stronger left bias. Impairment of repetition after damage to a dorsal language pathway and comprehension after other damage constrain different transformations. A deficit in producing a phoneme is not automatically a deficit in recognising it. Familiarity with a sound pattern and its linguistic role can also alter the task, so acoustic speed or frequency alone cannot define phonology.
Semantic processing illustrates why a leftward verbal-task result can conceal bilateral representational resources. In Gorana Pobric's rTMS experiment, perturbing either temporal pole slowed semantic associations for words and pictures while a perceptual comparison was spared; stimulation of a control site did not produce the same semantic effect. This supports a contribution from both anterior temporal lobes across input formats. It does not require identical response profiles throughout both lobes or imply that semantic retrieval and selection are entirely bilateral.[ref]
Amodal semantic representations depend on both anterior temporal lobes by Gorana Pobric and others. Neuropsychologia 48, 1336–1342; left/right temporal-pole rTMS, verbal/pictorial semantic association and perceptual control
Verbal naming places additional demands on lexical retrieval and speech production. Consequently, stronger left activity in naming than in passive picture viewing can reflect access and output as well as conceptual knowledge. Conversely, right-sided involvement in nonverbal meaning does not establish a separate nonlinguistic semantic store. Comparisons should separate semantic association from perceptual similarity and control both response requirements and difficulty. Lesion and perturbation results help adjudicate whether an activated region contributes to the task.
For syntax, lesion studies and functional imaging converge on a predominantly left frontotemporal network, rather than a single grammar centre. Evelina Fedorenko's individual-localisation study showed language-selective and domain-general regions next to one another within the anatomical territory called Broca's area. Averaging across people can merge them. Thus, an inferior-frontal response to a hard sentence may reflect language processing, domain-general control or both; independent functional localizers and nonlinguistic controls improve interpretation.[ref]
Language-Selective and Domain-General Regions Lie Side by Side within Broca's Area by Evelina Fedorenko and others. Current Biology 22, 2059–2062; individual functional localization and cross-domain response profiles
Corianne Rogalsky's lesion study compared sentence-picture matching and plausibility judgments in 66 patients. The distribution of syntactic-comprehension impairment implicated a wider left-hemisphere system and challenged a simple equation between Broca's area damage and agrammatic comprehension. Convergence across tasks is useful because picture matching also demands visual analysis and response selection, while plausibility can recruit semantic expectations. Neither behavioural label makes the task syntactically pure.[ref]
The Neurobiology of Agrammatic Sentence Comprehension by Corianne Rogalsky and others. Journal of Cognitive Neuroscience 30, 234–255; 66-patient sentence-picture matching, plausibility judgment and lesion mapping
Sentence comprehension in Japanese and Japanese Sign Language also showed left-dominant frontal and temporoparietal responses across sensory conditions. This directly addresses hemispheric comparisons, although comprehension versus nonword detection is not a pure assay of syntax.[ref]
Sign and speech: amodal commonality in left hemisphere dominance for comprehension of sentences by Kuniyoshi L. Sakai and others. Brain 128, 1407–1417; JSL/Japanese comprehension versus sentential non-word detection across Deaf/CODA/hearing groups
A quantitative laterality index can summarise an explicitly defined response. For nonnegative left and right measurements with ,It ranges from to , but depends on baseline, threshold and region selection. Responses and have the same index despite different total responses. If left activity falls from to while right activity remains , the index becomes zero without any right recruitment. These are illustrative values, not imaging observations. Negative contrasts need a separately justified convention.
The most convincing evidence therefore combines within-person process contrasts, unilateral perturbations or lesions, and converging measurements of behaviour and neural responses. It also describes individual variation instead of assuming that every participant has the population-average pattern. The justified conclusion is graded functional asymmetry within interacting networks: strongest left biases for many phonological and syntactic operations, bilateral conceptual contributions, and substantial dependence on task and representation level.
Basal ganglia abnormalities plausibly contribute to some developmental speech and language disorders, especially through motor sequencing and learning, but the evidence does not establish a single basal-ganglia cause across diagnoses. A causal account must specify the disorder, the affected computation and how an alteration in a circuit produces that impairment. Childhood apraxia of speech, developmental language disorder and stuttering are different phenotypes; difficulty with speech output does not by itself identify a grammatical deficit.
The basal ganglia participate in loops with cerebral cortex and thalamus. Such circuits could support selecting, initiating and learning sequences, including the rapid articulatory transitions needed for speech. A plausible mechanism is impaired acquisition or reliable initiation of a learned motor sequence, rather than storage of every word or syntactic rule in the striatum. This gives testable predictions about skill learning, nonword repetition and sensitivity to external timing cues. General plausibility, however, does not establish which circuit is responsible in an individual child.
The KE family supplied a particularly informative genetic case. Cecilia S. L. Lai and colleagues identified an FOXP2 alteration segregating with severe speech and language impairment, together with an independent case in which a chromosome translocation disrupted the same gene. The phenotype included major problems in coordinated orofacial sequencing alongside broader language difficulties. This strengthens a causal connection between the gene and development of the phenotype. It does not isolate the anatomical route: a transcription factor can alter several developing systems, and the family is not a representative sample of every developmental language disorder.[ref]
A forkhead-domain gene is mutated in a severe speech and language disorder by Cecilia S. L. Lai and others. Nature 413, 519–523; KE-family cosegregation and independent chromosome-translocation case
Kate Watkins's MRI study compared affected family members, unaffected relatives and controls. Voxel-based morphometry identified abnormalities in multiple motor- and speech-related regions; targeted volumetry confirmed reduced caudate volume bilaterally. Relationships with oral praxis and nonword repetition made the caudate result functionally relevant. The unaffected relatives provide a valuable comparison, but an anatomical correlation cannot establish that caudate reduction alone mediates the gene's effects. Multiple abnormalities and correlated behavioural measures make that inference underdetermined.[ref]
MRI analysis of an inherited speech and language disorder: structural brain abnormalities by Kate Watkins and others. Brain 125, 465–478; affected/unaffected KE-family members, matched controls, VBM and caudate volumetry
Animal experiments move beyond an association between a human scan and a symptom. Matthias Groszer and colleagues studied mice with a corresponding alteration of the FOXP2 orthologue. Heterozygotes had relatively preserved baseline motor abilities but impaired motor-skill learning, with abnormal plasticity in striatal and cerebellar circuits. The distinction between baseline performance and improvement with practice supports a learning-related mechanism. Yet a mouse motor task is not human syntax or learned speech, and the cerebellar findings themselves argue against an exclusively basal-ganglia interpretation.[ref]
Impaired synaptic plasticity and motor learning in mice with a point mutation implicated in human speech deficits by Matthias Groszer and others. Current Biology 18, 354–362; heterozygote motor-skill learning and striatal/cerebellar plasticity
Stuttering offers a partially independent line of evidence. Soo-Eun Chang's study combined resting-state fMRI and probabilistic tractography in children aged 3–9. Differences involved basal-ganglia–thalamocortical and auditory–motor networks, including weaker connectivity between putamen and supplementary motor regions. Studying young children reduces the extent to which decades of compensatory speaking strategies can explain the result. Nevertheless, the measurements were taken after symptoms began. Correlated activity at rest is not direct synaptic coupling, and tractography does not demonstrate the direction or necessity of a physiological connection.[ref]
Neural network connectivity differences in children who stutter by Soo-Eun Chang and others. Brain 136, 3709–3726; children aged 3–9, resting-state fMRI and probabilistic tractography
Improved fluency with an external pace would be compatible with compensation for impaired internal timing, but it would not uniquely identify a basal-ganglia abnormality. External cues also change attention, anticipation, auditory feedback and task structure. Similarly, a group difference in a procedural-learning task can result from poor motor execution, working memory or comprehension of instructions. The critical comparison separates learning rate from initial accuracy and uses nonverbal tasks, matched feedback and retained skill after a delay.
Several causal alternatives remain. A shared developmental influence may alter both caudate structure and cortical language function. Reduced language practice may itself change network measurements. A cortical or white-matter abnormality may produce downstream striatal differences. An experimentally supported gene-to-phenotype relationship does not automatically identify every intermediate step in a proposed gene-to-basal-ganglia-to-language chain.
A stronger programme would combine prospective measurements before or close to onset, repeated follow-up of persistence and recovery, detailed speech versus language phenotyping, and independent motor-learning measures. Analyses should control age, hearing, motion, general motor ability and broader development, and assess multiple network regions. Selective perturbations in appropriate models can test mechanisms, while their behavioural scope must remain explicit. The strongest claim is that distributed corticostriatal learning circuits are one important contributor in some phenotypes; neither a universal basal-ganglia lesion model nor a language-specific function of FOXP2 follows from the available evidence.
Primary progressive aphasia has helped dissociate syntactic impairment from loss of word meaning, phonological memory and motor speech, and has implicated a left frontotemporal network and its dorsal connections. Its contribution is substantial, but degeneration is distributed and evolving, so it does not yield a one-region map of syntax. PPA is a syndrome in which progressive language impairment is initially the principal clinical problem; the variant label should follow a detailed assessment rather than substitute for one.
In Maria Luisa Gorno-Tempini's 31-patient study, the nonfluent group combined speech apraxia and complex-syntax difficulties with left inferior-frontal and insular atrophy. Semantic impairment was associated with anterior temporal damage, while a logopenic pattern involved left posterior temporal and inferior parietal regions. Comparing variants showed that slow speech, reduced sentence comprehension and impaired naming need not share a single cause. The study established useful contrasts, not perfectly isolated syndromes or a unique pathology for each language deficit.[ref]
Cognition and anatomy in three variants of primary progressive aphasia by Maria Luisa Gorno-Tempini and others. Annals of Neurology 55, 335–346; 31 patients, detailed language assessment and variant-specific VBM
The central methodological gain is to test syntax rather than infer it from fluency. A person who cannot execute a well-planned utterance may still comprehend grammatical relations. Conversely, fluent production may conceal impaired thematic-role assignment. Compare short, reversible sentences whose meaning cannot be guessed from ordinary plausibility, vary grammatical construction while matching word knowledge, and measure both comprehension and production. Long sentences alone are insufficient because phonological working memory and attention also determine performance.
For example, an illustrative active/passive pair can reverse which noun is the agent while preserving familiar words. A sentence-picture matching task can offer pictures with the same participants but reversed roles. Failure on the noncanonical construction after single-word comprehension is verified is more informative about syntactic dependencies than failure to repeat a long unfamiliar sentence. These proposed controls do not make visual choice, memory demands or response selection disappear; they make the alternatives measurable.
Stephen M. Wilson's 2010 fMRI study examined eight patients with nonfluent variant primary progressive aphasia during sentence comprehension. Unlike controls, patients did not show the usual complex-versus-simple modulation in atrophic posterior inferior-frontal cortex, while a mid-superior-temporal region retained complexity modulation. A more anterior frontal region was recruited, but that recruitment did not support successful syntactic processing. This separates the presence of activation from normal computational responsiveness. The small, heterogeneous sample and altered structure limit inferences from a missing contrast.[ref]
Neural correlates of syntactic processing in the nonfluent variant of primary progressive aphasia by Stephen M. Wilson and others. Journal of Neuroscience 30, 16845–16854; sentence-picture matching, syntactic complexity and response-time modulation in eight patients
The subsequent tract study added a network constraint. In 27 patients, damage measured with diffusion imaging in the left superior longitudinal/arcuate system was associated with impaired syntactic comprehension and production, beyond the cortical-atrophy contribution included in the analysis. Comparable associations were not found for the ventral tracts examined. This supports the importance of dorsal frontotemporal communication under those tasks. It does not show that ventral connections never contribute to sentence meaning or that a diffusion-derived tract is exclusively syntactic.[ref]
These findings help distinguish a network-disconnection account from a narrowly local account: surviving frontal cortex may fail because temporal inputs or long-range interactions are disrupted. They also motivate looking for separable grammatical computations rather than a single complexity variable. Hierarchical dependencies, maintaining a noun's features, assigning roles and selecting an overt response need not have identical neural requirements.
Converging evidence outside PPA is necessary. Corianne Rogalsky's stroke lesion work relates comprehension to a distributed left system, and her concurrent-articulation experiments show how working-memory demands can contribute to inferior-frontal syntactic contrasts. These observations caution against treating frontal disease, reduced rehearsal and damaged syntax as interchangeable. They do not erase the PPA findings; they sharpen the processes the imaging contrast must explain.[ref]
The Neurobiology of Agrammatic Sentence Comprehension by Corianne Rogalsky and others. 2018, sentence-picture matching and plausibility tasks with lesion-symptom mapping
[ref]Broca's area, sentence comprehension, and working memory by Corianne Rogalsky and others. Frontiers in Human Neuroscience 2, 14; concurrent articulation and finger tapping during syntactic contrasts
PPA also has characteristic limitations. Atrophy covaries across connected areas and worsens with disease severity; a regional correlation can reflect a broader disease gradient. Clinical groups may be defined partly by the impairment under investigation, so rediscovering that difference is not independent confirmation. Grey-matter volume and fractional anisotropy are indirect measurements, while altered perfusion or tissue loss affects the observed fMRI signal. Statistical adjustment for one anatomical variable cannot guarantee complete separation of these causes.
Longitudinal within-person assessments, repeated controls, individual functional localisation and analyses of both structural and functional connections would strengthen the account. A decisive interpretation should predict which construction becomes impaired, which simpler operations remain intact and how the deficit changes with progression. PPA has made syntax a tractable network-level target by dissociating components and revealing dorsal connectivity requirements; it supports process-specific, convergent explanations rather than a diagnostic label or isolated grammar centre.
There is no secure, universal bilingual advantage in domain-general executive function. There are important benefits of knowing and using two languages, some positive task findings and suggestive associations with cognitive reserve, but these are different claims with different evidential requirements. Bilingualism varies with proficiency, acquisition age, frequency of use and the situations in which languages are switched. A binary label can obscure the experience most relevant to a proposed mechanism.
The executive-control hypothesis begins with competition: using one language while another is available may repeatedly exercise selection and interference control. Transfer to nonlinguistic tasks is plausible, but it is a far-transfer claim, not an automatic consequence of speaking two languages. The account should predict which control operation improves and under which switching experiences, rather than count every faster response as evidence of inhibition.
Ellen Bialystok's three studies of middle-aged and older adults reported smaller Simon interference costs in bilingual participants, with stronger effects in older groups and demanding conditions. In the Simon task, the required response depends on a relevant stimulus feature while an irrelevant spatial location can favour the competing response. Comparing congruent and incongruent trials operationalises conflict. These positive results support a conditional association; nonrandom language histories leave socioeconomic, educational and other selection explanations to be tested.[ref]
Bilingualism, aging, and cognitive control: evidence from the Simon task by Ellen Bialystok and others. Psychology and Aging 19, 290–303; three studies of middle-aged/older adults, congruency costs and working-memory demands
The relevant estimand must be stated. Let for group . A conflict advantage requires , which is a group-by-congruency interaction. Illustratively, monolingual means of ms and bilingual means of ms for congruent/incongruent trials give equal costs of ms. The bilingual group is faster overall, but this example supplies no selective conflict advantage. Accuracy and speed-accuracy trade-offs must also be examined. These numbers are a calculation, not observed study data.
Negative studies are therefore informative rather than disposable exceptions. Kenneth R. Paap and colleagues tested 15 executive-processing indicators across three studies, including Simon, flanker, antisaccade and switching tasks, and did not find a coherent bilingual benefit. Inconsistent cross-task correlations also challenged treating every task's interference score as a stable measure of one general control faculty. This does not prove an exactly zero effect for every bilingual population, but it contradicts a broad, easily expressed advantage.[ref]
There is no coherent evidence for a bilingual advantage in executive processing by Kenneth R. Paap and others. Cognitive Psychology 66, 232–258; three studies, 15 executive-processing indicators, cross-task validity
Child data also constrain generality. Eneko Antón's study used the Attention Network Test in bilingual and monolingual children with careful attention to age and socioeconomic variables, and found no bilingual advantage in the principal attentional measures. A reliable conflict effect within participants verifies that a task manipulation worked; it does not guarantee reliable individual differences or a sensitive group contrast. Measurement reliability and adequate statistical power matter to both positive and negative interpretations.[ref]
Is there a bilingual advantage in the ANT task? Evidence from children by Eneko Antón and others. Frontiers in Psychology 5, 398; child Attention Network Test, socioeconomic and age controls
Selective reporting can make the literature appear more consistent than the completed research. Angela de Bruin and colleagues followed conference abstracts into publication and found that results supporting an advantage were more likely to be published than null or opposing results. This is direct evidence about the research pipeline. It does not invalidate every positive experiment or by itself estimate the true average effect. Preregistration, shared outcomes and publication of null results address the identified bias.[ref]
Cognitive advantage in bilingualism: an example of publication bias? by Angela de Bruin and others. Psychological Science 26, 99–107; conference abstracts 1999–2012 and subsequent publication
A different question concerns later clinical symptoms. Suvarna Alladi's retrospective clinic series contained 648 people with dementia, including 391 bilingual participants, and reported symptom onset about 4.5 years later in the bilingual group after considering several covariates. The result is compatible with cognitive reserve. It is not evidence that bilingualism reduced dementia incidence: all participants already had dementia, and referral, survival, recalled onset and unmeasured life experiences can affect the comparison. Later symptoms also do not necessarily imply less underlying pathology.[ref]
Bilingualism delays age at onset of dementia, independent of education and immigration status by Suvarna Alladi and others. Neurology 81, 1938–1944; retrospective specialist-clinic series, 648 patients, 391 bilingual
A stronger test would measure language experience continuously, recruit groups from the same communities, prespecify a small set of well-measured outcomes and analyse multiple tasks with an explicit measurement model. Longitudinal studies with baseline cognitive performance reduce selection ambiguity; randomised language-learning interventions with active controls test narrower training effects, though short courses do not reproduce lifelong bilingual experience.
Finally, linguistic communication and cultural access are substantive benefits regardless of executive-task results. Metalinguistic awareness and language-specific proficiency are closer to the practised skill than general inhibition, and should be evaluated as separate outcomes. Bilingualism is valuable, but the evidence warrants specific, experience- and task-dependent claims rather than a universal cognitive enhancement or a promise of dementia prevention.
Sign languages recruit much of the left-dominant frontotemporal language network while also engaging modality-dependent visual, parietal and motor systems. The evidence supports shared organisation across modalities more strongly than it proves that the same neural populations contain fully amodal phonological, semantic and syntactic codes. Natural sign languages have conventional sublexical structure and grammar; they are not simply gestures illustrating spoken words.
Brain-lesion evidence provides an important starting point. In Gregory Hickok's study, 19 lifelong signers with unilateral lesions completed single-sign and simple/complex sentence comprehension tasks. Left temporal involvement was associated with substantial impairment across tasks; right-lesion and other groups performed well on the simpler conditions, with more difficulty on complex material. The result argues against assigning language to the right hemisphere merely because signs are visual and spatial. Complex-command performance can also reflect memory, spatial processing or general comprehension demands.[ref]
Role of the left hemisphere in sign language comprehension by Gregory Hickok and others. Brain and Language 82, 167–178; 19 lifelong signers with unilateral lesions and three comprehension tasks
Functional imaging identifies both common and distinct components. Karen Emmorey and colleagues compared sign and speech within native hearing ASL–English bilinguals using PET for picture naming and fMRI for sentence comprehension. Shared language-related responses coexisted with greater parietal recruitment for signing and different temporal responses for speech. The within-person comparison reduces confounding between hearing status and language modality. It also makes clear that motor output, visual movement and auditory feedback contribute to the total activation pattern.[ref]
How sensory-motor systems impact the neural organization for language: direct contrasts between spoken and signed language by Karen Emmorey and others. Frontiers in Psychology 5, 484; within-native-bimodal-bilingual PET naming and fMRI semantic-anomaly detection
An amodal representation is stronger than a common anatomical location: it should capture relevant information independently of how that information enters or leaves the system. A shared inferior-frontal mean response can arise from common control demands, different intermingled populations or the same computation over differently formatted representations. This is the distinction expressed by regional activation does not identify a neural code. Conjunction of significant maps is useful evidence for shared territory, but cannot by itself establish identity of the represented information.
For phonology, the relevant units need not be sounds. A sign can be distinguished by handshape, location and movement, just as speech forms can differ in sublexical features. Mairéad MacSweeney's study compared BSL location judgments with English rhyme judgments using picture-based tasks. A partly shared left frontoparietal network was modulated by language, hearing status and age of first acquisition. Thus sublexical form analysis can share network resources across modalities, while the differences argue against an entirely invariant implementation. Delayed access to a first language must be separated from deafness itself.[ref]
Phonological processing in deaf signers and the impact of age of first language acquisition by Mairéad MacSweeney and others. NeuroImage 40, 1369–1379; English rhyme versus BSL location judgments, hearing status and acquisition age
A stronger phonological test would match response selection and difficulty, contrast legal with carefully controlled sublexical combinations, and include nonlinguistic hand-movement judgments. Even successful cross-modal decoding would need interpretation: sign handshape and spoken sound have no automatic one-to-one physical mapping. An abstract combinatorial relation could be shared without every modality-specific feature having an amodal counterpart.
For semantics, signs and spoken words can access the same conceptual relations while having different forms. Emmorey's within-bilingual comprehension experiment used detection of semantic anomalies and identified overlapping frontotemporal responses with modality-dependent components. This supports common meaning-related processing, although anomaly detection also requires monitoring and a decision. A more specific test would train a decoder on one modality and test concept identity in the other, holding out stimuli and separating meaning from the picture, response or decision used to measure it.[ref]
How sensory-motor systems impact the neural organization for language: direct contrasts between spoken and signed language by Karen Emmorey and others. 2014, within-bilingual fMRI semantic-anomaly detection and conjunction/direct contrasts
For syntax, Kuniyoshi L. Sakai's comparison of Japanese Sign Language and Japanese sentences found common left-dominant frontal and temporoparietal recruitment for comprehension. Comparing sentence comprehension with sentential nonword detection improved specificity beyond passive sign viewing. Different participant groups and potentially different demands nevertheless prevent inferring identical neuronal syntax codes. Spatial referent tracking, prosody and grammatical relations may draw on partly overlapping resources rather than a single modality-free operation.[ref]
Sign and speech: amodal commonality in left hemisphere dominance for comprehension of sentences by Kuniyoshi L. Sakai and others. Brain 128, 1407–1417; JSL/Japanese comprehension versus sentential non-word detection across Deaf/CODA/hearing groups
The best design combines native Deaf signers, hearing native signers and hearing nonsigners where appropriate, with careful measurement of first-language access and proficiency. Nonlinguistic biological motion, matched visual complexity, meaningful versus meaningless sequences and matched response demands help identify what each contrast removes. Individual functional localisation, lesion convergence and cross-modal multivariate tests are stronger together than any activation map alone. A failed decoder does not establish separate representations if measurement noise or anatomical alignment prevents generalisation.
The clearest conclusion is a language network that can develop for signed or spoken input, with left temporal and inferior-frontal contributions to linguistic processing and modality-sensitive interfaces. Amodal conceptual or combinatorial operations are plausible; exact representational identity for every component remains a stronger, incompletely established claim.
Right-hemisphere activity after left-hemisphere damage can be compensatory, inefficiently helpful, maladaptive or incidental. Its role depends on the region, task, residual left network and recovery stage; a group activation map cannot decide among those possibilities. Functional compensation means that the recruitment supports performance in the damaged system. It need not restore normal performance or reproduce the computation formerly performed on the left.
Longitudinal evidence immediately challenges a uniform interpretation. Dorothee Saur and colleagues repeatedly imaged auditory comprehension in 14 patients after left middle-cerebral-artery stroke. Initially weak activation was followed by increased bilateral activity with a prominent right inferior-frontal homologue response, and later by a shift towards left language areas alongside further recovery. The trajectory makes time after stroke central to interpretation. Correlation between activation and improvement is compatible with a contribution to recovery, but can also reflect restored capacity to engage with the task.[ref]
Dynamics of language reorganization after stroke by Dorothee Saur and others. Brain 129, 1371–1384; 14 patients, auditory comprehension and fMRI at three recovery stages
A decrease in left dominance is particularly ambiguous. The laterality index can fall because left activity falls, without right activity increasing. Acute ischemia, diaschisis and altered neurovascular coupling also change the fMRI signal. Matching the task instruction is insufficient if one patient comprehends the sentences and another only attempts them. Accuracy, response time and an independent physiological assessment should therefore accompany the activation contrast.
A maladaptive account proposes that increased activity in a right homologue interferes with useful remaining left function or promotes an inefficient strategy. Interhemispheric inhibition is one candidate mechanism, but cannot be assumed from the fact that the two cerebral hemispheres change differently. Greater right activation among more severely impaired patients could mean that right activity causes impairment; equally, larger left lesions may both worsen performance and make right support more necessary. Statistical adjustment must account for lesion location and disconnection, not simply lesion volume.
Perturbation supplies a more direct test. Lutz Winhuisen and colleagues used PET to select inferior-frontal targets and then disrupted their activity during a semantic task in 11 patients examined within two weeks of stroke. Right-sided stimulation impaired performance in a subset of patients with right IFG activation. This supports a necessary contribution to residual performance in those individuals, even though their language remained less effective than in patients relying more on recovered left function. The result is not evidence that every activated right region is beneficial.[ref]
Role of the contralateral inferior frontal gyrus in recovery of language function in poststroke aphasia by Lutz Winhuisen and others. Stroke 36, 1759–1763; 11 patients within two weeks, PET-guided left/right IFG perturbation
Evidence sometimes presented for maladaptation also needs qualification. Margaret A. Naeser's open study applied repeated right inferior-frontal stimulation to four people with chronic aphasia and reported later picture-naming improvement. Suppression-associated improvement is compatible with a counterproductive component of right activity. Without a randomised sham comparator, however, practice, expectancy and nonspecific intervention effects remain possible; the result is preliminary, not a general treatment rule. An anterior target in chronic aphasia also need not have the same function as a different inferior-frontal site early after stroke.[ref]
A proposed mechanistic study would recruit a sufficiently characterised stroke cohort across prespecified stages, quantify left cortical and tract damage, and measure baseline naming, comprehension and connected speech. Use individual structural imaging and independent functional localisation to identify a right language-related target and a control target. Because an activated voxel can contain mixed functions, site selection should use a relevant contrast, not just the maximum response to any difficult task.
Within each participant, counterbalance a transient perturbation condition with credible sham and an active control, use masked assessment, parallel stimulus sets and a prespecified primary language outcome. Include nonlinguistic reaction and motor tasks to detect general distraction or response slowing. Session spacing should address carryover, and the analysis should model repeated measurements and interactions with stage and residual left-network integrity. Safety screening and consent are integral to a clinical stimulation study; a sample size should be justified from variability and the smallest informative effect, not invented from the exam prompt.
If perturbing the right target worsens language selectively relative to both controls, that supports a currently compensatory role. If it improves language selectively and reproducibly, that supports a maladaptive contribution under those conditions. No behavioural change is inconclusive unless the perturbation was effective and the outcome sensitive. The intervention could spread through the network, so neither sign of effect automatically identifies a local code or proves inhibition of the left hemisphere.
Finally, a treatment trial asks a different question from transient necessity. Randomise a longer intervention against sham with matched speech-language therapy, assess untreated items and everyday communication, and follow durability. Repeated imaging can test whether behavioural improvement accompanies a predicted network change, while avoiding circular selection of patients or outcomes on the same data. The evidence favours conditional, stage- and site-specific right-hemisphere contributions; perturbation with appropriate controls, followed by a separate clinical trial, can distinguish useful functional compensation from harmful recruitment more convincingly than activation alone.
Part II advanced option in the held 2022 papers. The source examination is shared by the psychology (experimental) course of the University of Oxford and the psychology, philosophy and linguistics course of the University of Oxford.
Solutions to all six essay options in the sensing and perceiving light, colour and materials course of the University of Oxford examination of 26 May 2022. Both printed parts of question 5 have separate solutions; its combined answer and each other essay are below 1,800 words. The scientific evidence used predates the examination. Source release: released examination archive, member a16861w1.pdf. Original figures illustrate stated mathematical models and do not reproduce examination diagrams or participant data.
Post-receptoral processing compares cone signals, organizes those comparisons across space and time, and uses them to represent surfaces and objects. Three receptor classes do not imply three neurons labelled with three color names. A complete answer must distinguish the information available at the receptors from its neural transformation and its perceptual interpretation.
The principle of univariance supplies the starting constraint. For one cone class, an absorption-dependent response does not identify wavelength independently of intensity. Comparing differently sensitive classes makes chromatic information available. Relative to an adapted background, cone contrasts can be written , where is the background catch. This representation separates a change relative to the prevailing input from the raw number of absorbed photons. It is a useful coordinate system, not a claim that every neuron implements this exact formula.
Retinal circuitry immediately transforms the signals. Light hyperpolarizes cone cells and changes their transmitter release. ON and OFF bipolar pathways respond differently to changes in cone output, while horizontal and amacrine circuitry contribute spatial and temporal interactions. Retinal ganglion cells transmit spike trains rather than simply forwarding a cone's voltage. Their center–surround organization compares regions, so chromatic and spatial structure are already intertwined. Near the central retina, the midget pathway can oppose an L- or M-dominated center to a surround containing other cone input. The same circuitry can carry information useful for fine spatial structure and for chromatic contrast; these are not necessarily separate wires.
A distinct S-cone route illustrates the anatomical specificity. Dennis M. Dacey and colleagues combined physiological characterization with identification of ganglion-cell morphology in primate retina, finding that the S-ON opponent response belonged to a small bistratified ganglion-cell type rather than simply another midget cell.[ref]
The blue-on opponent pathway in primate retina originates from a distinct bistratified ganglion cell type by Dennis M. Dacey and others. Nature 367, 731–735; physiological and morphological identification
This supports parallel circuits with different cone combinations. Calling the pathway “blue-on” is shorthand for its stimulus response, not proof that the cell itself produces a unique blue experience.At a simplified computational level, an achromatic-like combination and two chromatic combinations can be represented asThis invertible three-channel opponent transform reorganizes three coordinates rather than creating additional independent spectral information. Their matrix has determinant , so the transform is invertible: , and . Actual weights depend on cell, location, adaptation and stimulus conditions. This algebra is an illustrative opponent transform, not a fitted retinal wiring diagram or a complete perceptual color space.
The lateral geniculate nucleus preserves several parallel retinal pathways while also participating in cortical interactions. A. M. Derrington and colleagues studied macaque geniculate cells with gratings whose luminance and chromatic modulation could be varied independently on a calibrated color television display. Finding directions that changed cone stimulation without driving a cell constrained its linear cone weights.[ref]
Chromatic mechanisms in lateral geniculate nucleus of macaque by A. M. Derrington and others. J Physiol 357, 241–265; null-plane method and chromatic stimulus space
For a nonzero linear weight vector, the zero-response contrasts obey , defining a chromatic null plane. A null response therefore tests a relation between inputs, rather than merely assigning the cell a preferred color name. The resulting opponent directions need not coincide with human unique hues.Cortical processing adds more complex spatial comparisons. Bevil R. Conway mapped cone inputs to color-responsive neurons in alert macaque V1 using cone-isolating spots and eye-position-corrected reverse correlation. Some cells combined chromatic opponency with opposite tuning in adjacent spatial subregions.[ref]
Spatial Structure of Cone Inputs to Color Cells in Alert Macaque Primary Visual Cortex by Bevil R. Conway. J Neurosci 21, 2768–2783; receptive-field mapping and double opponency
Such double-opponent cells can respond strongly to a chromatic boundary while responding less to a spatially uniform change. This offers a mechanism useful for separating surface differences from shared illumination changes. It does not establish that one V1 population alone solves color constancy under arbitrary scenes.Further processing must relate color to form, illumination, material and the current task. The same cone contrasts can be interpreted differently in a shadow, highlight or translucent object. Surface color judgments, discrimination thresholds and color naming therefore constrain different computations. Feedback and attention can influence which information is selected, while learning can alter how a signal is interpreted or normalized. A lesion or imaging response can constrain contributions to those tasks, but an area responsive to color is not automatically an isolated “color center.”
The strongest picture is consequently a hierarchy of interacting computations: cone-specific signals, opponent and spatial filtering, combinations tuned to richer image structure, and object-level judgments. Trichromatic sampling limits spectral information; later processing determines how that information supports boundaries, stable surface appearance and behavior.
Sensitivity adjustments occur at several stages and over several timescales. They reveal adaptive gain control and flexible reference points, but no single aftereffect uniquely identifies one anatomical site. Changes in threshold, apparent hue, an achromatic setting and a receptor current must be distinguished before explaining them with one adaptation mechanism.
At the receptor level, a finite photocurrent range has to represent environments with very different mean light levels. Julie L. Schnapf and colleagues measured membrane currents from individual macaque cone outer segments. Responses to a maintained light step had an initial component followed by a smaller steady response, and a steady background reduced sensitivity to an added weak flash. This desensitization was distinguishable from loss of pigment through bleaching.[ref]
Visual transduction in cones of the monkey Macaca fascicularis by Julie L. Schnapf and others. J Physiol 427, 681–713; outer-segment recording, steps, backgrounds and bleaching comparisons
Direct recording establishes that some gain adjustment occurs before any color name, decision or cortical object representation. The preparation is macaque tissue, and a measured cone current is not identical to a human appearance judgment.An idealized normalization model illustrates the benefit. If a mechanism's incremental gain is proportional to , maintaining a fixed response increment requires . At high backgrounds this gives approximately constant fractional contrast , a Weber-like regime. It should not be confused with a universal law across all intensities. Under a known-background Poisson counting model with mean , the noise standard deviation is ; a small increment has signal-to-noise ratio approximately . A fixed signal-to-noise criterion then gives fractional threshold proportional to instead. The two predictions derive from different assumptions about what limits performance.
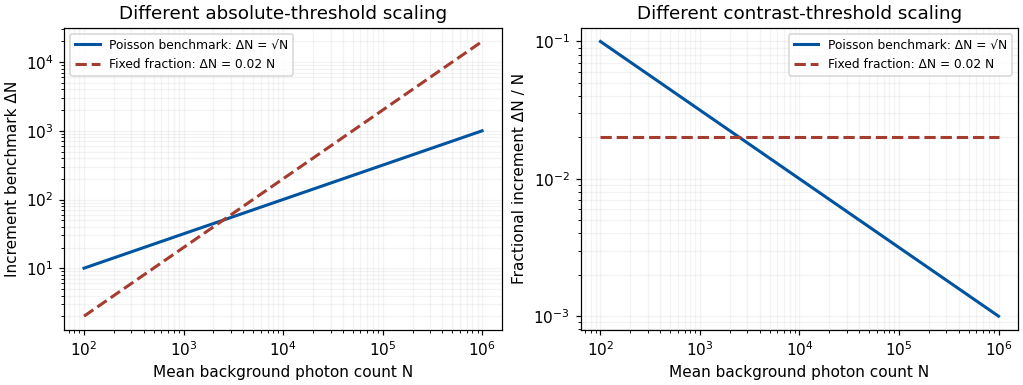
Original Poisson-counting and fixed-fraction threshold benchmarks; arbitrary criterion constants, not measured human adaptation data
. Details. Mean adaptation and contrast adaptation also differ. A diagonal cone-gain model replaces by , with gains related to recent stimulation. It can reduce the effect of a persistent chromatic shift in the illuminant. If the signal changes approximately as , choosing cancels that change. This is exact only for the assumed channelwise scaling; real spectral illuminant changes need not transform every surface's catches by the same three factors.
To test adjustments beyond mean cone excitation, experiments can modulate color around an unchanged time average. John Krauskopf and colleagues found direction-selective threshold elevation after temporal chromatic or luminance modulation, supporting separable adaptable mechanisms for particular directions near threshold.[ref]
Cardinal directions of color space by John Krauskopf and others. Vision Res 22, 1123–1131; selective threshold elevation for chromatic and luminance directions
Michael A. Webster and colleagues then measured appearance after adaptation to modulation along different color-space directions. A color monitor, a modulated adapting field and asymmetric appearance matches allowed testing effects beyond detection thresholds. Appearance shifted away from the adapting direction, including directions intermediate to the simplest cardinal color directions.[ref]Changes in colour appearance following post-receptoral adaptation by Michael A. Webster and others. Nature 349, 235–238; constant-mean modulation and asymmetric matching
Thus a three-independent-channel account sufficient for some threshold results was not sufficient for all suprathreshold appearance changes. Constant mean catches constrain a simple mean-receptor explanation, but do not prove that all receptor nonlinearities have been removed.Longer experience changes reference points too. Jay Neitz and colleagues altered chromatic experience with colored filters over days and measured unique yellow settings. Shifts persisted for one to two weeks after filter use ended.[ref]
Color perception is mediated by a plastic neural mechanism that is adjustable in adults by Jay Neitz and others. Neuron 35, 783–792; altered chromatic experience and persistent unique-yellow changes
Persistence after removing the immediate adapting stimulus demonstrates more than an instantaneous receptor response. It supports experience-dependent normalization without showing that a color category or verbal label has been rewritten. Any interocular transfer must also be measured explicitly; duration alone does not identify cortex.A natural perturbation extends the range to months. Peter B. Delahunt and colleagues followed achromatic settings before and after removal of cataractous lenses. Removal greatly changed short-wavelength input; settings continued to readjust over roughly three months, whereas chromatic discrimination recovered much faster.[ref]
Long-term renormalization of chromatic mechanisms following cataract surgery by Peter B. Delahunt and others. Vis Neurosci 21, 301–307; longitudinal achromatic settings and comparison with discrimination
An achromatic setting compensates for a perceived tint, so its physical shift should not be mistaken for a same-direction tint in appearance. The findings indicate distinct adjustment timescales. They are observational evidence with a changing optical input, not a randomized isolation of one neural site or a general treatment recommendation.These studies support a multilevel experimental strategy. Measure receptor responses, detection thresholds and appearance separately; manipulate mean and contrast independently; test spatial specificity, interocular transfer and recovery. Control exposure, eye position, stimulus calibration, response criterion and learning. A loss of sensitivity can reflect adaptation that preserves dynamic range rather than damage, and stable appearance can coexist with changed receptor inputs. Conversely, perfect compensation is not guaranteed.
Adaptation is a family of adjustments serving different constraints. Its most informative use is to distinguish which signal statistics, stages and reference points change, rather than treating every aftereffect as evidence for one fatigued color channel.
Photoreceptors determine which optical differences are available for vision, with what noise and spatial–temporal precision. They strongly constrain light, color and material perception without uniquely determining the eventual percept. Later processing can exploit context and action, but cannot recover arbitrary information already lost in receptor sampling.
For cone class , a simplified expected quantum catch over one sampling interval iswhere is the incident photon-number spectrum at the receptor, including ocular filtering, and effective absorption probability. An energy spectrum requires conversion by photon energy before this counting interpretation. The integral is many-to-one: equal catches do not imply equal spectra. The principle of univariance means that an individual receptor does not independently report photon wavelength and number.
Multiple receptor classes provide comparisons, but ordinary cone-mediated trichromacy still samples a spectral distribution with only three class responses at a specified location and time. In a discretized model, with three rows and more than three spectral bins. The matrix has a nonzero kernel. Around a strictly positive spectrum, a sufficiently small perturbation in that kernel preserves nonnegative intensities while leaving all three catches unchanged. This derives the possibility of metamers; it does not mean all real-world spectral differences are unobservable under every condition. Altering illumination, observer or spatial–temporal context can break a particular match.
Sensitivity also has a photon budget. In an ideal Poisson model, mean catch has variance , so relative counting uncertainty is . Gathering more photons reduces this uncertainty but requires a larger effective collecting area or more integration time. Temporal averaging can obscure rapid change, while spatial pooling can sacrifice fine detail. Receptor and downstream noise add limitations beyond shot noise. Rods support low-light detection with different sensitivity and pooling from cone cells; if only one receptor class provides usable signals, wavelength–intensity ambiguity cannot be resolved by comparisons within that class. Mesopic vision, where rods and cone cells can both contribute, is not captured by declaring all dim-light vision achromatic.
The receptor array is also uneven. Christine A. Curcio and colleagues mapped rods and cone cells in whole-mounted human retinas using microscopic counts. Cone density was highest centrally and fell strongly with eccentricity, while the rod distribution differed and the central foveal region was rod-free.[ref]
Human photoreceptor topography by Christine A. Curcio and others. J Comp Neurol 292, 497–523; methods and photoreceptor density maps
Thus acuity and sensitivity should not be treated as uniform over the visual field. Optical blur and downstream sampling constrain performance alongside receptor spacing. The S-cone mosaic is sparser than the combined L/M mosaic, so equal spatial detail cannot simply be assumed for all chromatic signals.A regular one-dimensional model of photoreceptor sampling makes one limitation explicit. Sampling a sinusoid at spacing gives identical samples for frequencies and , because the added phase at sample is . Restricting a real signal to frequencies below avoids this basic aliasing ambiguity. Real retinal mosaics are two-dimensional, irregular and optically filtered, so this is a benchmark rather than a literal universal retinal cutoff. Fine material texture can consequently disappear or alias even when coarser color and shape remain visible.
Individual variation changes the sampling system itself. Heidi Hofer and colleagues' adaptive-optics measurements showed large L:M cone-ratio variation among observers passing normal color tests.[ref]
Organization of the Human Trichromatic Cone Mosaic by Heidi Hofer and others. J Neurosci 25, 9669–9679; retinal densitometry and corrected abstract
Gabriele Jordan and colleagues found behavioral evidence consistent with an extra chromatic dimension in one of a selected set of carriers with potential extra pigment diversity, rather than in every carrier.[ref]The dimensionality of color vision in carriers of anomalous trichromacy by Gabriele Jordan and others. J Vis 10(8):12; behavioral and genetic comparisons
These findings separate receptor availability from downstream use: receptor counts and pigment variants constrain possibilities without directly specifying appearance or functional dimensionality.Material perception adds an inverse problem. For a matte surface under a single simplified illuminant, the reflected photon spectrum is proportional to , so catches mix illumination and surface reflectance. The same catches can therefore arise from different surfaces, even before considering three-channel spectral compression. Specular reflection, subsurface scattering, translucency and fluorescence introduce further dependencies on direction, geometry or wavelength conversion. Three cone values cannot independently label every physical material property.
Nevertheless, humans can exploit cues across space, movement and time. Highlights change with viewpoint; texture and shading constrain shape; surrounding surfaces provide illumination evidence. Such information can reduce ambiguity under useful assumptions, while metamerism and sampling limits remain. Receptor properties define an information bottleneck and a set of trade-offs. Successful material recognition depends on combining what survives that bottleneck with contextual constraints, not on receptors directly measuring “wood,” “metal” or intrinsic surface color.
L, M and S describe the relative spectral sensitivities of cone classes. Calling them red, green and blue confuses receptor sampling with the color appearance constructed from comparisons and context. The shorthand also wrongly suggests three narrow, nonoverlapping detectors or the primaries of a display.
First, each class has a broad sensitivity curve. A long-wavelength-sensitive cone responds to many wavelengths, and its sensitivity maximum is not a unique red stimulus. L- and M-cone sensitivities overlap extensively, while S cone cells are relatively more sensitive at shorter wavelengths. Light at one wavelength can therefore excite more than one class. Andrew Stockman and colleagues derived L- and M-cone sensitivity estimates using color-matching data and measurements from observers of known pigment genotype. Their analysis emphasizes broad overlap and the need for isolation procedures to measure one class without contamination from others.[ref]
The spectral sensitivities of the middle- and long-wavelength-sensitive cones derived from measurements in observers of known genotype by Andrew Stockman and others. Vision Res 40, 1711–1737; spectral-sensitivity measurements and cone fundamentals
Exact curves depend on pigment variant and optical filtering, so the letters denote relative classes rather than three invariant color labels.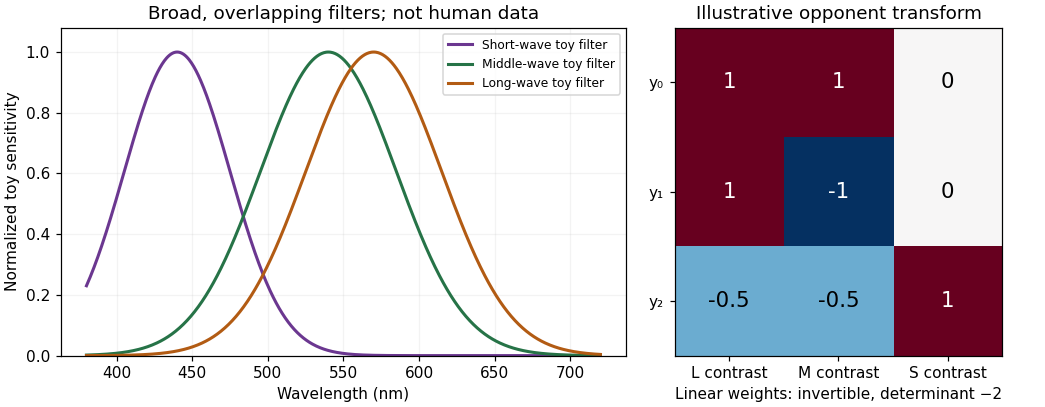
Original Gaussian toy receptor filters and an invertible opponent transform; the filters illustrate broad overlap and are not measured human cone fundamentals or a calibrated color chart
. Details. Second, the principle of univariance prevents one cone from identifying hue. For a monochromatic stimulus, let mean absorption be . Whenever and are positive, intensities satisfying give the same . The single receptor cannot distinguish those two inputs on absorption count alone. Calling that receptor a red detector would assign a color judgment to a signal that cannot even uniquely distinguish the two wavelengths. It remains true that spectral sensitivity constrains the comparison; univariance does not mean all receptor types are identical.
Third, perceptual color requires combinations. Comparing L and M signals and comparing S with L+M supplies chromatic information; summing appropriately weighted signals contributes to luminance-related processing. An L-cone increment can be part of several stimulus changes depending on what happens to M and S and on the adapted background. Neither an L response nor a raw L:M ratio by itself specifies a context-independent color word. The retinal and cortical opponent circuitry demonstrated by Dennis M. Dacey and Bevil R. Conway provides mechanisms for comparisons, rather than a relabelling of three cone outputs as three sensations.[ref]
The blue-on opponent pathway in primate retina originates from a distinct bistratified ganglion cell type by Dennis M. Dacey and others. Nature 367, 731–735
[ref]Fourth, “blue” or “red” need not identify a single wavelength. Spectrally different lights can be metamers, and a purple appearance can arise from a mixture rather than a monochromatic wavelength. Conversely, the same physical spectrum can look different against another surround or after adaptation. Cone labels cannot replace the distinction between emitted or reflected spectrum, receptor catch, opponent representation and reported hue.
Fifth, the display analogy is backwards. An RGB screen emits mixtures from three selected primary spectra. The cone cells receive and integrate the resulting spectrum; their response curves are not identical to those primary spectra. If primary intensities are and cone sensitivities to each primary form matrix , then . Off-diagonal terms are generally nonzero because each primary can excite several cone classes. If is nonsingular, an intended catch change can be computed through within the display's feasible gamut. It does not follow that every requested catch vector is realizable with nonnegative bounded primary intensities. Calibration and observer differences therefore matter in cone-isolating experiments.
Finally, color terms themselves vary across languages and tasks, whereas receptor class is a biological classification. Receptor genes, color matches, discrimination and linguistic categorization are related but distinct measurements. The labels L, M and S prevent an unwarranted assumption that one anatomical cell class directly instantiates one learned word or unique subjective hue.
The useful statement is that trichromatic vision starts with three broad, overlapping receptor classes and extracts chromatic information by comparison. “Red, green and blue cone cells” conceals both the information loss at each receptor and the transformations needed to see color.
The research challenge is to retain causal control while measuring appearance under the coupled spectral, spatial and temporal variations of actual scenes. Simply replacing a flat patch with a photograph does not guarantee that either the stimulus or the task is ecologically informative.
A display's RGB values do not specify the spectrum reaching a participant's cone cells. Primary spectra, viewing geometry, calibration, luminance range and the observer's lens and pigment sensitivities matter. A photograph can clip highlights, alter white balance and compress dynamic range; a display cannot necessarily reproduce the original spectrum, brightness or angular light field. A researcher studying spectral constancy should measure radiance and illuminants or specify the limits of a display simulation, rather than treating an uncalibrated image as physical ground truth.
Real materials also vary in more than diffuse reflectance. Shape, roughness, specularity, translucency and surrounding illumination jointly determine an image. Changing one rendering parameter can unintentionally change highlight area, contrast and apparent shape. Conversely, holding an image statistic constant can produce an unnatural stimulus. Experiments need independent manipulation of candidate causes and a clear statement of which physical scene properties are represented by the apparatus.
James M. Kraft and David H. Brainard demonstrated a productive compromise with a chamber of actual surfaces. They independently controlled illumination and surface reflectances and used a projection colorimeter to let observers adjust a test patch to appear achromatic. Manipulations could hold candidate image statistics approximately fixed while changing the illumination. The results rejected explanations based solely on local adaptation, the image mean or the most intense region.[ref]
Mechanisms of color constancy under nearly natural viewing by James M. Kraft and David H. Brainard. PNAS 96, 307–312; chamber, independent manipulations and achromatic settings
The achievement was not realism alone: it was enough realism combined with manipulations that made competing mechanisms disagree. These results do not show that local adaptation never contributes.For material appearance, Roland W. Fleming and colleagues used rendered objects illuminated by natural illumination distributions and systematically altered those distributions. Reflectance matching was more reliable under realistic illumination statistics than under some altered statistics.[ref]
Real-world illumination and the perception of surface reflectance properties by Roland W. Fleming and others. J Vis 3, 347–368; reflectance matching and illumination-statistics manipulations
This makes illumination an experimental variable, not merely a nuisance background. It also warns that a model tested only under a small set of studio lights can exploit cues unavailable or misleading elsewhere.The dependent variable needs equal care. Selecting the same paint, matching apparent color, adjusting an achromatic point, detecting an illuminant change and naming a material do not measure the same outcome. A person may correctly infer that two patches are the same material while still noticing an appearance difference. Instructions, response format, adaptation time and available context can alter the task. Eye and head movements change retinal exposure, so fixation constraints should be chosen deliberately and their cost to natural viewing acknowledged.
A strong program therefore combines calibrated simplified stimuli, controlled real scenes, validated rendering and tests on previously unseen objects and illumination. It should sample more than one observer and record relevant visual variation, report both accuracy and uncertainty, and test model generalization across scenes rather than only across random frames of the same scene. Proposed interventions can vary geometry while preserving spectral input, or alter illumination while suppressing a particular cue. Their outcomes must be measured, not assumed. The goal is interpretable generalization: experimental control sufficient to distinguish mechanisms and scene diversity sufficient to test whether those mechanisms remain useful.
The visual system must infer relatively stable object properties from images jointly determined by illumination, shape, material and viewpoint. The problem is intrinsically ambiguous; robust performance exploits several constraints and tolerates uncertainty rather than perfectly recovering a unique physical scene from every image.
Even a diffuse model contains a surface-illuminant ambiguity. Ignoring a fixed geometric factor, . For any positive function that leaves the resulting reflectance physically admissible, define and . Then , so even an observer measuring the complete outgoing spectrum could not distinguish those two explanations from that surface alone. Three cone catches introduce further spectral metamerism. Thus perfect color constancy cannot be obtained by a universal local inversion of three numbers.
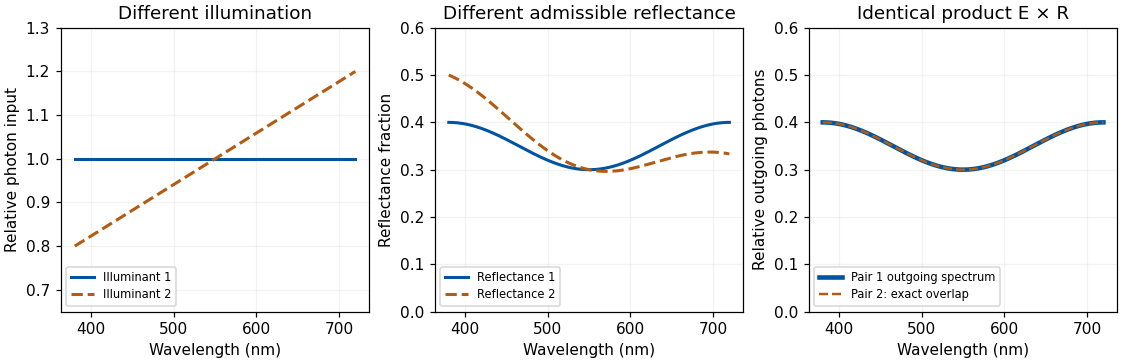
Original physically admissible diffuse-model example: two different illuminant–reflectance pairs produce the same outgoing photon spectrum; theoretical curves rather than measured surfaces
. Details. For directional optical reflection, an image sample instead depends on an integral such asThe expression sums contributions from incident directions, weighted by the bidirectional reflectance distribution function and projected area. It assumes a local, nonfluorescent optical reflection model and omits emission. A glossy surface therefore reflects aspects of its environment, and moving the observer changes the sampled outgoing direction even if the material is unchanged. Subsurface transport and transmission require further terms or models.
The system can constrain illumination by comparing surfaces, spatial boundaries and changes over time, while using shape and scene layout to distinguish a shadow from a pigment boundary. Cone-gain adjustment can approximately compensate shared spectral changes but cannot solve every mixture of differently colored lights, interreflections and specular components. A spatial average is unreliable if a scene is genuinely dominated by one colored material. A bright region might be a lamp, a highlight or a high-reflectance object, so “assume the brightest point is white” is not a universal solution.
Material judgments require distinguishing diffuse shading from highlights and transparency or translucency cues. Isamu Motoyoshi and colleagues showed that manipulating image statistics, including luminance-distribution skewness, could influence apparent gloss and lightness in their surface-image conditions.[ref]
Image statistics and the perception of surface qualities by Isamu Motoyoshi and others. Nature 447, 206–209; image-statistic manipulations and surface appearance
Such regularities offer efficient cues. They cannot uniquely specify a material: a histogram-preserving spatial permutation changes spatial organization while retaining the luminance histogram and all its moments. That mathematical ambiguity motivates experiments separating histogram cues from geometric consistency; it does not, by itself, predict every appearance judgment after scrambling.Juno Kim and colleagues directly tested the relation between highlights and diffuse shading. Manipulating their positional and orientation congruence reduced perceived gloss, including when simple proximity to broad luminance maxima was controlled.[ref]
The perception of gloss depends on highlight congruence with surface shading by Juno Kim and others. J Vis 11(9):4; Experiments 1–4
The visual system therefore uses relationships among image structures, not merely the presence of a few bright pixels. The conclusion concerns the tested images and judgments, rather than a claim that one cue explains every shiny or transparent material.Temporal information and active viewing help further. A highlight can move differently from a surface marking; multiple views constrain geometry, while familiar object structure and expected illumination supply priors. These strategies can fail under unusual lighting or deliberately misleading images. The system must also decide which differences matter: recognizing a material category, judging gloss and estimating spectral reflectance are related but separable goals.
Robustness comes from combining adaptation, spatial and temporal relations, shape information and learned scene constraints. It does not remove the physical ambiguities, and performance should be judged against a specified task rather than an impossible demand for exact recovery in every scene.
Language is not necessary for the basic capacity to discriminate or organize colors, but it can influence color judgments, attention and memory in particular tasks. The evidence supports neither the claim that words create all color experience nor the claim that language is irrelevant whenever the stimuli are visible.
The starting distinctions are essential. A receptor sensitivity, a color-matching relation, a discrimination threshold, a category boundary and a color name are different measurements. Molecular differences can change available cone signals, while linguistic experience can change how available information is grouped or used. Finding different words for two samples does not show that one group cannot discriminate them. Finding the same matching relation does not establish identical subjective appearance or identical naming.
The biological basis imposes constraints independent of a person's vocabulary. Three cone classes provide overlapping spectral measurements, and later circuits compare those measurements. Altered receptor signals or adaptation can change performance without requiring a new word. Conversely, changing a response strategy can change performance while leaving receptor input intact. The central empirical question is therefore which stage and task language influences, not whether one can name a color without knowing its name.
Prelinguistic evidence rules out a strict requirement for color words. Alice E. Skelton and colleagues used infants' recognition-memory responses to sample relations among colors across the hue circle. Infants' categorical distinctions showed organization related to common divisions in adult color lexicons and to early visual mechanisms.[ref]
Biological origins of color categorization by Alice E. Skelton and others. PNAS 114, 5545–5550; infant recognition-memory method and category structure
Infants did not need to produce the relevant color terms to show those distinctions. The inference is not that newborns possess an immutable adult lexicon: the infants already had visual experience, and looking-time measures require controls for discriminability, novelty and attention. The title's biological interpretation should not be strengthened into proof that experience plays no role.Cross-language studies also challenge a rigid universal partition. Debi Roberson and colleagues compared English speakers with Berinmo speakers using naming, recognition and category-learning tasks. Effects of linguistic category boundaries appeared for the categories used by each group, and response-bias controls weakened a simple claim that universally focal colors always enjoy a memory advantage.[ref]
Color categories are not universal: Replications and new evidence from a stone-age culture by Debi Roberson and others. J Exp Psychol Gen 129, 369–398; recognition, response-bias controls and boundary comparisons
The article's historical title is retained as a citation, not adopted as a description of people. The comparison shows that category use and memory cannot be reduced to one vocabulary-independent set of preferred labels. Because language group covaries with cultural and visual experience, it does not isolate vocabulary as the sole cause.A more direct manipulation was used by Jonathan Winawer and colleagues. Russian has conventional basic terms distinguishing lighter and darker blues that English usually groups under “blue.” Participants saw a target square and two alternatives together and selected the matching alternative. Russian speakers showed a speed advantage for comparisons crossing their linguistic boundary. A concurrent verbal task removed that advantage, while a spatial interference task did not produce the same pattern.[ref]
Russian blues reveal effects of language on color discrimination by Jonathan Winawer and others. PNAS 104, 7780–7785; simultaneous matching, category boundary and interference conditions
The simultaneous display reduces the long-term color-memory explanation, and the interference manipulation implicates access to language-related processes during performance. It does not establish a new receptor limit, a complete inability to discriminate within a category, or a necessary change in private color qualia. Concurrent tasks can affect more than one processing stage.These results motivate separating sensitivity from response facilitation. A faster match can reflect attentional selection, category-assisted comparison or decision formation. To claim changed sensory resolution, an experiment should measure psychometric functions over controlled stimulus separations, fit location, slope and lapse parameters, and test whether any effect persists with nonverbal responses and reversed response mappings. Equal physical distance in a standard color space does not automatically ensure equal discriminability for every participant; individual thresholds and adaptation should be measured where they matter.
A stronger causal program can combine within-person interference, language-learning interventions and longitudinal or bilingual comparisons, while matching exposure and task difficulty. Testing transfer to new samples distinguishes memorized stimulus labels from a changed category rule. Comparing immediate discrimination, delayed recognition, naming and appearance matches identifies whether an effect generalizes across measurement levels. These are proposed strategies rather than invented experimental outcomes. No test based only on verbal descriptions can directly establish equality or inequality of another observer's subjective experience.
The seemingly opposing findings can therefore coexist. Biology and early experience can produce color organization before fluent naming, while learned labels subsequently guide the use of that organization. Color vision does not depend on language for its existence; linguistic resources can nevertheless alter how people attend to, classify, remember and rapidly compare colors under specified conditions.
Part II advanced option in the held 2022 papers. The source examination is shared by the psychology (experimental) course of the University of Oxford and the psychology, philosophy and linguistics course of the University of Oxford.
Reading and language: development and disorder, Trinity Term 2022, 1 June at 09:30 BST. This undergraduate Part II advanced option has a three-hour writing period; the cover identifies the Second Public Examination without printing a Part number. Every essay option is treated below using evidence available by 1 June 2022.
Course: Reading and language: development and disorder course of the University of Oxford. Public source: Oxford-supplied archive, a10986w1.pdf.[ref]
Reading and language: development and disorder, 2022 by University of Oxford. Cover and all six options on page 2, A10986W1
Reading comprehension is measurable as performance on specified tasks and as a theoretically organised construct, but it is not a context-free quantity revealed equally well by every test. A score reflects a reader, a text, a question and an assessment format. The important question is whether the intended interpretation is supported: screening for difficulty, explaining an individual profile and evaluating an intervention can require different measurements.
A useful framework is the simple view of reading, which distinguishes decoding from linguistic comprehension. Wesley A. Hoover and Philip B. Gough tested predictions from a product relation in a longitudinal bilingual sample. The model captures the idea that understanding spoken language cannot compensate for completely inaccessible print, while accurate word reading alone cannot supply the meanings of the words. It does not imply that all raw test scores can simply be multiplied, or that each broad component is psychologically indivisible.[ref]
The simple view of reading by Wesley A. Hoover and Philip B. Gough. Reading and Writing 2, 127–160; decoding, linguistic comprehension and product predictions in a longitudinal bilingual sample
For an illustration, suppose decoding and linguistic comprehension are represented on idealised scales from zero to one and . Profiles and both give . The same comprehension outcome can therefore arise from different bottlenecks. These are hypothetical model values, not diagnostic cutoffs or observations about children. The distinction motivates measuring component skills rather than assigning one intervention from an aggregate score alone.
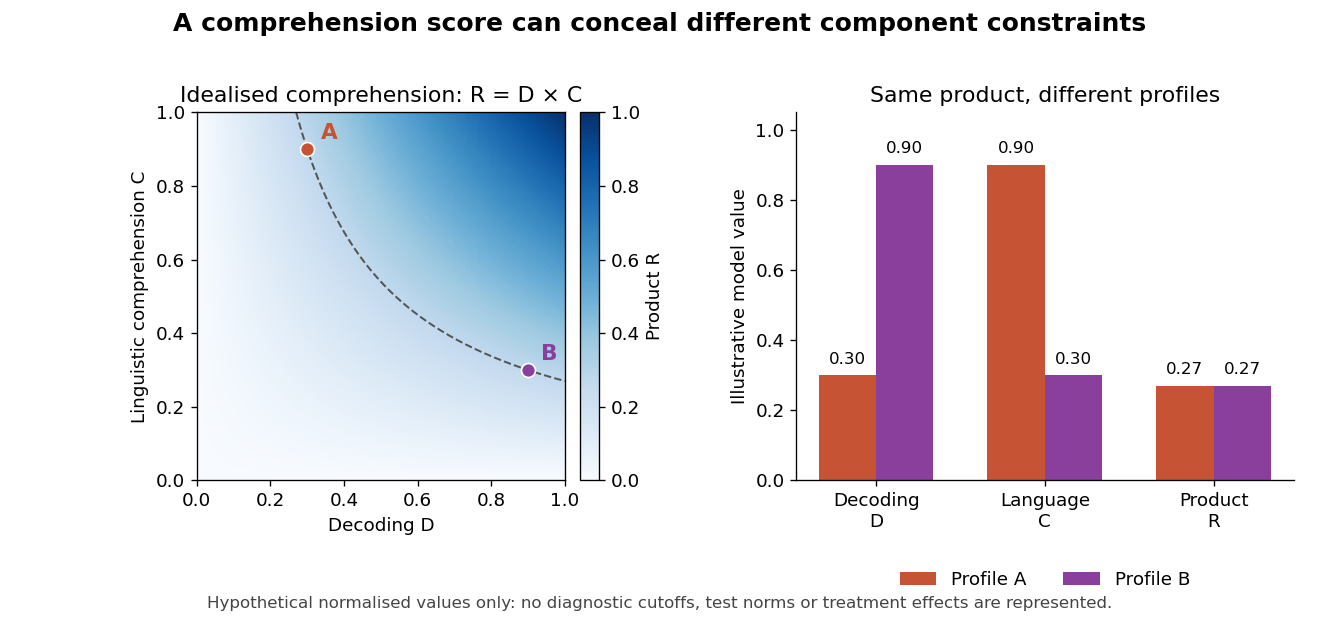
Different component profiles can yield the same product in the simple view of reading
. Details. Direct comparisons show that tests are not interchangeable. Janice M. Keenan and colleagues compared five reading comprehension measures. Decoding explained more variation in the PIAT and Woodcock–Johnson passage task, whereas listening comprehension contributed more strongly to the Gray Oral Reading Test and the two Qualitative Reading Inventory measures. The demands of some tests also changed with developmental level. Modest agreement therefore need not mean that comprehension is unreal: it can reveal different mixtures of processes and content, alongside measurement error.[ref]
Reading Comprehension Tests Vary in the Skills They Assess: Differential Dependence on Decoding and Oral Comprehension by Janice M. Keenan and others. Scientific Studies of Reading 12, 281–300; five measures, differential decoding/listening dependence and developmental changes
Assessment design determines what evidence is available. A short cloze item may be solved through local word knowledge and decoding, while questions about a passage can require integrating information across sentences. Retelling additionally requires organising and producing an answer. Removing the text increases memory demands; keeping it visible permits rereading and strategic search. Oral answers may expose expressive-language difficulties that a recognition format does not. None is automatically superior: the format must match the intended inference.
Reliability and validity are distinct. Repeated passages and sufficiently sampled items can improve precision, but a highly consistent score can still overemphasise decoding when the goal is discourse understanding. Convergence across texts and formats strengthens a construct interpretation; disagreement can identify task-specific demands. Measurement invariance matters when comparing ages or groups, because the same item format can depend on different skills as word recognition improves. A change in a standard score is not automatically an equal change in the underlying process at every age.
The first pressure point is efficient access to printed words. Slow or inaccurate decoding limits which propositions become available and can consume resources needed for integration. Assessment should distinguish familiar-word accuracy, unfamiliar-word decoding and fluency rather than assume that one word-reading score captures all three. A reader can identify isolated words accurately yet struggle to coordinate them in connected text.
The second pressure point is linguistic knowledge. Vocabulary breadth and depth determine whether word meanings are accessible and appropriate to context; grammar helps assign relations between entities and events. A text can be decoded accurately while remaining opaque because its meanings or sentence structures are unfamiliar. Background knowledge can support interpretation, but can also produce confident answers unsupported by the passage. Text selection should therefore vary topics rather than make one knowledge domain stand for general comprehension.
Higher-level processes provide further pressure points: generating necessary inferences, building a coherent representation, identifying relevant information and noticing inconsistencies. Kate Cain and colleagues assessed children at eight, nine and eleven and related comprehension to working memory and component skills. The study supports a multicomponent analysis, while its concurrent prediction models do not establish that training any correlated component will improve reading. Working memory demands are also partly determined by the text and response format.[ref]
Children's reading comprehension ability: concurrent prediction by working memory, verbal ability, and component skills by Kate Cain and others. Journal of Educational Psychology 96, 31–42; assessments at eight, nine and eleven, component skills and concurrent prediction
A useful assessment combines a comprehension measure with listening comprehension, vocabulary, grammar, decoding and fluency, then investigates the child's actual errors. Can they explain a referent, connect two statements or notice a contradiction when word-reading demands are reduced? Contrasting written and spoken versions can test a proposed bottleneck, although listening itself has memory and attention demands. A profile is a hypothesis about performance, not proof of a separate disorder or a unique cause.
Intervention supplies complementary evidence. Paula J. Clarke and colleagues randomised children with accurate reading but poor comprehension to text-focused, oral language, combined or untreated conditions. Comprehension improved in the intervention groups, with continued gains after oral language training. This demonstrates that difficulties can be modified through more than word decoding, but an improvement in a package does not isolate one underlying process. Maintenance, untrained texts and independent assessment are important when distinguishing learning the assessment from broader transfer.[ref]
Ameliorating children's reading-comprehension difficulties: a randomized controlled trial by Paula J. Clarke and others. Psychological Science 21, 1106–1116; text/oral/combined interventions, untreated comparison and eleven-month follow-up
The defensible conclusion is that comprehension is a measurable but task-dependent achievement supported by interacting skills. Its pressure points can lie in print access, language knowledge, integration, inference or monitoring, and their relative importance changes with the reader and text. Good measurement makes those dependencies explicit and samples enough situations to support the intended decision, rather than treating a single score as a complete explanation of failure.
Longitudinal data are critical for several developmental questions because they show whether an earlier characteristic precedes later reading, how individuals change and whether apparently similar outcomes have different histories. They are not sufficient to identify causes, and they are not the only informative evidence. The strongest understanding combines repeated observation with experiments, intervention and explicit models of measurement and development.
A cross-sectional age comparison confounds age with cohort, instruction and selection. Older and younger children may have received different teaching or differ in who remains in a sample. Following the same children can establish continuity and change, show whether an early weakness persists, and locate periods when a skill becomes more predictive. It also permits assessment before conventional reading instruction, reducing the risk of describing a consequence of reading experience as its original cause.
Valerie Muter and colleagues followed ninety school entrants over two years. Earlier letter knowledge and phoneme sensitivity predicted word recognition, whereas comprehension drew on word recognition, vocabulary and grammar. The temporally ordered pattern supports distinguishing developmental pathways rather than using a single readiness score. It does not prove that a predictor is sufficient, immutable or uniquely causal: teaching, family experience and other correlated skills may contribute to both the early measure and later outcome.[ref]
Phonemes, rimes, vocabulary, and grammatical skills as foundations of early reading development: evidence from a longitudinal study by Valerie Muter and others. Developmental Psychology 40, 665–681; ninety school entrants, two-year follow-up and distinct predictors
Developmental relations can change as constraints shift. When decoding is effortful, individual differences in print access may dominate a comprehension measure; later, oral language differences can become more visible. In Arne Lervåg and colleagues' five-year study beginning at about seven and a half, shared variation across vocabulary, grammar, verbal working memory and inference predicted listening and reading comprehension. Their modelling included interactions and nonlinearities. This shows why a fixed linear contribution estimated at one age may not describe the developmental process.[ref]
Repeated observation can distinguish trajectories concealed by an endpoint. Two children with similar reading at nine may differ because one began with weak decoding and improved, while another decoded adequately but developed a widening comprehension difficulty as texts became linguistically demanding. These histories generate different hypotheses about support and assessment. Conversely, using the later outcome to define groups can bias retrospective descriptions of their predictors, especially when classifications depend on noisy scores.
Longitudinal data are also needed to investigate reciprocal influence. Oral language knowledge can facilitate reading, while reading supplies new words and makes phonological structure more explicit. A path from an earlier reading score to later vocabulary is compatible with feedback, but it can also reflect stable differences in home experience or language ability. A conventional cross-lagged model may mix between-child differences with within-child change. Temporal ordering and statistical adjustment constrain explanations without automatically identifying the effect of changing a particular child's experience.
The home-literacy study by Monique Sénéchal and Jo-Anne LeFevre illustrates both the value and limits. Their five-year sample linked book exposure with language outcomes and direct parental teaching with early literacy, followed by later reading. Measuring activities and skills at different stages helps specify candidate routes that a single concurrent correlation would conceal. The observational design and relatively advantaged sample, however, do not establish that prescribing the measured activity would reproduce the association across all families.[ref]
Parental involvement in the development of children's reading skill: a five-year longitudinal study by Monique Sénéchal and Jo-Anne LeFevre. Child Development 73, 445–460; 168 middle/upper-middle-class children, home activities and distinct language/literacy pathways
Several methodological conditions are essential. The measures must remain interpretable across time: replacing an easy early task with a harder later one can be sensible, but common anchors or defensible latent models are needed for growth comparisons. Ceiling and floor effects can create apparent changes in prediction. A reliable group-average effect does not guarantee reliable ranking of individuals. Multiple measures can reduce task impurity, although a fitted latent factor still depends on its indicator and model assumptions.
Attrition can distort a trajectory if children with greater difficulty or disadvantage are less likely to remain. Recruitment and retention should be reported alongside the handling of missing observations. Statistical methods cannot recover information without assumptions, so sensitivity analyses should examine plausible departures from them. More waves do not automatically solve this problem, and closely spaced assessments can introduce practice effects while widely spaced assessments miss the timing of change.
Intervention provides additional causal leverage. Peter J. Hatcher and colleagues compared matched groups of seven-year-old poor readers receiving reading, phonological work, their integration or a control condition. Phonology-only work most improved the phonological tasks, while the integrated programme produced the greatest reading progress. This demonstrates why a longitudinal predictor cannot simply be translated into an isolated training prescription. The design supports the tested contrast, while allocation, contact and the content of each teaching package constrain finer causal claims.[ref]
Ameliorating Early Reading Failure by Integrating the Teaching of Reading and Phonological Skills: The Phonological Linkage Hypothesis by Peter J. Hatcher and others. Child Development 65, 41–57; matched groups of seven-year-old poor readers, reading/phonology/combined/control conditions
An informative future programme would begin before instruction, repeatedly measure oral language, phonological skills, letter knowledge, teaching and reading, and retain an inclusive range of children. Embedded randomisation could vary a specified teaching component while keeping adequate instruction available to everyone. Assess near-term target engagement, generalisation to untrained material and later comprehension. This combines developmental timing with an intervention contrast instead of treating observational paths as effects of manipulation.
Cross-linguistic and artificial orthography experiments can answer questions that a single natural cohort cannot. They can hold learning opportunities constant while changing the consistency or distribution of print-to-sound mappings. Longitudinal classroom studies then test whether the proposed process survives ordinary instruction and changing language demands. Agreement across methods is more persuasive than extending the duration of one observational design indefinitely.
Longitudinal data are therefore indispensable when the claim concerns ordering, change, persistence or reciprocal development. They are not a substitute for credible measurement or causal design. Their greatest contribution is to make developmental explanations more precise and testable, while experiments and interventions establish which changes in experience actually alter the path.
A meaningful distinction can be made between developmental language disorder and reading disorders, provided it is expressed as a distinction between dimensions and profiles rather than a claim that every child falls into one isolated biological category. Spoken-language difficulty and impaired word reading can occur separately or together. Their overlap is informative, and the definition of 'reading disorder' matters: dyslexia centred on word-level reading is not synonymous with every form of poor reading comprehension.
The CATALISE consensus endorsed developmental language disorder for persistent language difficulties associated with functional impairment and poor prognosis, without a known associated biomedical aetiology. Risk factors do not automatically exclude the diagnosis, and a verbal–nonverbal discrepancy is not required. This is a research and clinical terminology agreement, not an experiment proving a natural boundary. Earlier studies of specific language impairment used criteria that must be examined before their groups are equated with contemporary DLD.[ref]
Phase 2 of CATALISE: a multinational and multidisciplinary Delphi consensus study of problems with language development: Terminology by Dorothy V. M. Bishop and others. Journal of Child Psychology and Psychiatry 58, 1068–1080; 57-member terminology consensus, impairment, prognosis and biomedical associations
Dyslexia typically concerns persistent difficulties in accurate or fluent word reading and spelling. A child can have these difficulties while understanding spoken language relatively well. Another child can decode words adequately but struggle with vocabulary, grammar or discourse understanding, limiting comprehension in both spoken and written form. A third can have both profiles. The simple view of reading provides a useful two-dimensional description, while actual assessment must also consider fluency, instruction, language experience and the demands of the text.
Hugh W. Catts and colleagues tested the relation prospectively in a representative 527-child sample, comparing kindergarten language impairment with later dyslexia classifications. They found overlap but not identity. In a separate profile analysis, dyslexia was more closely associated with pronounced phonological-processing weaknesses, whereas language impairment without dyslexia showed milder phonological difficulties. The evidence supports distinguishable profiles, but depends on the diagnostic rules, measures and developmental occasions used.[ref]
Are Specific Language Impairment and Dyslexia Distinct Disorders? by Hugh W. Catts and others. Journal of Speech, Language, and Hearing Research 48, 1378–1396; 527-child longitudinal sample and separate phonological-profile subsample
Margaret J. Snowling and colleagues followed a cohort enriched for familial reading risk or preschool language difficulty. At eight, they identified dyslexia-only, DLD-only and comorbid groups; comprehension was measured at eight and nine. All groups had difficulties relative to controls, but the dyslexia-only group's comprehension weakness was milder than that of the groups with DLD. This is consistent with different routes to a shared outcome. Comorbidity rates in an enriched sample should not be treated as population prevalence.[ref]
Dyslexia and Developmental Language Disorder: comorbid disorders with distinct effects on reading comprehension by Margaret J. Snowling and others. Journal of Child Psychology and Psychiatry 61, 672–680; dyslexia-only, DLD-only and comorbid groups at eight, comprehension at eight/nine
The contrast between studies is itself useful. A representative cohort and a risk-enriched cohort can produce different overlap estimates without one necessarily invalidating the other. Selecting families with early language problems increases the chance of observing both difficulties. Restricting one group to normal decoding or oral language also creates cleaner profiles than may occur in routine assessment. Group definitions can therefore sharpen a theoretical contrast while understating the continuum of mixed presentations.
There are plausible shared and distinct developmental processes. Weak phonological representations or awareness can hinder learning letter–sound relations, while broader lexical, grammatical and discourse weaknesses affect understanding beyond word identification. These processes can covary because language systems interact and because experiences support several skills together. A phonological difficulty does not have to account for every aspect of DLD, and broader language risk does not guarantee dyslexia. A probabilistic multiple-risk account fits overlap more naturally than a necessary-and-sufficient deficit assigned to every child in a label.
Assessment should therefore specify the difficulty rather than infer it from the category. Include unfamiliar-word decoding, familiar-word accuracy and fluency, spelling, vocabulary, grammar, listening comprehension and discourse tasks. Nonword repetition and phoneme-awareness measures can contribute, but each has perceptual, memory, motor or metalinguistic demands. Hearing, opportunity to learn, multilingual experience and functional impact also require consideration. Low performance in the language of schooling is not, by itself, evidence of an intrinsic language disorder.
The distinction matters when choosing an intervention target. A child whose main barrier is acquiring written word forms needs teaching that addresses that barrier; accurate decoding cannot be assumed to resolve a broader comprehension weakness. Paula J. Clarke and colleagues' trial of children with specific comprehension difficulties showed benefit from oral language and text-focused interventions, beyond the children's existing accurate reading. It supports treating the identified language/comprehension problem, while not proving that a diagnostic label uniquely determines the best programme.[ref]
Ameliorating children's reading-comprehension difficulties: a randomized controlled trial by Paula J. Clarke and others. Psychological Science 21, 1106–1116; text/oral/combined interventions, untreated comparison and eleven-month follow-up
The combined profile may require support on both dimensions. Improvement should be monitored separately for word reading, oral language and comprehension, because a gain in one can leave the other limiting performance. A programme's effect on a trained task is not enough: transfer to untrained passages and everyday educational participation are relevant outcomes. Categories can help communication and access to services, but should not prevent a child with mixed needs from receiving both forms of support.
A stronger test of separability would recruit children before reading instruction, use reliable repeated measures and examine profiles without selecting only extreme, nonoverlapping groups. Dimensional models can be compared with categorical models, and competing predictions preregistered. An intervention study could test whether targeted decoding and oral language components have different effects across baseline profiles, with adequate power for interactions. Mere significance in one group and nonsignificance in another would not establish a differential response.
The meaningful distinction is consequently between patterns of spoken-language and written-word difficulty, with implications for mechanisms, assessment and support. The evidence rejects a simple equation of DLD with dyslexia and also rejects treating reading comprehension failure as one homogeneous condition. It does not require sharp, immutable boundaries or deny shared risks, comorbidity and developmental change.
Visual word recognition develops through sensitivity to statistical structure at several levels: visual letter patterns, relations between print and sound, and relations between word forms and meanings. Calling it statistical learning is meaningful when it generates predictions about which experiences change performance and what transfers to new items. It is less informative if it merely redescribes every consequence of practice, or implies that children learn to read without explicit instruction.
An alphabetic writing system contains systematic but imperfect correspondences. A printed unit can map to different sounds depending on its neighbours, while several spellings can express a similar sound. Frequency makes some patterns more available than others; consistency affects how strongly a local cue predicts an outcome. Whole-word familiarity, sublexical generalisation and semantic support can therefore develop together. Recognising a trained item does not by itself establish what unit or relation was learned.
David L. Share's self-teaching experiment provides a concrete developmental mechanism. Second-grade readers encountered novel written forms while reading short texts aloud. Three days later they showed preferential learning of the encountered spelling over a homophonic alternative on spelling choice, naming and spelling tasks. Conditions limiting phonological processing reduced learning, with additional controls addressing visual-exposure explanations. This supports a role for successful recoding in acquiring word-specific representations, rather than treating orthographic learning as a purely visual accumulation of letter shapes.[ref]
Phonological recoding and orthographic learning: A direct test of the self-teaching hypothesis by David L. Share. Journal of Experimental Child Psychology 72, 95–129; second-grade pseudoword reading, delayed spelling-choice/naming/spelling and recoding controls
Self-teaching also clarifies what the learner's input is. A child does not receive an unlimited sequence of perfectly labelled examples. They must attempt a pronunciation, connect it with a known spoken form or a context, and sometimes correct an initial interpretation. Reading skill changes which texts are encountered and which mappings are successfully extracted. Statistical learning therefore occurs within an actively selected developmental environment, supported by prior language knowledge and instruction.
Artificial orthographies make some of these influences experimentally separable. Joanne S. H. Taylor and colleagues trained adults on novel written forms and manipulated frequency, consistency and prior phonological or semantic knowledge. Participants learned trained items and generalised to new ones, showing sensitivity to more than isolated visual tokens. Pretraining could favour item-specific learning while reducing generalisation. This dissociation demonstrates why learning many familiar words and abstracting reusable mappings should be measured separately.[ref]
The influence of consistency, frequency, and semantics on learning to read: an artificial orthography paradigm by Joanne S. H. Taylor and others. Journal of Experimental Psychology: Learning, Memory, and Cognition 37, 60–76; sixteen/32 adults, novel script, frequency/consistency and pretraining
The apparatus in such studies is comparatively simple but powerful: unfamiliar characters and controlled pronunciations allow the experimenter to define the learning history. Training and test items can be chosen so that memorising the trained strings will not solve the transfer test. Naming, lexical decisions and generalisation can then constrain what was acquired. Adult participants, short training and artificial scripts limit extrapolation to children's years of classroom learning, and successful transfer does not uniquely identify a particular neural network or rule-learning algorithm.
Child evidence strengthens the link to ordinary instruction. Keith S. Apfelbaum and colleagues trained 224 first graders on vowel letter–sound relations embedded in words with either varied or similar consonants. Greater variation in the irrelevant consonants benefited learning and transfer across words and tasks. The result shows that the distribution of examples matters, not merely their total number. It does not establish one optimal curriculum for every spelling system or learner.[ref]
Statistical learning in reading: variability in irrelevant letters helps children learn phonics skills by Keith S. Apfelbaum and others. Developmental Psychology 49, 1348–1365; 224 first graders, vowel mappings with varied/similar consonants and transfer tasks
The idea is intuitive: if one vowel pattern occurs with many different consonants, the invariant mapping is easier to distinguish from accidental properties of a few whole words. This is a hypothesis about cue selection and generalisation. A competing possibility is that highly similar examples force a fine-grained contrast. Experiments can adjudicate these principles by matching exposure and manipulating irrelevant variation, rather than assuming that either maximum variety or maximum similarity must always be best.
Explicit teaching is compatible with this account. Joanne S. H. Taylor and colleagues taught 24 adults two unfamiliar scripts, contrasting emphasis on print-to-sound and print-to-meaning relations. Print-to-sound emphasis benefited naming, generalisation and single-word comprehension. Their behavioural and imaging results constrain how experience is organised, but do not constitute a classroom trial in beginning readers. The study shows why a statistical account should include what instructions direct the learner to notice.[ref]
Comparing and validating methods of reading instruction using behavioural and neural findings in an artificial orthography by Joanne S. H. Taylor and others. Journal of Experimental Psychology: General 146, 826–858; 24 adults, two novel scripts, eight-day training, generalisation and fMRI
Several levels of explanation must remain distinct. An observed frequency effect identifies a property of performance. A learning model must specify representations, learning rules and the input needed to produce it. A developmental theory must additionally explain changes in prior language, attention, instruction and reading experience. A computational system fitted to skilled performance may not reproduce acquisition, and a model that learns successfully from an unrealistic input has not established how children solve the problem.
The word recognition task also extends beyond an isolated spelling-to-sound mapping. Efficient recognition must tolerate changes in font and case, distinguish similar forms, access meaning and operate in context. Different scripts make different statistical units useful. Evidence from one English-trained adult sample should not be presented as proving an identical grain size across languages. Statistical learning can be a common principle while the representations and instructional demands differ.
A decisive developmental test would hold total exposures and teaching time constant while varying a specified distribution, measure both trained and untrained forms, and assess retention after a delay. Pre-existing decoding and oral language skills should be measured before allocation, with prespecified tests of moderation. Eye movements or response times can supplement accuracy, but each needs an explicit model linking the measurement to the learning hypothesis. A classroom replication should then test whether the predicted advantage survives ordinary teaching and broader text demands.
Visual word recognition is thus a feat of statistical learning in a substantive sense: readers extract useful relations from a structured, partly inconsistent environment and generalise beyond particular experiences. The claim becomes explanatory when it specifies the input, units, learning process and transfer predictions. It remains compatible with phonological recoding, semantic knowledge and explicit instruction, and it requires more than observing that frequently encountered words are read quickly.
By June 2022, important principles of reading acquisition were established, including the need to learn written word forms and to understand the language they express. The major unanswered questions concerned how these skills become efficient and integrated, why children respond differently to experience and instruction, and how experimental gains become sustained comprehension and participation. Useful future research should target those uncertainties with explicit competing predictions rather than reopen every instructional question as if no evidence existed.
One question concerns what is learned from a successful encounter with a new written word. Does the child acquire an item-specific spelling, a reusable mapping, a contextual guess, or some combination? David L. Share's delayed learning experiments motivate the distinction, while artificial orthography work shows that strong item learning and generalisation need not move together. Future studies should therefore distinguish recognition of practised items from transfer to novel combinations and later retention, rather than use one immediate naming test as a complete index of learning.[ref]
Phonological recoding and orthographic learning: A direct test of the self-teaching hypothesis by David L. Share. Journal of Experimental Child Psychology 72, 95–129; second-grade pseudoword reading, delayed spelling-choice/naming/spelling and recoding controls
[ref]The influence of consistency, frequency, and semantics on learning to read: an artificial orthography paradigm by Joanne S. H. Taylor and others. Journal of Experimental Psychology: Learning, Memory, and Cognition 37, 60–76; sixteen/32 adults, novel script, frequency/consistency and pretraining
A specific experiment could randomise unfamiliar but pronounceable items to matched exposure schedules varying the consistency of a spelling–sound relation. Hold the number of encounters, visual complexity and oral vocabulary knowledge constant. Assess trained spellings against homophonic alternatives after a delay, and test untrained recombinations that require the relevant mapping. Eye tracking during text reading could establish where the new form attracts attention, while comprehension questions verify meaningful engagement. The experiment should specify whether its prediction concerns initial learning, retention or generalisation.
A second question is how the distribution of teaching examples interacts with the learner's existing knowledge. Keith S. Apfelbaum and colleagues found that varied irrelevant consonants helped first graders learn vowel mappings. It remains necessary to identify when variation helps, whether its effects depend on prior decoding and how long the advantage lasts. A multisite classroom experiment could independently vary relevant consistency and irrelevant variation while matching total teaching time and opportunities to respond.[ref]
Statistical learning in reading: variability in irrelevant letters helps children learn phonics skills by Keith S. Apfelbaum and others. Developmental Psychology 49, 1348–1365; 224 first graders, vowel mappings with varied/similar consonants and transfer tasks
Pretraining measures should be collected before randomisation, and interaction tests powered prospectively. A significant benefit in one subgroup and a nonsignificant effect in another does not demonstrate different treatment effects. Instructional fidelity and actual exposure need observation because a teacher may adapt a nominally identical activity in different ways. Broader spelling, unfamiliar-word reading and later passage comprehension would distinguish a useful instructional principle from a narrow training-task effect.
A third question is how best to coordinate word-level and language-level support. Margaret J. Snowling and colleagues' longitudinal profiles show that dyslexia, DLD and their co-occurrence can lead to comprehension difficulty through different constraints. The unresolved question is not whether either dimension matters, but which combination, timing and intensity of support helps a specified child. Diagnostic categories are too coarse to substitute for a measured profile.[ref]
Dyslexia and Developmental Language Disorder: comorbid disorders with distinct effects on reading comprehension by Margaret J. Snowling and others. Journal of Child Psychology and Psychiatry 61, 672–680; dyslexia-only, DLD-only and comorbid groups at eight, comprehension at eight/nine
A factorial teaching trial could retain adequate core reading instruction for everyone and independently randomise additional decoding and oral language components, with contact and resource use measured. Include children across the skill distribution rather than only extreme, mutually exclusive categories. Prespecify primary outcomes for word reading, language and comprehension, with delayed follow-up. A subsequent adaptive stage could randomise a well-defined change for children not responding, instead of attributing improvement after an uncontrolled adjustment to personalisation itself.
The trial would also address a fourth question: what constitutes meaningful transfer? Janice M. Keenan and colleagues showed that comprehension assessments differ in their reliance on component skills. An intervention can look more successful simply because its outcome task resembles training. Future evaluations need independent passages, several assessment formats and checks that the construct retains a comparable meaning across time and groups. Function in the classroom and the child's experience should accompany test scores, without treating either as a substitute for accurate measurement.[ref]
Reading Comprehension Tests Vary in the Skills They Assess: Differential Dependence on Decoding and Oral Comprehension by Janice M. Keenan and others. Scientific Studies of Reading 12, 281–300; five measures, differential decoding/listening dependence and developmental changes
A fifth uncertainty concerns how findings generalise across writing systems, language backgrounds and educational environments. Artificial-script work offers experimental control, but Joanne S. H. Taylor and colleagues' instruction study used adults learning small novel vocabularies. It cannot establish the full trajectory of a multilingual child encountering an unfamiliar language of instruction. Coordinated cross-language studies should define the mappings and language experiences that differ, rather than merely compare national averages.[ref]
Comparing and validating methods of reading instruction using behavioural and neural findings in an artificial orthography by Joanne S. H. Taylor and others. Journal of Experimental Psychology: General 146, 826–858; 24 adults, two novel scripts, eight-day training, generalisation and fMRI
Recruitment should include varied socioeconomic circumstances and children whose language development differs from the majority sample. Assessment needs to separate opportunity to learn from persistent difficulty and to examine the validity of the measures in each context. Shared protocols and culturally appropriate materials can coexist. The aim is to test which mechanisms generalise and which depend on script, vocabulary or teaching, not presume that every observed group difference reveals an intrinsic deficit.
Computational models can sharpen all these questions. A model should learn from a specified developmental input, make predictions for held-out items and trajectories, and face comparison with alternatives that use different representations or learning rules. Matching average skilled-reader accuracy is weaker than predicting the effect of an experimental change in input. Parameters should not be allowed to absorb every individual difference without independent constraints; failure should inform revision rather than invite unrestricted refitting.
Finally, the timescale of research must match the educational claim. Short experiments identify candidate processes, longitudinal cohorts reveal ordering and trajectories, and controlled implementation studies assess delivery and lasting benefit. Preregistration, transparent exclusions, appropriate handling of school clustering and missing follow-up, and independent replication make the chain more credible. The central unanswered problem is how to connect the child's particular learning history and profile with an instructionally manipulable process that produces durable, generalisable gains.
Oral language shapes written language development by supplying the phonological, lexical, grammatical and discourse knowledge that print must connect with. The influence is not unidirectional. Learning to read and write can make speech structure more explicit, expand vocabulary and alter the processing of spoken words. The strength and direction of a particular relation depend on age, writing system, instruction and the aspect of language being measured.
At the word level, alphabetic reading links graphemes with speech sounds and familiar spoken forms. Phonological awareness can help a child analyse a word and use letter–sound relations, but it is not identical to speech comprehension or to the ability to pronounce a word. A child may understand a spoken word without being able to segment its phonemes deliberately. Reading instruction and metalinguistic awareness can consequently develop together rather than one being wholly completed before the other starts.
Longitudinal evidence separates some routes. Valerie Muter and colleagues found that letter knowledge and phoneme sensitivity predicted early word recognition, while vocabulary and grammar contributed to comprehension alongside word recognition. The result supports a differentiated oral language foundation. It does not imply that vocabulary is irrelevant to every unfamiliar-word problem or that the observed predictors alone specify a complete teaching programme.[ref]
Phonemes, rimes, vocabulary, and grammatical skills as foundations of early reading development: evidence from a longitudinal study by Valerie Muter and others. Developmental Psychology 40, 665–681; ninety school entrants, two-year follow-up and distinct predictors
For text comprehension, oral vocabulary supplies meanings and grammar supports interpretation of relations and reference. Inferencing and discourse knowledge connect information beyond a sentence. Listening comprehension offers a useful comparison when decoding is suspected to be the bottleneck, but it is not a demand-free measure of language. Speech unfolds over time and can tax attention and memory; written text can be reread. These differences should be considered before interpreting a written–spoken discrepancy as a pure decoding deficit.
Oral language also contributes to producing written language. Choosing words, constructing sentences and organising a narrative draw on language knowledge, while spelling and transcription add constraints. Julie E. Dockrell and colleagues followed 64 children with a history of language impairment, assessing them at eight and their written text at ten. The writing showed difficulties in sentence structure and organisation; concurrent vocabulary and reading helped explain variation. The associations support a broad profile, not proof that an isolated vocabulary treatment would resolve composition difficulties.[ref]
Constraints in the production of written text in children with specific language impairments by Julie E. Dockrell and others. Exceptional Children 73, 147–164; 64 children with language-impairment history, measures at eight and written text at ten
Intervention gives stronger leverage on one direction. Paula J. Clarke and colleagues' oral language programme improved reading comprehension in children who could already read accurately, with gains extending beyond the intervention period. This supports oral language as a modifiable contributor, while the multicomponent programme and untreated comparator leave its precise ingredients partly open. An implication is that improving word recognition alone may leave a language-level limitation unresolved.[ref]
Ameliorating children's reading-comprehension difficulties: a randomized controlled trial by Paula J. Clarke and others. Psychological Science 21, 1106–1116; text/oral/combined interventions, untreated comparison and eleven-month follow-up
Home experiences provide potentially different inputs. Monique Sénéchal and Jo-Anne LeFevre linked book exposure with vocabulary and listening comprehension, and direct parental teaching with early literacy in a five-year study. These routes help explain why 'home literacy' is not one uniform activity. The observational, relatively advantaged sample limits causal and population inference; shared reading can involve both spoken interaction and print exposure, making it difficult to assign its effects exclusively to either medium.[ref]
Parental involvement in the development of children's reading skill: a five-year longitudinal study by Monique Sénéchal and Jo-Anne LeFevre. Child Development 73, 445–460; 168 middle/upper-middle-class children, home activities and distinct language/literacy pathways
Evidence for the reverse direction has a long history. José Morais and colleagues compared adults who remained illiterate with people who had learned to read in adulthood. The former had difficulty deliberately adding or deleting a speech phone, whereas adult readers performed the tasks more readily. The contrast suggests that explicit access to phonemic structure is not an automatic consequence of mature spoken language. Because literacy was not randomly assigned, schooling and selection remain alternative contributors; the result concerns metalinguistic performance rather than absence of ordinary speech perception.[ref]
Does awareness of speech as a sequence of phones arise spontaneously? by José Morais and others. Cognition 7, 323–331; illiterate and adult-literate comparisons on phone addition/deletion
Written language also supplies new lexical knowledge. William E. Nagy and colleagues found small but reliable gains in knowledge of unfamiliar words encountered in natural text. Repeated reading can therefore contribute to vocabulary growth, rather than vocabulary always being an independent precursor. The amount learned from a passage depends on prior knowledge, context and assessment sensitivity, so tentative population extrapolations should not be confused with a guaranteed learning rate for every child.[ref]
Learning Words from Context by William E. Nagy and others. Reading Research Quarterly 20, 233–253; incidental word knowledge after reading natural text and limited extrapolation
Neuroscience provides converging evidence of reorganisation. Stanislas Dehaene and colleagues compared adults with different literacy histories using fMRI responses to written and spoken material. Literacy was associated with changed visual responses to writing, stronger phonological responses to speech and activation of orthographic information from spoken input. The inclusion of adult learners shows that relevant differences are not restricted to childhood schooling, but the groups were not randomly assigned. The imaging does not by itself identify a unique instructional cause or show that larger activation is always better.[ref]
How learning to read changes the cortical networks for vision and language by Stanislas Dehaene and others. Science 330, 1359–1364; 10 illiterate/22 adult-literate/31 childhood-literate adults, visual and spoken-language fMRI
The developmental relation can thus be recursive. Better language knowledge helps a child understand print; successful reading permits more independent encounters with words and structures; those encounters can support later oral language performance. Difficulty at either stage may restrict opportunities at the next. Such a loop is a hypothesis about mechanisms and experience, not a reason to assume that all observed growth differences are self-amplifying or irreversible.
A strong test would combine repeated measures before and after instruction with controlled changes to oral or written experience. One study could compare learning the same unfamiliar meanings through listening, independent reading or supported reading while matching content and exposure. Test both spoken understanding and written use after a delay, alongside decoding and prior vocabulary. Another could vary print support during phoneme instruction while assessing untrained speech-segmentation tasks. These designs can distinguish medium, content, instruction and transfer more clearly than a concurrent correlation.
Writing outcomes should remain part of that programme. Oral retelling, dictated composition and independent writing can help distinguish language formulation from spelling and transcription demands, though the tasks still differ in support and planning. Cross-language and multilingual studies can test whether reciprocity depends on script or experience rather than assuming that an English alphabetic result is universal.
Oral language is therefore a major foundation for reading and writing, but literacy is also an experience that reshapes language knowledge and access. The most useful account specifies the component and timescale in each direction. It treats experimental, longitudinal, intervention and imaging evidence as complementary constraints on a reciprocal developmental system.
Part II advanced option in the held 2022 papers. The source examination is shared by the psychology (experimental) course of the University of Oxford and the psychology, philosophy and linguistics course of the University of Oxford.
Source release: Oxford-released bundle, member a15915w1.pdf.
The cover requires three answers and gives a limit of 1,800 words without explicitly stating whether it applies per answer or per submission. All six options are developed here as separate study essays, each below 1,800 words; their aggregate is not presented as a three-answer submission. Scientific evidence is restricted to work available by 27 May 2022.
Arithmetic develops through learning what number words and symbols mean, coordinating counting with quantities, and selecting increasingly useful strategies. Teaching should connect these components and diagnose how a child obtained an answer, rather than treating fluent recitation or speed as sufficient evidence of understanding. Early abilities to notice quantity are relevant resources, but they do not by themselves supply exact symbolic arithmetic. The educational question concerns how children connect representations and procedures across tasks.
Counting requires more than producing a familiar sequence. The child must coordinate one number word with each object, preserve a stable word order and use the final count to answer how many objects there are. The cardinality principle links the counting procedure to the cardinality of the set. A child may recite farther than the quantities they can reliably produce on request. Comparing recitation, counting a displayed collection and giving a requested number of objects therefore reveals different aspects of knowledge rather than redundant measures of one skill.
Karen Wynn's longitudinal study followed two- and three-year-olds as they learned number-word meanings and the counting system. Children could recognize that number words referred to distinct quantities before knowing the exact quantity associated with each word. Their acquisition was gradual, with a substantial interval between early word-specific knowledge and understanding how counting represents quantity. A request to give a number of objects is particularly informative because repeating the word sequence alone cannot satisfy it. The result argues against assuming that a correct count routine establishes a complete number concept.[ref]
Children's acquisition of the number words and the counting system by Karen Wynn. 1992; longitudinal number-word and requested-set tasks
This transition also explains why a single performance should not be overinterpreted. A child can misunderstand instructions, lose track of touched objects or know a quantity in one context without transferring the word to another. Assessment should vary the arrangement and objects while keeping the numerical question comparable. Success with a small collection need not show that the child understands arbitrary larger counts; failure on a lengthy verbal instruction need not show absence of every numerical insight. Number-word knower levels are useful descriptions of task performance, not fixed identities or universal timetable requirements.
Arithmetic then creates opportunities to coordinate these meanings. For , a count-all strategy can represent both collections and count the combined objects. A counting-on strategy starts from the known eight and counts five further steps. A child can also use decomposition, , drawing on a relation to ten. These are different routes to 13, with different demands on attention, working memory and available facts. They should not be inferred solely from a correct answer or a fast response.


Counting on from the larger addend reduces the number of required increments. For nonnegative natural numbers and , commutativity permits starting from and making unit steps. This reduces counting effort without changing the sum. Understanding that relation is different from memorizing a rule to start with the larger written digit. When children explain or model why the shortcut works, the teacher can check whether it reflects a relation between quantities or only a rehearsed instruction.
Strategy development is not well described as every child abandoning one method on the same date. Children can use several procedures depending on number size, familiarity and confidence. Robert S. Siegler and colleagues used a microgenetic method to study second-graders discovering an arithmetic shortcut, with trial-by-trial response times and explicit reports. Evidence of the shortcut often appeared in performance before children could report it. The study shows why explanations and performance measures should be combined: failure to verbalize a strategy does not necessarily mean that no useful change has occurred.[ref]
Conscious and unconscious strategy discoveries: a microgenetic analysis by Robert S. Siegler and others. 1998; implicit performance and explicit-report measures of shortcut discovery
Increasing fluency can reduce the resources needed for familiar calculations, but rote speed and conceptual knowledge are not opposing educational goals. Reliable facts can support reasoning with less familiar numbers; understanding a relation can make facts easier to derive and check. Conversely, rapid retrieval of a wrong fact is not progress. Error patterns, use of inverses and flexible decomposition provide stronger evidence about developing arithmetic than a single timed total. Practice should therefore be evaluated through accuracy, efficiency, flexibility and retention, with task demands made explicit.
The teaching implications are specific. Counting activities should connect spoken numbers, objects and written numerals. Materials are useful when children understand what each object or movement represents, rather than merely manipulating attractive objects. Teachers can compare different correct solutions, ask children to predict how an answer changes when an addend changes, and connect a verbal story to its symbolic form. The relevant support depends on the child's current knowledge: supplying a more elaborate verbal explanation may burden someone who still needs to coordinate the count.
Thomas P. Carpenter and colleagues tested whether research knowledge about children's mathematical thinking could improve classroom instruction. Twenty first-grade teachers received a workshop and twenty were randomly assigned to a control condition. The workshop did not prescribe one script; intervention teachers paid more attention to children's problem-solving processes, and their pupils showed stronger outcomes on several mathematical measures. This is evidence that teacher understanding can matter beyond distributing a new worksheet. It does not identify one isolated workshop component as the unique cause or show that unguided discovery is always superior.[ref]
Using knowledge of children's mathematics thinking in classroom teaching: an experimental study by Thomas P. Carpenter and others. 1989; teacher randomization, instructional changes and pupil outcomes
Language, opportunities to participate, familiarity with symbols and classroom instruction all affect the observations used to judge arithmetic. A child learning the language of instruction may need a way to show a quantity without a lengthy explanation. Apparent success on a memorized format may fail on an unfamiliar representation. Formative assessment should therefore sample multiple tasks and use errors to select the next instructional step, while retaining ambitious goals rather than fixing a child permanently at an inferred ability level.
The strongest implication is to teach and assess connections: number words to quantities, counting to cardinality, procedures to relations, and practiced facts to flexible calculation. Developmental research identifies informative distinctions and plausible mechanisms; classroom experiments test whether using that knowledge improves learning. Neither a universal maturation schedule nor one preferred teaching method follows from the evidence.
Psychological research can improve mathematical intervention by identifying a child's component difficulties, translating a proposed mechanism into teachable activities and testing whether gains transfer to meaningful mathematics. Low attainment is an outcome to explain, not proof of one defective “number sense” system. A useful intervention must also specify its comparison condition, dose, intended learners and success criteria. The same program need not suit children whose errors have different origins.
Assessment can separate counting, number-word and numeral knowledge, symbolic magnitude comparison, number-line estimation, fact retrieval, calculation procedures and understanding of word problems. Language and working memory can affect these tasks, as can prior instruction and opportunity to practice. A broad low score may therefore conceal a relatively specific bottleneck. Developmental dyscalculia describes persistent mathematical learning difficulty in an appropriate assessment context; it should not be inferred from one poor session or used to assume that every affected child has the same cognitive profile.
Ann Dowker's Numeracy Recovery work illustrates a component-oriented approach: examine the child's performance in different arithmetical activities and provide targeted support rather than prescribing identical exercises from an overall score. Its early pilot status is important. Improvement after a program is compatible with benefit, but without a strong counterfactual it can also reflect ordinary teaching, repeated testing or regression toward the mean. The psychological formulation supplies a rationale that subsequently requires controlled evaluation; it is not itself an effect estimate.[ref]
Numeracy recovery: a pilot scheme for early intervention with young children with numeracy difficulties by Ann Dowker. 2001; component assessment and targeted intervention in the pilot scheme
For a child who can recite numbers but cannot connect them to quantities, an intervention can make the relationship between number words, numerals and ordered quantities explicit. Geetha B. Ramani and colleagues tested a linear number board game against an otherwise similar color board game with low-income preschoolers. Roughly an hour of play improved several numerical outcomes, including magnitude comparison, counting, numeral identification and number-line estimation; gains were retained at a nine-week follow-up. The matched game comparison helps separate numerical content from merely receiving attention or playing with an adult.[ref]
Promoting broad and stable improvements in low-income children's numerical knowledge through playing number board games by Geetha B. Ramani and others. 2008; numerical versus color board, four outcomes and retention
The result supports a mechanism-informed activity, but its scope needs care. Low-income preschoolers are not equivalent to children diagnosed with developmental dyscalculia. A number-board game combines several cues—counting words, movement, spatial order and numerals—so improvement does not uniquely identify which cue was necessary. Transfer to the assessed numerical tasks is informative without proving a lasting effect on every school arithmetic outcome. An extension should test classroom implementation and broader learning rather than equating a promising short intervention with complete remediation.
Practice can then be selected according to a learner's developing strategies. Lynn S. Fuchs and colleagues randomized at-risk first-graders to tutoring with speeded practice, tutoring with nonspeeded practice or no tutoring. Both tutoring conditions shared a substantial number-knowledge component and differed in the final five minutes of each session. Sixteen weeks of tutoring improved mathematical outcomes, while the practice contrast provided additional evidence about efficient counting and arithmetic learning. Because most instruction was shared, the comparison does not test timed practice as a stand-alone replacement for teaching concepts.[ref]
Effects of first-grade number knowledge tutoring with contrasting forms of practice by Lynn S. Fuchs and others. 2013; shared number-knowledge tutoring and randomized practice contrast
This design is useful because it distinguishes package benefit from a narrower component question. A teacher observing that children improve after frequent arithmetic practice cannot tell whether time, feedback, explanation or practice format produced the gain. Randomizing a well-defined component within otherwise similar sessions provides a more interpretable answer. Yet a component can have different effects at different levels of prior knowledge. Testing those interactions requires prespecified measures and sufficient statistical power, not selecting a subgroup only after the average result is disappointing.
Computer delivery can adapt task difficulty and record detailed responses, but an adaptive interface is not evidence of efficacy. Pekka Räsänen and colleagues randomized children with low numeracy between two computer games emphasizing different numerical representations. The study found improvements in number comparison, with more limited generalization to other skills. It therefore supports asking which representation is trained and which outcome changes, rather than treating all improvement as a rise in general mathematical ability. The modest study and comparison structure also limit a universal ranking of software.[ref]
Computer-assisted intervention for children with low numeracy skills by Pekka Räsänen and others. 2009; randomized game comparison and outcome-specific transfer
A common alternative is to train a domain-general capacity thought to constrain mathematics. The crucial distinction is between association and intervention: working memory can predict performance without working-memory practice becoming an effective arithmetic treatment. Darren L. Dunning and colleagues randomized children with low working memory to adaptive training, low-level practice or a comparison condition. Improvements in related memory performance did not establish a corresponding generalized academic benefit. The study illustrates why near transfer should not be presented as demonstrated far transfer to mathematics.[ref]
Does working memory training lead to generalized improvements in children with low working memory? by Darren L. Dunning and others. 2013; randomized training comparison and limits of academic generalization
Intervention evaluation should include untaught examples, delayed tests and classroom-relevant performance. A program that only improves practiced items may still have value, but its claim is narrower than improving flexible calculation or word-problem understanding. Blinded assessors, comparable adult contact, monitoring of attendance and suitable analysis of class or school clustering strengthen inference. A no-treatment comparison estimates the package effect relative to ordinary opportunities; an active comparison is needed for stronger claims about distinctive instructional ingredients.
Researchers should also ask why an intervention fails. A child may not understand the vocabulary, may be overloaded by instructions or may have had too little opportunity to participate. Mathematical anxiety can affect engagement, but it should not become an unfalsifiable explanation for every weak response. Fidelity and acceptability matter alongside cognitive mechanism: an effective activity in a closely supported laboratory may be difficult to deliver in an ordinary classroom. Those constraints are part of the educational intervention, not distractions from its psychological theory.
The practical model is a cycle of assessment, targeted teaching and reassessment. Performance can determine the next task, while repeated review prevents a provisional description from becoming a permanent ceiling. A strong design measures proposed processes before outcomes, then tests whether the intervention changed the intended process and whether that change predicts relevant learning. Statistical mediation alone remains weaker than a selective manipulation of the mechanism, especially when motivation and extra teaching change together.
The contribution of psychology is not one universal cure but a disciplined way to match an instructional problem to a testable account of learning. Targeted number teaching has encouraging experimental support; the evidence also warns against mistaking commercial sophistication, trained-task improvement or a correlational cognitive predictor for demonstrated mathematical benefit. Evaluation should remain tied to the particular child population, content and transferable outcome claimed.
Separating pupils by attainment is not, by itself, a reliable solution to individual differences. Benefits depend on whether the arrangement changes the instruction pupils receive, while costs can arise from restricted opportunities, inaccurate placement and persistent labels. Evidence distinguishes whole-curriculum separation from subject-specific and flexible grouping; it does not justify treating all forms as one intervention. Current achievement should also not be mistaken for a fixed measure of learning potential.
Streaming by attainment assigns a pupil to a group across much of the curriculum. Subject setting regroups pupils for a particular subject, allowing different placements in, for example, reading and mathematics. Within-class grouping creates smaller instructional groups inside a shared classroom and can be revised by task. These arrangements differ in exposure to peers, teachers, curriculum and opportunities to move. A finding about flexible mathematics groups therefore cannot automatically defend an enduring all-subject stream.
The favorable hypothesis is instructional fit. A narrower range of prior knowledge may let a teacher select examples, pace and support more accurately, while advanced pupils avoid unnecessary repetition. But the group label must actually change the lesson in a useful way. Separating pupils and then delivering the same unsuitable instruction supplies little reason to expect benefit. Nor does an appropriate lesson logically require fixed separation: formative assessment and flexible task allocation can address differences within a mixed classroom.
Robert E. Slavin's best-evidence synthesis distinguished assignment to self-contained ability classes, which lacked a general achievement advantage, from some subject regrouping and within-class mathematics arrangements with more favorable results. Its conditions emphasized reassessment and adapting the level and pace of teaching. The historical importance is the distinction between organization and instruction, not a timeless verdict that any arrangement called “grouping” works. A synthesis also inherits variation in the quality of its constituent comparisons.[ref]
Ability grouping and student achievement in elementary schools: a best-evidence synthesis by Robert E. Slavin. 1987; separate conclusions on self-contained classes, subject regrouping and within-class instruction
Saiying Steenbergen-Hu and colleagues' later second-order meta-analysis likewise separated forms of grouping. Across thirteen meta-analyses, between-class grouping showed little overall achievement benefit, while within-class grouping, cross-grade subject grouping and specialized arrangements had more positive average results. Acceleration was analyzed separately and should not be collapsed into ordinary attainment sorting. The evidence spans school ages and implementations, so its averages are not estimates of one particular primary-school policy. Reviews that share primary studies are also not independent replications to be counted as separate votes.[ref]
What one hundred years of research says about the effects of ability grouping and acceleration on K–12 students' academic achievement: findings of two second-order meta-analyses by Saiying Steenbergen-Hu and others. 2016; grouping categories, second-order synthesis and separate acceleration analyses
These conclusions do not establish that tracking must harm low-attaining pupils in every setting. Esther Duflo and colleagues conducted a randomized tracking experiment in 121 Kenyan primary schools. In that context, tracking benefited lower-achieving pupils through better instructional targeting, despite the potential advantages of exposure to higher-achieving peers. The experiment provides a causal counterexample to a universal claim that mixed-attainment classes are always best. Its teacher incentives, curriculum and wider school conditions also limit transfer to a different education system.[ref]
Peer effects, teacher incentives, and the impact of tracking: evidence from a randomized evaluation in Kenya by Esther Duflo and others. 2011; randomized primary-school tracking experiment and instructional-level mechanism
The Kenyan result helps distinguish two effects often conflated in discussion. Peer effects concern how classmates' skills or behavior influence learning; instructional targeting concerns what a teacher teaches to whom. They can act in opposite directions. A lower-attaining group might lose some peer opportunities yet gain a lesson that it can use. A different system could concentrate less experienced teachers or narrow tasks in the same group, producing a different outcome. The causal question is therefore the effect of the whole implemented arrangement, not a social label in isolation.
Placement creates further challenges. An assessment contains measurement error and reflects prior opportunity, language and familiarity with the task. Selecting pupils at one time point can therefore turn temporary performance differences into apparently stable categories. Even frequent movement on paper is insufficient if movement rarely occurs in practice. Researchers need placement histories and the material actually taught, not only the school's description of its policy. Comparing final scores of high and low groups is especially uninformative because initial attainment helped define those groups.
Teacher expectations and children's interpretations of their placement are plausible additional pathways. A label can affect the challenge offered or the opportunities to demonstrate improvement; a child may interpret it as a statement of fixed worth. These are hypotheses requiring direct measurement rather than automatic explanations for every group difference. Self-concept, participation and belonging matter even when an average test score is unchanged. Conversely, a pupil may value appropriately demanding peers and tasks, so increased challenge should not be equated with social harm merely because it involves grouping.
A useful evaluation would randomize schools or classes to well-specified arrangements, measure baseline attainment before allocation and monitor curriculum, staffing and movement. It should retain an intention-to-treat comparison rather than excluding pupils whose placements changed. Multilevel analysis or appropriate uncertainty estimates are required when pupils share teachers or classrooms. Prespecified subgroup analyses can ask whether effects differ by starting attainment, while distributional outcomes show whether an average gain masks widening gaps. Longer follow-up is important because early curricular restriction may have consequences beyond an immediate assessment.
The relevant comparison should be equally credible. A well-resourced setting program compared with an under-supported mixed class does not identify separation alone as the active ingredient. Equally, a mixed class receiving no help to differentiate instruction is not a decisive test of responsive mixed teaching. Comparing arrangements under explicit resource and implementation conditions makes the evidence more useful for practice. It also permits testing whether flexibility and good assessment capture the benefit without committing pupils to permanent categories.
For primary education, where performance profiles and opportunities can change quickly, the most defensible principle is responsiveness. Grouping may serve a specific instructional purpose when it is revisable and tied to what the pupil needs to learn next. Its effects should be monitored rather than justified by a presumed innate hierarchy. Maintaining ambitious curriculum access and checking actual movement are safeguards whose value should be assessed alongside attainment, not assumed to follow from a policy name.
The research supports evaluating instructional fit, opportunity and flexibility rather than endorsing streaming or setting as default answers to individual differences. Broad between-class sorting has weak average support, while particular subject and within-class arrangements can help under specified conditions. A successful contextual experiment does not universalize the policy, and an overall null average does not make the content and quality of teaching irrelevant.
Language matters substantially for reading, but spoken-language competence, properties of the writing system and the conditions of instruction must be distinguished. Different orthographies change the difficulty and useful grain of decoding, while oral language remains crucial for constructing meaning. Cross-language differences therefore do not imply that children have fundamentally different reading minds or that speaking one language sets a fixed ceiling on literacy.
Reading performance is not a single outcome. Word decoding can be accurate but slow; fluent pronunciation can occur without good reading comprehension. Alphabetic writing connects graphemes with phonemes, but those correspondences differ in consistency and complexity. Spoken vocabulary and sentence understanding contribute to interpreting a text after its words have been identified. The language a child speaks at home is also distinct from the language being learned at school and from the script used to write either language. These distinctions determine what a study can show.
Philip H. K. Seymour and colleagues compared early literacy acquisition across European orthographies, using word and nonword reading. Basic accuracy developed more slowly in deep orthographies, especially English, than in many more consistent systems; syllabic complexity also mattered. The result shows why an English reading milestone should not be assumed to describe every language. However, countries differ in school entry, teaching and exposure, so the study does not randomly isolate spelling consistency from all other features of instruction and language.[ref]
Foundation literacy acquisition in European orthographies by Philip H. K. Seymour and others. 2003; early word/nonword acquisition, orthographic depth and syllabic complexity
The mechanism is plausible without making language an all-or-none determinant. When a grapheme has a relatively reliable pronunciation, a beginning reader can more often apply a small-unit correspondence successfully. An inconsistent mapping makes larger patterns and word-specific information more valuable. This does not mean that an inconsistent orthography should be taught by visual memorization alone, or that a consistent one eliminates the need for phonological skills. It predicts differences in how information is combined, as well as in the pace at which basic accuracy reaches ceiling.
Longitudinal comparison can test shared predictors more directly. Markéta Caravolas and colleagues followed children learning English, Spanish, Czech and Slovak over ten months. Phoneme awareness, letter knowledge and rapid automatized naming predicted later literacy growth in all four languages, whereas verbal memory span was not a reliable unique predictor in the reported models. The study used comparable component measures and modeled prior literacy. Its findings support common proximal skills across orthographies while leaving room for differences in levels and rates of learning. Prediction still does not establish that practicing any one predictor will necessarily cause better reading.[ref]
Common patterns of prediction of literacy development in different alphabetic orthographies by Markéta Caravolas and others. 2012; longitudinal multigroup models and component-skill predictors
Measurement matters in interpreting such comparisons. A pronunciation-accuracy task can become too easy to reveal meaningful differences in a consistent orthography, while speed or comprehension continues to vary. A rapid naming task measures a coordinated performance, not one isolated neural process. Similarly, a nonword is only comparable across languages if its phonological and orthographic demands are appropriate. Equivalent labels on tests do not establish measurement invariance. Claims about universal causes need to survive those design problems rather than rely on national mean differences.
Not all writing systems organize the task in the same way. Chinese characters commonly provide information relevant to morphemes and syllables, so an account based only on an English-style phoneme task is incomplete. Hua Shu and colleagues compared Chinese children with developmental dyslexia and age-matched controls using multiple cognitive measures. Morphological awareness, naming and vocabulary were particularly informative, with morphological awareness strongly associated with literacy measures. This supports examining linguistic units beyond phonemes. The selected dyslexic comparison is not a randomized manipulation of writing system or proof that phonology has no role in Chinese reading.[ref]
Understanding Chinese developmental dyslexia: morphological awareness as a core cognitive construct by Hua Shu and others. 2006; fifth/sixth-grade comparison and multiple cognitive constructs
Oral-language competence also matters within one orthography. A child may decode a word yet not know its meaning or be able to integrate its sentence with the rest of a passage. Vocabulary, grammatical interpretation and relevant knowledge contribute to reading comprehension. A low comprehension score therefore should not automatically trigger more decoding practice when the child's main difficulty concerns language understanding. Conversely, strong spoken understanding does not remove the need to learn how a script represents words.
Paula J. Clarke and colleagues tested interventions for children whose reading comprehension was poor despite relatively adequate word reading. They compared text-comprehension, oral-language and combined approaches with a control condition. The trial found benefits from intervention, with particularly informative delayed gains for the oral-language approach and vocabulary-related change. This provides stronger evidence for a contribution from language-focused teaching than a cross-sectional correlation alone. It does not establish vocabulary change as the sole causal mediator, because the intervention changed several experiences together.[ref]
Ameliorating children's reading-comprehension difficulties: a randomized controlled trial by Paula J. Clarke and others. 2010; randomized poor-comprehender interventions and delayed outcomes
The question about the language children speak therefore requires care with bilingualism and dialect. Limited experience with the language of a particular test can affect performance without demonstrating a general learning deficit. Dialect differences should not be treated as absence of language, and unfamiliar vocabulary can obscure a child's understanding of a concept. Studies should measure relevant language experience, exposure to print, educational opportunities and the task language. These considerations identify confounds and assessment needs rather than proving that every bilingual experience produces the same advantage or disadvantage.
Teaching implications are correspondingly differentiated. Explicit links between written and spoken units can be adapted to the writing system while meaningful oral and written language activities develop comprehension. Assessing decoding, fluency and understanding separately helps identify the target. Children learning a new language of instruction may need opportunities to build vocabulary and demonstrate understanding without being assigned a fixed low-ability identity. Cross-language evidence is useful for testing which principles generalize, not for copying an entire curriculum while ignoring context.
The strongest conclusion is substantial linguistic influence with shared learning resources and modifiable opportunities. Orthographic properties affect the path to accurate and fluent word reading; spoken-language knowledge affects understanding; instruction and exposure shape both. Reading performance cannot be attributed to the name of a language alone, and evidence about one component should not be substituted for evidence about the whole task.
Children possess structured expectations about living things, but knowledge of biological words, causal mechanisms and illness risk develops unevenly. Those expectations can shape pandemic explanations and emotions without determining one uniform reaction. Developmental findings are useful for generating predictions about children's interpretations; direct pandemic data are needed before those predictions are treated as demonstrated responses to COVID-19.
Intuitive biology includes expectations about growth, internal properties, needs and the persistence of kinds despite changes in appearance. Susan A. Gelman and colleagues' experiments showed that children can attend to nonobvious internal properties rather than reasoning only from what an object looks like. This challenges a picture of young children as entirely restricted to surface appearance. It does not establish a complete adult theory of physiology or a correct understanding of every invisible cause. An experiment on familiar animals is also not a direct test of understanding a novel infectious disease.[ref]
Insides and essences: early understandings of the non-obvious by Susan A. Gelman and others. 1991; internal properties, category judgments and nonobvious biological expectations
Children's explanations can nevertheless extend beyond adult biological boundaries. Deborah Kelemen compared preferences for purpose-based and physical explanations of natural properties. Children accepted teleological explanations more broadly than adults, including for nonliving features. The tasks suggest a readiness to interpret nature in terms of what things are for. Their forced alternatives and wording constrain what follows: the result does not show that every child believes all natural events are intentionally designed, or that a child cannot understand a mechanistic explanation when it is made available.[ref]
Why are rocks pointy? Children's preference for teleological explanations of the natural world by Deborah Kelemen. 1999; judgments of purpose-based and physical explanations
Applied to a pandemic, teleological reasoning could encourage a question about what a virus or restriction is “for,” rather than what caused it. A virus need not be understood as a tiny agent with human intentions for the child to ask that question. Adults can help distinguish the reason for a public-health decision from the biological cause of an illness. This is an educational implication of the developmental account, not an empirical claim that the laboratory study measured children's pandemic beliefs.
Knowledge about germs is a particularly important case of facts versus a causal system. Gregg E. A. Solomon and colleagues presented stories in which similar symptoms arose through different causes and asked about contagion. Across five studies, preschoolers' answers often failed to integrate germs into a consistent biological causal account. Some responses were more compatible with treating particular symptoms as contagious than with tracking the cause. Additional tasks questioned whether children understood germs as distinctively biological agents. Knowing the word “germ” therefore should not be equated with understanding how illness can spread.[ref]
On facts and conceptual systems: young children's integration of their understandings of germs and contagion by Gregg E. A. Solomon and others. 1999; matched-symptom stories, cause-based contagion judgments and germ-property studies
That distinction yields concrete predictions. A child might overgeneralize danger from any visible sign of illness, fail to understand why someone who appears well can still matter in a disease account, or apply a rule correctly without being able to explain it. Conversely, prior discussion, schooling and family experience can support more coherent reasoning. These possibilities require direct assessment rather than inference from age alone. Children can also learn a practical action through trusted instruction before they possess an adult mechanism; practical participation and conceptual completeness are different outcomes.
Psychological essentialism can support expectations of stable kinds, but it can also encourage an overly fixed distinction between “safe people” and “sick people.” Infection status and a person's moral worth are not the same property. A useful educational account can explain change and recovery without assigning blame to a person or community. This is a reason to examine the interpretation of biological categories, not to attribute prejudice automatically to every child's causal error. Context and what adults say matter alongside the child's prior concepts.
There is direct evidence that school-age children actively sought to understand the pandemic. Lucy Bray and colleagues surveyed 390 children aged seven to twelve and caregivers in six countries during the first wave. The online survey combined closed and open questions about information, knowledge and needs. Parents were a major information source, with school more prominent in Sweden; adults often filtered information, yet children still reported awareness of serious consequences. The study shows active interpretation and unmet information needs rather than simple ignorance protected by adult silence.[ref]
Children's health literacy relating to a global pandemic (COVID-19): an international cross-sectional study by Lucy Bray and others. 2021; first-wave six-country child/caregiver survey and information-source findings
Its method also limits the conclusion. An online volunteer sample is not representative of all children, countries experienced different conditions, and a factual statement in a survey is not a detailed causal model. Older school-age participants should not be treated as interchangeable with preschoolers in the germ studies. Nor does the survey establish that a particular explanation reduced anxiety or changed behavior: that would require a comparison or intervention design. Cross-study differences in age, questions and context can explain apparent inconsistencies without requiring that one result be dismissed.
Emotional reactions can be understandable even with accurate biological knowledge. Concern about relatives, changes to routines and loss of ordinary contact are not simply failures to understand germs. Information can also interact with perceived control and the consistency of adults' explanations. An implication is to ask what the child thinks and fears before selecting an explanation. Developmental knowledge should help make a conversation interpretable, not be used to assume that a child is incapable of understanding or ought to be unconcerned.
An educational approach can distinguish agents, causes and protective decisions using accessible explanations, ask children to apply an idea to a new case and correct a misunderstanding without shame. Checking transfer is more informative than asking whether the child can repeat a phrase. Explanations can acknowledge uncertainty and distinguish a possibility from its probability. This remains a general communication principle; it is not a substitute for appropriate, time-specific health advice, and the examination does not provide data for choosing a clinical or public-health protocol.
A rigorous follow-up would measure prior biological reasoning and language, elicit pandemic explanations in the child's own words, and separately assess factual knowledge, emotion and action. An age-appropriate explanatory intervention could then be compared with equally supportive information, using delayed tests and unfamiliar scenarios. Family circumstances and educational access would need measurement. Such a design would test whether changing understanding contributes to a better outcome, rather than assuming that knowledge and reassurance are equivalent.
The research predicts a mixture of genuine biological insight, incomplete mechanisms and active meaning-making. It supports listening to children's explanations, differentiating factual labels from causal understanding and testing communication rather than relying on a simple age stereotype. Pandemic reactions arise within families, schools and changing circumstances as well as within the child's developing concepts.
Public understanding of neuroscience can be improved, and some neuromyth beliefs can be reduced, but better quiz performance does not itself establish better teaching or pupil attainment. The educational case depends on a chain from understanding to decisions, implementation and learning outcomes. Each link requires evidence. Brain-related language can inform a sound educational explanation, but its presence is not a substitute for a test of the proposed method.
A neuromyth is a misconception presented as following from knowledge about the brain. Examples include rigid learner types inferred from hemispheric labels or the claim that teaching should be matched to a learner's preferred sensory modality. Preferences and individual differences are real phenomena, but a preference for a format does not prove that learning is better in that format. Nor does a demonstration of neural involvement establish a unique classroom prescription: every learning activity has biological implementation.
Sanne Dekker and colleagues surveyed teachers about general brain knowledge and common neuromyth statements. Myth endorsement was frequent even in a sample interested in educational neuroscience, and greater general knowledge did not provide a simple guarantee against misconceptions. This is evidence about the co-occurrence of facts and beliefs in that sample, not a randomized test that neuroscience education makes teachers worse. Questionnaire wording and recruitment also affect prevalence estimates, so a headline percentage should not be generalized to every teacher.[ref]
Kelly Macdonald and colleagues compared respondents with different education and neuroscience backgrounds. Greater relevant training was associated with lower endorsement, yet misconceptions remained. Because training was not randomly assigned, the study cannot isolate its causal effect from selection, interests and other educational differences. Its value is to show that expertise and misinformation are not all-or-none categories. A useful public program needs more than exposure to additional terminology; it should support evaluating how a claim follows from evidence.[ref]
Dispelling the myth: training in education or neuroscience decreases but does not eliminate beliefs in neuromyths by Kelly Macdonald and others. 2017; cross-sectional training-background comparisons and persistent misconceptions
Deena Skolnick Weisberg and colleagues supplied a possible reason for undue credibility. Participants judged explanations that varied in quality and in whether they included neuroscience information irrelevant to the logic. Such information increased the apparent satisfaction of some explanations, particularly poor ones, among nonexperts; relevant expertise changed the pattern. This was a text-explanation experiment, not a demonstration that every brain image persuades a teacher or that all biological explanation is misleading. It suggests teaching people to ask whether the extra information actually improves the argument.[ref]
The seductive allure of neuroscience explanations by Deena Skolnick Weisberg and others. 2008; explanation-quality and irrelevant-neuroscience manipulations
The learning-style matching hypothesis makes the evidential requirement especially clear. Classify a preference before instruction, randomly allocate learners within each preference group to formats, and assess both with a fair common outcome. Matching predicts that the preferred format is better within each group. In notation, if is mean learning for preference and format , the visual/auditory version requiresA main effect in which one format helps everyone is not this pattern. Even a statistical interaction is insufficient if one format remains better in both groups. Preference reports or satisfaction ratings alone do not test the proposed learning advantage.
Original illustrative patterns for testing learning-style matching; hypothetical scores, not experimental data
. Details. 
Beth A. Rogowsky and colleagues tested preferences, instructional format and comprehension using audio and written materials with college-educated adults. The findings did not support the predicted matching benefit. That is a direct test of a specific meshing hypothesis, not proof that every individual difference is educationally irrelevant. Its adult sample also limits a claim about every primary-age child. A sensible response is to select representations for the content and learning goal, then evaluate their effect, rather than assign a permanent type from a preference questionnaire.[ref]
Matching learning style to instructional method: effects on comprehension by Beth A. Rogowsky and others. 2015; preference assessment, audio/e-text instruction and comprehension outcomes
Correction experiments provide a more direct answer about reducing myths. Marta Ferrero and colleagues exposed teacher-education students to refutation texts, variants adding origin information, and comparison conditions. Myth endorsement decreased immediately but the benefit was short-lived and intentions to use related educational methods did not show a corresponding improvement. This separates correcting a statement from changing an instructional decision. It also shows why an immediate post-course questionnaire is an incomplete evaluation of a neuroscience-literacy program.[ref]
An attempt to correct erroneous ideas among teacher education students: the effectiveness of refutation texts by Marta Ferrero and others. 2020; refutation conditions, delayed endorsement and intended teaching practices
The mechanism of a useful correction should therefore be considered rather than assumed. A refutation text can state what is wrong and supply a better explanation; repeated application to new examples could help learners use that explanation rather than merely remember the correct answer. Opportunities to compare claims, evaluate controls and identify an unjustified inference are plausible additions. Their effectiveness still needs testing, including retention and behavior, rather than being declared established because they sound scientifically sophisticated.
Educational benefit is possible through better decisions and reduced opportunity cost. Time and money spent diagnosing unsupported fixed learner types could be redirected to evaluating subject-specific instruction and formative assessment. A neuroscience account might also help explain genuine constraints without labeling them as immutable. Yet correcting a belief is not automatically equivalent to changing established classroom routines, and a teacher can use an effective practice while holding an inaccurate account of why it works. Evidence about beliefs should therefore not be used as a complete ranking of teaching quality.
A stronger evaluation would compare a neuroscience-literacy program with an equally credible program teaching general research literacy. It would measure immediate knowledge, delayed reasoning about unfamiliar claims, actual instructional choices and relevant pupil outcomes. Randomization and appropriate analysis of class or school clustering would help distinguish the effect from recruitment of unusually motivated teachers. Process measures could ask whether changed reasoning altered decisions, while implementation data show whether those decisions reached pupils. The benefit of a label such as “brain-based” should never be the outcome being optimized.
Reducing neuromyths is achievable to a degree, but durable understanding and positive educational effects must be demonstrated separately. The most promising aim is not collecting isolated brain facts; it is learning to connect a claim, its mechanism, a fair test and the outcome that matters. Neuroscience can contribute to that process alongside cognitive and educational psychology, with its practical value judged by evidence rather than prestige.
Part II advanced option in the held 2022 papers. The source examination is shared by the psychology (experimental) course of the University of Oxford and the psychology, philosophy and linguistics course of the University of Oxford.
Worked essays for all six options in the historical paper dated 30 May 2022. Source release: Oxford psychology examination release, member
a15655w1.pdf. Part II is the audited classification retained from the scaffold; the cover itself prints Second Public Examination. The paper asks candidates to select three questions, whereas this study edition addresses every option. The research used below predates the examination; current portrait and diagnostic-reference pages are identified separately from research findings.Psychological resilience is best defined as successful adaptation in the context of significant adversity, specified by outcome, developmental context and time. It is inferred from an adversity–adaptation relationship, not established merely by a high personality score or the absence of a diagnosis at one assessment. The definition needs both credible exposure and an explicit criterion of adaptation: an unexposed person with good mental health has not thereby demonstrated resistance to that particular challenge.
Suniya S. Luthar and colleagues emphasized this dual requirement and the danger of treating success in one domain as success in all domains. A young person might maintain academic performance while experiencing substantial depression, or recover emotionally while material circumstances remain difficult. An investigation should therefore state whether it concerns symptoms, social relationships, school functioning or several outcomes. It should not define psychological resilience as every desirable attribute simultaneously, because that makes meaningful measurement and explanation nearly impossible.[ref]
The Construct of Resilience by Suniya S. Luthar and others. 2000, definition, multidimensionality and operational criteria
Time is equally important. Stable low disturbance, initial disturbance followed by recovery after adversity, chronic difficulty and delayed deterioration are different trajectories. A single post-event score can confuse them, especially without a pre-event baseline. George A. Bonanno and colleagues assessed 205 people before spousal bereavement and again at six and eighteen months afterward. They identified several patterns, including relatively stable adaptation, chronic difficulties and improvement from pre-existing depression. The prospective baseline made distinctions possible that a retrospective “how well did you cope?” question could not establish.[ref]
Resilience to loss and chronic grief by George A. Bonanno and others. 2002, preloss assessment, follow-up and five observed patterns
Different histories of adaptation can share the same score at one follow-up
. Original schematic trajectories around an adverse event. Curves are constructed illustrations, not fitted classes or data from the cited bereavement study. They distinguish stable low symptoms, recovery, persistent distress and delayed deterioration without asserting universal population proportions. Details.
Trajectory methods need their own scrutiny. A growth mixture model can describe heterogeneous longitudinal patterns, but the number and size of classes depend on assumptions about within-class variation and error. Frank J. Infurna and colleagues reanalyzed responses to bereavement, divorce and unemployment. Relaxing restrictions on class variances and within-class change substantially altered the apparent prevalence of a resilient class. This demonstrates model dependence, not that every earlier low-distress trajectory was fictitious. Researchers should compare plausible models, report uncertainty in class assignment and avoid treating a convenient latent class as a naturally discrete kind of person.[ref]
Resilience to Major Life Stressors Is Not as Common as Thought by Frank J. Infurna and Suniya S. Luthar. 2016, reanalysis and alternative growth-mixture specifications
Exposure measurement must characterize what happened, its severity, duration, developmental timing and relevant context. Counting heterogeneous events as equivalent can conceal very different experiences. Subjective appraisal matters, but using the same distressed respondent to report both adversity and symptoms can create common method variance. Independent records, contextual interviews and repeated assessments improve inference, while still potentially missing chronic insecurity or unrecorded events. Exposure groups also need comparable follow-up opportunities: selective loss of the most impaired participants can make adaptation appear better than it was.
Adaptation should be measured with reliable, culturally appropriate instruments and, where feasible, several informants. Absence of disorder and positive functioning are related but distinct outcomes. Cutoffs need justification and sensitivity analysis; moving a threshold should not silently redefine a large group as resilient. Measurement invariance matters when comparing ages, languages or social groups. Biological measures of psychological stress may clarify a mechanism, but a low cortisol response alone is not a complete assessment of psychological functioning or evidence of a universally optimal response.
Self-report capacity measures have a useful but narrower role. The original Connor-Davidson Resilience Scale, developed by Kathryn M. Connor and Jonathan R. T. Davidson, contains 25 items rating perceived coping-related qualities. Its original validation examined community and clinical samples and sensitivity to treatment-associated change. These findings support a measurable self-reported construct; they do not prove that the scale independently identifies successful adaptation to a documented adversity. Concurrent symptoms can influence perceived competence, so prospective prediction beyond baseline distress is a stronger test than a concurrent correlation.[ref]
Development of a new resilience scale by Kathryn M. Connor and Jonathan R. T. Davidson. 2003, original 25-item scale, validation samples and treatment-associated change
Another approach measures better-than-expected outcomes conditional on exposure. With distress and adversity , one possible score is , where predicts distress. Higher then means less distress than the selected model predicts. Ananda B. Amstadter and colleagues used a regression residual-based approach in longitudinal twin research. Its advantage is explicit conditioning on exposure; its limitations are dependence on the reference sample, exposure measurement and prediction model. An in-sample regression residual is not a new independent biological capacity.[ref]
Psychiatric resilience: longitudinal twin study by Ananda B. Amstadter and others. 2014, exposure-conditioned symptom residual phenotype
The best design combines prospective adversity measurement, pre-event functioning and repeated, multidomain outcomes, with an operational definition registered before outcome selection. Capacity scales, trajectories and regression residual scores can answer complementary questions if their differences are preserved. Psychological resilience should be treated as a context-dependent pattern of adaptation that can change, while proposed capacities and protective mechanisms are tested as predictors of that pattern. Otherwise the explanation becomes circular: calling someone resilient because they did well cannot itself explain why they did well.
Psychological resilience research has redirected prevention toward strengthening modifiable adaptive systems and reducing avoidable adversity, rather than identifying unusually invulnerable people. Its contribution is a set of hypotheses about protective processes and developmental opportunities. Whether an intervention actually promotes adaptation must then be established through appropriate comparisons and meaningful follow-up outcomes; the word “psychological resilience” in a program title is not evidence of effectiveness.
Early longitudinal work, including Emmy E. Werner's Kauai research, showed that high-risk developmental histories did not imply uniformly poor outcomes. Later synthesis by Ann S. Masten argued that adaptation often relies on ordinary systems such as effective caregiving, self-regulation and learning. This suggests three broad intervention routes: reduce exposure, preserve external supports and strengthen relevant coping or regulatory skills. The implication is ecological: a child's capacities operate through relationships and opportunities, not in isolation from them.[ref]
Risk, resilience, and recovery by Emmy E. Werner. 1993, developmental follow-up and protective processes
[ref]Ordinary magic by Ann S. Masten. 2001, adaptive systems and implications for intervention
A protective correlate is not automatically a causal target. Good parenting may accompany unmeasured resources, and a child's behavior may affect parenting. Intervention development therefore needs a proposed mechanism, a feasible procedure and a test of whether changing it improves subsequent functioning. It also needs to distinguish a promotive factor, beneficial across adversity levels, from a stress-buffering interaction, whose effect depends on exposure. Both can be useful; neither is established by simply correlating a questionnaire with current well-being.
The Penn Resiliency Program illustrates efforts to teach coping and cognitive skills in schools. Jane E. Gillham and colleagues randomized 697 children across three middle schools to the program, an alternative program controlling nonspecific ingredients, or a control condition. There was no overall reduction in average depressive symptoms across the full sample, although benefits appeared in two schools and not the third. The active comparison improved the test of specificity. The variation cautions against assuming that a curriculum transfers unchanged across settings or that a symptom effect establishes prevention of first-onset disorder.[ref]
School-Based Prevention of Depressive Symptoms by Jane E. Gillham and others. 2007, three-arm trial, school variation and three-year follow-up
Family interventions put supportive relationships closer to the proposed mechanism. The Family Bereavement Program uses caregiver and youth groups to develop parenting, coping and communication after parental death. Its randomized follow-up found benefits in several symptom and functioning domains six years later, while diagnostic effects varied with baseline problems. This is consistent with strengthening adaptation after a defined adversity, rather than treating ordinary grief as illness. A literature-control comparison, however, does not separate the specific skills from all benefits of group attention and support.[ref]
Six-year follow-up of a preventive intervention for parentally bereaved youths by Irwin Sandler and others. 2010, intervention components, comparison condition and outcome-specific follow-up
Environmental intervention can be still more direct. In the Bucharest Early Intervention Project, institutionalized young children were randomized to a supported foster-care offer or care as usual. Katie A. McLaughlin and colleagues assessed attachment security at 42 months and internalizing outcomes at 54 months. The foster-care intervention reduced internalizing disorders among girls, with attachment findings consistent with a protective pathway; a comparable statistically demonstrated intervention effect was not found in boys. A significant result in one sex and a nonsignificant result in the other do not alone establish an interaction. This supports changing a caregiving environment while preserving the sex- and outcome-specific limits of the result.[ref]
Attachment security as a mechanism linking foster care placement to improved mental health outcomes in previously institutionalized children by Katie A. McLaughlin and others. 2012, randomized foster-care offer, attachment assessment and internalizing outcomes
The mediator claim deserves separate evaluation. Placement was randomized; attachment security was not. Attachment may mark other changes in caregiving, and mediator–outcome confounding can survive randomization of the overall intervention. The trial therefore provides stronger causal evidence for the foster-care package than for attachment as its unique active ingredient. This distinction turns psychological resilience theory into a research program: assess whether proposed processes change before outcomes, examine alternatives and test components where ethical and feasible.
Structural resources also matter. E. Jane Costello and colleagues exploited a casino-related income supplement during a longitudinal study. Children in families lifted out of poverty showed improvements particularly in conduct and oppositional symptoms, while anxiety and depression symptoms did not show the same benefit. Although not a randomized cash trial, the externally generated change offered stronger leverage than a cross-sectional poverty–symptom correlation. It shows why prevention need not consist solely of training a person to tolerate an unchanged environment.[ref]
Relationships between poverty and psychopathology by E. Jane Costello and others. 2003, natural experiment and outcome-specific effects
Targeting can be universal, selective or indicated, according to population risk and early symptoms. Judy Garber and colleagues' depression-prevention trial found an overall benefit from a cognitive-behavioral program in high-risk adolescents but no demonstrated benefit when the parent was currently depressed. Because eligibility also included previous episodes, the study mixes first-onset and recurrence-related questions. Its relevance is that individual skills can depend on family context; it does not justify a universal exclusion rule based on one subgroup analysis.[ref]
Prevention of Depression in At-Risk Adolescents by Judy Garber and others. 2009, eligibility and baseline parental-depression moderation
Finally, evaluation should assess actual exposure, disorder onset, functioning, harms, implementation and durability, not merely improvement on the same psychological resilience questionnaire used to teach the course. Reach and material inequalities affect who can benefit. The strongest influence of psychological resilience research is a move toward developmentally timed, multilevel prevention, evaluated with the same causal rigor as treatment. Protecting ordinary relationships and resources can be as relevant as teaching coping; successful adaptation should remain an outcome to demonstrate rather than a trait attributed to those a program happens to help.
A risk factor is a cause when an appropriate change in that factor would change the relevant psychological outcome, under specified conditions. Prediction and causation are different: a variable can forecast disorder because it is a marker, a consequence of emerging illness, or correlated with an unmeasured cause. Confidence comes from designs that address different alternative explanations and from convergence on a clearly defined exposure, population and outcome.
A cross-sectional study can establish an association and suggest hypotheses, but timing is ambiguous. A depressed respondent may recall more adversity, and family disadvantage may influence both exposure and symptoms. A case–control study is efficient for uncommon disorders but remains sensitive to recall, control selection and exposure misclassification. Adjusting for many measured variables is not automatically an improvement: controlling a consequence of exposure can block a real pathway, while conditioning on a common consequence of exposure and outcome can induce collider bias.
Prospective longitudinal studies improve temporal ordering. In Constance Hammen and colleagues' two-year follow-up, childhood-adversity histories predicted depressive reactions at lower subsequent psychological stress levels. Measuring events and symptoms over time made this more informative than asking affected people retrospectively why they became ill. Yet adversity was not randomized, and histories may be measured imperfectly. Temporal precedence is necessary for the proposed direction of influence, but does not remove familial liability, prior symptoms or unmeasured social circumstances as competing explanations.[ref]
Depression and sensitization to stressors among young women as a function of childhood adversity by Constance Hammen and others. 2000, two-year follow-up and sensitization hypothesis
Stronger observational designs make their counterfactual comparison explicit. A natural experiment exploits an external change that alters exposure without being produced by the same individual characteristics that usually determine it. E. Jane Costello and colleagues observed children before and after an income supplement associated with a casino opening. Comparing developmental changes across differently affected families strengthened the social-causation interpretation for particular behavioral outcomes. It did not randomize poverty, and concurrent community changes or selection into an income-defined subgroup remain possible alternatives.[ref]
Relationships between poverty and psychopathology by E. Jane Costello and others. 2003, longitudinal quasi-experimental comparison
A difference-in-differences analysis formalizes such reasoning as the exposed group's change minus the comparison group's change. Its causal interpretation requires a credible untreated trend comparison, no differential concurrent change that explains the effect, and careful attention to anticipation and changes in sample composition. Merely measuring before and after a policy is not sufficient. Examining pre-intervention trends can expose some problems but cannot prove that every counterfactual assumption is true.
A randomized controlled trial offers another route by breaking systematic baseline links between allocation and measured or unmeasured causes. The foster-care offer in the Bucharest Early Intervention Project is an example of ethically intervening to improve a harmful setting, rather than deliberately assigning children to initial deprivation. Under suitable follow-up and analysis, differences between allocated groups estimate the effect of offering that intervention. Nonadherence, placement changes and attrition still matter. An intention-to-treat analysis retains the allocation comparison; simply regrouping children by the care they eventually received can reintroduce selection.[ref]
Attachment security as a mechanism linking foster care placement to improved mental health outcomes in previously institutionalized children by Katie A. McLaughlin and others. 2012, random allocation and subsequent mental-health assessment
Even a successful trial does not identify the causal contribution of every component. A foster-care package changes several experiences simultaneously. A coping course may alter attention, expectations, peer contact and behavior. To identify a mediator, it is necessary to consider confounding of the mediator–outcome relationship and its temporal ordering, not only whether the treatment changes both mediator and outcome. Conversely, a null intervention can reflect inadequate delivery, insufficient contrast or the wrong developmental timing; it need not prove that the proposed risk factor is irrelevant under every possible intervention.
Genetically informed studies address another set of alternatives. Comparing differently exposed identical twins can reduce confounding by inherited sequence and shared family background. However, exposure differences can arise from nonshared antecedents that also affect disorder, and within-pair measurement error can be substantial. Family and adoption designs are similarly informative without making every remaining environmental association causal. Molecular associations can indicate inherited liability, but linkage disequilibrium and population stratification separate an associated marker from a demonstrated mechanism.
Mendelian randomization uses genetic variants as instruments for an exposure, requiring relevant instruments, independence from exposure–outcome confounders and an exclusion restriction. The design can be useful when its assumptions are credible. It is not a shortcut for every social risk factor: horizontal pleiotropy, parental genetic effects and ancestry structure can create misleading estimates. A genetic score associated with stressful experiences does not necessarily act only through those experiences. This is a methodological distinction, not evidence that any particular untested exposure is causal.
Animal experiments can manipulate mechanisms and timing more tightly. Karen J. Parker and colleagues randomized young squirrel monkeys to intermittent separation experiences or a comparison condition and later tested responses in a novel setting. This supports causal conclusions about that rearing contrast and those measured responses. It does not directly estimate the effect of childhood adversity on human psychiatric diagnoses: species, development, psychological stressor meaning and outcomes differ.[ref]
Prospective Investigation of Stress Inoculation in Young Monkeys by Karen J. Parker and others. 2004, randomized rearing contrast and later behavioral/endocrine tests
The strongest conclusion is obtained when these designs converge despite their different weaknesses, with sensitivity analyses and transparent outcome definitions. A causal claim should specify the contrast it establishes and the alternatives it has not excluded. Prospective timing, externally driven exposure changes, randomization, within-family controls and mechanistic experiments together can provide much stronger evidence than any isolated risk correlation, while still leaving uncertainty about transport to another population or developmental stage.
Individual characteristics contribute to adaptation, but their effects depend on adversity, relationships, opportunities and the outcome being measured. Psychological resilience is therefore not well explained by dividing people into inherently strong and weak types. A useful account asks which characteristic predicts which aspect of functioning under which conditions, and whether changing that characteristic would improve the outcome.
Cognitive capacities can help a person understand a problem, plan a response and use available support. Temperament and emotion regulation may influence how strongly threat is experienced and how readily attention can be redirected. Coping confidence may encourage engagement, while flexible strategies can help match responses to a controllable or uncontrollable situation. These are plausible mechanisms, not proof that a single score measures psychological resilience. Some apparently personal resources, such as social competence, also operate by eliciting or maintaining helpful relationships.
Longitudinal evidence supports contributions from both person and context. Emmy E. Werner's Kauai study followed a birth cohort from early life into adulthood, identifying protective patterns among people exposed to substantial developmental risks. Individual capacities, supportive caregivers and opportunities outside the immediate family all featured in the account. Because these resources were not randomly allocated, their predictive value does not isolate a pure individual effect from the environments that helped develop or express it.[ref]
Risk, resilience, and recovery by Emmy E. Werner. 1993, prospective developmental course and protective-resource clusters
More specific evidence comes from Ann S. Masten and colleagues' ten-year follow-up of 205 children recruited during elementary school. Using multiple methods and informants, they examined academic, conduct and peer competence in relation to adversity. Intellectual functioning and parenting resources predicted favorable outcomes across domains; findings also suggested protective roles for IQ and parenting in relation to antisocial behavior. Resilient adolescents resembled competent low-adversity peers in several ordinary resources rather than exhibiting an entirely separate human type.[ref]
Competence in the context of adversity by Ann S. Masten and others. 1999, longitudinal sample, competence domains and intellectual/parenting resources
The causal interpretation remains qualified. Better intellectual performance can reflect previous schooling, health and caregiving as well as inherited variation. Parenting can respond to child behavior, and both may share unmeasured antecedents. A variable measured before a later outcome is a stronger predictor than a simultaneous self-description, but prediction alone does not establish that raising its score will reproduce the observed benefit. An intervention needs to test the proposed process rather than assume the correlational ordering is causal.
Promotive and buffering effects should also be separated. For an adverse outcome , adversity and resource , consider an illustrative model,When and , the resource has a constant favorable association across the modeled adversity range. A negative instead means that increasing the resource reduces the adversity slope, . This is a psychological stress-buffering pattern on this scale. Neither coefficient alone proves causation; interaction can change with the outcome scale, and a statistically nonsignificant interaction may reflect poor measurement or insufficient power rather than equal effects everywhere.[ref]
The Construct of Resilience by Suniya S. Luthar and others. 2000, precision in protective terminology and interactive patterns
Context can enable or suppress a capacity. Planning is less useful when there are no safe options, and willingness to seek support cannot ensure that responsive support exists. A coping response that helps during a brief challenge can be costly during prolonged insecurity. High observable achievement can coexist with internal distress, so defining success entirely by school performance can exaggerate the apparent protection conferred by conscientious behavior. Outcome selection changes which characteristics seem important.
Experimental evidence argues against treating context as a passive background. The supported foster-care offer in the Bucharest Early Intervention Project improved some later mental-health outcomes, with sex-specific uncertainty. Such a change cannot be explained solely by an immutable difference between supposedly resilient and nonresilient children. It demonstrates that modifying a developmental environment can change observed adaptation, while not establishing that every child benefits equally or through one unique mechanism.[ref]
Attachment security as a mechanism linking foster care placement to improved mental health outcomes in previously institutionalized children by Katie A. McLaughlin and others. 2012, randomized environmental intervention and outcome heterogeneity
The relative importance of characteristics can change over time. A relationship or opportunity encountered later can alter a developmental course; stable adaptation after one event does not guarantee the same response to another. Prospective bereavement findings also show why baseline functioning matters: a favorable post-event score can represent stable functioning or improvement from earlier difficulty. A personality correlate measured only after the event may partly be a consequence of the adjustment being explained.[ref]
Resilience to loss and chronic grief by George A. Bonanno and others. 2002, prospective baseline and heterogeneous courses
Genetic findings do not restore a simple fixed-trait account. A heritable regression residual-based adaptation score still depends on exposure measurement, the surrounding environment and inherited influences on the component symptoms. Heritability partitions variation in a studied population; it does not say that an individual's coping capacity is fixed or that a social intervention cannot help. Equally, environmental influence does not make every individual difference transient or unimportant.
Individual characteristics are consequential resources within a developmental system, not sufficient explanations of who will adapt successfully. Good research compares personal and contextual predictors prospectively, tests interactions and mechanisms, and evaluates functioning across domains. Prevention can strengthen relevant skills while also protecting relationships and material conditions. This is a more useful consequence of individual-difference evidence than attributing continuing difficulty to an alleged lack of personal psychological resilience.
Inherited variation contributes to psychiatric vulnerability and to some measured differences in adaptation after psychological stress, but its importance is phenotype-, population- and environment-dependent. Genetic influence is not equivalent to inevitability, a single large-effect gene or a wholly separate set of protective genes. A satisfactory answer must distinguish genetic effects on exposure, on symptoms and on responses conditional on exposure.
Family resemblance provides an initial clue, but families transmit environments and social circumstances as well as DNA. Twin comparisons exploit differences in relatedness: monozygotic pairs share essentially all inherited sequence variation, whereas dizygotic pairs share about half their segregating additive variation on average. Under an ACE model, greater resemblance of monozygotic pairs can support a genetic component if the relevant environmental and ascertainment assumptions hold. Equal environments means comparable effects of relevant environmental similarity, not literally identical treatment of every twin.
Disorder-level evidence is substantial. Patrick F. Sullivan and colleagues' ascertainment-aware synthesis of schizophrenia twin studies estimated liability heritability at roughly , with uncertainty. Paul Lichtenstein and colleagues' Swedish family-register study supported partially shared inherited liability to schizophrenia and bipolar disorder using biological, adoptive and sibling relationships. The convergence supports inherited vulnerability while showing that diagnostic categories do not necessarily partition genetic causes into entirely independent sets.[ref]
Schizophrenia as a complex trait by Patrick F. Sullivan and others. 2003, twin-liability synthesis
[ref]Common genetic determinants of schizophrenia and bipolar disorder in Swedish families by Paul Lichtenstein and others. 2009, family/adoption comparisons and cross-disorder liability
Molecular evidence provides a different test. The Psychiatric Genomics Consortium's 2014 schizophrenia study identified associations spanning 108 loci in a large multi-stage genome-wide analysis. Many common variants contribute small effects; an associated locus is not automatically one causal gene or a known mechanism. Population stratification, linkage disequilibrium, case ascertainment and sample overlap still require control. A genetic risk score can predict risk differences in independent data while remaining far from a deterministic diagnosis or a transportable measure of one person's psychological resilience.[ref]
Biological insights from 108 schizophrenia-associated genetic loci by Psychiatric Genomics Consortium. 2014, multi-stage associations and polygenic interpretation
Psychological resilience needs additional definition because favorable outcomes without adversity do not establish psychological stress resistance. Ananda B. Amstadter and colleagues studied 7,500 adult twins at two assessments, modeling internalizing symptoms relative to cumulative stressful events. Their regression residual-based phenotype had estimated heritability around at each wave; longitudinal modeling that accounted for measurement error and occasion-specific influences gave a larger latent estimate, around . This supports both inherited and environmental contributions to that operationalization, not a universal percentage for every meaning of psychological resilience.[ref]
Psychiatric resilience: longitudinal twin study by Ananda B. Amstadter and others. 2014, residual phenotype, wave-specific and longitudinal estimates
The shift in estimates is conceptually informative. Independent measurement error adds to observed variance without adding the corresponding genetic signal. In a simple measurement model, if is genetic variance, true-score variance and independent error variance, thenRemoving noise can therefore raise estimated heritability without changing anyone's genes. This illustration is not a reconstruction of the study's full model: occasion-specific effects and longitudinal assumptions also matter, so should not be reported as an independently established measurement reliability coefficient.
A regression residual phenotype also inherits assumptions from its construction. If adversity is undermeasured or a prediction model is misspecified, the regression residual includes more than protective capacity. Genetic effects on depression or anxiety can appear as genetic effects on low symptom burden after psychological stress, even without a separate buffering mechanism. Demonstrating a psychological resilience-specific effect would require stronger evidence that inherited variation changes the response to comparable exposure, with adequate exposure measurement and explicit competing models.
Gene–environment processes further complicate simple partitioning. Gene-environment correlation occurs when inherited characteristics influence environments encountered or elicited, or when parental characteristics affect both inherited liability and the rearing environment. Genotype-environment interaction instead means that inherited differences have different consequences across environments. Neither can be inferred merely because both genes and psychological stress predict the outcome. Restricting analysis to people with a particular exposure can also create selection bias if exposure is influenced by several causes relevant to symptoms.
Historical candidate-gene findings illustrate the need for stringent evidence. Richard Border and colleagues' large, preregistered analyses did not support widely proposed depression candidate-gene or candidate-gene-by-environment effects. This challenges those specific claims and the power of small discovery studies; it does not demonstrate that all interactions are absent. Replication, correction for multiple testing, ancestry-aware analyses and precise phenotype definitions are essential before a plausible biological story becomes a reliable finding.[ref]
No support for historic candidate gene or candidate gene-by-interaction hypotheses for major depression across multiple large samples by Richard Border and others. 2019, candidate-variant, gene and interaction tests
Finally, high heritability does not mean an outcome cannot be changed. It describes sources of variation under a particular range of environments, not the response to an environment absent from the data. Genetic effects can act through modifiable developmental systems, and external support can benefit people across inherited-risk levels. Predictive accuracy and equity can also deteriorate when scores are transferred to populations unlike the discovery sample.
Genes contribute meaningfully to liability and to particular measured adaptation phenotypes, while evidence for specific protective mechanisms is narrower than evidence for heritability. The strongest account combines family and molecular results with explicit exposure and developmental models, rather than assigning a fixed genetic percentage to an individual or replacing environmental prevention with genetic classification.
Psychological psychological stress is neither universally necessary nor sufficient for psychological disorder, and prior exposure can increase or decrease later psychological stress reactivity under different conditions. This conclusion requires a specific definition of psychological stress. If every internal demand, inherited vulnerability or symptom is relabeled “psychological stress,” necessity becomes nearly impossible to falsify. It is more useful to distinguish an external psychological stressor, its appraisal, physiological responses and the subsequent clinical outcome.
For a defined exposure and disorder , necessity would mean , while sufficiency would mean . A causal risk factor need satisfy neither implication: it can increase risk for some people without producing disorder in all exposed people or accounting for every case. The absence of a recorded stressful event is not proof that no relevant adversity occurred, but repeated measurement can make a proposed universal requirement more testable. A diagnostic qualification is post-traumatic stress disorder, which requires a qualifying traumatic exposure as part of its definition; even there, exposure alone does not meet the remaining diagnostic requirements.[ref]
PTSD and DSM-5 by National Center for PTSD. DSM-5 Criteria for PTSD, Criterion A and the requirement for the full syndrome; used to verify the pre-examination diagnostic distinction
Exposure is clearly not sufficient for all adverse outcomes. Prospective studies identify heterogeneous courses following bereavement, including maintained functioning and recovery after adversity. Individual liability, developmental timing, available support and continuing consequences alter risk. A vulnerability–psychological stress account therefore treats exposure as interacting with other causes rather than as a switch that produces the same outcome in everyone. The observation that some exposed people adapt well does not imply the exposure was harmless or that those with continuing difficulties lacked effort.
Stress sensitization proposes that prior adversity lowers the threshold for a later adverse response. Constance Hammen and colleagues followed young women for two years and found that those with significant childhood adversity were more likely to develop depression following less subsequent psychological stress than those without such histories. The finding was not explained by the measured chronic psychological stress or previous depression. This supports a sensitization pattern, while leaving its precise biological and psychological mechanisms unresolved and retaining the limitations of observational exposure histories.[ref]
Depression and sensitization to stressors among young women as a function of childhood adversity by Constance Hammen and others. 2000, prospective sensitization test and alternative measured explanations
Possible pathways include altered threat appraisal, reduced regulatory resources and persistent disruption of supportive relationships. These mechanisms make different predictions and need direct tests. A lower observed psychological stress level before an episode could also reflect incomplete event measurement, emerging illness generating psychological stress or shared vulnerability to both exposure and depression. Sensitization should be distinguished from stress generation, where symptoms or related characteristics increase the probability of later stressful experiences. Both processes could form a feedback loop without being identical.
Stress inoculation makes a different prediction: manageable prior challenges can sometimes improve later regulation or coping. Mark D. Seery and colleagues' multiyear study found that people reporting some, rather than zero or very high, lifetime adversity had more favorable mental-health and functioning outcomes and appeared less affected by recent events. This supports a nonmonotonic association, but not a causal recommendation to expose people to adversity. Retrospective histories, selection, differences in resources and unmeasured confounding could help produce the pattern.[ref]
Whatever Does Not Kill Us by Mark D. Seery and others. 2010, quadratic adversity associations and response to subsequent events
Experimental animal evidence addresses some causal alternatives. Karen J. Parker and colleagues randomly assigned twenty young squirrel monkeys to intermittent separation experiences or a comparison condition during postnatal weeks 17–27. Subsequent testing included a novel environment with the mother present and a home-cage exploratory task, with behavioral observations and plasma cortisol measurements. The intermittently exposed animals showed greater exploration and lower anxiety-related and hormonal responses on specified measures. The contrast provides evidence that this particular developmental experience changed later responses.[ref]
Prospective Investigation of Stress Inoculation in Young Monkeys by Karen J. Parker and others. 2004, randomized rearing contrast, novel-environment test and behavioral/endocrine outcomes
The limits are important. The comparison concerns a controlled, intermittent challenge with return to a social environment, not severe chronic maltreatment. Exploration and psychological stress-hormone measures are not equivalent to prevention of human psychiatric diagnoses. Maternal responses and subsequent experiences can mediate the randomized package, so the result does not identify one cellular mechanism. Human application would need independent evidence about benefits, harms, developmental timing and the meaning of the experience; deliberately creating harmful adversity does not follow from this experiment.
Sensitization and inoculation can coexist because exposure varies in intensity, duration, controllability, timing and the support available afterward. Repeated overwhelming threat can exhaust or disrupt adaptive systems, while manageable experiences may provide opportunities for learning and recovery after adversity. Nevertheless, “moderate psychological stress helps” is not a universal law: what is manageable differs by person and context, and a population-level curved association does not identify a beneficial dose for an individual. Neither pattern should be assumed merely from knowing the number of events.
A discriminating human study would measure functioning before exposure, assess prior and subsequent psychological stress independently where possible, and follow several clinical and functional outcomes. It would examine whether earlier exposure modifies the effect of a later comparable challenge rather than merely correlating history with current symptoms. Within-family comparisons, externally driven changes and ethical intervention studies can help test alternatives. Predefined analyses should distinguish stress generation, sensitization, recovery after adversity and true moderation, with attention to selective attrition and shared-reporting bias.
Psychological stress contributes to disorder probabilistically, through developmentally situated mechanisms; its presence does not guarantee illness and its absence from a checklist does not establish an exclusively nonenvironmental cause. Sensitization has prospective human support and inoculation has observational human and experimentally controlled animal support, but their scope and causal strength differ. The practical implication for prevention is to reduce harmful exposure and strengthen support and adaptive learning, not to assume either inevitable damage or inevitable strengthening.
Part II advanced option in the held 2022 papers. The source examination is shared by the psychology (experimental) course of the University of Oxford and the psychology, philosophy and linguistics course of the University of Oxford.
Study answers to all six options in the neuropsychopharmacology of higher cognition examination of 27 May 2022. Source release: released examination PDF. The original examination required a choice of three questions; this resource develops every option without reproducing the statements.
Scientific conclusions use work available by the examination date. Experimental models, clinical syndromes and proposed treatments are distinguished; none of the pharmacological discussions is patient-specific advice. Abstract model states and computational illustrations are not presented as biological measurements.
Fear and anxiety share learning mechanisms, neuromodulators and defensive circuitry, but differ in how threat is specified and sustained. A useful operational distinction is an immediate response to an identified danger versus prolonged anticipation of uncertain danger. That distinction should not be mistaken for a universal division into two independent brain centres. Neuropsychopharmacology is most informative when it compares matched behavioural endpoints and identifies where and when a drug acts.
The first issue is measurement. Freezing, avoidance, autonomic changes, fear-potentiated startle and subjective reports capture different aspects of threat responding. A rat’s reduced open-arm exploration can reflect anxiety, but also altered movement or novelty preference. A smaller startle response can reflect sedation rather than reduced threat processing. It is therefore necessary to measure baseline responsiveness, locomotion and sensory function, and to distinguish acquisition, consolidation, retrieval and expression. A drug administered only at testing does not establish an effect on the original learning.
An influential rat experiment compared potentiation of acoustic startle by a conditioned threat cue with enhancement during sustained bright illumination. Local AMPA receptor antagonism in the central nucleus of the amygdala disrupted the conditioned-cue effect, whereas antagonism in the bed nucleus of the stria terminalis disrupted the light-enhanced effect. The basolateral amygdala contributed to both. This is stronger evidence for differentiation than comparing unrelated assays because the measured reflex was shared. However, conditioning history, stimulus properties and duration differed together, so the result does not isolate duration or uncertainty as the sole cause of the dissociation.[ref]
Double dissociation between the involvement of the bed nucleus of the stria terminalis and the central nucleus of the amygdala in startle increases produced by conditioned versus unconditioned fear by David L. Walker and others. Abstract and Figures 2–5: local glutamate-receptor antagonism and two startle-potentiation paradigms
The amygdala and BNST belong to interacting networks receiving cortical and other inputs and influencing hypothalamic and brainstem outputs. The hippocampus supplies contextual information and prefrontal cortex can influence threat regulation and extinction retrieval. Subdivisions and projection-defined populations within the extended amygdala can differ in function. A general claim that the amygdala produces all fear and the BNST produces all anxiety consequently ignores shared pathways, task dependence and cellular heterogeneity.
Fast inhibitory signalling supplies an important pharmacological comparison. Many benzodiazepines positively modulate susceptible GABA-A receptors, but anxiolysis must be distinguished from sedation and amnesia. A controlled human crossover study compared predictable-cue, unpredictable-threat and no-threat conditions. Alprazolam reduced sustained contextual startle enhancement at the effective tested treatment condition while leaving phasic cue potentiation relatively unaffected. The design included an active sedating comparison as well as placebo. This supports psychopharmacological differentiation between sustained and phasic measures; it does not prove absolute drug selectivity for a subjective state or show that every clinical anxiety presentation has the same mechanism.[ref]
The benzodiazepine alprazolam dissociates contextual fear from cued fear in humans as assessed by fear-potentiated startle by Christian Grillon and others. Abstract and pp. 760–766: crossover treatments, predictable/unpredictable threat and phasic versus sustained startle
Serotonin illustrates why transmitter identity alone is insufficient. Reuptake inhibition affects multiple receptors and projection targets, and early effects can differ from adaptations after repeated treatment. In mice, a dorsal-raphe projection to the BNST recruited a serotonin-sensitive local circuit and promoted selected threat-related behaviours. This provides a pathway-specific explanation for an anxiogenic effect of increasing serotonin signalling, compatible with different effects at other targets. It is not evidence that serotonin uniformly causes anxiety or that rodent threat responses establish the clinical time course of an SSRI.[ref]
Serotonin engages an anxiety and fear-promoting circuit in the extended amygdala by Catherine A. Marcinkiewcz and others. Abstract and Figure 1: dorsal-raphe–BNST projection and threat-related behaviour
Receptor subtype and developmental timing also matter. The same receptor class can act as an autoreceptor controlling raphe output or on non-serotonergic target neurons. Norepinephrine, corticotropin-releasing hormone and other modulators interact with these systems rather than map one-to-one onto fear or anxiety. Local circuit effects should not be inferred from circulating hormone concentrations. A mechanistic explanation should state the receptor, target, timescale and outcome, not merely whether a brain-wide chemical level rose or fell.
Learning about safety supplies both a shared mechanism and a therapeutic distinction. In extinction learning, an expected aversive outcome is omitted; reduced responding can reflect new inhibitory or contextual knowledge rather than deletion of the original association. In rats, the NMDA receptor partial agonist D-cycloserine facilitated later reduction of conditioned startle when combined with extinction training. Its effect depended on learning conditions rather than acting simply as an acute suppressant of every defensive response. This motivates a learning-adjunct strategy, but the animal result alone cannot establish clinical efficacy.[ref]
Facilitation of conditioned fear extinction by systemic administration or intra-amygdala infusions of D-cycloserine as assessed with fear-potentiated startle in rats by David L. Walker and others. Abstract and Results: extinction-dependent facilitation assessed with conditioned startle
Anxiety about uncertain contexts can involve more than a response to one cue: broad threat generalization, avoidance that prevents corrective experience, and context-dependent retrieval may sustain it. Conversely, a sharply defined learned cue can acquire persistent control. Exposure therapy therefore cannot be reduced to suppressing an output on one occasion. An intervention that changes expression without improving subsequent safety learning might have a different long-term effect from one that changes what is retained. Renewal after extinction also predicts that improvement in one context need not transfer automatically to another.
The strongest comparison is thus dimensional and mechanistic. Fear and anxiety share synaptic plasticity, inhibitory signalling and distributed threat networks, while particular temporal and informational demands recruit distinguishable components. Drug and circuit dissociations are meaningful when matched controls rule out motor or sensory explanations; they should refine this network account rather than replace it with a pair of transmitter labels. These are conclusions about evidence and experimental models, not instructions for selecting medication.
Learning and memory provide powerful mechanistic accounts of some psychiatric symptoms, but they are not an adequate single-level definition of all psychiatric disorders. The most useful claim is that abnormal learning, valuation or retrieval can mediate particular symptoms and interact with biological vulnerability and environment. Calling every persistent symptom a “memory” without specifying a computation, mechanism and discriminating prediction would make the account unfalsifiable.
Several causal positions must be separated. A learning abnormality could precede illness and increase vulnerability, mediate the expression of an established biological disturbance, or follow from the illness, medication or adverse experiences. A cross-sectional task deficit does not distinguish these possibilities. Nor does a diagnosis identify one latent parameter: poor performance can result from altered motivation, perception, attention, beliefs or motor output as well as learning. Construct validity and external validity are therefore central, not afterthoughts.
For schizophrenia, an influential proposal links dopamine dysregulation to aberrant salience. Events or internal representations acquire inappropriate significance, and attempts to explain those experiences can contribute to delusions. This creates a possible bridge between neurochemistry and acquired belief. It is a theoretical framework rather than evidence that each psychotic belief is an ordinary reinforced association; psychosis is also not specific to schizophrenia. The account must explain which symptoms it predicts and which remain outside its scope.[ref]
Psychosis as a state of aberrant salience: a framework linking biology, phenomenology, and pharmacology in schizophrenia by Shitij Kapur. Abstract and pp. 13–23: proposed salience framework and its stated explanatory scope
A pharmacological experiment provides a more direct test of one link. Healthy volunteers performed causal associative learning during randomized ketamine and placebo sessions with functional magnetic resonance imaging. The drug perturbed right-frontal responses related to violated expectations, and individual neural responses were related to subsequently assessed perceptual and belief-like drug effects. This supports an association between altered learning-related processing and psychotomimetic experience. It does not show that ketamine reproduces the developmental course of schizophrenia, or that the observed imaging signal is the unique mediator of a delusion. Pharmacology causally changes the drug condition; the relationship between an imaging response and a symptom remains a separate inferential step.[ref]
Frontal responses during learning predict vulnerability to the psychotogenic effects of ketamine: linking cognition, brain activity, and psychosis by Philip R. Corlett and others. Abstract; Results and Comment, pp. 611–621: randomized drug challenge, learning responses and symptom relations
Prospective evidence helps with temporal ordering. Elevated striatal dopamine synthesis capacity was observed before transition to psychotic disorder in a high-risk cohort. That finding is important biological evidence, but a PET synthesis-capacity estimate does not directly measure trial-wise reward prediction errors, and elevated capacity does not establish a specific learning algorithm. It also does not imply that every high-risk person or every diagnosed patient has the same abnormality. A learning account should connect this biological vulnerability to task-defined computations rather than substitute one measure for another.[ref]
Dopamine synthesis capacity before onset of psychosis by Oliver D. Howes and others. Abstract and pp. 1311–1317: prospective imaging and transition-group comparison
For major depressive disorder, low expectations of control, persistent negative interpretations and reduced engagement with rewarding opportunities are plausible learning-related mechanisms. Learned helplessness provides a specific model of how uncontrollability can change later behaviour; attributional style helps explain generalization and persistence in human accounts. These mechanisms are neither a moral judgment about the individual nor proof that all adverse circumstances are controllable. Sleep, bodily symptoms, neurodevelopmental factors and the diversity of depressive presentations remain part of the explanandum.
Behavioural evidence is more precise than a global claim that depressed people “cannot learn.” In a probabilistic reward task, unmedicated depressed participants showed reduced development of response bias toward a more frequently rewarded stimulus, with analyses implicating integration of reinforcement history rather than total absence of response to an individual reward. This separates one aspect of reward learning from subjective pleasure and from every component of anhedonia. The direction of causation remains open in a cross-sectional comparison.[ref]
Treatment findings can also link biological and cognitive levels. An acute norepinephrine-reuptake manipulation changed emotional processing in depressed participants before subjective mood changed. That observation is consistent with pharmacologically altered experience processing contributing to later improvement; it does not prove that the early task change mediates every later clinical response. Learning and pharmacology can interact rather than constitute mutually exclusive treatments. A drug might alter the conditions under which corrective experiences are encoded, while behavioural intervention supplies those experiences.[ref]
Effect of acute antidepressant administration on negative affective bias in depressed patients by Catherine J. Harmer and others. Abstract; Methods and Results: early emotional-processing effects without immediate mood change
The learning perspective generates concrete treatment hypotheses. In threat disorders, extinction learning suggests improving safety learning and its retrieval across contexts, rather than merely suppressing an immediate response. A randomized pilot study combined D-cycloserine or placebo with virtual-reality exposure to heights in people with acrophobia. Greater improvement in the adjunct condition provided an early proof of concept for facilitating a specified learning experience. The small, specific trial does not establish a general cognitive enhancer for all diagnoses, and an intervention that facilitates learning need not selectively strengthen desirable information. Treatment timing and the quality of the learning episode are therefore empirical issues.[ref]
Cognitive enhancers as adjuncts to psychotherapy: use of D-cycloserine in phobic individuals to facilitate extinction of fear by Kerry J. Ressler and others. Abstract and pp. 1136–1144: blinded randomized pilot, virtual glass-elevator exposure and follow-up
For psychotic symptoms, a learning account predicts that reducing inappropriate salience may permit new interpretation without instantly deleting established beliefs. For depression, it motivates tests of changes in reward sensitivity, information integration and expectations, with functional recovery as an outcome. These are treatment-development hypotheses, not conclusions that a single task parameter should dictate care. Symptom improvement, correction of a proposed mechanism and prevention of relapse require separate measurements; changing a laboratory score is not sufficient evidence of benefit.
The broad claim becomes convincing only when models predict specific patterns, survive controls for performance confounds, and show temporally appropriate changes linked to symptoms. Comparisons with unaffected high-risk individuals, longitudinal designs and mechanism-sensitive randomized trials can distinguish vulnerability, mediation and consequence. Learning and memory are therefore valuable explanatory levels and possible treatment targets, especially for particular acquired responses and beliefs. They do not replace the biological, developmental and social causes of psychiatric illness, and they should not turn diagnostic heterogeneity into one assumed defect.
Non-human experiments have made serotonin’s role in emotion more specific: its effects depend on receptor subtype, developmental history, projection and behavioural demand. Their strength is controlled intervention at levels inaccessible in ordinary human research. Their weakness is that an experimentally altered behaviour is an operational measure, not a direct reading of human emotional experience or an entire psychiatric disorder.
Serotonin arises from heterogeneous neuronal populations and acts through multiple serotonin receptors. Manipulating synthesis, reuptake, a receptor or one projection is not interchangeable. Systemic drug administration can affect many targets, while a permanent depletion permits adaptation. Conversely, temporally restricted intervention can reveal when a pathway matters but imposes a pattern that may differ from natural activity. These distinctions make converging approaches more informative than assigning a single emotional function to the molecule.
Developmental rescue experiments demonstrate why timing matters. Mice lacking 5-HT1A receptors showed increased anxiety-like behaviour; conditional receptor expression largely in hippocampal and cortical targets rescued the measured phenotype when present during an early postnatal period, whereas adult expression alone did not provide the same rescue. This supports a developmental contribution and warns against equating a lifelong genetic perturbation with acute adult treatment. However, rescue establishes sufficiency of the introduced expression pattern under those conditions, not necessarily the endogenous receptor location’s unique necessity. Ectopic expression, altered circuitry and compensatory development remain relevant limitations.[ref]
Serotonin1A receptor acts during development to establish normal anxiety-like behaviour in the adult by Cornelius Gross and others. Abstract and pp. 396–400: conditional spatial and developmental rescue
Local depletion in primates provides a different kind of evidence. Marmosets with prefrontal serotonin depletion perseverated on a previously rewarded visual stimulus when its contingency reversed, while retention of a previously learned discrimination and acquisition of a new one were relatively spared. These controls constrain explanations based on general inability to learn or recognize the stimuli. The result links serotonin to flexible use of changed outcomes, a process relevant to emotion regulation. Yet reversal learning is not itself a measure of sadness, fear or subjective affect, and depletion is not equivalent to an isolated physiological fluctuation.[ref]
Cognitive inflexibility after prefrontal serotonin depletion by Hannah F. Clarke and others. Abstract and pp. 878–880: serial reversals, retention and new-discrimination controls
Optogenetic studies add temporal precision. In mice waiting for delayed rewards, timed activation of dorsal-raphe serotonergic neurons reduced premature abandonment of waiting, including on omission trials. Control experiments argued against simple motor inhibition and against the effect being merely reinforcing. This challenges an account of serotonin as only a punishment or generalized behavioural-inhibition signal. The appropriate conclusion is that activating the targeted population can promote waiting in that task; patience is still a behavioural construct, and the imposed activity does not by itself identify the natural signal’s full content.[ref]
Optogenetic activation of dorsal raphe serotonin neurons enhances patience for future rewards by Kayoko W. Miyazaki and others. Abstract and Results, pp. 2033–2040: delayed-reward waiting and motor/reinforcement controls
A pathway-specific experiment gives the complementary result. Activating serotonergic projections from the dorsal raphe nucleus to the BNST promoted selected anxiety- and fear-related behaviours. Combined anatomical, electrophysiological and pharmacological evidence implicated a local 5-HT2C receptor-sensitive circuit involving corticotropin-releasing hormone neurons. Thus raising serotonergic activity in one pathway can have a different behavioural consequence from activating another population during reward waiting. Local inhibition and disinhibition matter: transmitter effects on one cell class need not have the same sign as the pathway’s net behavioural effect.[ref]
These examples also show how apparatus shapes the claim. Open-arm exploration measures approach–avoidance under environmental threat; conditioned freezing measures one defensive output; visual choice tasks measure outcome-guided flexibility; a reward port allows measurement of waiting and leaving. Each permits careful timing and quantitative controls, but none is a complete emotional state. Converging measures of movement, feeding, autonomic state, discrimination and learned response reduce the risk of interpreting every changed score as an emotional effect.
Species comparisons are informative when they isolate conserved functions rather than presume identical experience. Primates allow some translational similarities in prefrontal organization and complex behaviour; rodents allow larger experimental samples and finer cellular access. Strain, sex, age, housing and prior stress can influence measured phenotypes. Highly controlled laboratory conditions improve internal validity while limiting the contexts over which the result is known to generalize. Inbred animals and one aversive task cannot represent the full diversity of human affective illness.
Cell specificity creates further opportunities and limits. Targeting neurons by a serotonergic marker improves on identifying them only from spike shape or location. Nevertheless, cell populations can differ in projections and co-transmission; stimulating a cell can affect more than serotonin at one target. Terminal stimulation can recruit network or collateral effects, and a receptor antagonist can have off-target drug effects. Claims about a particular released transmitter are stronger when supported by release measurements, receptor-level tests and independent perturbations, not genetic targeting alone.
Temporal comparisons are equally important. Developmental effects concern how a circuit is established; acute effects concern its current operation; repeated pharmacological exposure may change receptor regulation and experience-dependent learning. A behavioural rescue in a genetically altered mouse therefore cannot be read as a prescription for an adult human. Nor does a transient anxiogenic effect contradict every beneficial effect of longer treatment: different times, targets and readouts are being compared.
The best use of animal work is an iterative programme. Specify a computation or response, establish a selective circuit or receptor contribution, test alternative performance explanations, and then examine corresponding predictions with human behavioural and pharmacological measures. Animal experiments have already replaced a simple “more serotonin means better mood” story with mechanistic heterogeneity. Their translational value increases when they identify that heterogeneity and its boundary conditions rather than claim that one manipulation models all emotion.
Reward prediction error remains a strong account of particular phasic dopamine signals and their contribution to learning; it is inadequate as a universal description of every dopamine neuron, projection and timescale. The question is best answered by separating the computational hypothesis, measurements of naturally occurring activity, and evidence that manipulating an error-like signal changes later learning.
In temporal-difference learning, a prediction is updated usingwhere is the value function for state , is the next reward, discounts later return, and is the update step size. The terminal value is zero. A reward prediction error is therefore not simply reward, pleasure or salience. Its sign depends on what was expected and when. An unexpected reward can generate a positive error; an accurately predicted reward can generate little error; omission of an expected reward can generate a negative error. A cue can produce an error when it changes the prediction of future return even though no immediate reward is delivered.
Primate recordings motivated this account because phasic responses changed with learning and reward expectation rather than responding identically to every reward. Linking these patterns to a quantitative learning rule provided predictions about cue responses and outcome omissions that a generic “reward neuron” label lacked. However, extracellular identification and population sampling matter, and the computational state representation is an assumption. A model fitted with a poor description of what the animal knows can misclassify a genuine expectation-related response as a theoretical failure.[ref]
A neural substrate of prediction and reward by Wolfram Schultz and others. Abstract and pp. 1593–1599: linkage between dopaminergic activity, changing predictions and computational learning
Prediction errors in an original toy temporal-difference learning task
. Calculated learning curves and value estimates for a deterministic state chain; these are not neuronal recordings. A reset trial state supplies the first informative cue. After learning, an unexpected reward omission produces a negative error at the expected reward transition. Details.
Association-learning experiments make the interpretation more than a curve-fitting exercise. In blocking, an established cue already predicts the reward, reducing learning about an added cue. Reward-timed optogenetic activation of dopamine neurons could overcome this blocking, supplying an error-like teaching event despite the normally expected reward. The relevant endpoint was subsequent learning about a cue, not just movement during stimulation. This supports a causal teaching contribution but does not establish that artificially synchronized activation reproduces every feature of an endogenous code.[ref]
The negative side of the error also has intervention evidence. Brief inhibition of targeted dopamine neurons around reward processing produced later learning changes resembling those expected from a negative error, with behavioural controls addressing distraction or immediate aversion. This strengthens a bidirectional teaching account beyond sufficiency of excitation alone. The imposed pause still tests a particular population and task, and inhibition can affect processes other than the proposed scalar signal. Appropriate timing controls and later unstimulated testing are essential to the interpretation.[ref]
Brief optogenetic inhibition of dopamine neurons mimics endogenous negative reward prediction errors by Chun Yun Chang and others. Abstract and Results, pp. 111–116: brief inhibition and later associative responding
Population heterogeneity can refine the hypothesis rather than simply refute it. Distributional reinforcement-learning work proposed multiple channels differing in optimism and in their relative sensitivity to positive and negative errors. Mouse single-unit data showed systematic variation in response reversal points consistent with this account. One reward can then be better than expected for one channel and worse for another. The finding challenges a single shared scalar prediction broadcast identically by all cells, while retaining prediction-error-like computations. It does not make heterogeneity alone proof of a particular distributional algorithm.[ref]
A distributional code for value in dopamine-based reinforcement learning by Will Dabney and others. Abstract and Figures 1–5: differential reversal points and distributional predictions
Other heterogeneity is not readily summarized as reward error. Cell-resolved imaging during a mouse virtual-navigation task found dopamine-neuron signals related to sensory, motor and cognitive variables, with structured differences across neurons. Regression and task design can separate some predictors, but correlated movements and expectations limit unique interpretation. Such findings make a universal scalar account implausible; they do not eliminate the well-controlled reward-error results in other populations. Nor should every movement-related signal be re-labelled as error without an independently specified model that predicts it.[ref]
Specialized coding of sensory, motor and cognitive variables in VTA dopamine neurons by Ben Engelhard and others. Abstract and encoding analyses, pp. 509–513: cell-resolved task-variable heterogeneity
The measurement compartment is another limitation. A comparison of identified VTA cell spiking with nucleus-accumbens dopamine release in a common decision task found release dynamics related to evolving reward expectations without corresponding changes in recorded cell-body spiking. Local release regulation therefore matters: a terminal sensor and a somatic spike train need not report the same quantity. This is especially important for interpreting slower ramps or motivational effects as direct readings of a broadcast phasic error.[ref]
Dissociable dopamine dynamics for learning and motivation by Ali Mohebi and others. Abstract and Figures 2–5: comparison of identified spiking and accumbens release dynamics
Further qualifications concern learning itself. An error depends on subjective reward, inferred state, uncertainty and task structure; it is not calculated from the experimenter’s reward schedule alone. Values informed by a model of the environment can also contribute, so identifying an error-like signal does not automatically prove exclusively model-free learning. Conversely, a very flexible state model can accommodate almost any observation unless its representation and parameters are constrained independently. Good tests manipulate expectation while matching outcome and movement, and compare explicit alternatives on held-out behaviour and neural data.
The account is thus still appropriate when stated at the right resolution: some temporally precise dopamine activity supplies expectation-dependent teaching signals, supported by both recordings and causal learning manipulations. A complete account of the dopamine system must additionally explain projection-specific coding, local transmitter dynamics, motivation and movement. The productive revision is a family of constrained computational and circuit hypotheses, rather than either one molecule–one number or abandonment of prediction error altogether.
The SOP model family specifies testable principles of stimulus processing and association, but it does not yet have a uniquely established neural implementation. Its behavioural breadth should be distinguished from evidence identifying the biological counterparts of its states, transition rules and separate response systems. The strongest neurobiology concerns processes that the models require—priming, associative retrieval and differentiated response pathways—rather than a one-to-one mapping of every symbol onto a brain structure.
Ivan Pavlov’s classical conditioning tradition made stimulus history and the measured conditioned response objects of controlled experiment. The SOP model introduced by Allan R. Wagner represents stimuli as elements distributed among inactivity , primary activation and secondary activation . External presentation promotes inactive elements into ; activity then passes through before returning to inactivity. A learned associate can activate an expected event directly into . Recently or associatively activated elements are less available for renewed primary processing, distinguishing self-generated priming from retrieval-generated priming. A contemporary quantitative analysis shows how these dynamics can generate several habituation regularities; these are simulations, not measurements of neuronal states.[ref]
A quantitative account of the behavioral characteristics of habituation: the sometimes opponent processes model of stimulus processing by Yerco E. Uribe-Bahamonde and others. The SOP Model section: state occupancy, decay and two sources of priming
The association rules make the account more specific than a generic fading trace. In the original formulation, concurrent and activity promotes excitation, whereas with promotes inhibition. The Modified SOP model additionally permits learning involving a cue activated into : matched-state combinations can strengthen excitation and mismatched-state combinations inhibition. This allows an absent cue’s association to change through retrieval, addressing retrospective revaluation. The model is therefore not simply equivalent to a reward-error equation or to synaptic fatigue.
Human causal-judgment experiments motivated an important constraint. Participants learned relations among compound cues and an outcome, then received information about a companion cue without the target. Retrospective changes in judgments depended on the consistency of earlier within-compound pairings. This supports a role for learned cue–cue relations in revaluation, but the behavioural result does not identify synapses implementing the modified state-pair rules. Other retrieval or inference models can also use knowledge of those relations.[ref]
Within compound associations mediate the retrospective revaluation of causality judgements by Anthony Dickinson and others. Abstract and experiments, pp. 60–80: consistent versus varied compounds and backward revaluation
Primary and secondary activation in an original illustrative SOP-style state model
. Calculated occupancy fractions with chosen parameters, not neuronal activity. A recent presentation or associative priming leaves fewer inactive elements available for a subsequent primary response. The figure illustrates the state logic and conservation of probability, not a full SOP, M-SOP or AESOP learning simulation. Details.
Neural adaptation alone is insufficient to explain retrieval-generated effects. A transient reduction in response to a repeated physical stimulus could result from receptor adaptation, local synaptic dynamics or wider circuit changes, whereas context-specific long-term priming requires an account of the context’s learned relation to the event. A biological test must distinguish an unfamiliar stimulus from an unexpected combination of familiar stimuli and control attention, orienting and stimulus exposure. Reduced firing cannot simply be labelled : the theory permits secondary activity to be behaviourally silent or have a response-system-dependent effect.
Hippocampal lesion experiments provide evidence at that process level. Rats learned audiovisual sequences in which particular sounds preceded particular lights. Switching the familiar sound–light combinations renewed visual orienting in controls but not in hippocampal-lesioned animals, despite relatively preserved habituation to visual stimuli and evidence of sequence associations. This implicates the hippocampus in associative mismatch rather than novelty alone. It is compatible with a contribution to expectation or retrieval, but does not uniquely show that the hippocampus is , nor that every SOP model process is hippocampal.[ref]
Hippocampal lesions disrupt an associative mismatch process by Robert C. Honey and others. Abstract and pp. 2226–2230: audiovisual sequence switching, orienting and lesion controls
Receptor perturbation further separates short- and long-term components. Mice lacking the GluA1 AMPA-receptor subunit showed impaired short-term spatial novelty performance but enhanced long-term performance under the tested interval conditions. Manipulating exposure and test intervals helped distinguish rapid recency-dependent effects from longer-lasting learning. This is consistent with separable processes of the kind emphasized by the SOP model, rather than an undifferentiated stronger-versus-weaker memory. Nevertheless, a lifelong mutation can alter development and network function, and task dependence prevents identifying GluA1 with a single abstract transition parameter.[ref]
Enhanced long-term and impaired short-term spatial memory in GluA1 AMPA receptor subunit knockout mice: evidence for a dual-process memory model by David J. Sanderson and others. Abstract and Experiments 1–2: exposure/test intervals, spatial novelty and the opposite short-/long-term effects
Associative access to an absent outcome has additional circuit support. In rat sensory preconditioning, orbitofrontal inactivation impaired behaviour guided by an indirectly inferred outcome while sparing behaviour supported by the directly reward-paired cue. The manipulation also altered learning when inferred value normally acted as a blocker. This shows that retrieved associative structure can influence both performance and new learning. It is relevant to the demands of Modified SOP model, but does not demonstrate that the neural representation is in exactly or that its plasticity has the model’s stipulated sign.[ref]
Orbitofrontal cortex supports behavior and learning using inferred but not cached values by Joshua L. Jones and others. Abstract and Figures 1–2: inferred versus directly trained values and reversible inactivation
The Affective extension of SOP, developed by Allan R. Wagner and Susan E. Brandon, distinguishes sensory-specific and emotive components with different processing time courses and response consequences. Behavioural experiments in rabbits showed modulation of a discrete conditioned eyeblink by another putatively emotive conditioned stimulus. Such dissociations motivate separate response components. They do not locate a complete emotive representation in one nucleus. Basic conditioned-eyelid experiments independently implicated cerebellar nuclear circuitry through lesions, recordings and stimulation, illustrating why a motor conditioned response cannot simply be assigned to the same mechanism as every autonomic or emotional effect.[ref]
Modulation of a discrete Pavlovian conditioned reflex by a putative emotive Pavlovian conditioned stimulus by Susan E. Brandon and others. Abstract and pp. 299–311: modulation of the discrete conditioned reflex
[ref]Cerebellum: essential involvement in the classically conditioned eyelid response by David A. McCormick and others. Abstract and pp. 296–299: cerebellar lesions, activity and stimulation
The remaining challenge is discriminative implementation. A candidate neural model should specify what an element is, how direct and retrieved activity differ, how relevant overlap controls plasticity, and how sensory and affective components affect separate outputs. Manipulating receptor function or recording reactivation is not enough unless alternative mechanisms make different predictions. Neuromodulators could regulate transition rates, representation selection or plasticity, but there is no justified general identity such as “dopamine is ” or “serotonin is .” Multiple biological mechanisms could realize the same functional state description.
The SOP model family is therefore a valuable framework connecting stimulus history, expectation and response organization. Primary lesion, receptor and inactivation evidence supports several component processes. Its comprehensive behavioural ambitions exceed what is currently established about its precise neurobiology; the next useful experiments distinguish direct activation from retrieved activation and test the associated plasticity rules, rather than merely find a neural correlate of one familiar behavioural effect.
Correlative and causal approaches answer different questions, and neither is dispensable for understanding neuromodulation. An intervention is generally stronger evidence about the consequence of changing a specified target, while observation is essential for discovering the naturally occurring signal, its heterogeneity and the contexts in which it appears. Usefulness depends on the claim, measurement and assumptions, not simply on whether an experiment uses an optogenetic actuator.
A correlation between a neuromodulatory signal and behaviour can arise because the signal influences the behaviour, behaviour changes the signal, or a third variable influences both. Reward expectation, movement and arousal often covary. Temporal precedence helps reject some accounts but does not eliminate an unmeasured common cause. Detailed task manipulations can nevertheless make correlative evidence much more discriminating: varying expectation while holding delivered outcome constant tests a different hypothesis from merely comparing rewarded and unrewarded trials.
The dopamine prediction-error account illustrates this value. Patterns across unexpected rewards, predictive cues and omitted expected rewards constrained an explicit computational hypothesis. A generic rise in activity at a reward would not distinguish reward receipt, expectation and error. Recording before intervening helped identify the timing and task conditions in which a putative teaching signal should be manipulated. Without that information, a stimulation experiment might show that a pathway can change behaviour while leaving the proposed natural computation largely unspecified.
Observations also reveal what population averages hide. Cell-resolved dopamine imaging showed structured sensory, motor and cognitive heterogeneity during a navigation task. Comparing identified dopamine spiking with accumbens release revealed that evolving release dynamics need not mirror recorded somatic activity. These findings constrain the target and measurement level of subsequent interventions. They are not failures of observation: a perturbation of an entire heterogeneous population could obscure precisely the functional distinctions that recording discovers.[ref]
Specialized coding of sensory, motor and cognitive variables in VTA dopamine neurons by Ben Engelhard and others. Abstract and cell-resolved encoding analyses: heterogeneous task-variable relationships
[ref]Dissociable dopamine dynamics for learning and motivation by Ali Mohebi and others. Abstract and Figures 2–5: cell-body spiking versus local release
Interventions can then test a well-specified causal prediction. Reward-timed activation of dopamine neurons overcame associative blocking, changing subsequent cue learning; brief inhibition supported a negative-error-like learning effect. These manipulations are stronger evidence for a teaching contribution than a correlation alone. Yet the manipulated population and timing must match the proposed endogenous signal, and later unstimulated testing is needed to separate acquired learning from immediate performance effects. Sufficiency to impose an effect is not proof that the artificial activity pattern occurs naturally or is the only possible teaching route.[ref]
A causal link between prediction errors, dopamine neurons and learning by Elizabeth E. Steinberg and others. Abstract and Figures 1–4: temporally targeted manipulation and subsequent associative learning
[ref]Brief optogenetic inhibition of dopamine neurons mimics endogenous negative reward prediction errors by Chun Yun Chang and others. Abstract and Results: brief inhibition and later learning effects
Claims of functional necessity and sufficiency are conditional. Selective inhibition that impairs performance can support necessity under the tested conditions, but may act through sensation, movement or motivation rather than the hypothesized computation. A null effect can reflect redundant circuits, incomplete target engagement or compensation. Conversely, stimulation can recruit an unnatural synchrony, reverse-propagating activity or multiple collateral targets. Changing neurons identified by one transmitter can also change co-transmission, so the intervention is not automatically selective for that chemical signal at one synapse.
Pharmacological perturbations make similar assumptions visible. A systemic drug affects receptors according to exposure and selectivity, not according to the experimenter’s functional label. Time of testing, peripheral actions, active metabolites and off-target drug effects matter. The chemogenetic ligand clozapine-N-oxide provides a concrete example: receptor-binding and distribution work showed that conversion to clozapine can account for central DREADD activation. Thus an apparent designer-receptor intervention cannot be assumed to have the intended pharmacological isolation merely because the receptor was genetically targeted. Ligand-only controls and exposure measurements improve the causal interpretation.[ref]
Measurement is therefore required inside causal experiments as well as before them. Histology can confirm targeting but not the actual moment-to-moment physiological effect; electrophysiology or transmitter measurements can test target engagement. Calcium signals, fibre photometry, voltammetry and spikes have different spatial, temporal and chemical limitations. Converging methods are more persuasive when they agree at their common resolution, while disagreements can identify local regulation or a mistaken measurement model rather than simply experimental failure.
Causal mediation is a further step. Randomizing a drug can establish an effect of the assigned treatment, but correlating a post-treatment neural signal with symptom change does not prove that signal mediated the effect. Both may reflect another drug consequence. Likewise, statistically controlling for movement can remove a confound in one causal model but remove a genuine intermediate mechanism in another. A causal diagram and an explicit target estimand should guide adjustment rather than a rule to regress out every variable associated with behaviour.
Human and animal approaches have complementary scope. Fine cellular interventions can provide internal validity in a restricted animal task, while human longitudinal observations can test whether candidate abnormalities precede illness and whether the same behavioural dimensions matter clinically. Ethical and practical constraints preclude arbitrary human lesions or perfectly selective transmitter manipulation. It would be unhelpful to discard clinically relevant observation for failing to perform an impossible experiment; equally, a prospective association should not be relabelled as a proven biological cause.
The most productive programme iterates among formal models, naturalistic measurements and selective perturbations. Specify the computation, identify its predicted signal, vary task factors that distinguish alternatives, and intervene with appropriate timing, targeting and performance controls. Re-test the resulting behavioural and neural predictions across contexts. Causal experiments generally have an advantage for a precise intervention question, but correlative approaches remain essential for deciding what should be changed and what the causal result actually explains.
Part II advanced option in the held 2022 papers. The source examination is shared by the psychology (experimental) course of the University of Oxford and the psychology, philosophy and linguistics course of the University of Oxford.
Solutions to all six essay options in the multisensory perception: attention, integration, and development course of the University of Oxford examination held on 24 May 2022. The examination required three options; all six are covered here, with each answer below 1,800 words. The scientific evidence used was published before the examination. Source release: released examination archive. The held PDF prints A16860W1; the archive contains two byte-identical members, including a16860w1.pdf. Original figures below illustrate stated models, not measured participant results.
Crossmodal correspondences differ meaningfully in what is associated, how the association is acquired and where it affects performance. A matching preference, a response-compatibility effect and altered perceptual binding are distinct observations. They need not have distinct underlying causes, and a single correspondence can have several causes.
A crossmodal correspondence is a systematic relation between attributes in different sensory modalities, such as auditory pitch and visual size. It does not require either stimulus to generate an extra conscious sensation. Thus it should not automatically be classified as developmental synesthesia, where stable inducer–concurrent experiences may be highly individual. Nor is correspondence equivalent to multisensory integration: judging that two attributes fit together does not establish that information from them was combined into one estimate.
Three useful explanatory distinctions concern sensory organization, environmental statistics and meaning. A structural crossmodal correspondence would arise from shared coding or magnitude organization; this predicts a relation surviving changes in labels and response assignments. A statistical crossmodal correspondence would link features repeatedly generated by the same objects. For example, geometrically similar resonators with a fixed wave speed have characteristic frequencies scaling approximately as inverse size: from , increasing lowers . This conditional physical relation can make pitch–size coupling informative, but different materials, tensions or sound-production mechanisms can reverse a simple rule. A semantic crossmodal correspondence can link dimensions through language or common concepts: “high” can describe pitch and elevation. An affective crossmodal correspondence could instead be mediated by shared pleasantness, which should be separated from a direct relation between sensory dimensions. These are explanatory hypotheses, not mutually exclusive boxes established by the appearance of a pairing.
Some correspondences are relative rather than absolute. A tone can be the higher member of one pair and the lower member of another. An experiment should therefore manipulate comparison range and context, rather than assuming that every participant has one fixed pitch-to-size conversion. Relations can also be asymmetric: an irrelevant sound might alter a visual response without a visual stimulus equivalently altering auditory judgment. Asymmetry can arise from task reliability or attention, so it does not by itself establish a one-way anatomical connection.
A comparative experiment provides an important constraint. Vera U. Ludwig and colleagues tested 33 humans and six chimpanzees on matching black and white squares while irrelevant high or low tones were played. Both groups performed better for high-pitch/white and low-pitch/black pairings; in chimpanzees the effect was expressed particularly in errors, whereas human errors were near floor and reaction times were more informative. Both species used a touchscreen and loudspeaker arrangement.[ref]
Visuoauditory mappings between high luminance and high pitch are shared by chimpanzees and humans by Vera U. Ludwig and others. PNAS 108, 20661–20665; Results, Apparatus and Procedure
This makes a human-language-only account inadequate for that mapping. It does not distinguish inherited organization from every form of nonlinguistic learning: the animals had substantial task experience, and shared environments can also generate shared associations.A stronger test of perceptual consequences changes the dependent variable. Cesare Valerio Parise and Charles Spence presented small/large visual stimuli with high/low tones and manipulated audiovisual timing or position. Participants judged temporal order or spatial discrepancy, rather than simply reporting which pairing they preferred. Matched pairings produced poorer access to the intersensory discrepancy, interpreted as stronger coupling.[ref]
When Birds of a Feather Flock Together: Synesthetic Correspondences Modulate Audiovisual Integration in Non-Synesthetes by Cesare Valerio Parise and Charles Spence. PLoS ONE 4:e5664; Experiments 1–3
This illustrates why increased binding need not improve every task: reducing conflict between estimates can make the conflict itself harder to discriminate. A changed discrimination threshold still needs controls for distraction, detectability and decision strategy; it does not uniquely identify a perceptual fusion mechanism.To distinguish mechanisms experimentally, first obtain unisensory detection and discrimination measures and equate unintended salience differences. Then compare explicit matching, speeded classification, conflict discrimination and judgments of a common object. Counterbalance response keys and reverse stimulus–response mappings. A congruency effect that follows the response rule suggests compatibility at a decision or motor stage; persistence under orthogonal response rules constrains that explanation. Fit psychometric functions to conflict judgments and estimate bias, slope and lapses separately. A shift in subjective equality and a loss of sensitivity are different outcomes.
Next manipulate experience. Randomly assign participants to congruent, reversed or uncorrelated audiovisual training with equal exposures, and test untrained exemplars and delayed retention. A reversible mapping with transfer supports an experience-dependent contribution; failure to reverse it does not prove innateness, because training may be weak or poorly measured. Cross-language comparisons with nonverbal responses can test whether a shared word is necessary. Infant or nonhuman results can constrain linguistic explanations, but age differences, task accessibility and species-specific response demands remain possible confounds. For a pleasantness account, collect independent pleasantness ratings and select or manipulate stimuli so that hedonic matching varies separately from the sensory pairing. These are proposed discriminating designs, not asserted experimental results.
The most useful classification therefore combines origin, representational content and measurable consequence. Correspondences are scientifically informative when their predicted transfer, context dependence and effects on sensitivity distinguish them from mere agreement about labels or response keys.
Single-unit recording has been exceptionally fruitful in identifying where and under what conditions multisensory signals interact. Its contribution to human perception is mechanistic and constraining; one cell's discharge is not a complete account of a conscious multisensory event. The strongest conclusions combine cellular recording with behavior, perturbation and models at a comparable computational level.
The essential advance is resolution. An extracellular electrode can isolate action potentials from a neuron, allowing experimenters to map its receptive fields in several sensory modalities, vary stimulus timing and intensity, and compare repeated trials. A cell responsive to light and sound demonstrates convergence at the output of that cell, rather than merely neighboring visual and auditory activity within one imaging voxel. Yet lack of an overt auditory response does not establish lack of auditory input: an input can modulate responsiveness without crossing the cell's firing threshold by itself.
Classic experiments by M. Alex Meredith and Barry E. Stein compared visual, auditory and somatosensory stimuli individually and in combination in the cat superior colliculus. Deep-layer neurons showed enhancement or depression when modalities were combined; many sampled cells had access to descending pathways relevant to orienting.[ref]
Visual, auditory, and somatosensory convergence on cells in superior colliculus results in multisensory integration by M. Alex Meredith and Barry E. Stein. J Neurophysiol 56, 640–662; comparisons of unimodal and combined responses and descending projections
This supplied an experimentally tractable mechanism for using several weak cues to guide an action. It did not require a distinct central place where every sensation becomes conscious.Response enhancement must be defined against an explicit benchmark. Let and be mean stimulus-evoked spike counts after subtracting the matched spontaneous count, and the similarly corrected paired response. Enhancement above the strongest input means . Superadditive multisensory response means the stronger condition . A response can satisfy the former without the latter. Subtracting baseline consistently matters because summing two raw counts also sums spontaneous activity twice. Trial variability and the analysis window determine whether an apparent inequality is statistically credible.
The spatial and temporal rules added testable organization. Mapping stimulus positions relative to each modality's receptive field showed that spatial alignment could favor enhancement, while other arrangements could yield suppression.[ref]
Spatial factors determine the activity of multisensory neurons in cat superior colliculus by M. Alex Meredith and Barry E. Stein. Brain Res 365, 350–354; spatial arrangement relative to receptive fields
Subsequent timing experiments found maximal enhancement when modality-specific peak discharge periods overlapped, with weaker or even depressive interactions at other offsets.[ref]Determinants of multisensory integration in superior colliculus neurons. I. Temporal factors by M. Alex Meredith and others. J Neurosci 7, 3215–3229; response-train overlap and temporal-disparity manipulations
The relevant coincidence is neural, so equal physical onset times need not maximize a cell's interaction.Inverse effectiveness further challenged an account based only on strong signals: the percentage enhancement was often largest when the isolated stimuli evoked weak responses. But the percentage measure itself needs care. If and , enhancement above the strongest response is 300%; if the corresponding values are 20, 20 and 26, it is 30%, although the absolute increment is six in both examples. These invented numbers illustrate a denominator effect, not a measured neuron. Percentage enhancement, absolute gain, information and behavioral benefit are distinct. Weak inputs can give biologically important interactions, but a large ratio alone is not enough to establish special multiplication or perceptual optimality.
Cellular and behavioral definitions of integration also differ. Faster responses to audiovisual than to either unisensory stimuli might arise from a redundant-signals race model: two channels race to trigger a response. If context-invariant channel completion times are , thenThis race model inequality follows from the union bound and does not require independent channels. Violation rejects that race account under its assumptions, but does not identify which collicular or cortical cells produced the effect. Conversely, a nonlinear cell response need not produce a detectable behavioral advantage if other stages limit performance.
Translation to humans requires care about species, sampled structure, task and state. The superior colliculus is well suited to studying orienting, but flavor identity, speech comprehension and deliberate causal judgments need additional circuits. Animal preparation and restraint can change the operating state; a sampled cell population may not represent every multisensory computation. Spiking also reflects recurrent and descending influences, not just a feed-forward meeting of modalities. Human functional magnetic resonance imaging has broader coverage but coactivation cannot establish convergence in one neuron. Timing measures, eye movements, psychophysical cue conflicts and causal perturbations provide complementary constraints.
A useful bridge is to ask whether cellular mechanisms predict a specific human outcome: which weak cue improves localization, which offset permits binding, or when a distractor suppresses orienting. Multisensory cue integration models predict changes in estimates and uncertainty, which are not the same quantity as firing-rate enhancement. Development and learning must also be tested rather than inferred from mature animal responses. Single-cell work supplied fundamental interaction rules and plausible circuit operations; explaining human multisensory experience requires linking those operations to population codes, task-specific decisions and causal behavioral evidence.
Articles were limited to the first 100 out of 279 total.
Articles by others on the same topic
There are currently no matching articles.