Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Quadratic norm penalty
Past exam of the mathematics course of the University of Cambridge 2016 iii Paper 335 3 a Solution Created 2026-10-03 Updated 2026-10-06
A regularization of an inverse problem replaces the possibly unbounded inverse by a family of continuous reconstruction operators . For compatible exact data it must recover the minimum-norm solution as . For noisy data , a parameter rule must make both bias and amplified noise tend to zero. The target is the minimum-norm solution because data cannot determine a component in the kernel of a linear map.
Tikhonov regularization minimizesThe quadratic norm penalty makes this functional strictly convex and a coercive function. Its first variation, applied to arbitrary real and imaginary perturbations, givesThe positive operator is bounded below by and has a bounded inverse. The unique Tikhonov regularization solution isThe Tikhonov stability bound follows from the singular-value gain:Thus reconstruction is stable for each fixed positive . Stability is not uniform as : that limit restores the unbounded inverse. For exact compatible data,The singular system of a compact operator makes this strong convergence transparent: each positive singular-value coefficient tends to zero and is bounded by the corresponding coefficient of . Consequentlywhenever and , for example . This is a convergent regularization of an inverse problem, not merely a bounded formula.
Regularization of an inverse problem Created 2026-09-24 Updated 2026-10-14
Regularization replaces sensitive inversion by a controlled approximation. For a bounded linear operator between Hilbert spaces, a linear regularization is a family of bounded linear operators satisfying as for each datum in the domain of the Moore–Penrose inverse of an operator. Noisy-data convergence additionally requires a suitable regularization parameter choice.[ref] Nonlinear variational regularization can instead use nonquadratic penalties.
The noise-bias decomposition for linear regularization separates two costs: amplifying measurement noise and changing the exact-data reconstruction. Truncated singular value decomposition discards weak modes; Tikhonov regularization attenuates them smoothly. A quadratic norm penalty expresses a preference for smaller reconstructions. Neither method manufactures a missing null space component: with complete averaging, the minimum-norm least-squares solution for is , even if the original image was . The preference selects a representative; extra observations or justified constraints are needed to identify the original.
For Tikhonov regularization, the Tikhonov stability bound limits transmitted measurement noise of norm at most to . Taking while gives a sufficient rule for convergent regularization of an inverse problem. Holding fixed leaves approximation bias; letting it vanish too quickly can admit overwhelming measurement noise.
Tikhonov regularization Created 2026-09-24 Updated 2026-10-14
For a bounded linear operator between Hilbert spaces and , Tikhonov regularization minimizesThe quadratic norm penalty makes this functional a strictly convex, coercive function, yielding the unique minimizer displayed in the title. Here is the adjoint operator and the identity operator. Our regularization parameter multiplies the squared norm directly. Hansen's notes instead write : the same reconstruction requires , not .[ref]
https://www.imm.dtu.dk/~pcha/Regutools/RTv4manual.pdf. Per Christian Hansen, Regularization Tools, §§2.4 and 2.7.1
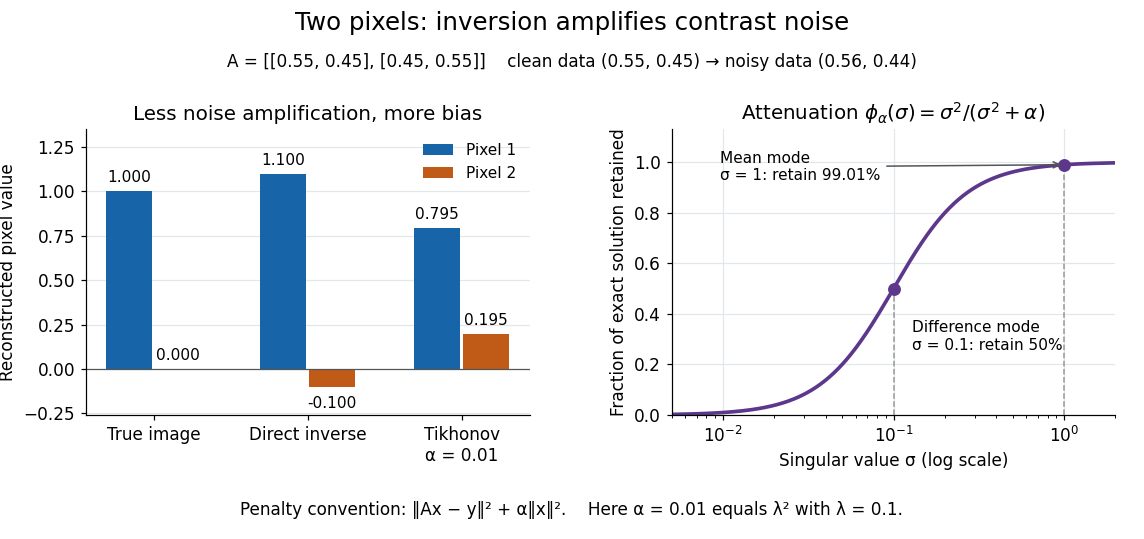
For a real matrix with singular value decomposition , the exact reconstruction isThe singular-system Tikhonov filter is the data-to-solution gain; is the fraction of an exact solution mode retained. If , a positive singular value mode has errorThe first term is approximation bias; the second is transmitted measurement noise. Suppressing a weak mode suppresses its true signal too.
For the two-pixel matrix in the inverse problem example and (), the mean and difference attenuation factors are and . Since , the reconstruction isIts noise contribution is , half the direct inverse's, but its exact-data reconstruction is . Consequently its total error Euclidean norm, about , exceeds the direct inverse's : this parameter sacrifices too much contrast. Taking instead gives and error about . Regularization parameter choice matters; attenuation alone does not guarantee accuracy.