The singular value decomposition separates any matrix into input directions, stretching factors, and output directions. Every complex matrix admitsHere are unitary matrices, is the conjugate transpose, and is a rectangular diagonal matrix. Its diagonal entries are the singular values, ordered . We use the conventional letters: contains the right singular vectors , while contains the left singular vectors . Writing instead merely swaps these two matrix names; it requires swapping their roles consistently. For real matrices, choose orthogonal matrices and replace the conjugate transpose with the transpose.[ref]
Reading from right to left, expresses the input in an orthonormal basis, stretches or annihilates those coordinates, and assembles the output in another orthonormal basis. Unlike matrix similarity, the input and output bases can differ, and even have different sizes. A matrix has full factors of sizes , , and . If its matrix rank is , one can retain only the active columns, giving sizes , , and for ; the full additionally describes an unused output direction.
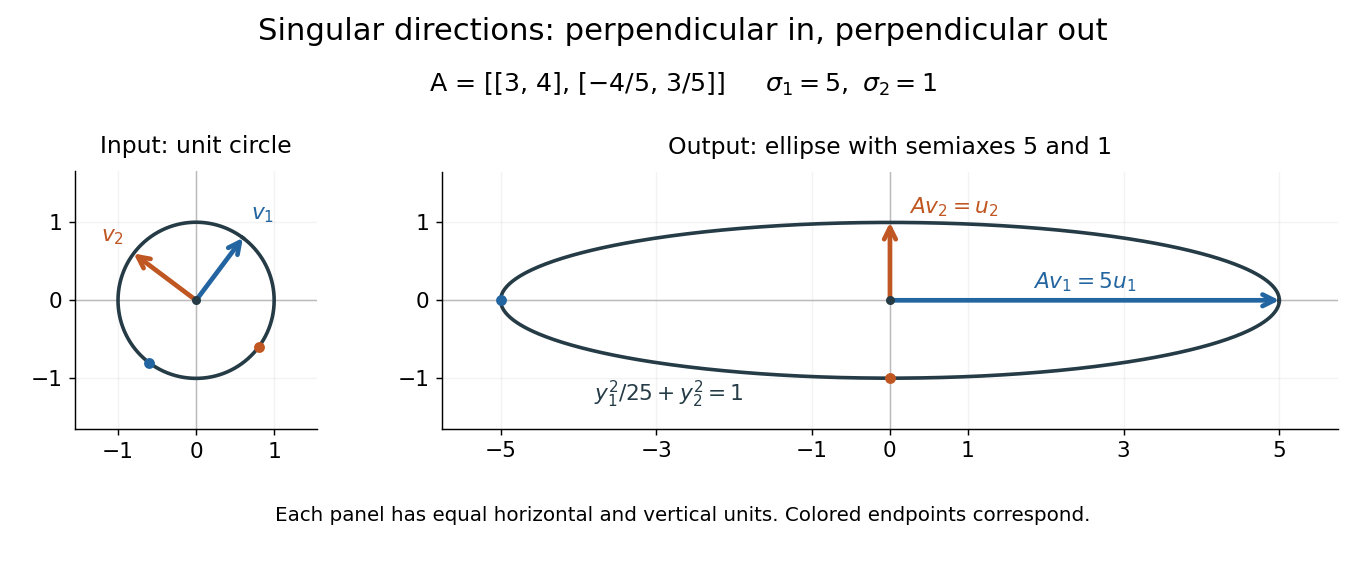
For a fully computed nonsymmetric example, takeMultiplication gives . The right singular vectors are and ; their images are and . Thus, parametrizing the unit circle by gives . Its image is the ellipse . The two singular values are its semiaxis lengths, and the left singular vectors point along its axes. The singular value decomposition finds precisely the perpendicular input directions whose images stay perpendicular.
For compression, write the matrix as a sum of outer products and retain the largest terms:where is the matrix rank. Among all matrices of matrix rank at most , minimizes the Frobenius norm error; this is the Eckart-Young-Mirsky theorem. The operator norm error is for . These statements concern specified norms, rather than guaranteeing that discarded details are visually or scientifically unimportant.[ref]
Consider an brightness matrix , withand , . The broad bright patch and alternating checkerboard have orthogonal row and column directions: . Their singular values are and . This low-rank approximation keeps the first outer product, giving , with Frobenius norm error and relative error . For example, becomes , and becomes : every entry changes by in magnitude. The discarded pattern is small but entirely lost.
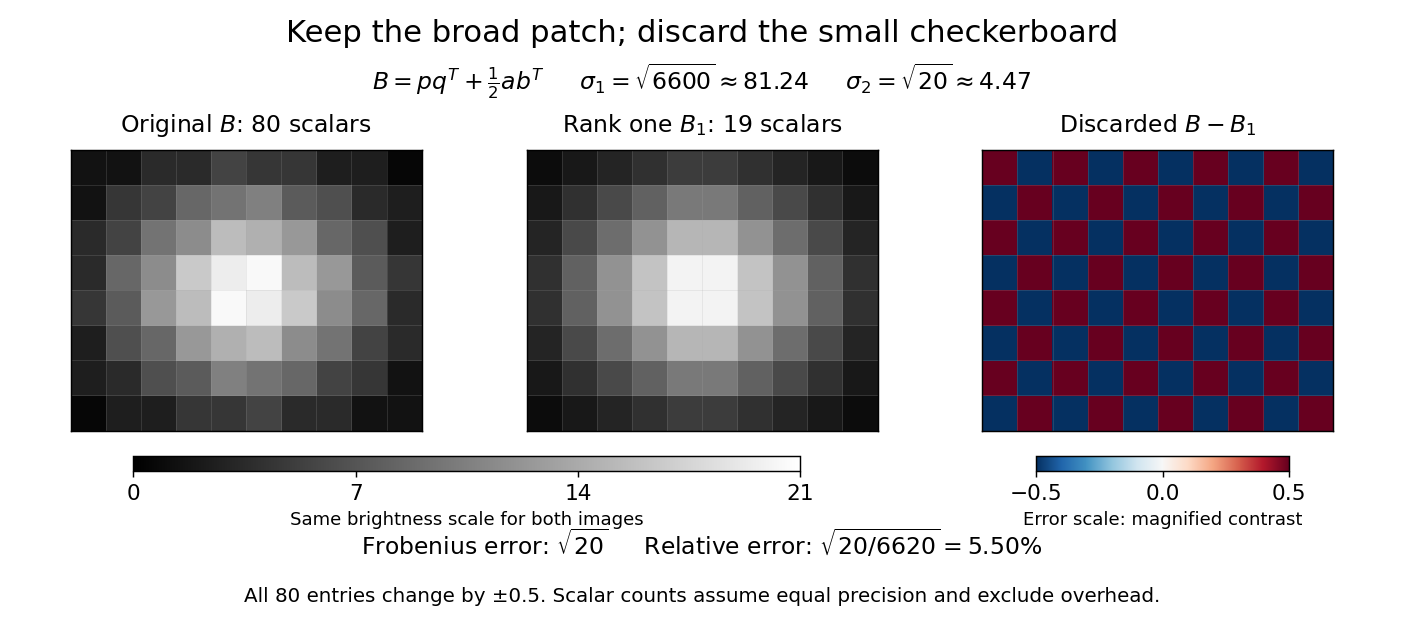
For this illustrative image compression, storing one normalized left singular vector, one normalized right singular vector, and one singular value requires scalars instead of . This counts scalars at equal precision, before storage overhead. In general, scalars beat only for sufficiently small , and small error requires a small discarded sum of squared singular values. The usefulness comes from measuring the tradeoff before throwing information away.[ref]
https://math.mit.edu/~gs/linearalgebra/ila5/SVD_Slides.pdf. Verma, Singular value decomposition of real matrices, slides 9 and 15–16
If a matrix with orthonormal columns is divided into two row blocks, each having at least as many rows as there are columns, it admits simultaneous thin factorizations , , with orthonormal , an orthogonal matrix , and nonnegative diagonal matrices satisfying . To prove this, apply the spectral theorem to ; the same orthonormal eigenbasis diagonalizes . Normalize the nonzero columns of and complete the zero columns to orthonormal sets. The entries of can be written as cosines and sines of angles in .
Every complex symmetric matrix admits a unitary congruence decomposition with a unitary matrix and nonnegative diagonal entries equal to its singular values. This differs from unitary similarity diagonalization. It reduces a multimode squeezed vacuum to independent oscillator squeezing factors.
The singular values of a matrix measure stretching of Euclidean norm. They are the nonnegative square roots of the eigenvalues of , counting the diagonal slots of the singular value decomposition; when , has additional zero eigenvalues. Nonnegativity follows from , so is a positive semidefinite matrix. For the preceding matrix,Both have eigenvalues , giving singular values . In particular,Here the operator norm uses Euclidean norm: no unit vector stretches more than fivefold. Zero singular values identify lost directions; the number of positive singular values equals the matrix rank. This summarizes both amplification and information loss with nonnegative numbers.[ref]
https://math.mit.edu/~gs/linearalgebra/ila5/SVD_Slides.pdf. Verma, slides 7–8: singular values and maximum stretching
Small positive singular values also explain sensitivity in an inverse problem. For a square invertible matrix, the matrix inverse sends to : a weak forward response becomes strong inverse amplification. The condition number for Euclidean norm is , equal to in our example. To see a larger effect, keep the same right singular vectors but change the second singular value to :The output perturbation has Euclidean norm , but the recovered input changes by . Its hundredfold amplification follows from the direction of the perturbation, not just its size. The condition number is now ; it measures the disparity between the strongest and weakest responses.[ref]
https://www.cs.cornell.edu/courses/cs322/2007sp/notes/condition.pdf. Marschner, Condition numbers, §2: inverse amplification and singular values
For a real matrix , let . It is positive semidefinite, and the spectral theorem for real symmetric matrices gives . If , rescaling any longer vector to unit length decreases its image norm, so minimizers lie on the unit sphere. Lagrange multipliers applied to with give . Thus the minimizers are exactly the unit vectors in the least eigenspace.
If , the minimum is zero and the full argmin consists of all with . Indeed, because . Restricting the minimizers to the sphere would omit longer kernel vectors in this case. For a ball constraint , the argmin is always intersected with the ball.
For equally sized matrices, corresponding ordered singular values differ by at most the spectral norm of the perturbation. Indeed, let be a best approximation of matrix rank at most . The Eckart-Young-Mirsky theorem and the triangle inequality give . Interchanging proves the bound.
A right singular vector is a unit vector in the input space satisfying . For positive singular values, determines the matching left singular vector. In the ellipse example, is not parallel to : a right singular vector need not be an eigenvector of . Indeed, the characteristic polynomial of is , with eigenvalues and no real eigenvectors. Nevertheless, its real right singular vectors give a complete orthonormal basis. Eigenvectors describe preserved directions; right singular vectors describe orthogonal input channels of stretching.[ref]
An arbitrary input mixes these channels. For , orthogonality gives , while . Equal contributions, , produce output Euclidean norm from a unit vector. Concentrating the entire input along produces the maximum . This is why the right singular vectors give a direct reading of how any input will behave. For a compact operator, the same definition describes the positive terms of its singular value system.
A left singular vector is a unit vector in the output space satisfying . For positive singular values, the pairing also satisfies . Thus and describe the output axes of the preceding ellipse, while the right singular vectors describe its input directions. At zero singular values, division by is impossible: complete the orthonormal bases independently in the null spaces of and . Repeated singular values allow different matched orthonormal bases within the corresponding eigenspaces. The same positive pairing extends to a compact operator through its singular value system.
Even distinct singular values do not fix arrow signs: replacing both and by their negatives preserves and the outer product . Reversing only one arrow would change that term's sign. The paired directions, rather than independently chosen arrow orientations, encode the matrix.
Articles by others on the same topic



Singular Value Decomposition (SVD) is a mathematical technique in linear algebra used to factorize a matrix into three other matrices. It is particularly useful for analyzing and reducing the dimensionality of data, solving linear equations, and performing principal component analysis.