An inverse problem reconstructs an unknown object from observed data and a specified model . The associated forward problem predicts the observations from . In image deblurring, contains sharp pixel values and a matrix mixes neighbouring pixels; in tomography, the observations are integrals through the object. The appeal is that indirect measurements can reveal otherwise inaccessible structure. The difficulty is that the forward problem may erase precisely the distinctions we want to recover.
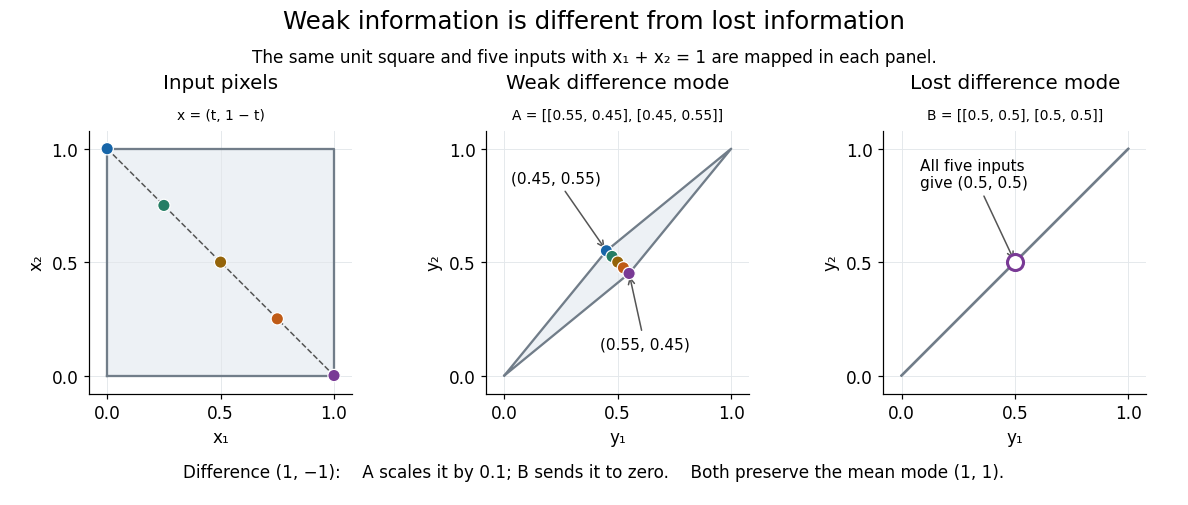
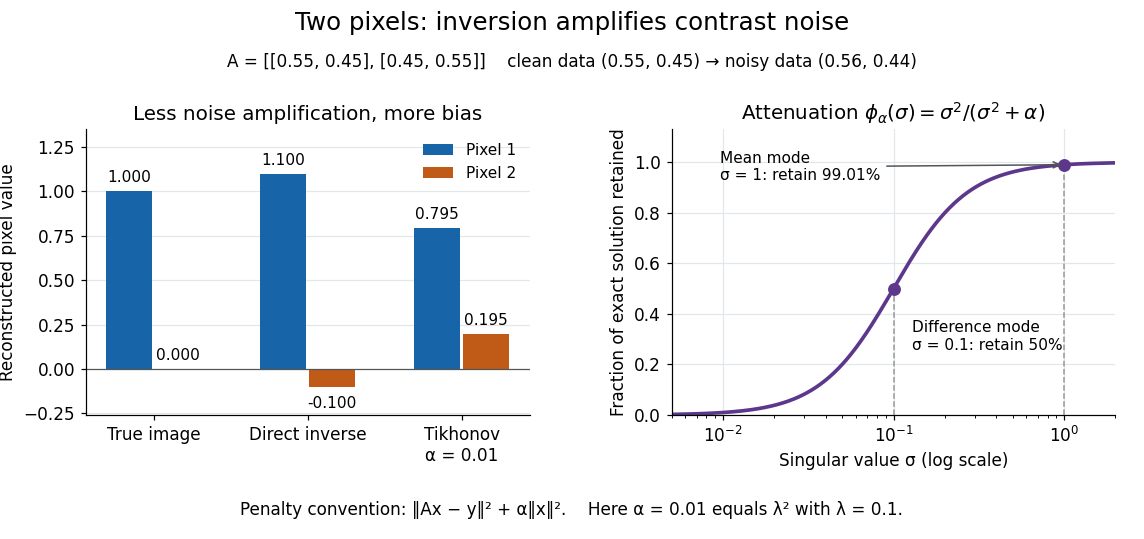
Consider this completely computable two-pixel image deblurring model:Each measured pixel retains of its own value and receives of its neighbour's. Adding measurement noise gives , whose direct reconstruction is . The Euclidean norm of the reconstruction error is , ten times the data error . A negative second pixel appears even though both observed pixels are positive.
Despite this wrong reconstruction, its residual of an inverse problem is exactly zero: the predicted data equal the noisy observations. Thus matching the data perfectly does not certify reconstruction accuracy. The relevant question is how large a change in the unknown could hide within the measurement uncertainty. A condition number quantifies that sensitivity for an invertible matrix; the null space identifies changes that no improvement in precision can reveal.
The exact singular value decomposition explains this amplification. With the orthonormal basisthe mean mode survives unchanged while the difference mode shrinks tenfold. Direct inversion multiplies difference-mode measurement noise by ten. The condition number is . The beauty of the singular value decomposition is this separation into independent channels: it identifies which information survives and which needs protection by regularization of an inverse problem.
A Riemannian metric is boundary rigid within a specified class if the distances it induces between all pairs of boundary points determine the interior metric, up to a diffeomorphism that fixes the boundary pointwise. The qualification is unavoidable: relabeling interior points in this way changes the coordinate expression of the metric without changing any boundary distance.
This inverse problem idealizes recovering an interior wave-speed geometry from boundary travel times. Its data are shortest-path distances, so arbitrary trapped regions need not be visible. For a Euclidean disk, multiplying the metric by multiplies every boundary distance by ; this simple experiment already distinguishes a uniform change of travel-time scale. Determining a general spatially varying metric is much harder. A landmark theorem proves boundary rigidity for compact simple two-dimensional Riemannian manifolds, where the boundary is strictly convex and the relevant geodesics have no conjugate-point ambiguity.[ref]
Different subsurface models can produce the same measured field. A gravity anomaly, for example, does not uniquely separate density, body shape and regional background. Geological constraints and complementary observations reduce this ambiguity; an inferred density should retain the model and reference-field assumptions used to obtain it.
Inference of subsurface geophysical density contrast from a gravity anomaly. Different geometries and density distributions can produce the same external field, so independent geological or seismic constraints are essential.
Image registration estimates a coordinate transformation aligning corresponding image content. If is the moving image and is the reference, one simple model chooses a transformation to minimizeThe first term compares image values; penalizes unwanted deformation. A translation model has only a displacement vector to estimate, while a spatially varying deformation needs many more parameters and stronger regularization.
The transformation direction is part of the convention: this expression samples the moving image at for each reference location. The sampling requires interpolation when falls between pixel centers. Boundary handling must also specify what happens outside the image domain.
Intensity agreement does not prove correct correspondence. Repeated patterns can produce several alignment minima, and a change of imaging modality can alter intensities even at matching physical locations. The transformation family, similarity objective, interpolation rule and deformation penalty are distinct modeling decisions in this inverse problem.
Phase retrieval reconstructs a signal from measurements that discard its complex wave phase. A basic diffraction model measures , rather than the complex Fourier transform itself. The lost phase cannot generally be recovered simply by taking a square root of the intensity.
There are immediate ambiguities. Multiplication by a constant leaves every magnitude unchanged. A translation multiplies the transform by a unit-modulus phase factor, and conjugate reflection conjugates its transform. These transformations therefore preserve . They need not exhaust the ambiguities of one-dimensional data.[ref]
Fourier Phase Retrieval: Uniqueness and Algorithms by Tamir Bendory and others. §3.1, printed p6, trivial and non-trivial ambiguities
By the convolution theorem, magnitude-squared data determine the autocorrelation of a square-integrable function under suitable inversion hypotheses, rather than automatically determining the function itself. Known support, additional masked measurements or other structural assumptions can reduce the ambiguity; their sufficiency must be checked for the actual measurement model. Frequency-resolved optical gating uses a family of delayed nonlinear spectra, giving more information than a single unmodified Fourier magnitude.
Seismic tomography infers a spatial model of elastic-wave propagation from many source-receiver observations. Uneven illumination, finite wavelength, parameter tradeoffs and regularization limit its resolution. A seismic-velocity image is not directly an image of temperature or flow velocity.
Surface-wave tomography combines path-dependent measurements of seismic surface-wave dispersion to infer lateral and depth variation in elastic properties. Joint Rayleigh wave and Love wave measurements can help constrain seismic anisotropy.
Seismic source inversion estimates source location, origin time and source strength or mechanism from seismograms. A symmetric seismic moment tensor has six independent entries. At fixed location and origin time, its predicted seismograms are linear in those entries, allowing variable projection to reduce the nonlinear search.
Image deblurring reconstructs a sharper image from observations described by a blur model. In the linear model, a matrix or linear operator mixes values of the unknown image; measurement noise perturbs the observed result. The inverse problem must therefore recover attenuated distinctions while controlling amplification of measurement noise, as the two-pixel example illustrates.
Tomography reconstructs an interior distribution from measurements along multiple lines or paths through it. A linear unattenuated model is the Radon transform; absorption changes it to an attenuated Radon transform.
Tomography using approximately coincident annihilation-photon detections to constrain an internal emission distribution. A calibrated model accounts for propagation, detector response, unrelated coincidences and scattering.
A pair of nearly simultaneous detector events treated as a candidate two-photon positron annihilation. True unscattered pairs define a coincidence line of response. For attenuation along one such line, the complementary survival path integrals add to the full chord and are independent of the annihilation depth.
The distance between positron emission and annihilation. Its distribution introduces a blur even if the subsequent line of response is measured perfectly.
Coincidence imaging using the detection-time difference to estimate annihilation position along a line of response. For timing difference , displacement from the midpoint is .
The line joining two coincident photon detections in ideal two-photon annihilation imaging. Finite detector size, non-collinearity and positron travel limit its relation to the original decay position.
A line defined by an approximately coincident detector pair in annihilation-photon tomography. An event constrains a possible annihilation location to that line within instrumental and physical uncertainties. Time-of-flight data can add a position constraint along it; attenuation, scattering and random coincidences change the forward model.
Transmission measurements determine line integrals of an absorption coefficient after taking the logarithm of incident intensity divided by transmitted intensity. Under the ideal straight-ray model, these measurements are a Radon transform; filtered backprojection reconstructs a planar slice. Angular coverage, calibration and noise control matter because differentiating measured projections amplifies high frequencies. In contrast, single-photon emission computed tomography reconstructs an emitting source through a possibly attenuating medium.
A dimensionless relative attenuation value calibrated so that water is zero and air is approximately . It depends on the computed tomography spectrum and material composition. It is not directly a linear attenuation coefficient at the energy used in positron emission tomography.
X-ray tomography at a scale that can resolve small skeletal features without destroying a specimen. Segmentation and resolution constrain anatomical interpretation.
A form of tomography that reconstructs an internal radioactive source from directional counts of individually emitted photons. Known spatial photon absorption gives the exponential path weight in an attenuated Radon transform. Full directed data and a suitable reconstruction formula recover the source intensity rather than a transmitted exterior-beam attenuation map.
An inverse problem is an ill-posed problem if it fails any requirement of a well-posed problem: existence for every admissible datum, uniqueness, or continuity of the reconstructed object as the data change. These requirements depend on the chosen spaces and norms, not just the equation. Clason's regularization notes formulate this distinction explicitly.[ref]
Complete averaging illustrates lost information:The difference mode belongs to the null space because . Even restricting both pixels to leaves infinitely many indistinguishable inputs. This is failure of uniqueness. Data such as also have no exact preimage under , illustrating failure of existence when arbitrary two-component observations are admissible.
The two-pixel matrix in the inverse problem example has a weakly observed difference mode, not a null space mode. Its inverse is continuous: this finite-dimensional problem is a well-posed problem with noise-sensitive conditioning. Small positive singular values alone do not imply mathematical ill-posedness. In infinite-dimensional problems, positive singular values approaching zero can make inversion unbounded: unit solution modes then produce data tending to zero. This destroys continuity even without a null space. Regularization of an inverse problem must distinguish missing information from information recoverable only at the cost of amplifying measurement noise.
The X-ray transform records integrals of a function or tensor evaluation over a specified family of curves. The curve family, parametrization and any weights are part of the definition. Straight lines, geodesics and magnetic flows give different versions; their injectivity and unavoidable potential kernels depend on that geometry.
The transform integrates a base function and a velocity-evaluated one-form along the closed trajectories of a surface thermostat. Every exact differential form of degree one integrates to zero, because . The relevant kernel theorem concerns these functions of velocity degree zero and one, rather than arbitrary functions on the unit tangent bundle.
For a smooth Anosov flow generated by a surface thermostat on a closed oriented Riemannian surface, a smooth base function plus a smooth one-form is a smooth flow coboundary precisely when the base function is zero and the one-form is an exact differential form. This is the nontrivial degree-zero/one kernel theorem. It does not require negative curvature or preservation of Liouville volume. The converse follows directly from . A primary proof of the kernel theorem is arxiv.org/abs/math/0601039.
The magnetic transform integrates functions or velocity-evaluated one-forms along magnetic trajectories, rather than ordinary geodesics. For closed trajectories, every exact one-form integrates to zero. Hyperbolic dynamics can make these the entire degree-one kernel.
For a smooth Anosov magnetic flow on a closed oriented surface, a smooth function plus a smooth one-form can be a smooth flow coboundary only when the function is zero and the one-form is exact. Equivalently their sum has zero integral along every closed orbit precisely in that case, using the smooth Livšic theorem. This is the nontrivial magnetic transform kernel theorem. Exact one-forms give the converse directly, since . The theorem does not require pointwise negative Gaussian curvature.
For a symmetric covariant two-tensor, the geodesic transform integrates its evaluation on the unit velocity along boundary-to-boundary or closed geodesics, as appropriate to the manifold. A potential symmetric 2-tensor gives a total derivative along each geodesic and therefore integrates to zero on closed geodesics; boundary data require the corresponding boundary potential to vanish.
The displayed one-form on the unit round sphere has zero integral on every closed geodesic. Indeed, the antipodal map pulls it back to its negative, and the second half of an oriented great circle is the antipodal image of the first. Nevertheless is nonzero on an open set, so the one-form is not a closed differential form and cannot be an exact differential form. Thus a curvature-free extension of one-form injectivity fails.
On a closed oriented Riemannian surface this integral identity follows from the canonical commutators and integration by parts against Liouville volume of a surface geodesic flow. If and , substitution gives . Each term is nonnegative, forcing all three derivatives to vanish. For , the fibre equation then makes a constant plus a fibrewise linear function, supplying the potential symmetric 2-tensor kernel.
For a vector field , define . Its diagonal evaluation is . Along a geodesic this equals , so it is invisible to closed-geodesic integrals. If a fibrewise linear function solves , then gives this convention.
A forward problem computes observable data from a known state or parameter and a specified model . Its associated inverse problem reconstructs from and the model. Inverse problems can fail existence, uniqueness or continuous dependence on the data.
The residual is the difference between predicted and observed data. Its norm measures data misfit and can determine an iteration stopping rule for regularization of an inverse problem.
An inverse scattering problem reconstructs a medium or obstacle from measured scattered waves. Under the Born approximation, fixed-frequency far-field data sample the Fourier transform of the scattering potential on a restricted frequency surface.
For an outgoing field outside a sphere of radius , write . Its far-field pattern is . If its trace on that sphere lies in L2 space, Parseval's identity gives . The fixed-argument growth of spherical Hankel functions yields the displayed equivalent range condition, with the low-order weights defined finitely. Square summability of the far-field coefficients alone does not ensure continuation to the chosen sphere.
Continuation of a far-field pattern to a spherical trace multiplies harmonic coefficients by the displayed factor, whose magnitude grows faster than exponentially with order. A data error of size in one normalized high-order harmonic therefore produces near-field error , unbounded as its order increases. Some noisy square-summable far fields fail the range condition entirely. This proves unstable field continuation; bounds on actual obstacle geometry additionally require an admissible shape class and a stable boundary-extraction procedure.
The Born approximation for scalar wave scattering relates an incident plane wave and the transverse Fourier transform of its scattered field to samples of the three-dimensional Fourier transform of a scattering potential on a shifted Ewald sphere. One incident direction at one frequency samples a surface, rather than an entire three-dimensional frequency region. Additional illuminations, frequencies or structural constraints are needed for a full reconstruction.
With , elastic scattering into a propagating wavevector samples Fourier transfer . These transfers satisfy the displayed shifted sphere relation. This reciprocal-space construction appears in crystallographic diffraction and the Fourier diffraction theorem.
With the normal directed out of an obstacle into the fluid, a field solving outside has the representationHere is the outgoing Green function for the three-dimensional Helmholtz equation and the observation point lies outside the obstacle. The formula follows from Green second identity; the normal to the exterior fluid on its inner boundary is the negative of the stated obstacle normal. The surface term represents the scattered field.
For a scattered field satisfying , the Kirchhoff–Helmholtz representation givesThe sign assumes the normal points out of the obstacle.
A Herglotz wave function is a superposition of incident plane waves,It solves the Helmholtz equation everywhere and is real analytic. The finite sphere area makes the density integrable, so each spatial derivative can be taken under the integral.
Pairing a far-field pattern with the conjugate density of a Herglotz wave function converts the angular integral into boundary data:This follows by substituting the surface representation of an obstacle far-field pattern and interchanging the integrals.
If measured far-field patterns determine a density and its Herglotz wave function equals a prescribed spherical wave on the obstacle boundary, that trace identity can locate the boundary. A star-shaped axisymmetric obstacle can be represented by one radial function . Numerically, expand and in suitable bases, match the far-field constraints, and minimize the complex boundary residual at angular collocation points, using regularization of an inverse problem for noise and small singular values. A single scalar pairing constraint alone does not determine an arbitrary density.
For a refractive index and background wavenumber , one sign convention defines the scattering potential by . The total field then satisfies .
The opposite convention gives and reverses the sign attached to the corresponding Green-function integral. Either convention is valid when used consistently.
Using , the scalar Lippmann-Schwinger equation is . The Born approximation replaces the total field inside the integral by the known incident field:For a unit plane wave, its far-field pattern is . Thus each incident direction samples a shifted sphere in the Fourier transform of the potential.
For real , the displayed real compactly supported contrast has Fourier transform . This vanishes on the shifted Ewald sphere because there. Thus nonzero contrasts can have zero fixed-frequency, fixed-incidence Born approximation data. A small amplitude preserves weak contrast and a positive refractive index.
The Born series is the Neumann series expansion of the Lippmann-Schwinger equation. Its terms describe successive orders of wave scattering; convergence is ensured, for example, by a scattering operator norm smaller than one.
The Rytov approximation writes a total wave field as and linearizes the equation for the complex logarithmic perturbation . At first order, equals the first Born approximation scattered field, soIt can remain useful when phase accumulation is appreciable but local scattering is weak.
If the first logarithmic perturbation is a centered linear functional of a Gaussian random field, the complex Gaussian exponential moment gives the displayed mean of the first Rytov approximation . This is the mean of the truncated logarithmic model. A nonzero mean of the omitted second logarithmic perturbation can change the true field mean at order .
For a centered real scattering potential fluctuation and the imaginary part of the incident-field-weighted Green function, . Its mean vanishes, and its covariance function is the double integral of the two deterministic kernels against the covariance function of . The correlation of the refractive index itself is insufficient when the scattering potential depends quadratically on that index.
The Rytov approximation omits the quadratic gradient source in the logarithmic wave perturbation equation. Its next correction solves . Control of the propagated correction, weak amplitude fluctuations and avoidance of field zeros are needed. An appreciable smooth accumulated phase can be retained by exponentiation; small total phase is not the same condition as small local phase gradients.
The logarithmic wave perturbation measures relative complex amplitude and phase through . A continuous branch requires nonzero incident and total fields in the region considered. For the Helmholtz equation with scattering potential convention , its equation is . The dot product is bilinear, not a squared modulus.
Let with unit-modulus incidence and . For a centered real Gaussian random field , the exponential moment of a Gaussian linear functional givesHere is the autocorrelation function of a random field. Both the covariance and the generally nonzero term enter the exponent; dropping the latter is not justified for an arbitrary finite real random medium.
For with jointly centered unit-variance Gaussian random field , the scattering potential has mean and covariance . It is not Gaussian. In the far-field Rytov approximation let , so intensity is . Expansion through order includes both the mean term and the covariance term shown. The remainder starts at order under suitable exponential integrability. Keeping a covariance correction while omitting the same-order mean term is inconsistent. The exact quadratic model uses the Gaussian quadratic exponential moment.
For a bounded source region and fixed positive wavenumber, expand . In the outgoing Green function for the three-dimensional Helmholtz equation, this gives . Volume integration gives the outgoing field's far-field pattern with an remainder. The estimate is an asymptotic statement for fixed source size and frequency.
The Sommerfeld radiation condition selects outgoing solutions of the exterior Helmholtz equation. In three dimensions it requires as uniformly in direction.
A problem is well posed in the sense of Hadamard when a solution exists for every admissible datum, is unique, and depends continuously on the data. Failure of any condition makes it ill posed.
Regularization replaces sensitive inversion by a controlled approximation. For a bounded linear operator between Hilbert spaces, a linear regularization is a family of bounded linear operators satisfying as for each datum in the domain of the Moore–Penrose inverse of an operator. Noisy-data convergence additionally requires a suitable regularization parameter choice.[ref] Nonlinear variational regularization can instead use nonquadratic penalties.
The noise-bias decomposition for linear regularization separates two costs: amplifying measurement noise and changing the exact-data reconstruction. Truncated singular value decomposition discards weak modes; Tikhonov regularization attenuates them smoothly. A quadratic norm penalty expresses a preference for smaller reconstructions. Neither method manufactures a missing null space component: with complete averaging, the minimum-norm least-squares solution for is , even if the original image was . The preference selects a representative; extra observations or justified constraints are needed to identify the original.
For Tikhonov regularization, the Tikhonov stability bound limits transmitted measurement noise of norm at most to . Taking while gives a sufficient rule for convergent regularization of an inverse problem. Holding fixed leaves approximation bias; letting it vanish too quickly can admit overwhelming measurement noise.
For a positive self-adjoint linear operator , Lavrentiev regularization shifts itself rather than . In a finite-dimensional positive-definite problem, writing gives error coefficients in its orthonormal eigenbasis. Consequently . A known bound permits , giving a robust bound . For fixed positive , the sharper finite-dimensional estimate can give a linear noise rate with a smaller parameter; regularization is then a conditioning choice, not a cure for nonexistence of the inverse.
A linear regularization uses a family of bounded linear operators such that for each . A regularization parameter choice must balance approximation error with noise amplification to obtain a convergent regularization of an inverse problem.
For the mixed forward, central finite difference, and backward derivative regularizer on , with dividing points and , the overlap multiplicity bound for piecewise difference operators has . On the middle interval, the error kernel is for , with L1 norm . Young's convolution inequality bounds that part of the bias by . If the two outer intervals together have squared error at most , combining the three pieces gives the displayed estimate for and . Interpreting as the inverse of the Volterra integration operator requires the range of the Volterra integration operator boundary condition .
Suppose a piecewise finite difference uses two translated evaluations divided by . If the pulled-back evaluation intervals cover almost every input point at most times, then gives . This converts an interval-overlap count into an operator norm estimate without requiring pointwise values of an L2 space equivalence class outside the almost-everywhere evaluation rule.
A regularization parameter controls the tradeoff between approximation bias and data-noise amplification in an inverse problem. For early stopping of Landweber iteration with fixed step , the convention associates a smaller parameter with more iterations.
A regularization is convergent when its parameter can be chosen from the noise level and data so that the regularized reconstruction converges to the exact Moore–Penrose inverse of an operator solution as the noise level tends to zero.
For a bounded linear regularization operator and noisy data with , the triangle inequality givesThe first term is noise amplification; the second is the approximation bias on exact data. Thus and suffice for a convergent regularization of an inverse problem, provided is consistent on exact data.
A spectral regularization method applies a bounded scalar filter to the spectrum of . In a singular system of a compact operator, it has the formwhere the filters approximate while controlling amplification near .
Asymptotic regularization stops the gradient flow at , starting from zero. With the singular system of a compact operator convention , its spectral filter givesThe scalar coefficient solves with zero initial value. Since for , the operator norm is at most . On the domain of the Moore–Penrose inverse of an operator, dominated convergence theorem of the squared spectral coefficients proves . The noise-bias decomposition for linear regularization then gives noisy-data convergence when .
For a singular value decomposition , truncated SVD with cutoff estimates the inverse action by . Discarding small singular values limits amplification of data errors; this is a spectral regularization method.
Truncated singular value decomposition retains only singular components above a threshold, or equivalently only a finite leading set of singular vectors.
For a bounded linear operator between Hilbert spaces and , Tikhonov regularization minimizesThe quadratic norm penalty makes this functional a strictly convex, coercive function, yielding the unique minimizer displayed in the title. Here is the adjoint operator and the identity operator. Our regularization parameter multiplies the squared norm directly. Hansen's notes instead write : the same reconstruction requires , not .[ref]
https://www.imm.dtu.dk/~pcha/Regutools/RTv4manual.pdf. Per Christian Hansen, Regularization Tools, §§2.4 and 2.7.1
For a real matrix with singular value decomposition , the exact reconstruction isThe singular-system Tikhonov filter is the data-to-solution gain; is the fraction of an exact solution mode retained. If , a positive singular value mode has errorThe first term is approximation bias; the second is transmitted measurement noise. Suppressing a weak mode suppresses its true signal too.
For the two-pixel matrix in the inverse problem example and (), the mean and difference attenuation factors are and . Since , the reconstruction isIts noise contribution is , half the direct inverse's, but its exact-data reconstruction is . Consequently its total error Euclidean norm, about , exceeds the direct inverse's : this parameter sacrifices too much contrast. Taking instead gives and error about . Regularization parameter choice matters; attenuation alone does not guarantee accuracy.
Let and map the near-field trace to the far field by . Quadratic Tikhonov regularization minimizes and yields the displayed filtered coefficients. Its data-error gain is at most . Total error also contains bias: . A convergent parameter rule has and . Under , , the bias is at most ; choosing minimizes that error bound. Making indefinitely large removes noise by shrinking the reconstruction to zero, not by recovering the true field.
The two Born approximation measurement operators map a supported scattering potential to fields on planes above and below it. The displayed Tikhonov regularization functional balances their residuals against a positive quadratic penalty. With an penalty, the unconstrained minimizer is , where . Regularization stabilizes estimation but cannot remove the nonuniqueness of Born non-scattering contrasts at one incident direction without extra information.
For , the polynomial displayed here truncates the Neumann series for . It obeys , and is not an exact inverse. If , it is a controlled large-parameter expansion; its error is . At each fixed positive parameter the reconstruction is bounded. However this polynomial diverges on nonzero singular modes as and is not a substitute for the exact convergent Tikhonov filter in that limit.
For a bounded linear operator between Hilbert spaces, a quadratic penalty givesIts first variation in direction is in the real case; use the real part of the pairing in the complex case. Dividing stationarity by two gives . Thus the derivative of the displayed penalty itself is , while its contribution to the normalized normal equation for a linear inverse problem is .
The positive quadratic term makes the objective strongly convex and coercive, yielding a unique minimizer. In a singular system of a compact operator, the data-to-solution coefficient is instead of . Small singular values are suppressed, trading approximation bias against amplification of measurement noise. This is Tikhonov regularization, rather than exact minimization of the residual alone.
For a singular system of a compact operator with , Tikhonov regularization gives , where and the inner product is linear in the first argument. The bounded gain yields a norm-convergent reconstruction; components in are discarded and no component in is introduced.
The reconstruction operator in Tikhonov regularization has scalar gain . Its maximum over is , so a data perturbation of norm at most changes the solution by at most . A convergent noisy-data parameter choice satisfies and . Fixed-parameter stability is distinct from stability of the unregularized inverse.
For a bounded linear operator between Hilbert spaces, the spectral regularization method for quadratic Tikhonov regularization has scalar coefficient . Since , this coefficient is at most . The spectral theorem for normal operators transfers this scalar bound to the operator norm, providing the noise term in the noise-bias decomposition for linear regularization.
For bounded linear operators between Hilbert spaces with and , the operator is coercive and invertible for . The reconstruction uniquely minimizes . Testing its normal equation for coercive Tikhonov regularization by gives . If is injective, exact-data consistency and , give norm convergence to .
Let be injective, , , and . Since , . For the normal equation for coercive Tikhonov regularization gives . Insert an approximate and complete the square in to obtain . This implies the displayed bound, even with coefficient on its last term, and proves consistency without a fixed exact source condition for quadratic regularization.
For bounded linear operators and between real Hilbert spaces, and with , the unique minimizer of satisfies . Differentiate the objective in every direction and use the adjoint operator to obtain this equation. The coercive quadratic penalty makes its left-hand operator boundedly invertible. Setting gives the Tikhonov normal equation; omitting the penalty instead gives the normal equation for a linear inverse problem.
This range condition puts the exact solution in the operator range of the adjoint operator. It controls the small-singular value components of the solution and supplies convergence rates for spectral regularization methods. It is the quadratic-penalty case of a source condition in variational regularization.
The unique minimizer of satisfies
A spectral filter replaces unstable inversion of a singular value by a bounded scalar factor . For Tikhonov regularization, .
For a nonzero nonnegative integrable bandlimited function with frequency support in , the displayed construction is even, nonnegative and normalizable. Each factor has half-width frequency support, so their product retains width . Boundedness gives . Thus a positive-time tail estimate becomes a two-sided estimate after evenization, with a rescaled decay constant. A simple average with would not establish this from an uncontrolled negative tail.
A regularization parameter choice selects the amount of stabilization from the noise level, the measured data, or both. For Tikhonov regularization with deterministic error at most , a sufficient a priori condition for convergence is and .
An error bound , with positive , is minimized at , with value . Differentiate the scalar bound, or apply the arithmetic-geometric mean inequality. This is an a priori regularization parameter choice for a linear regularization with inverse-parameter noise amplification and first-order approximation bias; the parameter must also lie in the method's allowed interval.
An a priori regularization parameter choice depends on a known noise bound and fixed problem information, but not on the observed values of the noisy data.
With fixed , iterated Tikhonov regularization repeatedly fits the data while penalizing displacement from the preceding estimate:For a bounded linear operator between Hilbert spaces, each step is uniquely defined and obeysEquivalently the correction solves . This is an implicit residual correction; Landweber iteration instead multiplies the residual gradient by a scalar step.
Starting from zero, a singular value has inverse coefficient . For each fixed mode it approaches , while finite iteration limits noise amplification. Holding the penalty parameter fixed therefore does not remove the need for a stopping rule on noisy data. With , this is the iterated Tikhonov spectral filter.
The implicit iteration , starting from zero, multiplies each data singular vector by . Its operator norm is at most .
Variational regularization reconstructs an unknown by balancing data fit with a penalty expressing desired structure. A standard model isThe linear operator predicts data, denotes observations, and the extended-real functional can impose smoothness, sparsity or hard constraints. This construction includes nonlinear reconstruction maps even when itself is linear.[ref]
Modern Regularization Methods for Inverse Problems by Martin Benning and Martin Burger. §5, Definition5.1, equation(47), printed pp19–20
For , the model is quadratic Tikhonov regularization. For , the penalty controls the total variation seminorm on a domain and can retain jumps without demanding a square-integrable classical gradient. Adding the indicator functional of a constraint set enforces constraints such as nonnegativity.
Existence, uniqueness and stability are separate conclusions. A direct method in the calculus of variations requires suitable compactness of bounded-energy sets and lower semicontinuity; convexity alone does not supply compactness. A unique minimizer at fixed also does not prove convergence to the true object as noise vanishes: the regularization parameter choice must balance bias and noise.
Replacing a discrete gradient by a second-difference operator gives the global-norm penalty . Its reconstruction is for . Components in are preserved; affine-image membership of this kernel depends on the boundary stencil. Pixelwise Hessian penalties instead use a product of four-component balls.
For a discrete image signal operator , minimize with one Euclidean norm on the full gradient array. This differs from discrete isotropic total variation, which sums pixelwise Euclidean lengths. The global norm's dual ball is a single ball; its convex projection normalizes the whole vector array.
Let with one global dual ball. Its support function is , and the proximal operator of a support function gives . The removed component is the convex projection, while the reconstructed image signal is its residual. Projected gradient descent on , , converges for .
For positive observations and positive predicted intensities , this is the generalized Kullback–Leibler divergence with observation in the first argument. Its scalar derivative in is and its second derivative is . It differs from the divergence of a reconstructed density from a reference density by which argument is varied. A linear prediction gives derivative through the adjoint operator, on suitable admissible function spaces. This fidelity arises from the negative log likelihood of a Poisson observation model, after removal of terms depending only on observations.
For and a positivity-preserving operator, this is the negative log-likelihood for independent Poisson observations with intensity , up to constants depending only on the data and the unit background. For bounded , its scalar derivatives are and on . It is convex, and strictly convex in the predicted intensity when almost everywhere. On a unit-area domain, the Jensen inequality gives . The shift makes integrable whenever ; no integrability of is needed.
Let be a bounded connected Lipschitz domain, , bounded, and bounded and positivity preserving with . Minimize over nonnegative BV space functions. The logarithmic Jensen inequality bounds and variation on sublevels; mean control for positive imaging operators then bounds the full norm. Bounded-variation compactness gives strong convergence, including nonnegativity. The scalar fidelity has bounded derivative on , so continuity of makes its integral continuous in that limit. Lower semicontinuity of variation proves existence by the direct method in the calculus of variations. If almost everywhere and is injective, strict convexity of the fidelity gives uniqueness. For , zero is the unique minimizer even without injectivity, since zero energy forces both and a constant nonnegative .
On a bounded domain, suppose , , and a bounded positivity-preserving operator satisfies . Every strictly positive has : otherwise for all , and continuity gives . Since whenever , every such has positive energy. The constants have zero variation and energy at most . Their excluded zero limit proves nonattainment. Coercivity and bounded-variation compactness cannot by themselves preserve a nonclosed strict-positivity constraint.
For and , minimizing on gives . The roots have opposite signs, so only the displayed positive root belongs to the effective domain. Strict positivity of the second derivative proves uniqueness. For an integral Poisson data fidelity, the proximal operator separates pointwise under the appropriate integrability assumptions.
This convex function penalizes positive densities using negative entropy, with and infinite value for negative inputs. Its scalar derivative is on . On a bounded domain, restricting to uniformly positive bounded functions gives a simple setting for a Fréchet derivative. Its Bregman distance is the generalized Kullback–Leibler divergence. With fixed total mass, minimizing this negative-entropy expression maximizes the corresponding entropy.
Exact fitting in the small-parameter limit requires data that can be approximated by forward images of elements in the regulariser's effective domain. Membership merely in the operator range is insufficient when an extended-real regulariser imposes a hard constraint.
For a nonnegative regulariser , the optimal objective value is non-decreasing and concave in the positive regularization parameter. If and , comparison with zero makes it finite and a locally Lipschitz function away from parameter zero.
Articles were limited to the first 100 out of 206 total.
Articles by others on the same topic




The term "inverse problem" generally refers to a type of problem in various fields (such as mathematics, physics, engineering, and data science) where one aims to infer or reconstruct the inputs or causes from observed outputs or effects. Inverse problems contrast with "forward problems," where the relationship between inputs and outputs is known, and the goal is to predict the results of certain input conditions.